
Figure 1 From Vita Par Visual And Textual Attribute Alignment With

Figure 1 from ViTA-PAR: Visual and Textual Attribute Alignment with ...
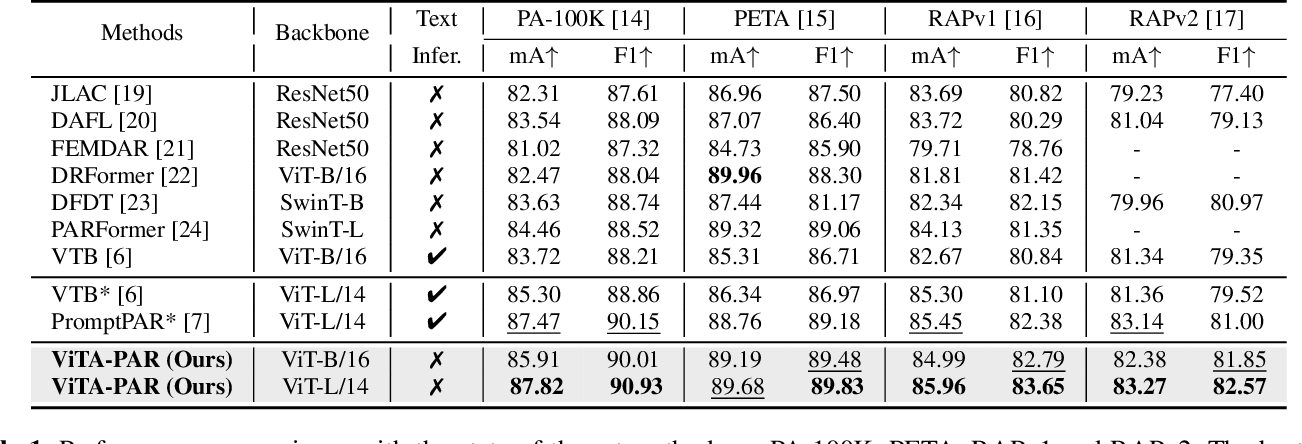
Table 1 from ViTA-PAR: Visual and Textual Attribute Alignment with ...
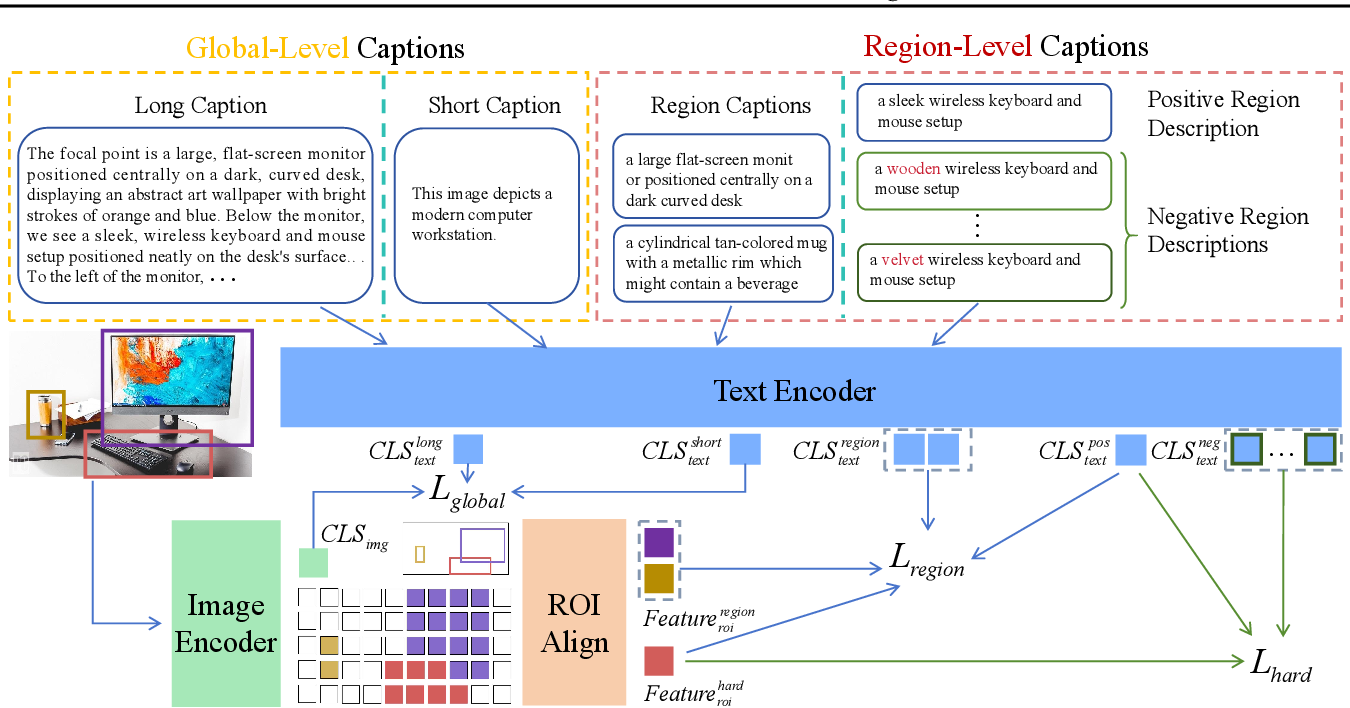
Figure 1 from FG-CLIP: Fine-Grained Visual and Textual Alignment ...

Figure 1 from Textual and Visual Prompt Fusion for Image Editing via ...

Figure 1 from Visual-Textual Alignment for Graph Inference in Visual ...

Figure 1 from Cross-Modality Pyramid Alignment for Visual Intention ...
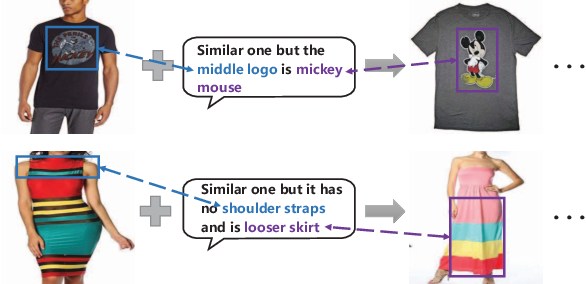
Figure 1 from Visual-Linguistic Alignment and Composition for Image ...
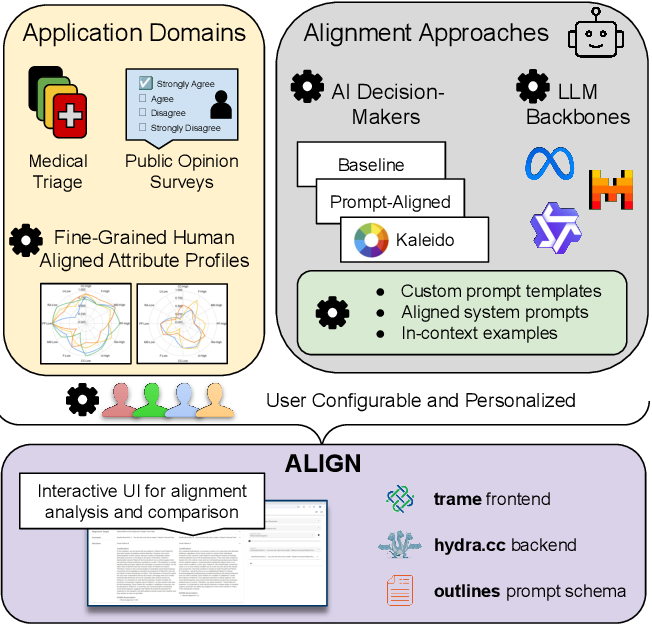
Figure 1 from ALIGN: Prompt-based Attribute Alignment for Reliable ...

Figure 1 from Spatial alignment facilitates visual comparison ...
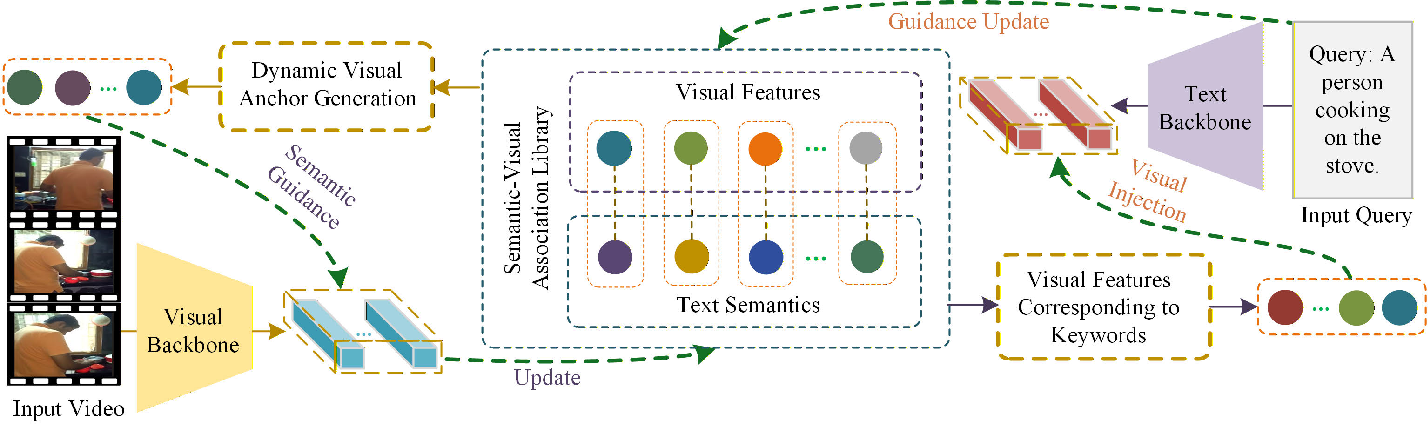
Figure 1 from Bidirectional Cross-Modal Collaborative Alignment via ...
Advertisement Space (300x250)
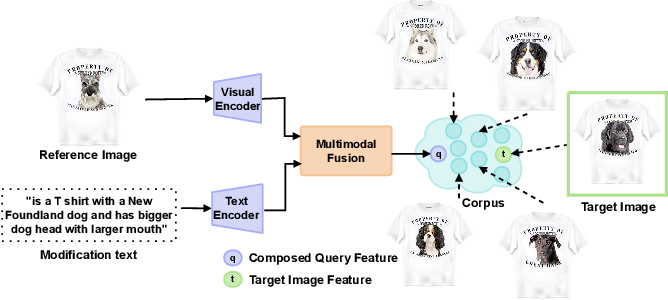
Figure 1 from Text-Guided Attribute Enhancement Framework for Composed ...
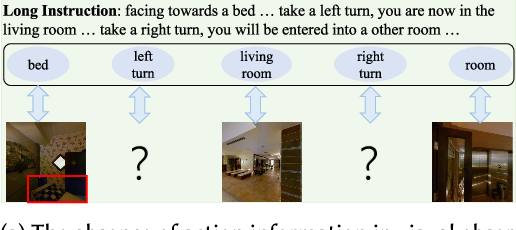
Figure 1 from Action-Aware Visual-Textual Alignment for Long ...

Figure 1 from Action-Aware Visual-Textual Alignment for Long ...

Alignment of visual and textual objects (entities) and relation ...

Figure 1 from Effectively Leveraging Attributes for Visual Similarity ...

Figure 1 from Visual–Textual Alignment for Generalizable Person ...
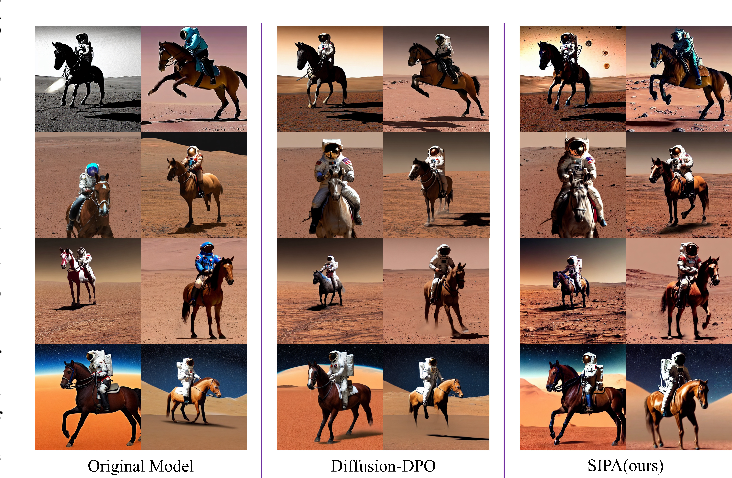
Figure 1 from Identical Human Preference Alignment Paradigm for Text-to ...

Figure 1 from Joint Visual-Textual Reasoning and Visible-Infrared ...

(a) Image with visual entities and caption, (b) Alignment of visual ...

Figure 1 from Learning to Predict Visual Attributes in the Wild ...
Advertisement Space (336x280)

Alignment of visual and textual objects (entities) and relation ...

Figure 1 from Discrete Joint Semantic Alignment Hashing for Cross-Modal ...

Figure 1 from A Simple Visual-Textual Baseline for Pedestrian Attribute ...

Figure 1 from Prototype-Aware Multimodal Alignment for Open-Vocabulary ...

(a) Image with visual entities and caption, (b) Alignment of visual ...
FG-CLIP: Fine-Grained Visual and Textual Alignment

Figure 2 from Attributes-Guided and Pure-Visual Attention Alignment for ...
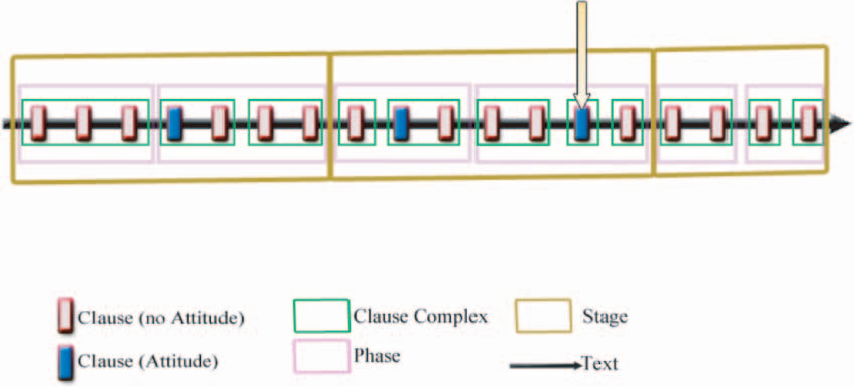
Figure 1 from Visualizing patterns of appraisal in texts and corpora ...

Figure 1 from Visual-Text Cross Alignment: Refining the Similarity ...

Figure 2 from Visual–Textual Alignment for Generalizable Person ...
Advertisement Space (336x280)

Figure 1 from Design of the topology for contrastive visual-textual ...

Table 2 from Cross-modal Generation and Alignment via Attribute-guided ...

Figure 1 from Unleashing the Potential of Vision-Language Pre-Training ...

Figure 3 from Multi-Modal Attribute Prompting for Vision-Language ...
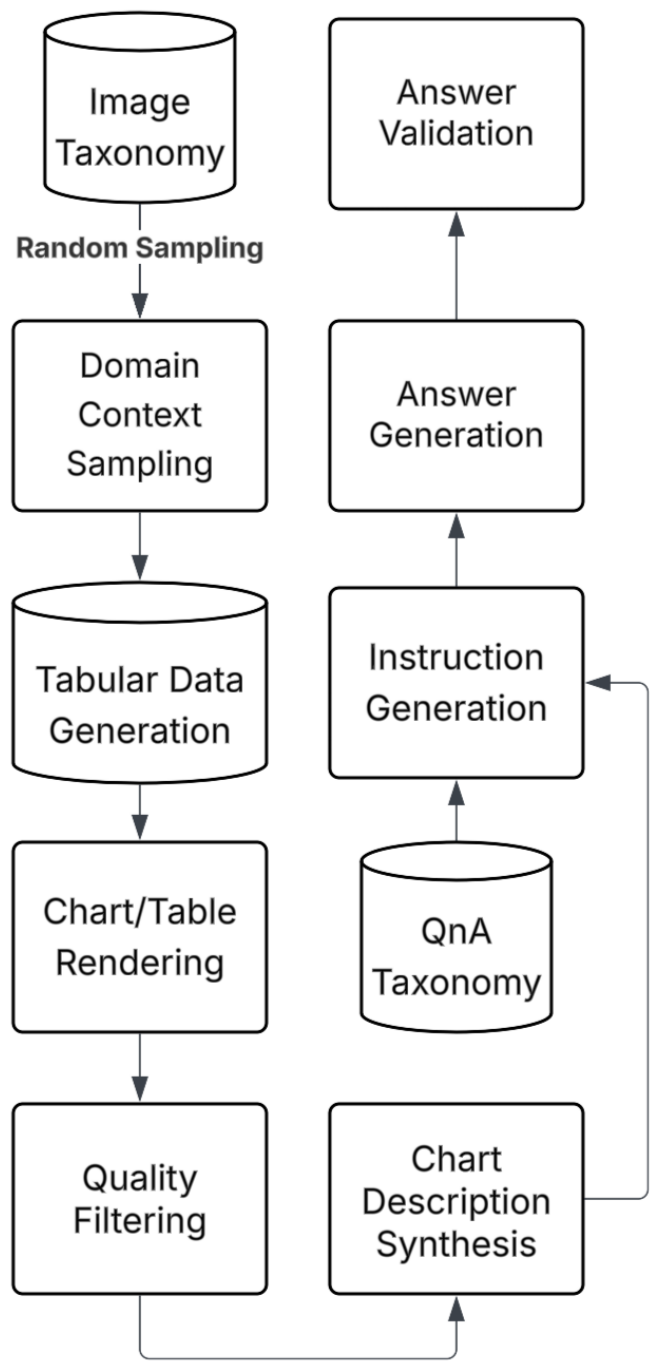
[论文评述] GRAFT: GRaPH and Table Reasoning for Textual Alignment -- A ...

Comparison attribute alignment in Person Re-identification and Person ...