
Figure 4 From Tinybenchmarks Evaluating Llms With Fewer Examples
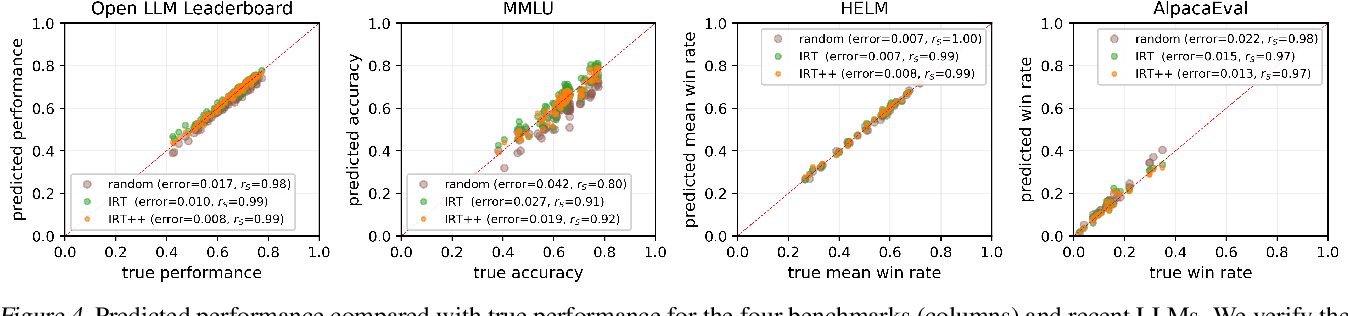
Figure 4 from tinyBenchmarks: evaluating LLMs with fewer examples ...

tinyBenchmarks: evaluating LLMs with fewer examples | AI Research Paper ...
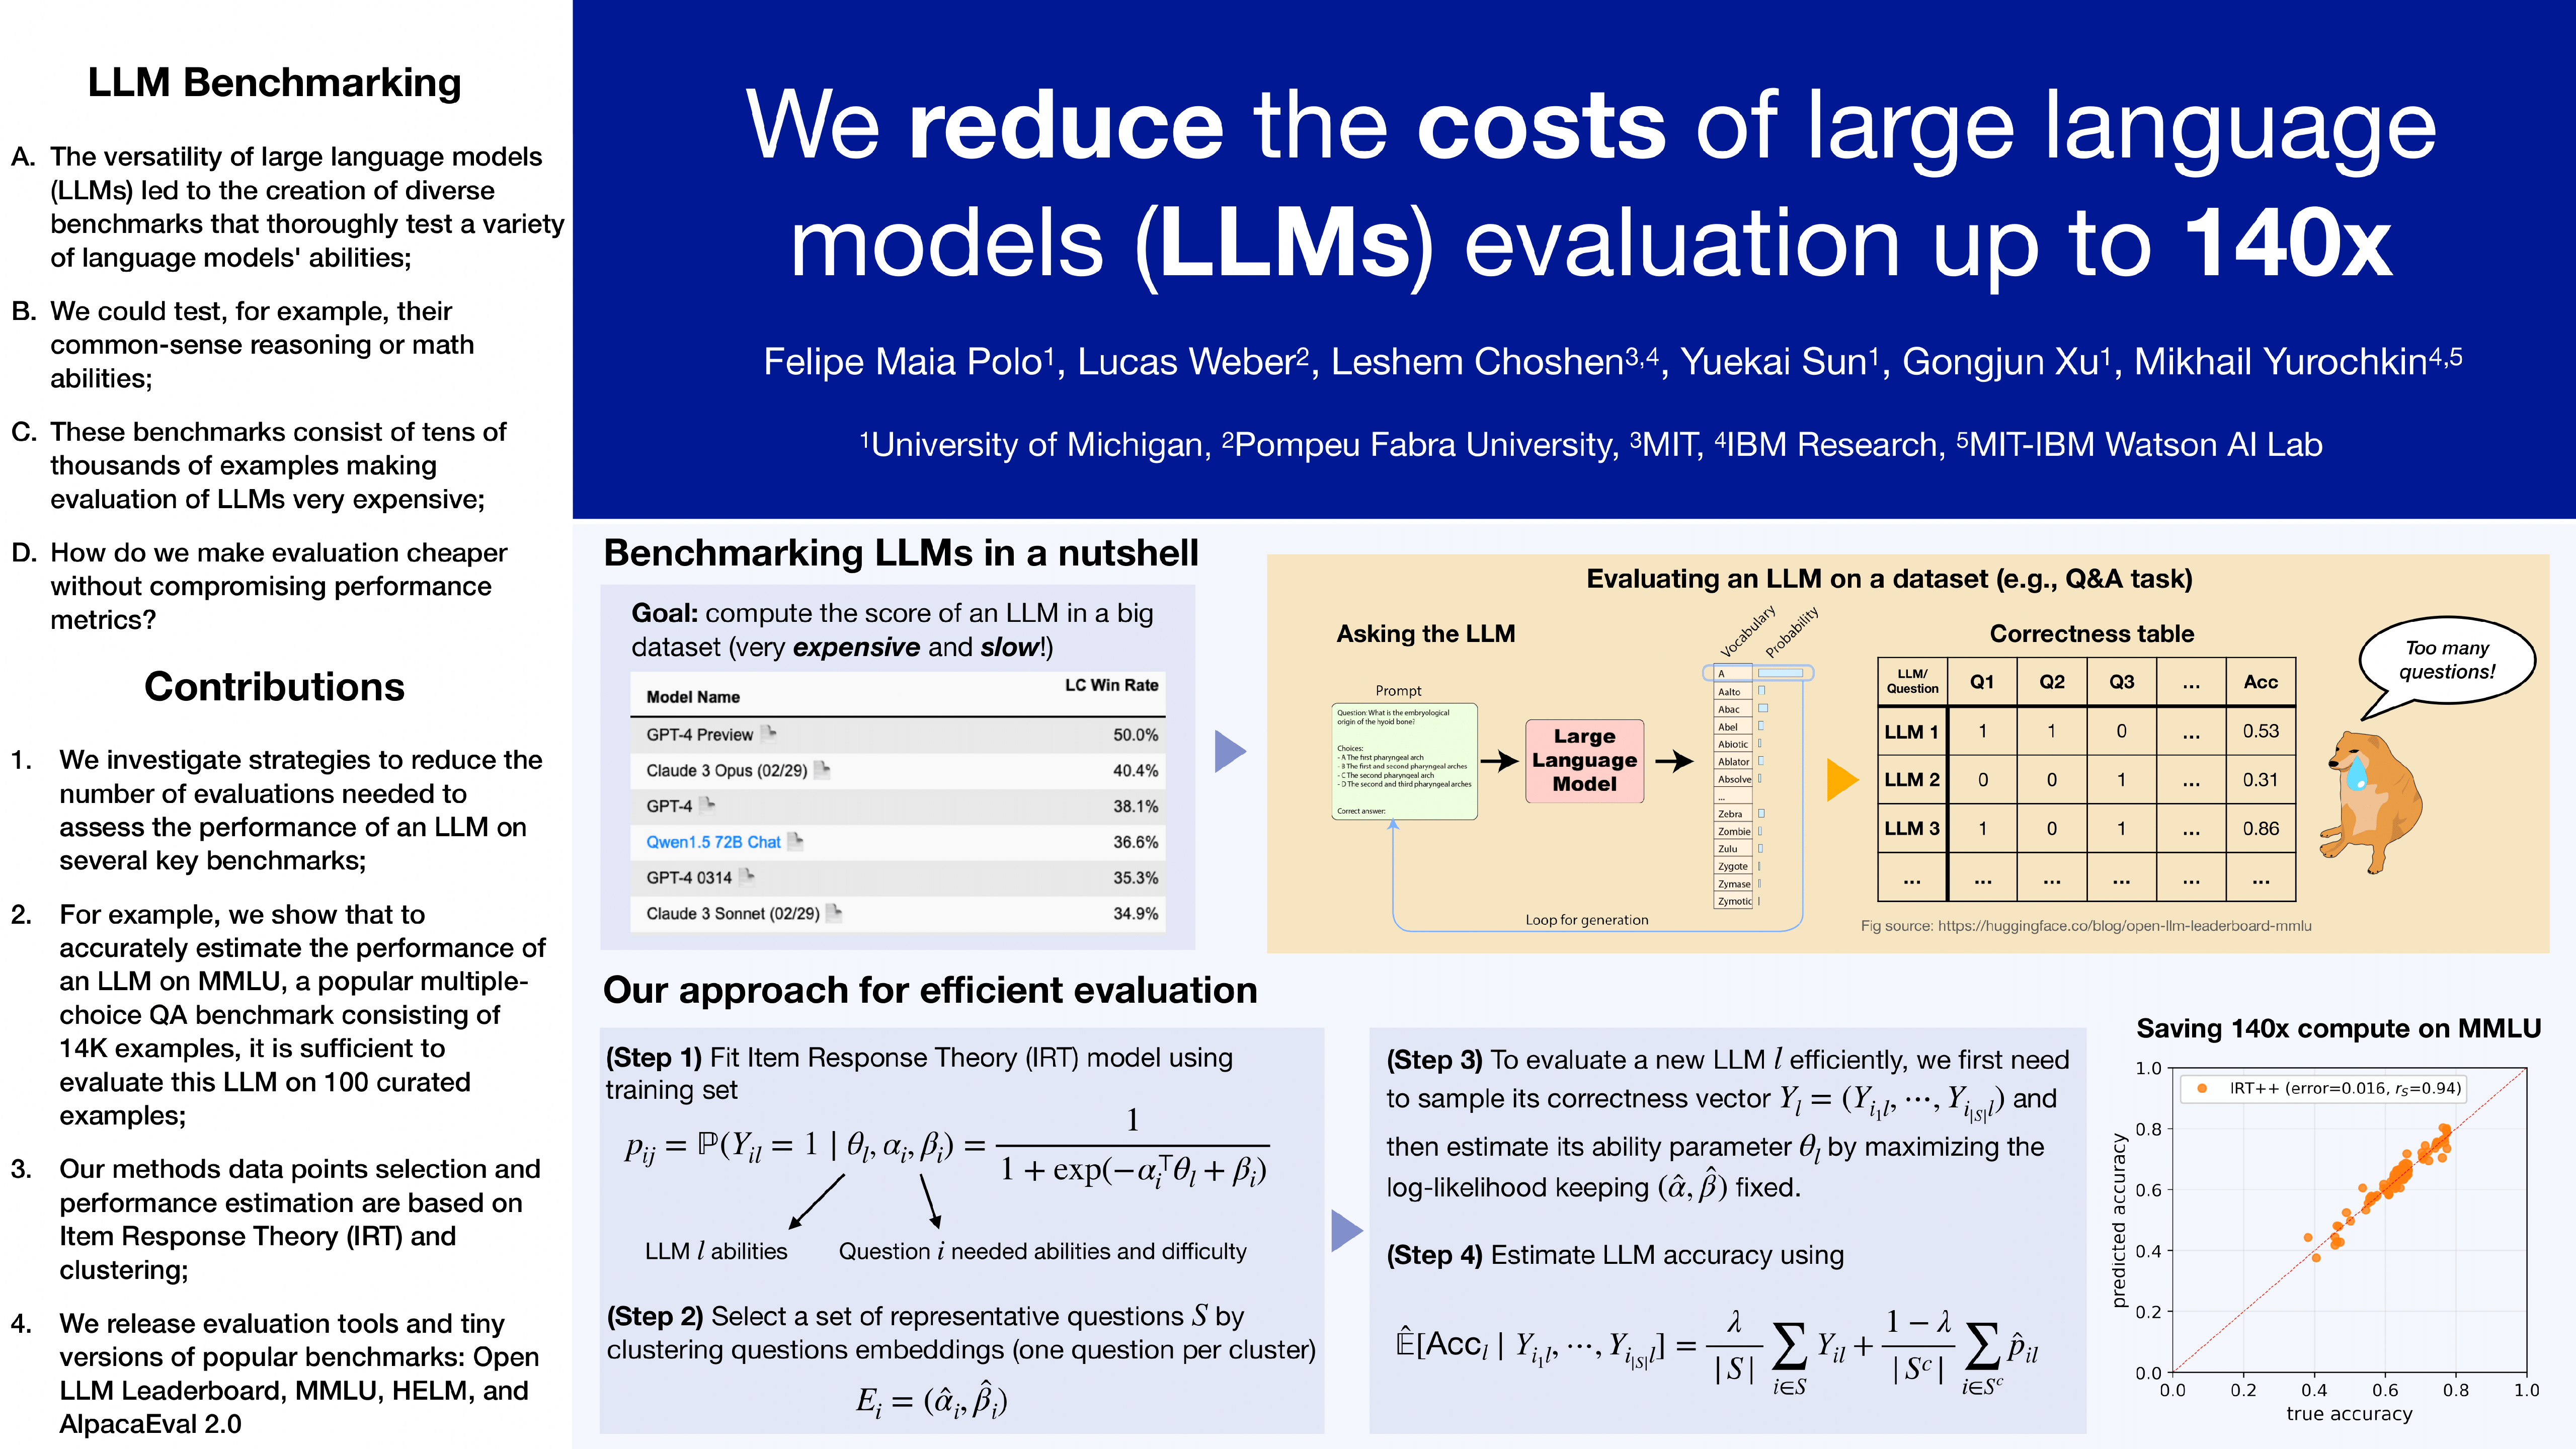
ICML Poster tinyBenchmarks: evaluating LLMs with fewer examples

tinyBenchmarks: evaluating LLMs with fewer examples

(PDF) tinyBenchmarks: evaluating LLMs with fewer examples

[PDF] tinyBenchmarks: evaluating LLMs with fewer examples | Semantic ...

Paper page - tinyBenchmarks: evaluating LLMs with fewer examples
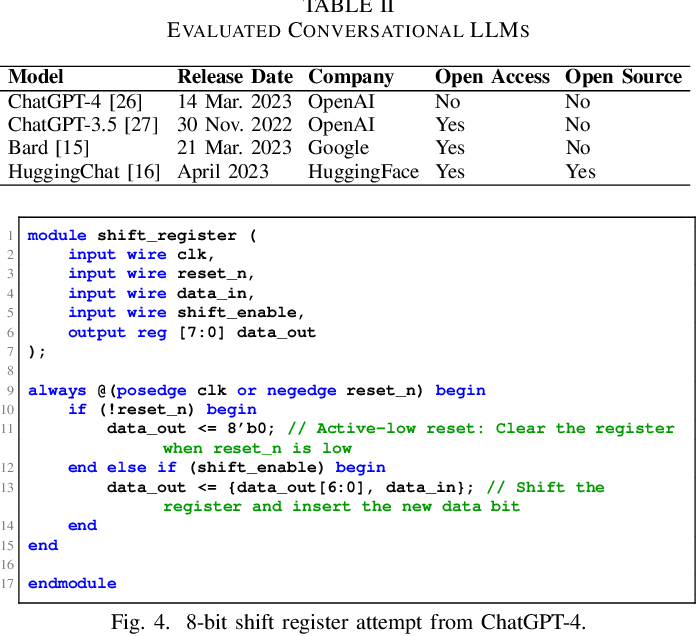
Figure 4 from Evaluating LLMs for Hardware Design and Test | Semantic ...
tinyBenchmarks: Efficiently Evaluating LLMs with Fewer Examples | The ...
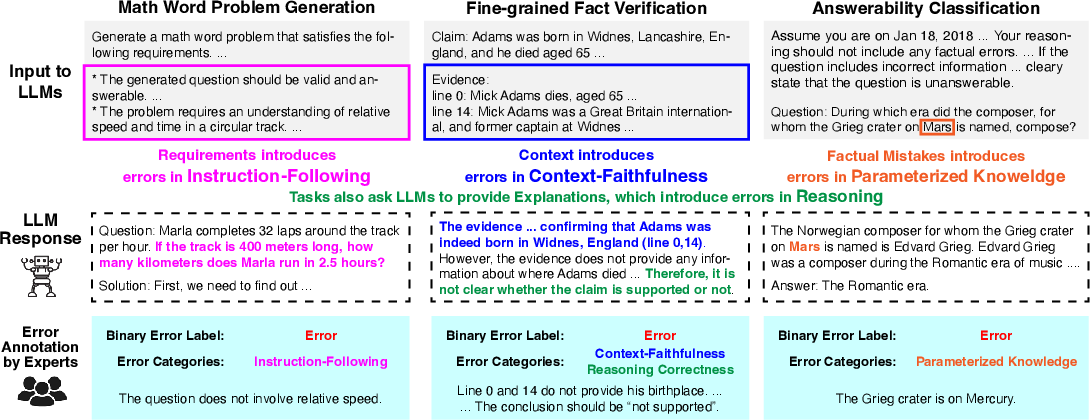
Figure 2 from Evaluating LLMs at Detecting Errors in LLM Responses ...
Advertisement Space (300x250)

CIBench: Evaluating Your LLMs with a Code Interpreter Plugin

Figure 1 from Less is More for Long Document Summary Evaluation by LLMs ...
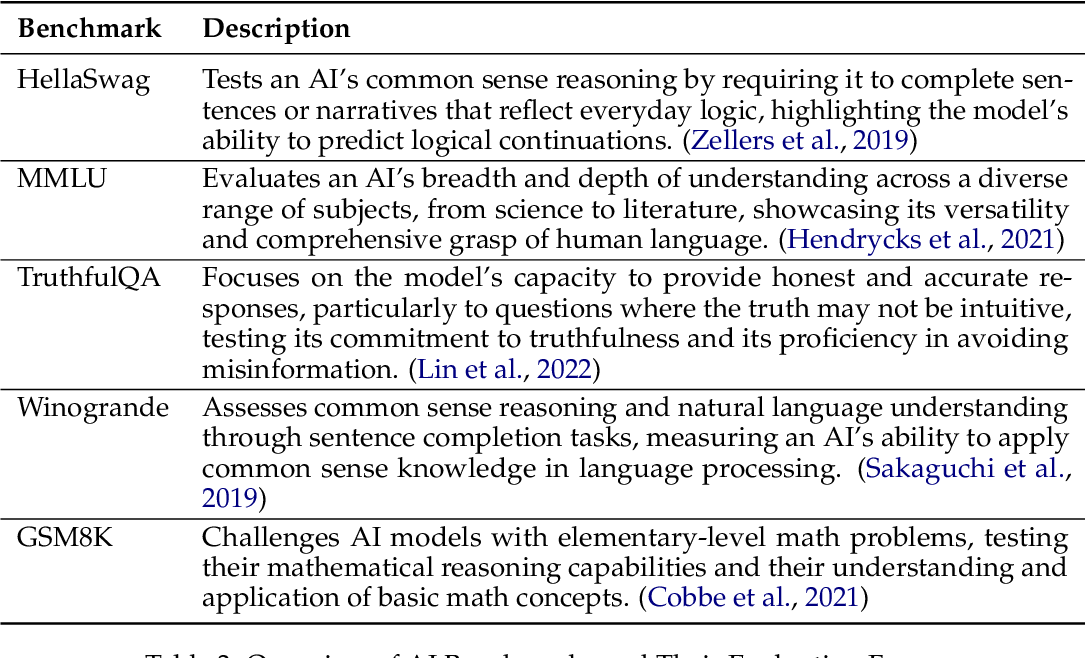
Table 3 from Evaluating LLMs at Evaluating Temporal Generalization ...
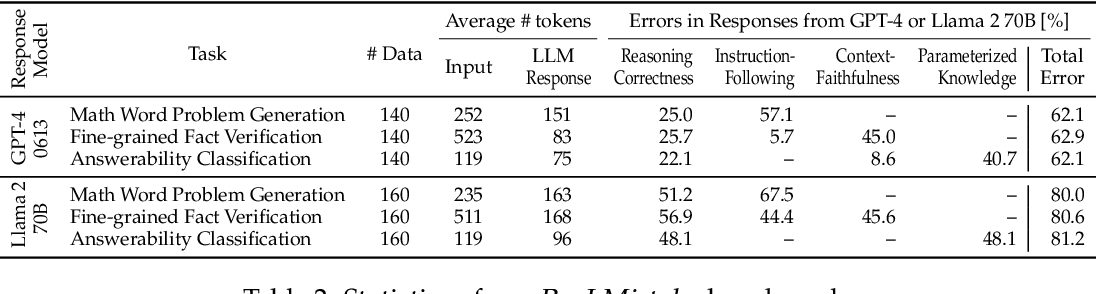
Table 2 from Evaluating LLMs at Detecting Errors in LLM Responses ...

Table 1 from Evaluating LLMs at Detecting Errors in LLM Responses ...

[논문 리뷰] Evaluating LLMs Robustness in Less Resourced Languages with ...
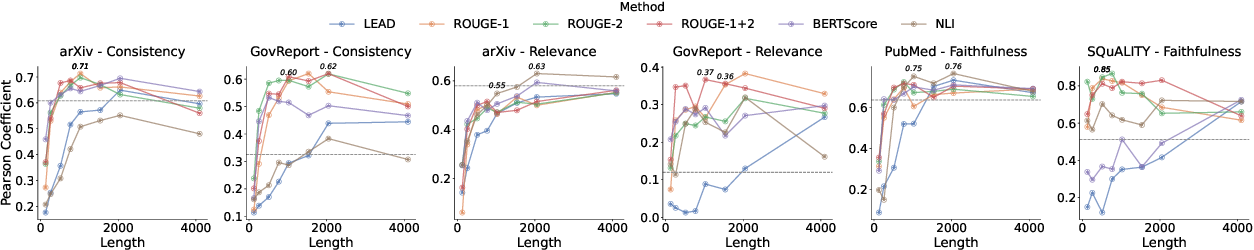
Figure 3 from Less is More for Long Document Summary Evaluation by LLMs ...
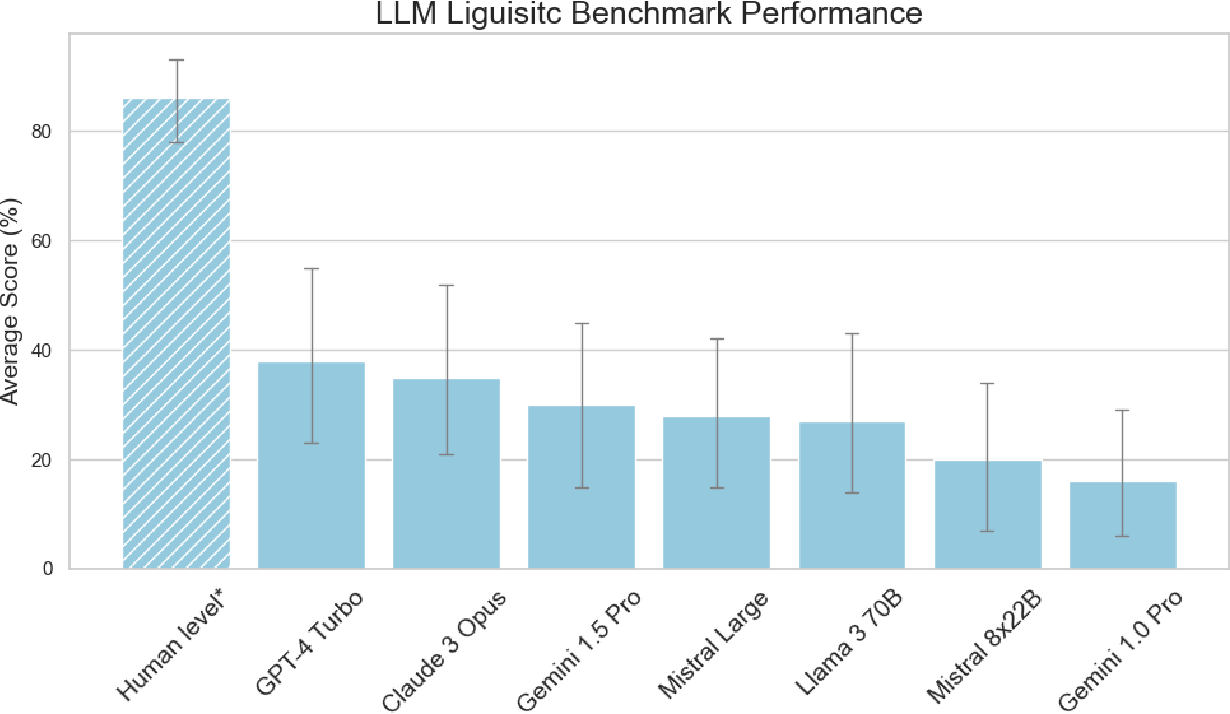
Figure 1 from Easy Problems That LLMs Get Wrong | Semantic Scholar

How can we evaluate LLMs during training? 🤔 Evaluating LLMs on common ...

Evaluating LLMs at Detecting Errors in LLM Responses
Advertisement Space (336x280)

Evaluating LLMs Capabilities Towards Understanding Social Dynamics
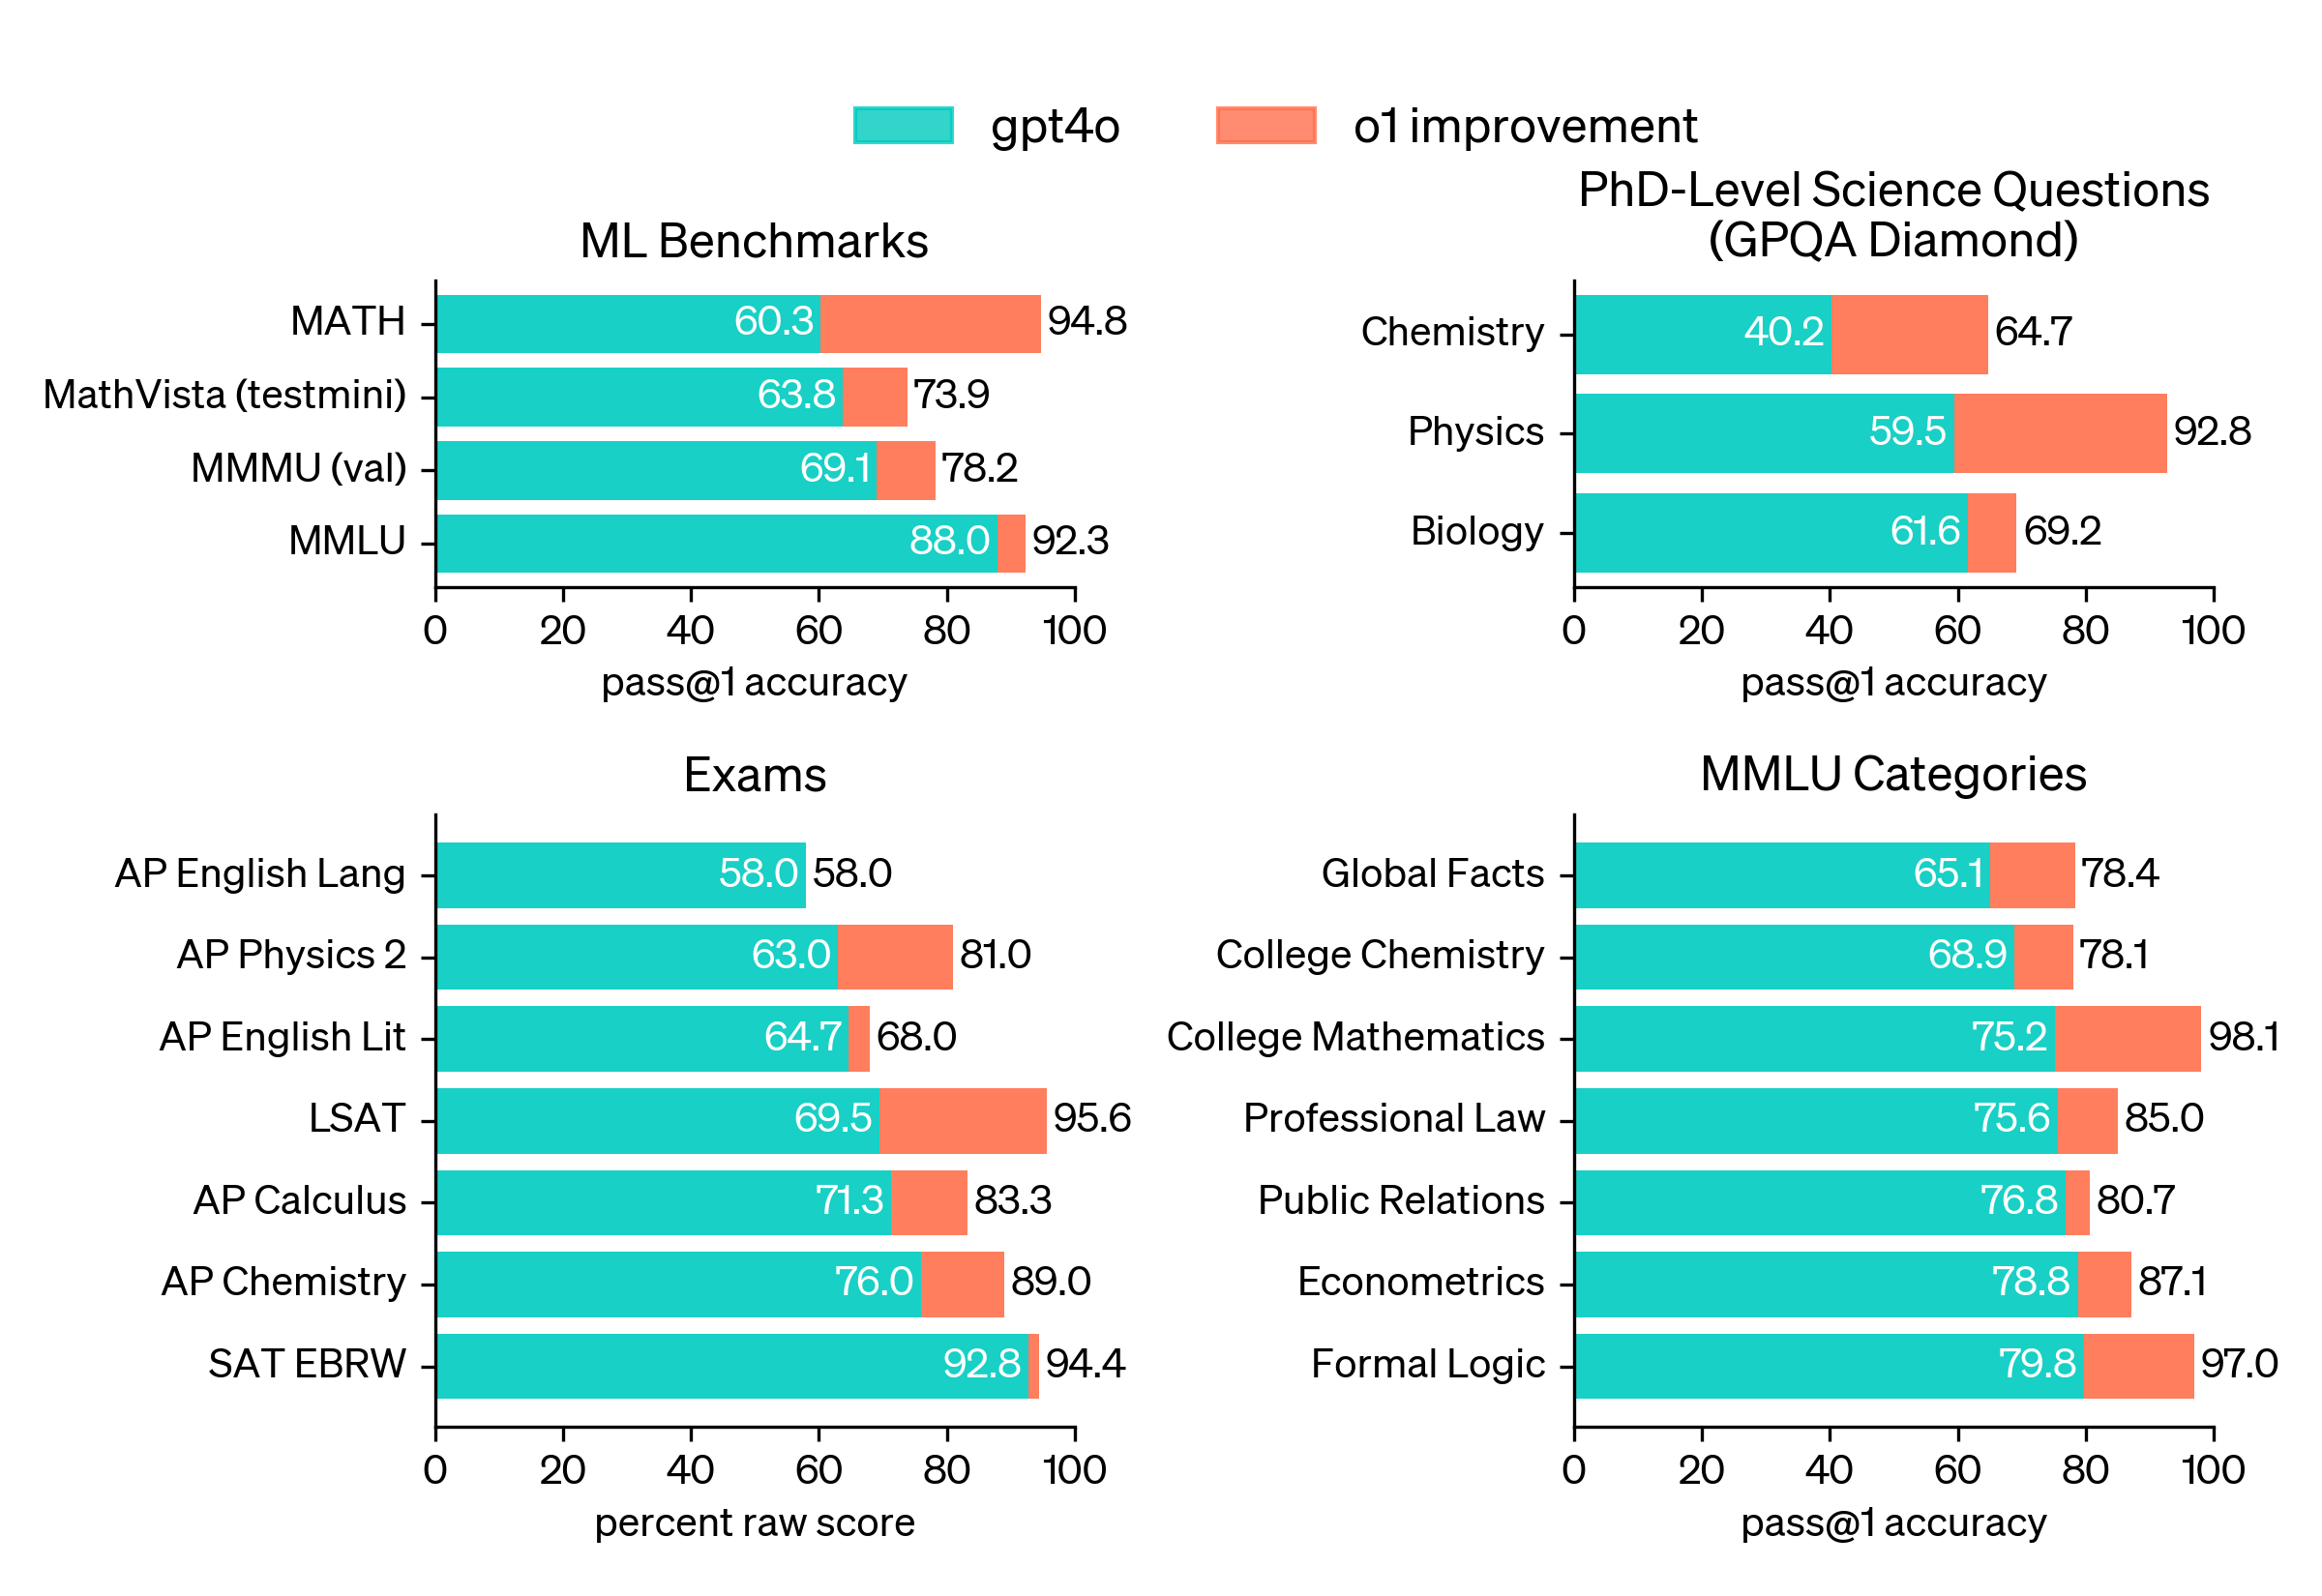
Learning to reason with LLMs | OpenAI
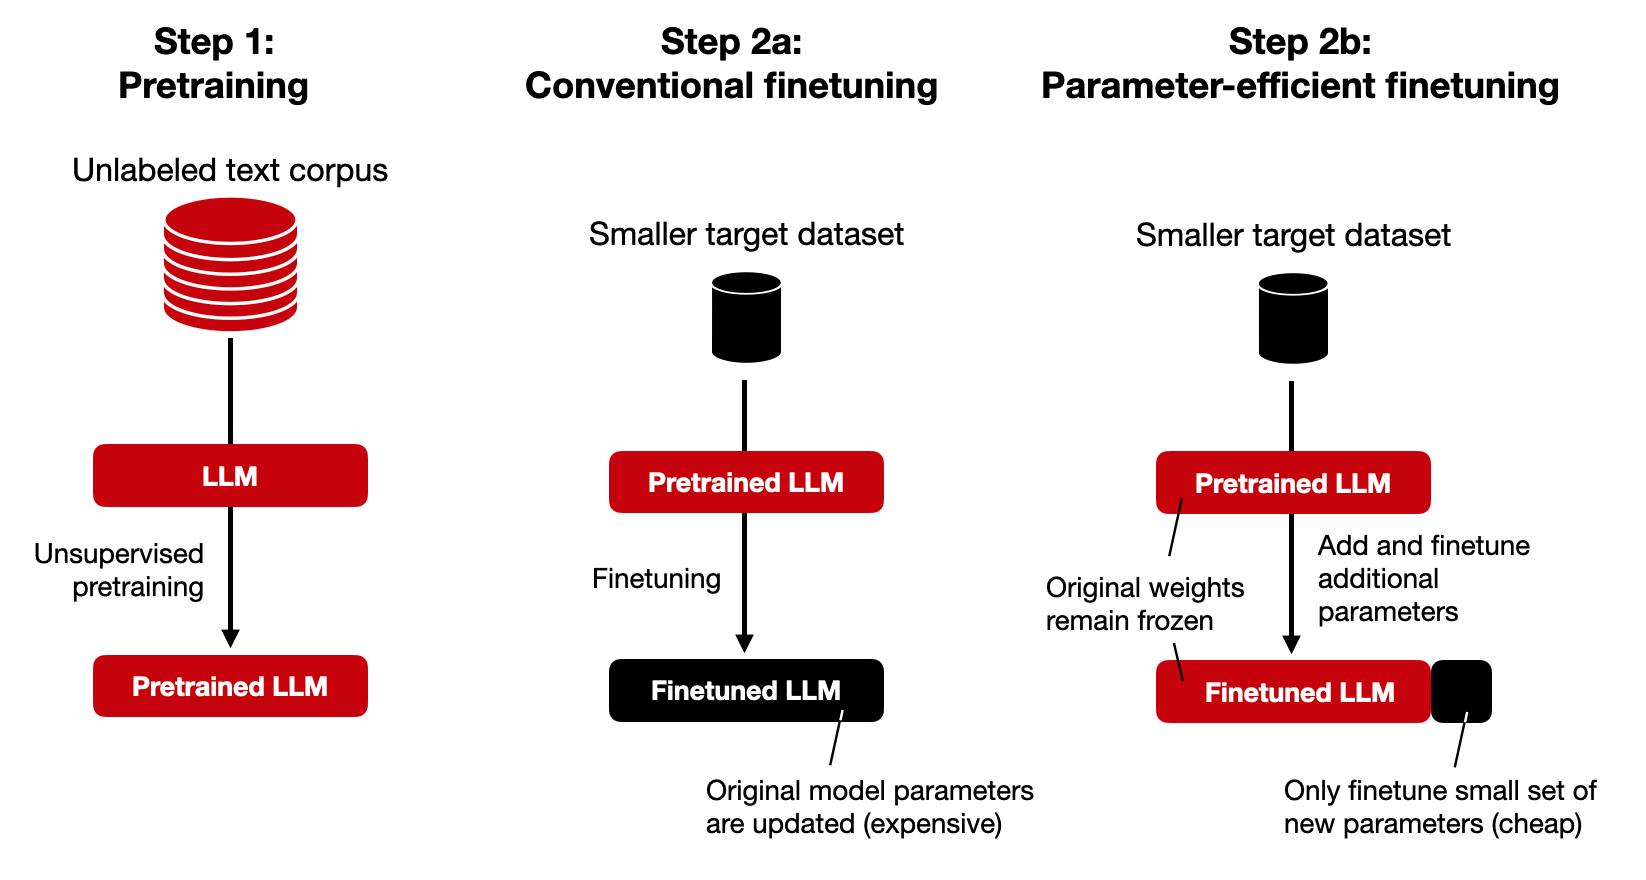
Finetuning LLMs Efficiently with Adapters
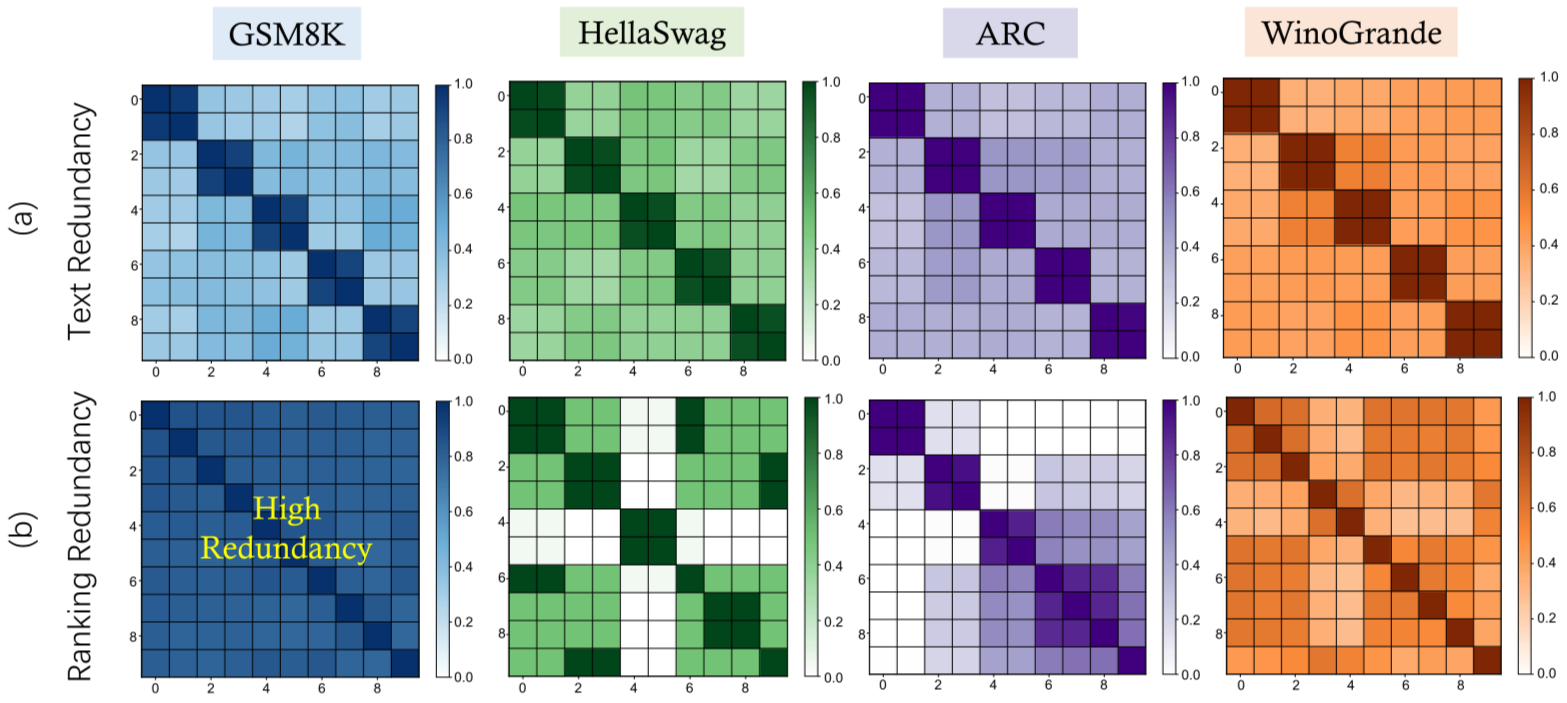
[논문 리뷰] Rethinking LLM Evaluation: Can We Evaluate LLMs with 200x Less ...

Better LLMs with Better Data & Cleanlab | Databricks Blog
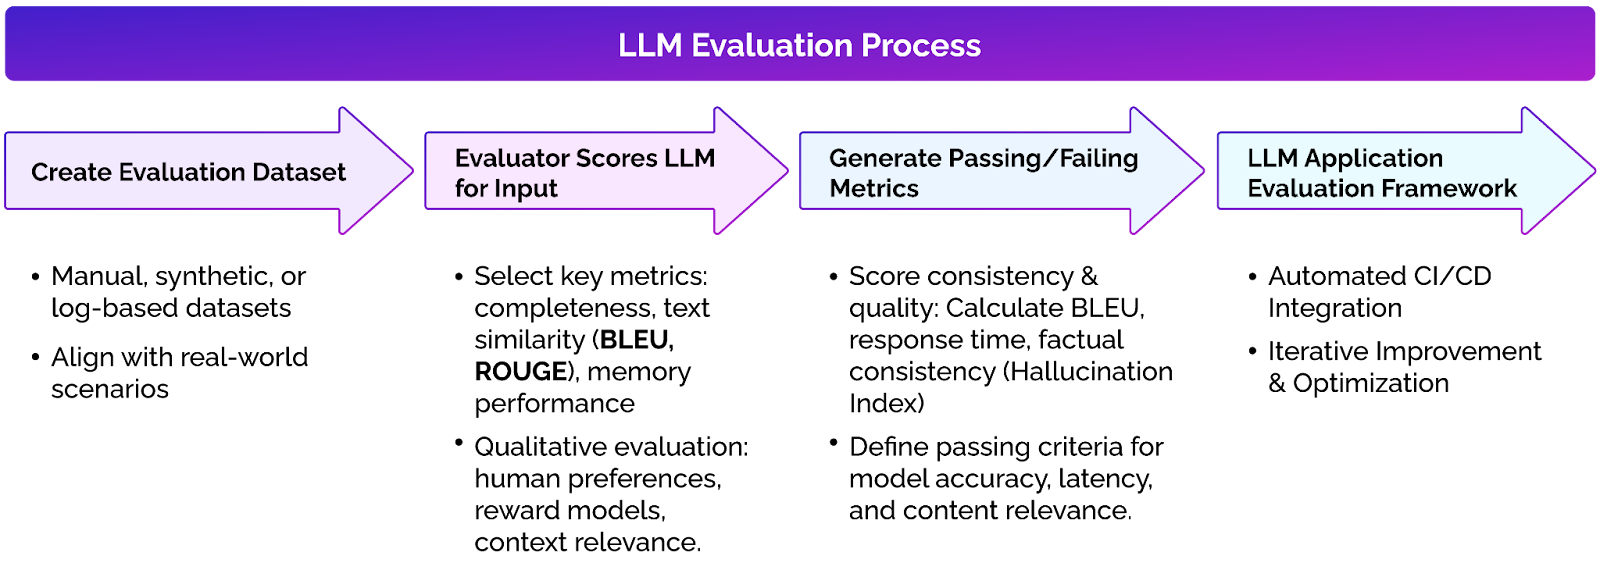
LLM Evaluation Framework: In-depth Tutorial With Examples | Zep

(PDF) GeoEval: Benchmark for Evaluating LLMs and Multi-Modal Models on ...

LatEval: An Interactive LLMs Evaluation Benchmark with Incomplete ...

Evaluating progress of LLMs on scientific problem-solving
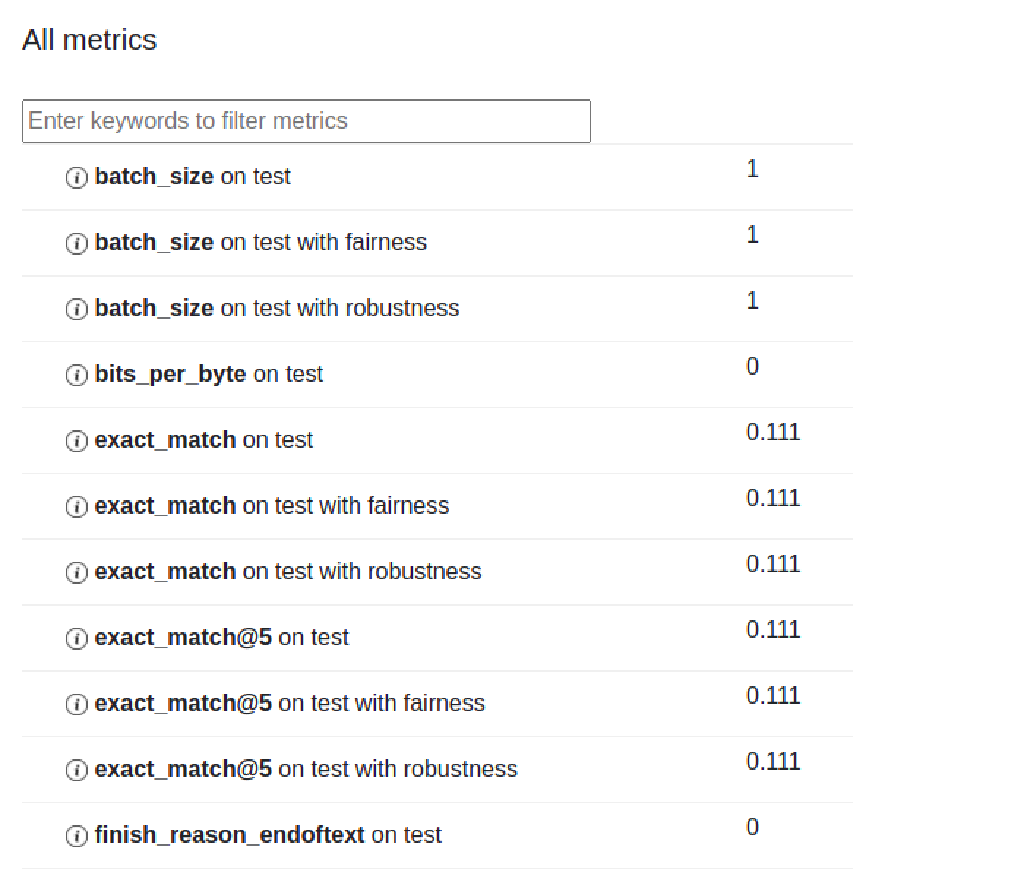
Evaluating LLMs Part I - Benchmarking Strategies
Advertisement Space (336x280)

Figure 1 from Benchmarking LLM Tool-Use in the Wild | Semantic Scholar

Benchmarking LLMs Made Easy with LLMeBench - DEV Community
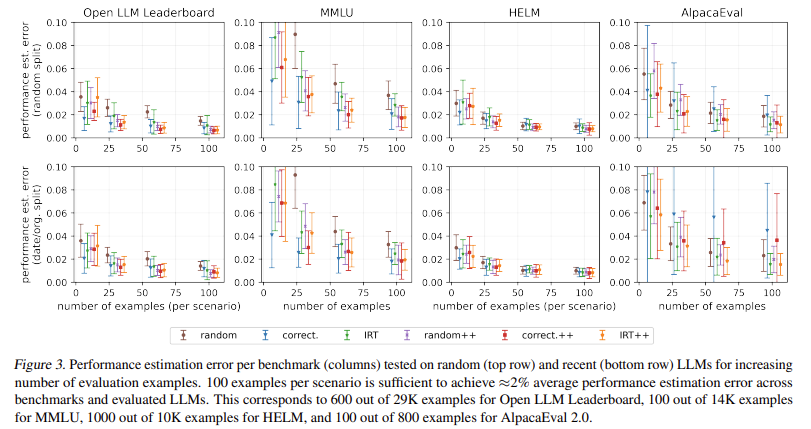
tinyBenchmarks: Revolutionizing LLM Evaluation with 100-Example Curated ...

🚀 tinyBenchmarks: Less Data, Similar Eval! Evaluating large language ...

Four Ways Benchmark Providers Evaluate LLMs - Annielytics.com

tinyBenchmarks: Revolutionizing LLM Evaluation with 100-Example Curated ...