
Paper Page Tinybenchmarks Evaluating Llms With Fewer Examples

Paper page - tinyBenchmarks: evaluating LLMs with fewer examples

tinyBenchmarks: evaluating LLMs with fewer examples | AI Research Paper ...
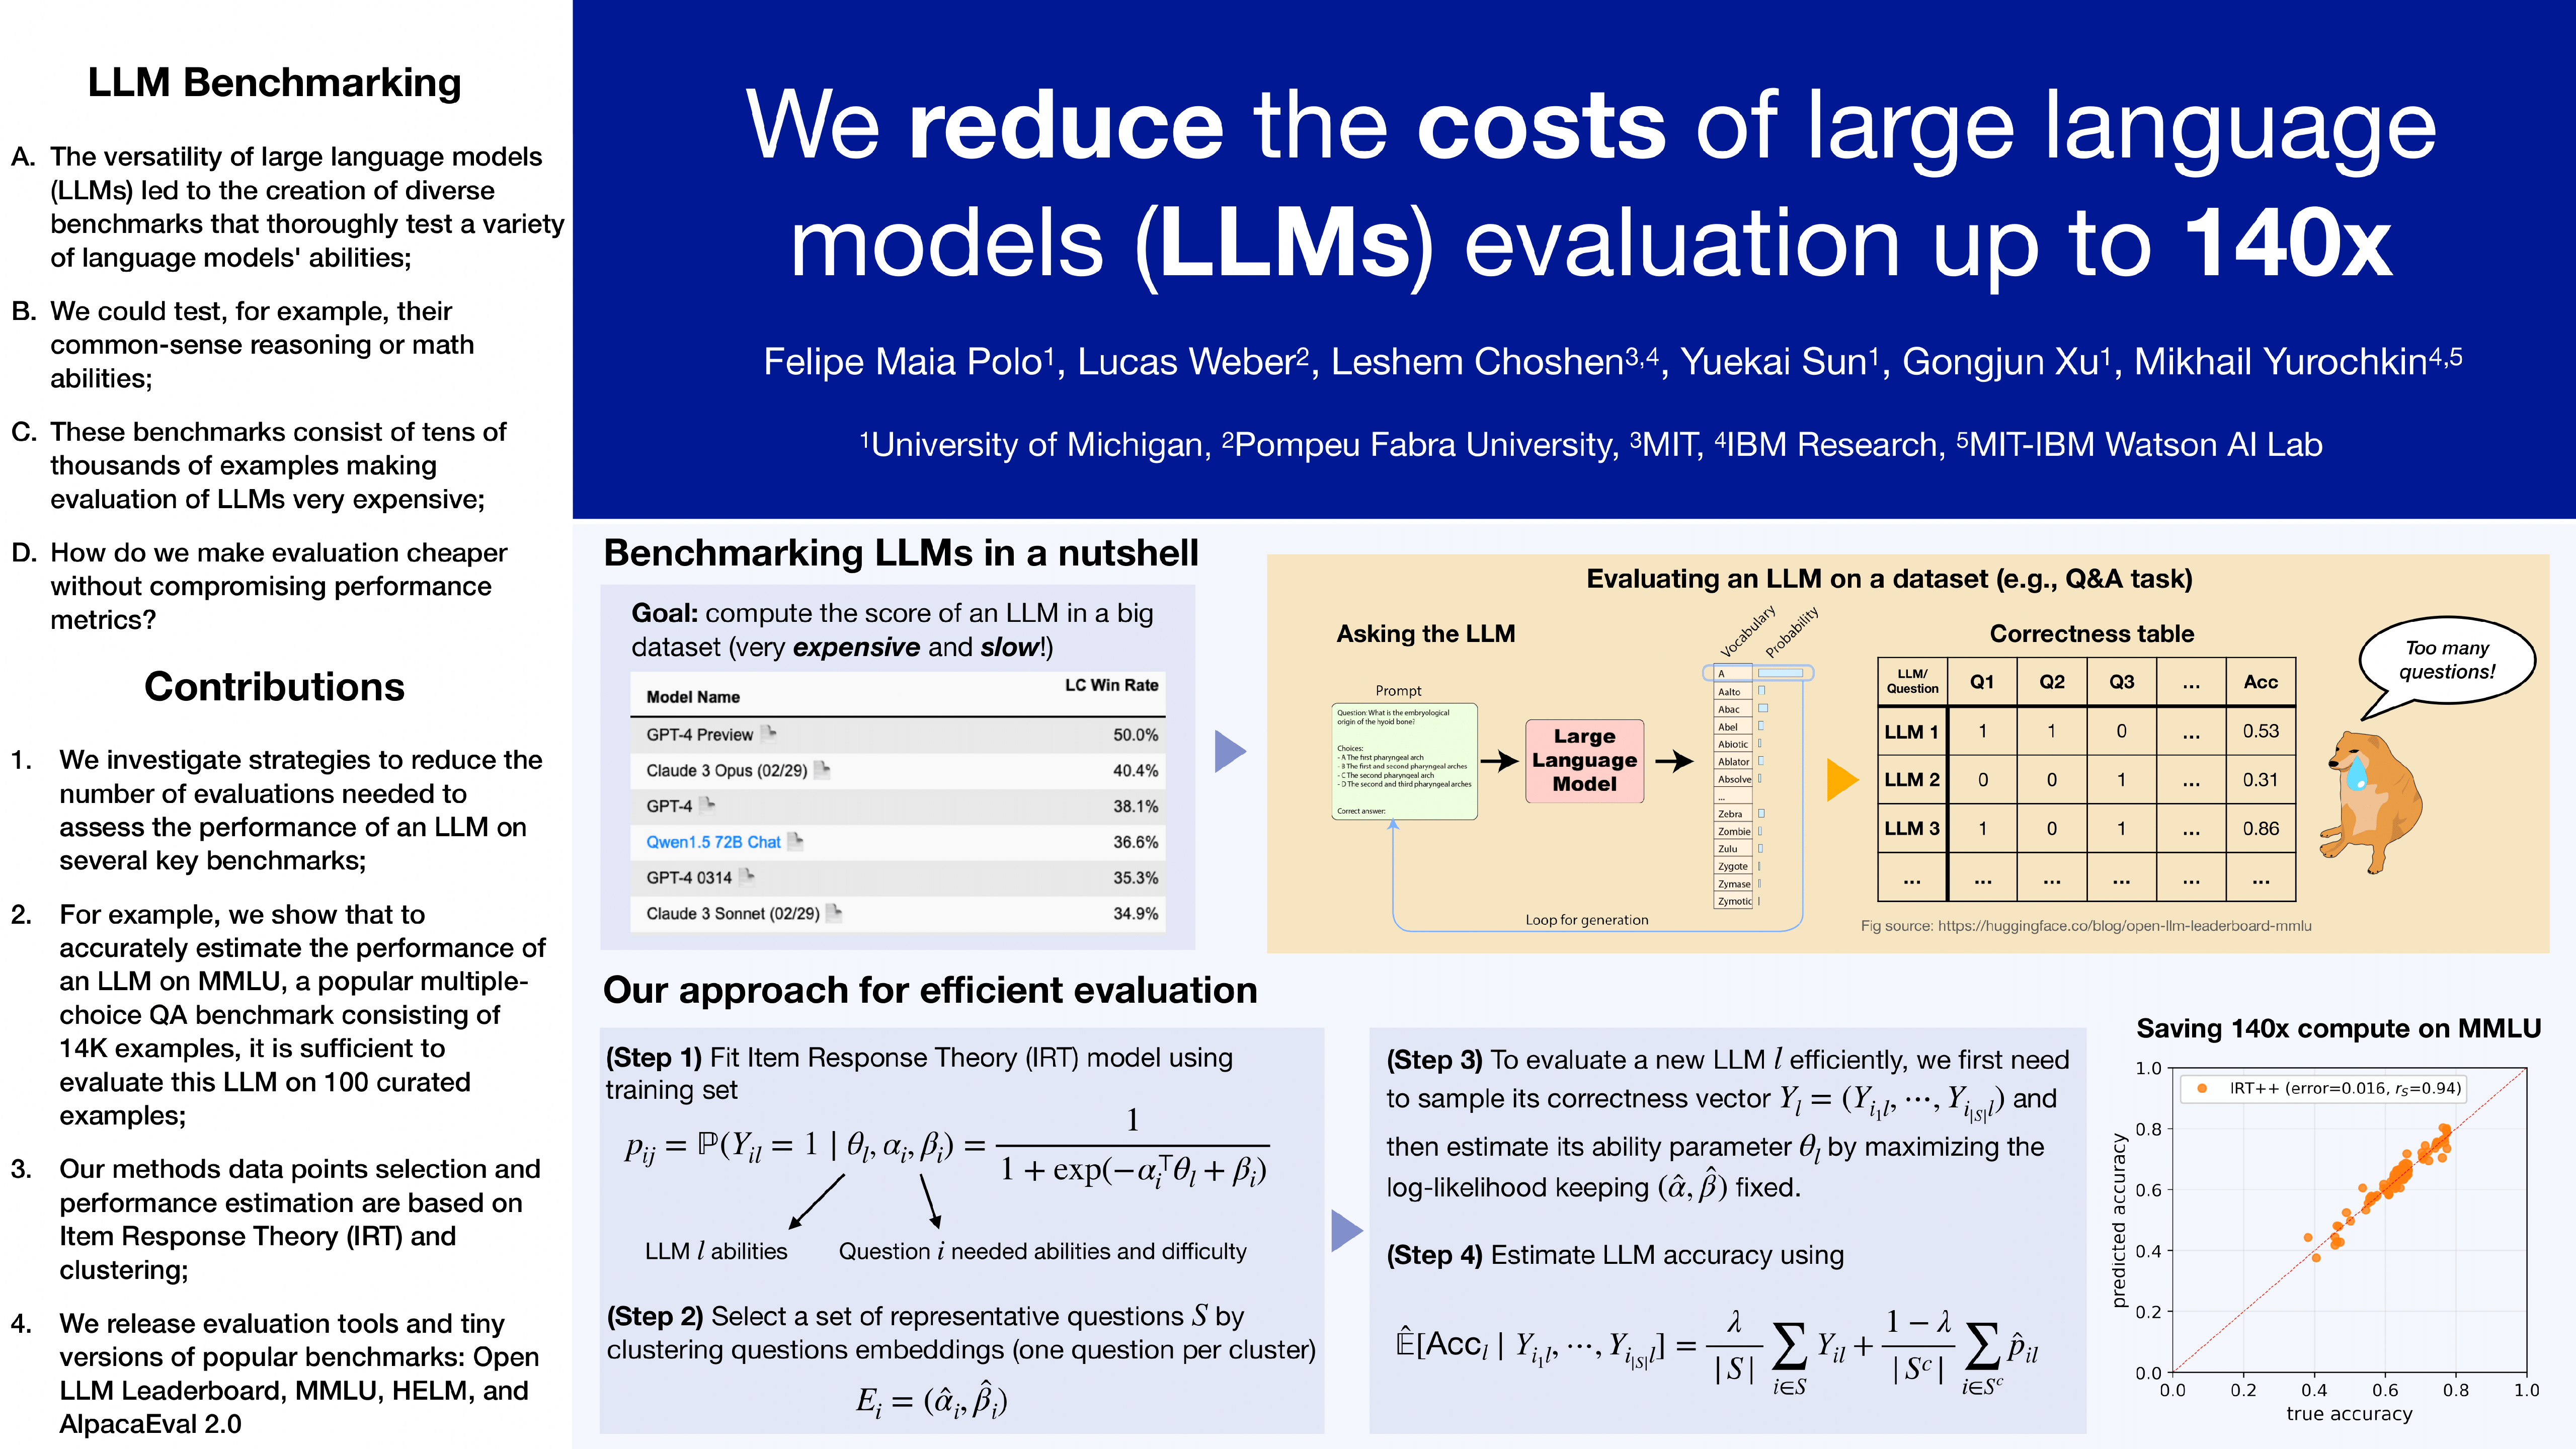
ICML Poster tinyBenchmarks: evaluating LLMs with fewer examples

tinyBenchmarks: evaluating LLMs with fewer examples

(PDF) tinyBenchmarks: evaluating LLMs with fewer examples
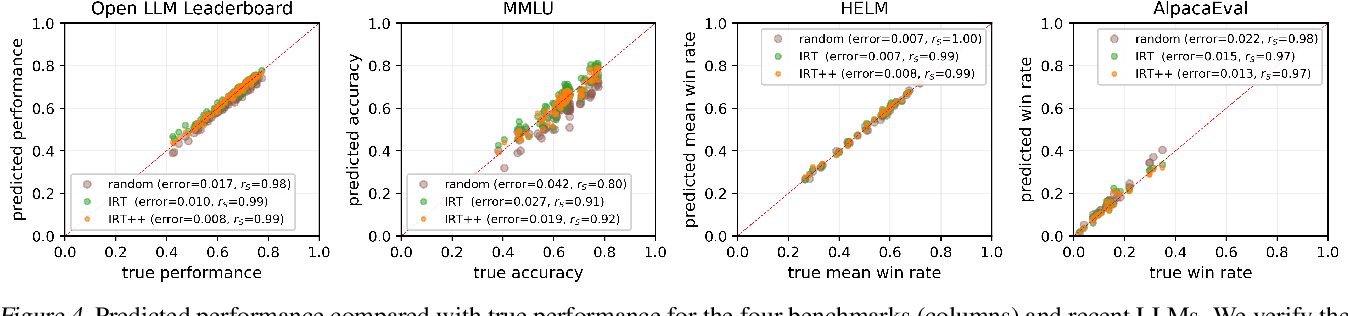
Figure 4 from tinyBenchmarks: evaluating LLMs with fewer examples ...

[PDF] tinyBenchmarks: evaluating LLMs with fewer examples | Semantic ...
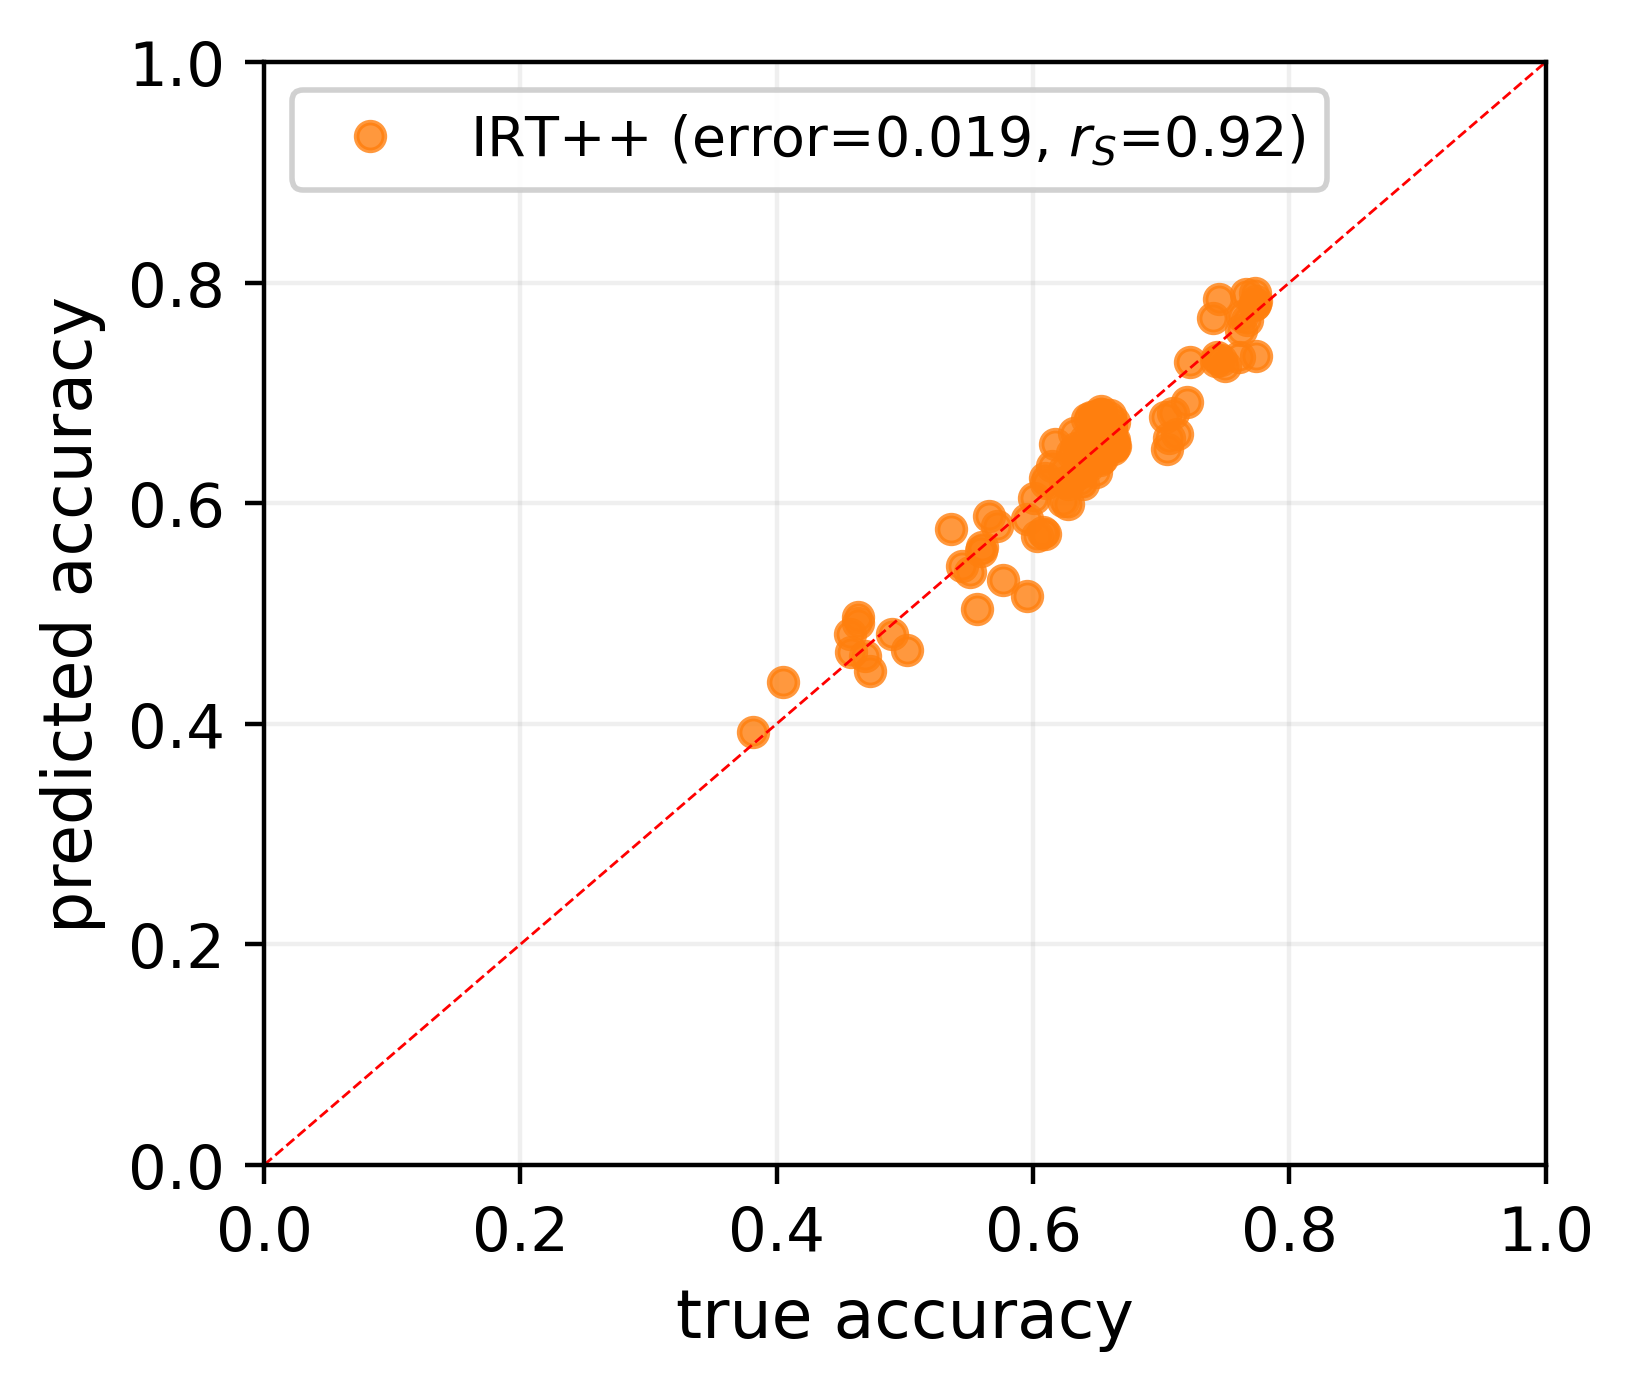
tinyBenchmarks: Efficiently Evaluating LLMs with Fewer Examples | The ...

Paper page - Rethinking LLM Evaluation: Can We Evaluate LLMs with 200x ...

Paper page - Benchmarking LLMs for Fine-Grained Code Review with ...
Advertisement Space (300x250)

Paper page - WebGen-Bench: Evaluating LLMs on Generating Interactive ...

Paper page - PATCHEVAL: A New Benchmark for Evaluating LLMs on Patching ...

Paper page - CTIBench: A Benchmark for Evaluating LLMs in Cyber Threat ...

Paper page - AgentBench: Evaluating LLMs as Agents

Paper page - AthenaBench: A Dynamic Benchmark for Evaluating LLMs in ...

Paper page - TAM-Eval: Evaluating LLMs for Automated Unit Test Maintenance

Paper page - From Tools to Teammates: Evaluating LLMs in Multi-Session ...

Paper page - LikeBench: Evaluating Subjective Likability in LLMs for ...

Paper page - Do LLMs Understand User Preferences? Evaluating LLMs On ...

Paper page - WildBench: Benchmarking LLMs with Challenging Tasks from ...
Advertisement Space (336x280)
MLLM-Bench: Evaluating Multimodal LLMs with Per-sample Criteria | AI ...

Paper page - Less is More for Long Document Summary Evaluation by LLMs

Paper page - LLMeBench: A Flexible Framework for Accelerating LLMs ...

Paper page - DOCBENCH: A Benchmark for Evaluating LLM-based Document ...

Paper page - SmartPlay : A Benchmark for LLMs as Intelligent Agents

Paper page - Have LLMs Advanced Enough? A Challenging Problem Solving ...

Paper page - ClassEval: A Manually-Crafted Benchmark for Evaluating ...

Paper page - Benchmarking LLMs via Uncertainty Quantification

Paper page - CriticBench: Benchmarking LLMs for Critique-Correct Reasoning

Paper page - StackEval: Benchmarking LLMs in Coding Assistance
Advertisement Space (336x280)

Paper page - Are LLMs Better than Reported? Detecting Label Errors and ...

Paper page - Are LLMs Better than Reported? Detecting Label Errors and ...

Paper page - When LLMs Struggle: Reference-less Translation Evaluation ...

Paper page - GISTBench: Evaluating LLM User Understanding via Evidence ...

Paper page - ResearchCodeBench: Benchmarking LLMs on Implementing Novel ...

Paper page - CrossWordBench: Evaluating the Reasoning Capabilities of ...