
Tinybenchmarks Evaluating Llms With Fewer Examples Ai Research Paper

tinyBenchmarks: evaluating LLMs with fewer examples | AI Research Paper ...

Paper page - tinyBenchmarks: evaluating LLMs with fewer examples
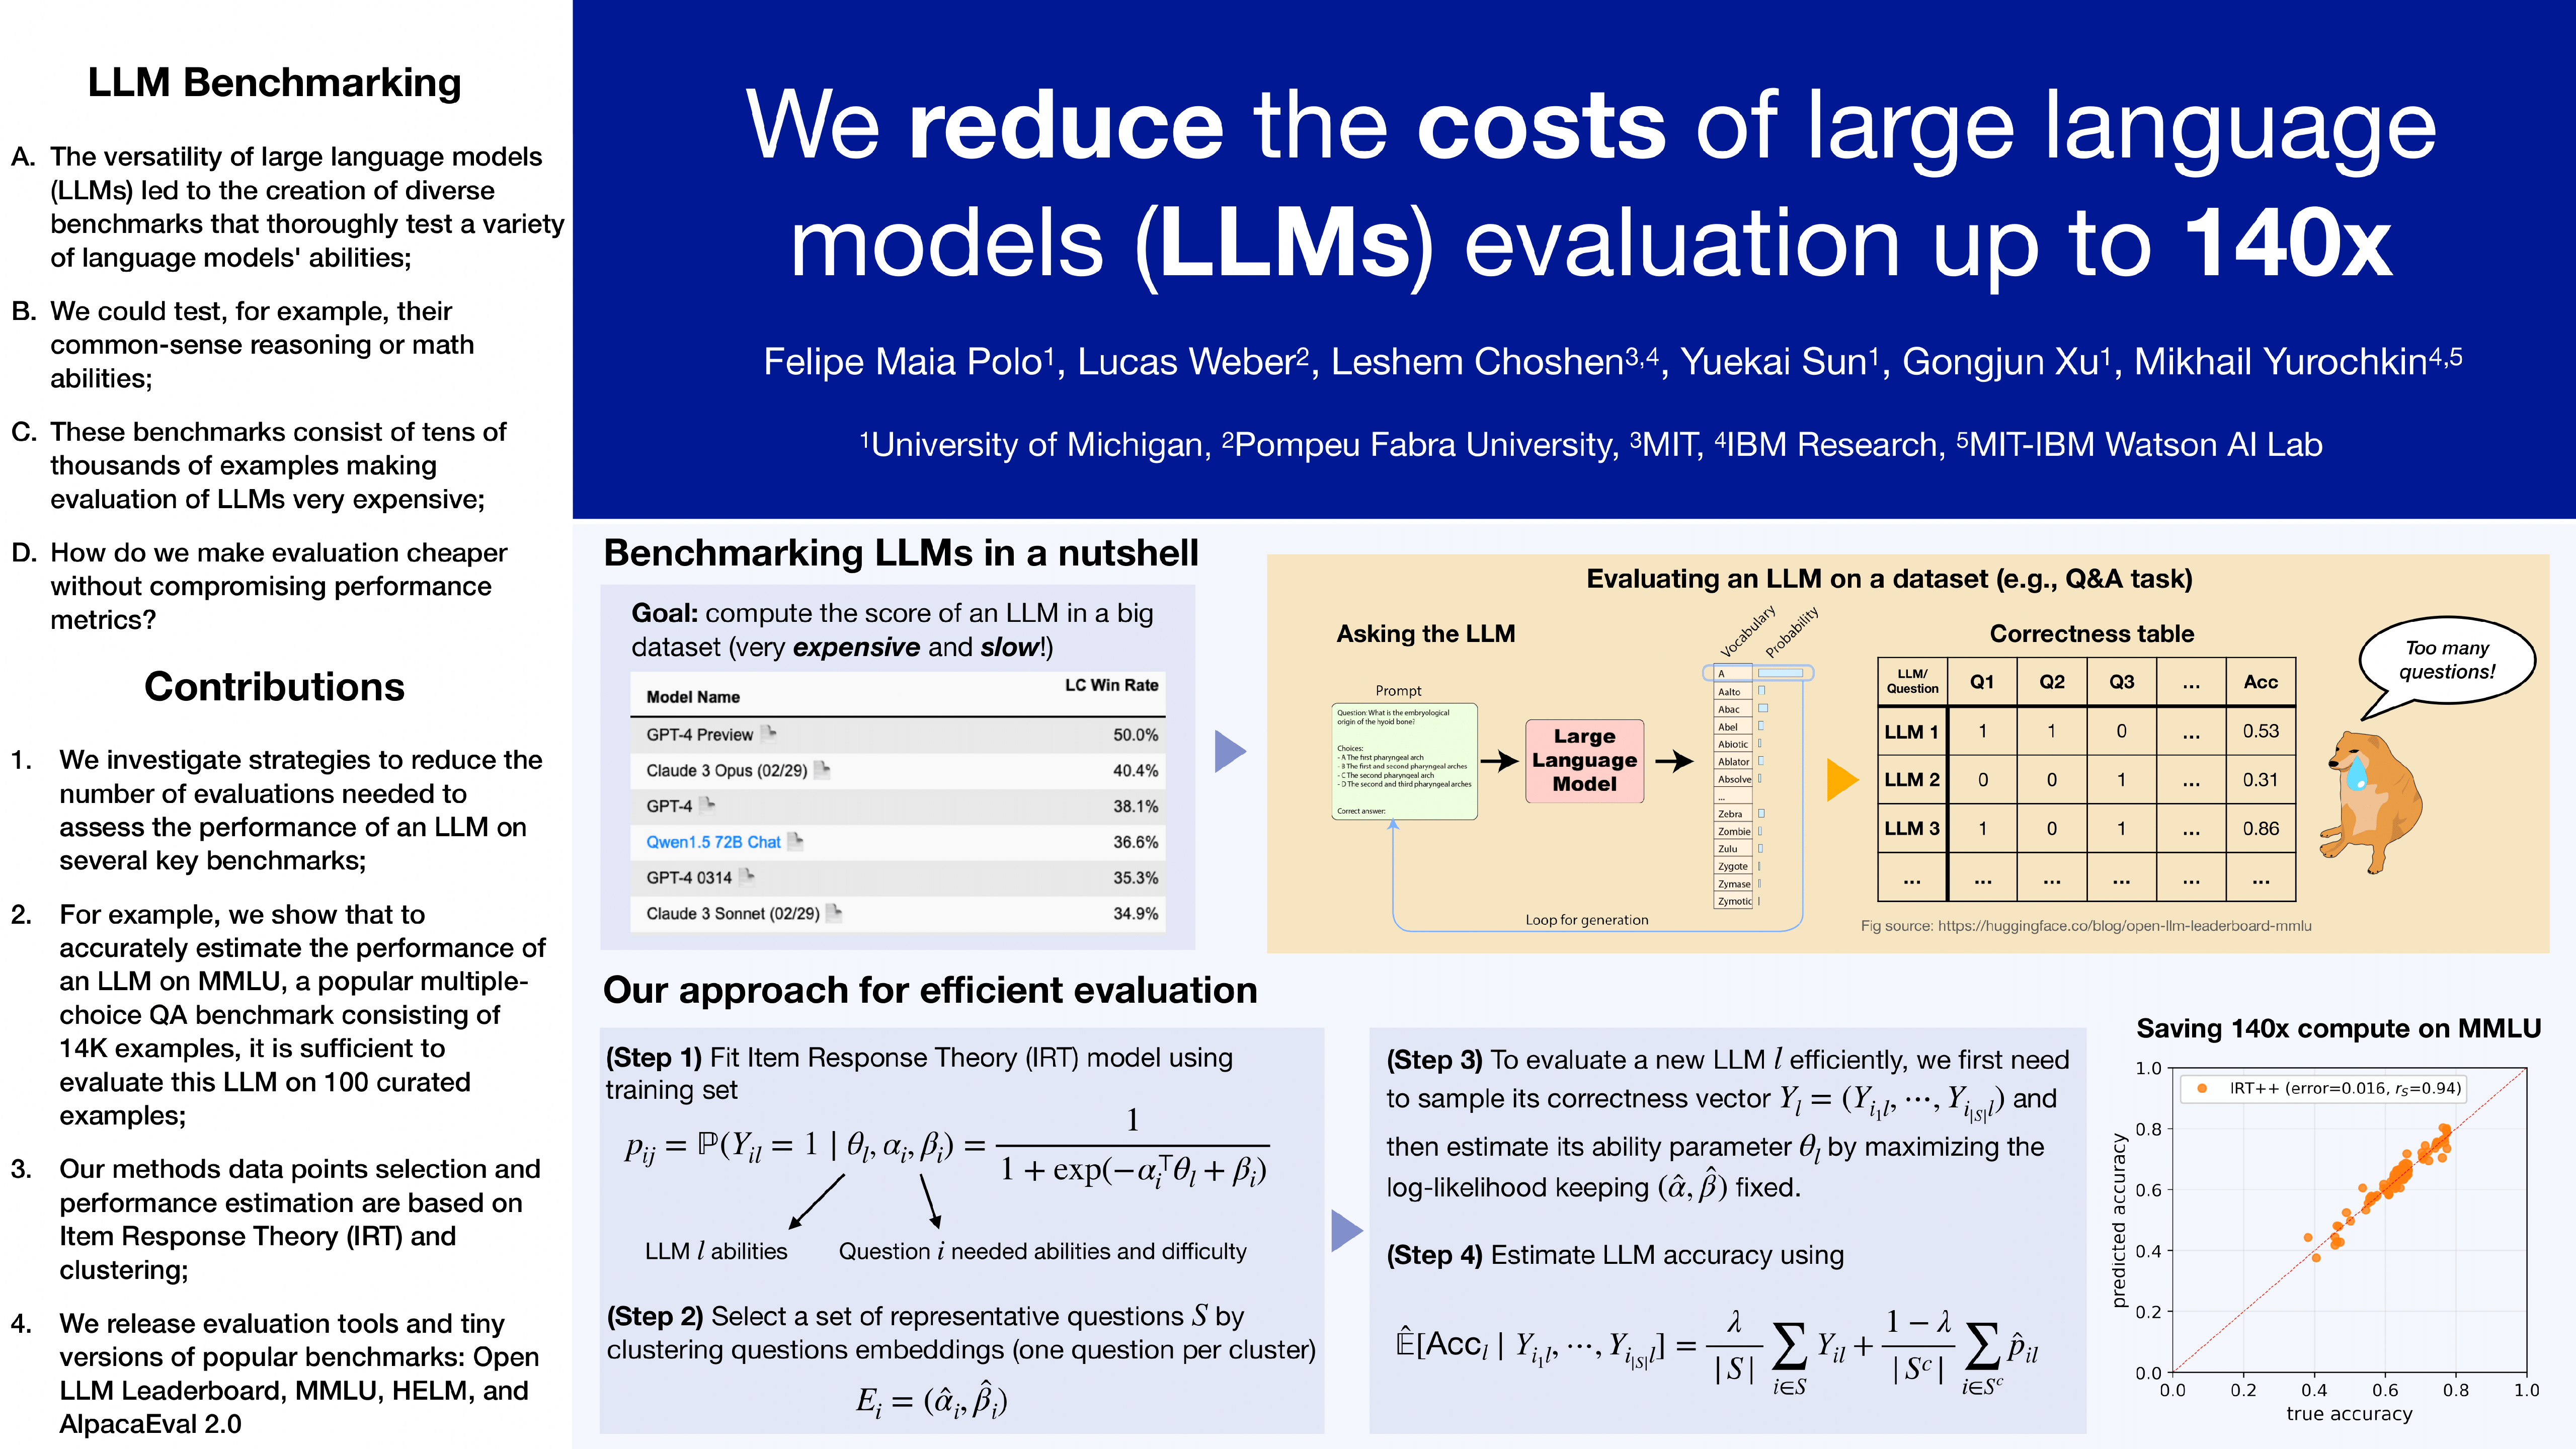
ICML Poster tinyBenchmarks: evaluating LLMs with fewer examples

(PDF) tinyBenchmarks: evaluating LLMs with fewer examples
tinyBenchmarks: Efficiently Evaluating LLMs with Fewer Examples | The ...

tinyBenchmarks: evaluating LLMs with fewer examples
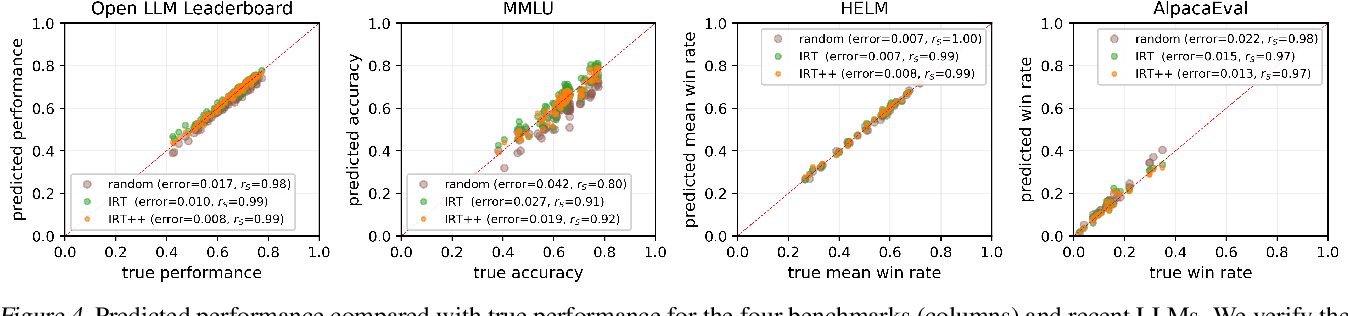
Figure 4 from tinyBenchmarks: evaluating LLMs with fewer examples ...
MLLM-Bench: Evaluating Multimodal LLMs with Per-sample Criteria | AI ...

Efficient multi-prompt evaluation of LLMs | AI Research Paper Details

Easy Problems That LLMs Get Wrong | AI Research Paper Details
Advertisement Space (300x250)

LLMs for Explainable AI: A Comprehensive Survey | AI Research Paper Details

EVOLvE: Evaluating and Optimizing LLMs For Exploration | AI Research ...

Evaluation and Benchmarking of LLM Agents: A Survey | AI Research Paper ...

TAM-Eval: Evaluating LLMs for Automated Unit Test Maintenance | AI ...

Paper page - AthenaBench: A Dynamic Benchmark for Evaluating LLMs in ...

MLR-Bench: Evaluating AI Agents on Open-Ended Machine Learning Research ...

How can we evaluate LLMs during training? 🤔 Evaluating LLMs on common ...
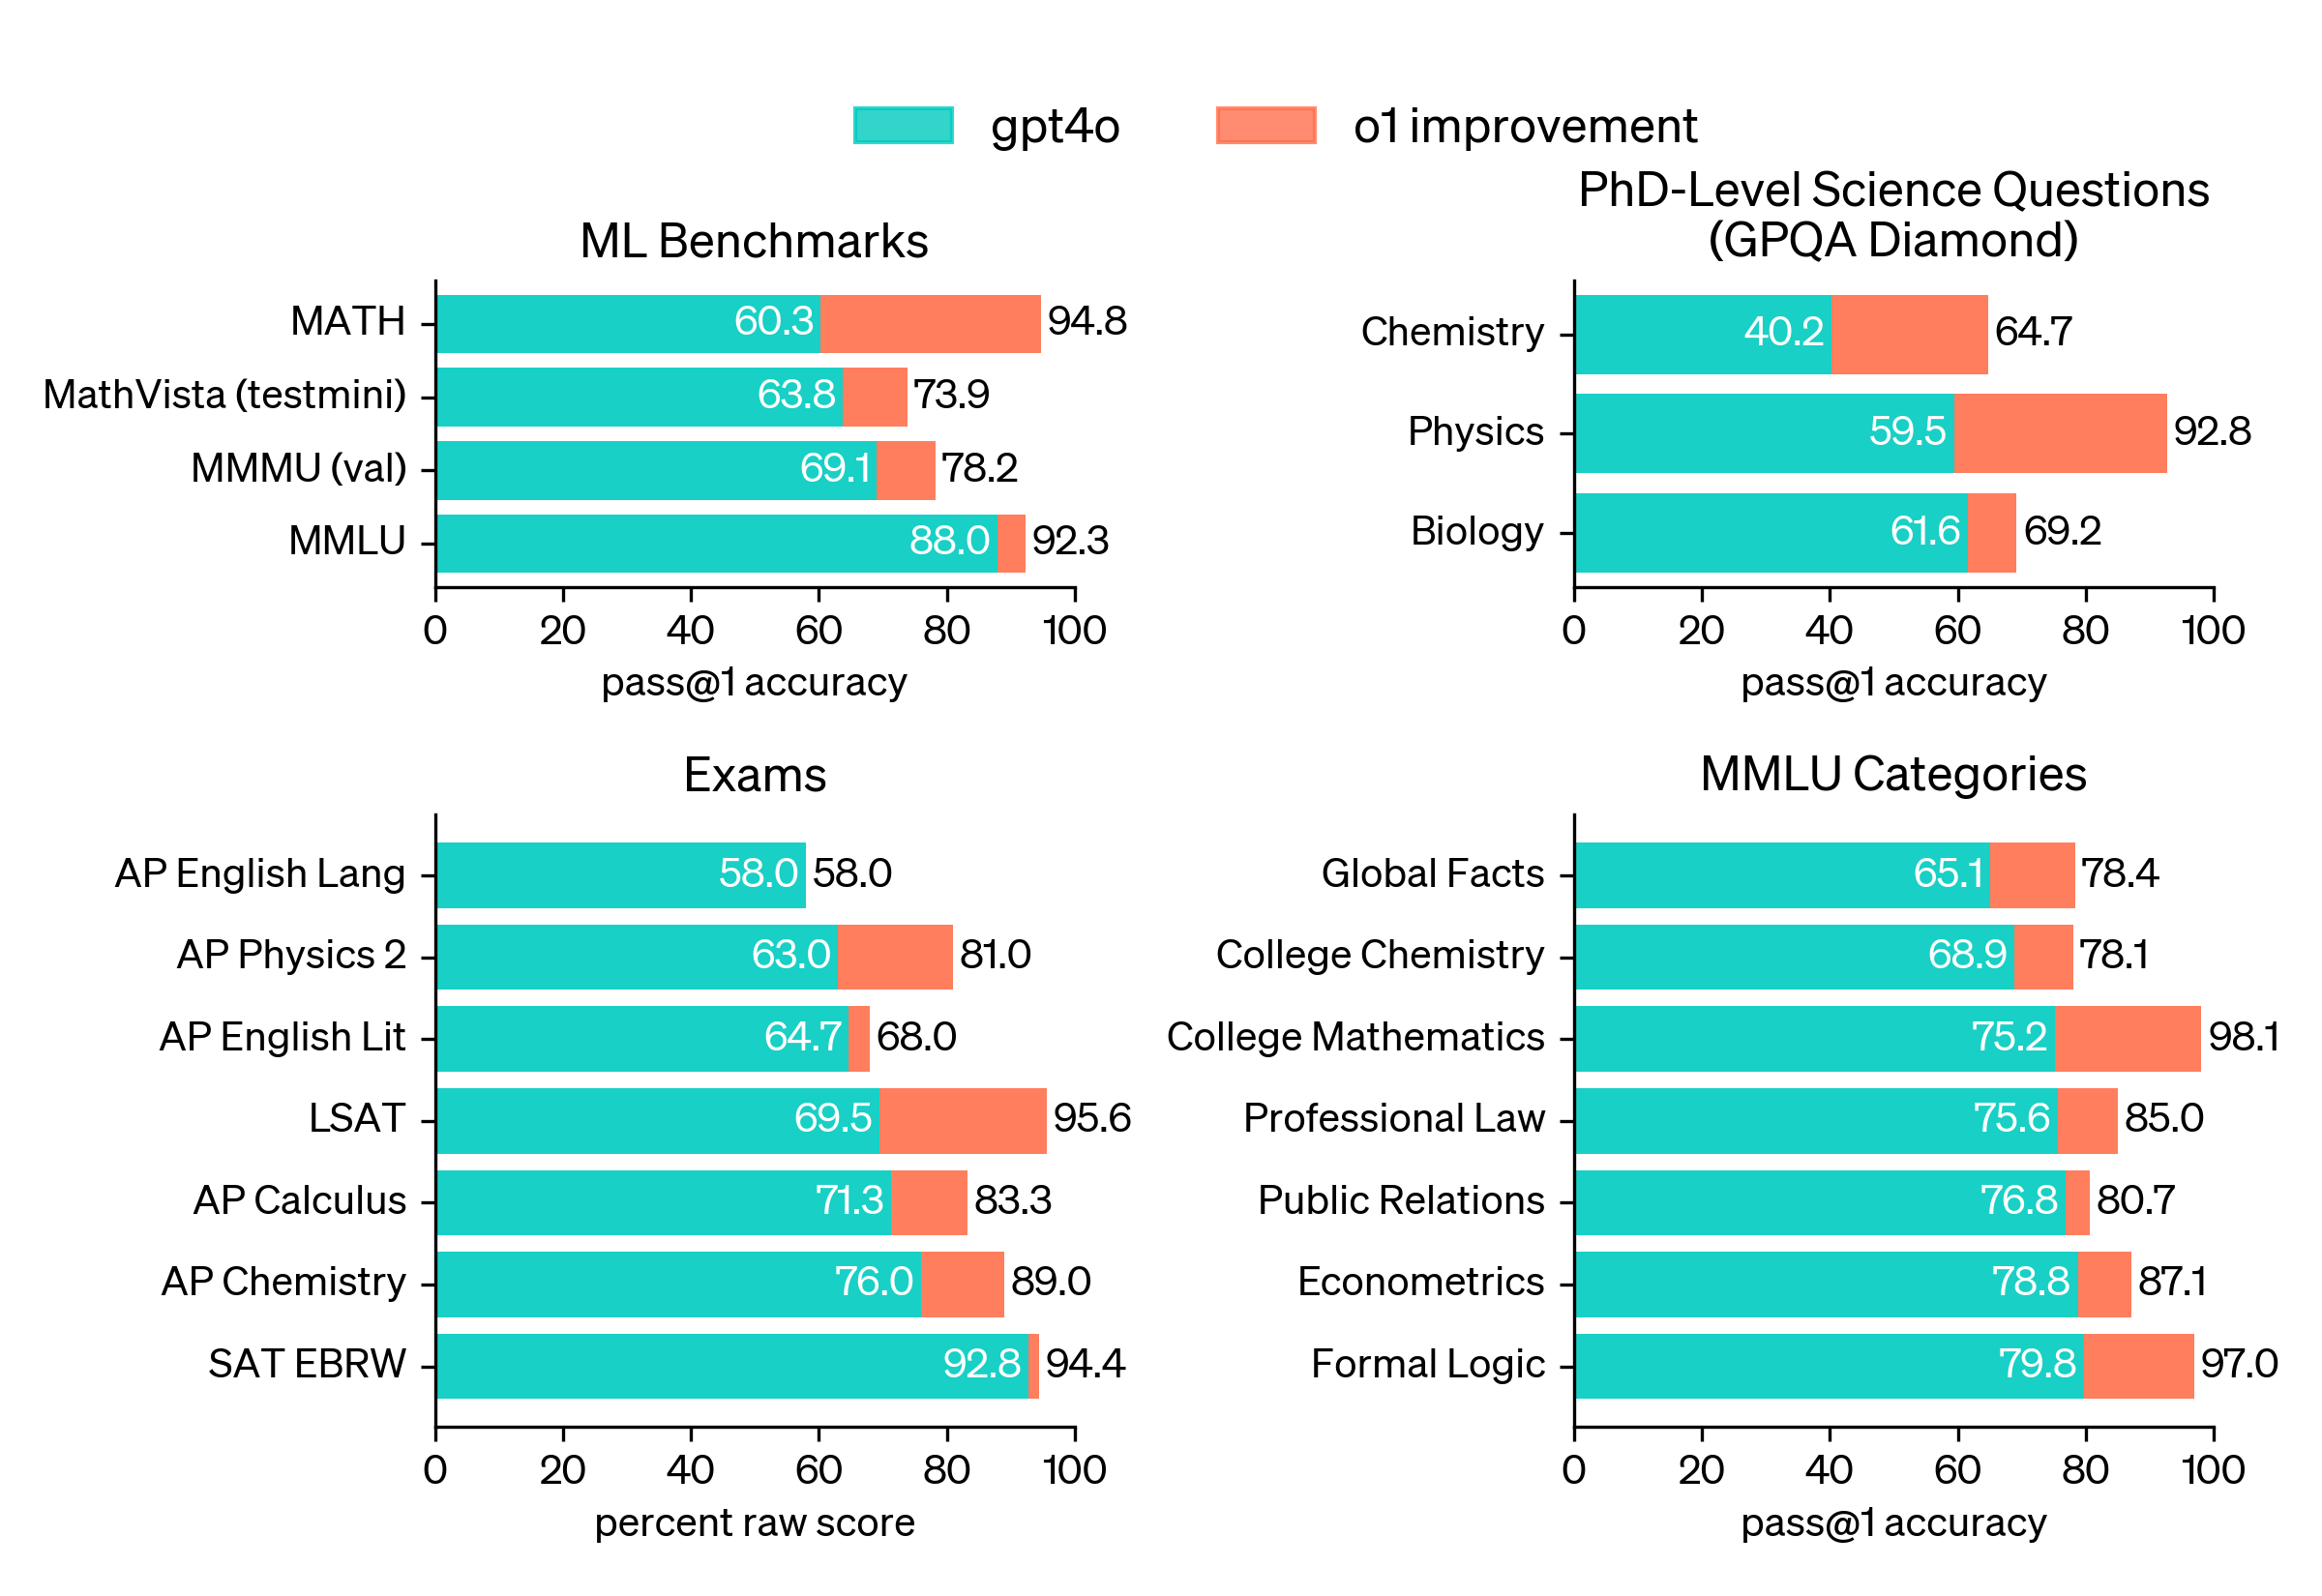
Learning to reason with LLMs | OpenAI

Meeseeks: An Iterative Benchmark Evaluating LLMs Multi-Turn Instruction ...

CTIBench - A Benchmark For Evaluating LLMs in Cyber Threat ...
Advertisement Space (336x280)

When Benchmarks Talk: Re-Evaluating Code LLMs with Interactive Feedback ...

Key Benchmarks for Evaluating LLMs | PDF | Learning | Cognition

Evaluating Test-Time Scaling LLMs for Legal Reasoning: OpenAI o1 ...
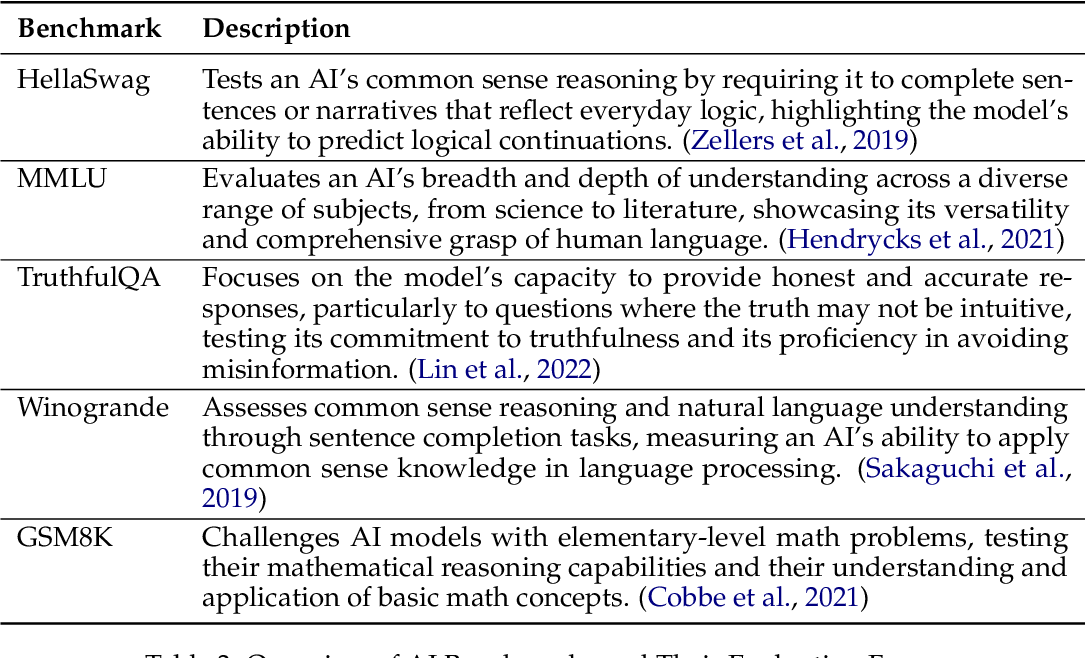
Table 3 from Evaluating LLMs at Evaluating Temporal Generalization ...
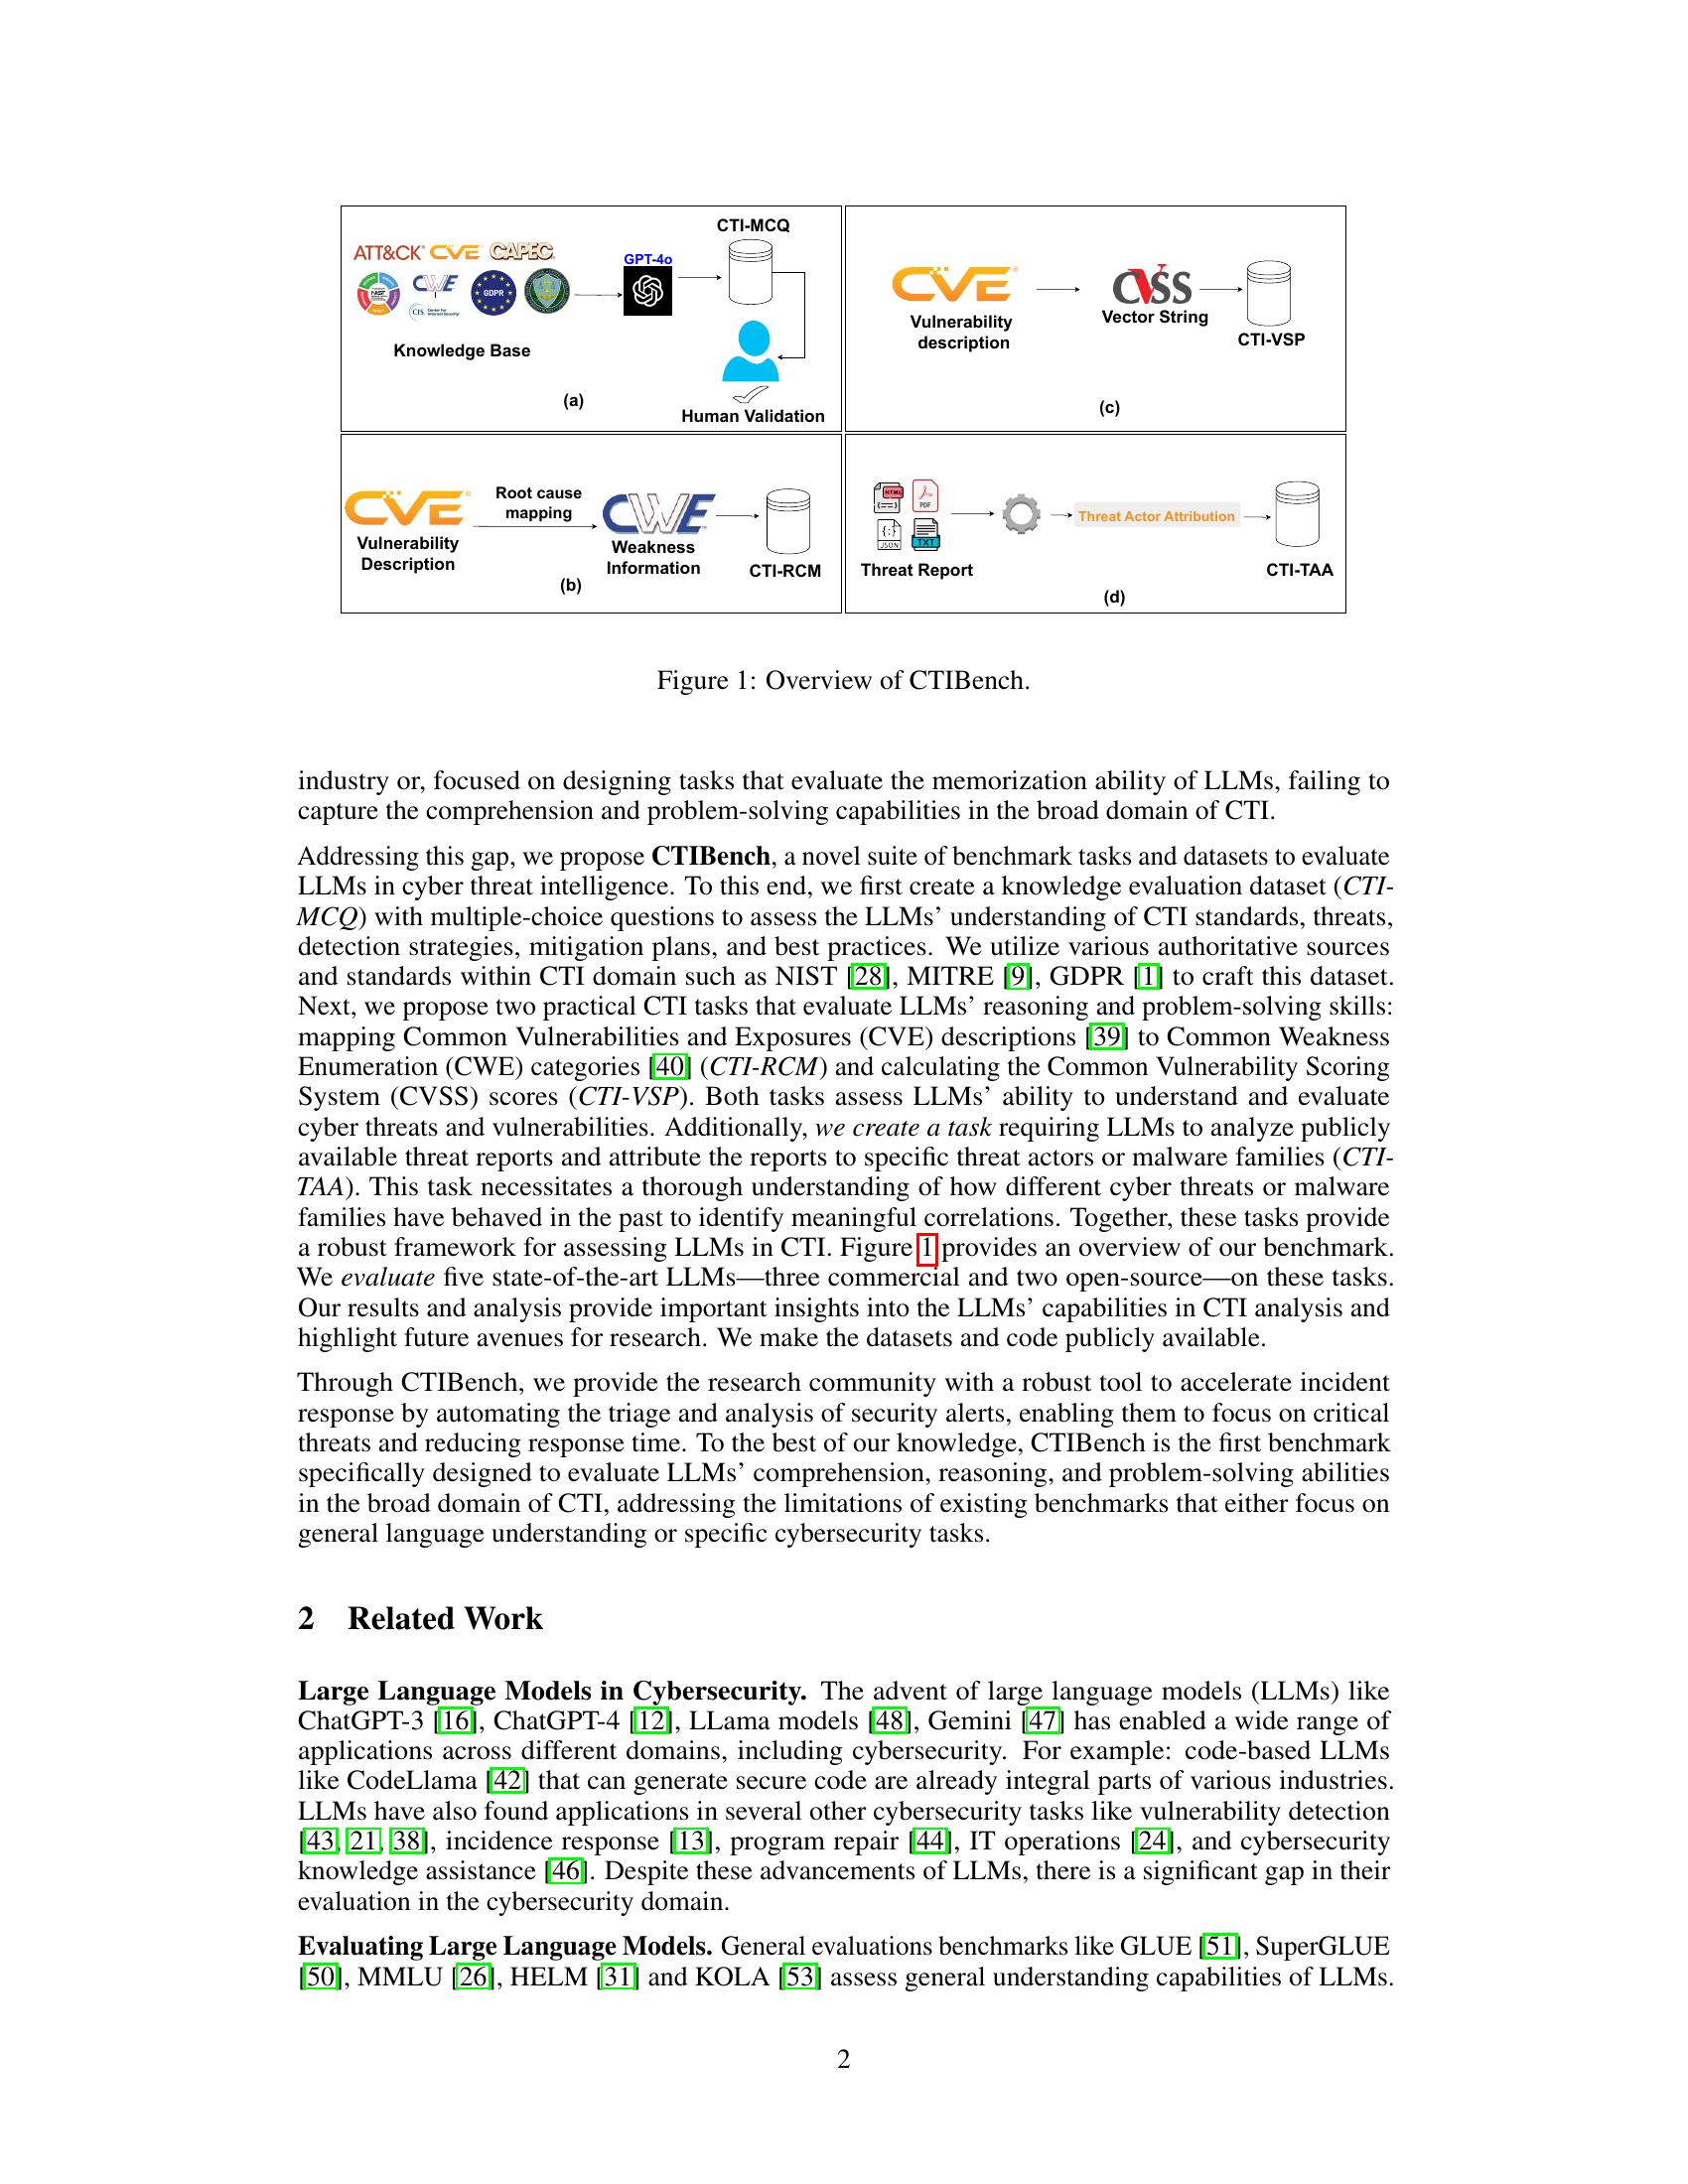
CTIBench: A Benchmark for Evaluating LLMs in Cyber Threat Intelligence ...

Evaluating the Effectiveness of LLMs in Introductory Computer Science ...

From Prompts to Performance: Evaluating LLMs for Task-based Parallel ...
Enterprise AI Benchmarking: A Practical Guide to Evaluating Rule-Based ...
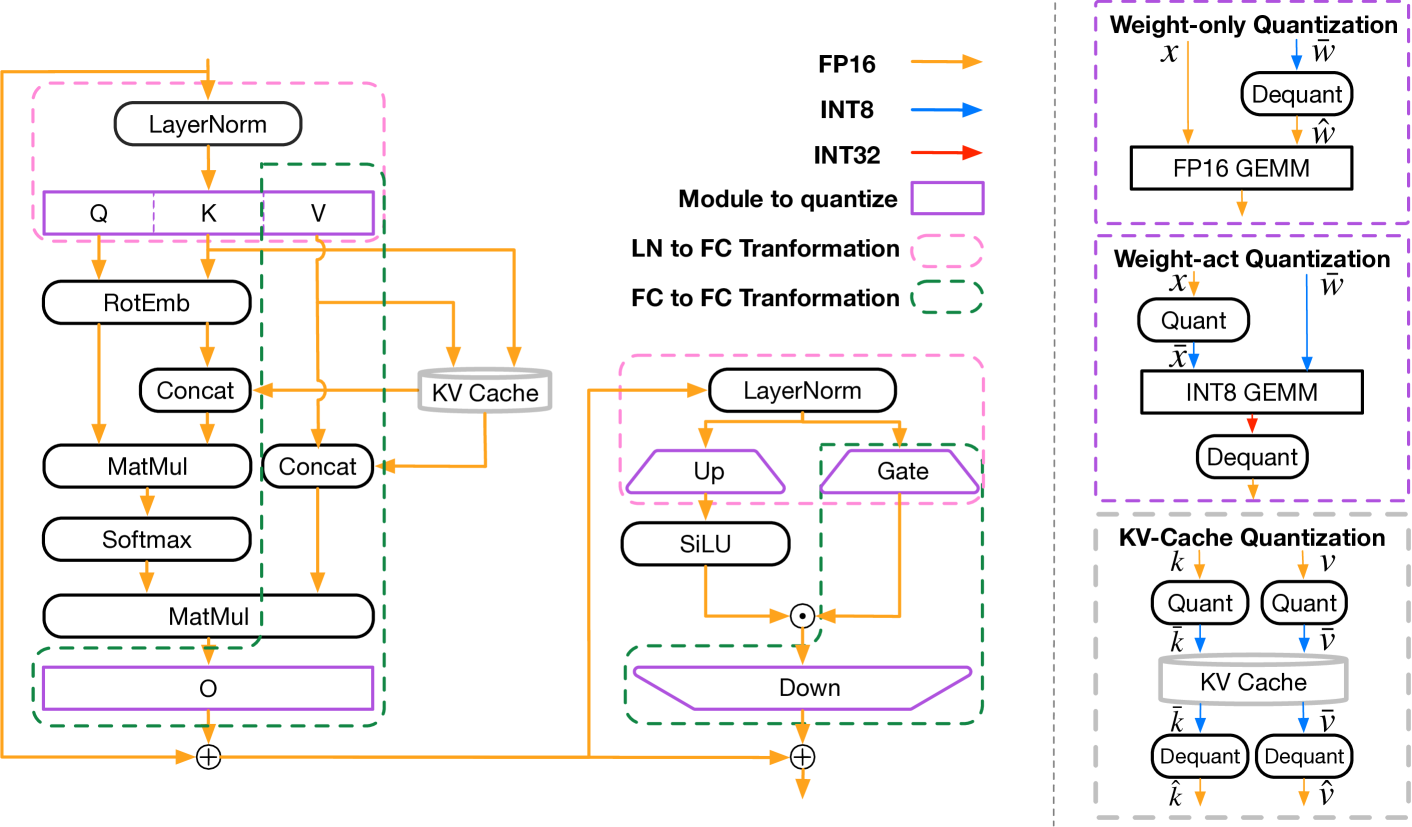
MobileAIBench: Benchmarking LLMs and LMMs for On-Device Use Cases | AI ...
[논문리뷰] CTIBench: A Benchmark for Evaluating LLMs in Cyber Threat ...
Advertisement Space (336x280)
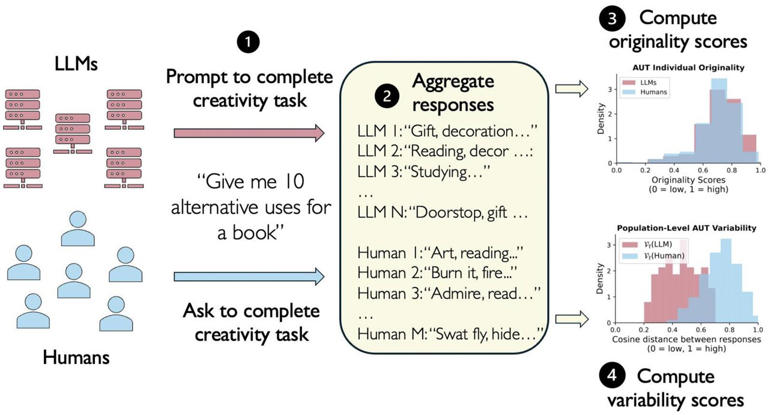
LLMs and creativity: AI responses show less variety than human ones

Comparing Open-source and Proprietary LLMs in Medical AI
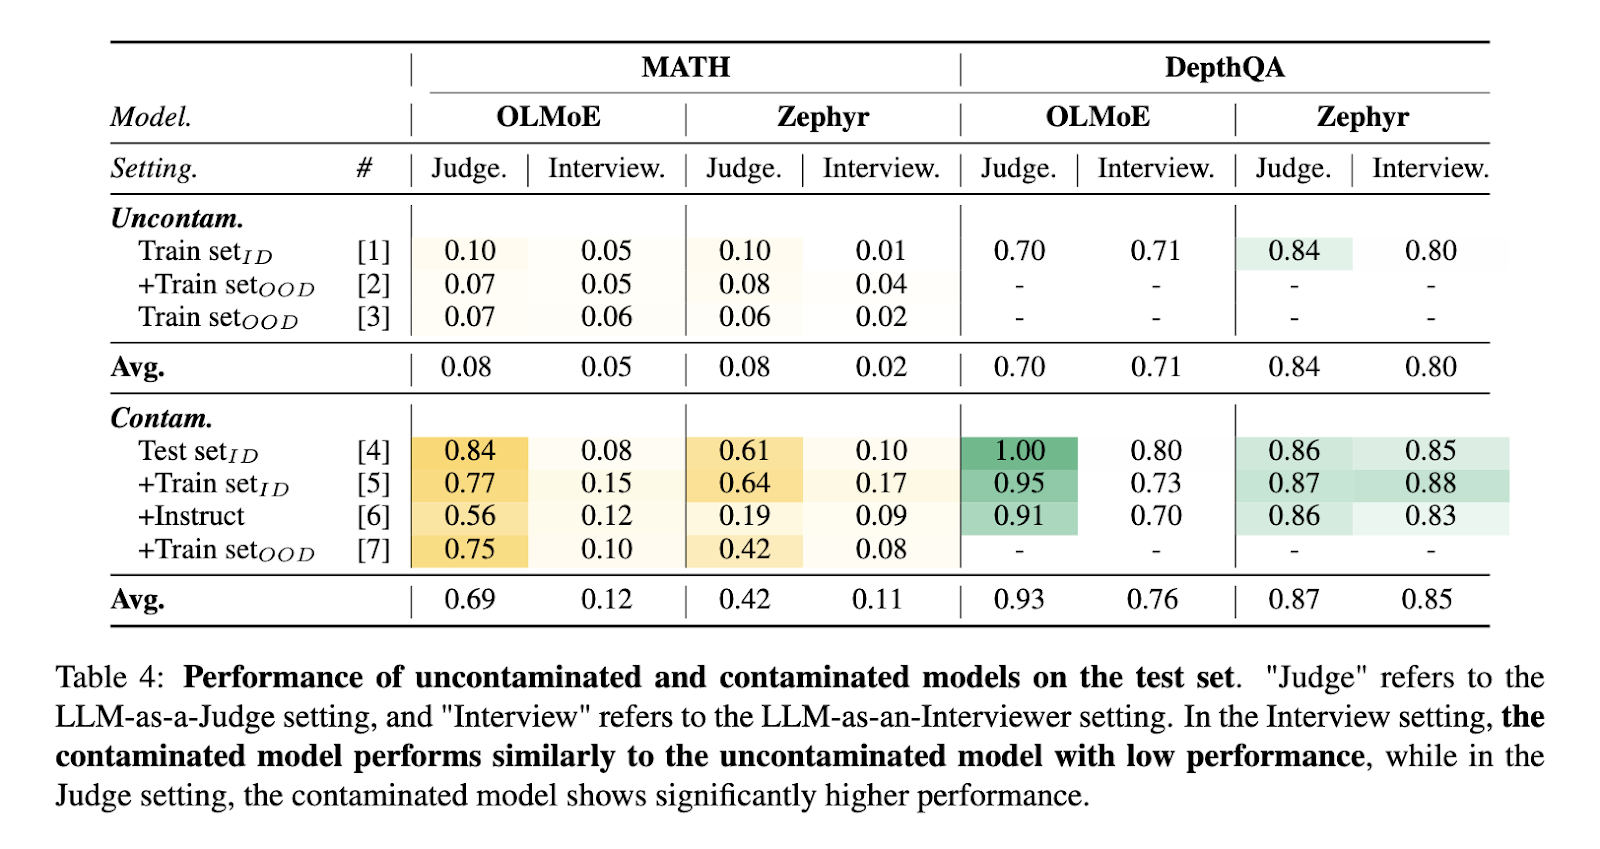
This AI Paper Introduces LLM-as-an-Interviewer: A Dynamic AI Framework ...
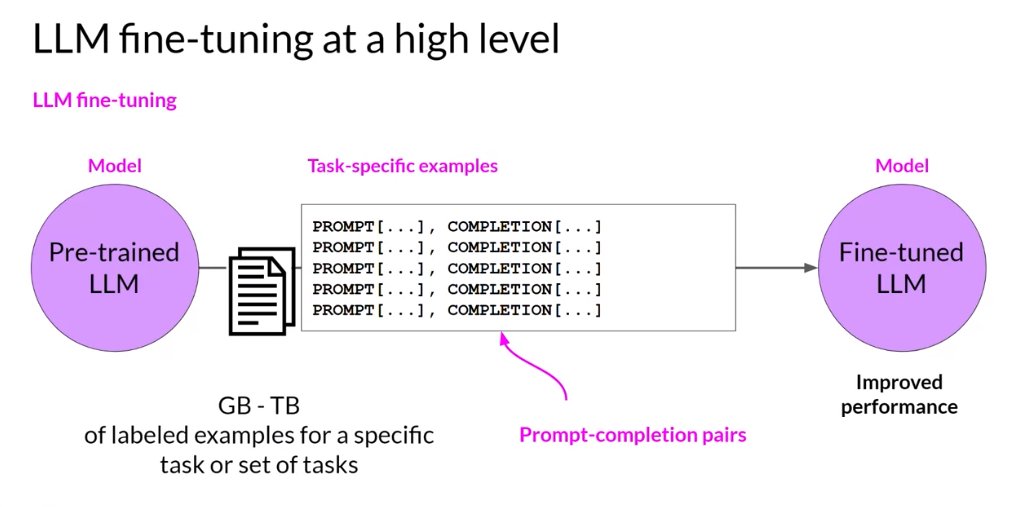
Introduction to LLMs and the generative AI : Part 3— Fine Tuning LLM ...

Benchmark^2: Systematic Evaluation of LLM Benchmarks | AI Research ...
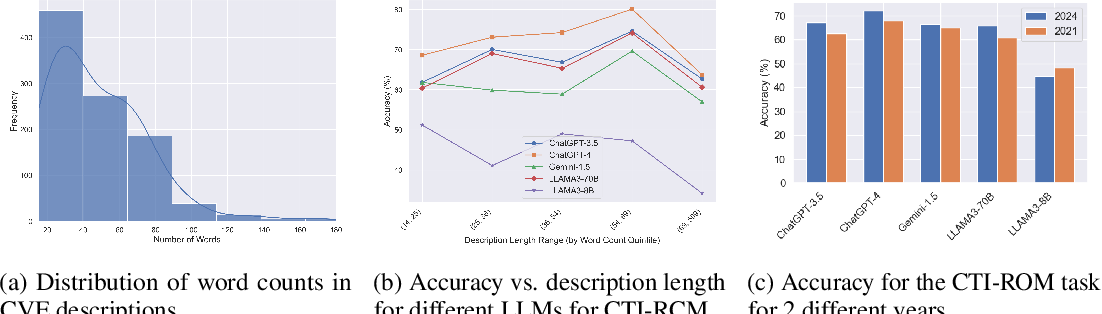
Figure 3 from CTIBench: A Benchmark for Evaluating LLMs in Cyber Threat ...