
Github Quantumaikrquantcpp Llm Inference With 7x Longer Context
GitHub - quantumaikr/quant.cpp: LLM inference with 7x longer context ...

Near-Lossless Acceleration of Long Context LLM Inference with Adaptive ...

GitHub - NVIDIA/Star-Attention: Efficient LLM Inference over Long ...
GitHub - sunzx/llama-cpp-turboquant: LLM inference in C/C++ · GitHub

LLM Inference: Accelerating Long Context Generation with KV Cache ...
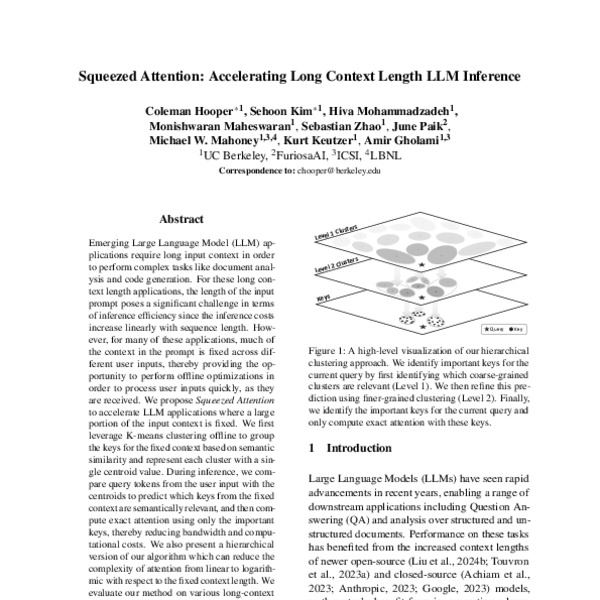
Squeezed Attention: Accelerating Long Context Length LLM Inference ...

Infinite-LLM: Efficient LLM Service for Long Context with DistAttention ...
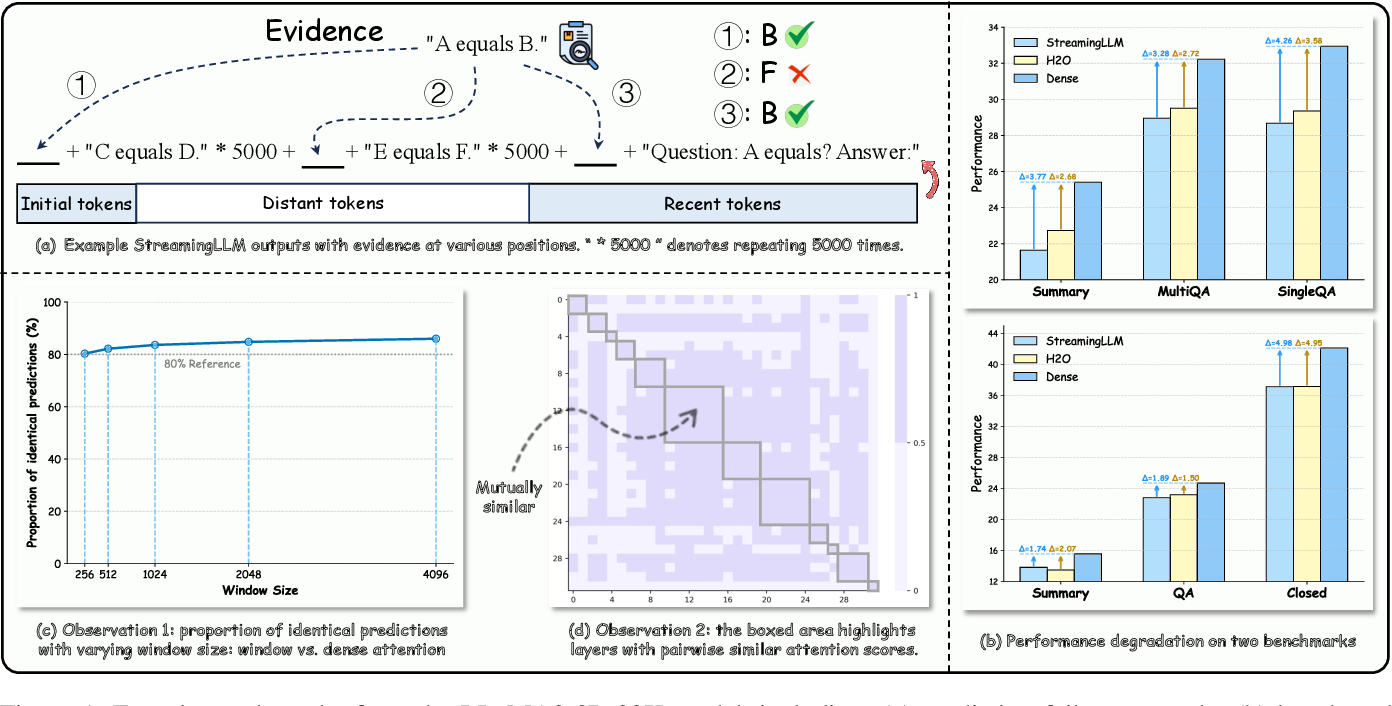
Figure 1 from Compressing KV Cache for Long-Context LLM Inference with ...

Accelerating Long-Context LLM Inference Eightfold with FlashAttention ...
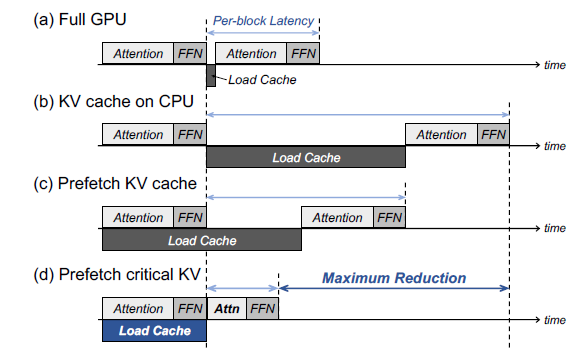
LLM Inference: Accelerating Long Context Generation with KV Cache ...
Advertisement Space (300x250)
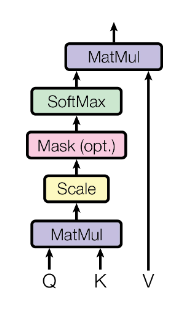
Understanding how LLM inference works with llama.cpp

Infinite-LLM: Efficient LLM Service for Long Context with DistAttention ...

LazyLLM: Dynamic Token Pruning for Efficient Long Context LLM Inference

HGCA: Hybrid GPU-CPU Attention for Long Context LLM Inference | AI ...
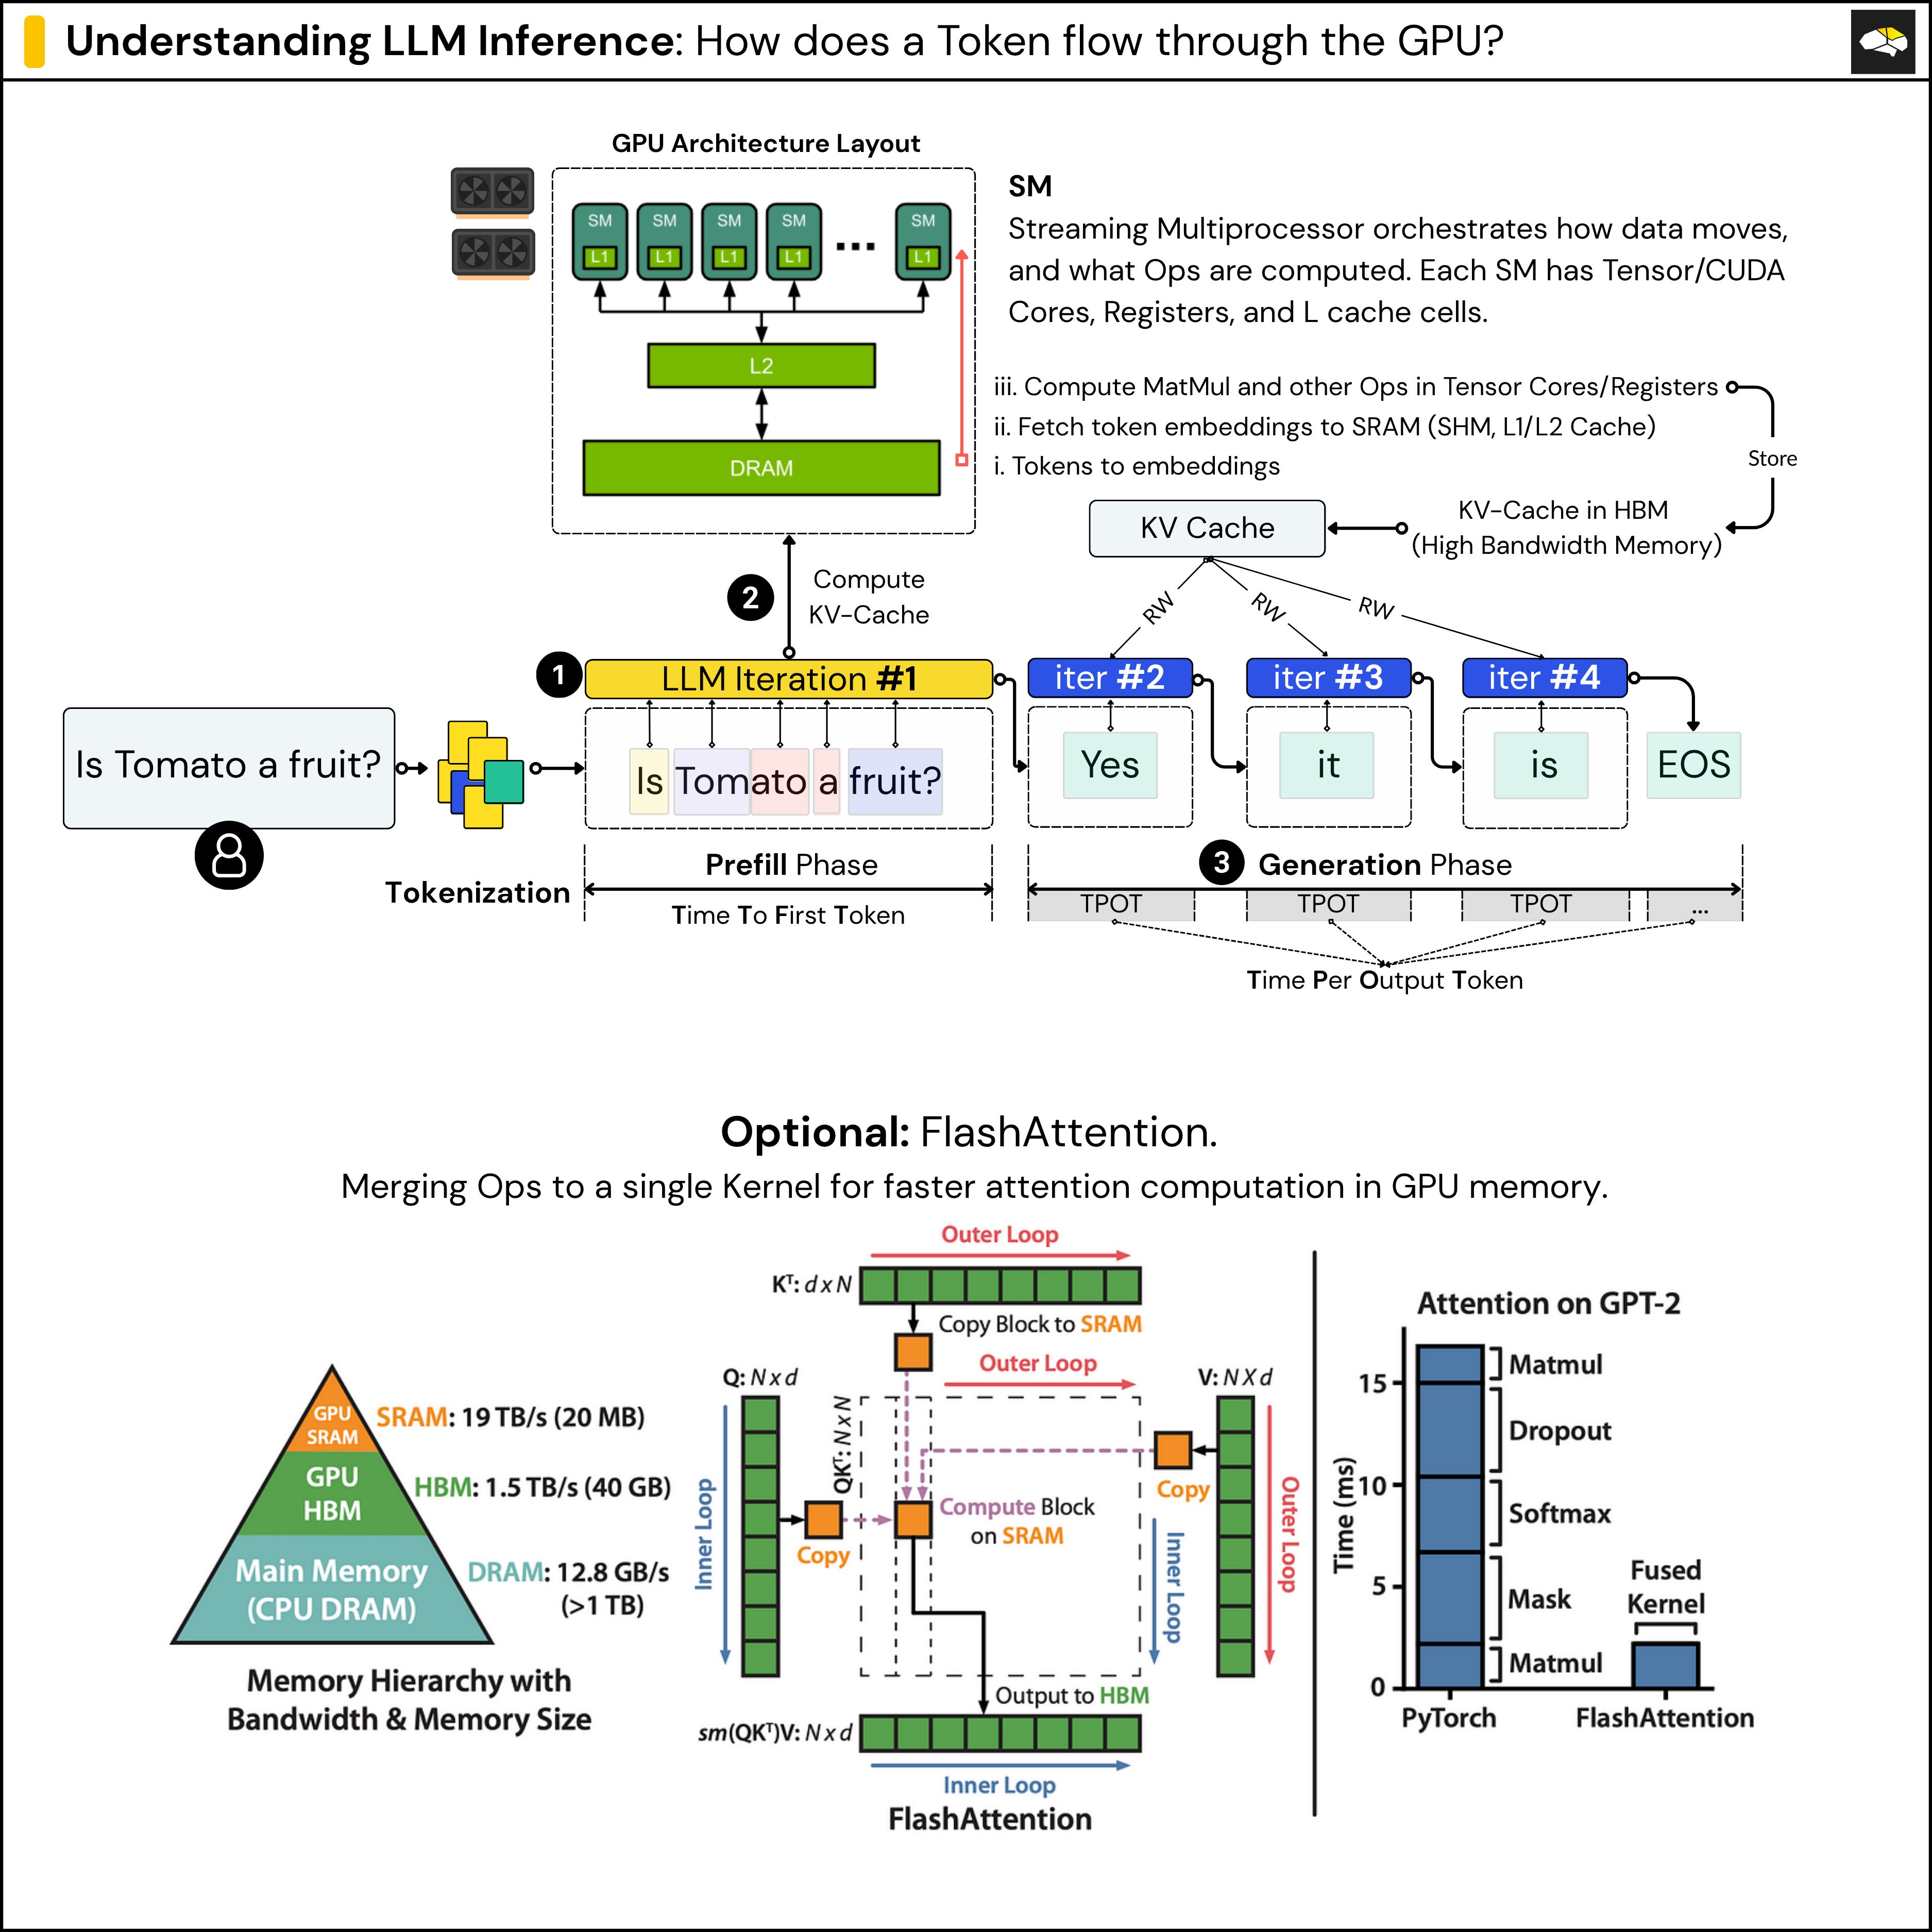
Understanding LLM Inference - by Alex Razvant

MILLION: Mastering Long-Context LLM Inference Via Outlier-Immunized KV ...
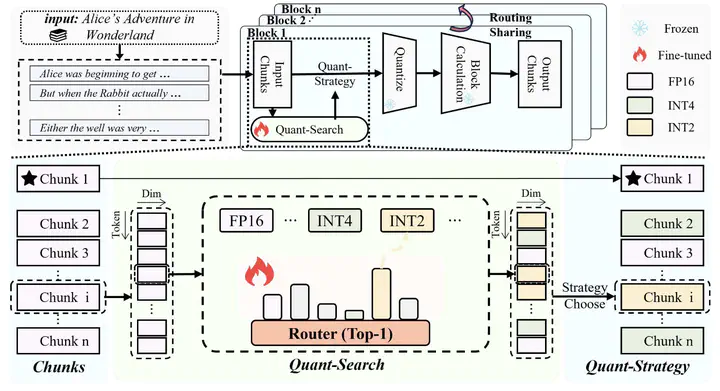
MoQAE: Mixed-Precision Quantization for Long-Context LLM Inference via ...

Star Attention: Efficient LLM Inference over Long Sequences · HF Daily ...
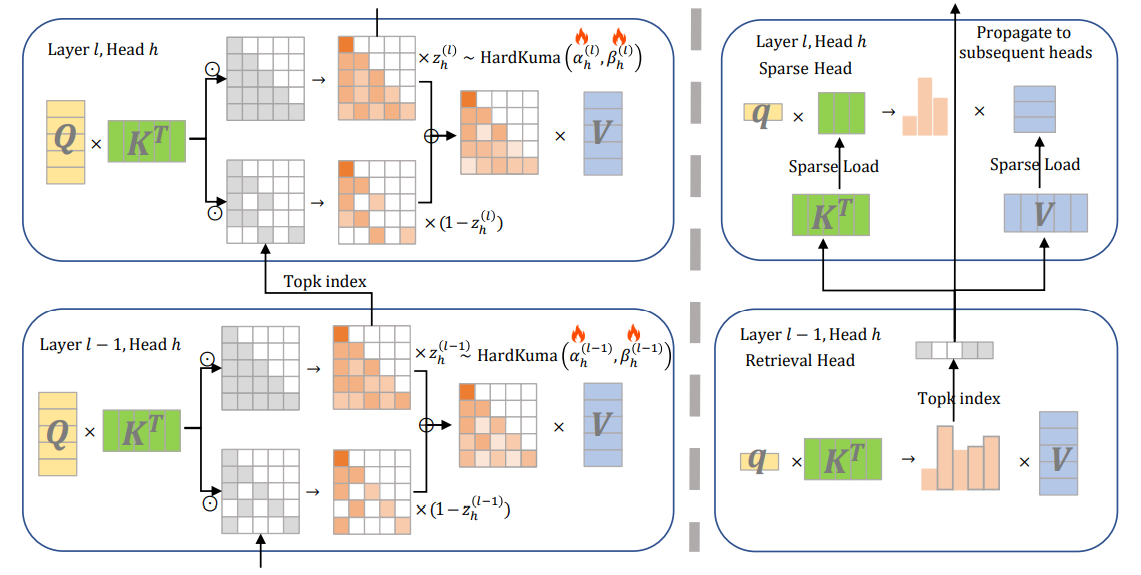
LycheeDecode: Accelerating Long-Context LLM Inference via Hybrid-Head ...
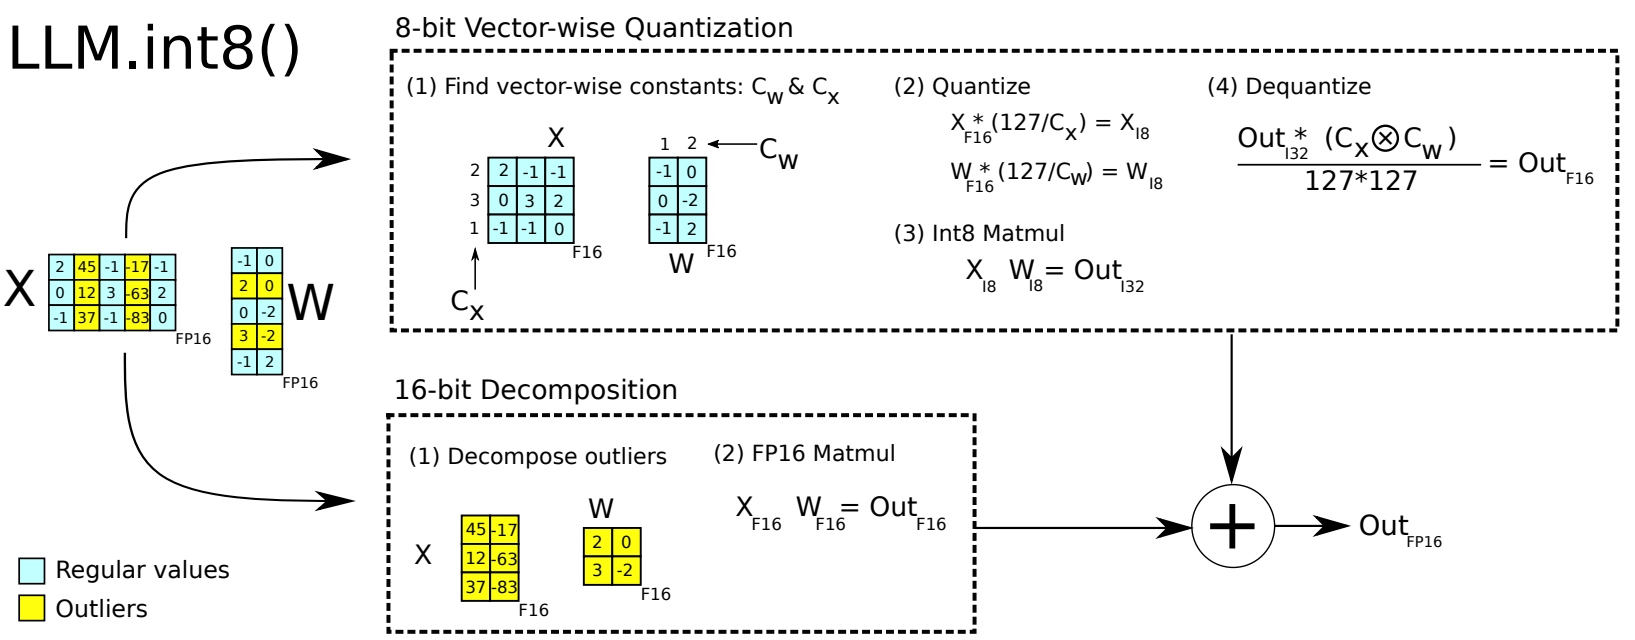
20. Inference Acceleration (WIP) — LLM Foundations
Advertisement Space (336x280)
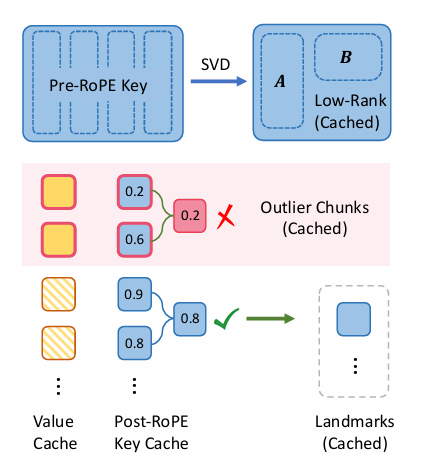
ShadowKV: A High-Throughput Inference System for Long-Context LLM ...
AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...
MoQAE: Mixed-Precision Quantization for Long-Context LLM Inference via ...
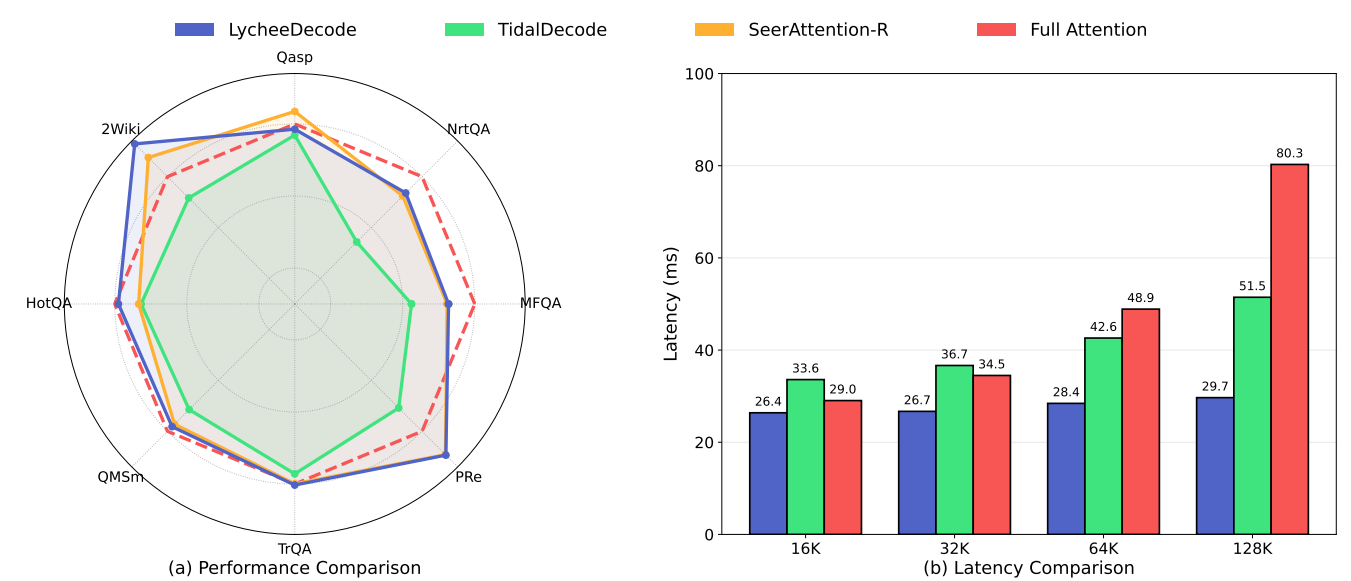
LycheeDecode: Accelerating Long-Context LLM Inference via Hybrid-Head ...

Paper page - Squeezed Attention: Accelerating Long Context Length LLM ...
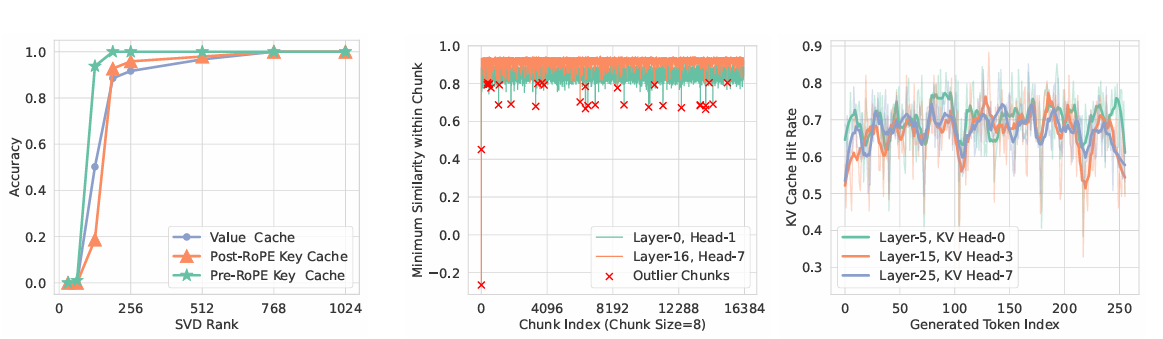
ShadowKV: A High-Throughput Inference System for Long-Context LLM ...

Star Attention: Efficient LLM Inference over Long Sequences | AI ...
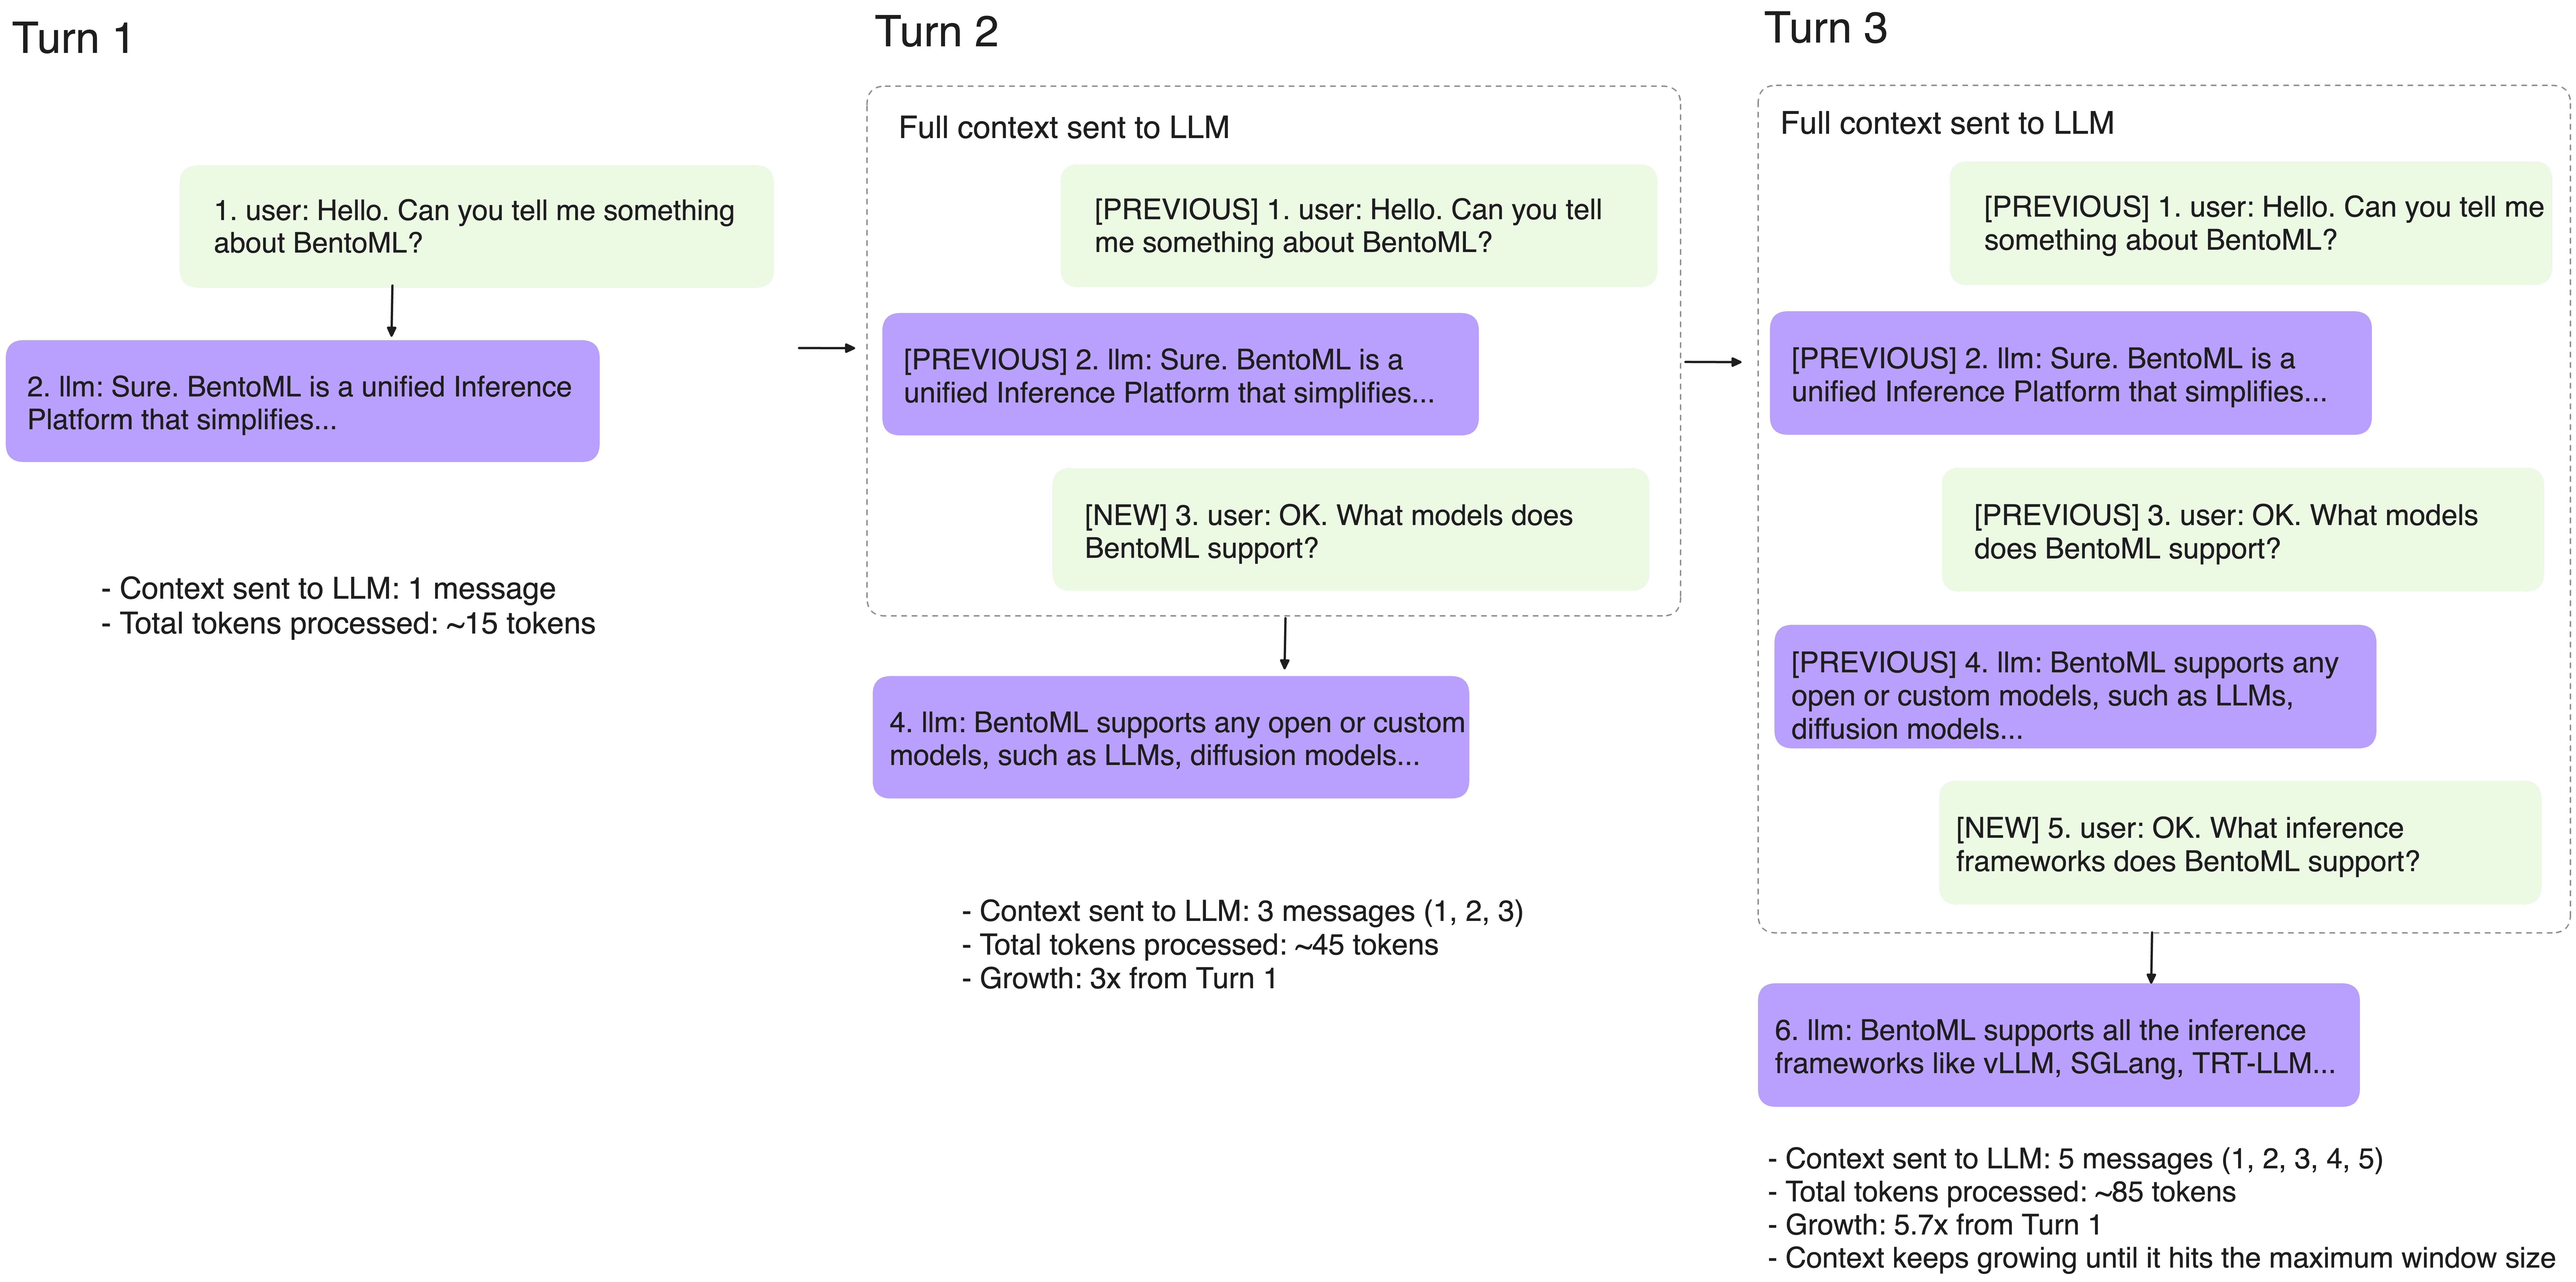
What is GPU Memory and Why it Matters for LLM Inference

GemFilter: A Novel AI Approach to Accelerate LLM Inference and Reduce ...

LLM inference optimization: Model Quantization and Distillation - YouTube
Advertisement Space (336x280)

Pushing the Limits of LLM Inference via 2-Bit Layer-Discriminative KV ...
GitHub - aivrar/multi-turboquant: Unified KV cache compression for LLM ...

GitHub - IBM/3D-CiM-LLM-Inference-Simulator: Simulator for LLM ...
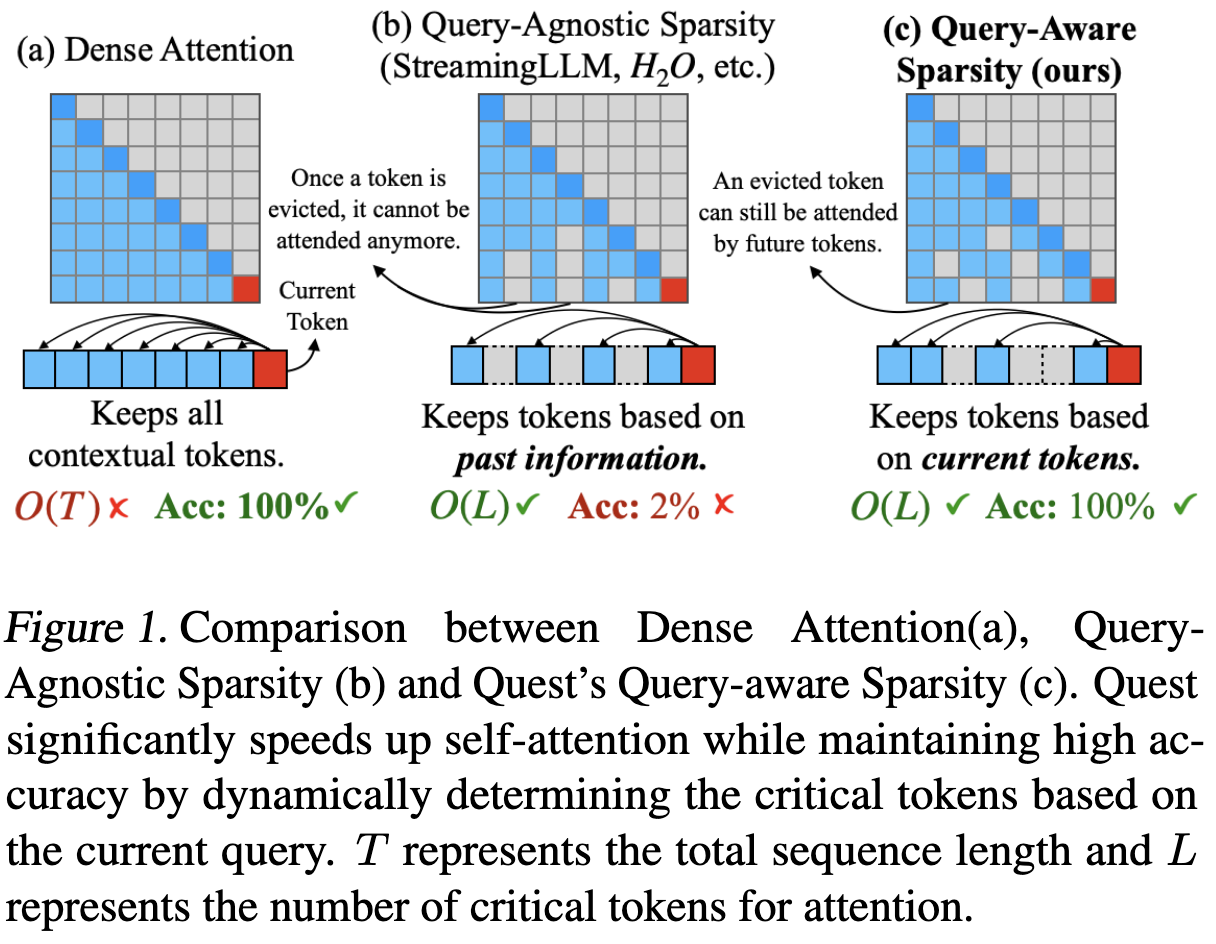
Quest Query-Aware Sparsity for Efficient Long-Context LLM Inference ...

LycheeDecode: Accelerating Long-Context LLM Inference via Hybrid-Head ...

RetrievalAttention: Accelerating Long-Context LLM Inference via Vector ...