
Kv Cache Inference Memory Bottleneck Llm Construction Theorempath
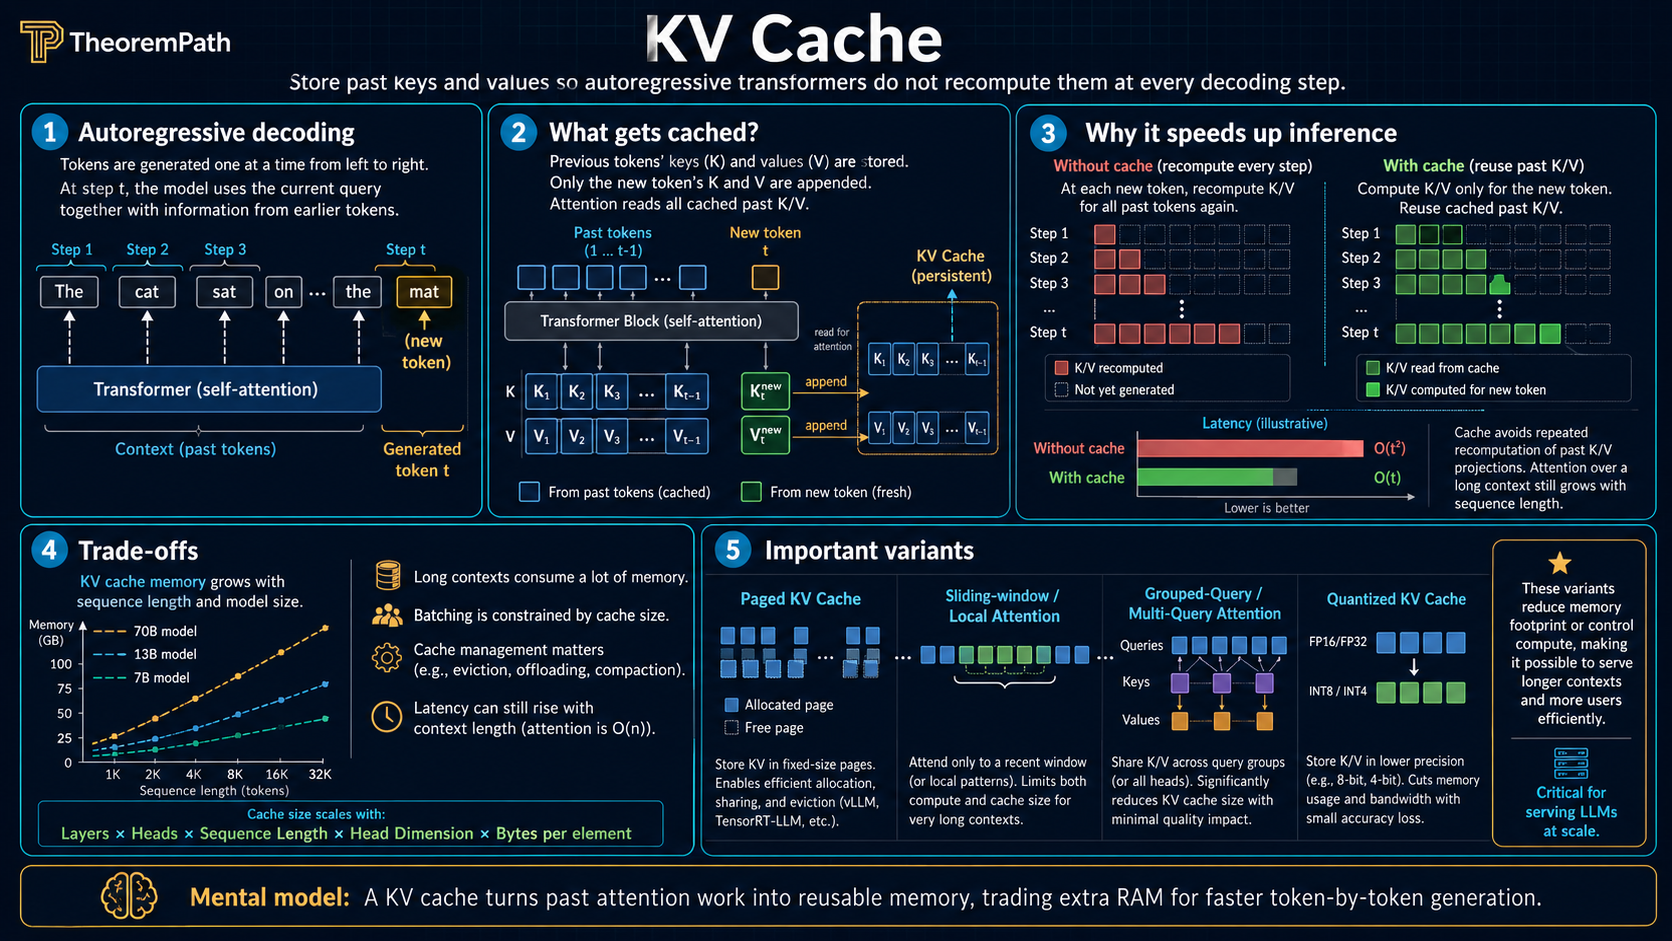
KV Cache. Inference Memory Bottleneck. LLM Construction | TheoremPath

LLM Inference Bottleneck: KV Cache vs GPU Memory | Osama Altaf posted ...

LLM Inference Bottleneck: KV Cache vs Model Weights | Vinjam ...
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...
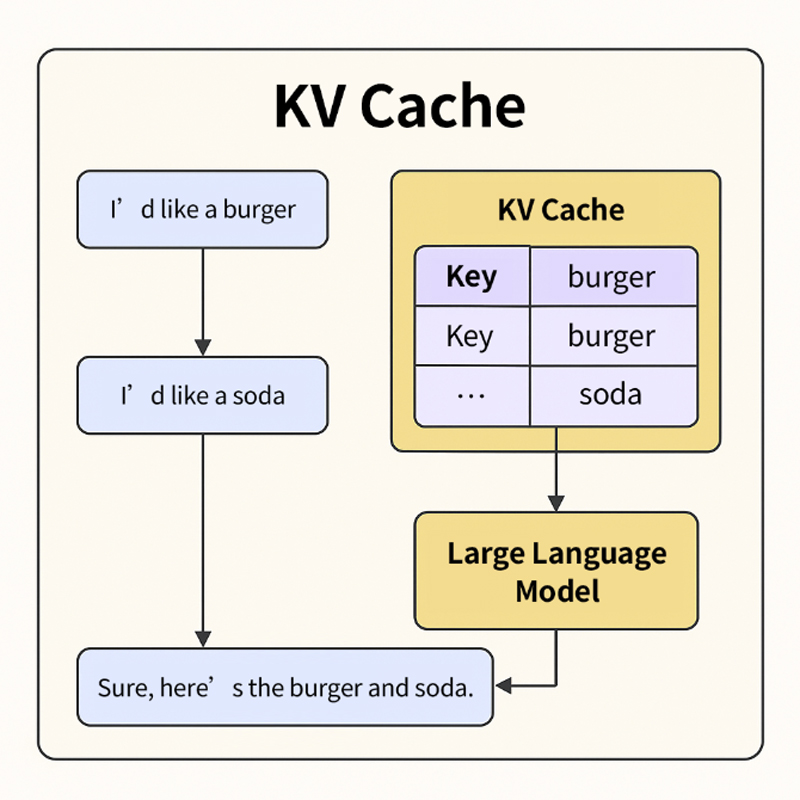
KV Cache Meets NVMe: The Key to Accelerating LLM Inference
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
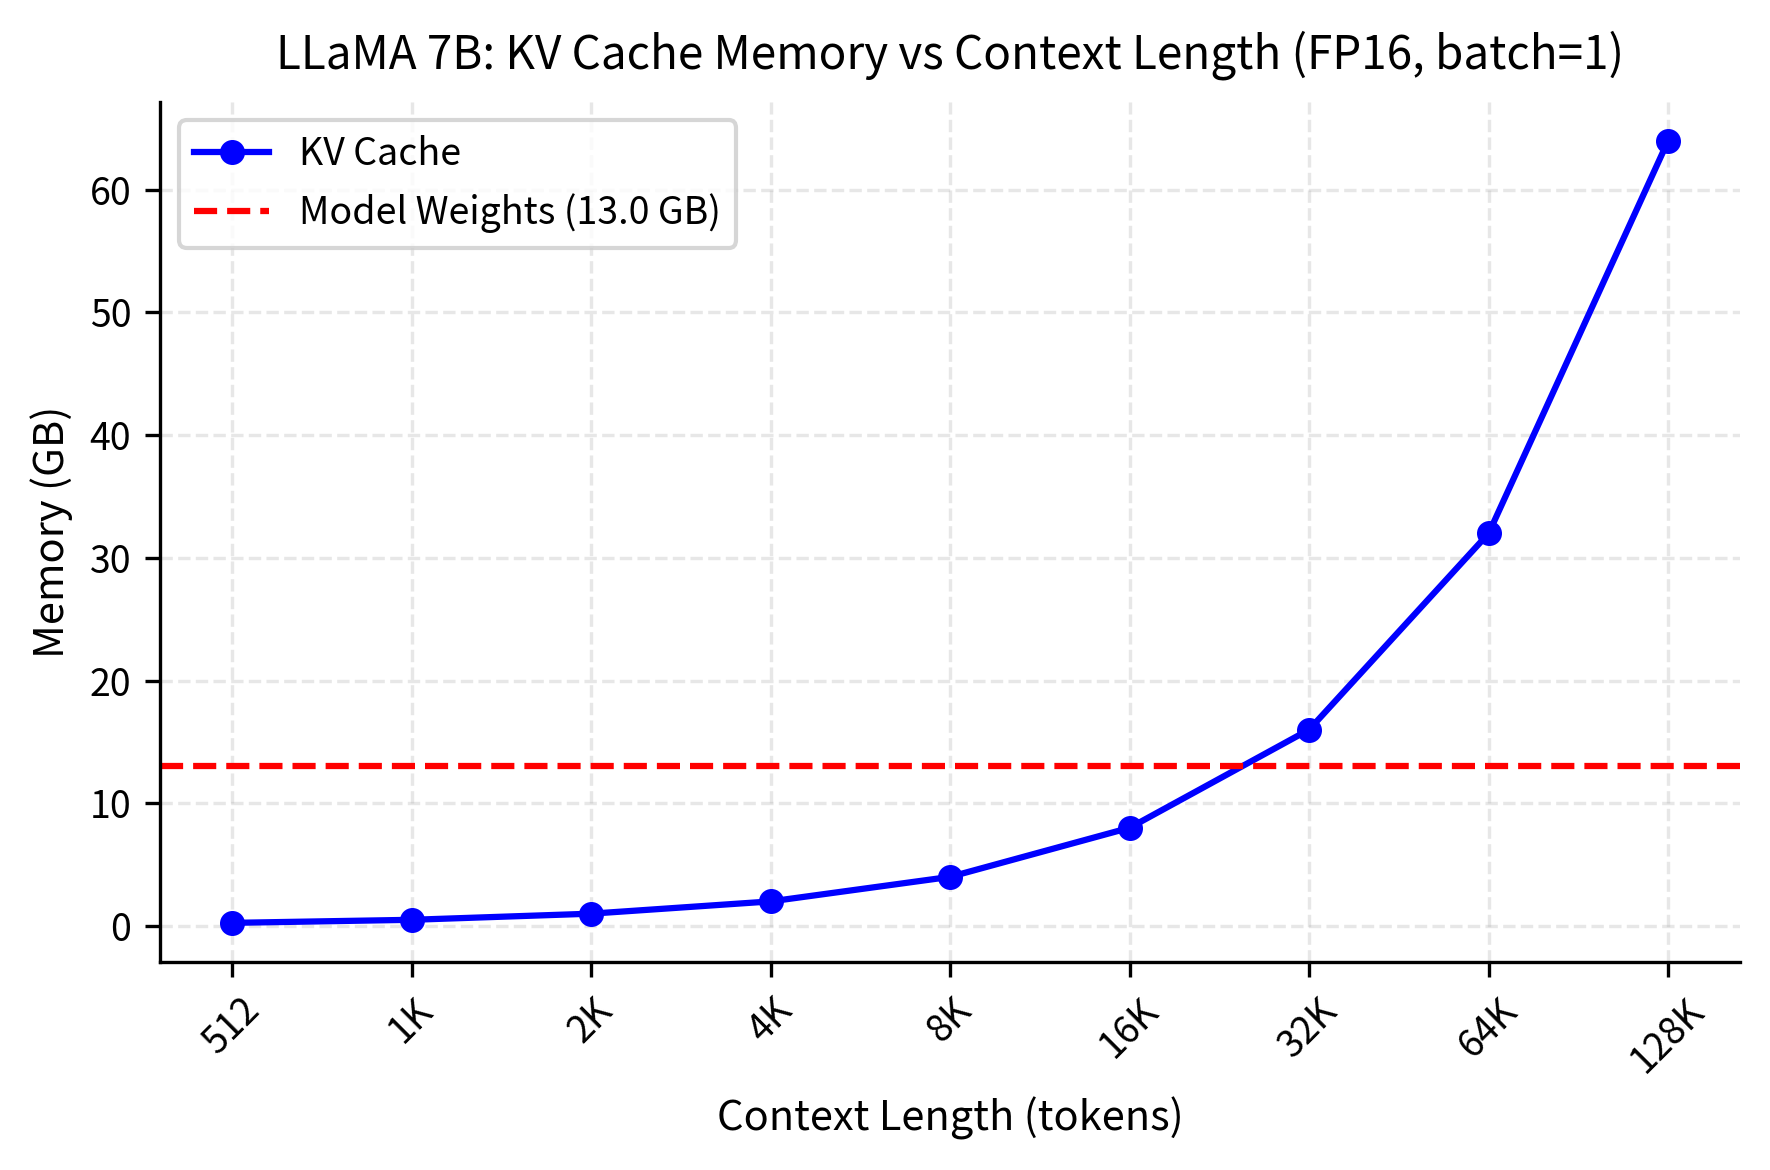
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
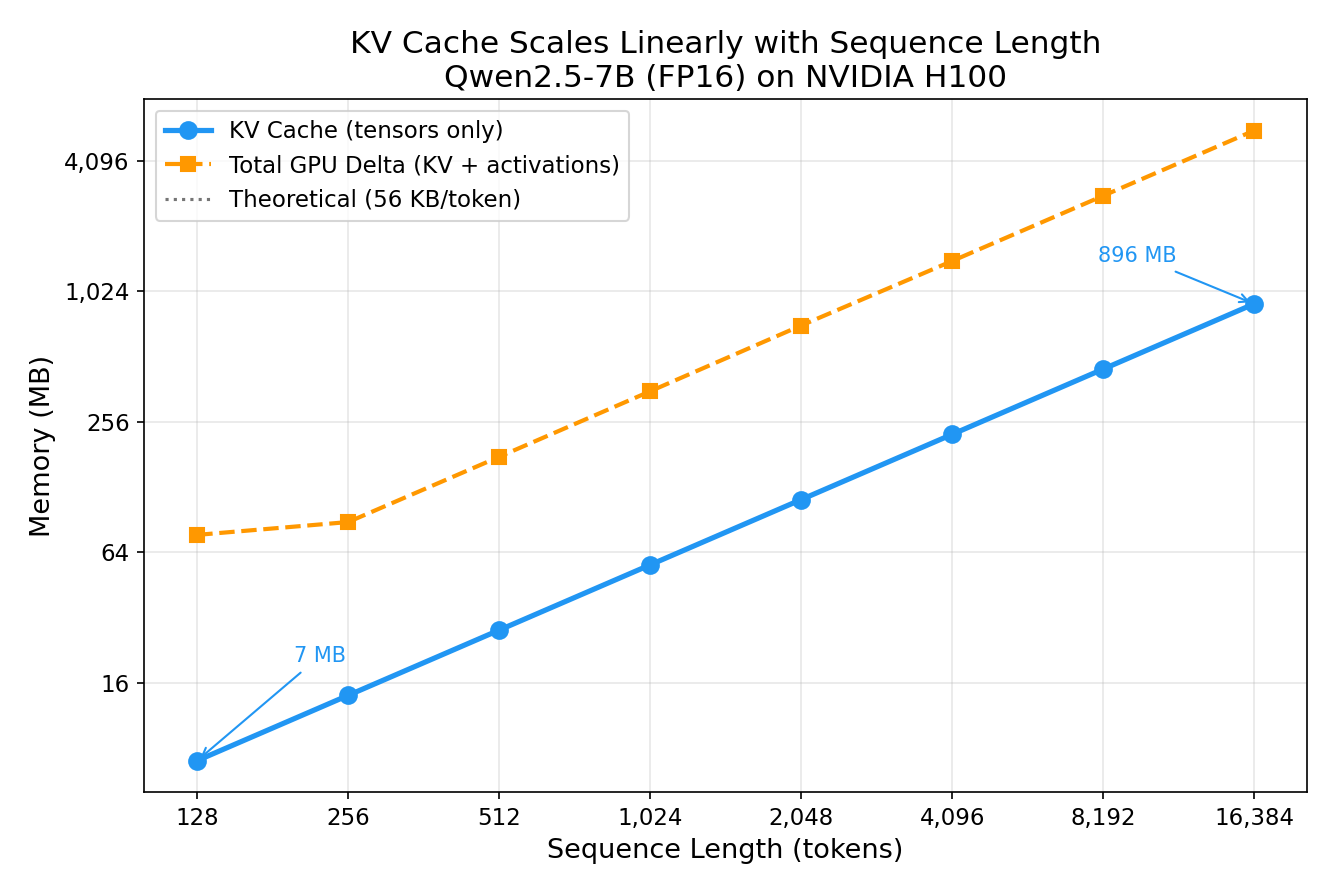
Understanding KV Cache in LLM Inference - Jingchao’s Website
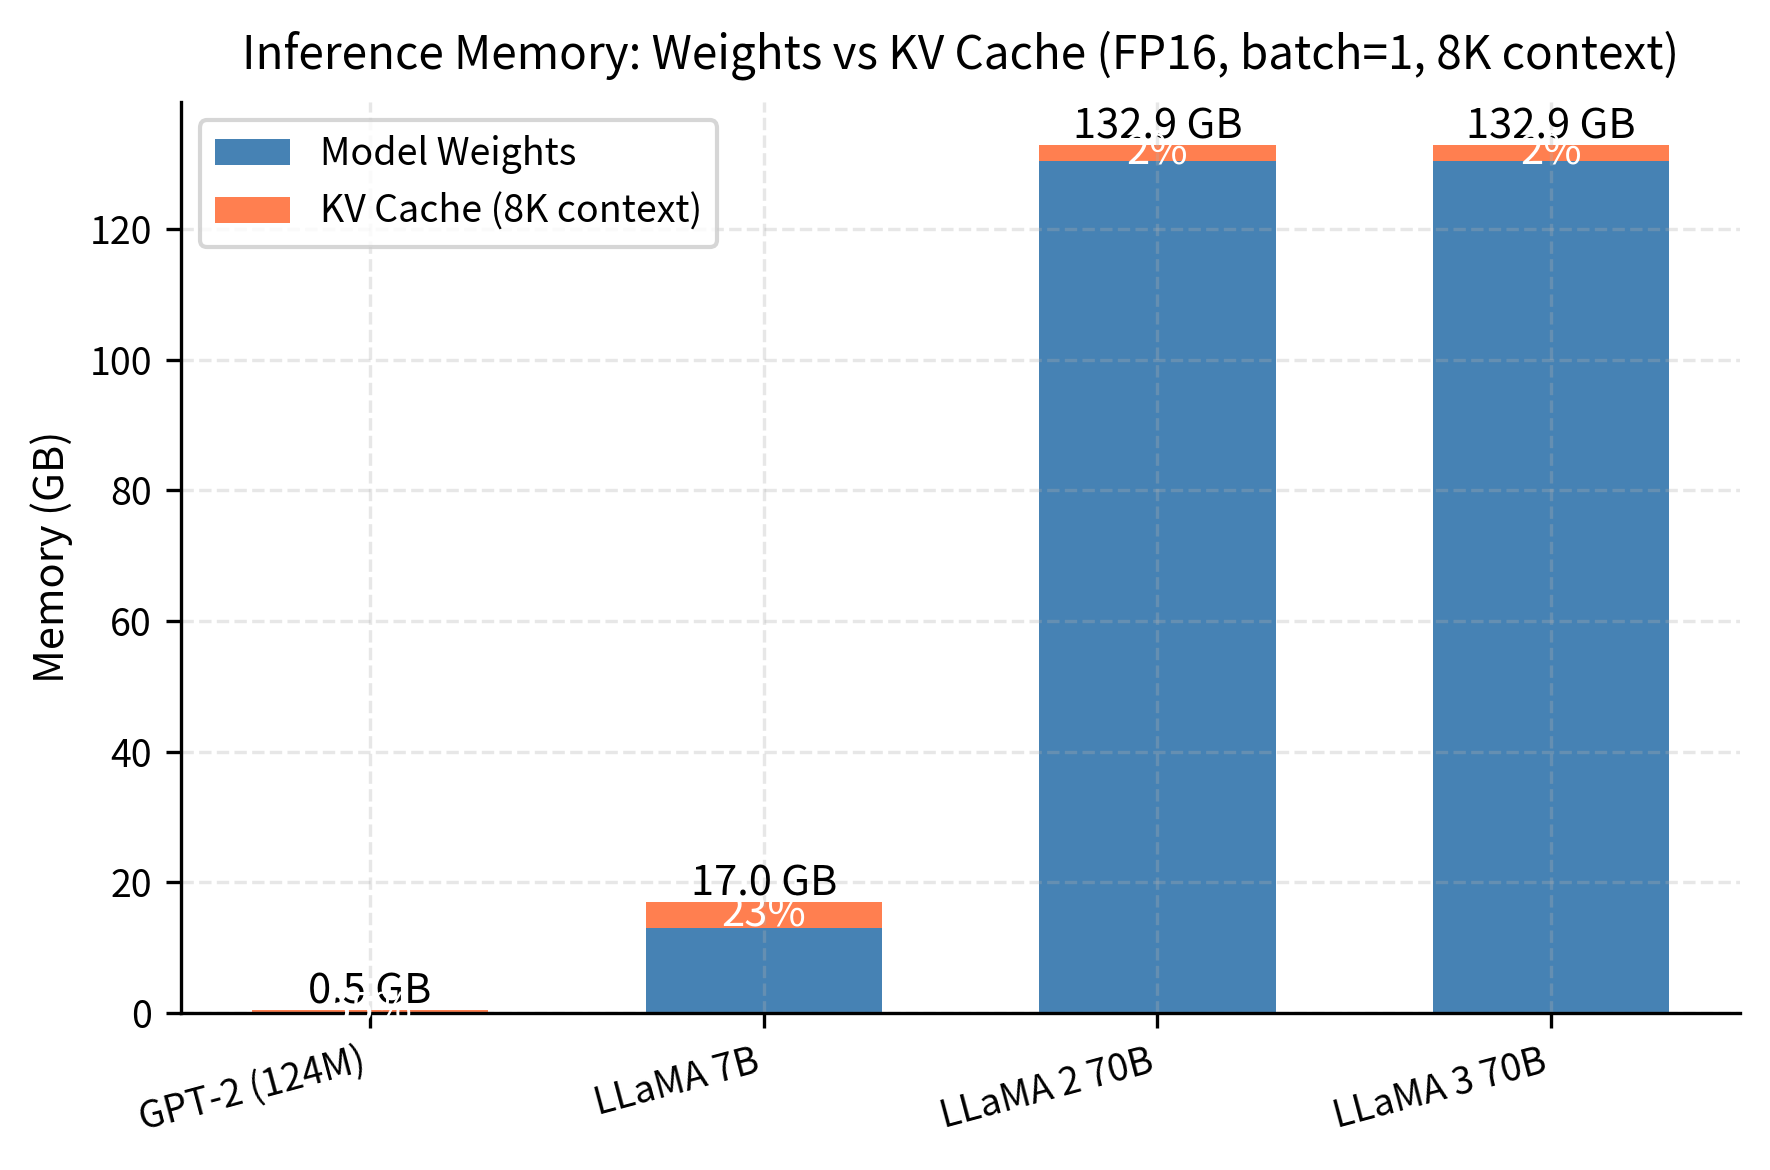
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

LLM Inference Optimization: KV Caching Bottleneck | Sanyam Sharma ...
Advertisement Space (300x250)

KV Cache Offload Accelerates LLM Inference - NADDOD Blog

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

LLM inference optimization: Architecture, KV cache and Flash attention ...
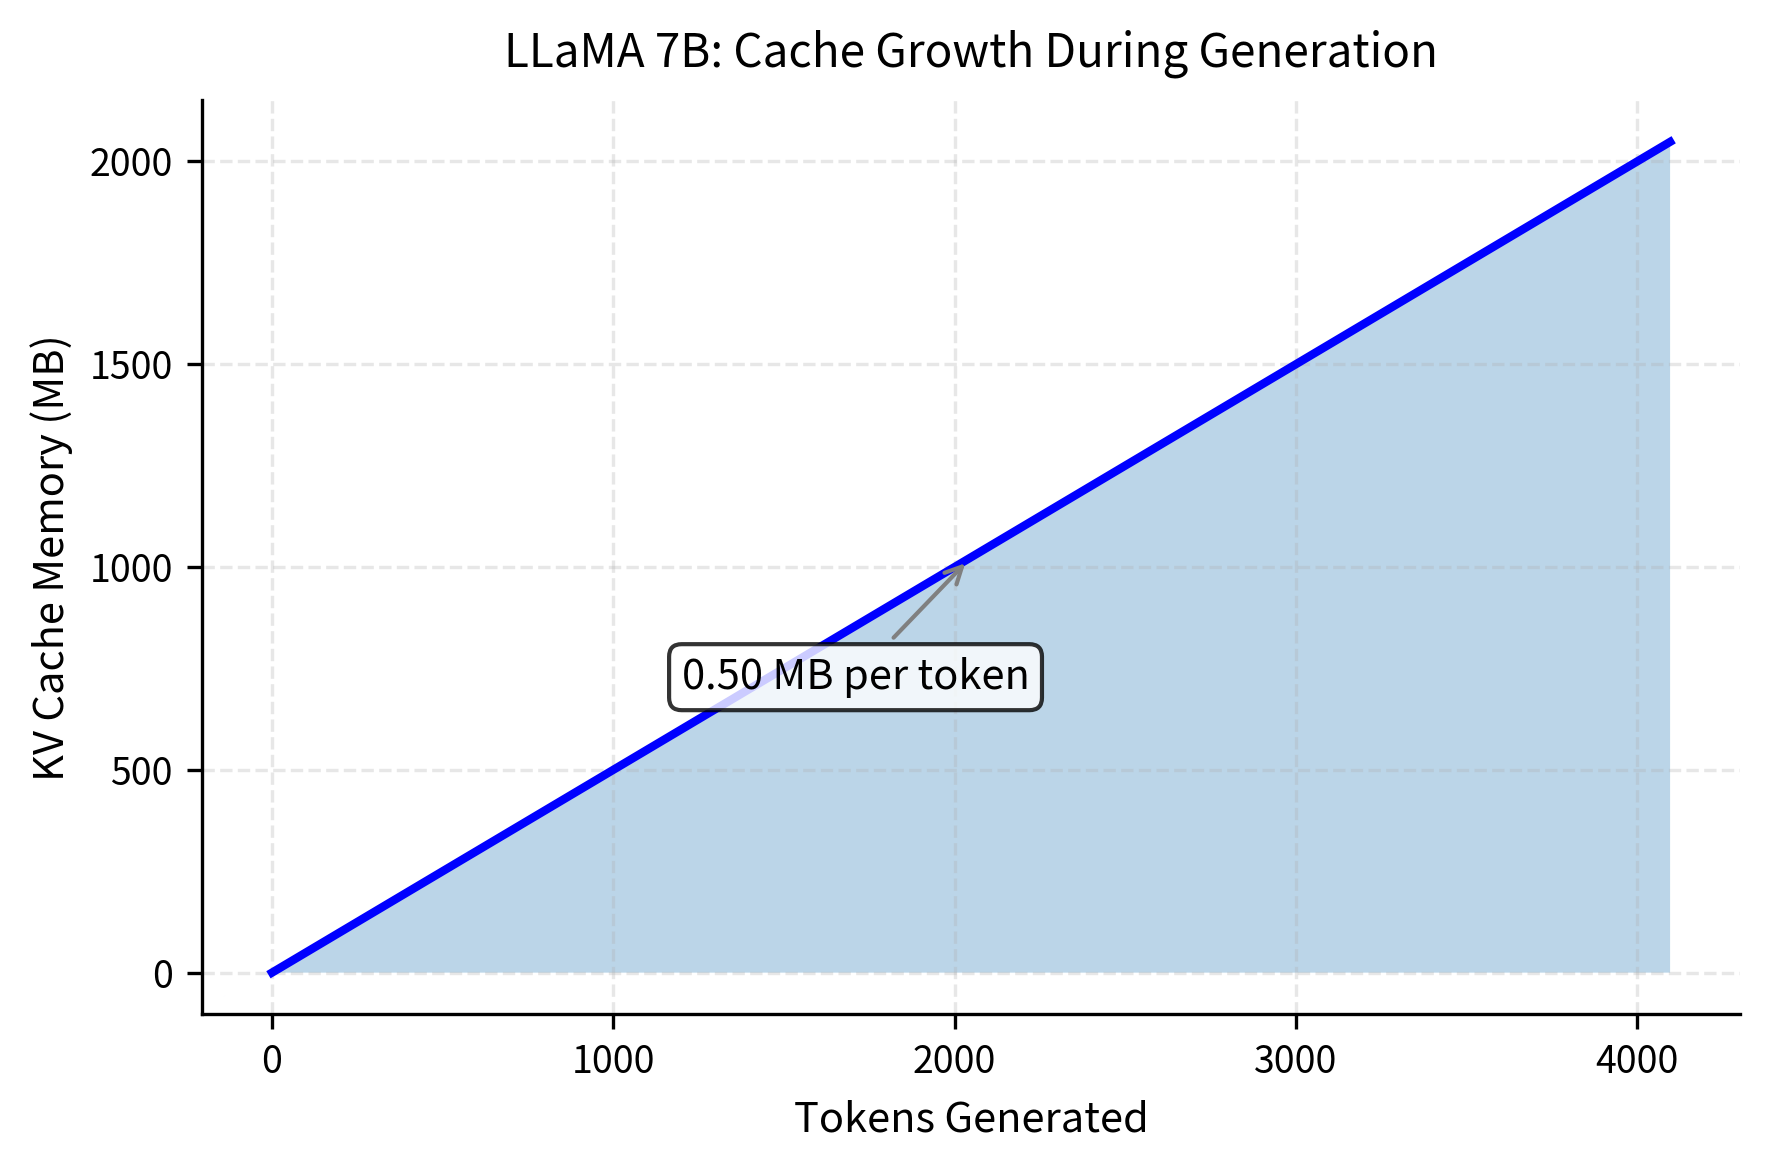
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
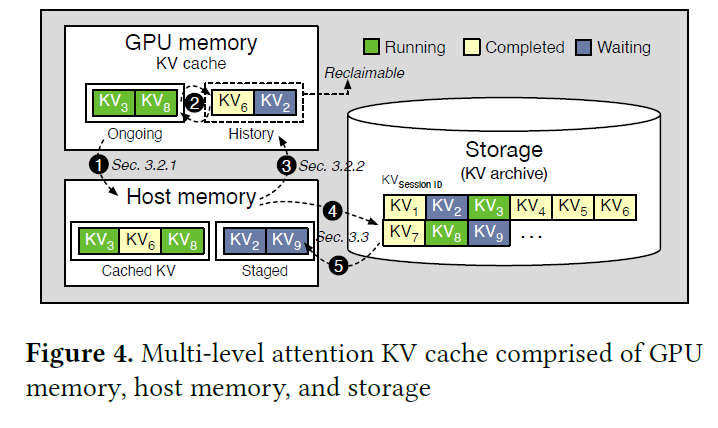
Accelerating LLM Inference via Dynamic KV Cache Placement in ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

KV Cache Reuse Is Quietly Reshaping LLM Inference Architecture | by ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference
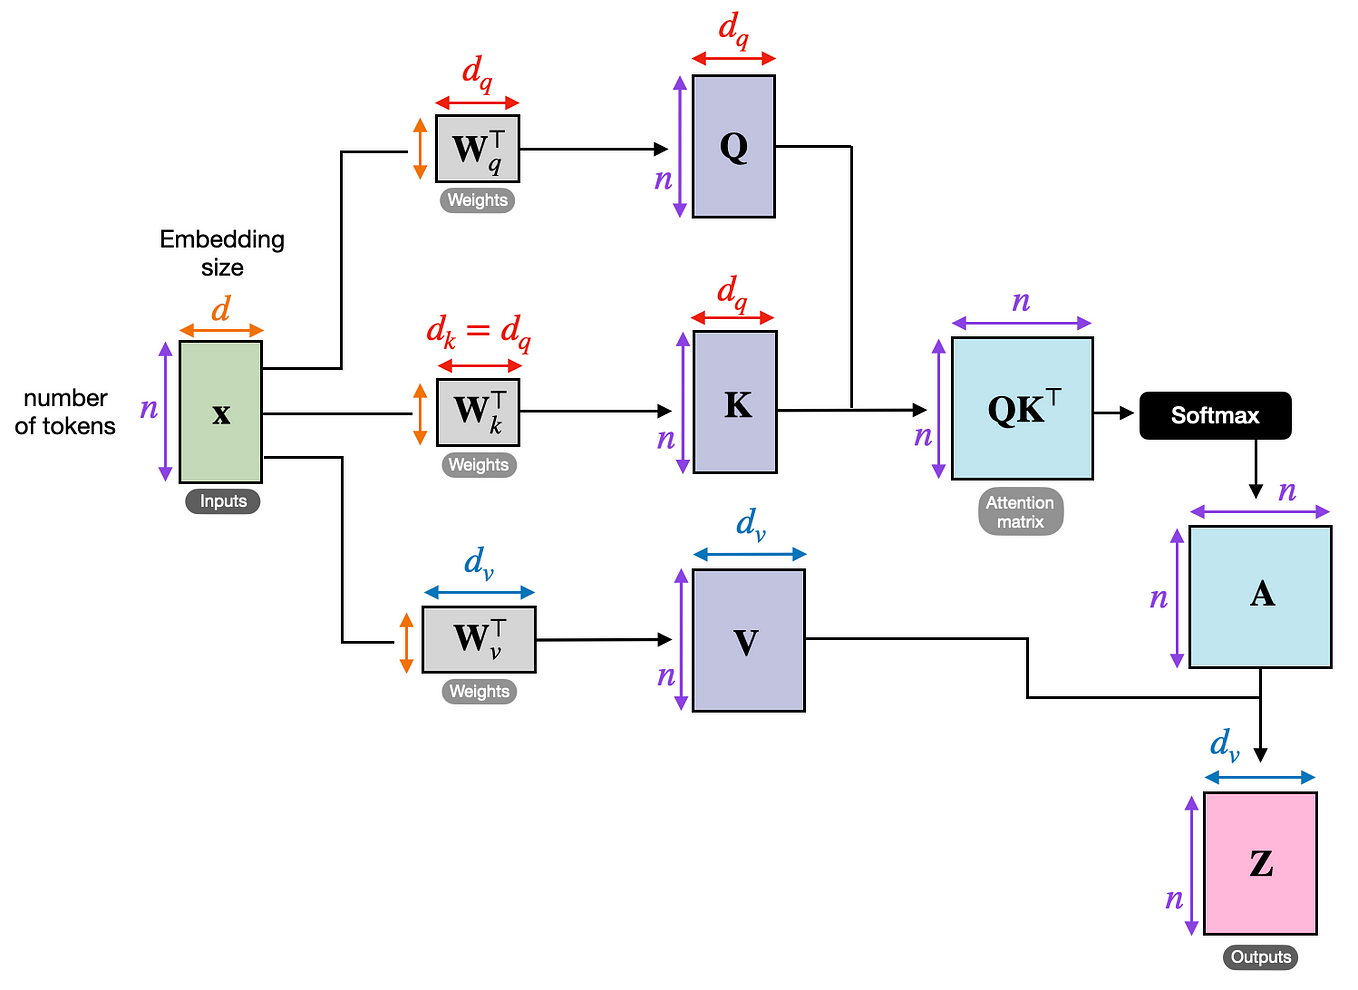
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

Figure 1 from Accelerating LLM Inference via Dynamic KV Cache Placement ...
Advertisement Space (336x280)
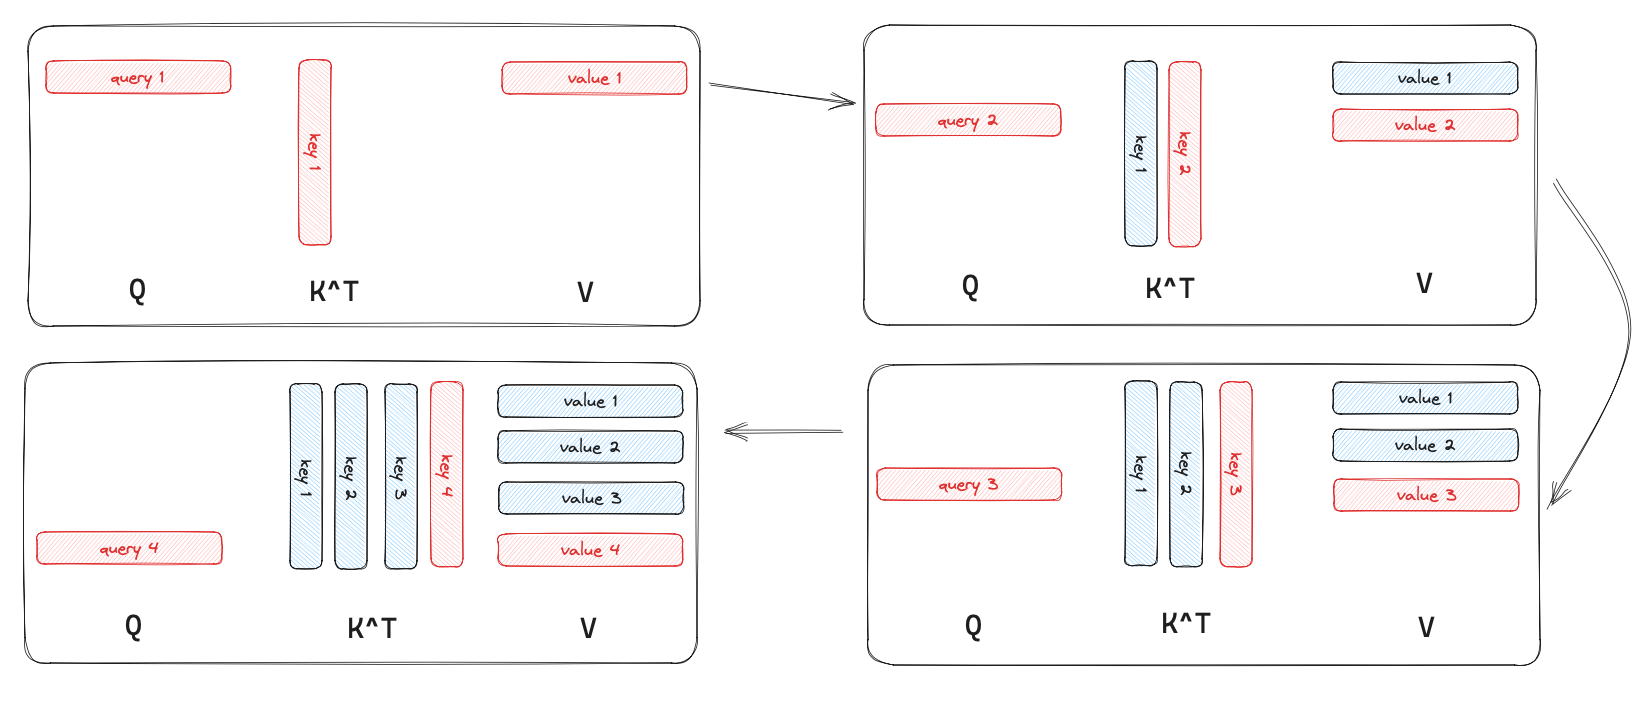
LLM inference optimization (1): KV Cache - MartinLwx's Blog
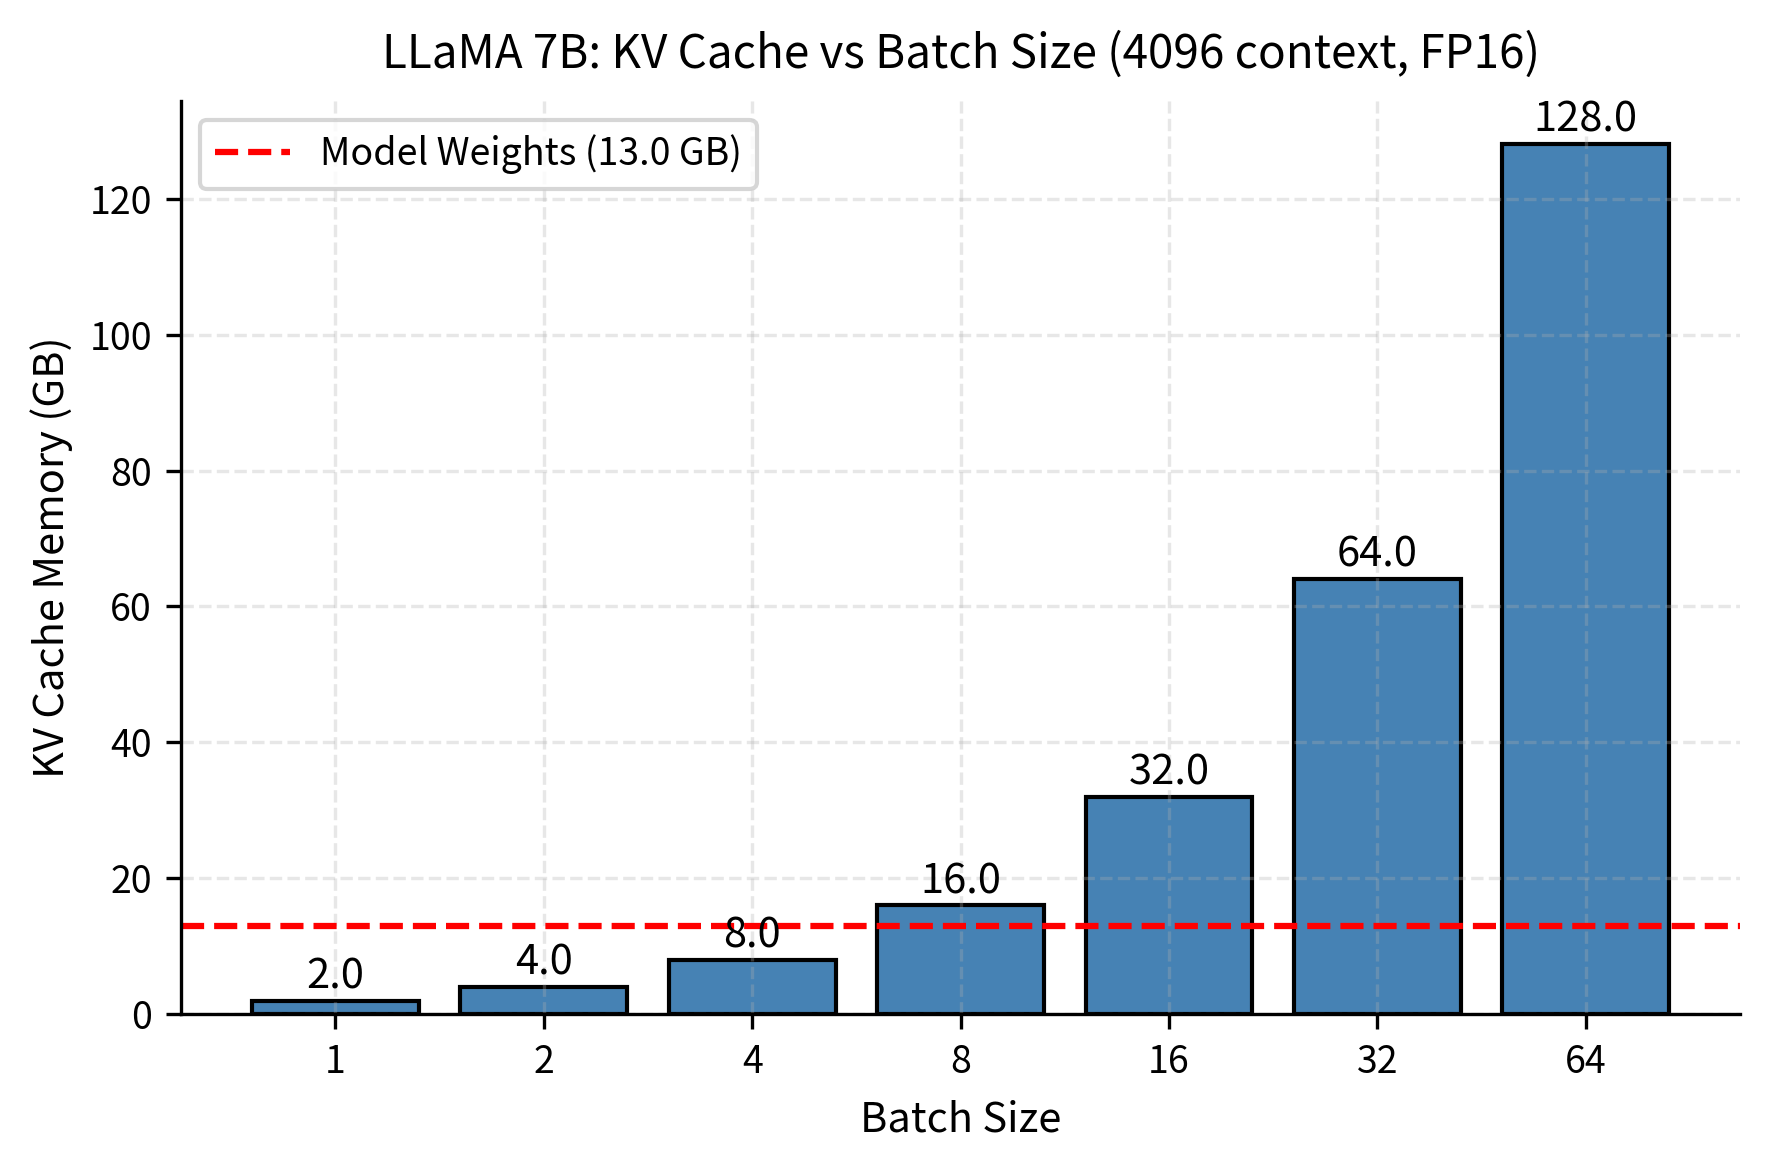
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

Multi-Query Attention — Why the KV Cache Becomes the Bottleneck in LLM ...

LLM Inference: Accelerating Long Context Generation with KV Cache ...
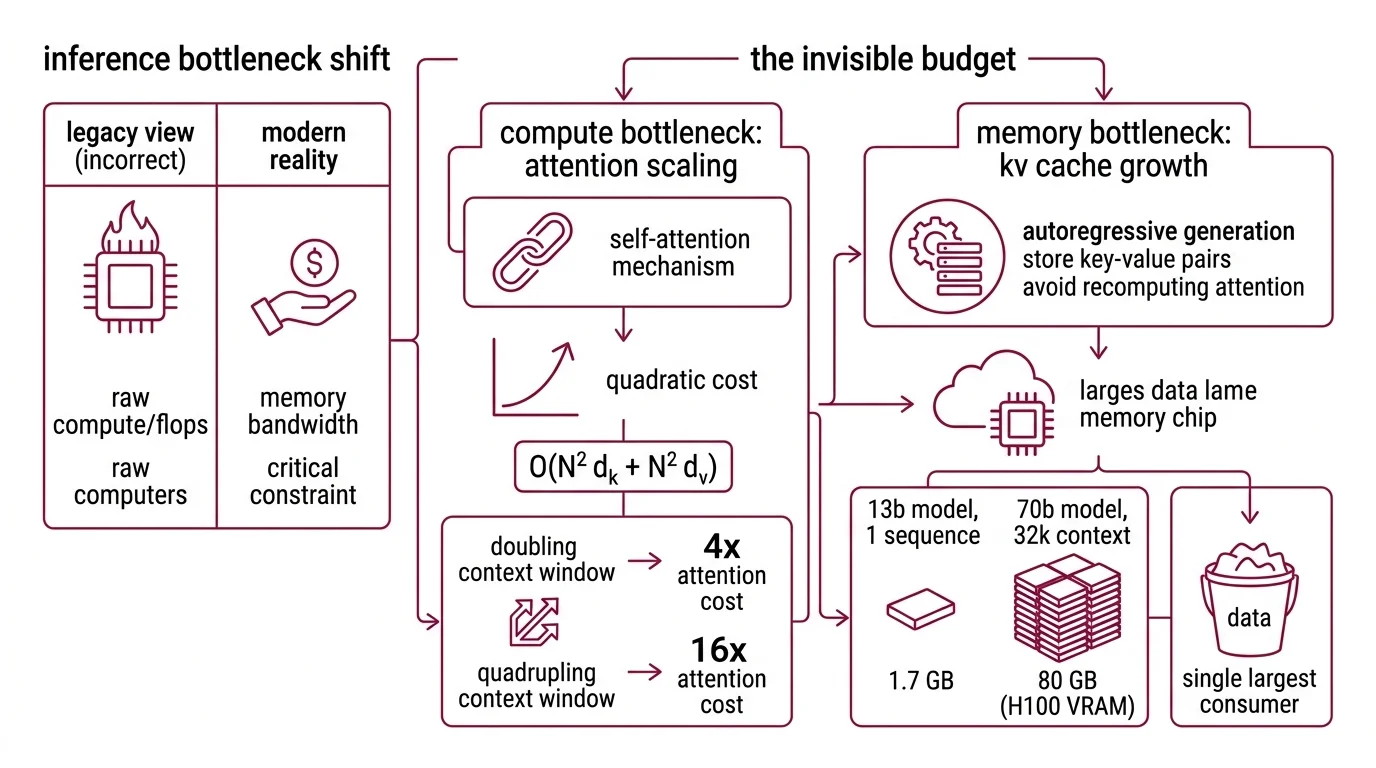
LLM Inference Limits: Memory Walls & Real Costs
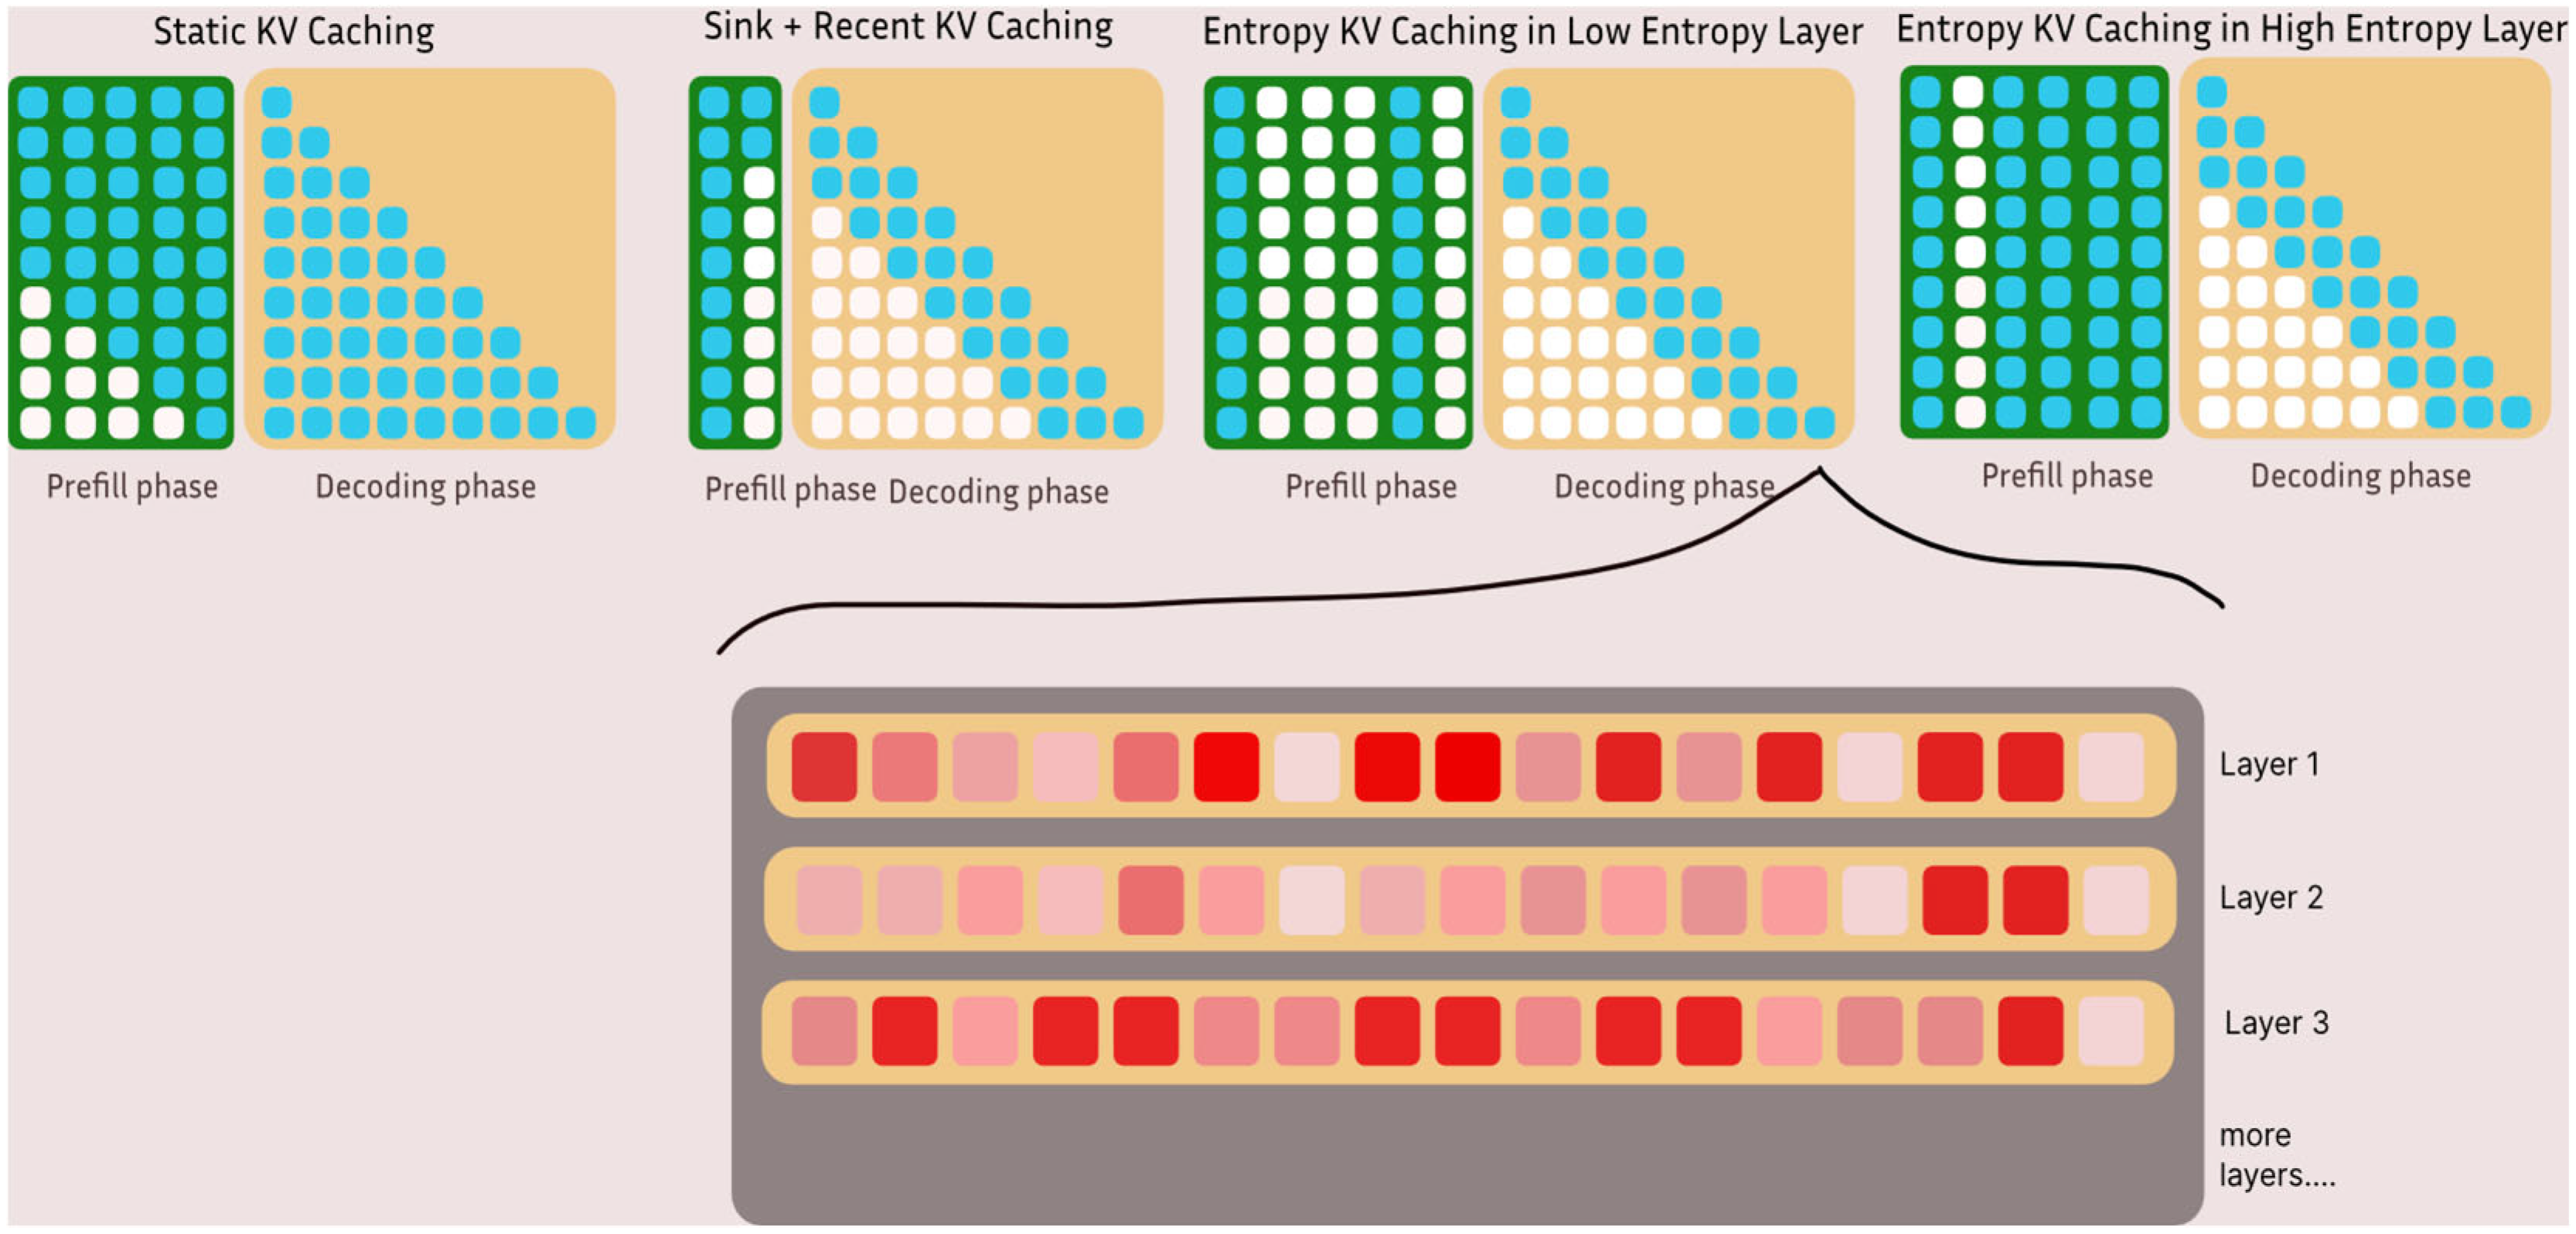
Entropy-Guided KV Caching for Efficient LLM Inference

LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...

Lessons Learned Scaling LLM Training and Inference with Direct Memory ...
Top 10 KV Cache Compression Techniques for LLM Inference: Reducing ...
What is KV Cache? | LLM Inference Optimization | Inference Systems
Advertisement Space (336x280)

Inside LLM Inference: KV Cache, Prefill, and the Decode Bottleneck | by ...

Why LLM Inference Gets Fast and Then Runs Out of Memory

Comparative Characterization of KV Cache Management Strategies for LLM ...
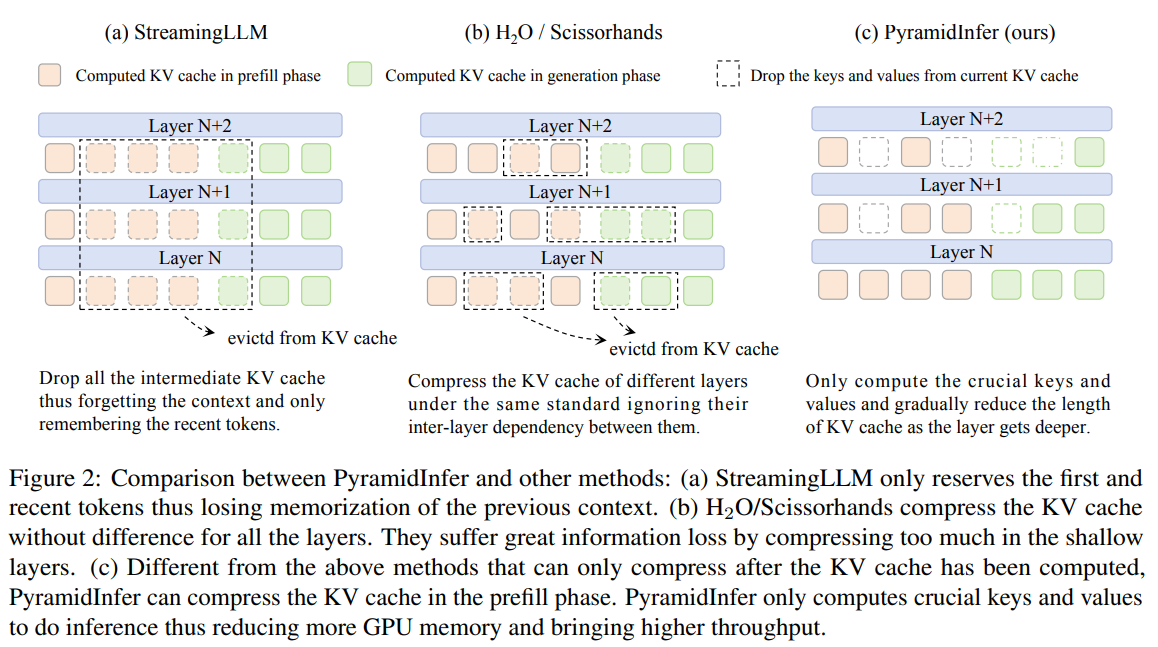
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...

Comparative Characterization of KV Cache Management Strategies for LLM ...
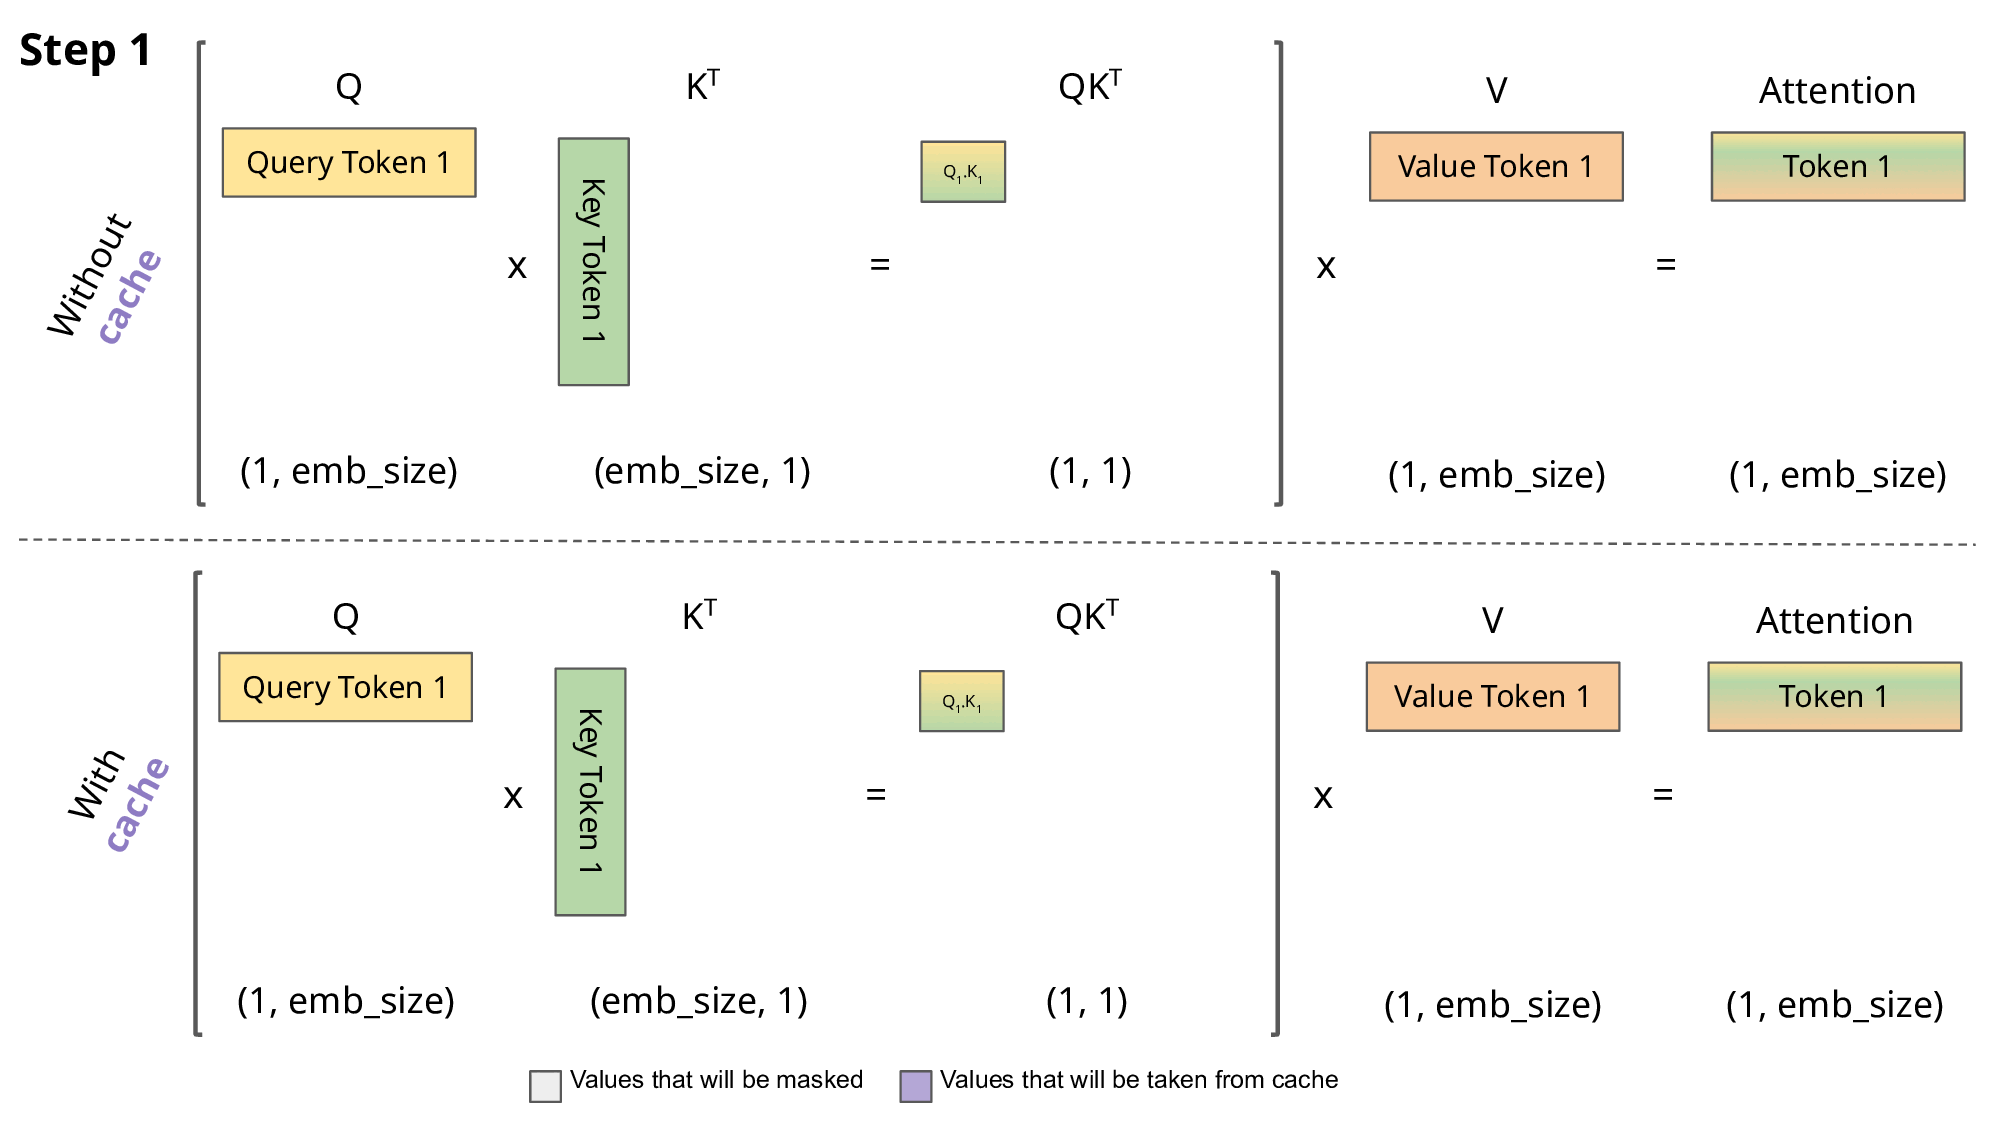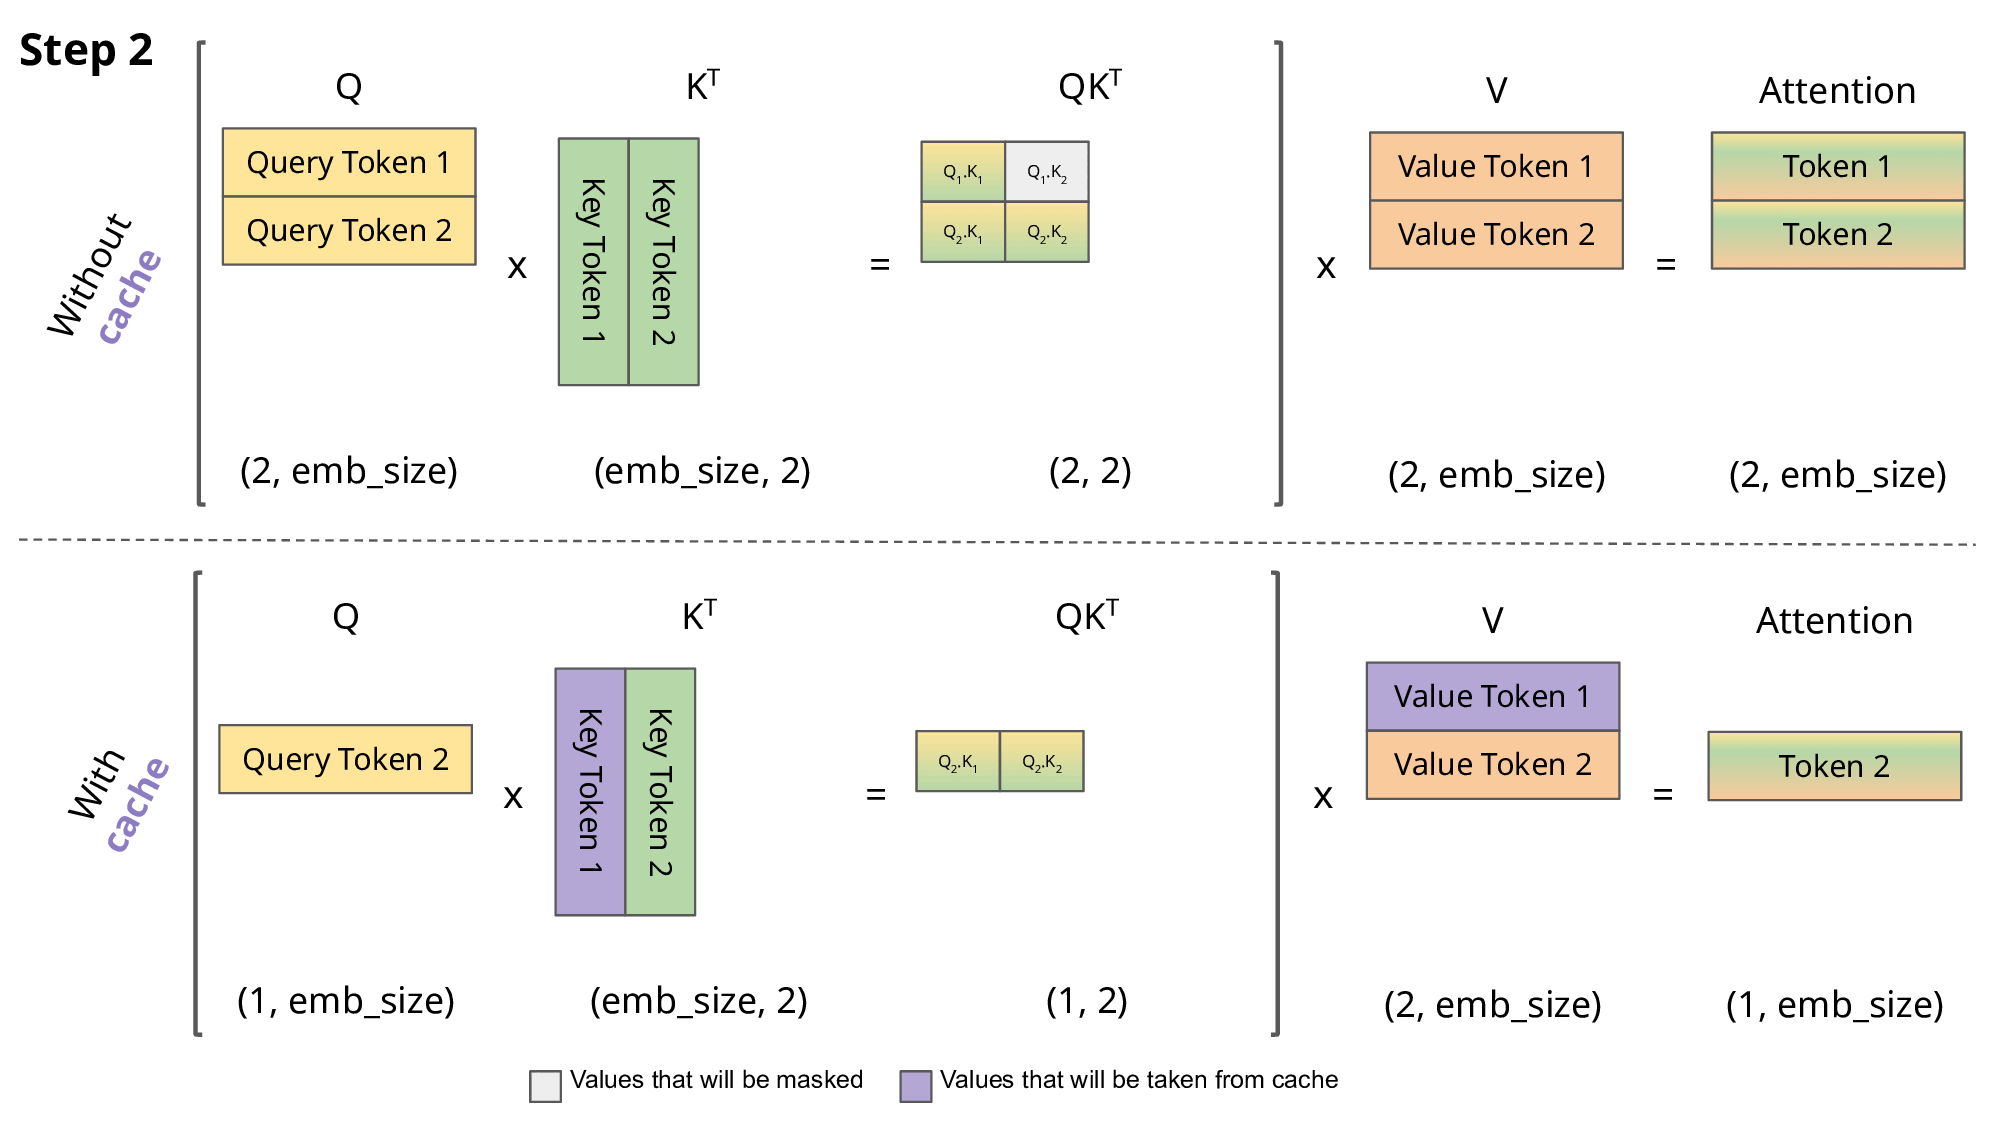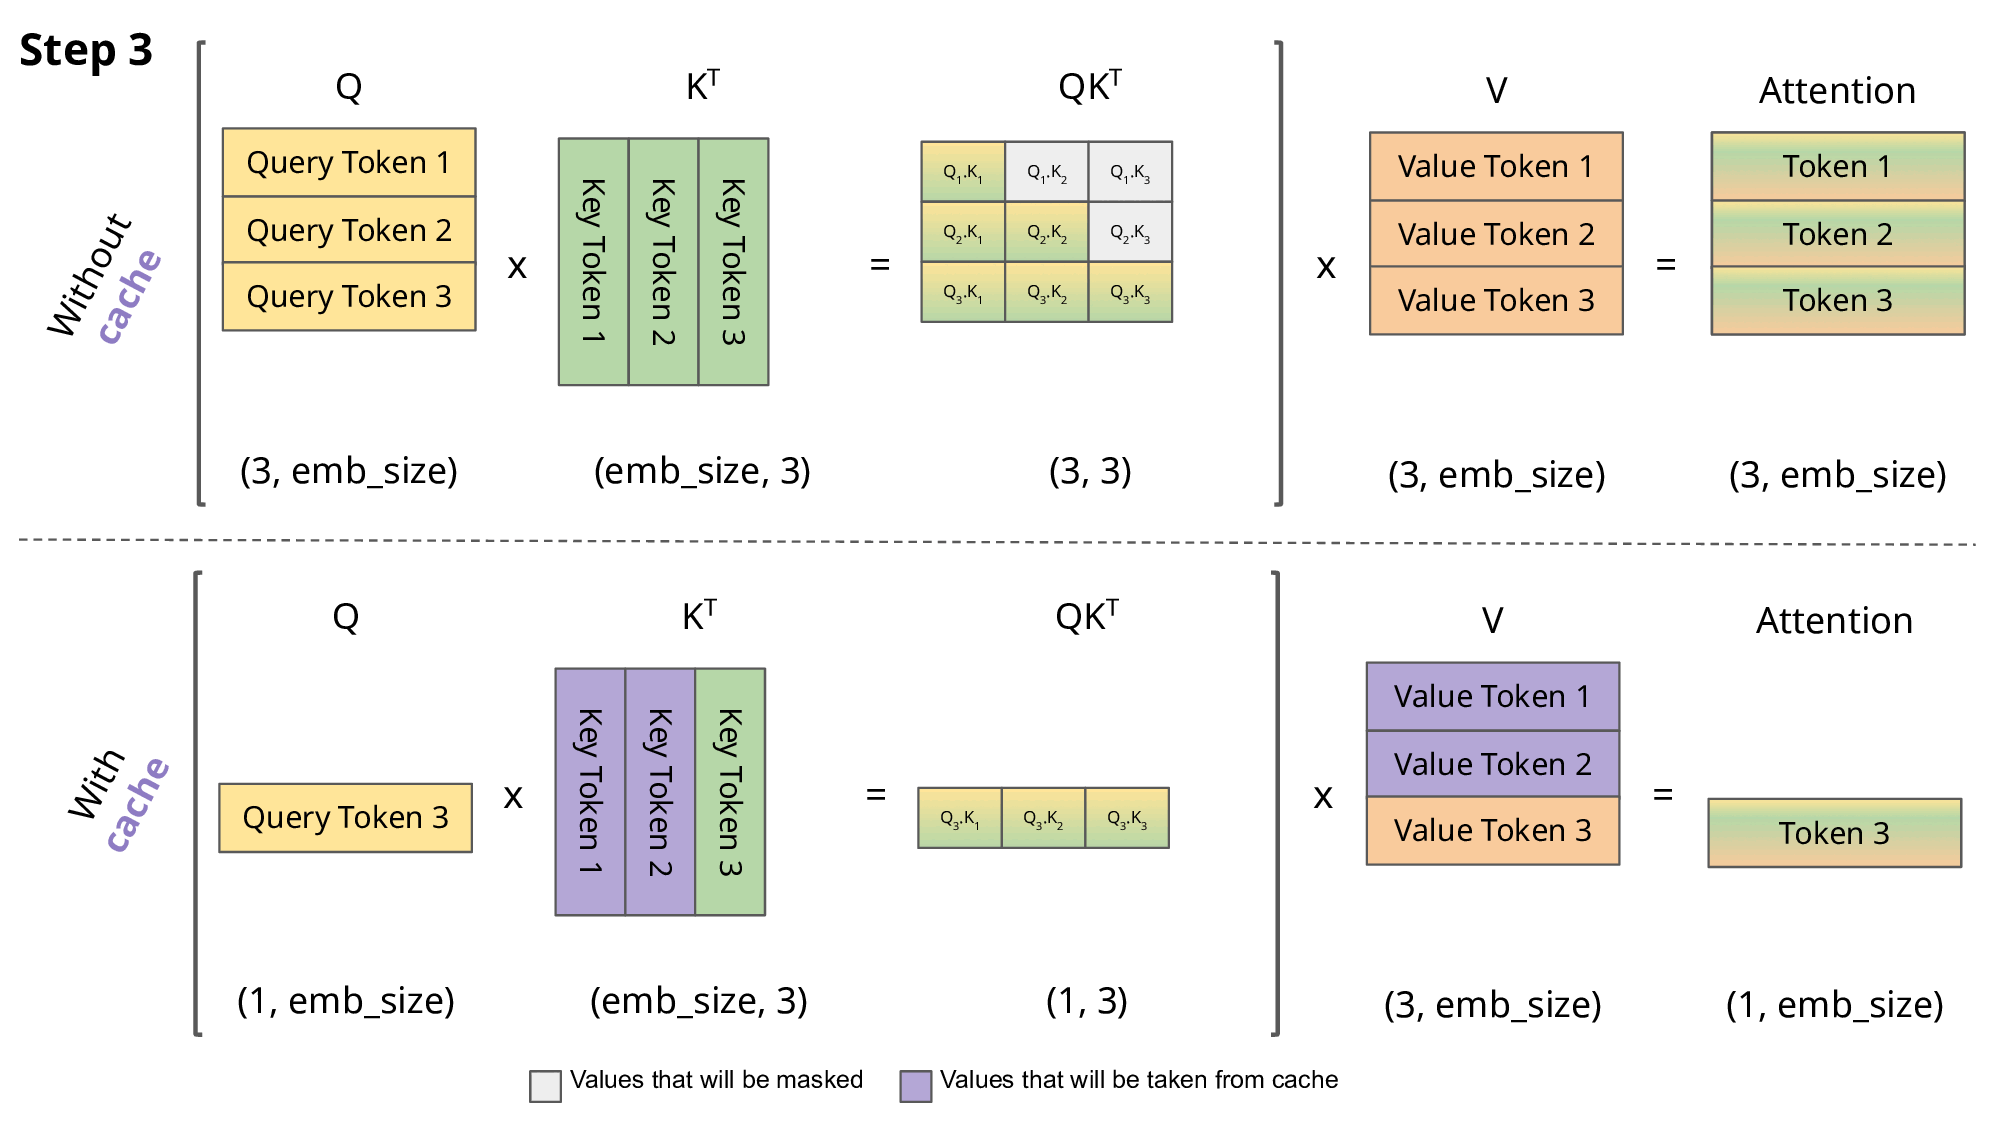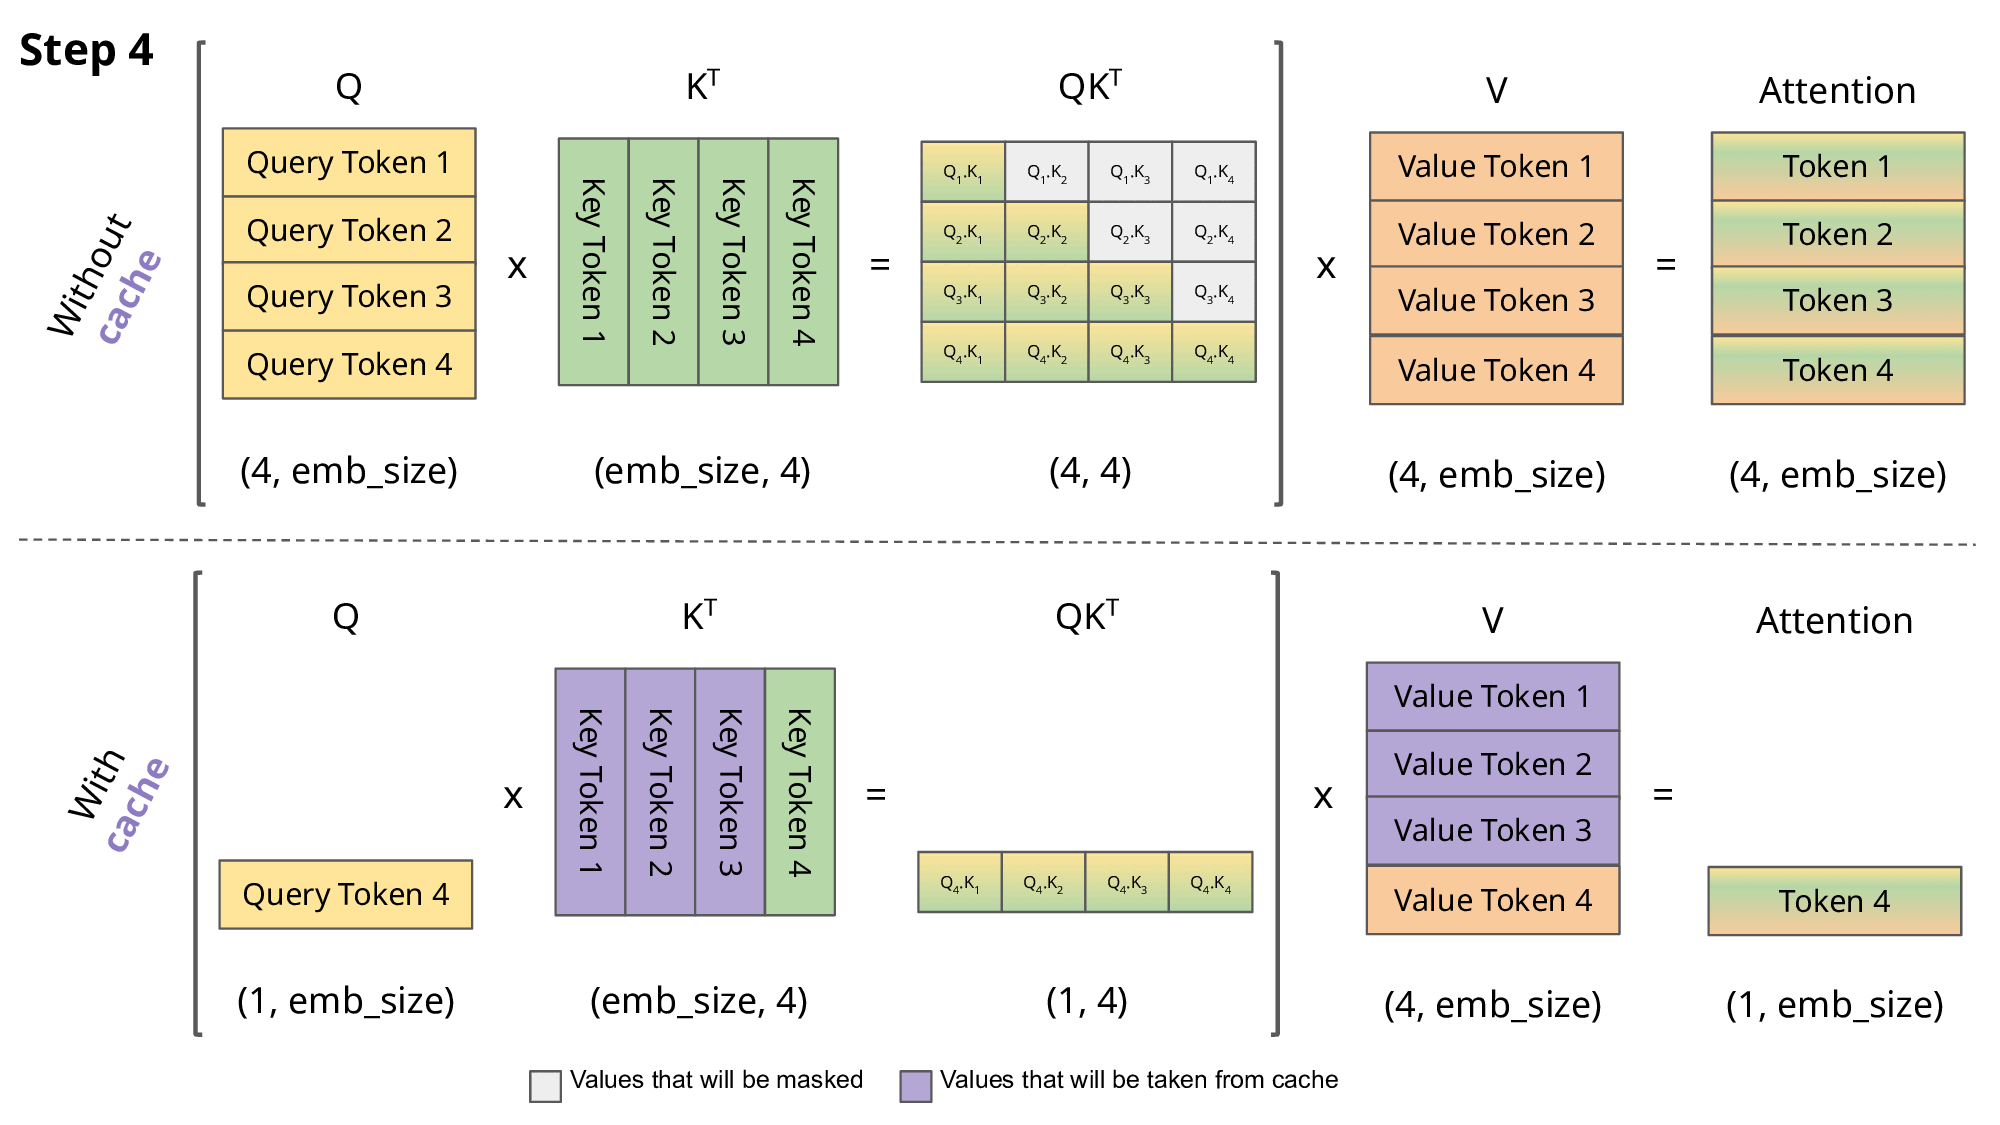
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium