
Kv Cache Llm Csdn
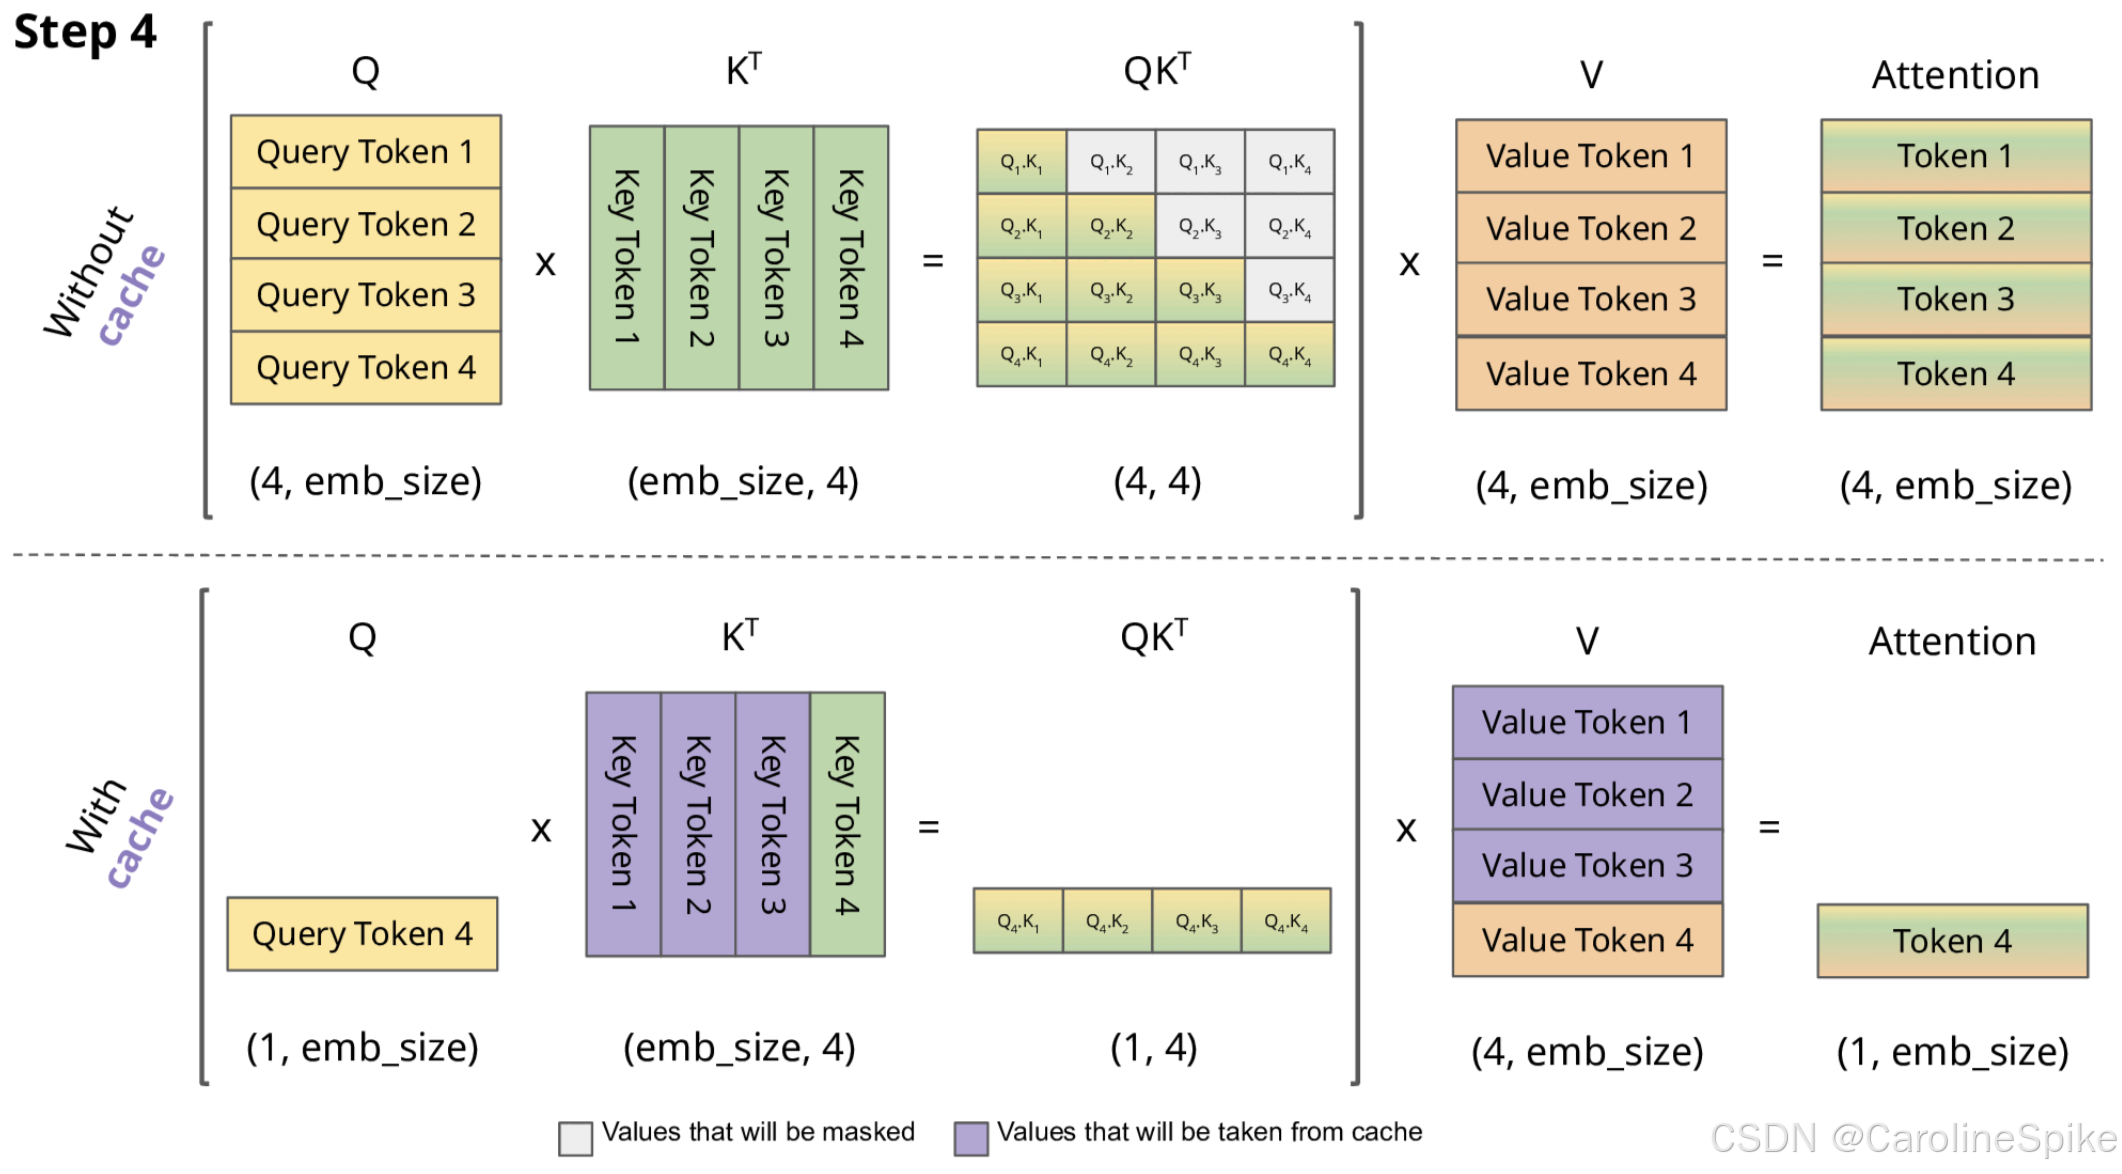
LLM - GPT(Decoder Only) 类模型的 KV Cache 公式与原理 教程_大模型 (LLM)-CSDN专栏
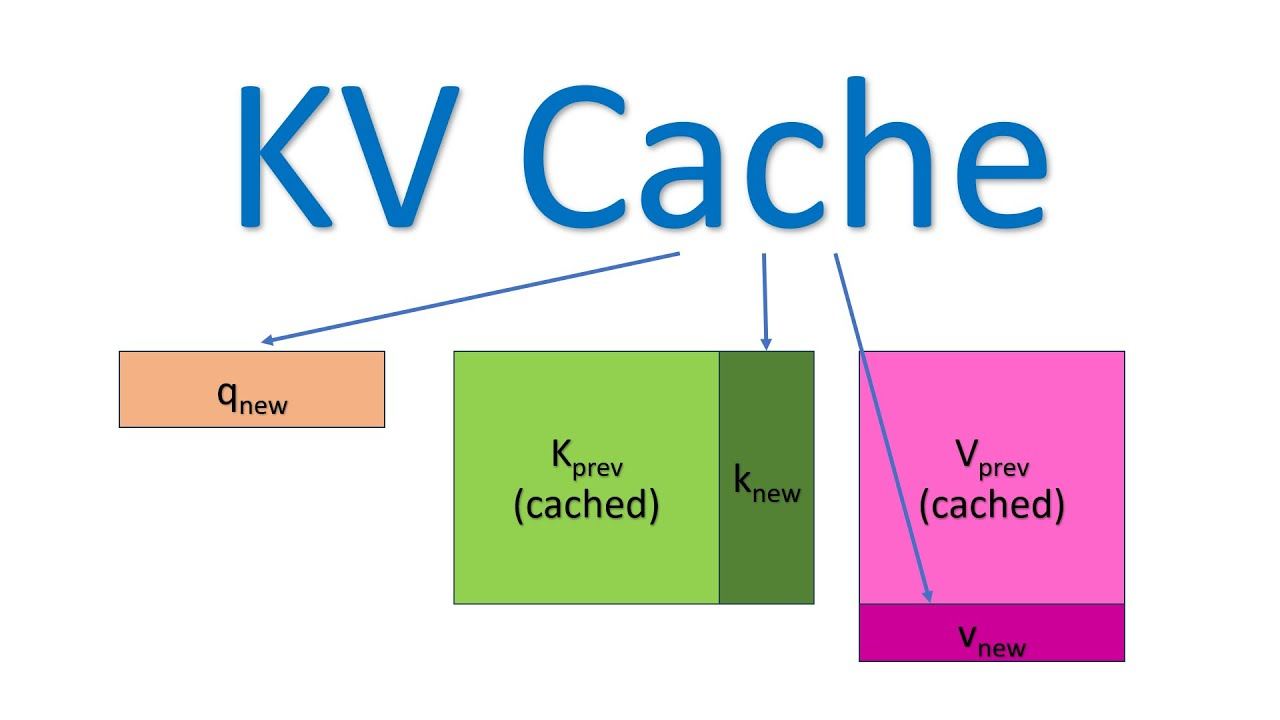
KV Cache 详解:新手也能理解的 LLM 推理加速技巧-CSDN博客
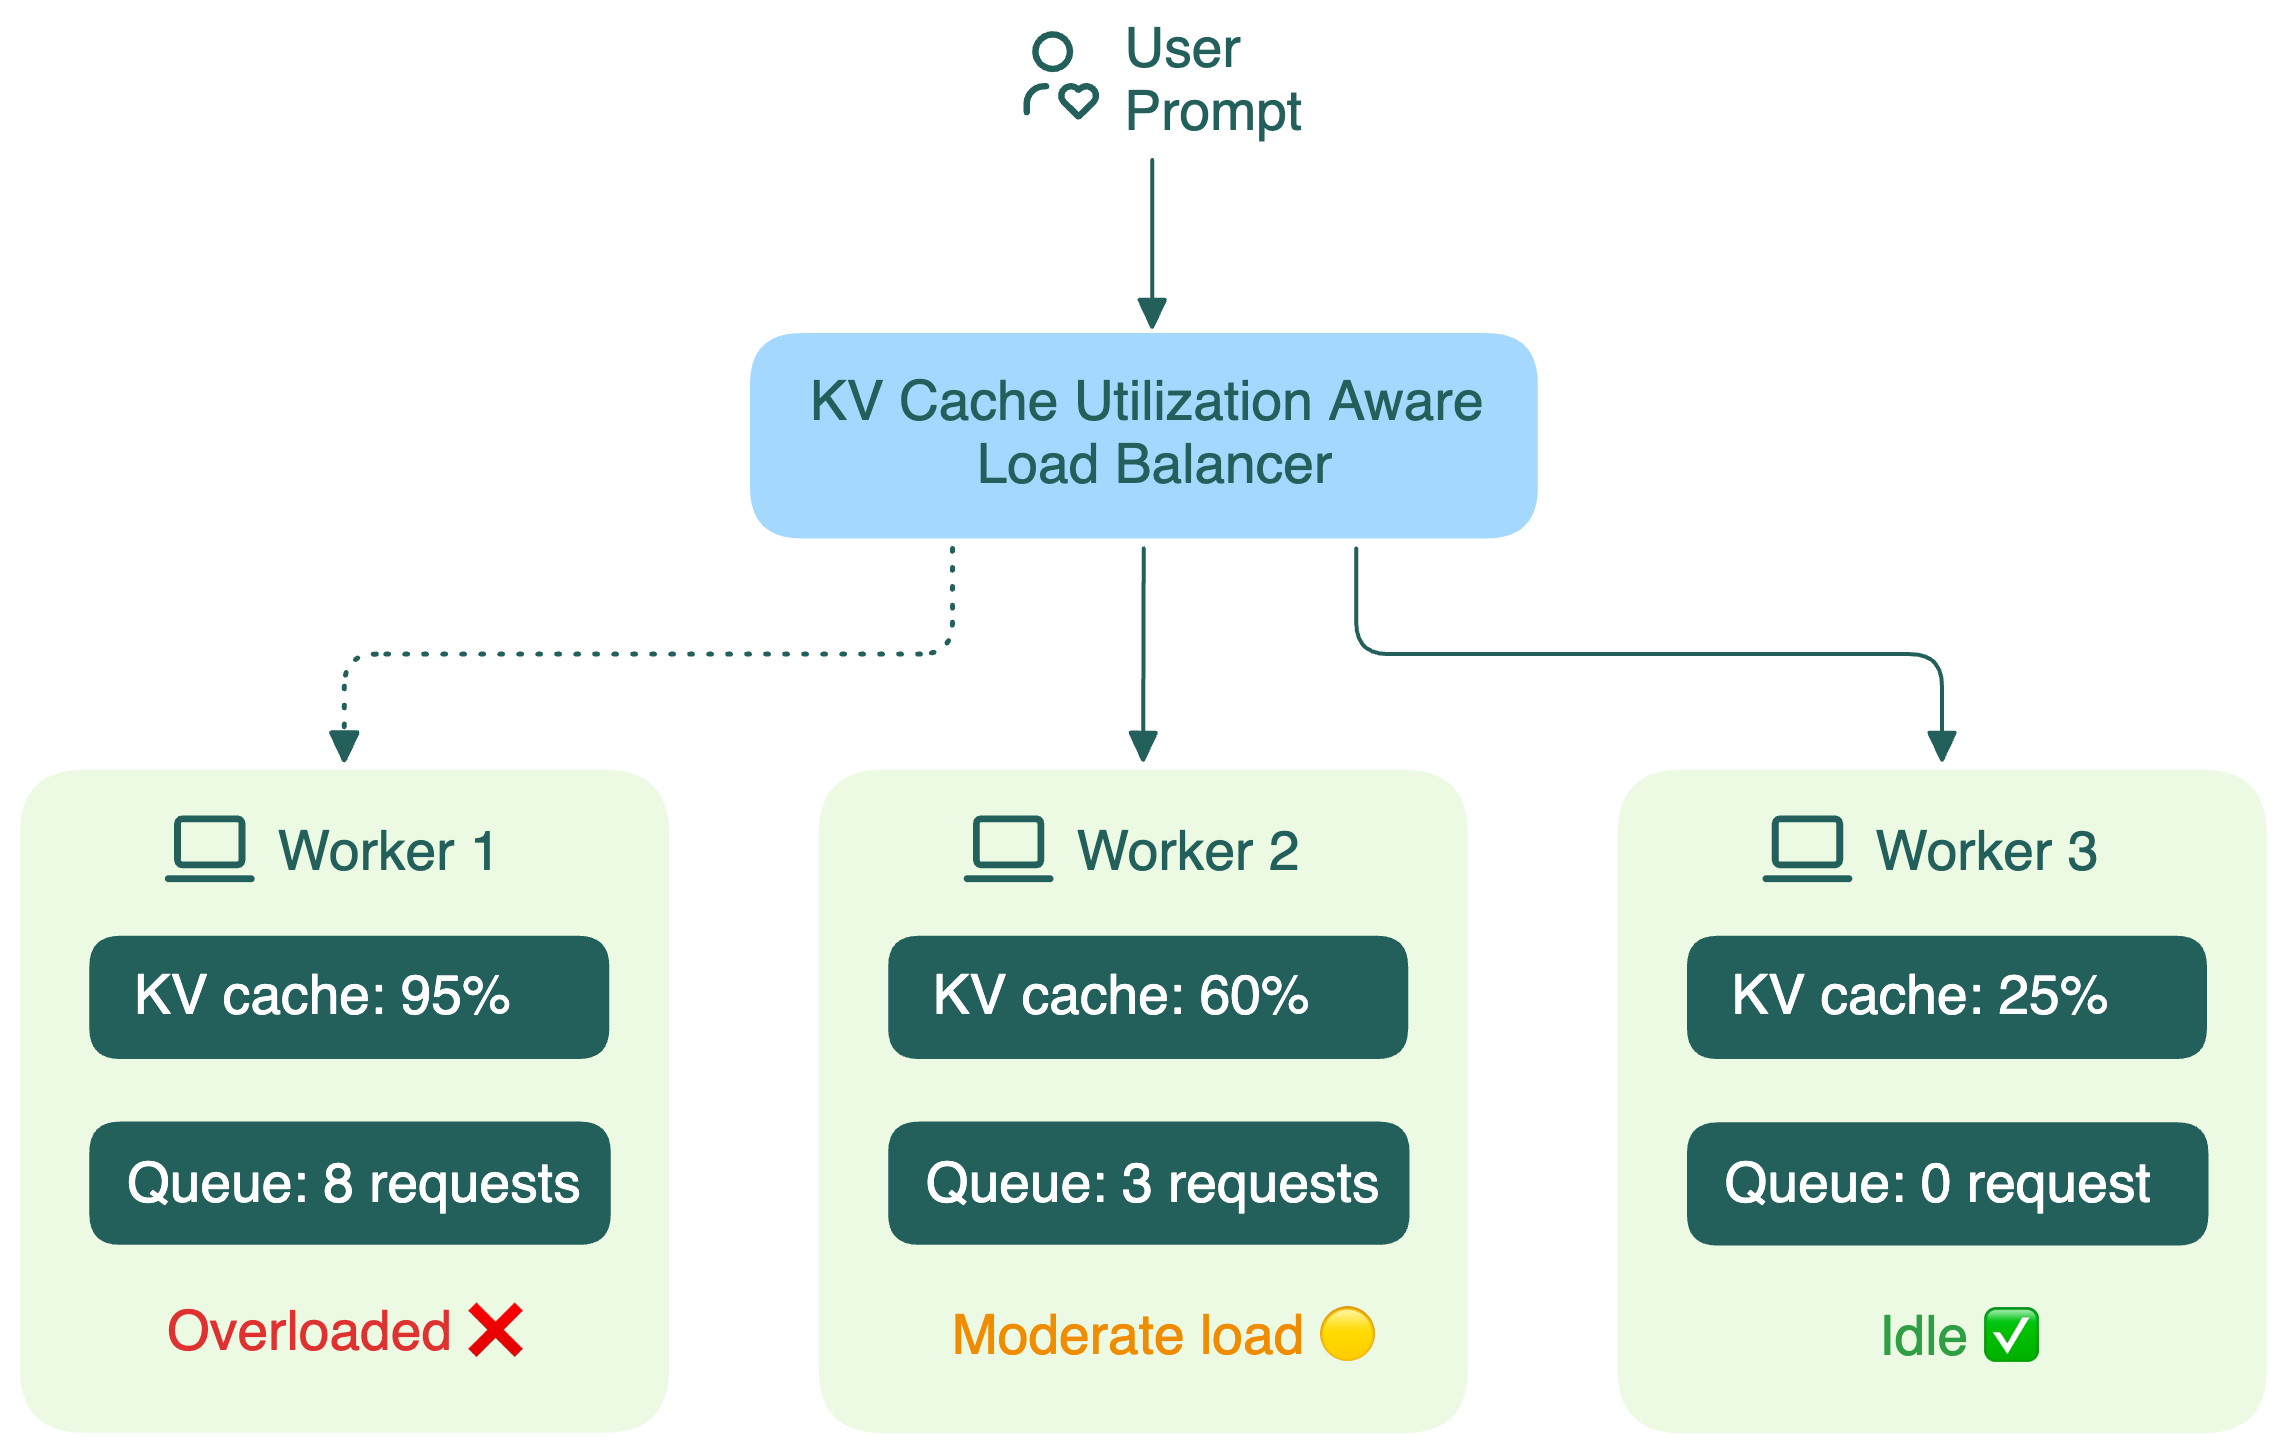
KV cache utilization-aware load balancing | LLM Inference Handbook
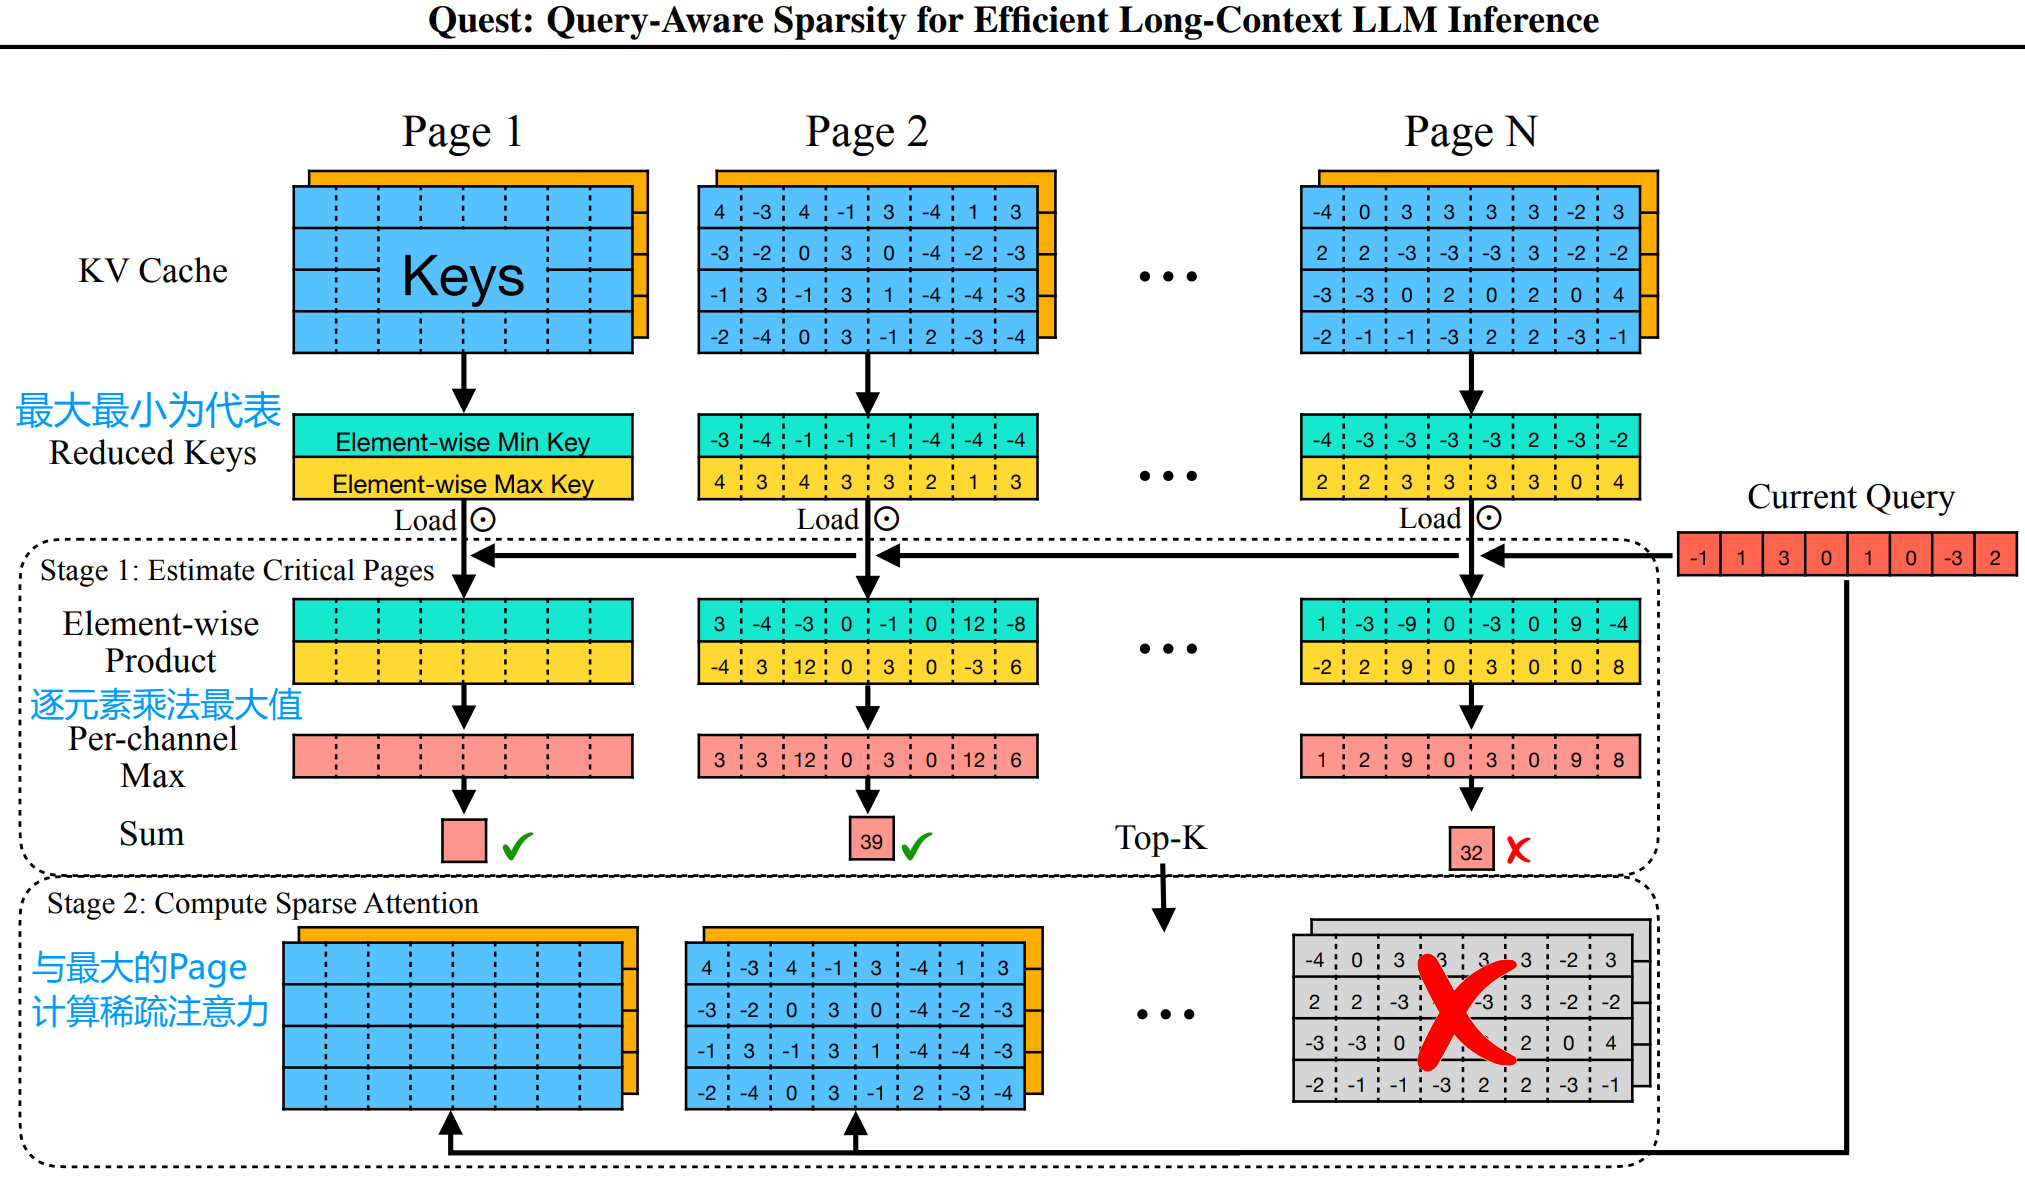
南京大学 LLM 开发基础(六)推理优化 KV Cache + Sparse Attention_nju spar-CSDN博客
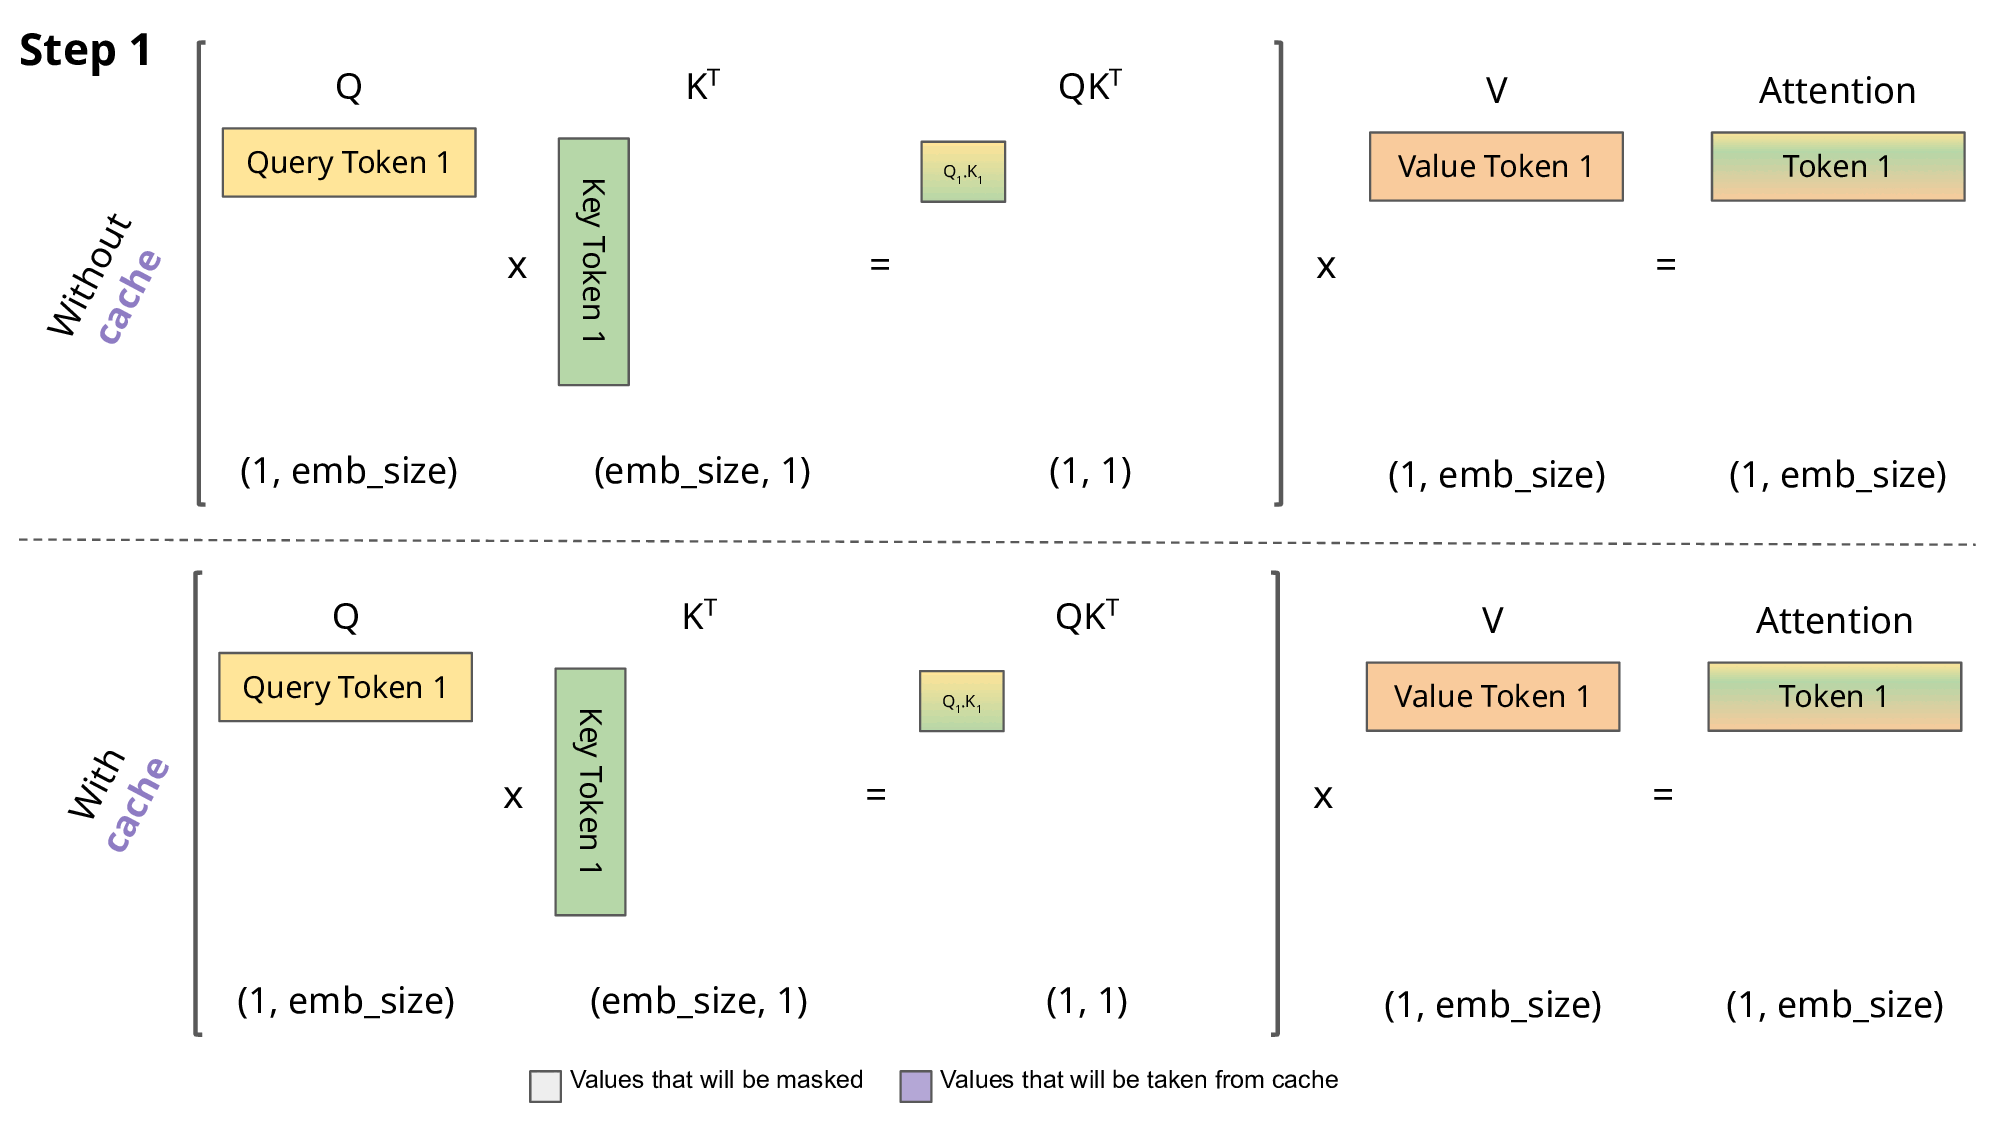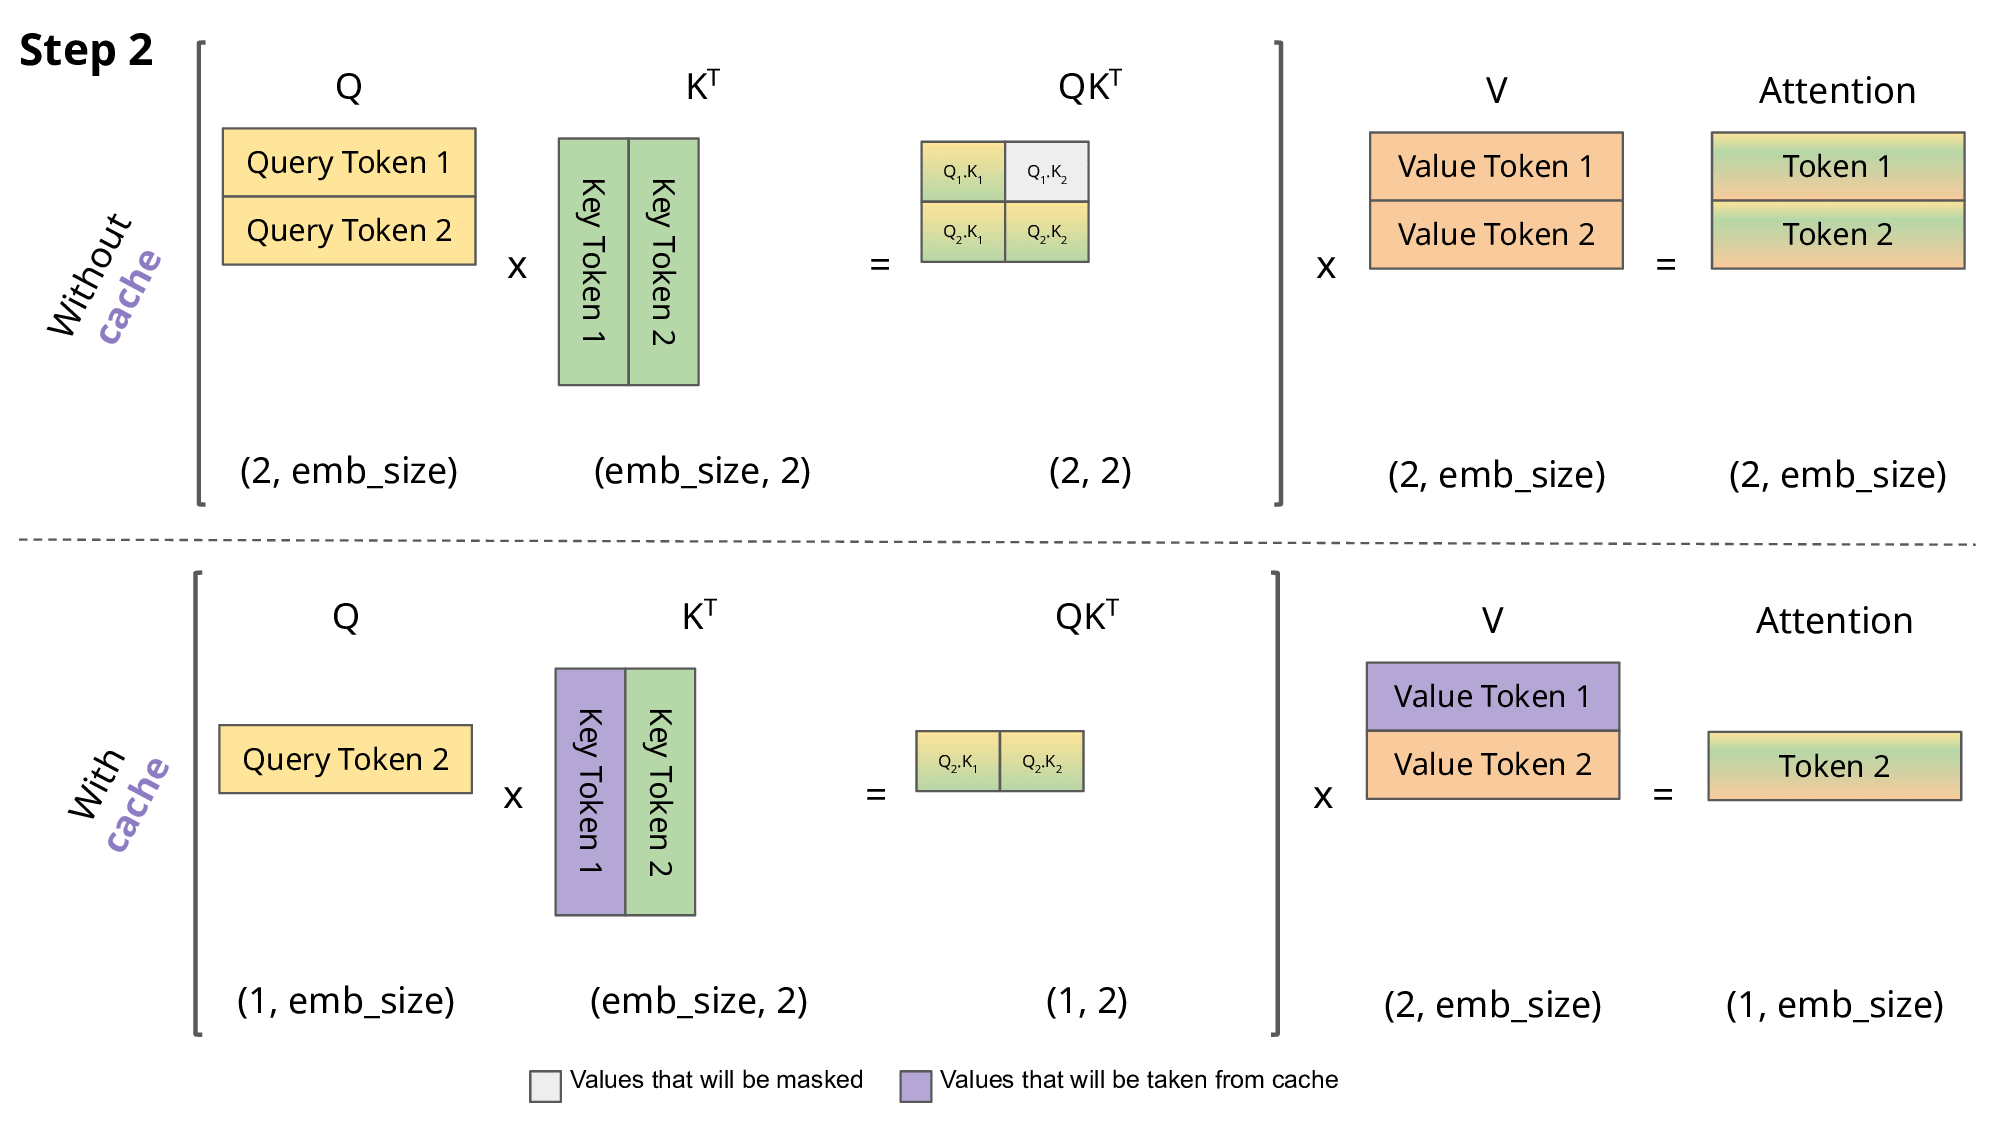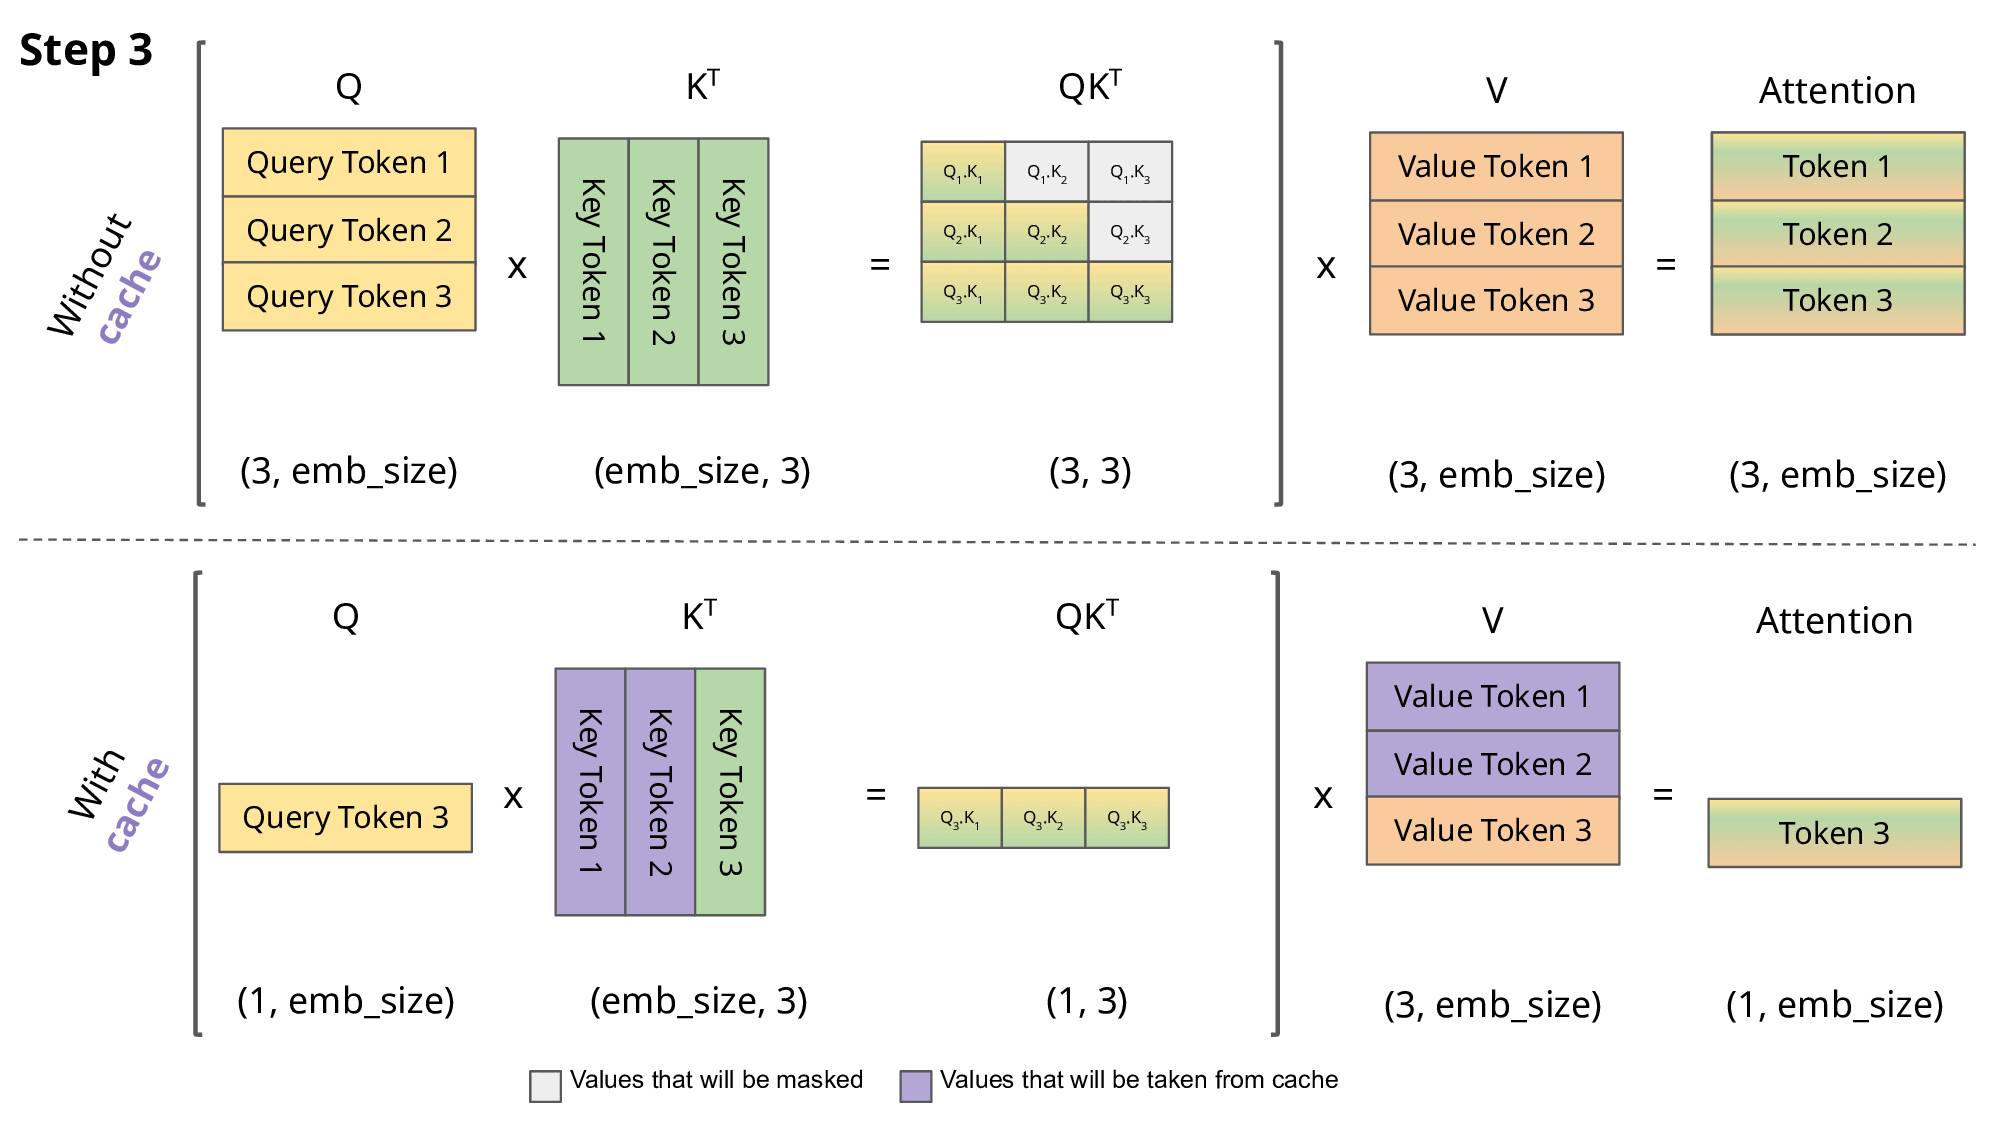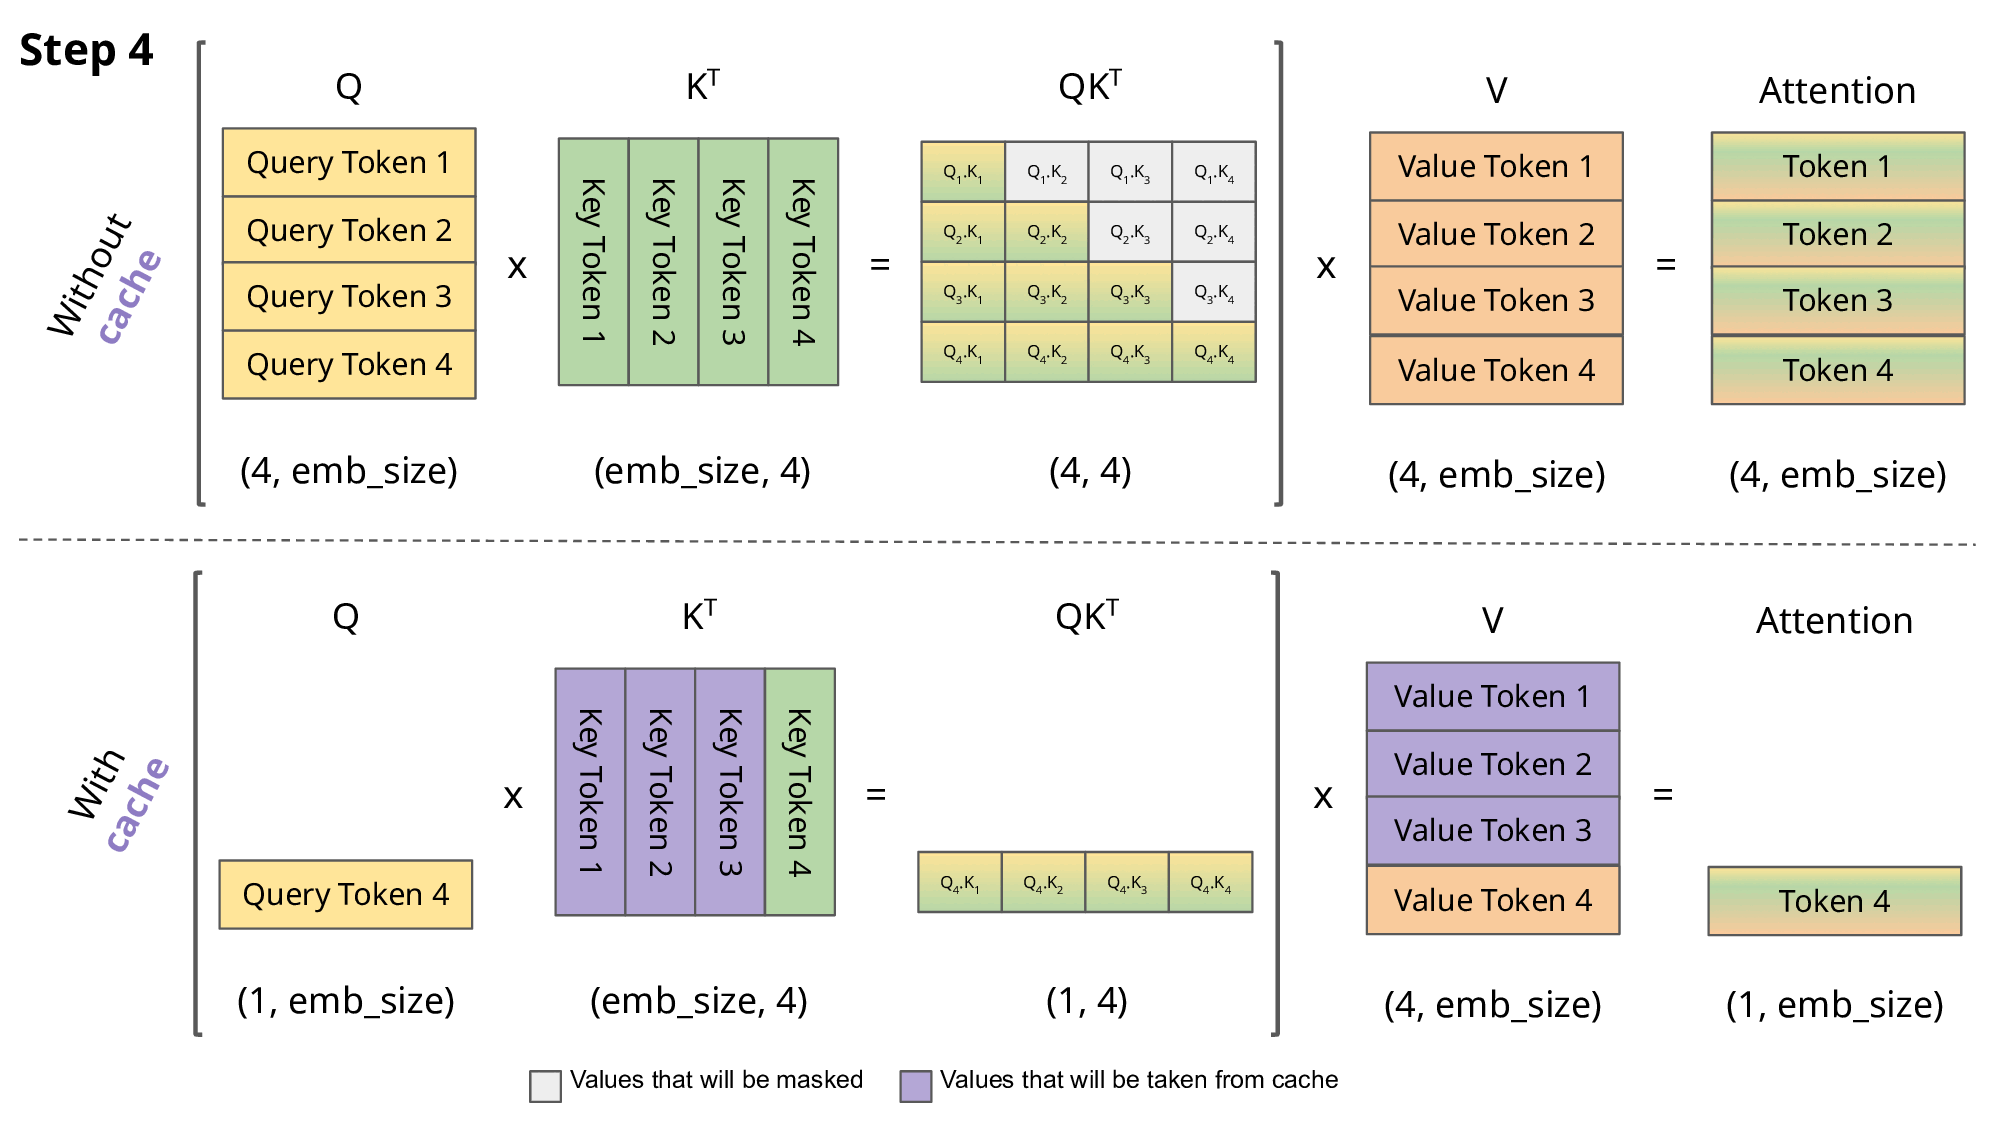
KV Cache 详解:新手也能理解的 LLM 推理加速技巧-CSDN博客

LLM KV Cache 从0到1:原理、实现与工程实践-CSDN博客
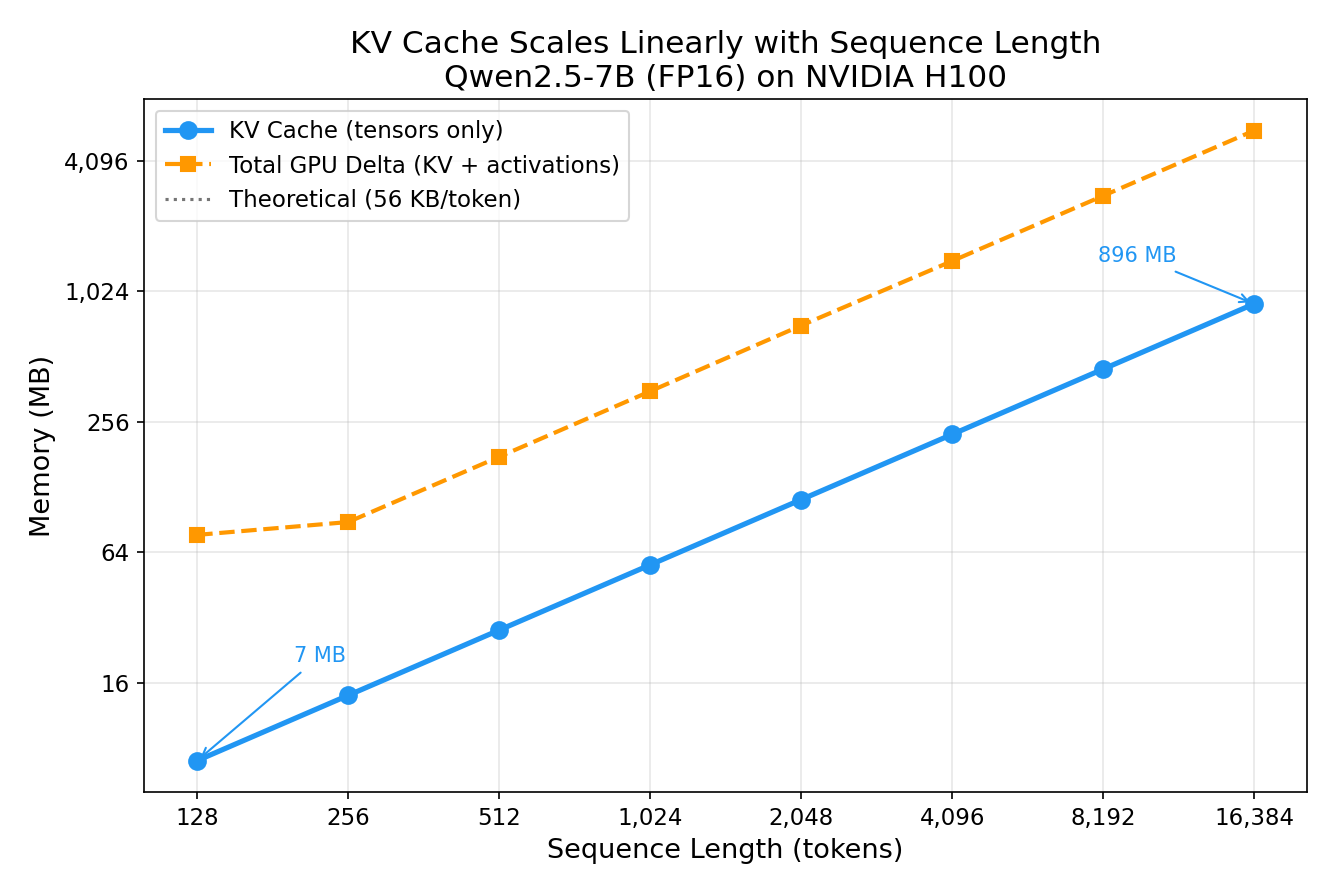
Understanding KV Cache in LLM Inference - Jingchao’s Website
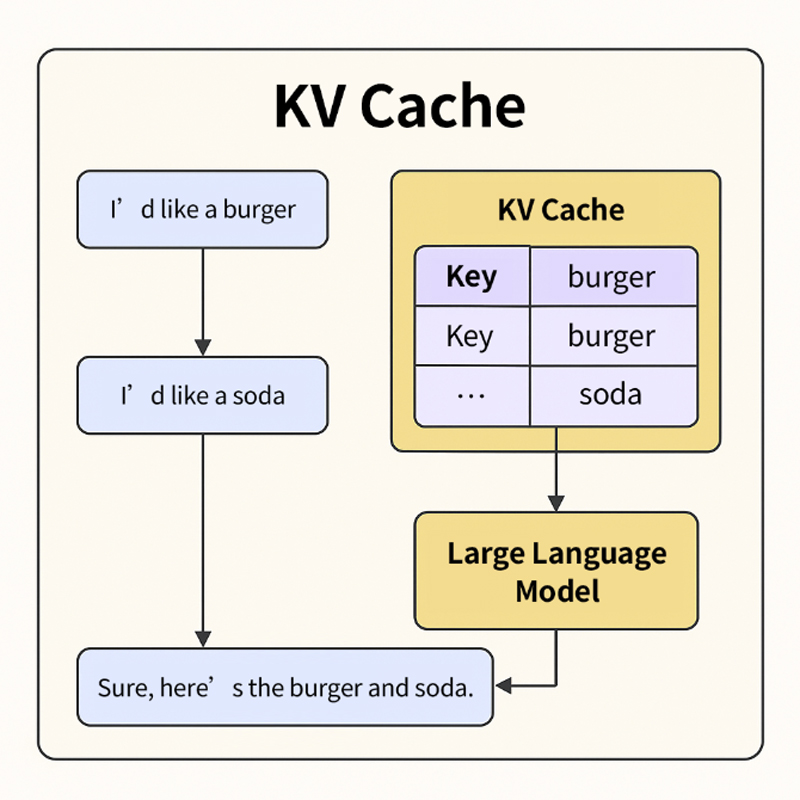
KV Cache Meets NVMe: The Key to Accelerating LLM Inference
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...
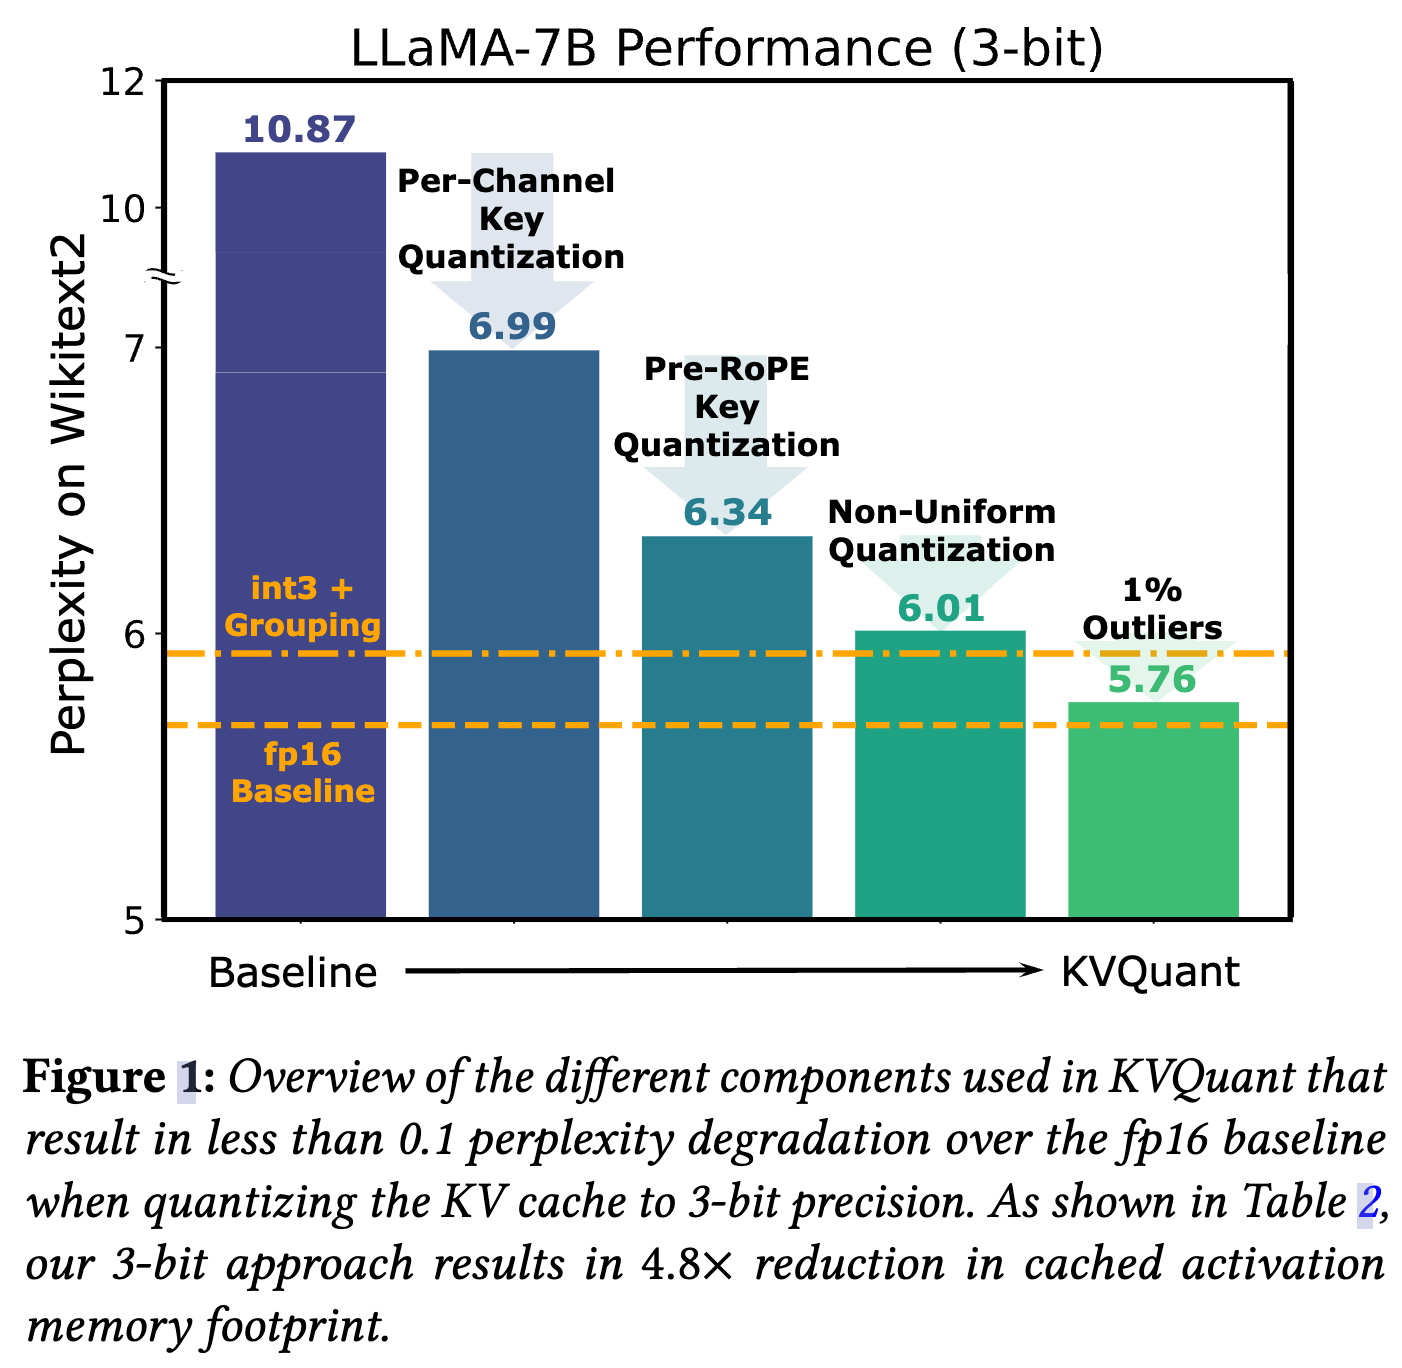
KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache ...
Advertisement Space (300x250)
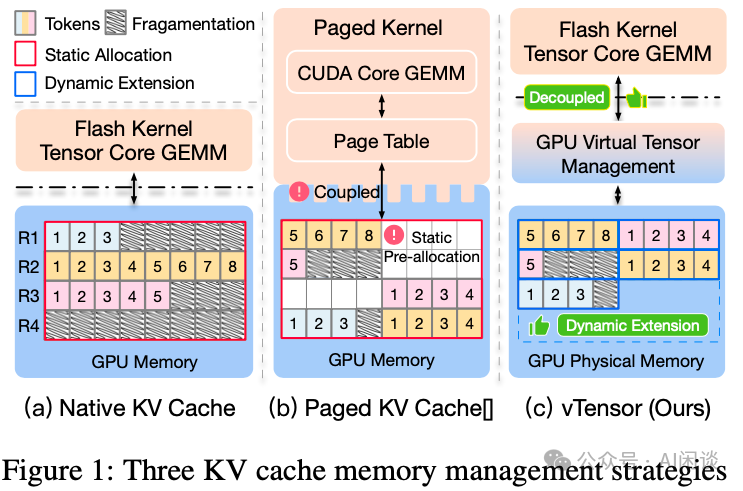
LLM 推理的 Attention 计算和 KV Cache 优化:PagedAttention、vAttention 等_paged ...

LLM 推理的 Attention 计算和 KV Cache 优化:PagedAttention、vAttention 等_paged ...

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

KV Cache Offload Accelerates LLM Inference - NADDOD Blog

南京大学 LLM 开发基础(六)推理优化 KV Cache + Sparse Attention_nju spar-CSDN博客

南京大学 LLM 开发基础(六)推理优化 KV Cache + Sparse Attention_nju spar-CSDN博客
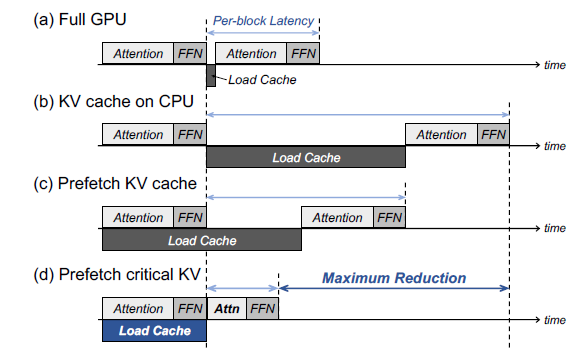
LLM Inference: Accelerating Long Context Generation with KV Cache ...
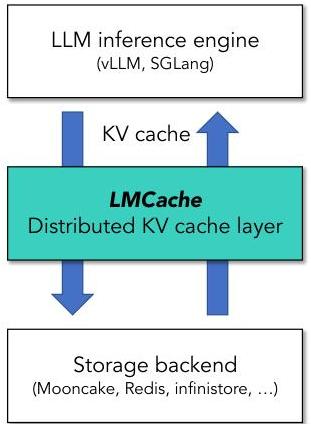
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

LLM - Generate With KV-Cache 图解与实践 By GPT-2_llm kv cache-CSDN博客
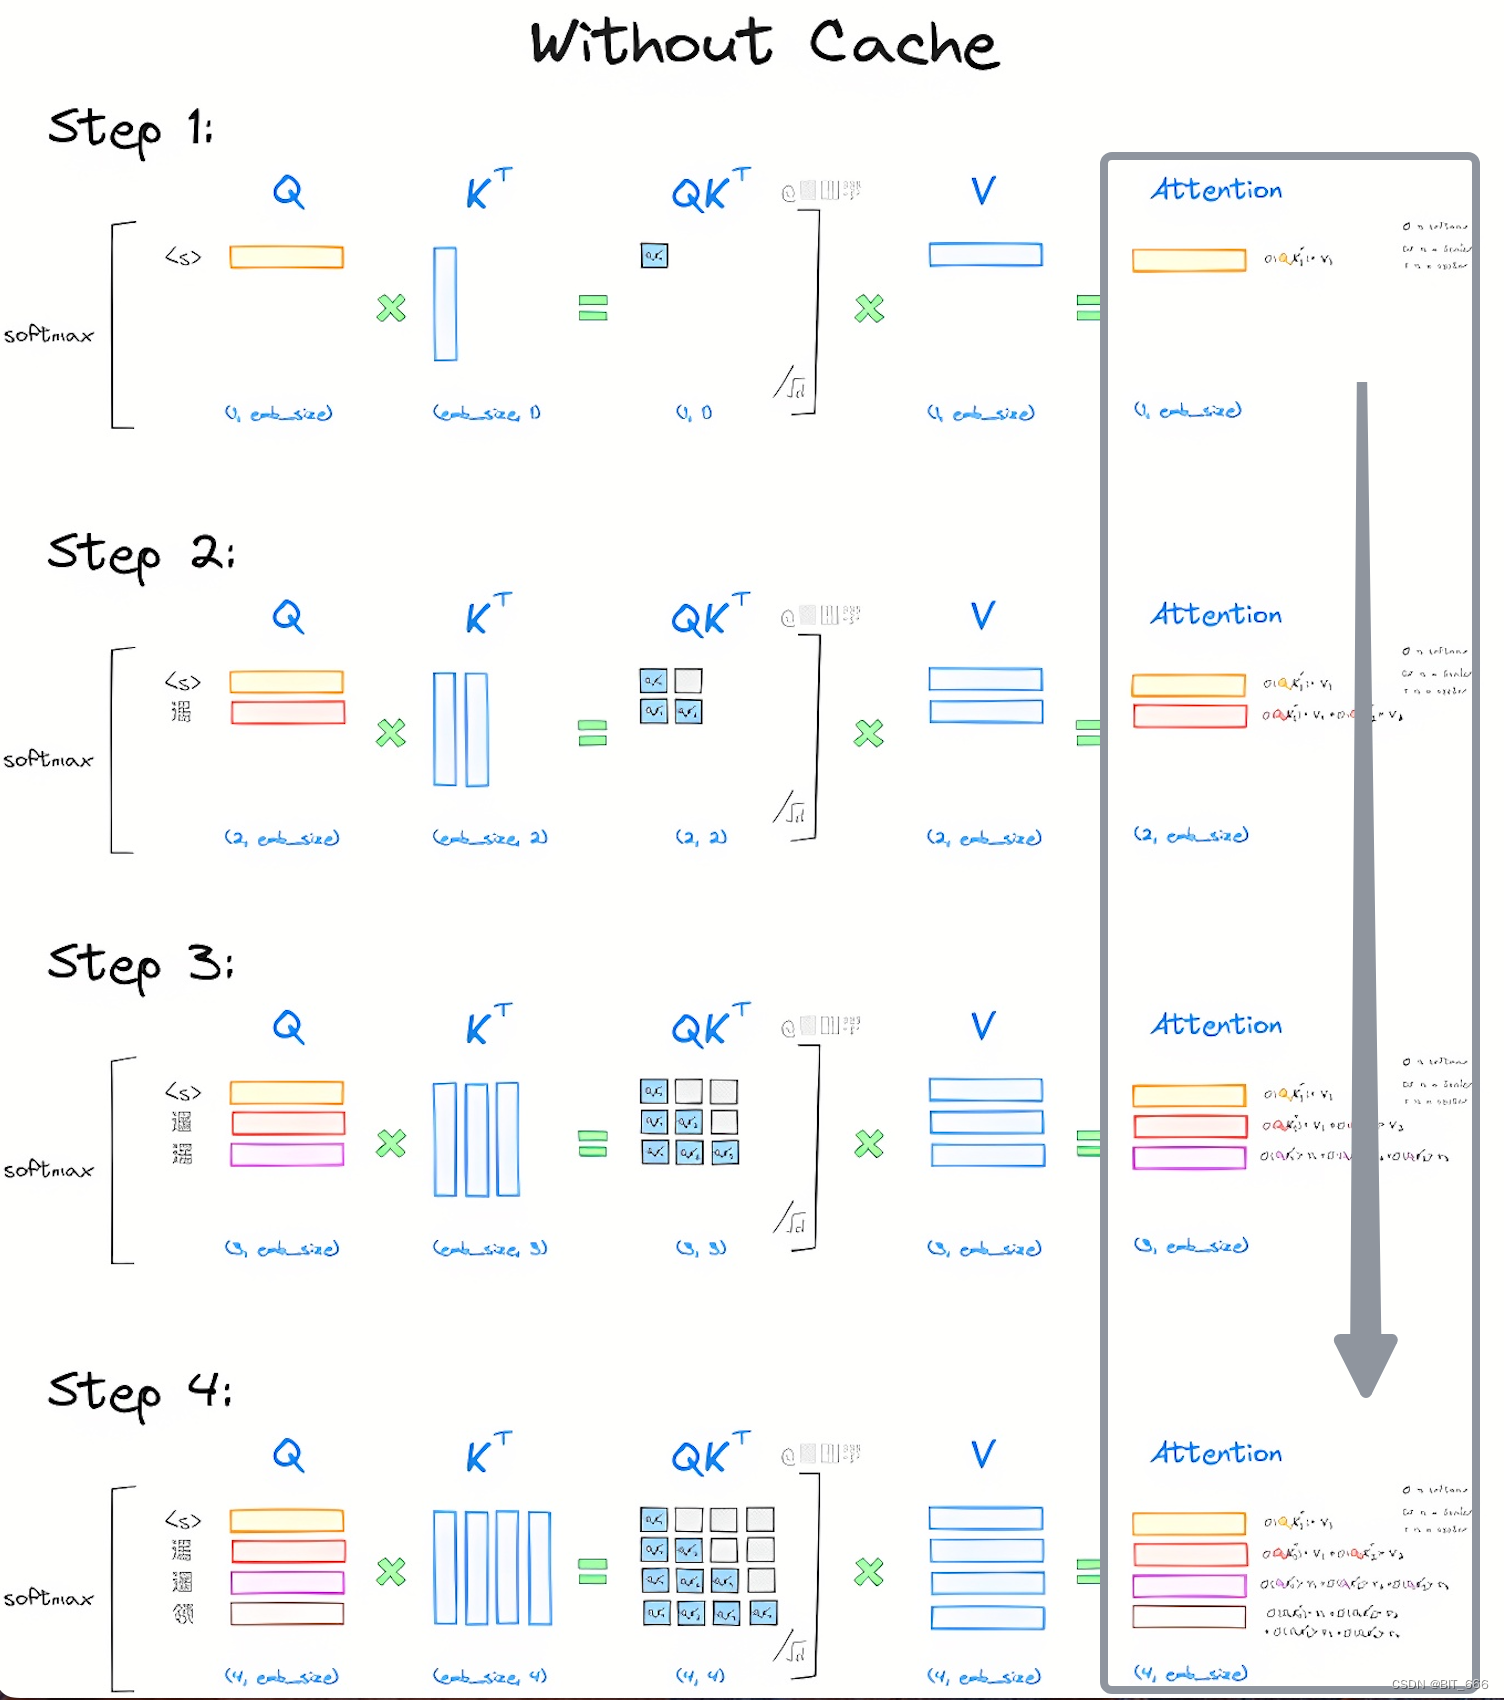
LLM - Generate With KV-Cache 图解与实践 By GPT-2_llm kv cache-CSDN博客
Advertisement Space (336x280)
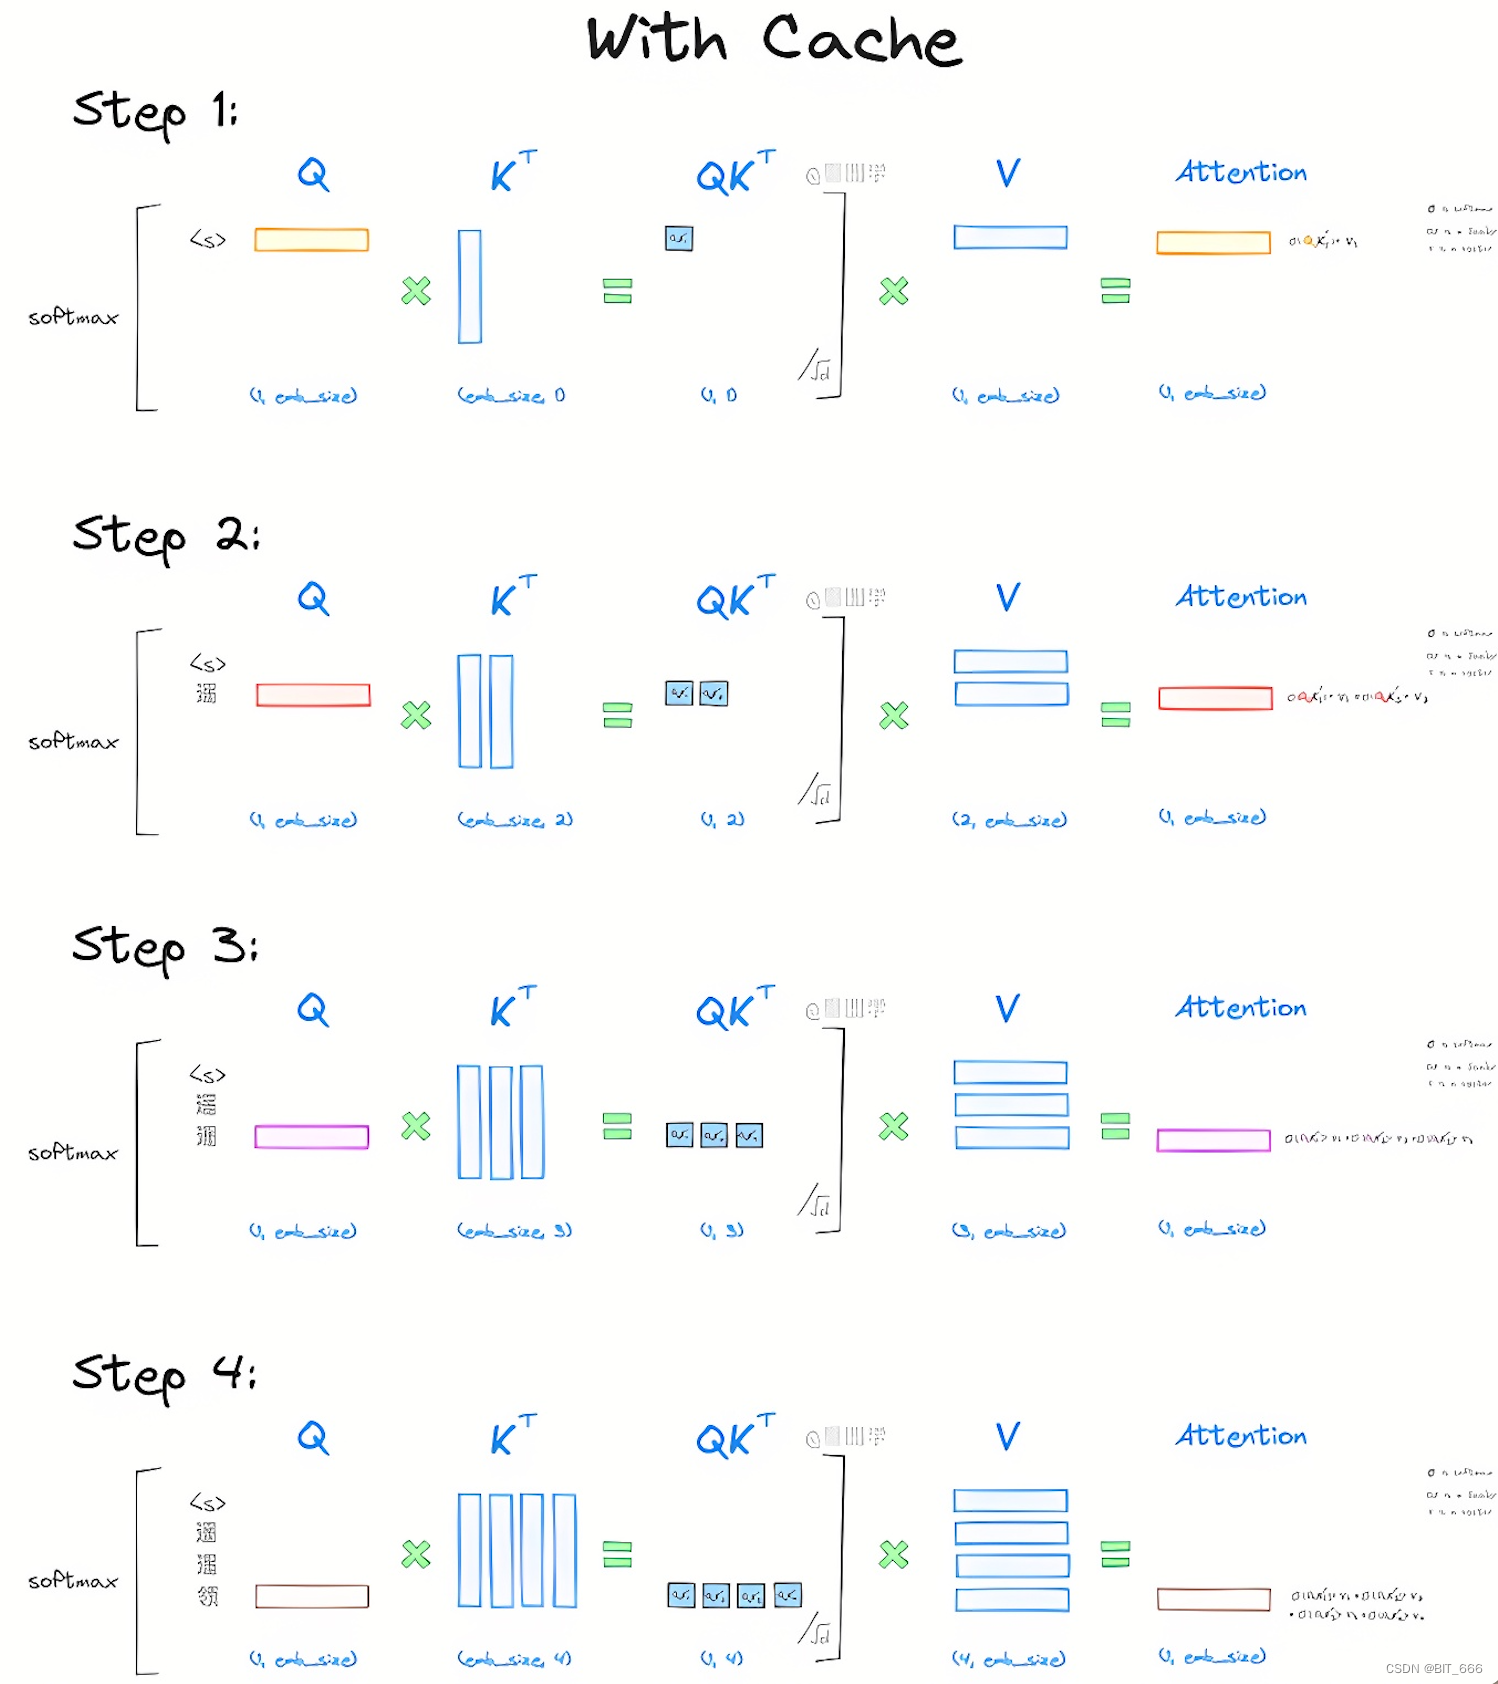
LLM - Generate With KV-Cache 图解与实践 By GPT-2_llm kv cache-CSDN博客

LLM - Generate With KV-Cache 图解与实践 By GPT-2_llm kv cache-CSDN博客

LLM - Generate With KV-Cache 图解与实践 By GPT-2_llm kv cache-CSDN博客

5x Faster Time to First Token with NVIDIA TensorRT-LLM KV Cache Early ...
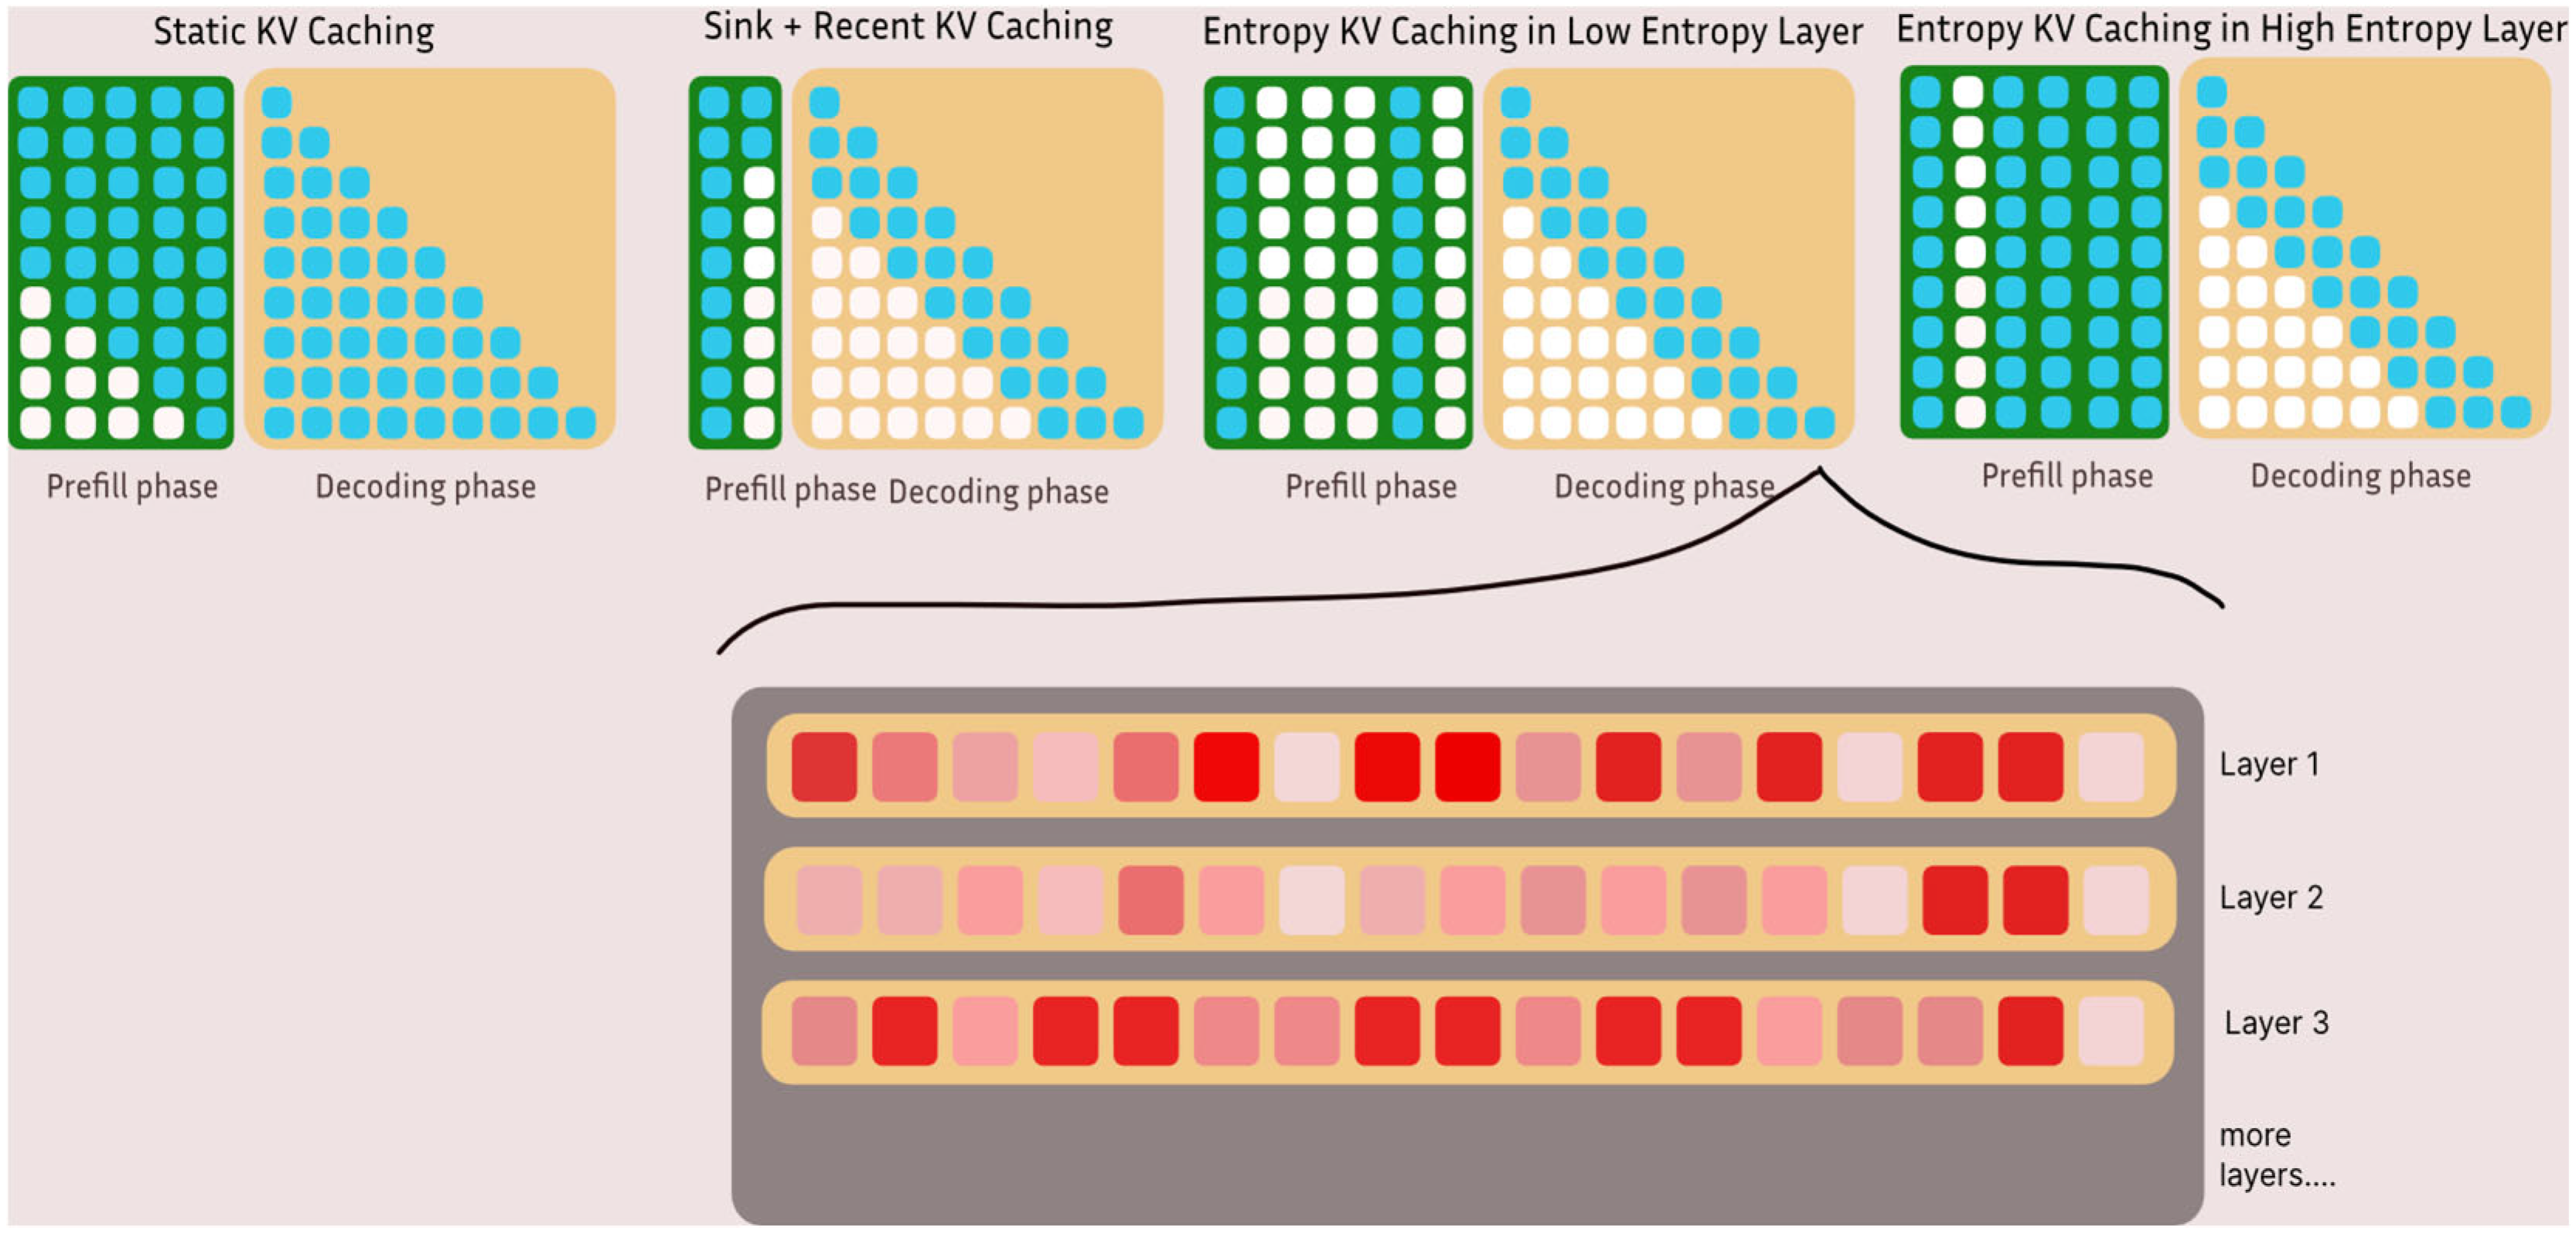
Entropy-Guided KV Caching for Efficient LLM Inference
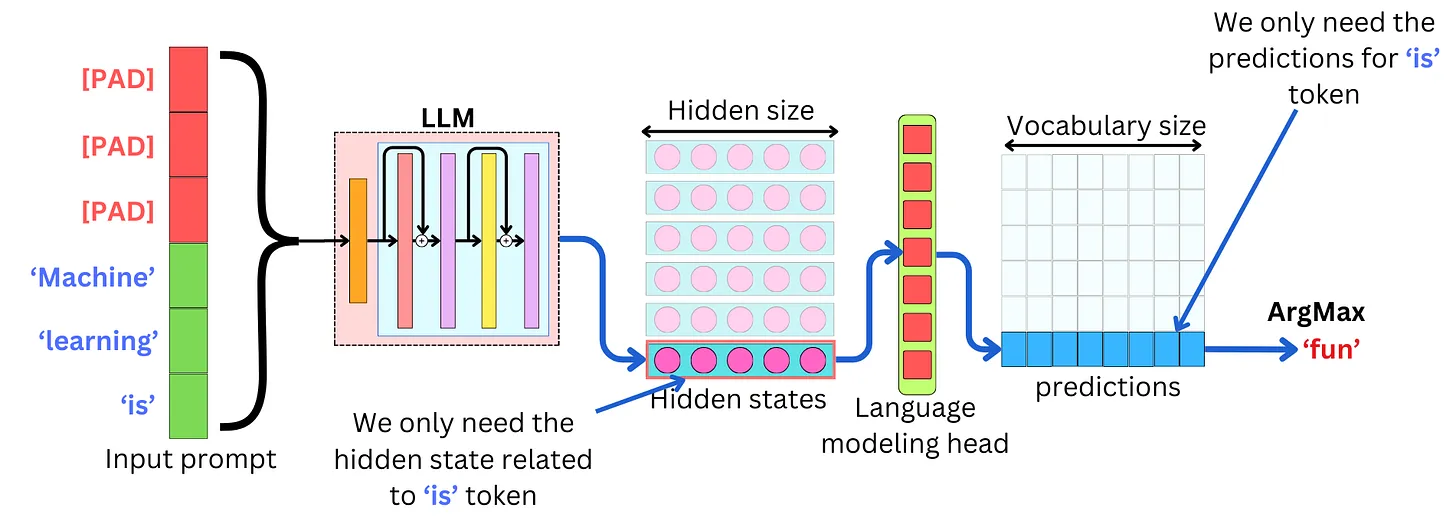
KV Cache 是如何降低大模型的Decode耗时的-CSDN博客

LLM - Generate With KV-Cache 图解与实践 By GPT-2_llm kv cache-CSDN博客
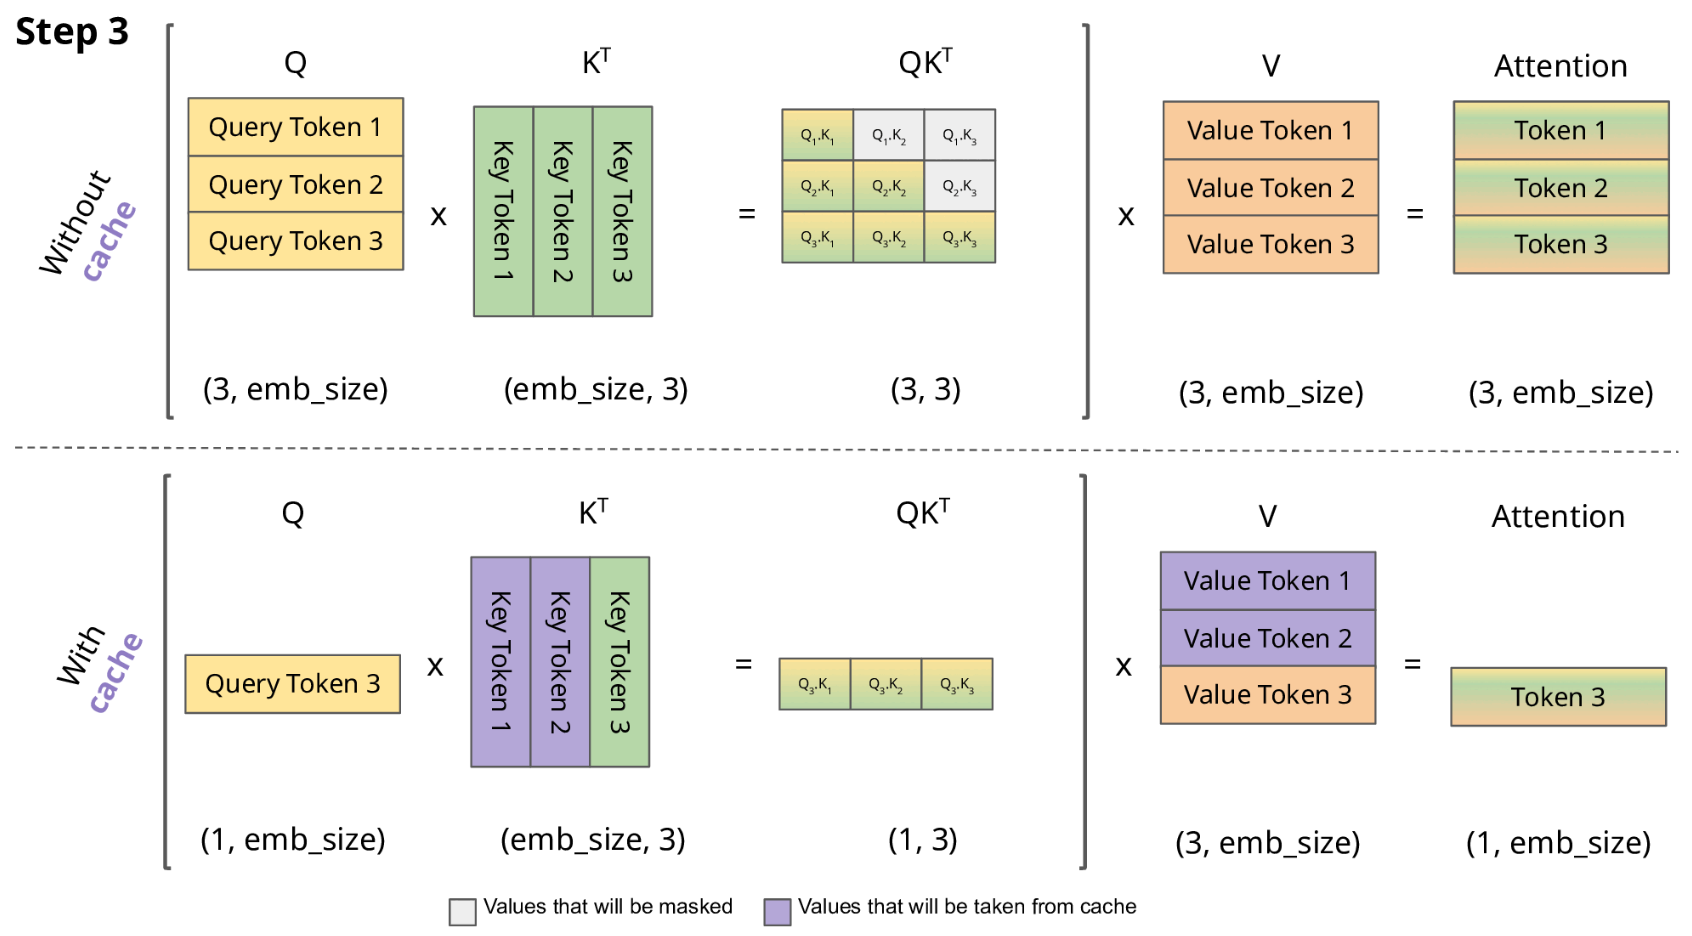
KV cache 缓存与量化:加速大型语言模型推理的关键技术_kvcache的量化怎么做-CSDN博客
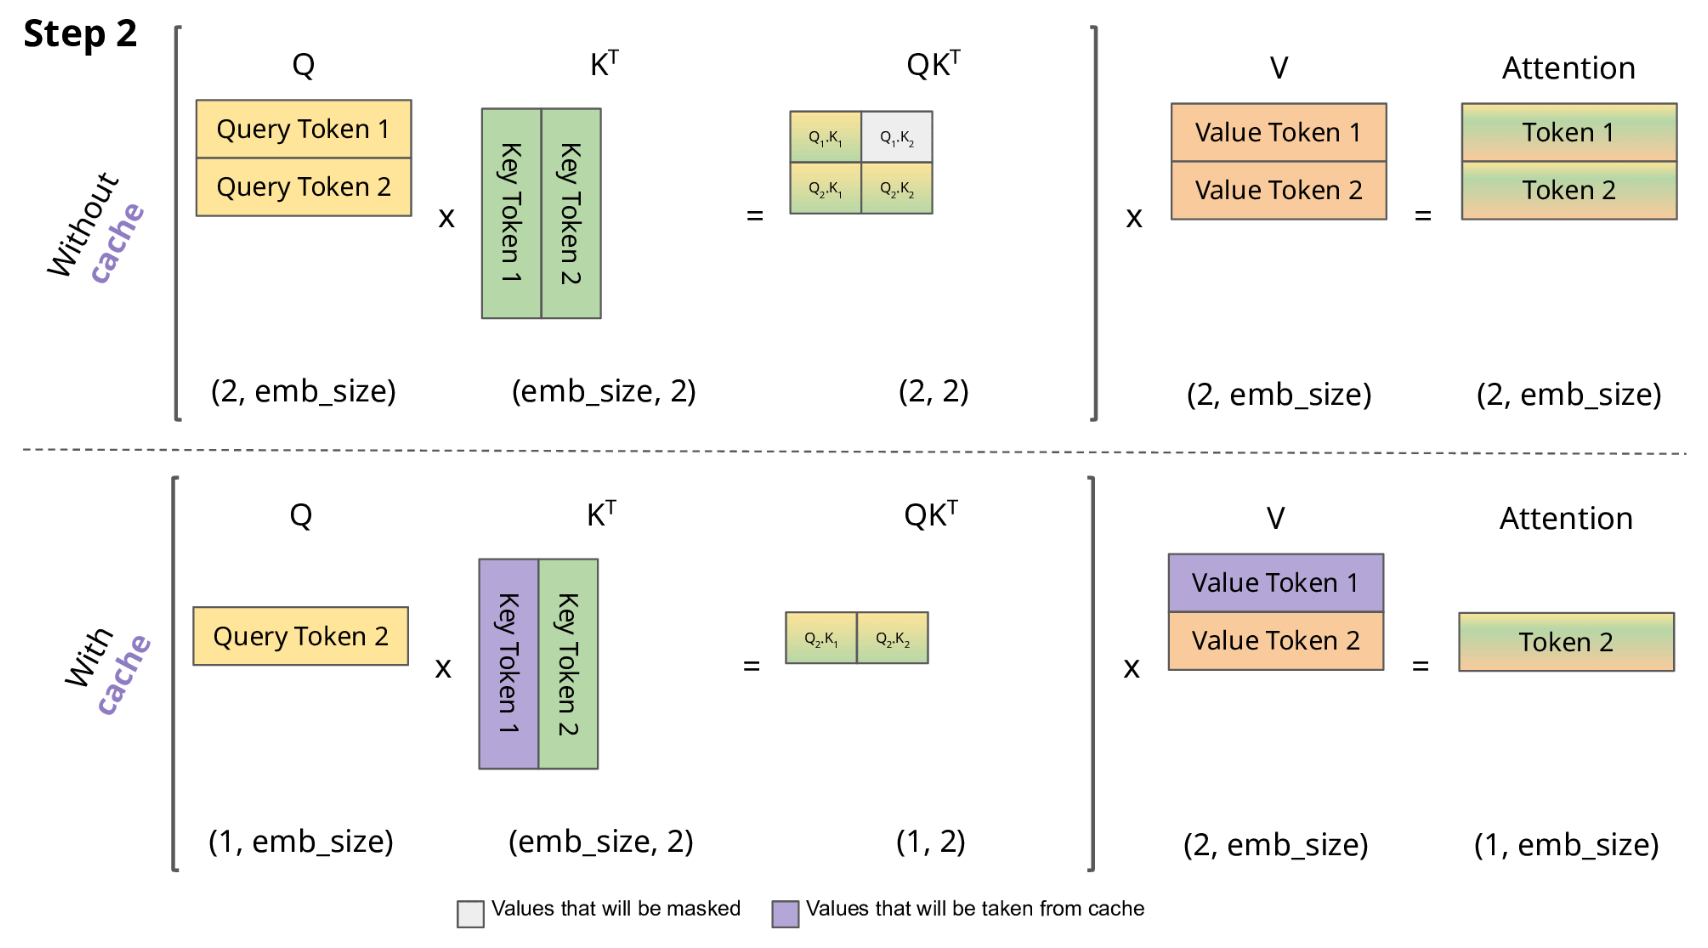
KV cache 缓存与量化:加速大型语言模型推理的关键技术_key-value(kv) cache 量化-CSDN博客

LLM - Generate With KV-Cache 图解与实践 By GPT-2_llm kv cache-CSDN博客
Advertisement Space (336x280)
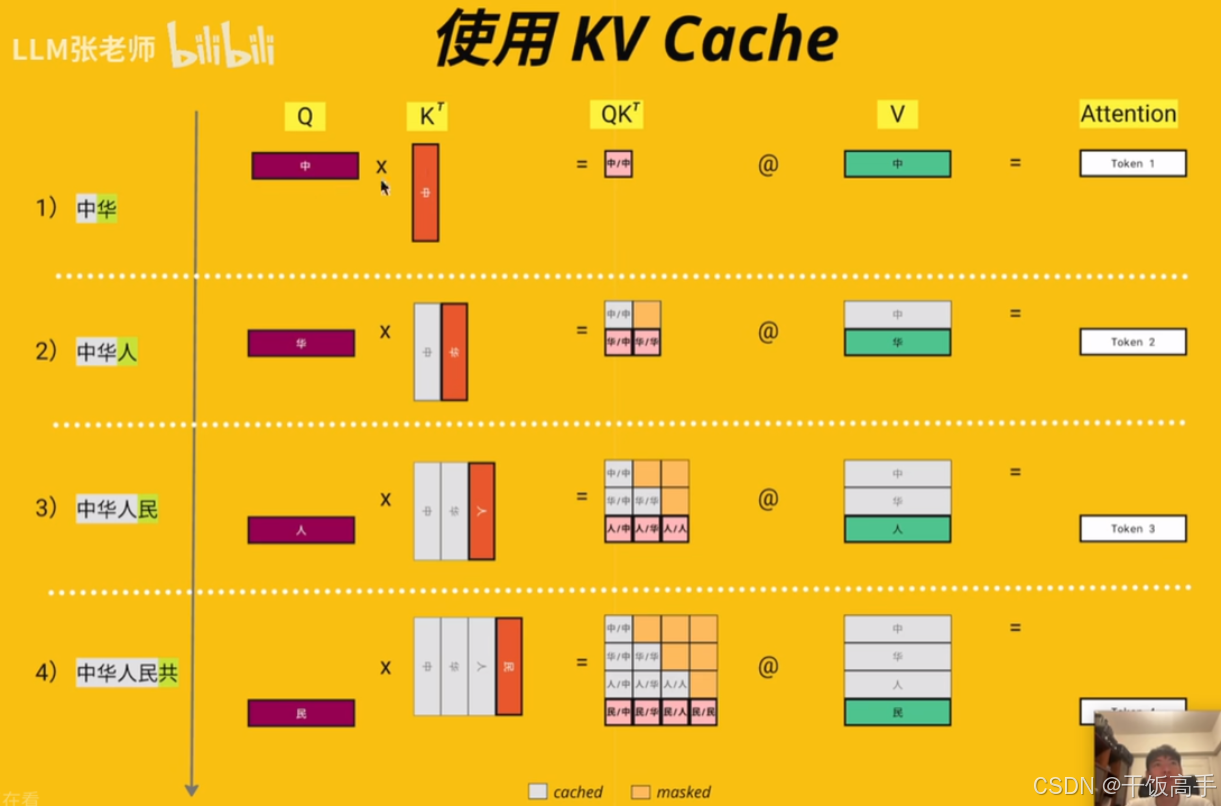
KV cache 以及 Attention 各种变种_attention kv cache-CSDN博客
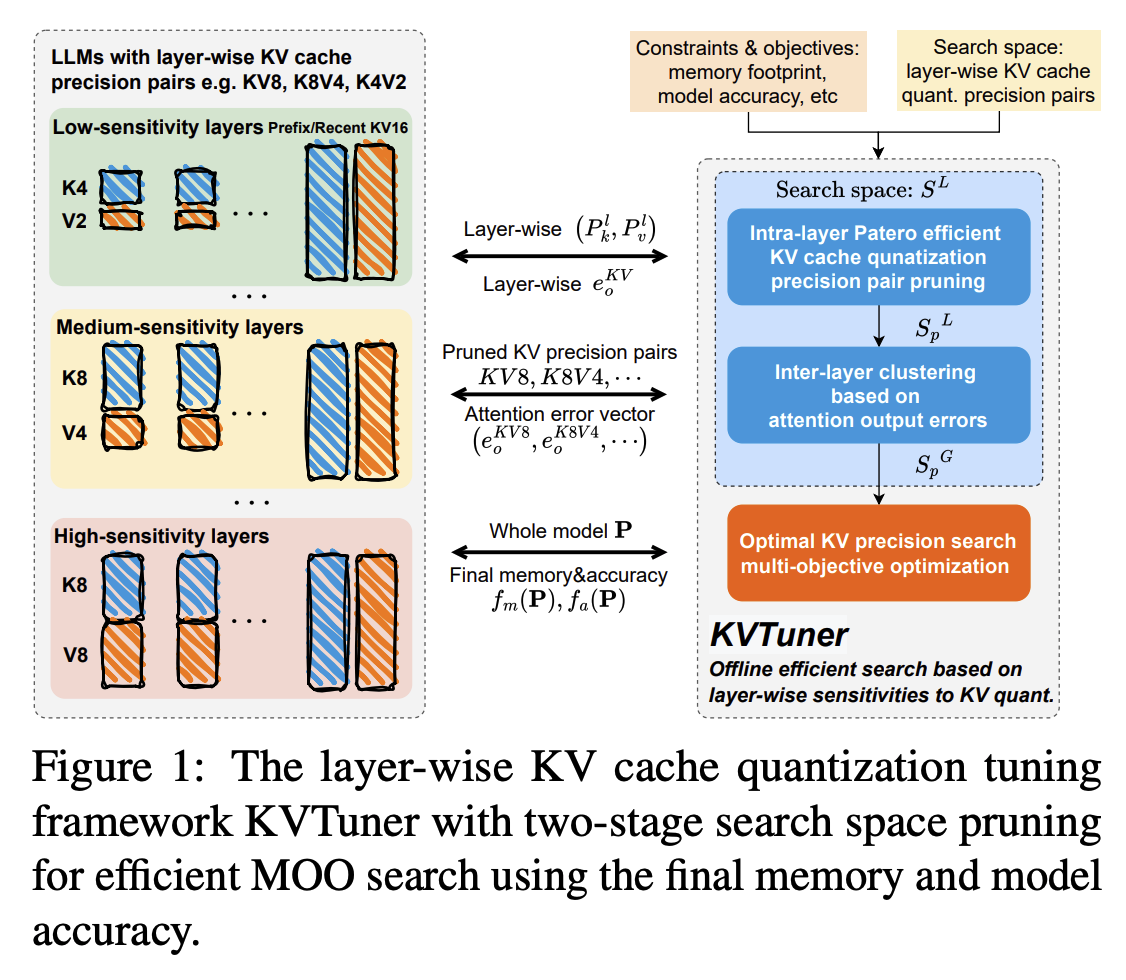
KVTuner: Sensitivity-Aware Layer-Wise Mixed-Precision KV Cache ...
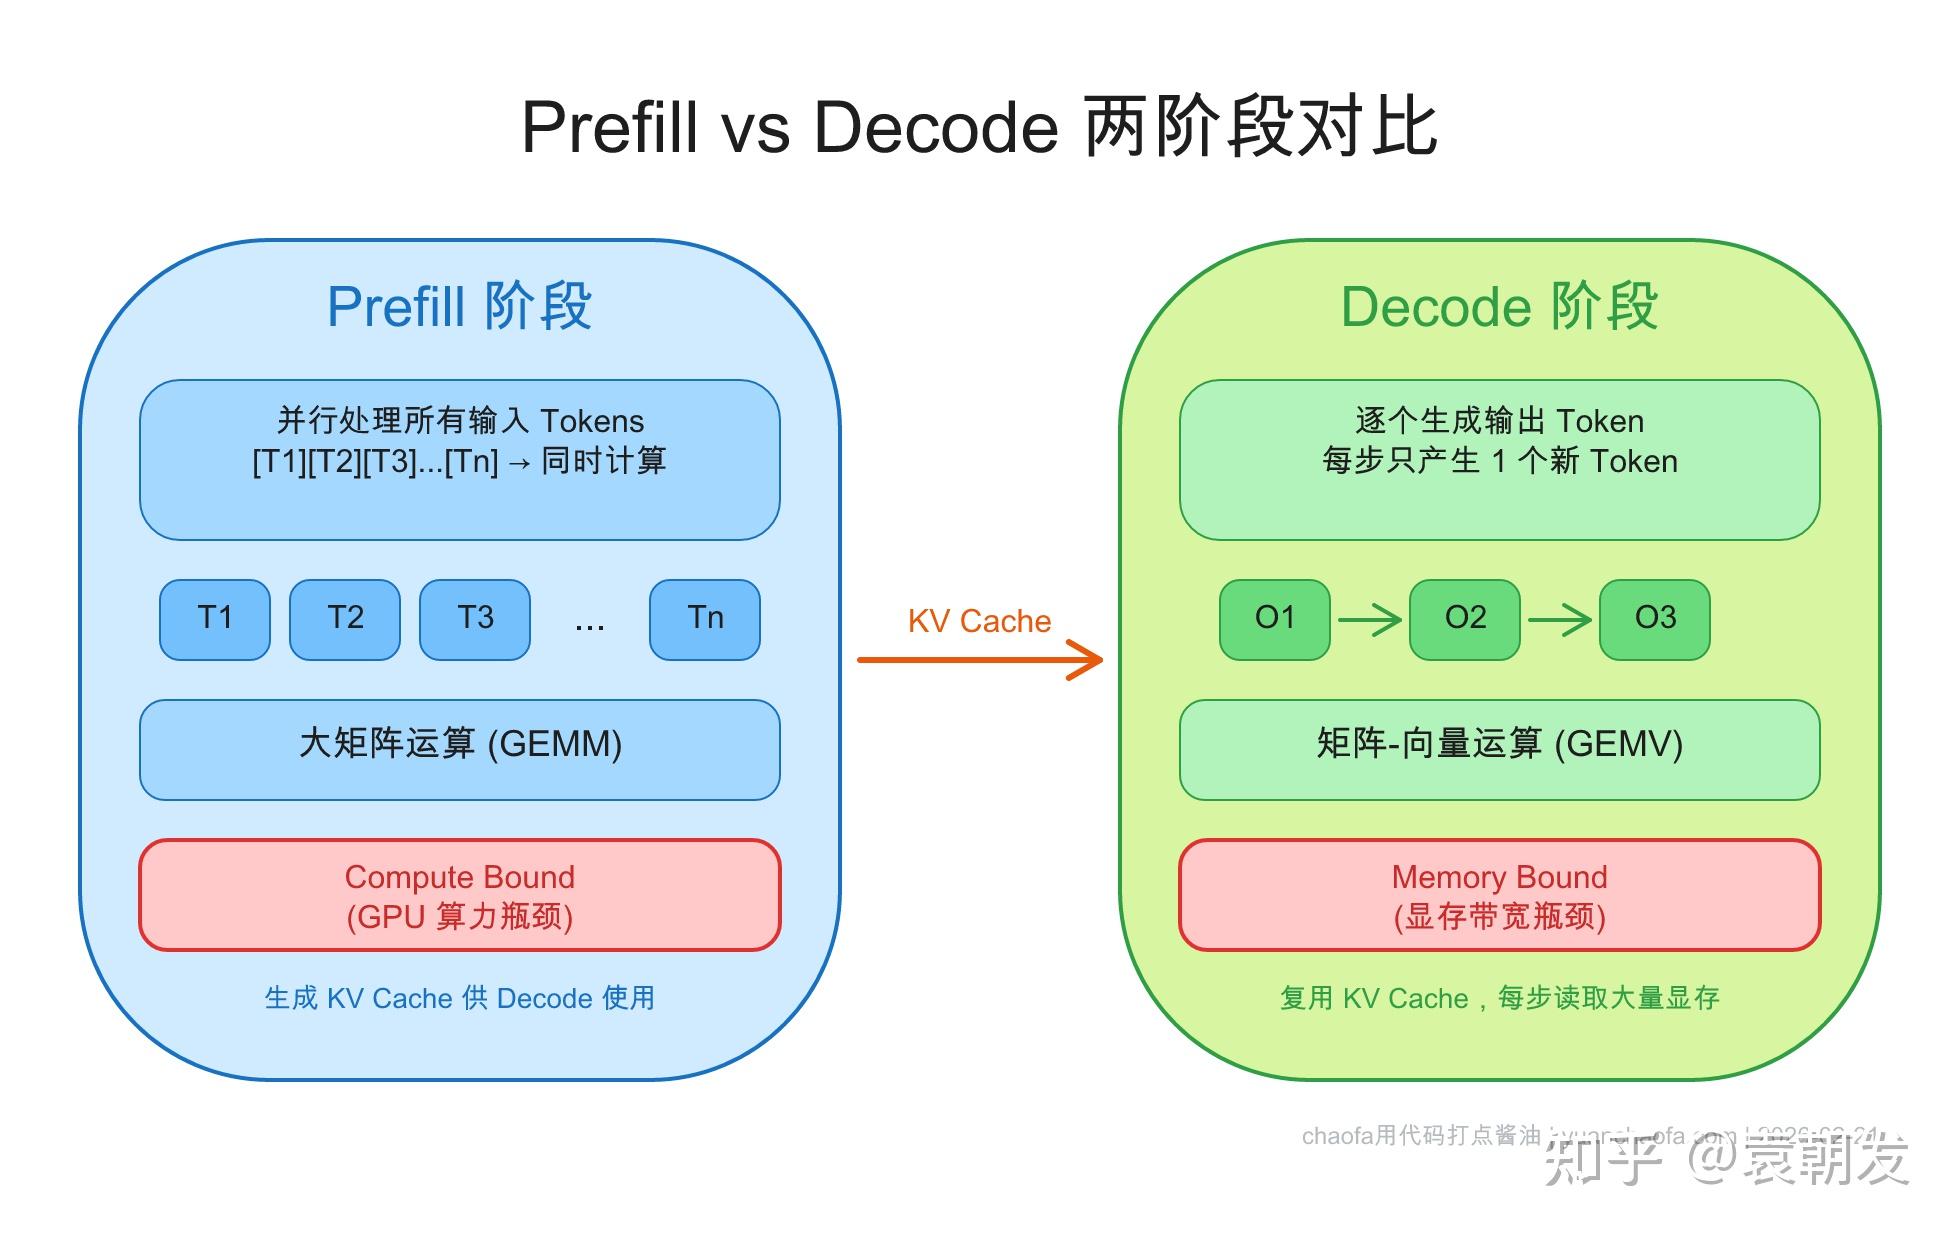
理解 KV Cache 与 Prompt Caching:LLM 推理加速的核心机制 - 知乎

KV Cache 技术分析-CSDN博客
What is KV Cache? | LLM Inference Optimization | Inference Systems
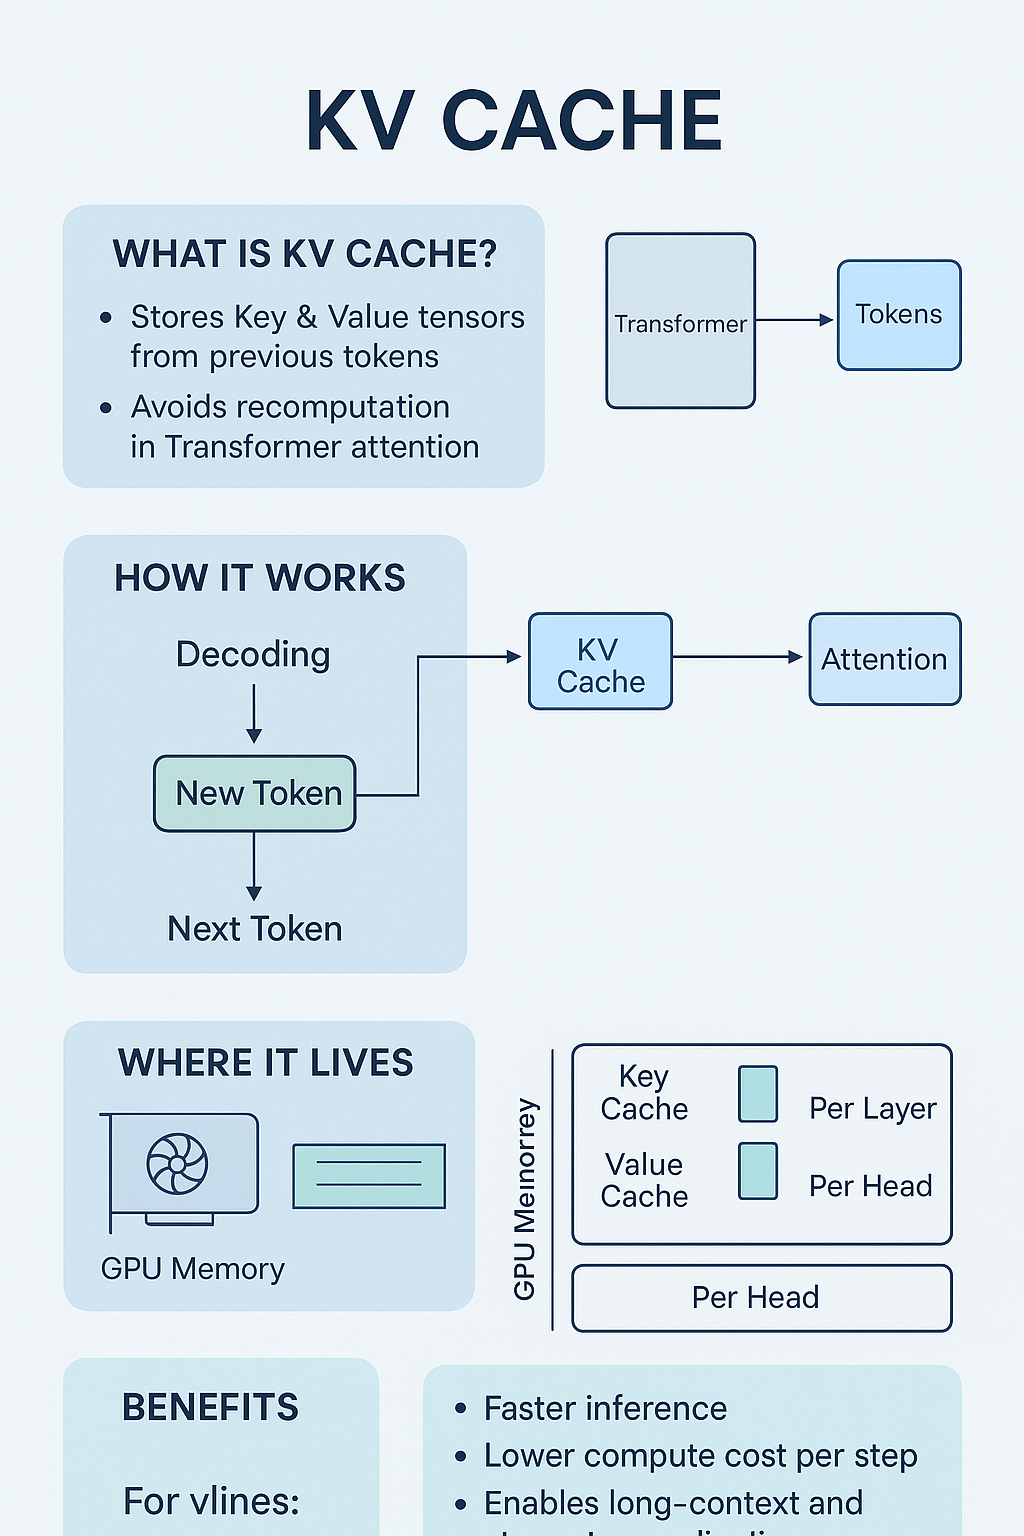
【LLMs篇】19:vLLM推理中的KV Cache技术全解析_vllm kv cache-CSDN博客