
Llm Elyza Aws Inferentia2 Speculative Decoding

LLM 社会実装を進める ELYZA 社: AWS Inferentia2 × Speculative Decoding の組み合わせは世界初 ...

LLM 社会実装を進める ELYZA 社: AWS Inferentia2 × Speculative Decoding の組み合わせは世界初 ...

LLM 社会実装を進める ELYZA 社: AWS Inferentia2 × Speculative Decoding の組み合わせは世界初 ...

LLM 社会実装を進める ELYZA 社: AWS Inferentia2 × Speculative Decoding の組み合わせは世界初 ...

LLM 社会実装を進める ELYZA 社: AWS Inferentia2 × Speculative Decoding の組み合わせは世界初 ...

LLM 社会実装を進める ELYZA 社: AWS Inferentia2 × Speculative Decoding の組み合わせは世界初 ...

Faster LLMs with speculative decoding and AWS Inferentia2

Tuto Startup - Faster LLMs with speculative decoding and AWS Inferentia2
🚀 Speed Up LLM Inference with Speculative Decoding | by Generative AI ...

Speculative Decoding with CTC-based Draft Model for LLM Inference ...
Advertisement Space (300x250)
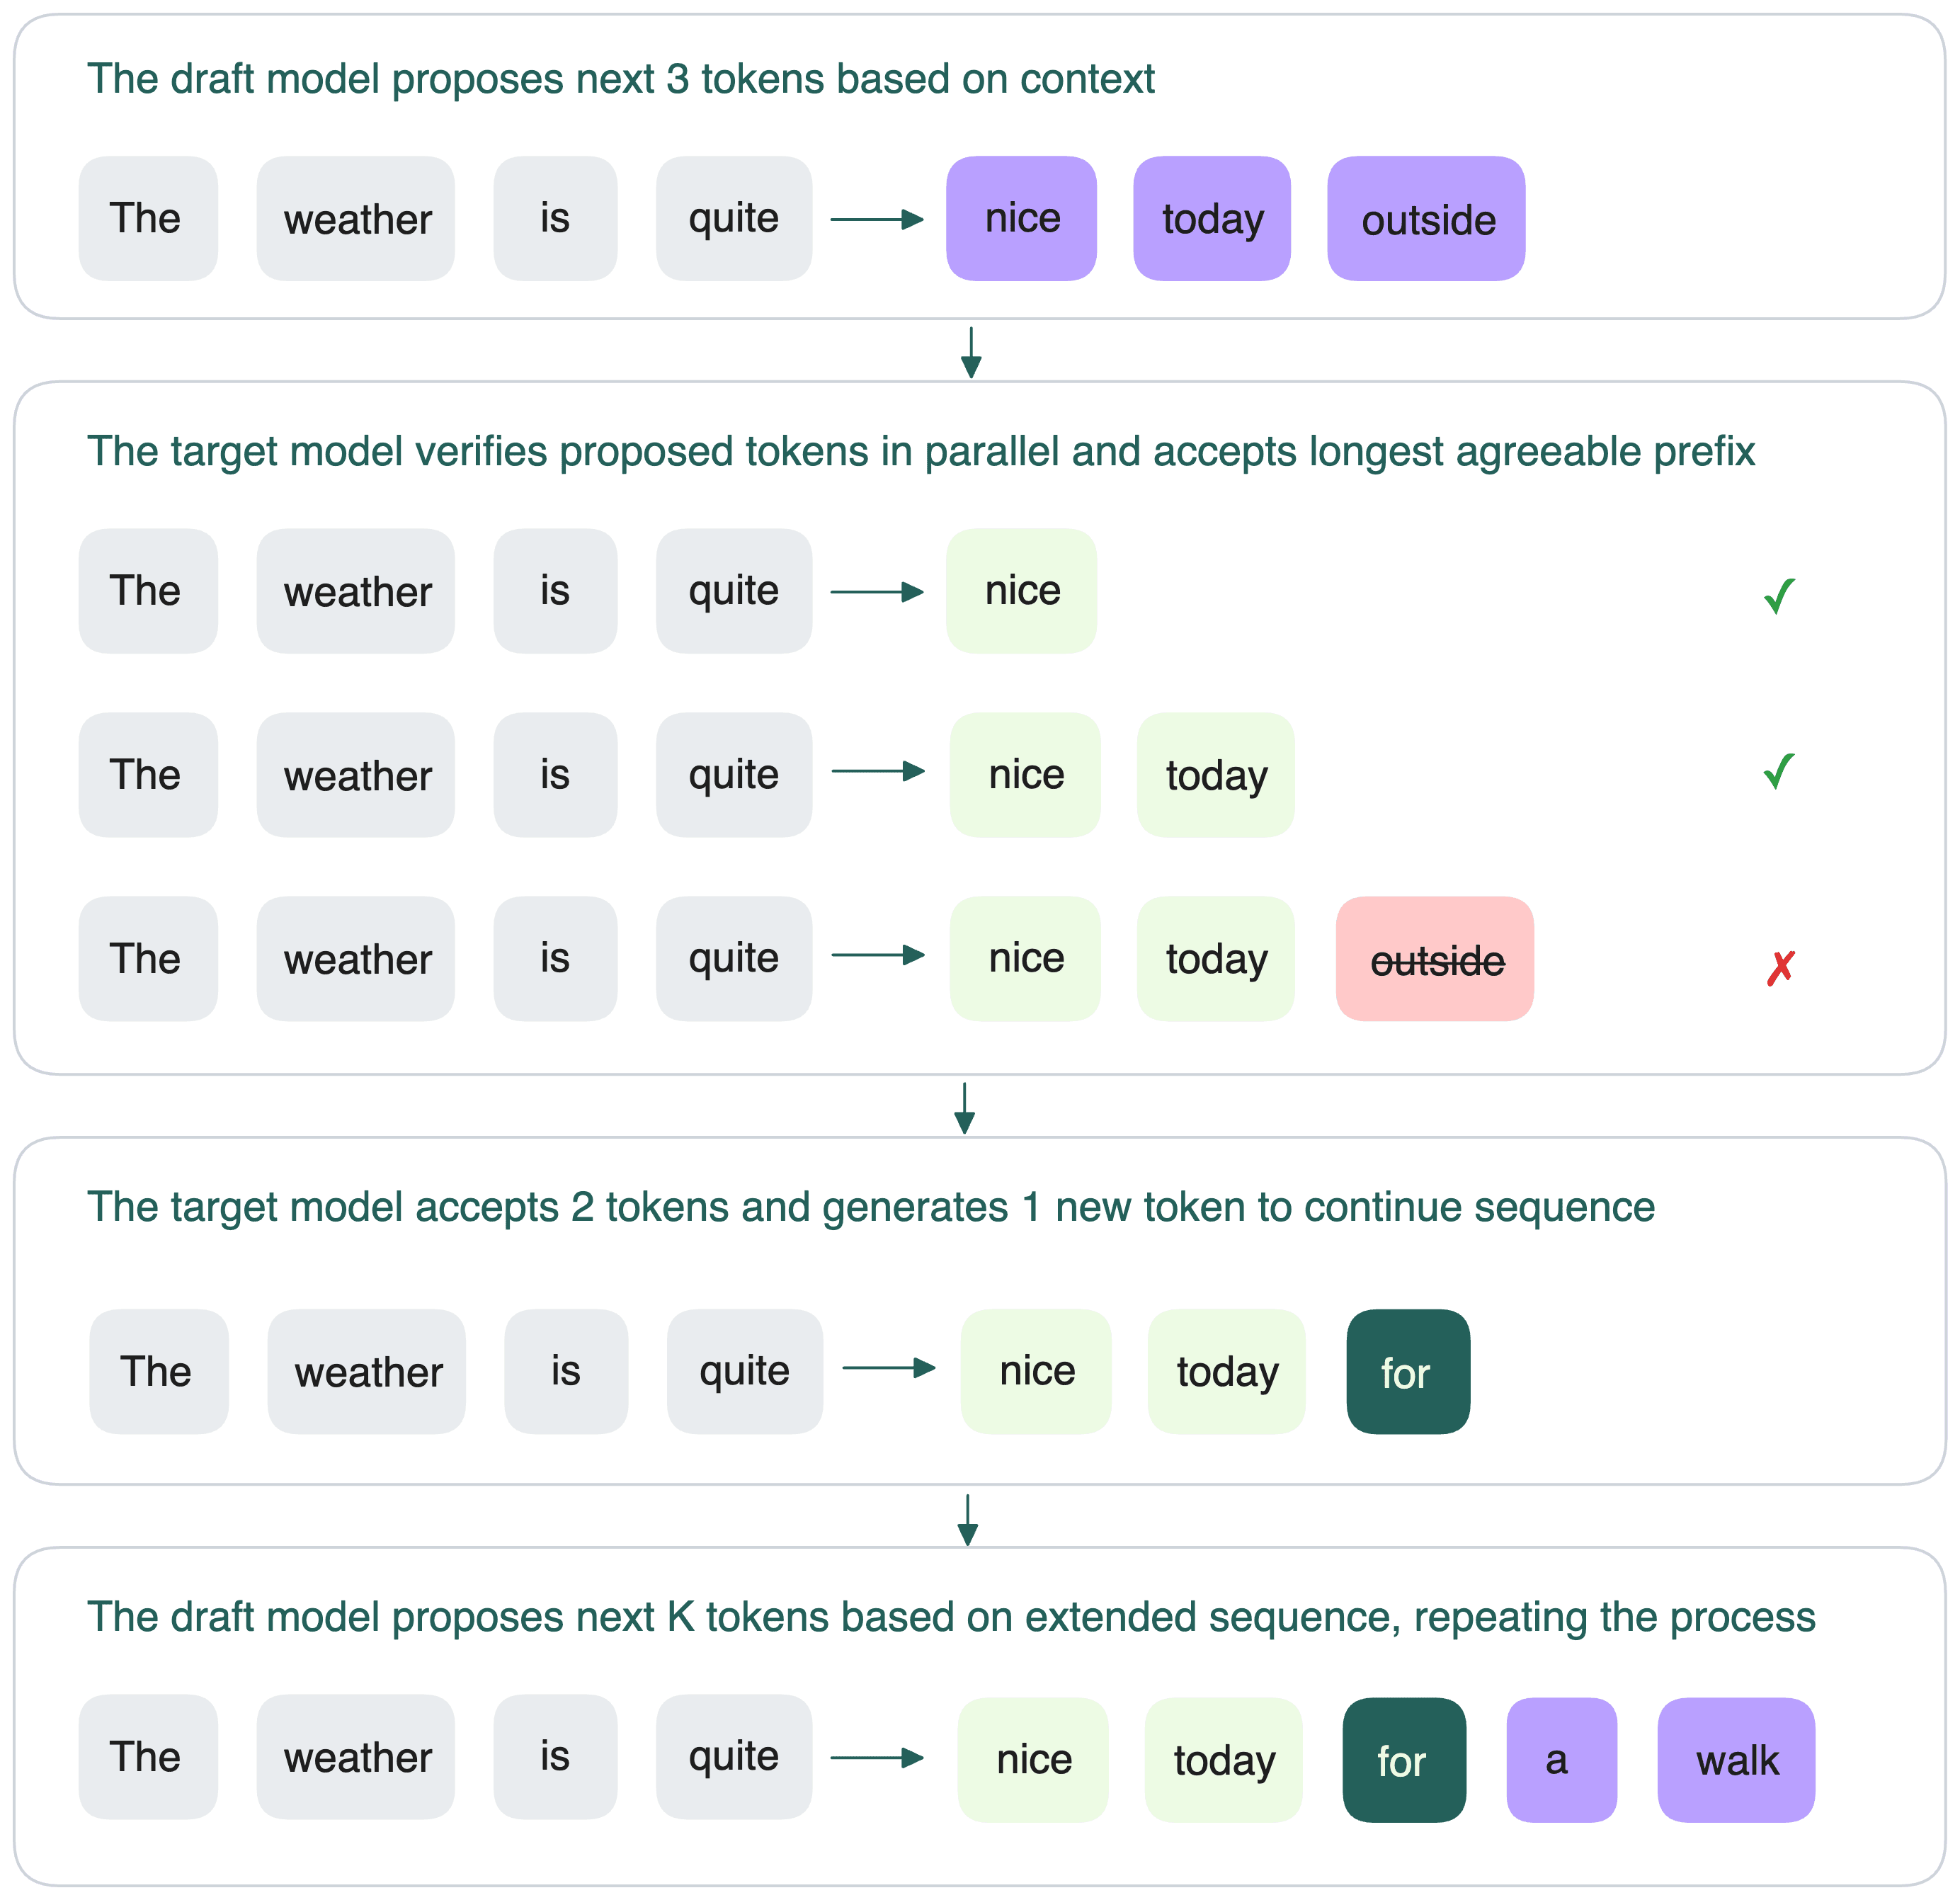
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...

A Survey of Speculative Decoding Techniques in LLM Inference
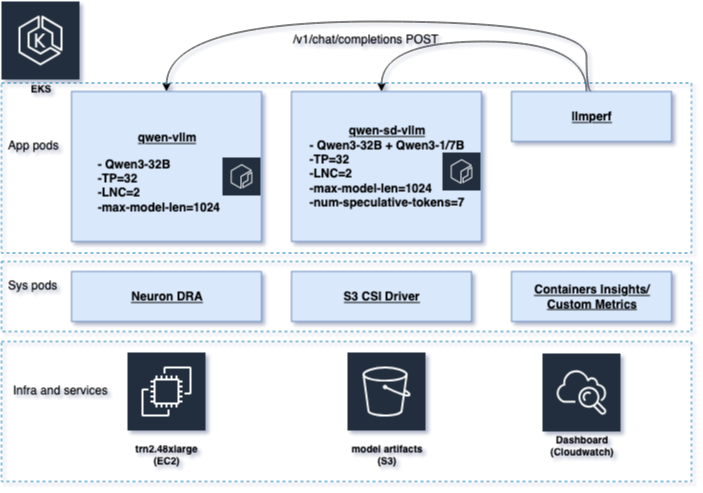
Accelerating decode-heavy LLM inference with speculative decoding on ...
Accelerating decode-heavy LLM inference with speculative decoding on ...
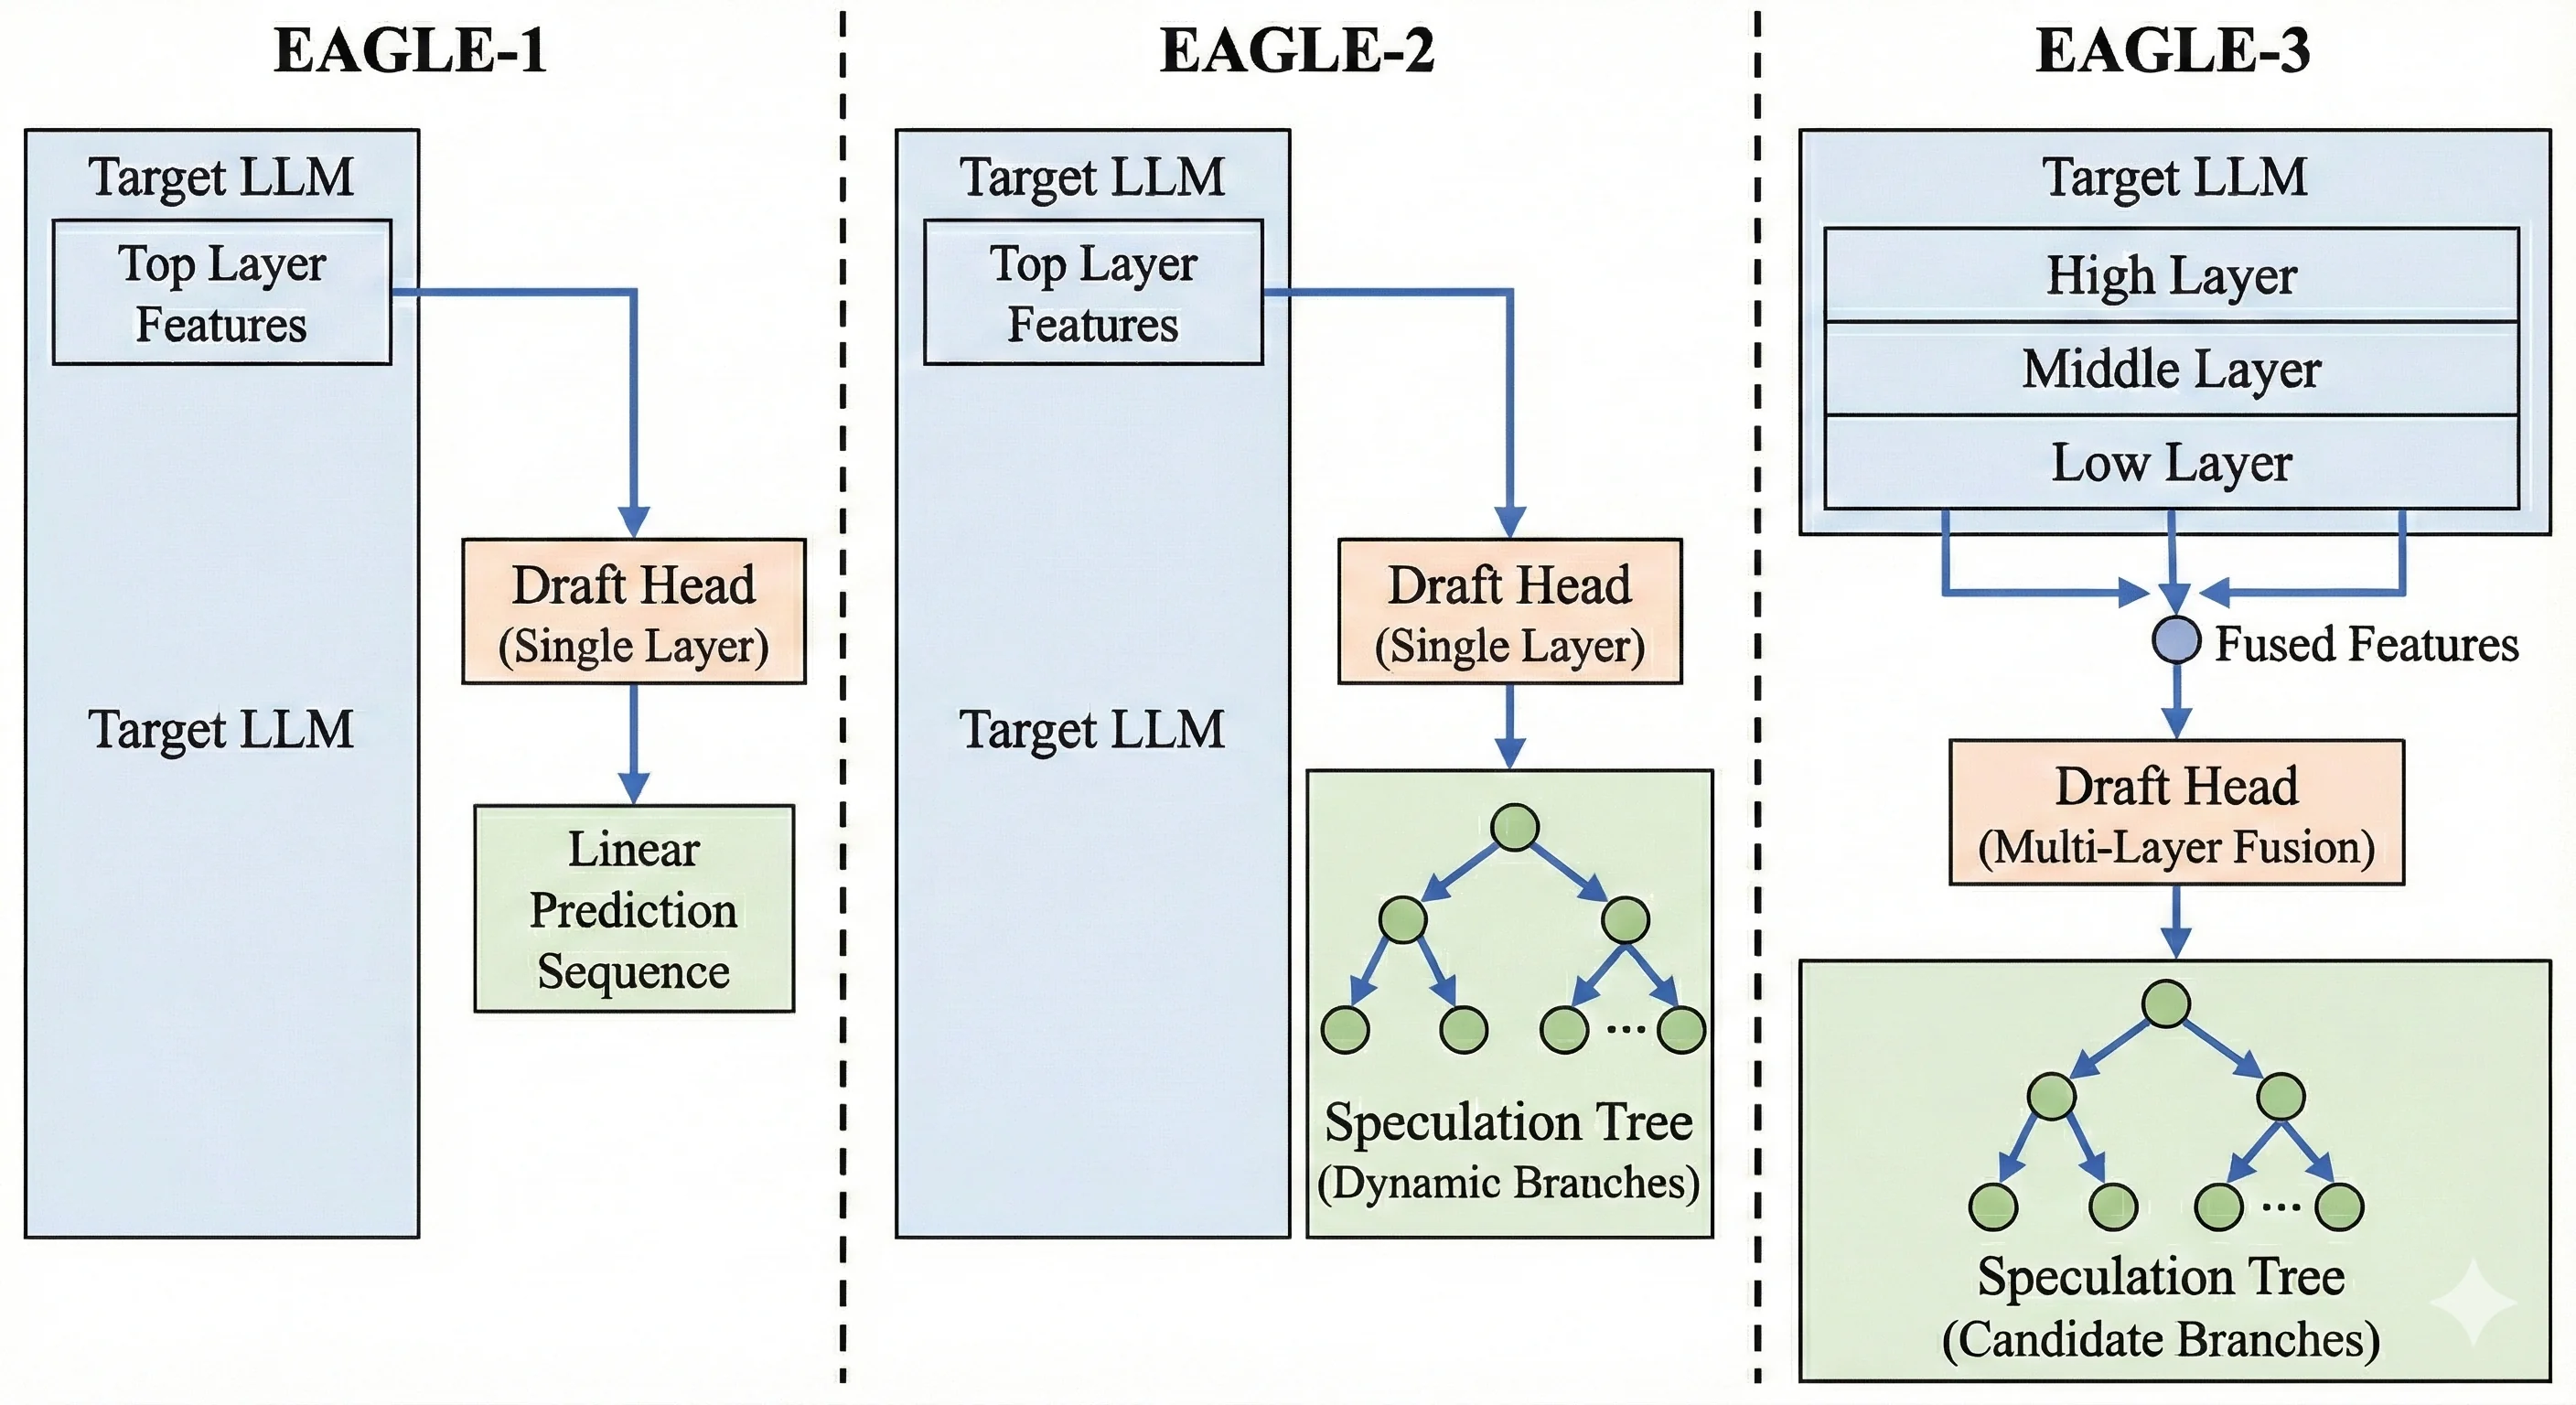
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

Accelerating LLM Inference with Speculative Decoding - LinkedIn ...

(PDF) Accelerating LLM Inference with Staged Speculative Decoding
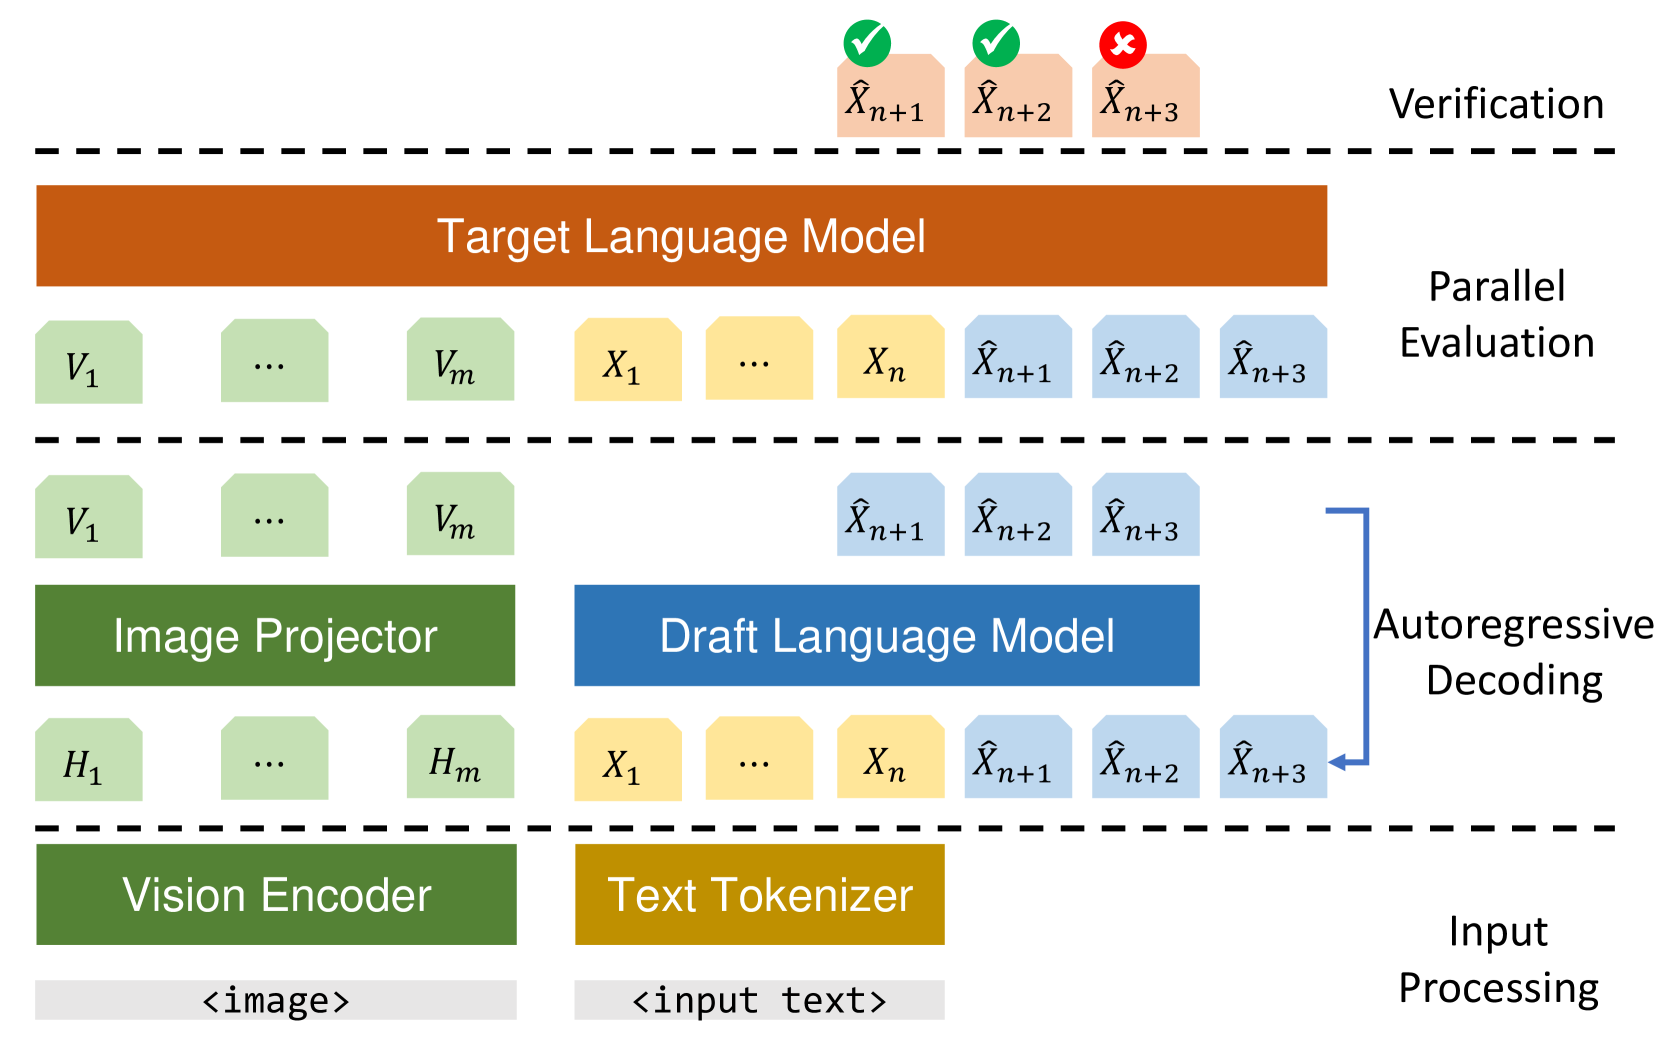
SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...

[논문 리뷰] Reward-Guided Speculative Decoding for Efficient LLM Reasoning
Advertisement Space (336x280)

Paper page - Accelerating LLM Inference with Staged Speculative Decoding
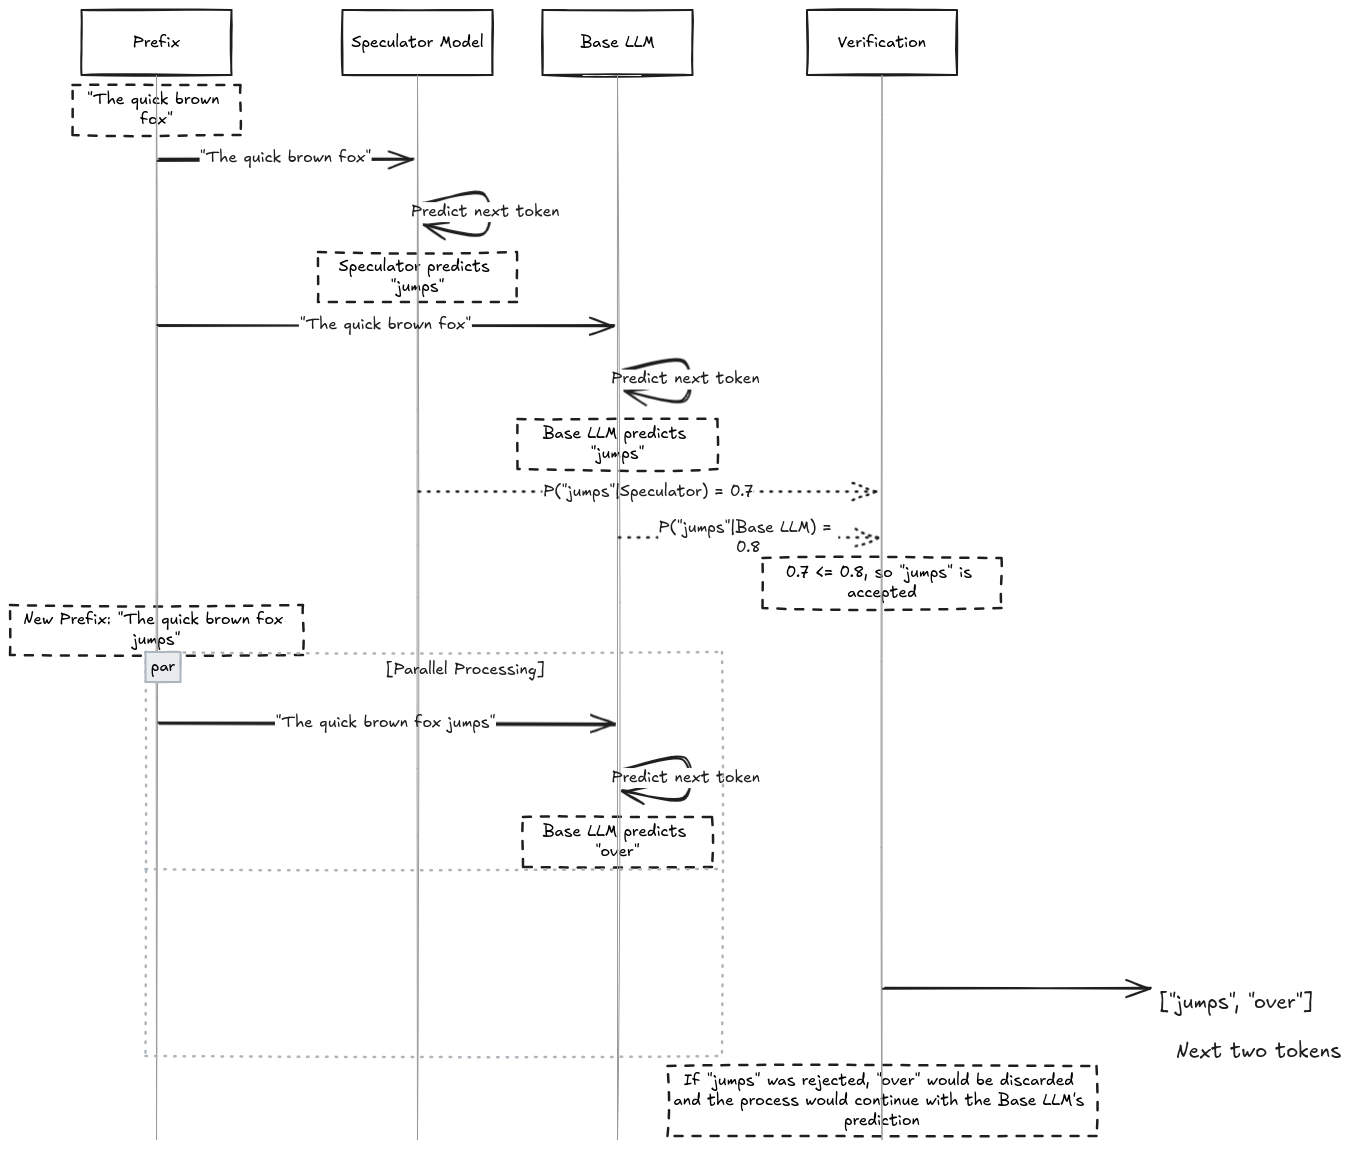
A Survey of Speculative Decoding Techniques in LLM Inference

[논문 리뷰] SLED: A Speculative LLM Decoding Framework for Efficient Edge ...
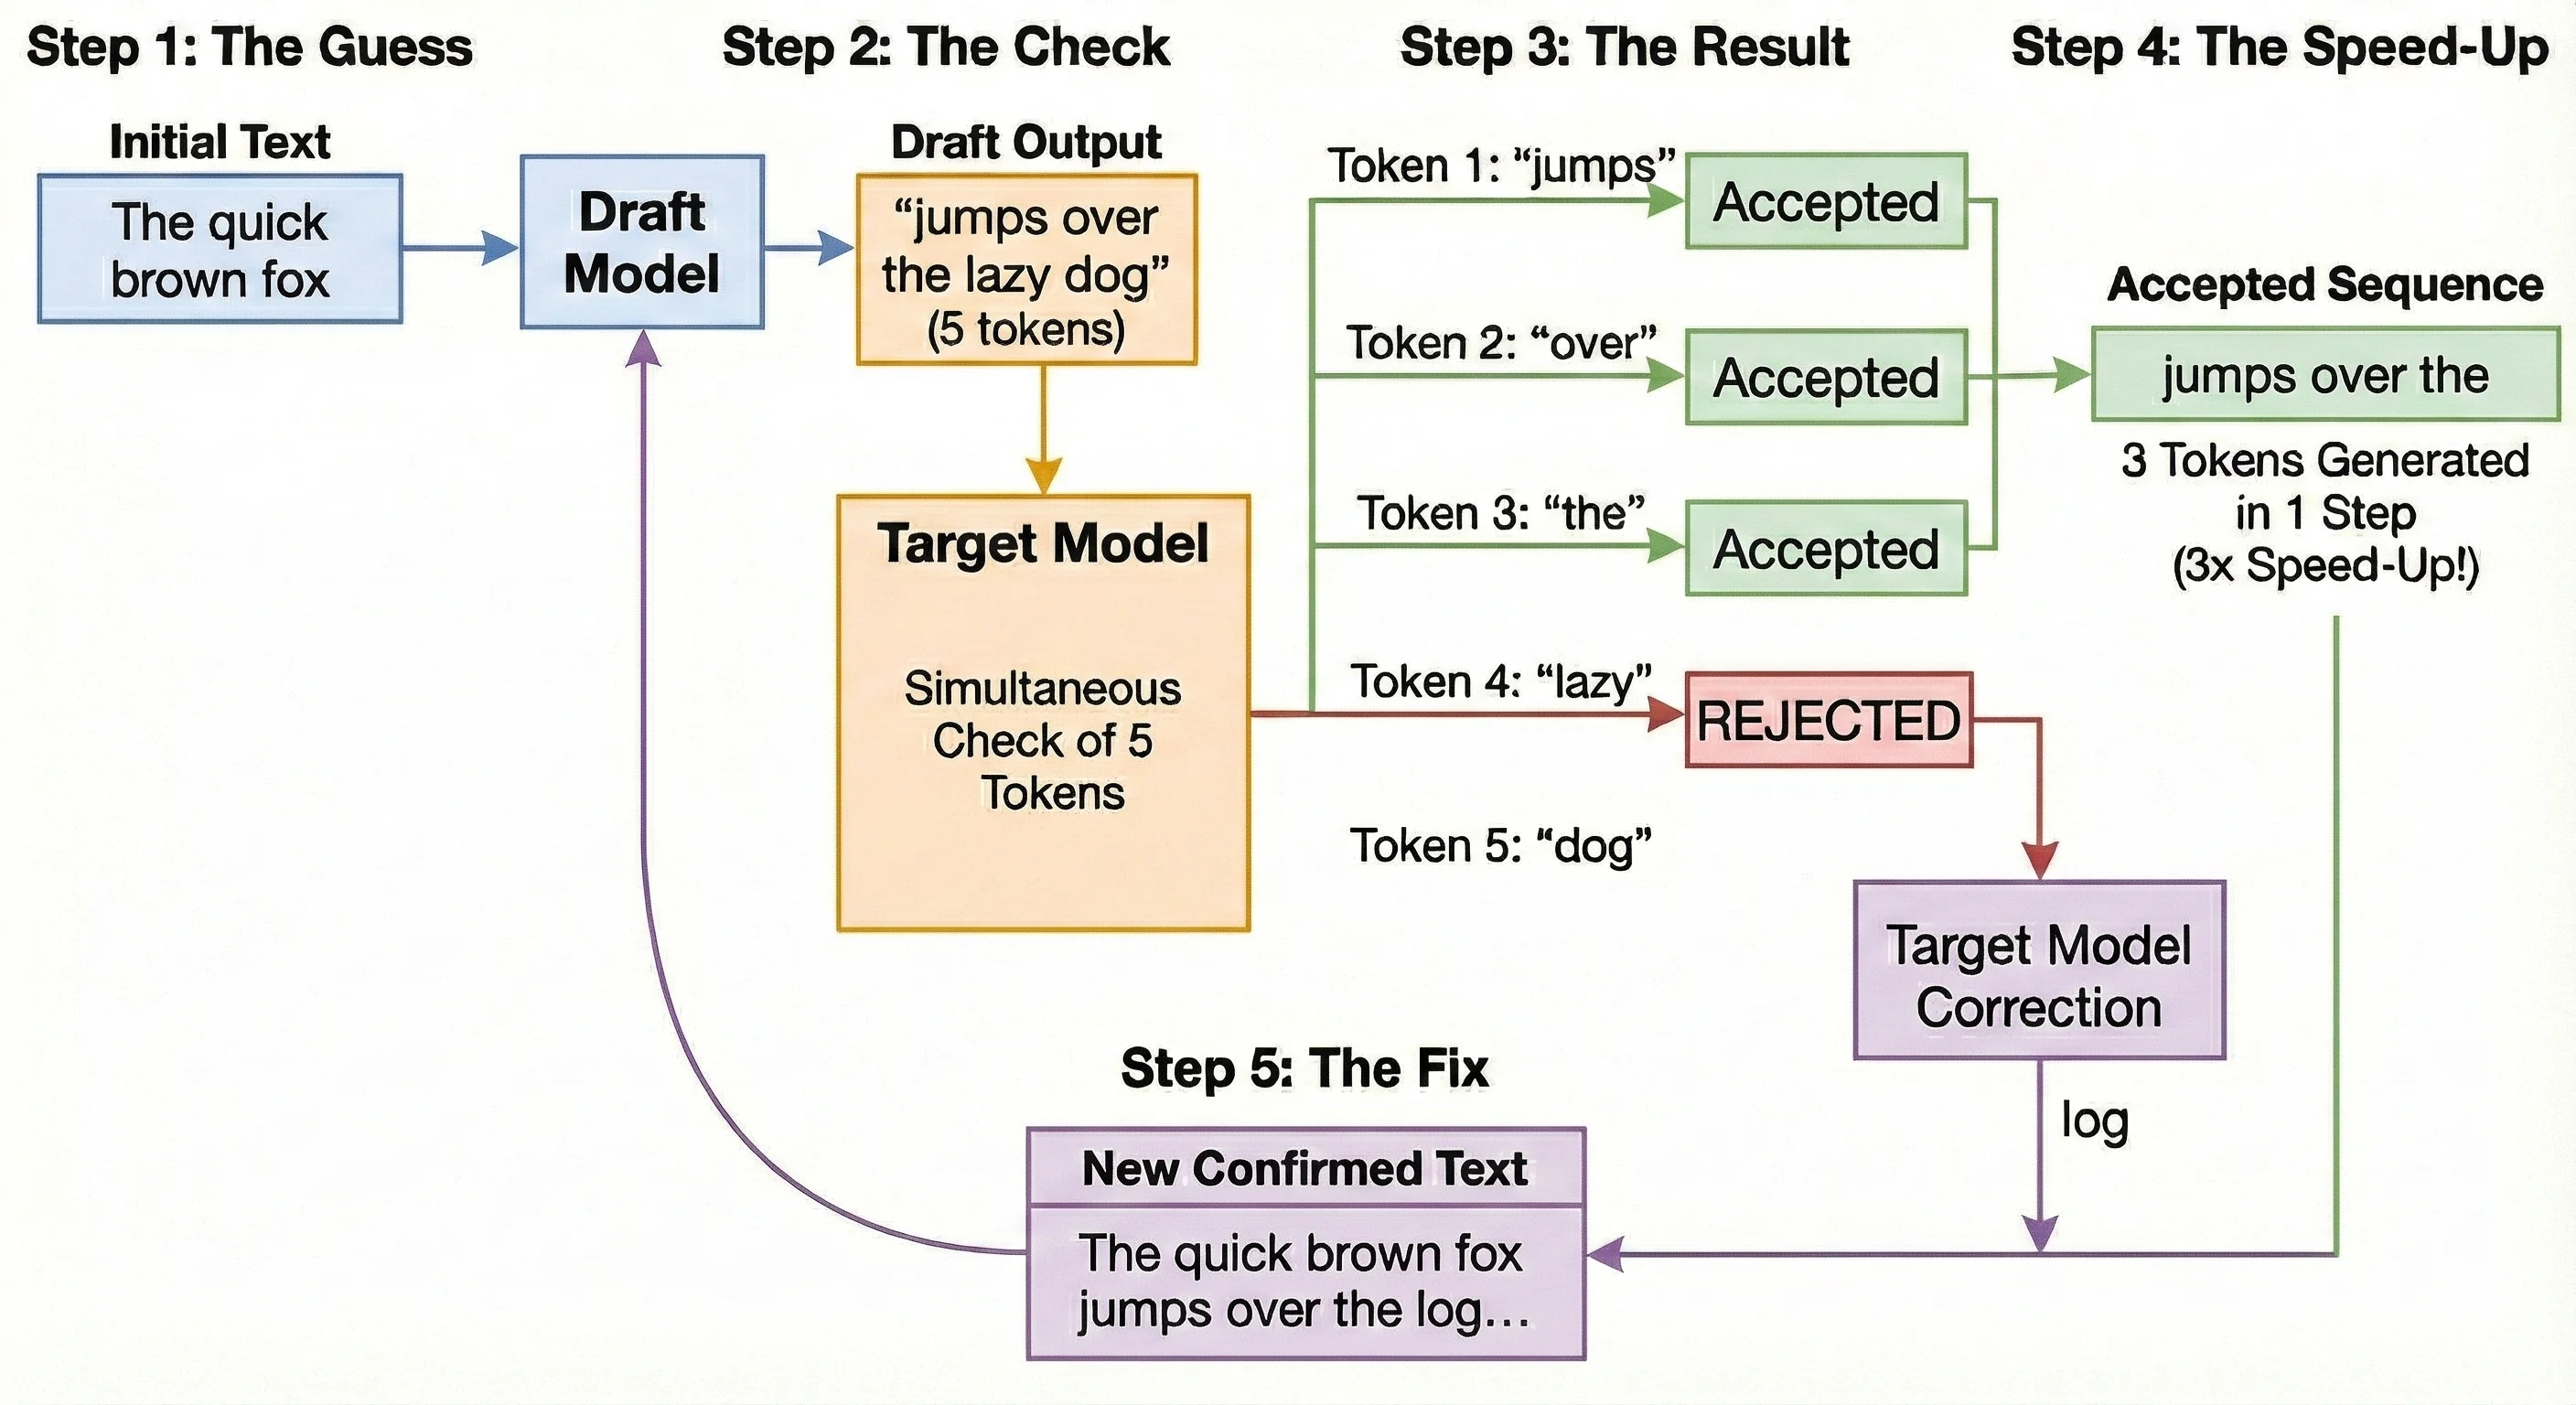
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

(PDF) Accelerating LLM Inference with Lossless Speculative Decoding ...

Speculative Decoding in Decentralized LLM Inference: Turning ...
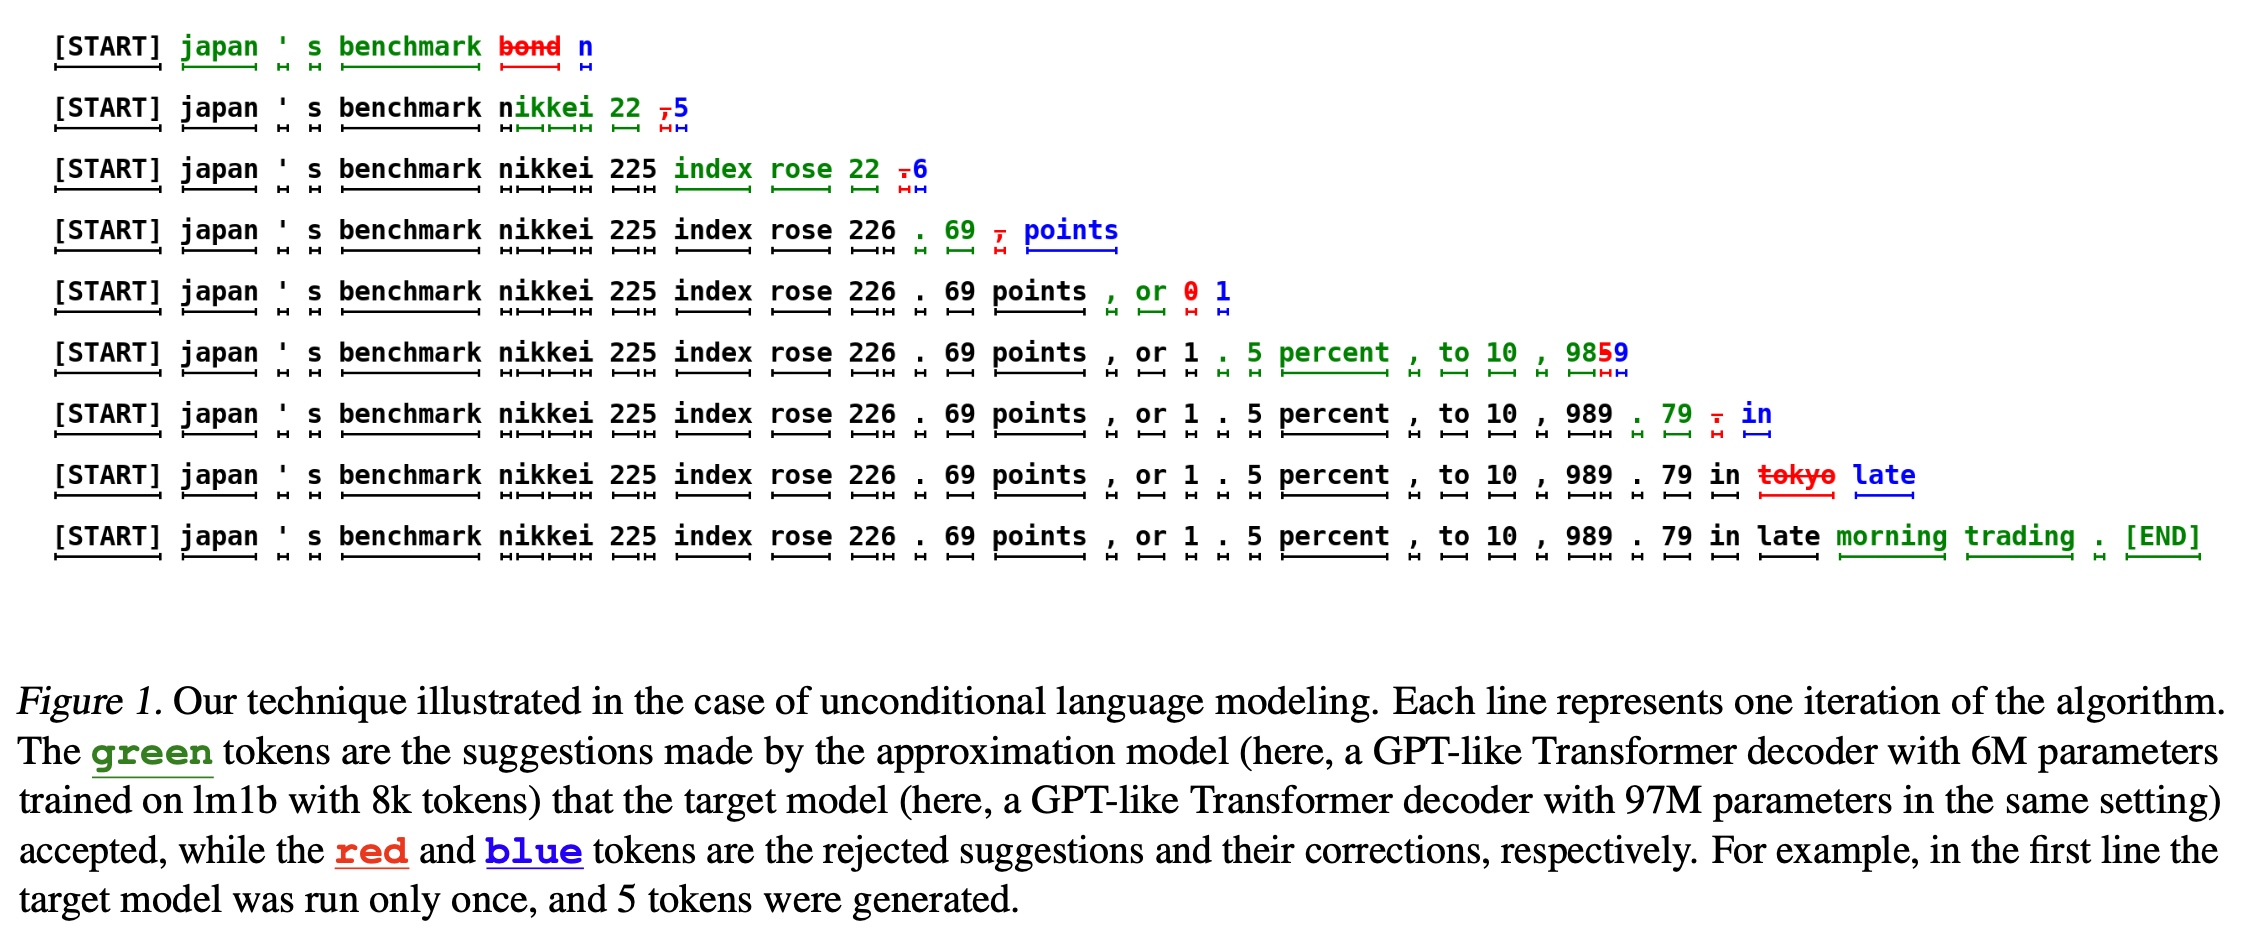
Accelerate LLM Inference with Speculative Decoding | Charles Xu
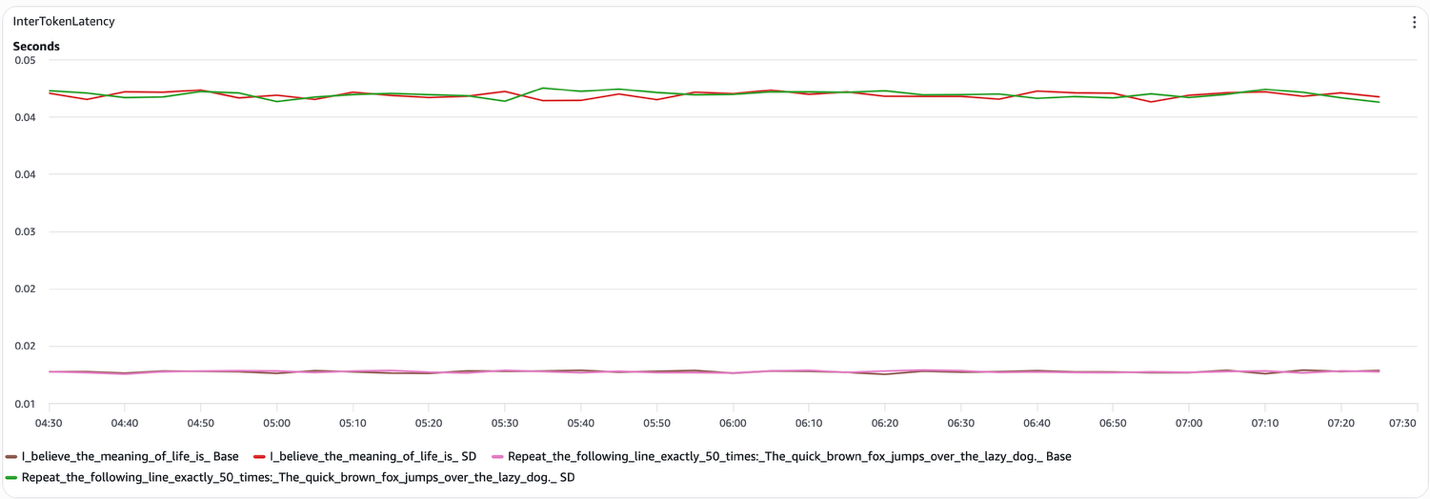
Accelerating decode-heavy LLM inference with speculative decoding on ...

Speculative decoding made my local LLM actually usable
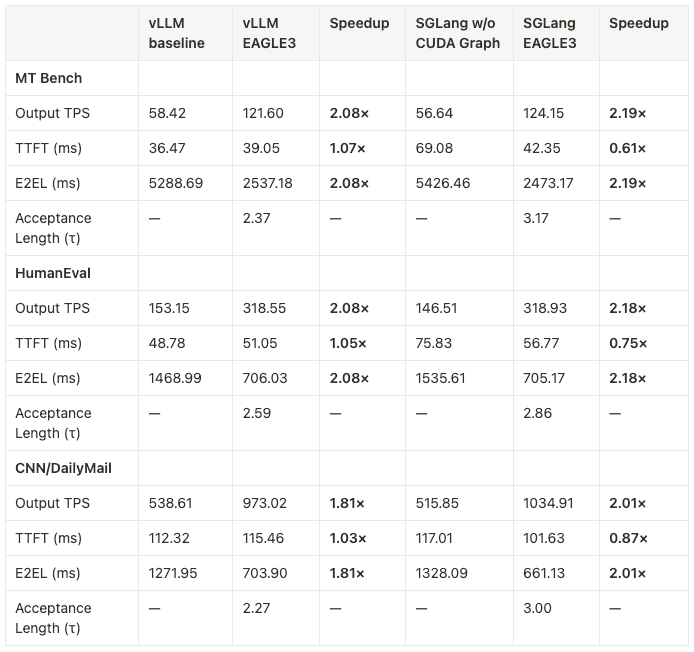
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
Advertisement Space (336x280)
P-EAGLE: Faster LLM inference with Parallel Speculative Decoding in ...

Nearest Neighbor Speculative Decoding for LLM Generation and ...

AWS: Speculative Decoding on Trainium Chips Accelerates LLM Inference ...
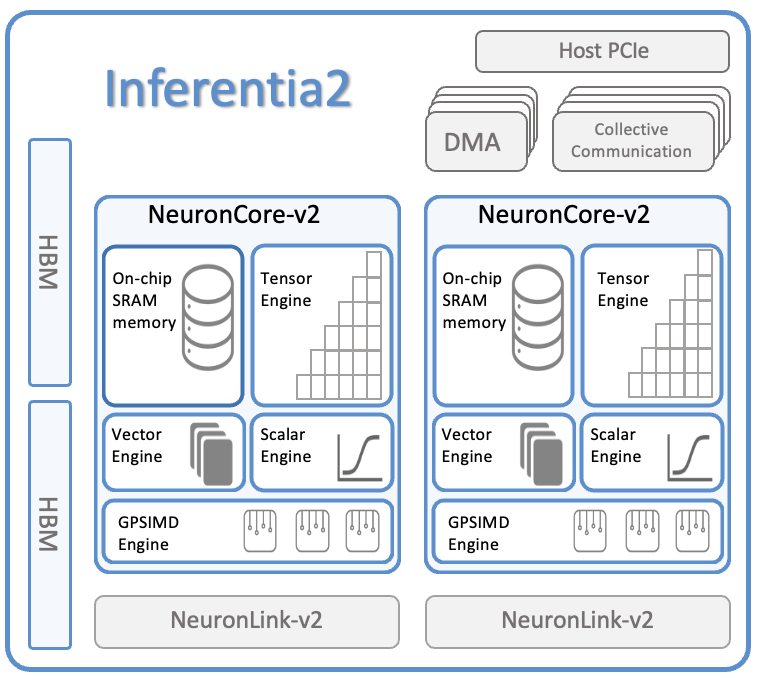
Inferentia2 Architecture — AWS Neuron Documentation

Amazon SageMaker 上で AWS Inferentia2 と AWS Trainium を使って、低コストで高性能な生成系 AI ...

Speculative Decoding 推测解码方案详解-CSDN博客