
Tuto Startup Faster Llms With Speculative Decoding And Aws Inferentia2

Tuto Startup - Faster LLMs with speculative decoding and AWS Inferentia2

Faster LLMs with speculative decoding and AWS Inferentia2 | Artificial ...

Faster LLMs with speculative decoding and AWS Inferentia2
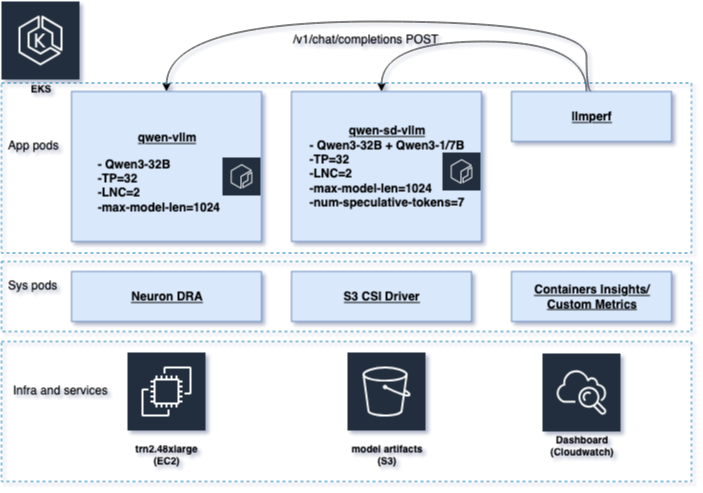
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec
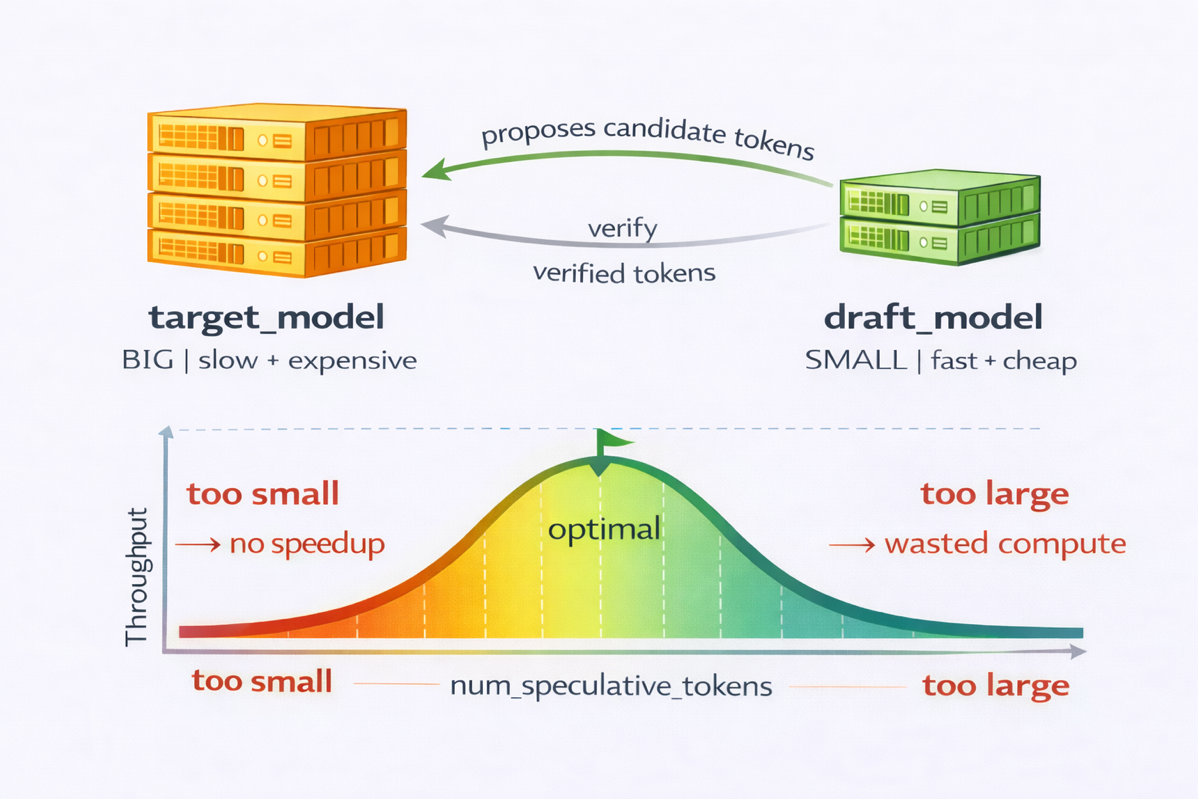
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec
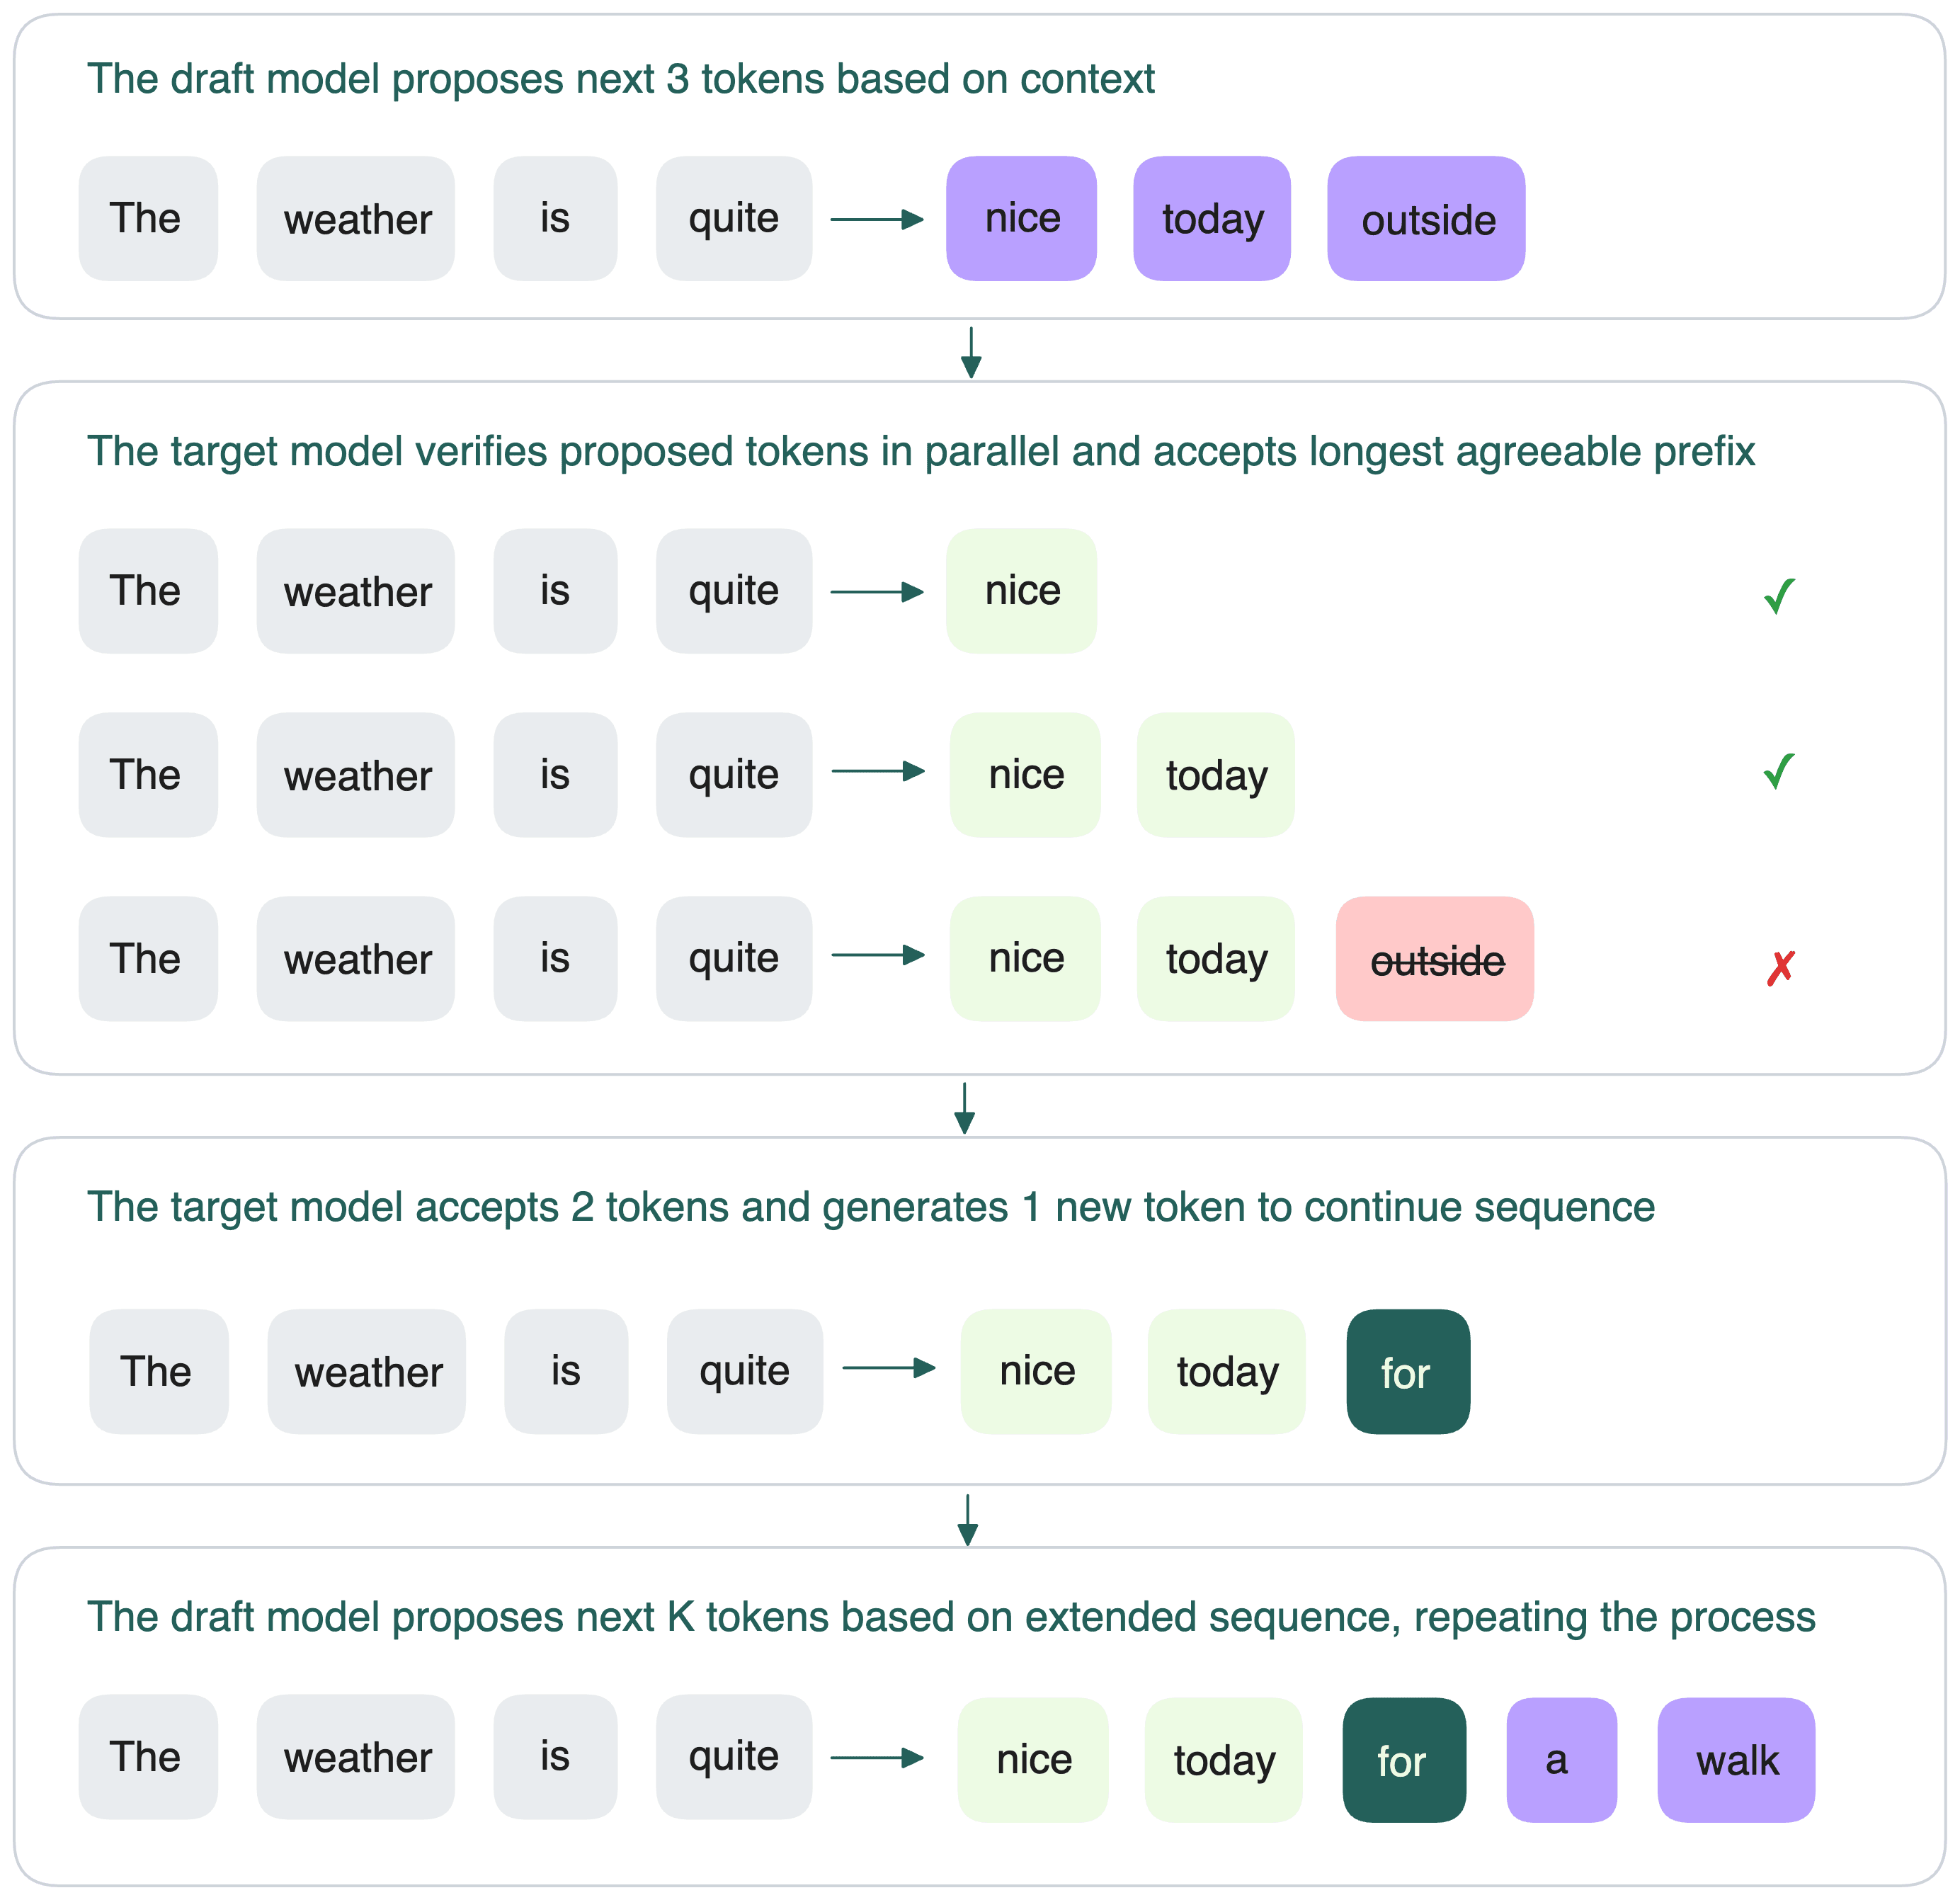
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

Faster LLMs: Accelerate Inference with Speculative Decoding - YouTube
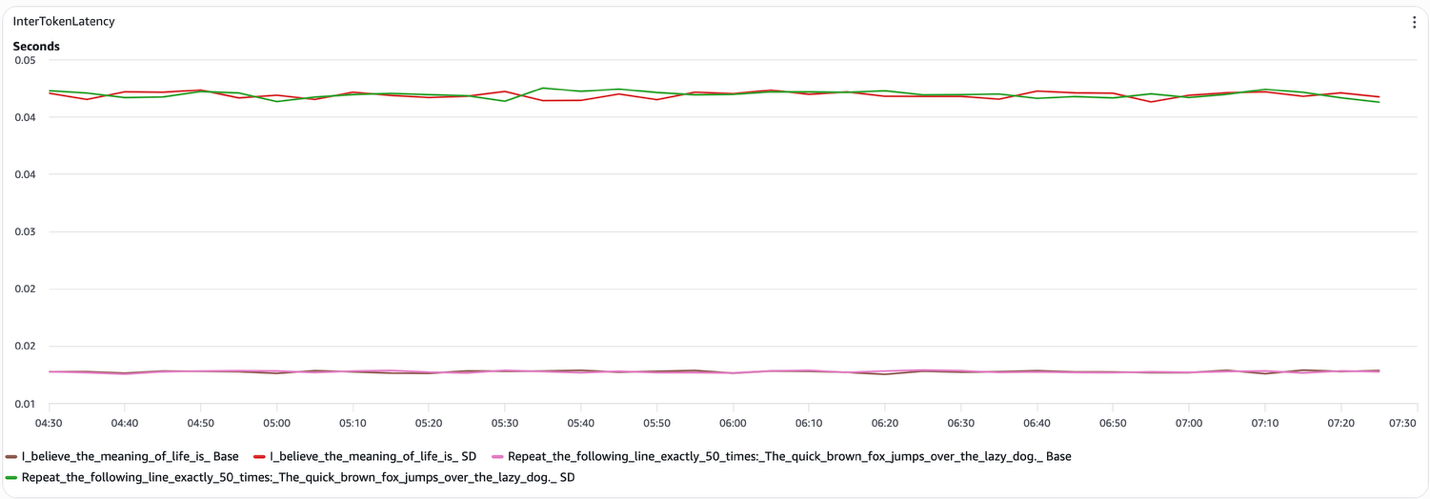
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec
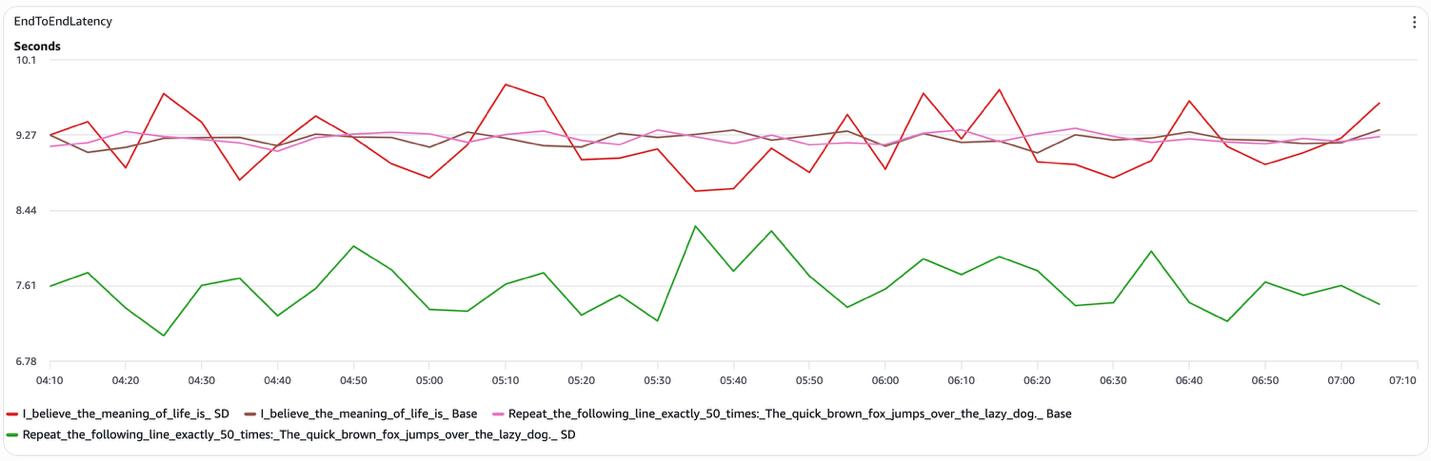
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec
P-EAGLE: Faster LLM inference with Parallel Speculative Decoding in ...
Advertisement Space (300x250)

LLM 社会実装を進める ELYZA 社: AWS Inferentia2 × Speculative Decoding の組み合わせは世界初 ...
How Speculative Decoding Makes LLMs 2.5x Faster (The Secret to Faster ...
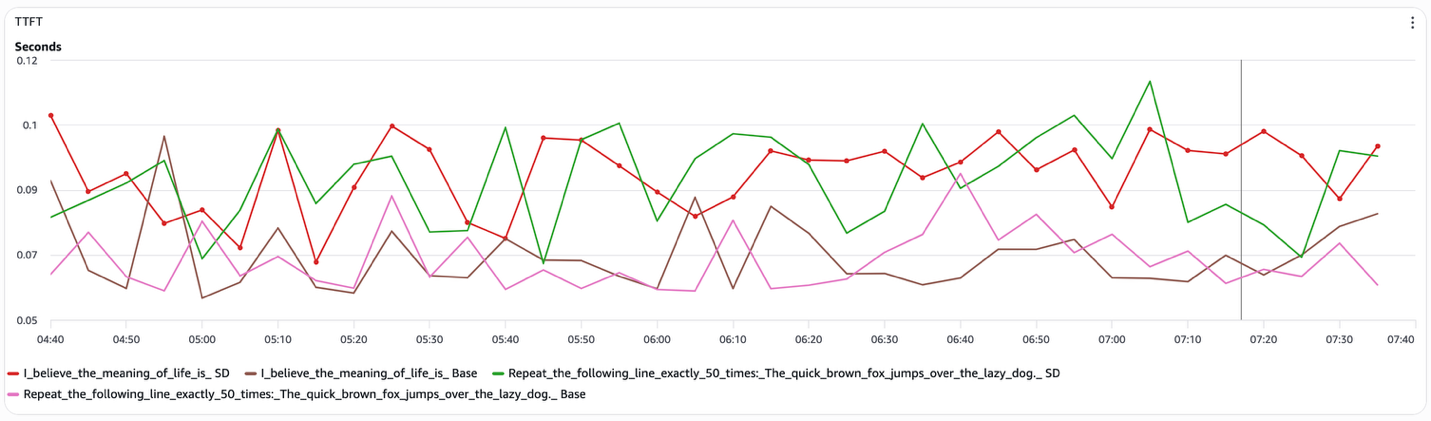
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec
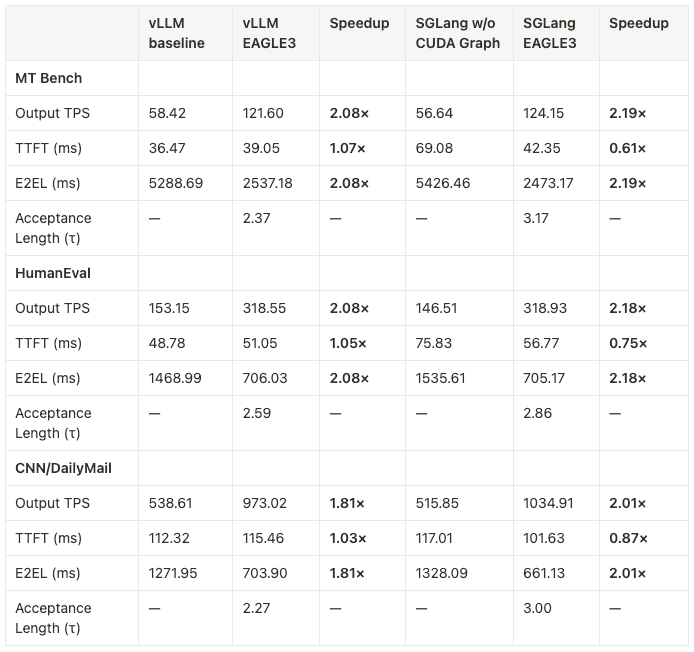
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

Dynamic Depth Decoding: Faster Speculative Decoding for LLMs | AI ...
Speculative Decoding for Faster LLMs | by M | Foundation Models Deep ...

Speculative Decoding for Faster LLMs | by M | Foundation Models Deep ...
Speculative Decoding for Faster LLMs | by M | Foundation Models Deep ...
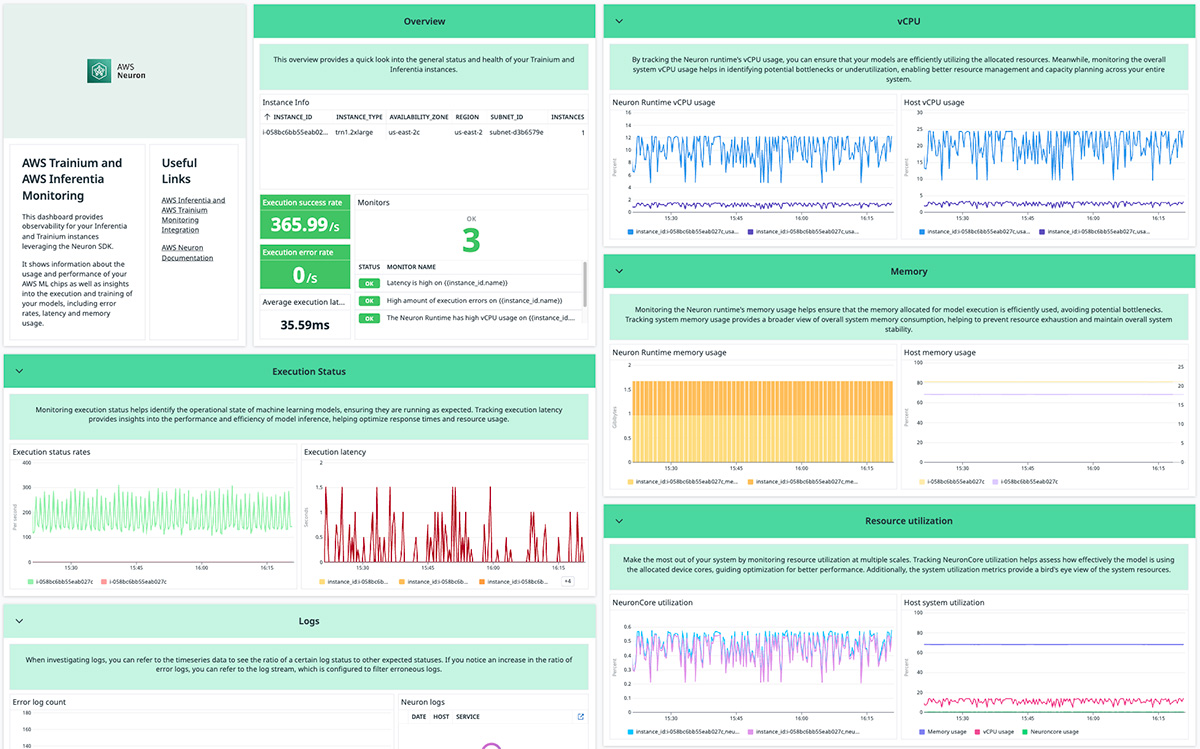
Tuto Startup - Enhanced observability for AWS Trainium and AWS Inferentia w
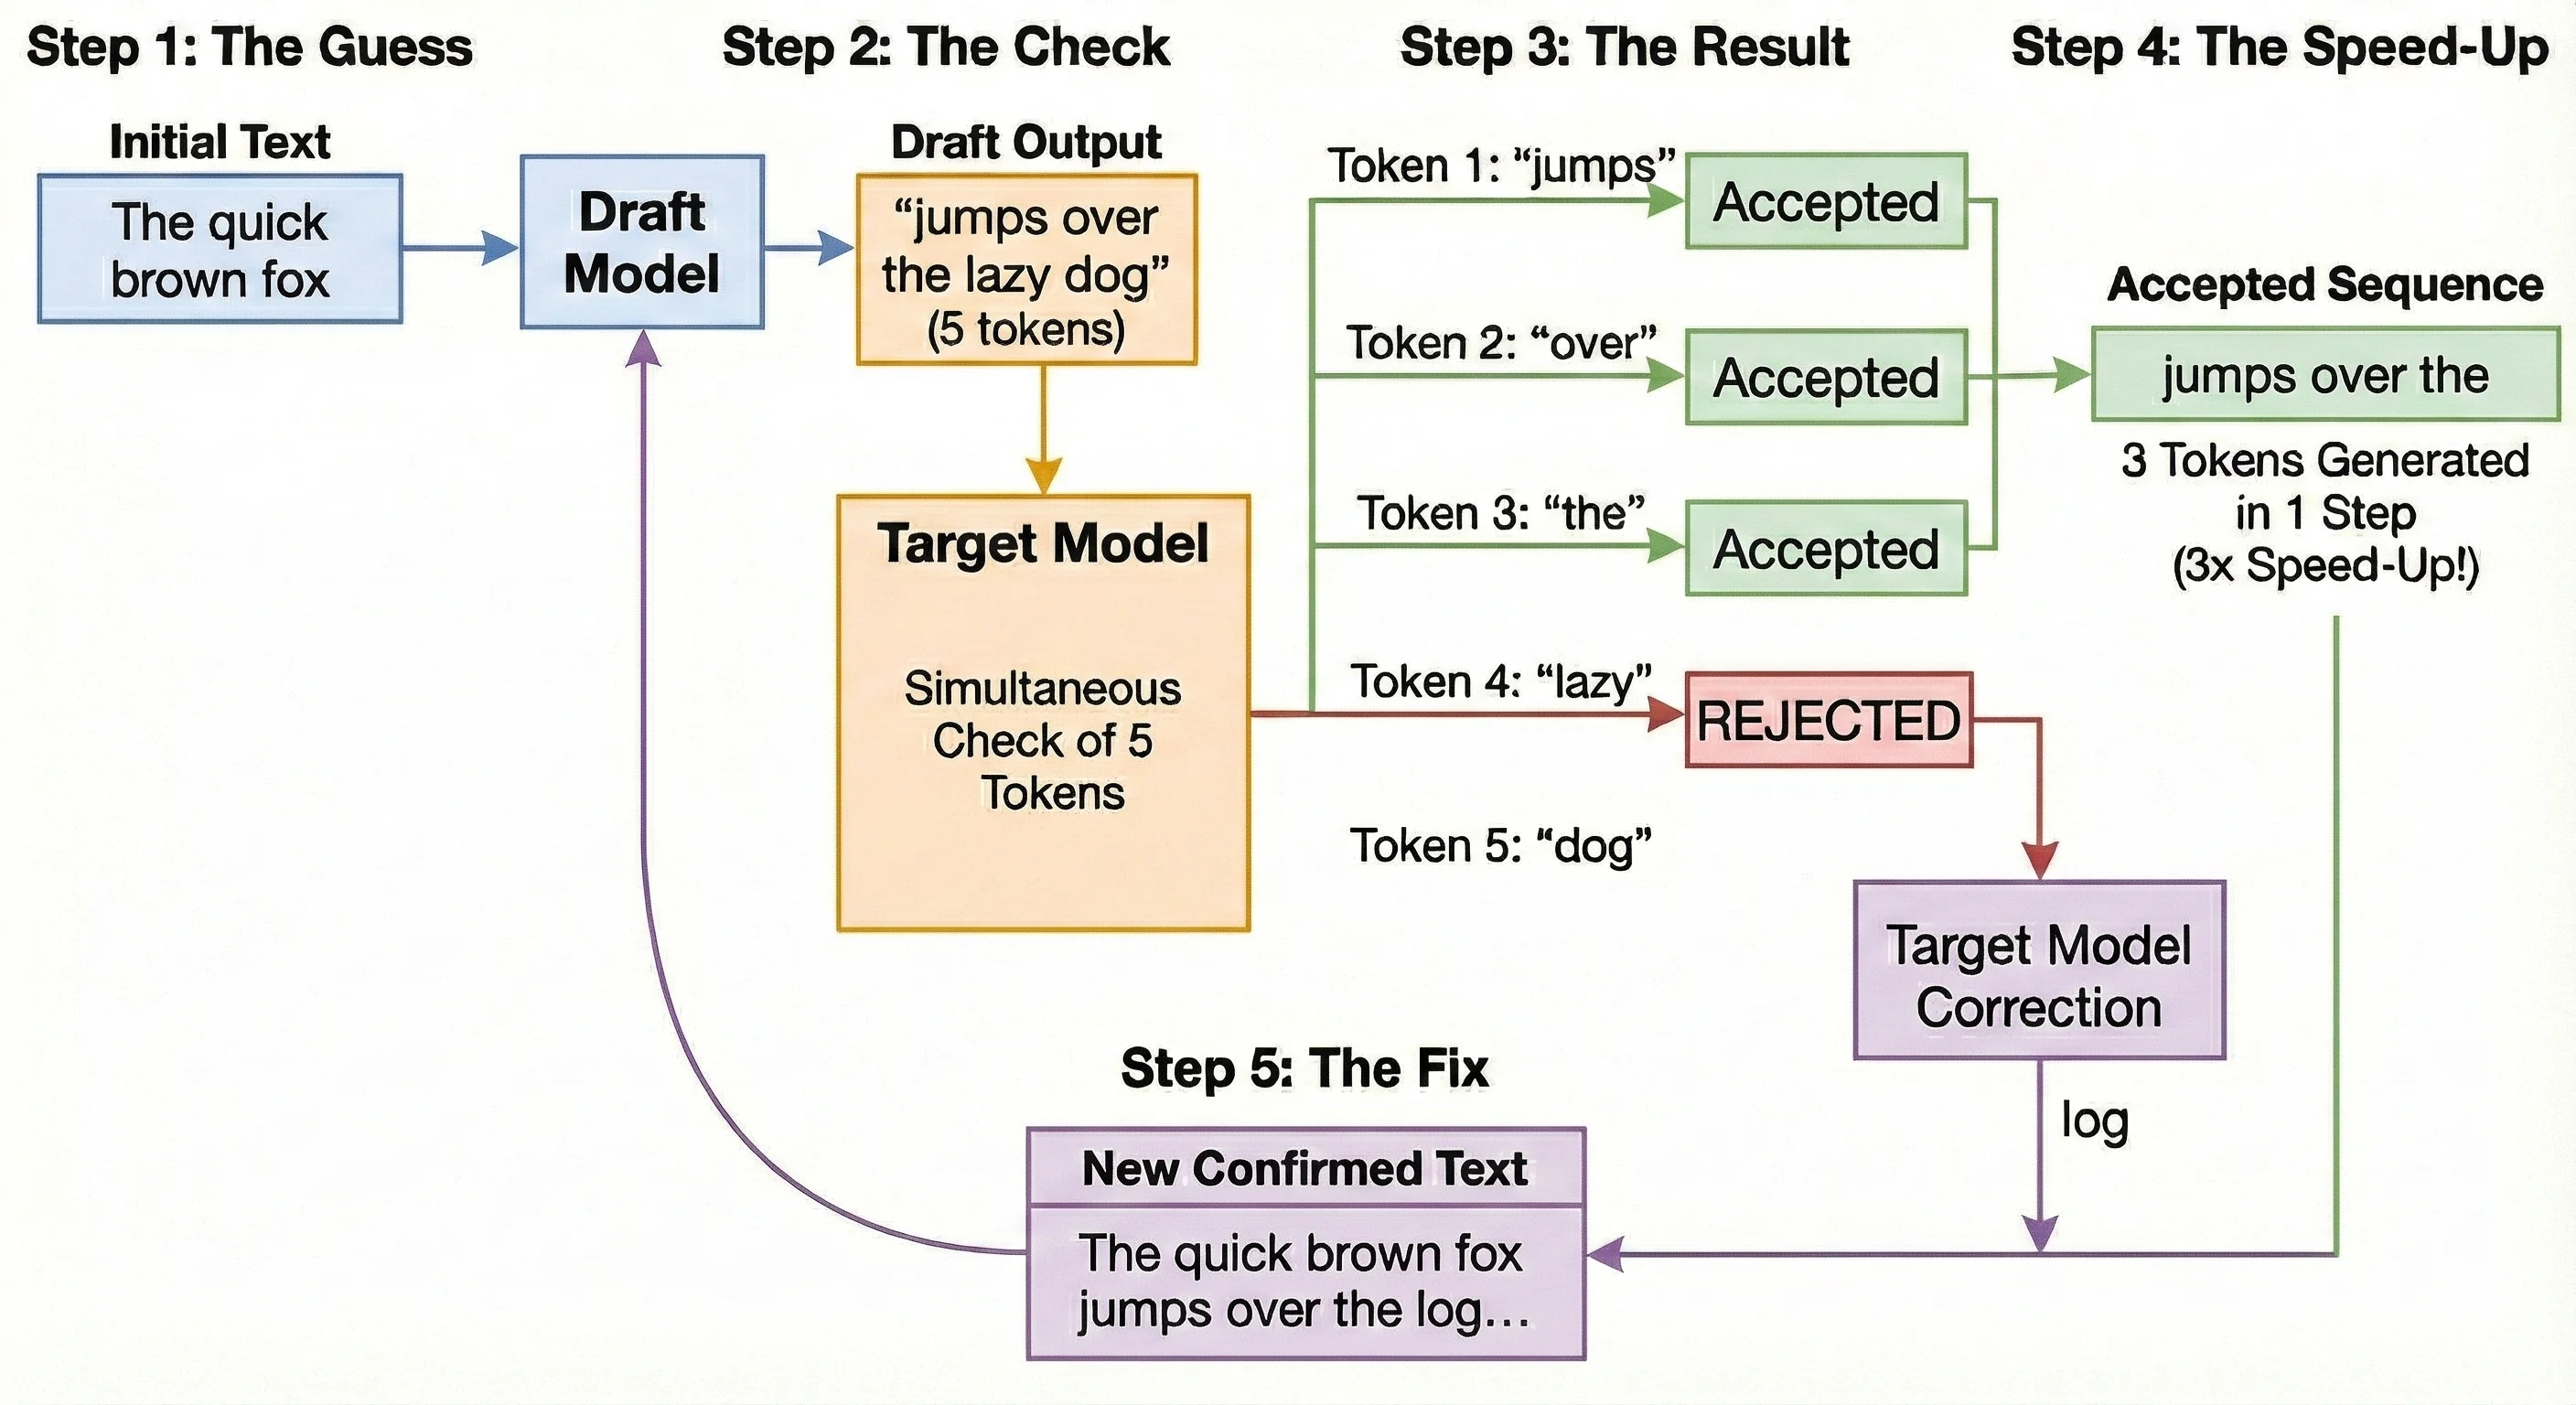
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Advertisement Space (336x280)
Speculative Decoding Explained: Faster Inference Without Quality Loss
🚀 Speed Up LLM Inference with Speculative Decoding | by Generative AI ...
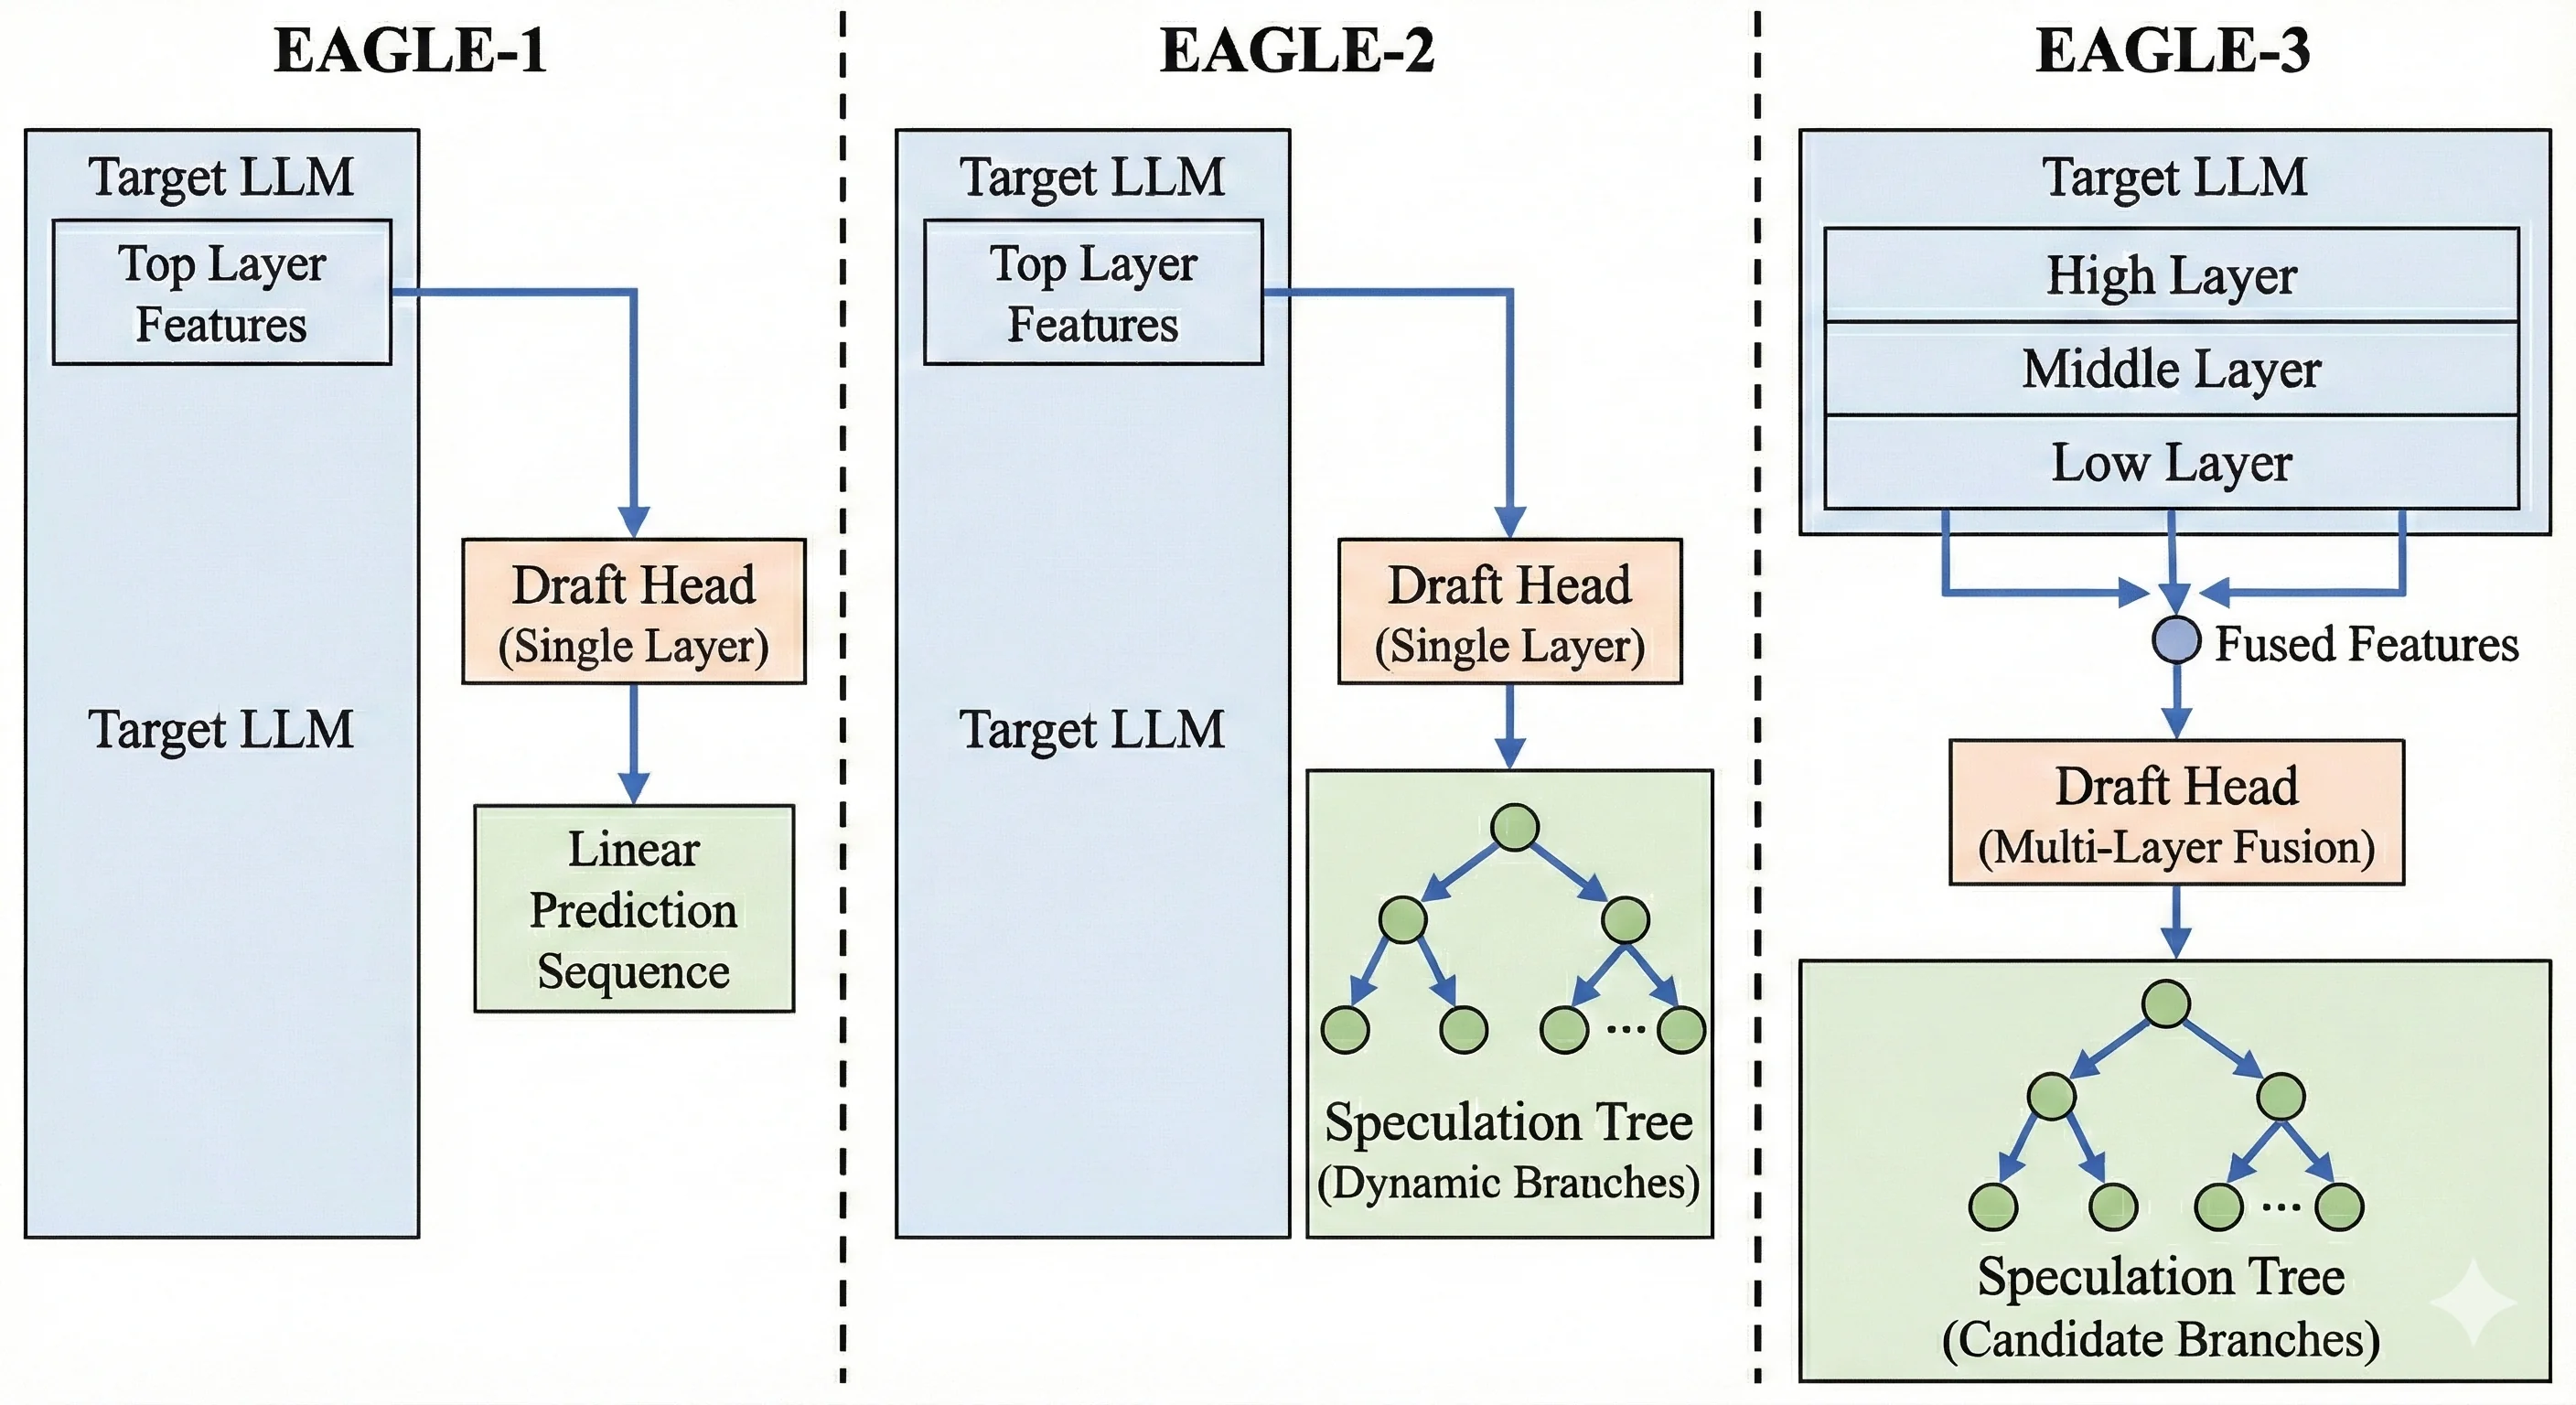
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

Tuto Startup - InterVision accelerates AI development using AWS LLM League

Speculative Decoding - Making Language Models Generate Faster Without ...
Accelerating decode-heavy LLM inference with speculative decoding on ...
Speculative decoding moves into production for decode-heavy LLMs | AI News

Speculative Decoding: 3× Faster LLM Inference with Zero Quality Loss ...
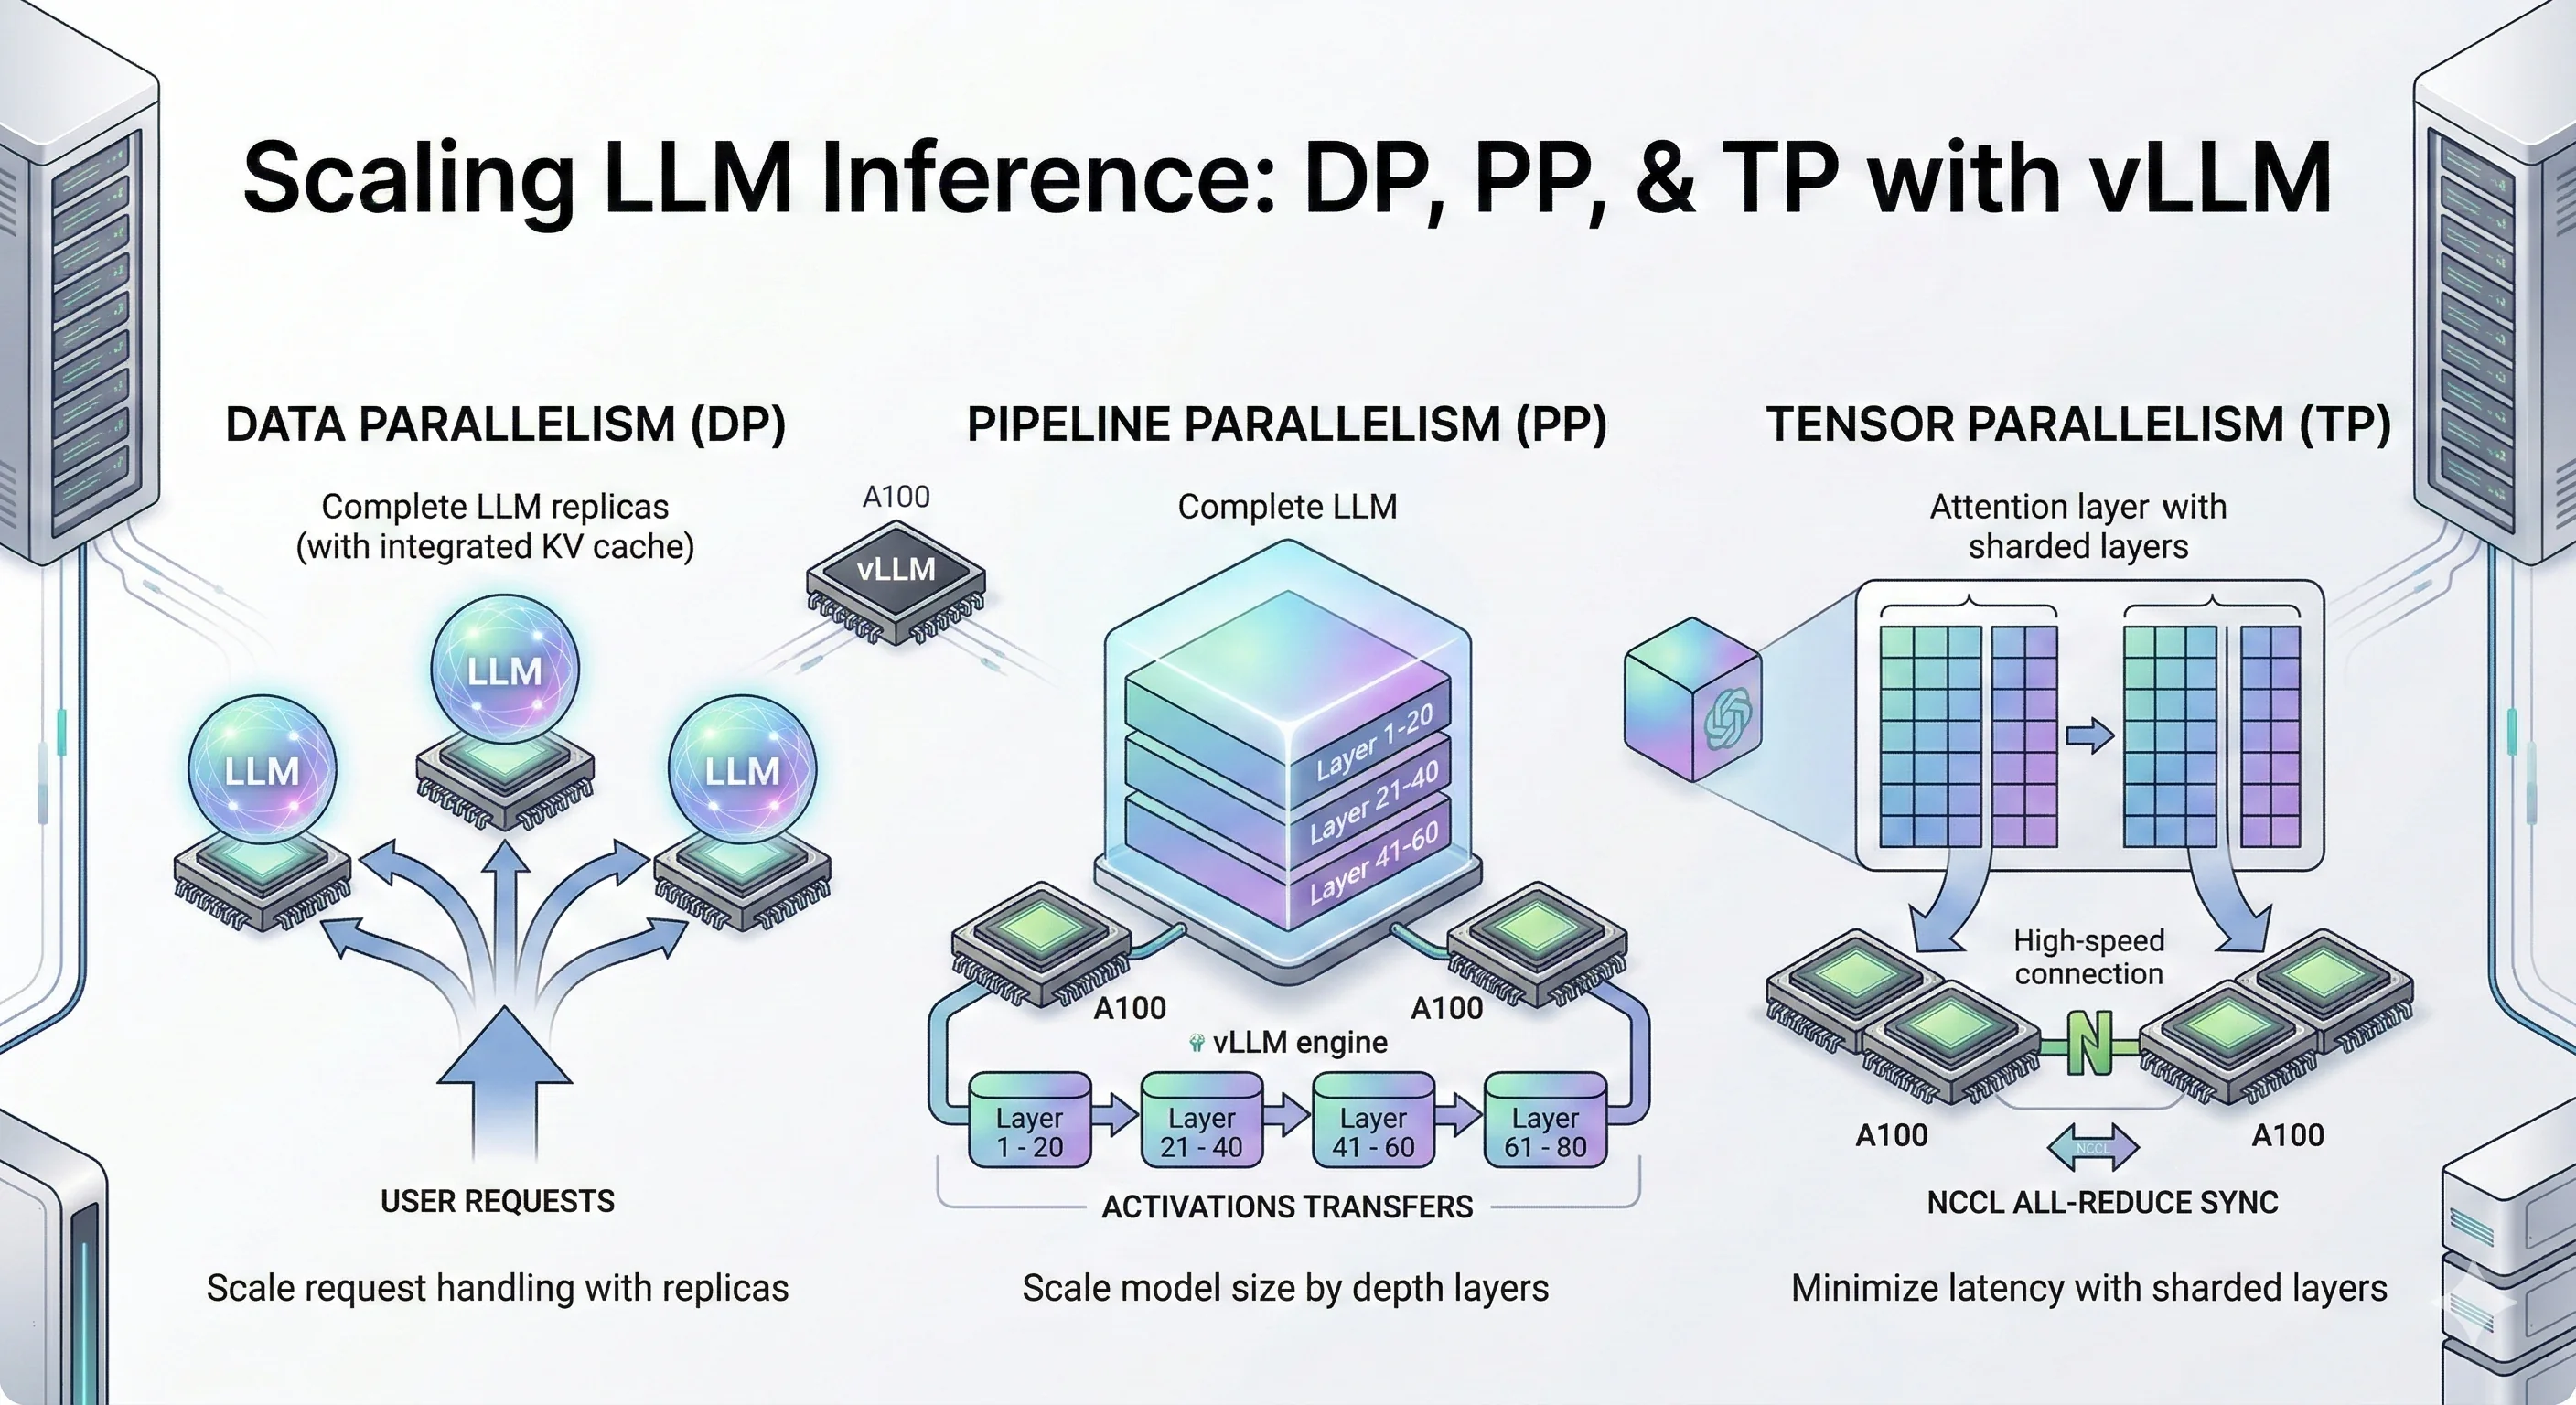
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Advertisement Space (336x280)

Speculative Decoding for Production LLMs | TURION.AI

Speculative Decoding with CTC-based Draft Model for LLM Inference ...
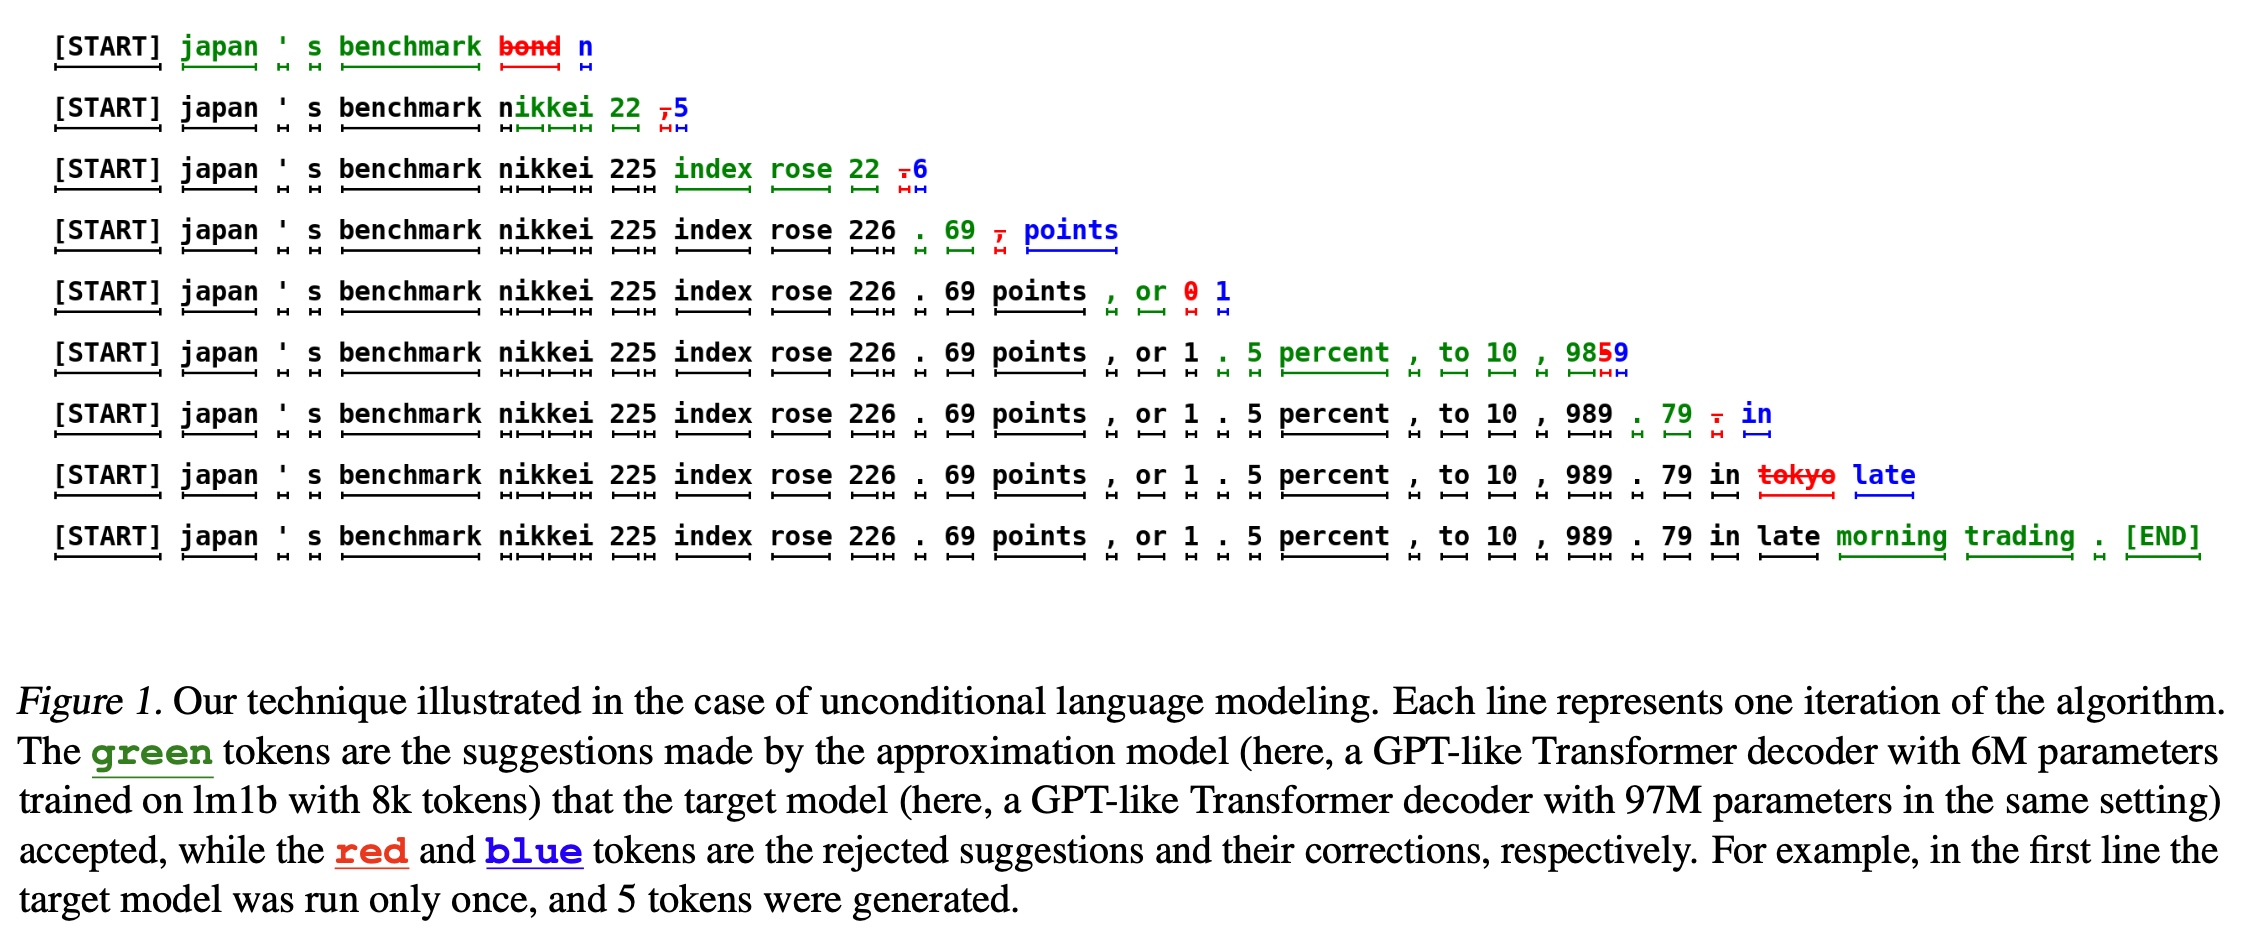
Accelerate LLM Inference with Speculative Decoding | Charles Xu

Speculative Decoding - Making Language Models Generate Faster Without ...

re:Invent 2023 CMP319 Deploy LLMs with AWS Inferentia & Ray to optimize ...
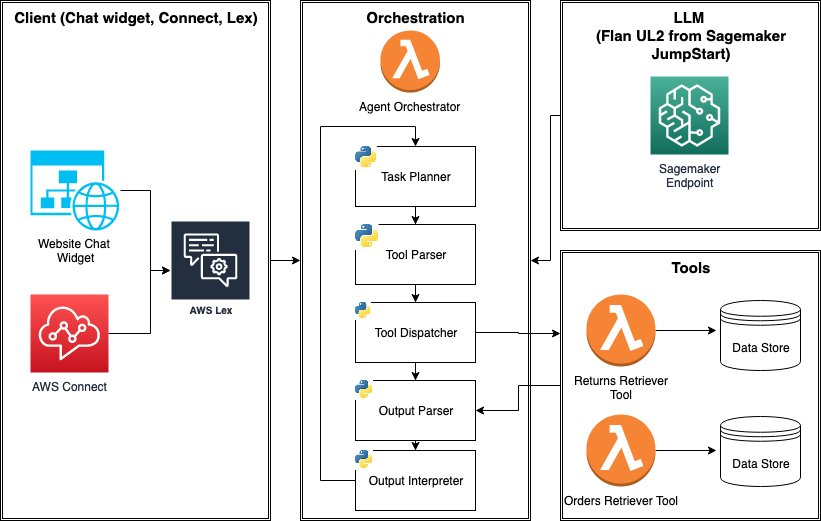
Tuto Startup - Learn how to build and deploy tool-using LLM agents using AW