
Llm Prompt Cache Kv Cache
LLM Caching Strategies 2026: Prompt Cache, KV Cache, Semantic Cache ...
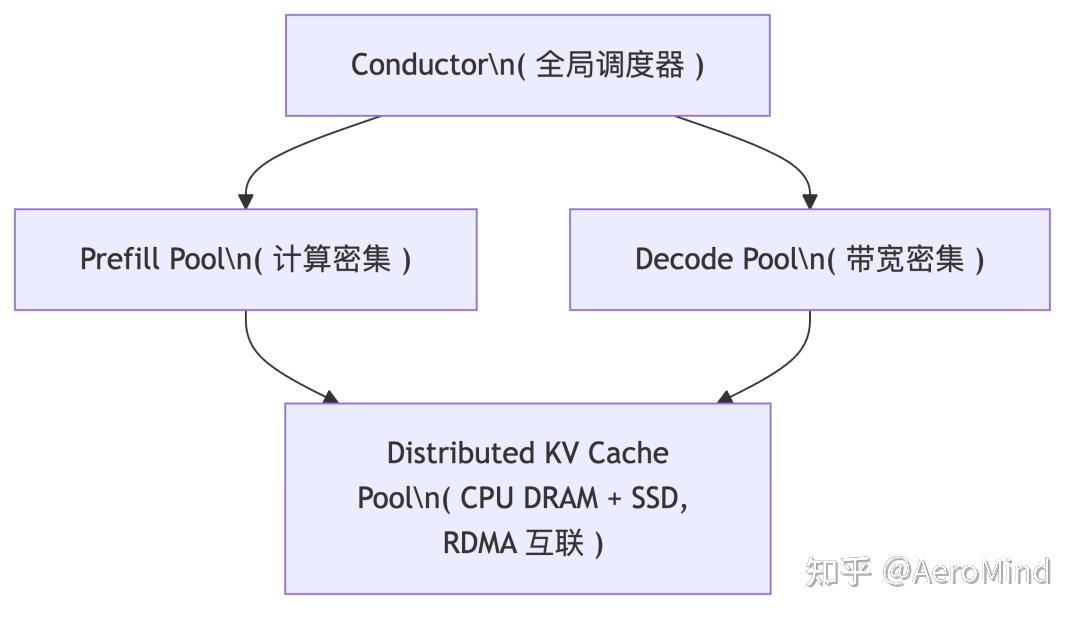
LLM Prompt Cache 深度解析:从 KV Cache 原理到大规模推理架构 - 知乎
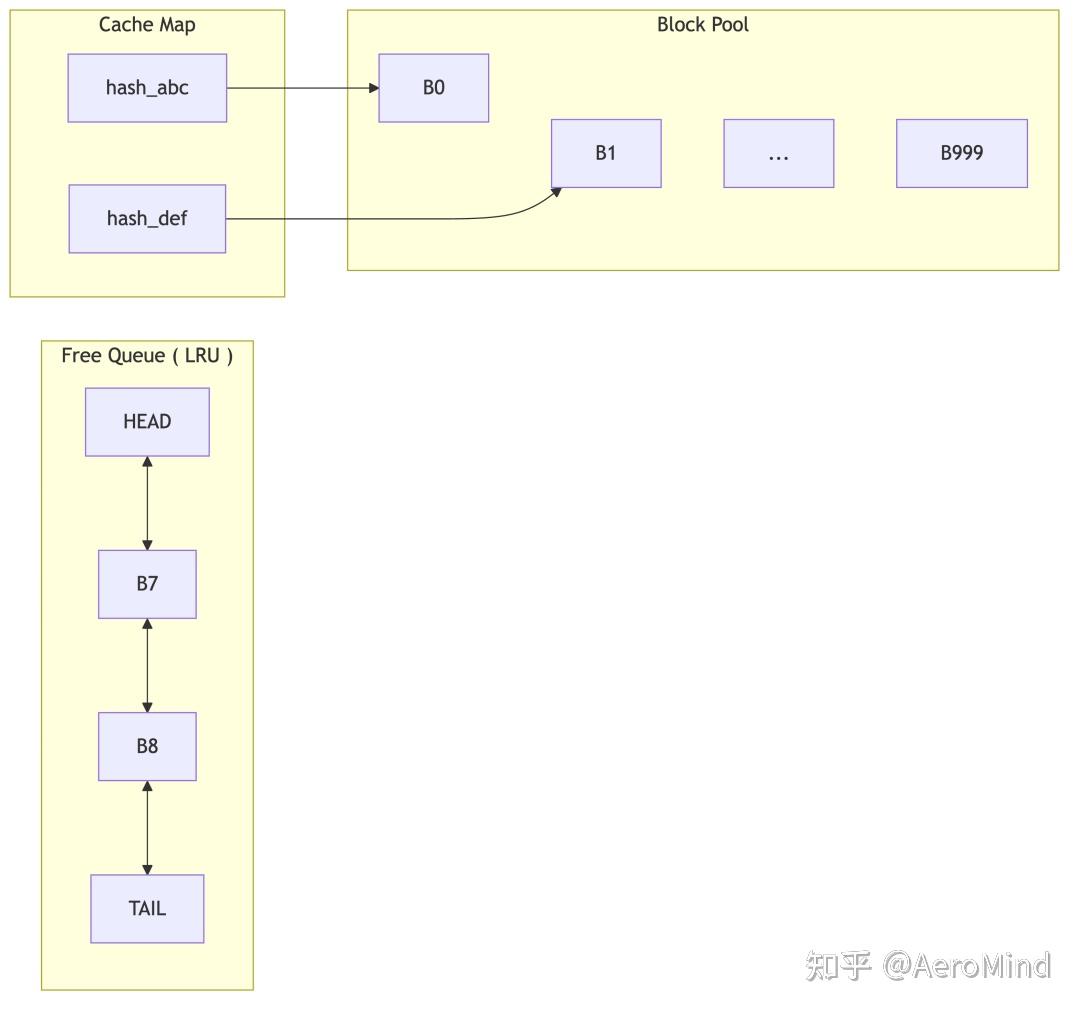
LLM Prompt Cache 深度解析:从 KV Cache 原理到大规模推理架构 - 知乎
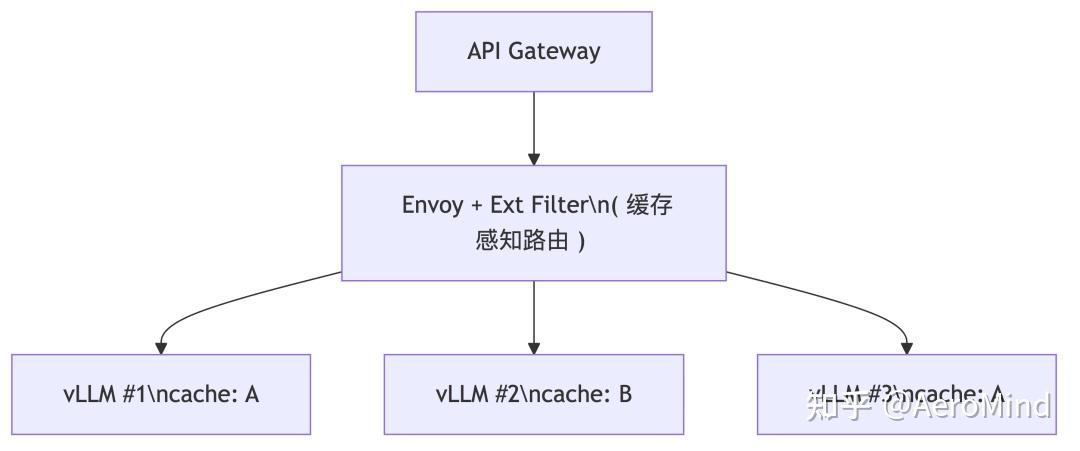
LLM Prompt Cache 深度解析:从 KV Cache 原理到大规模推理架构 - 知乎
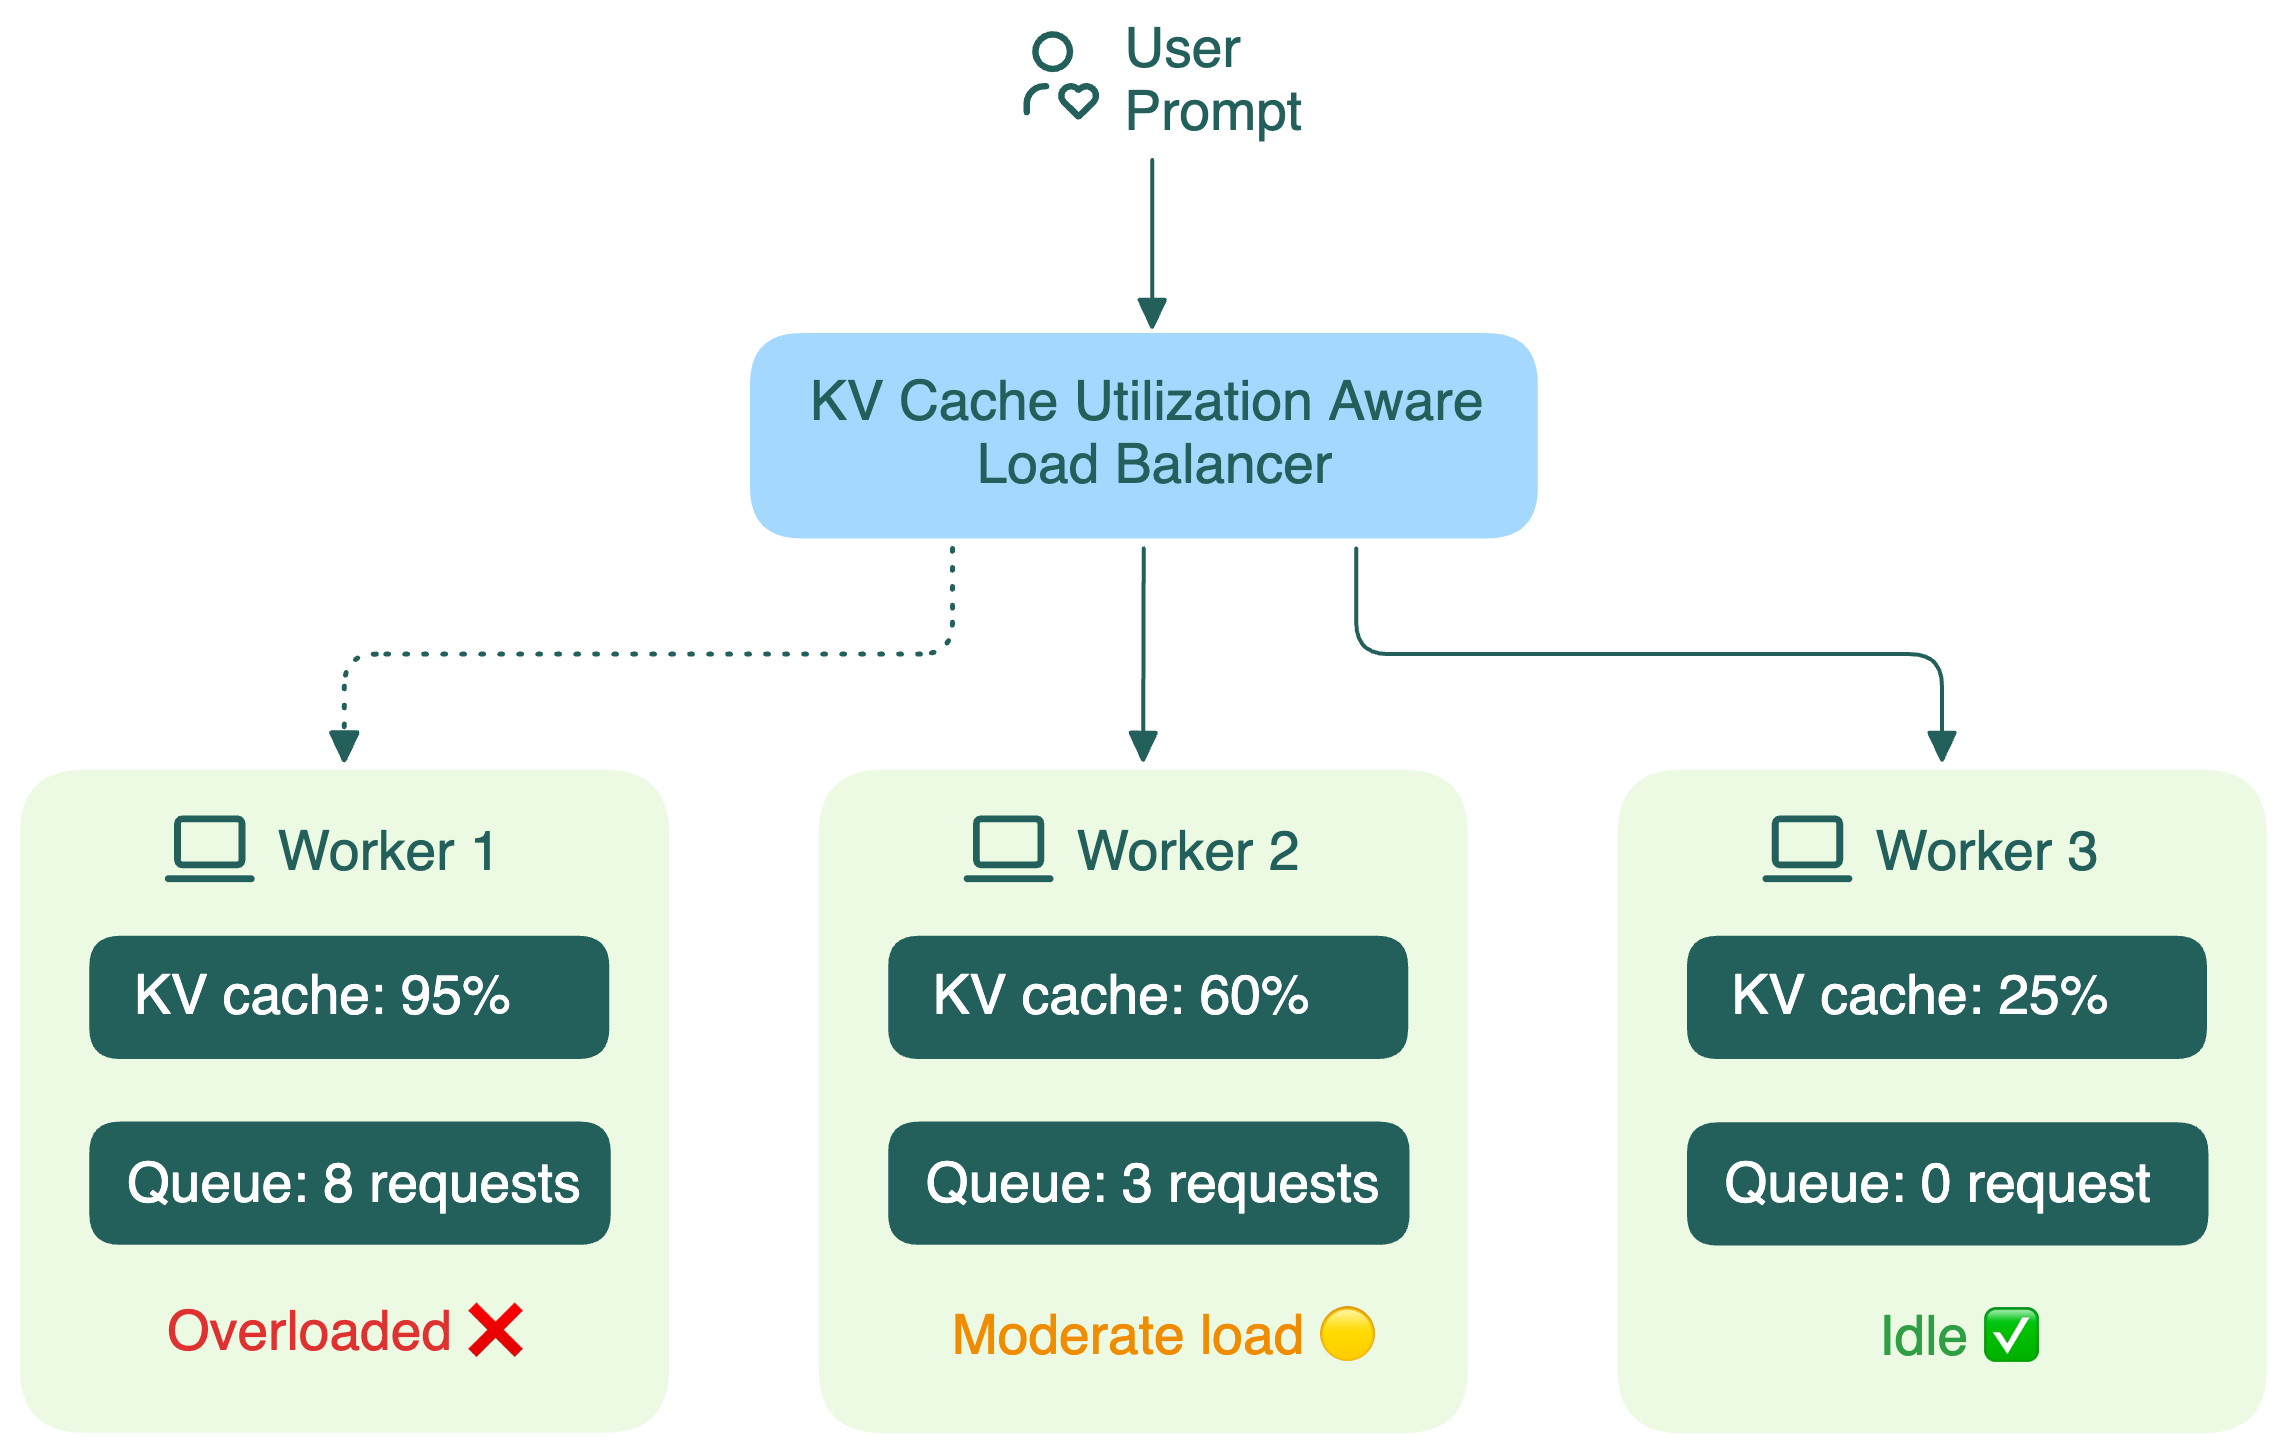
KV cache utilization-aware load balancing | LLM Inference Handbook
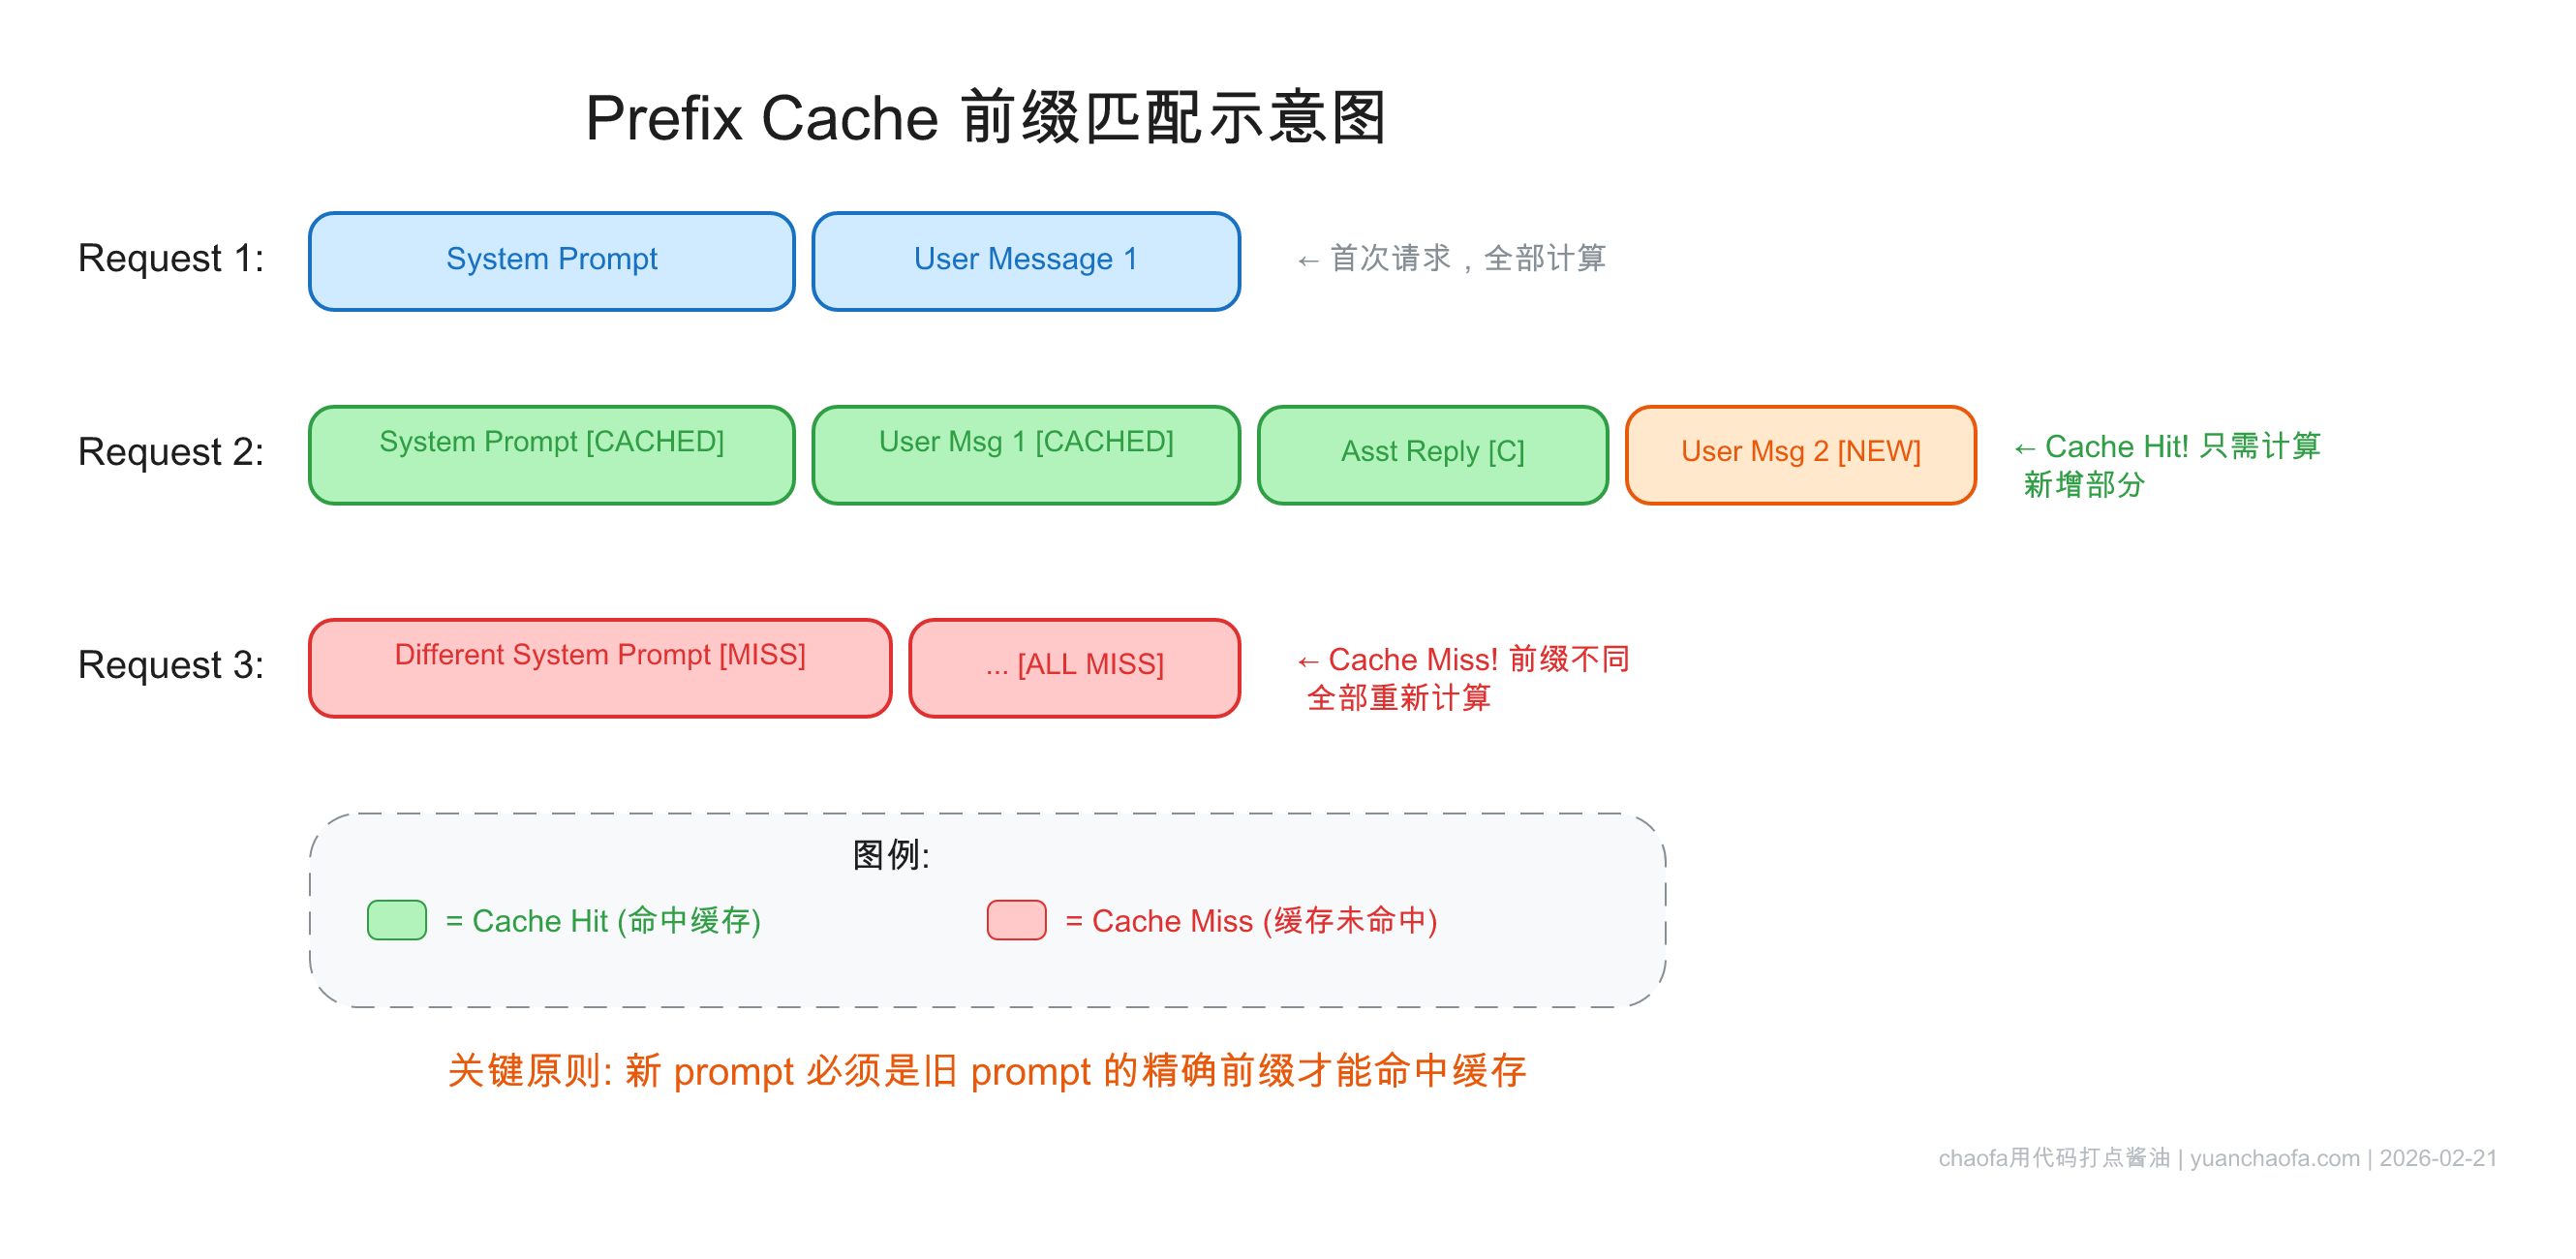
理解 KV Cache 与 Prompt Caching:LLM 推理加速的核心机制 | chaofa用代码打点酱油
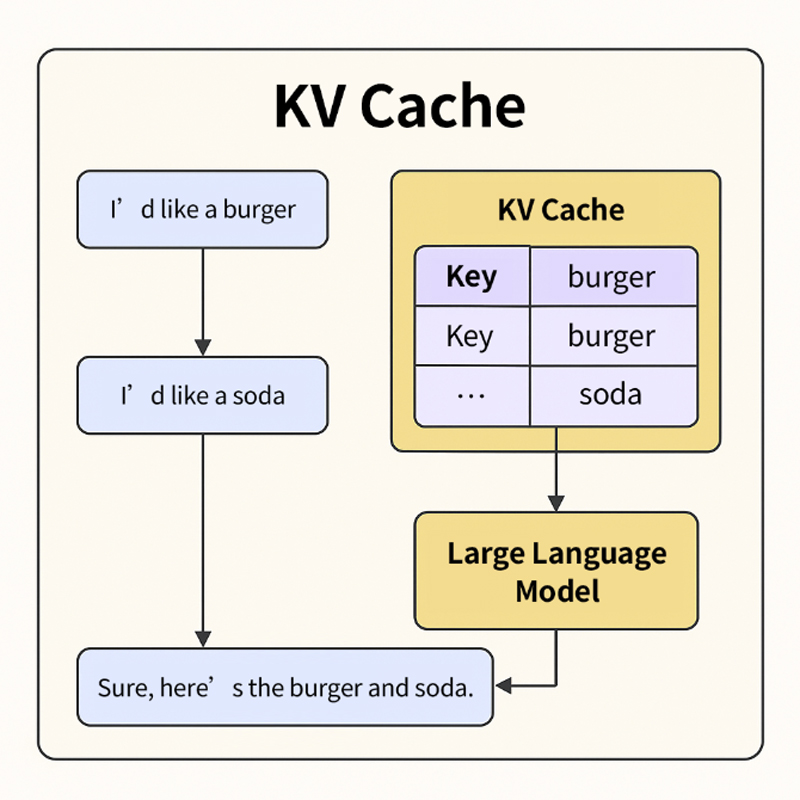
KV Cache Meets NVMe: The Key to Accelerating LLM Inference

ClusterKV: Manipulating LLM KV Cache in Semantic Space for Recallable ...
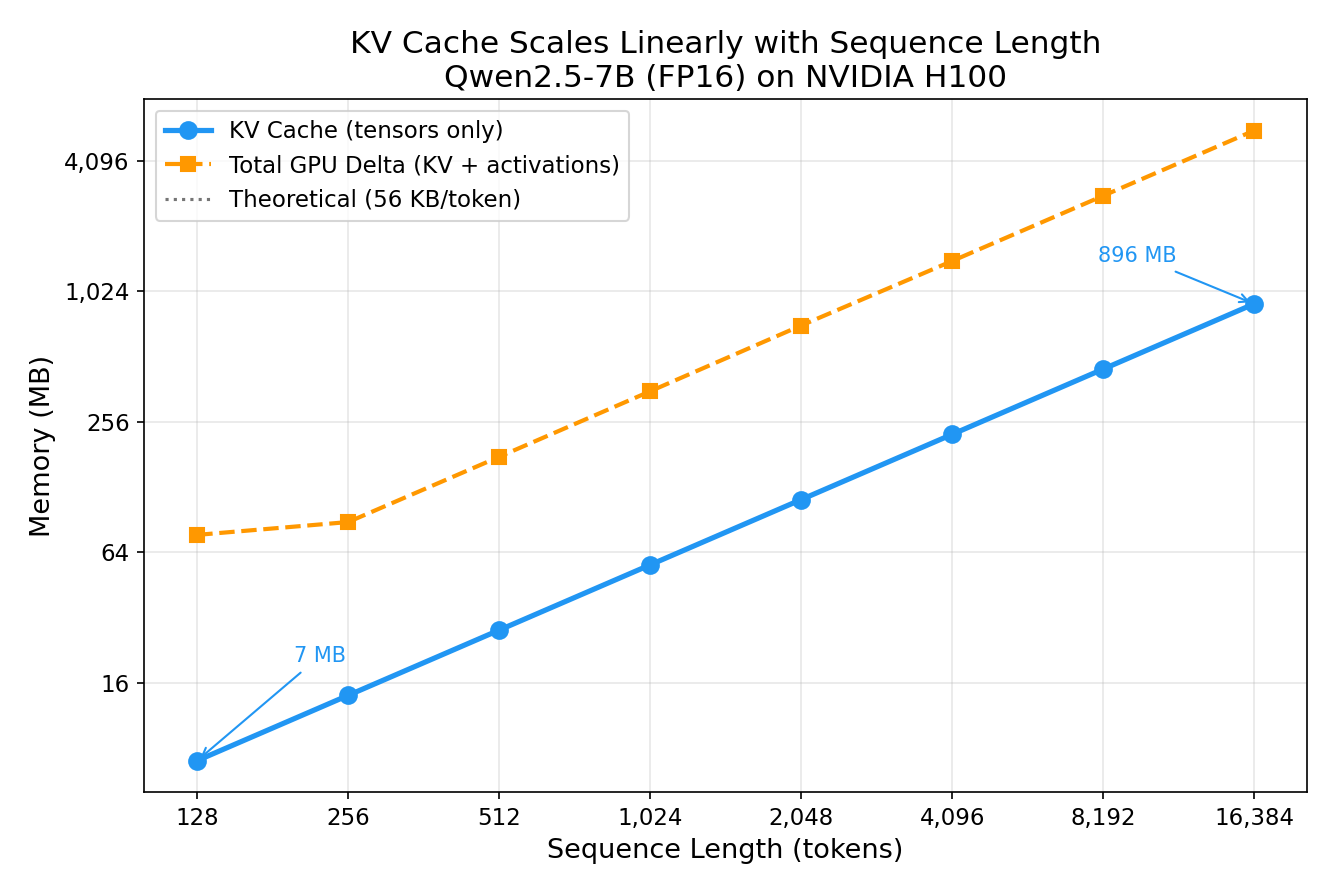
Understanding KV Cache in LLM Inference - Jingchao’s Website

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...
Advertisement Space (300x250)
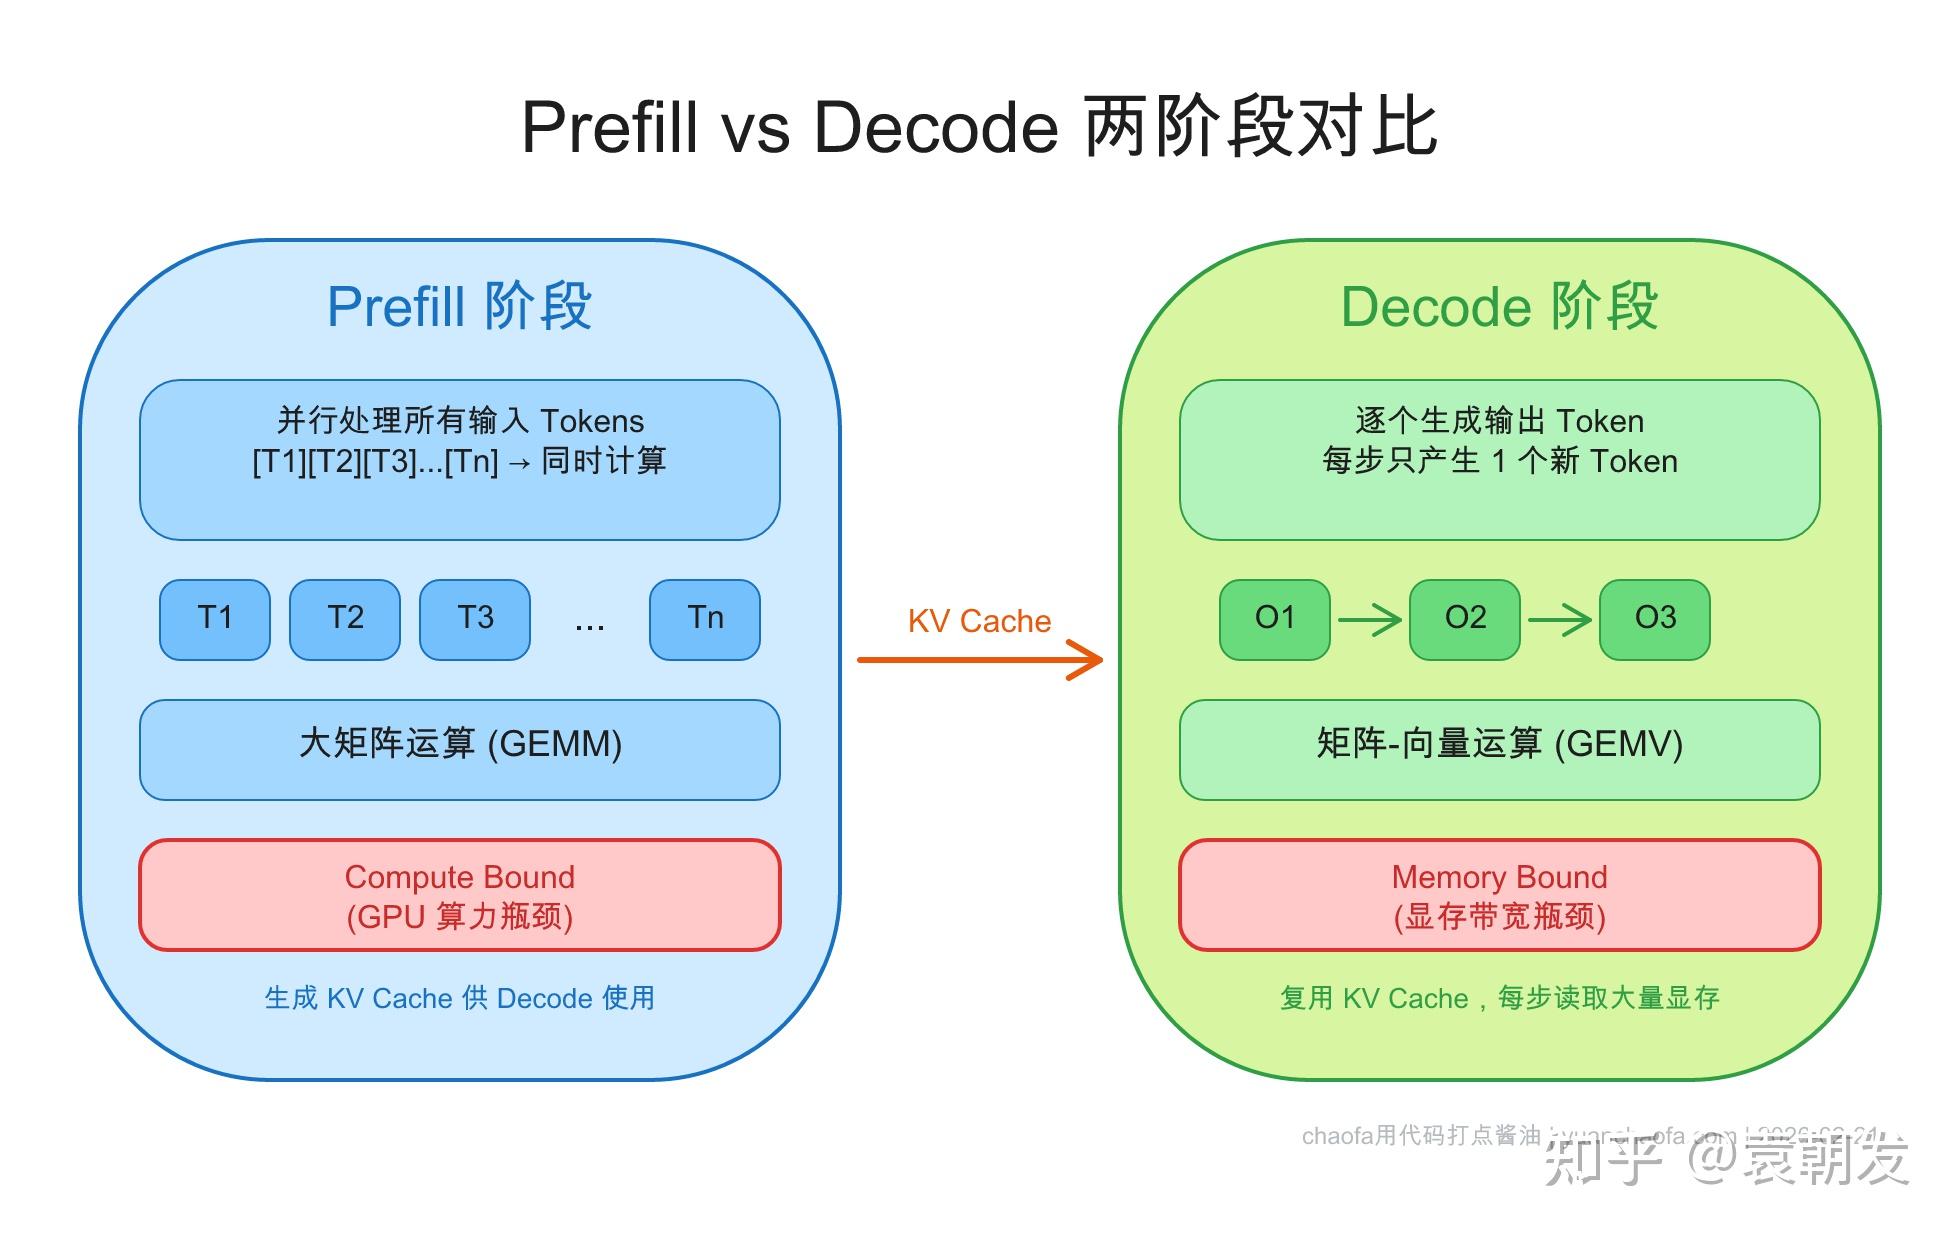
理解 KV Cache 与 Prompt Caching:LLM 推理加速的核心机制 - 知乎
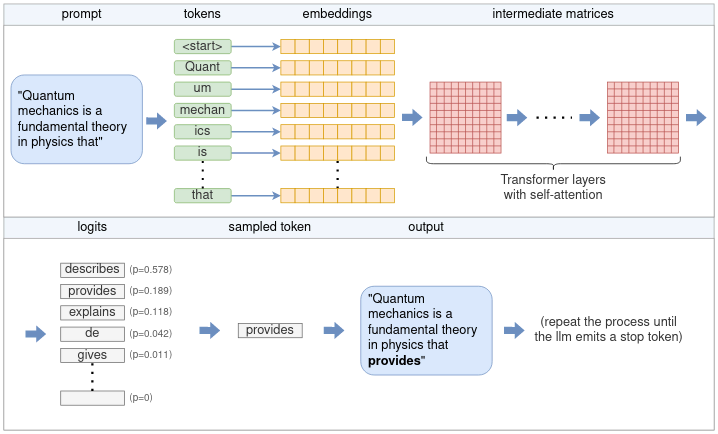
LLM 和 KV cache 详解 | Jasmine
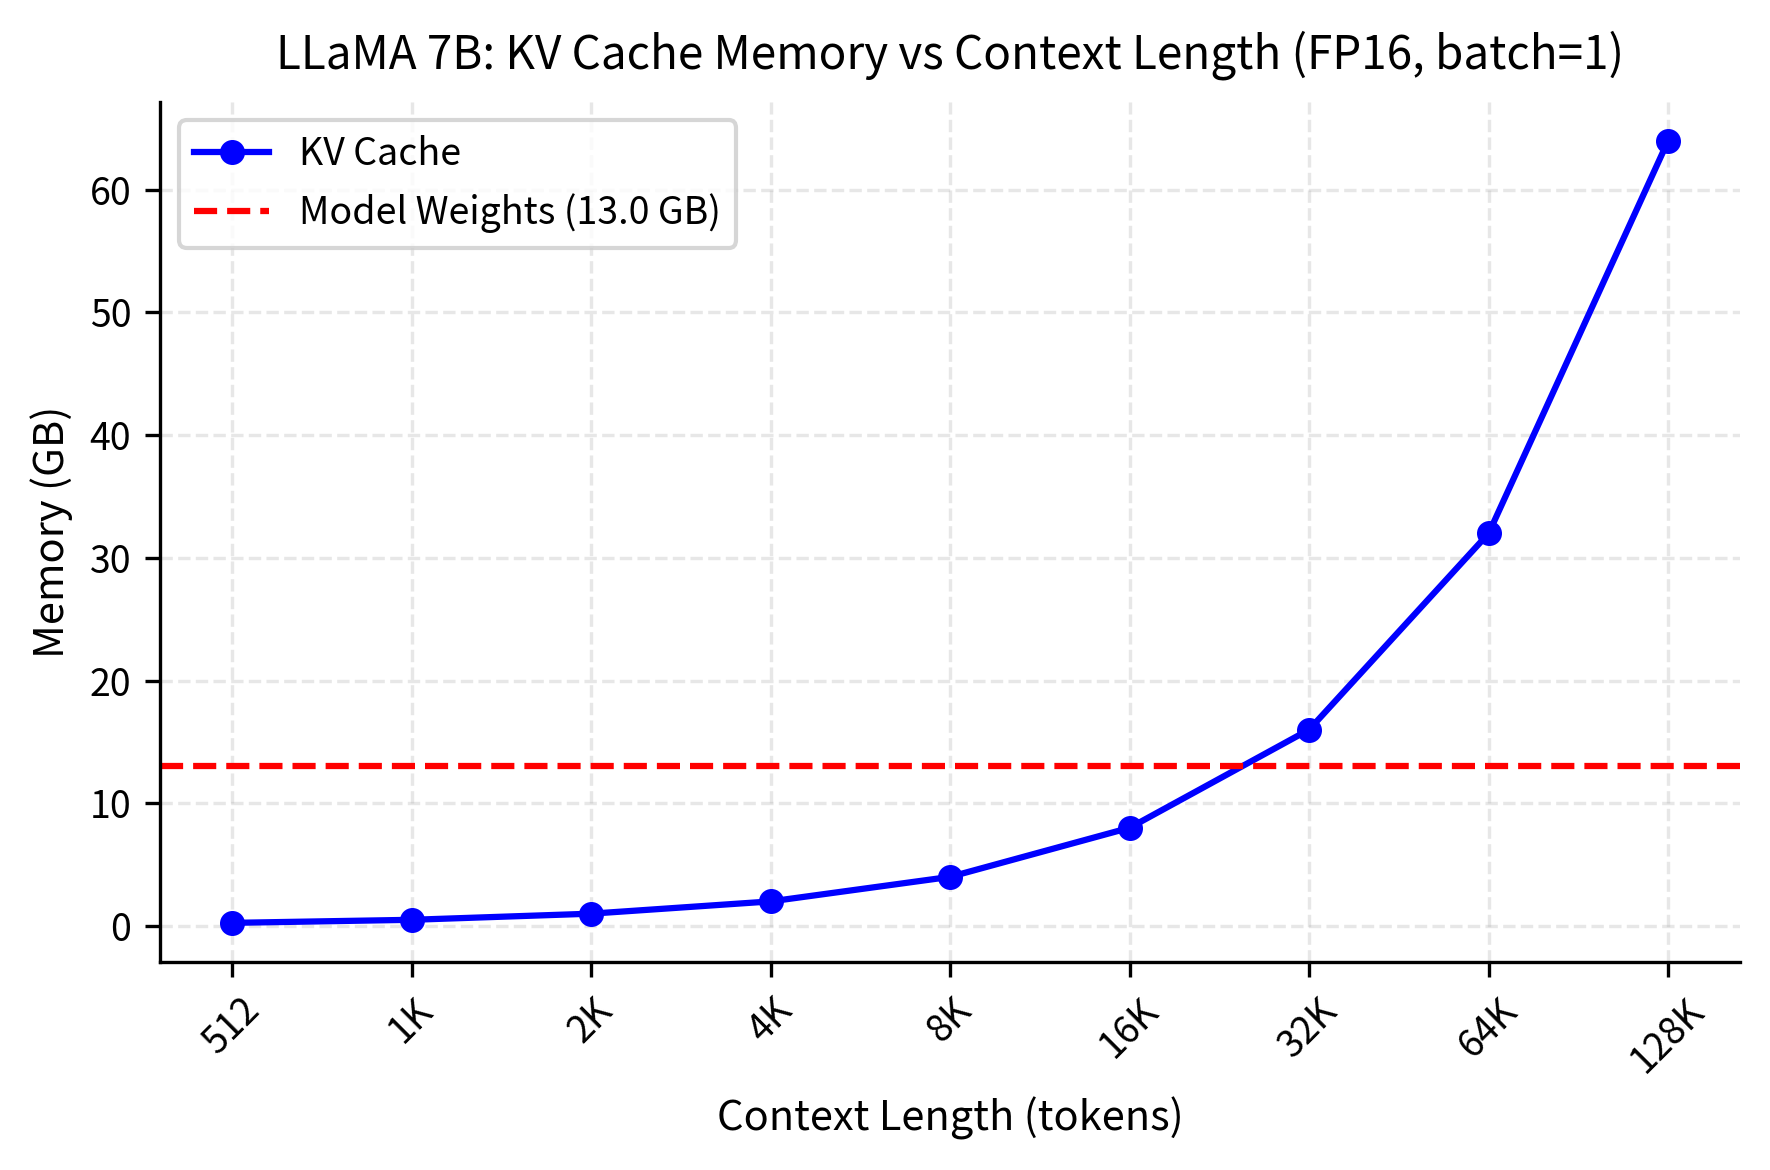
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
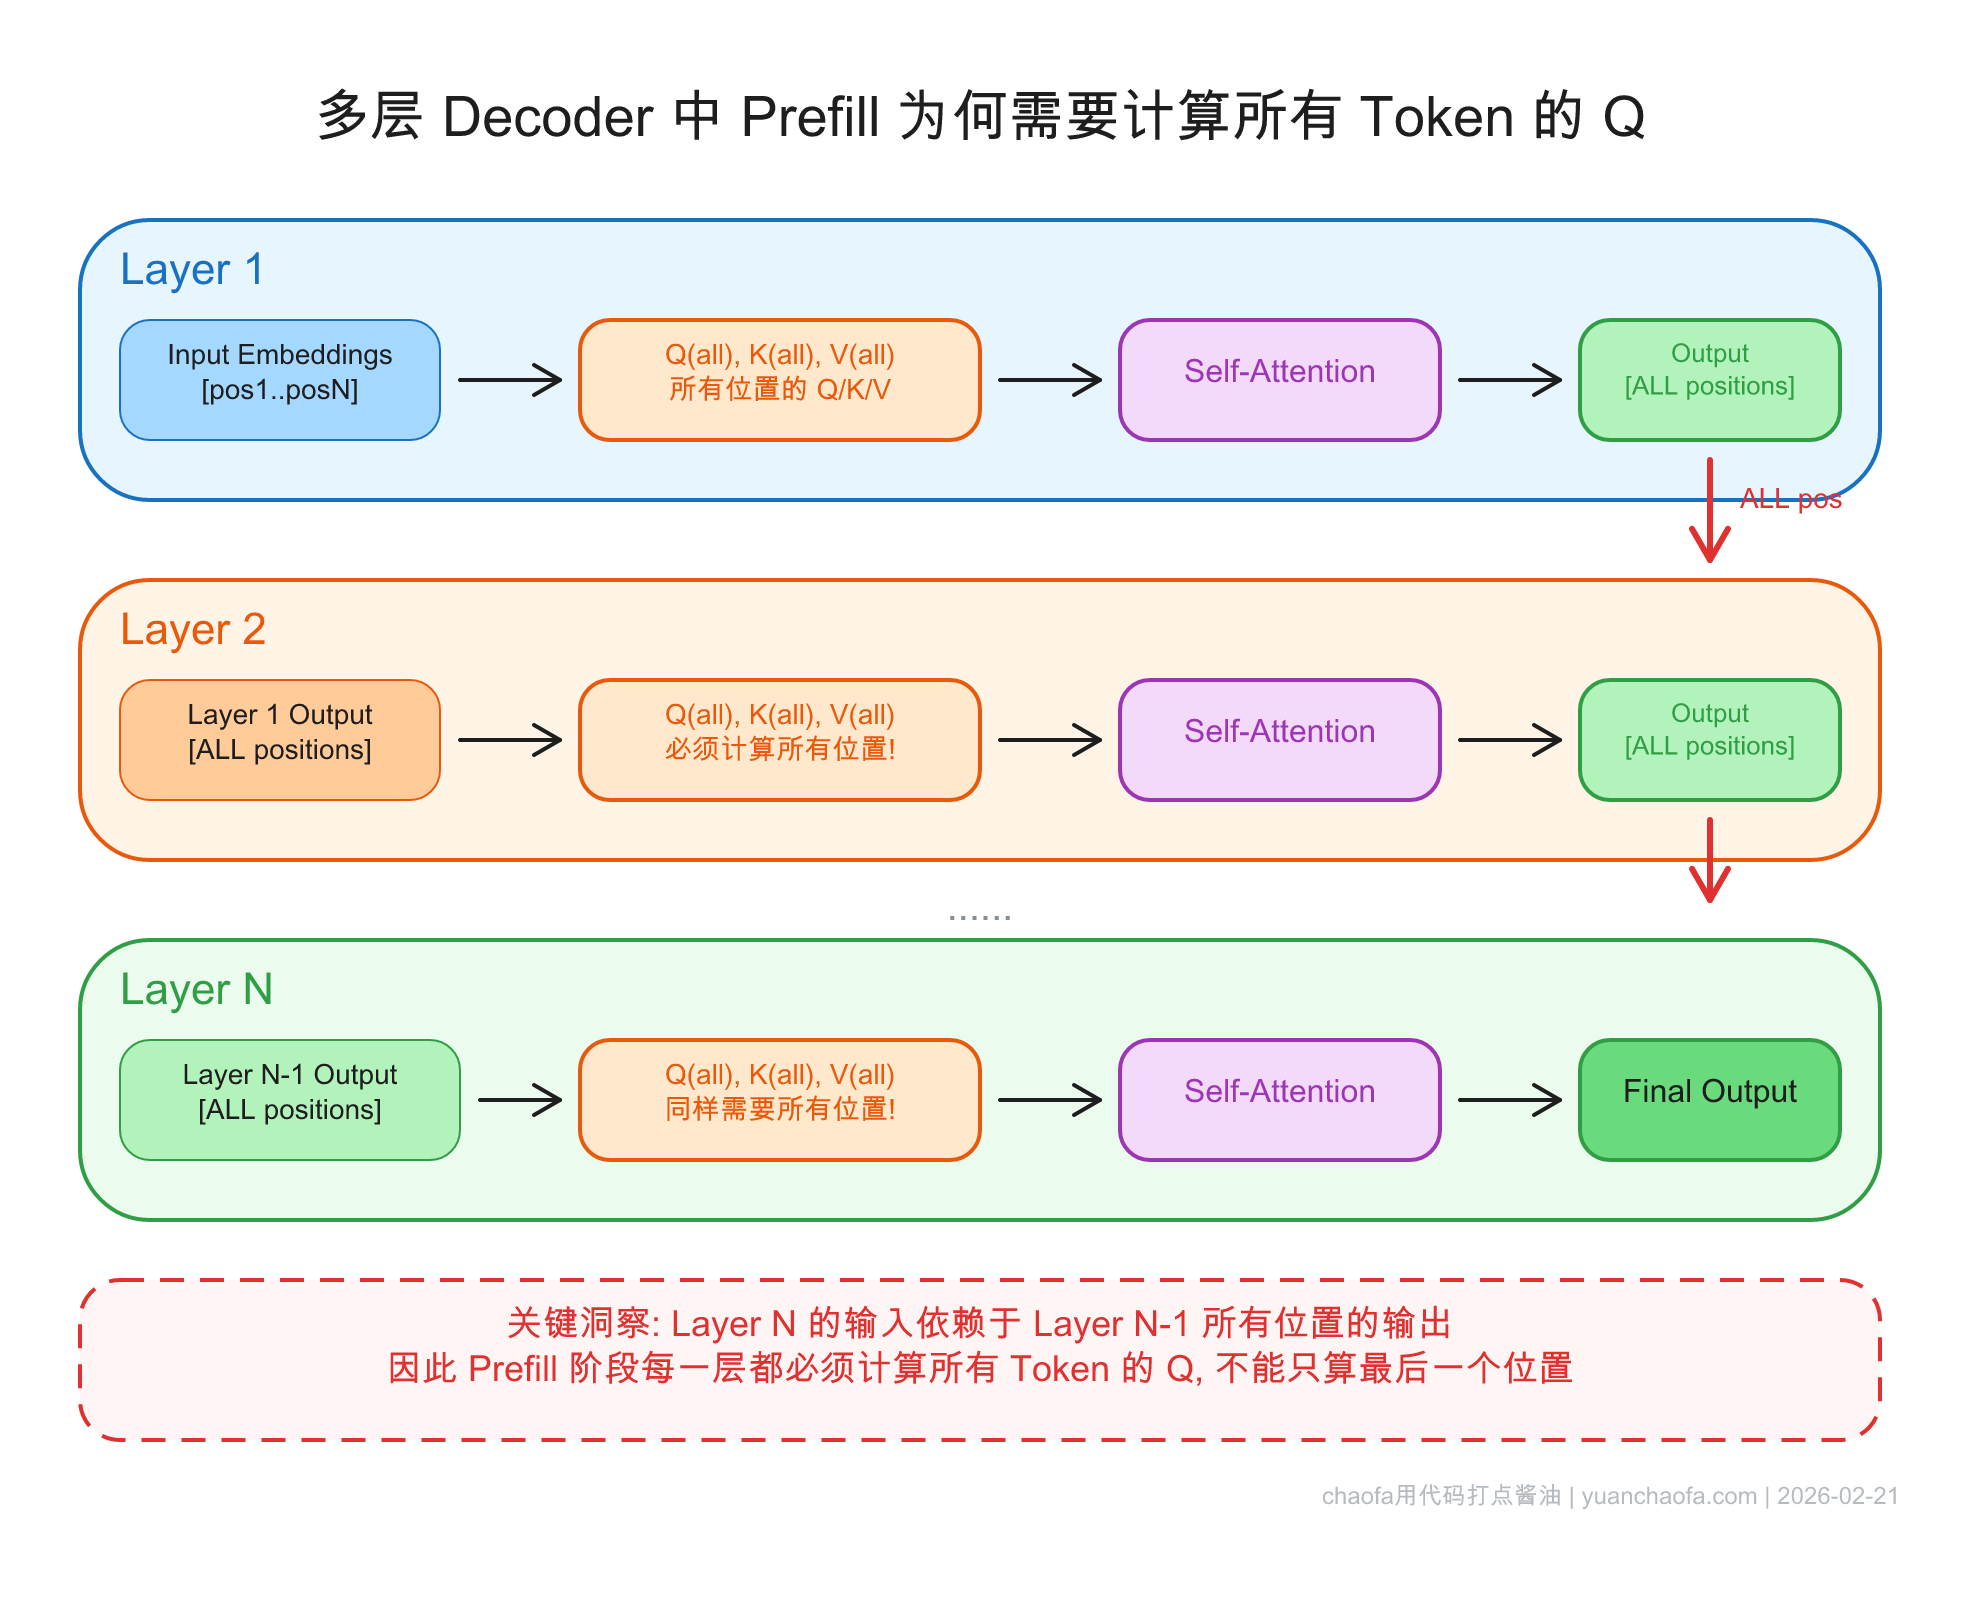
理解 KV Cache 与 Prompt Caching:LLM 推理加速的核心机制 | chaofa用代码打点酱油

KV Cache Offload Accelerates LLM Inference - NADDOD Blog
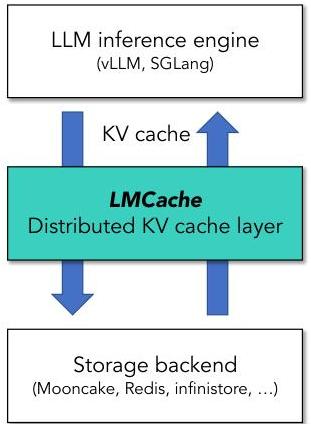
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

KV Cache and Prompt Caching: How to Leverage them to Cut Time and Costs ...
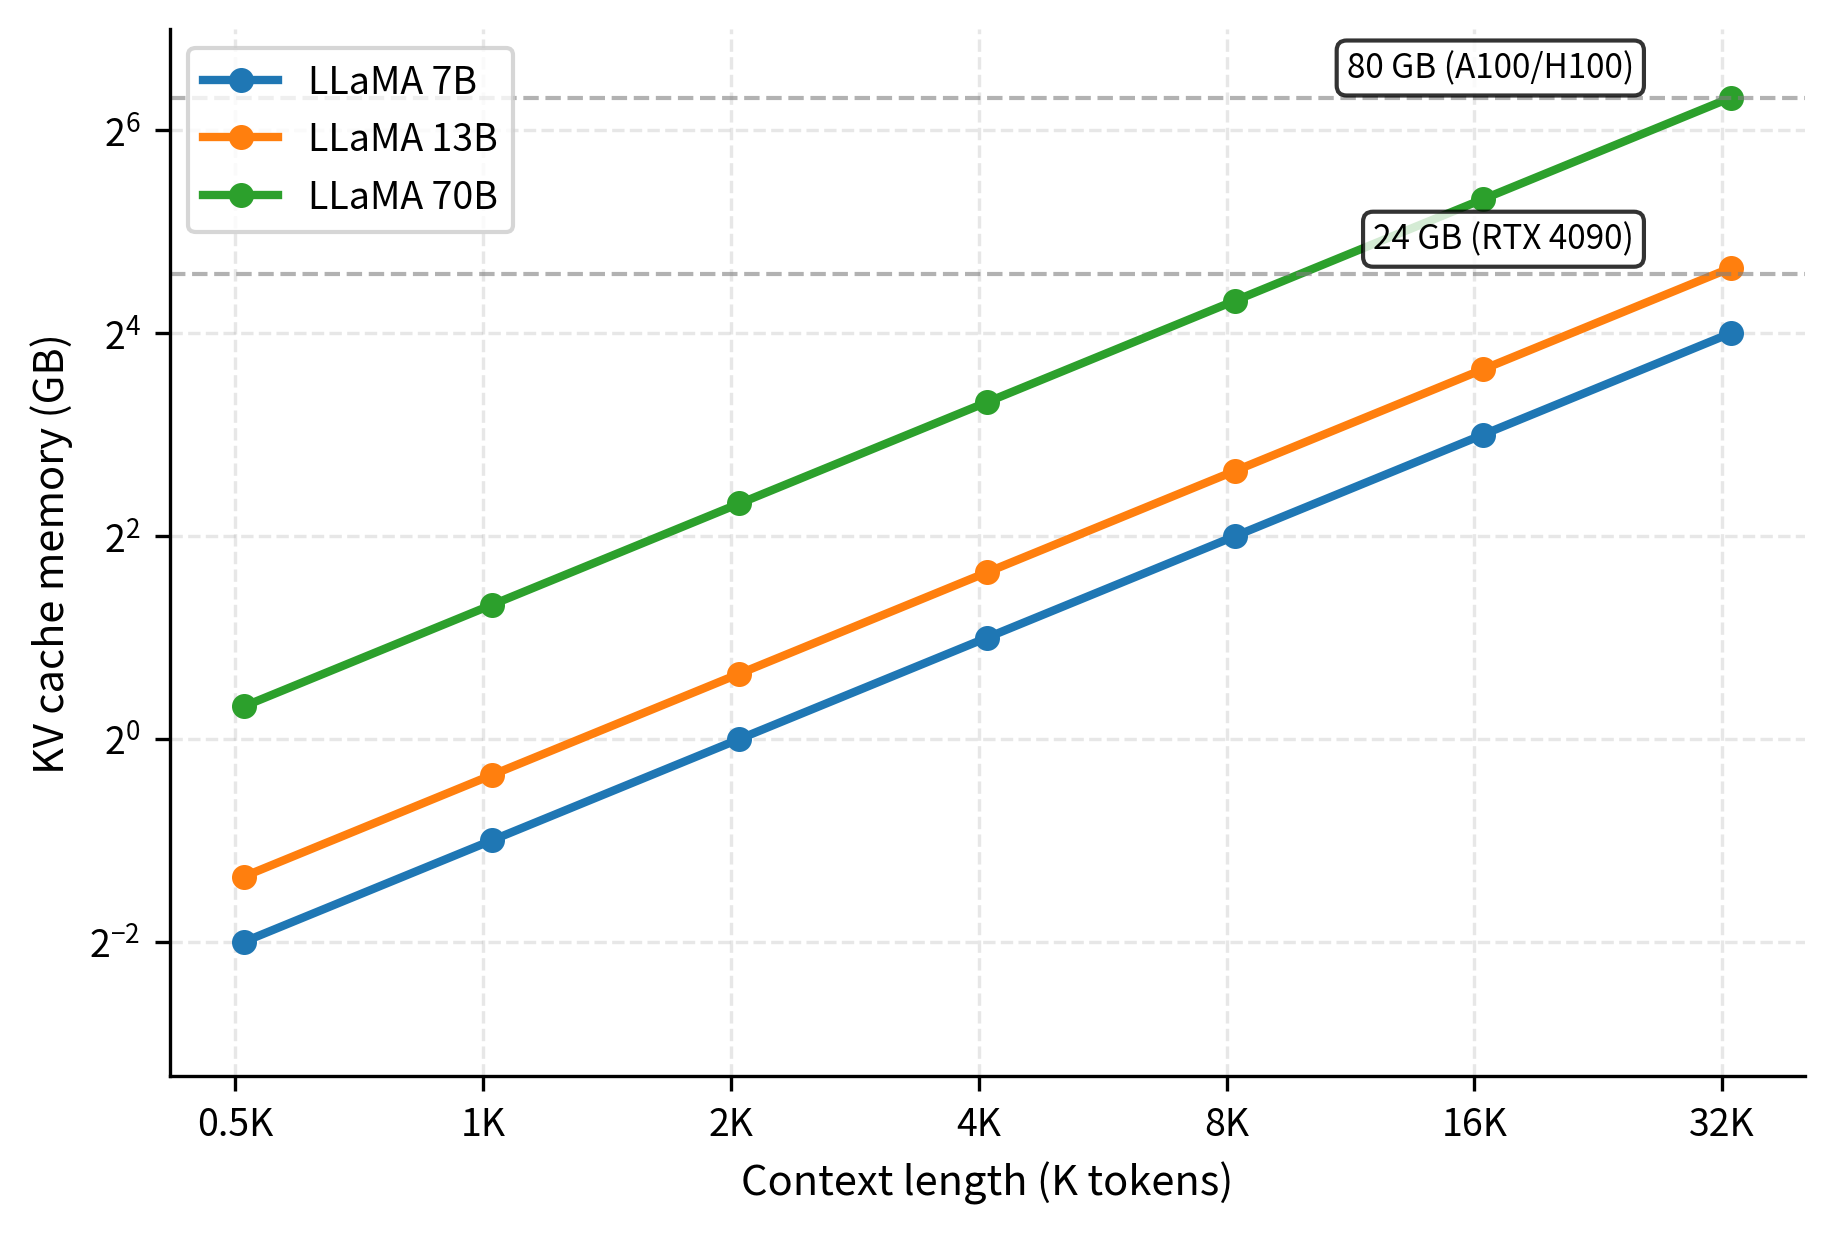
KV Cache Explained: Efficient Attention for LLM Generation ...
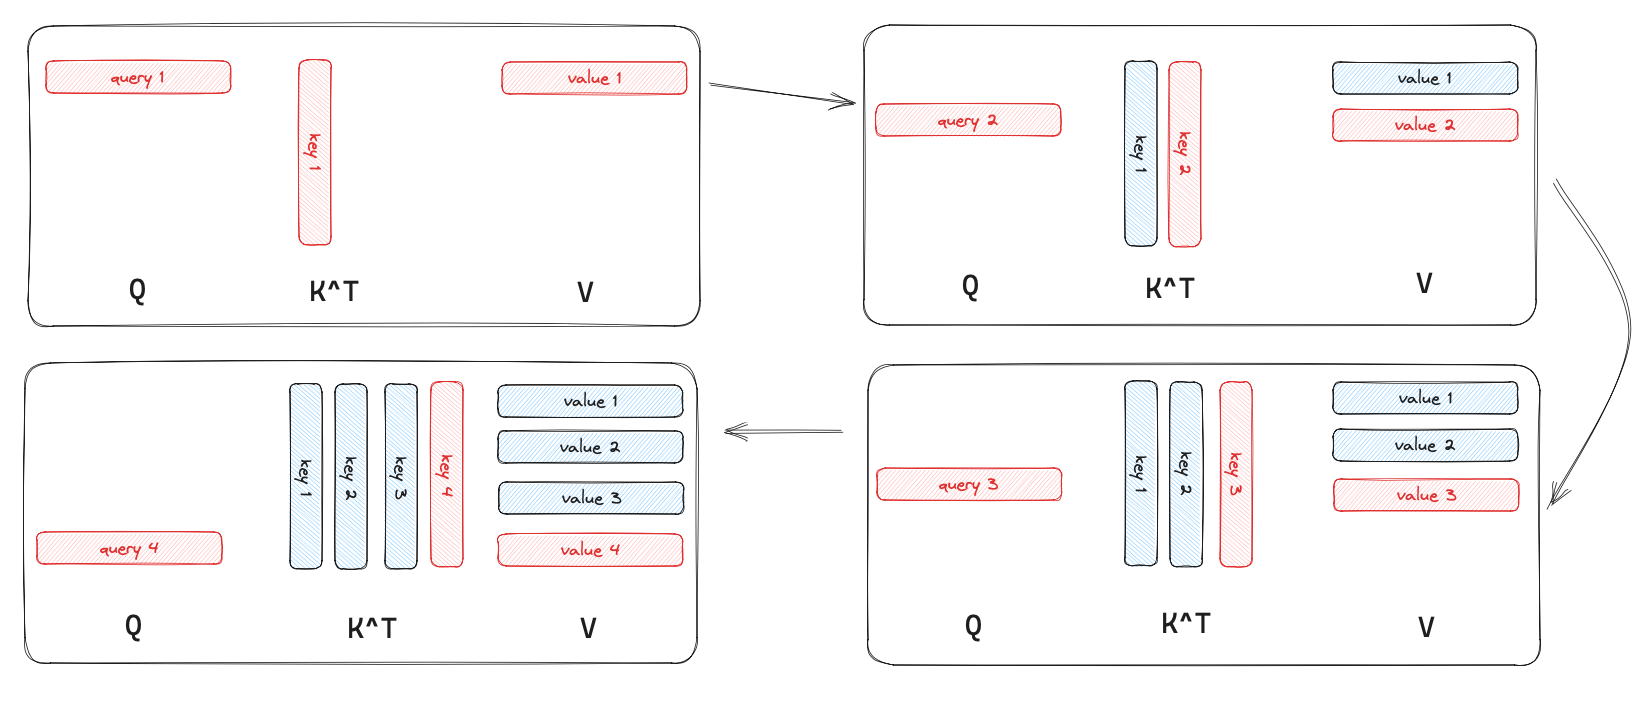
LLM inference optimization (1): KV Cache - MartinLwx's Blog
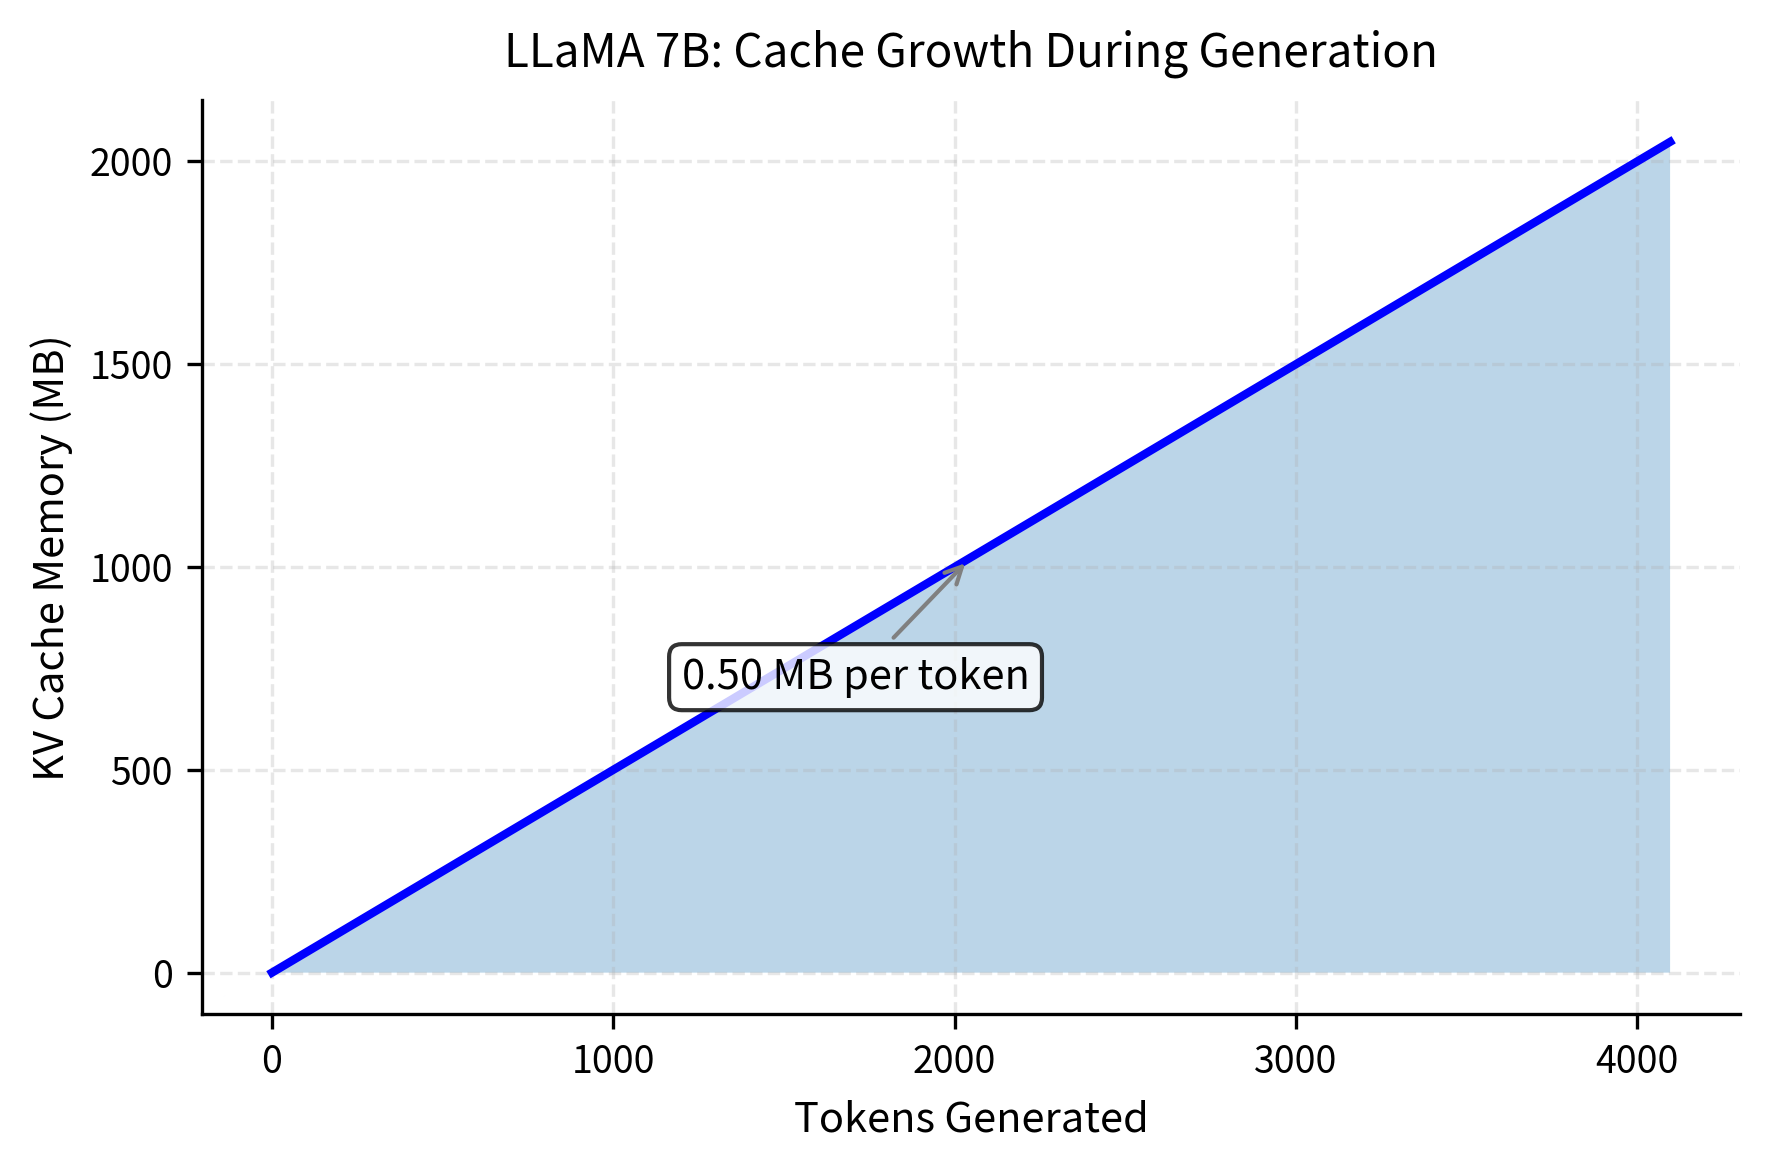
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
Advertisement Space (336x280)
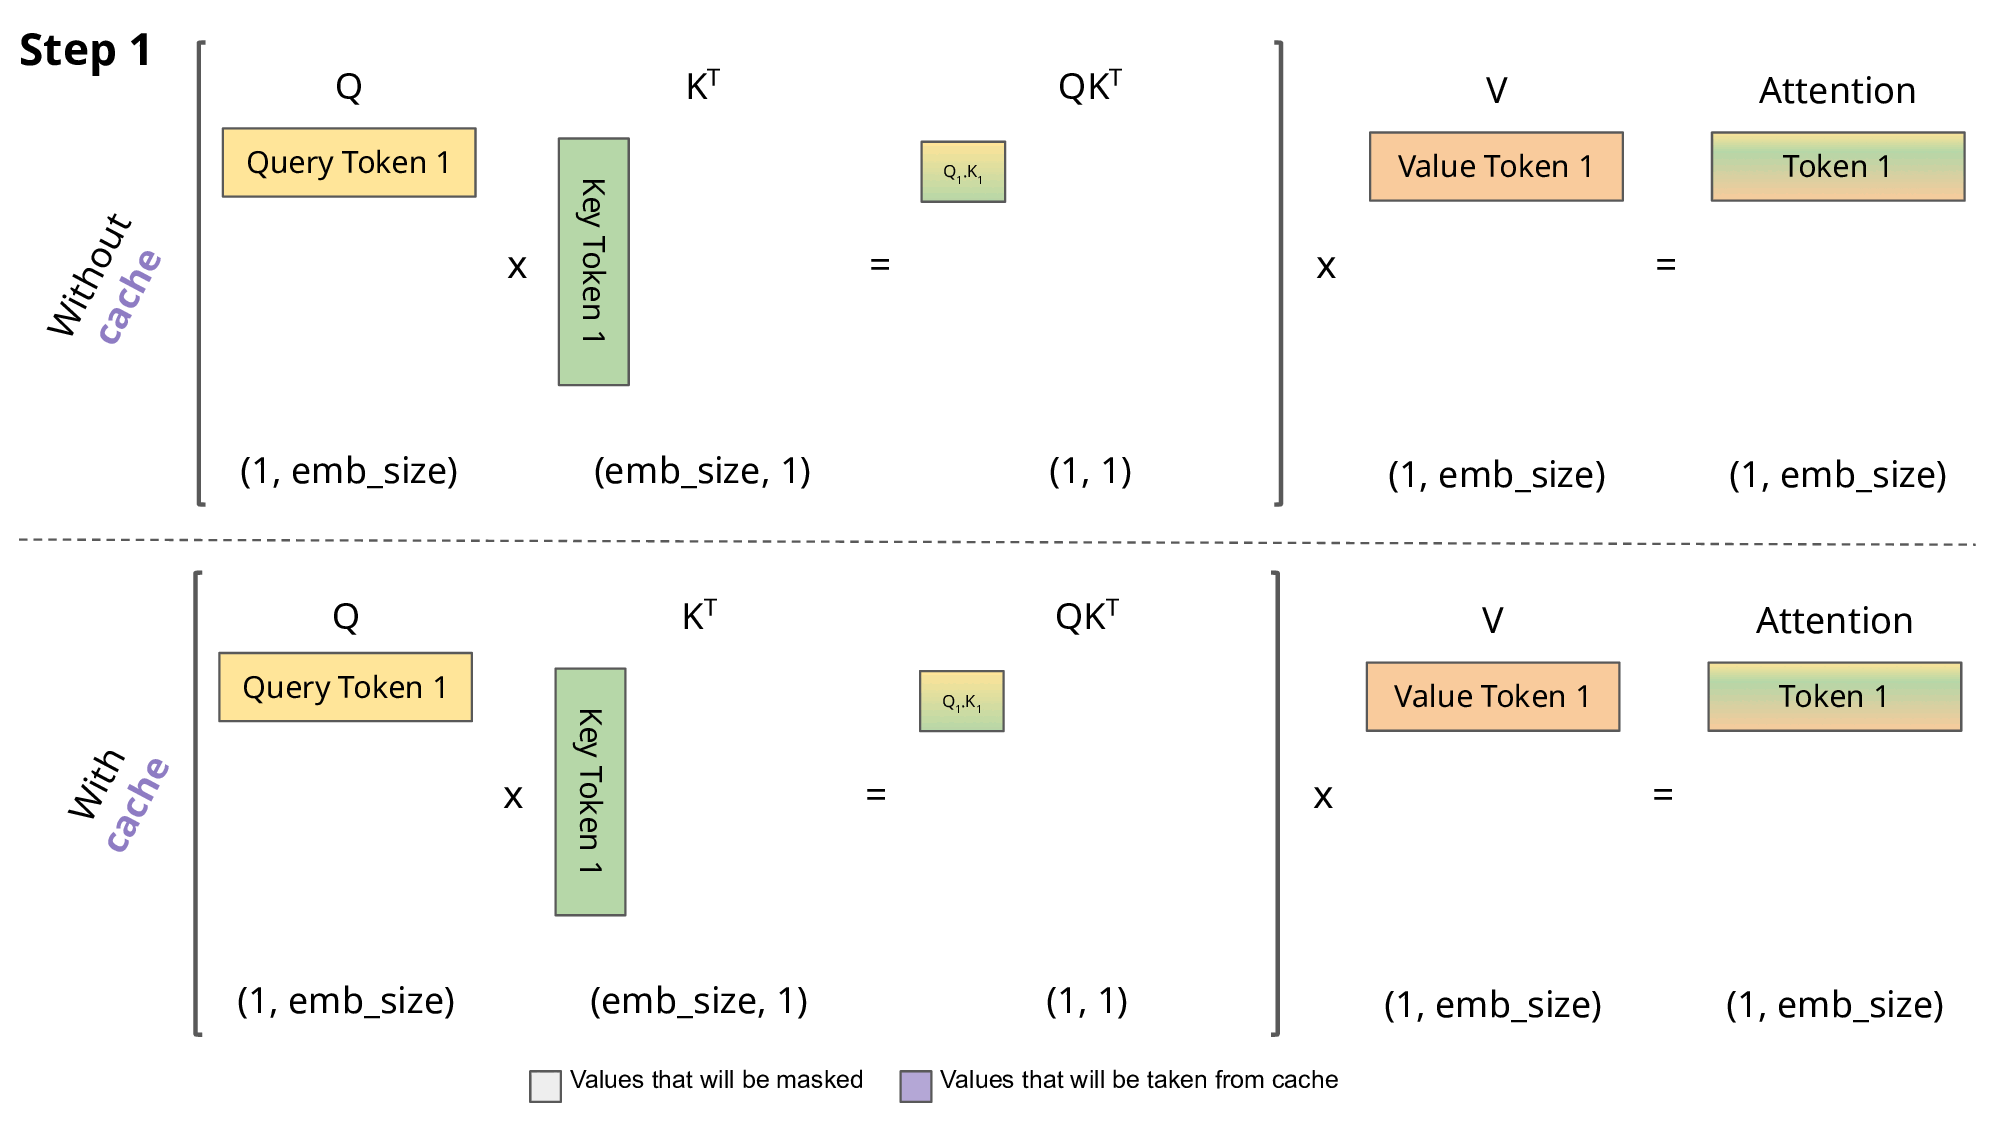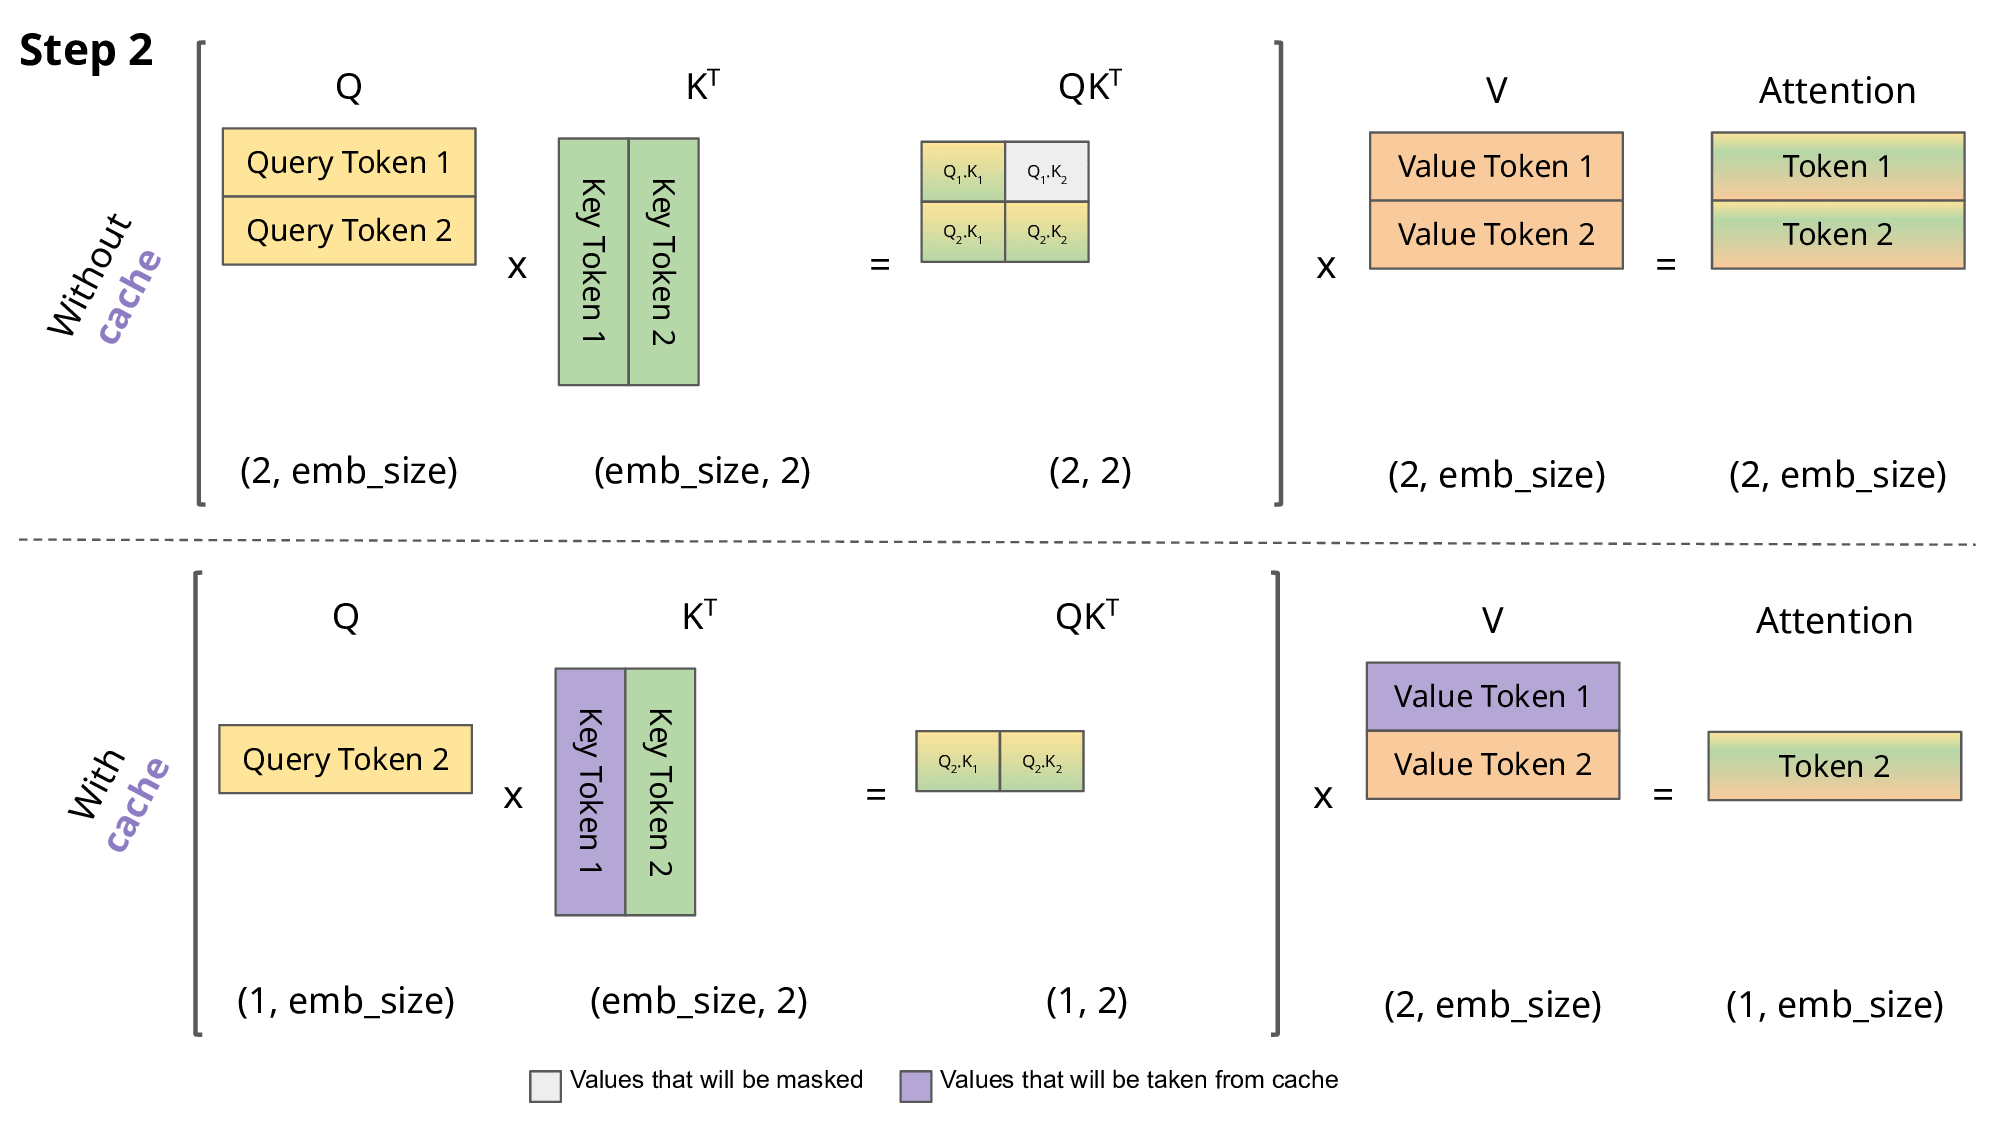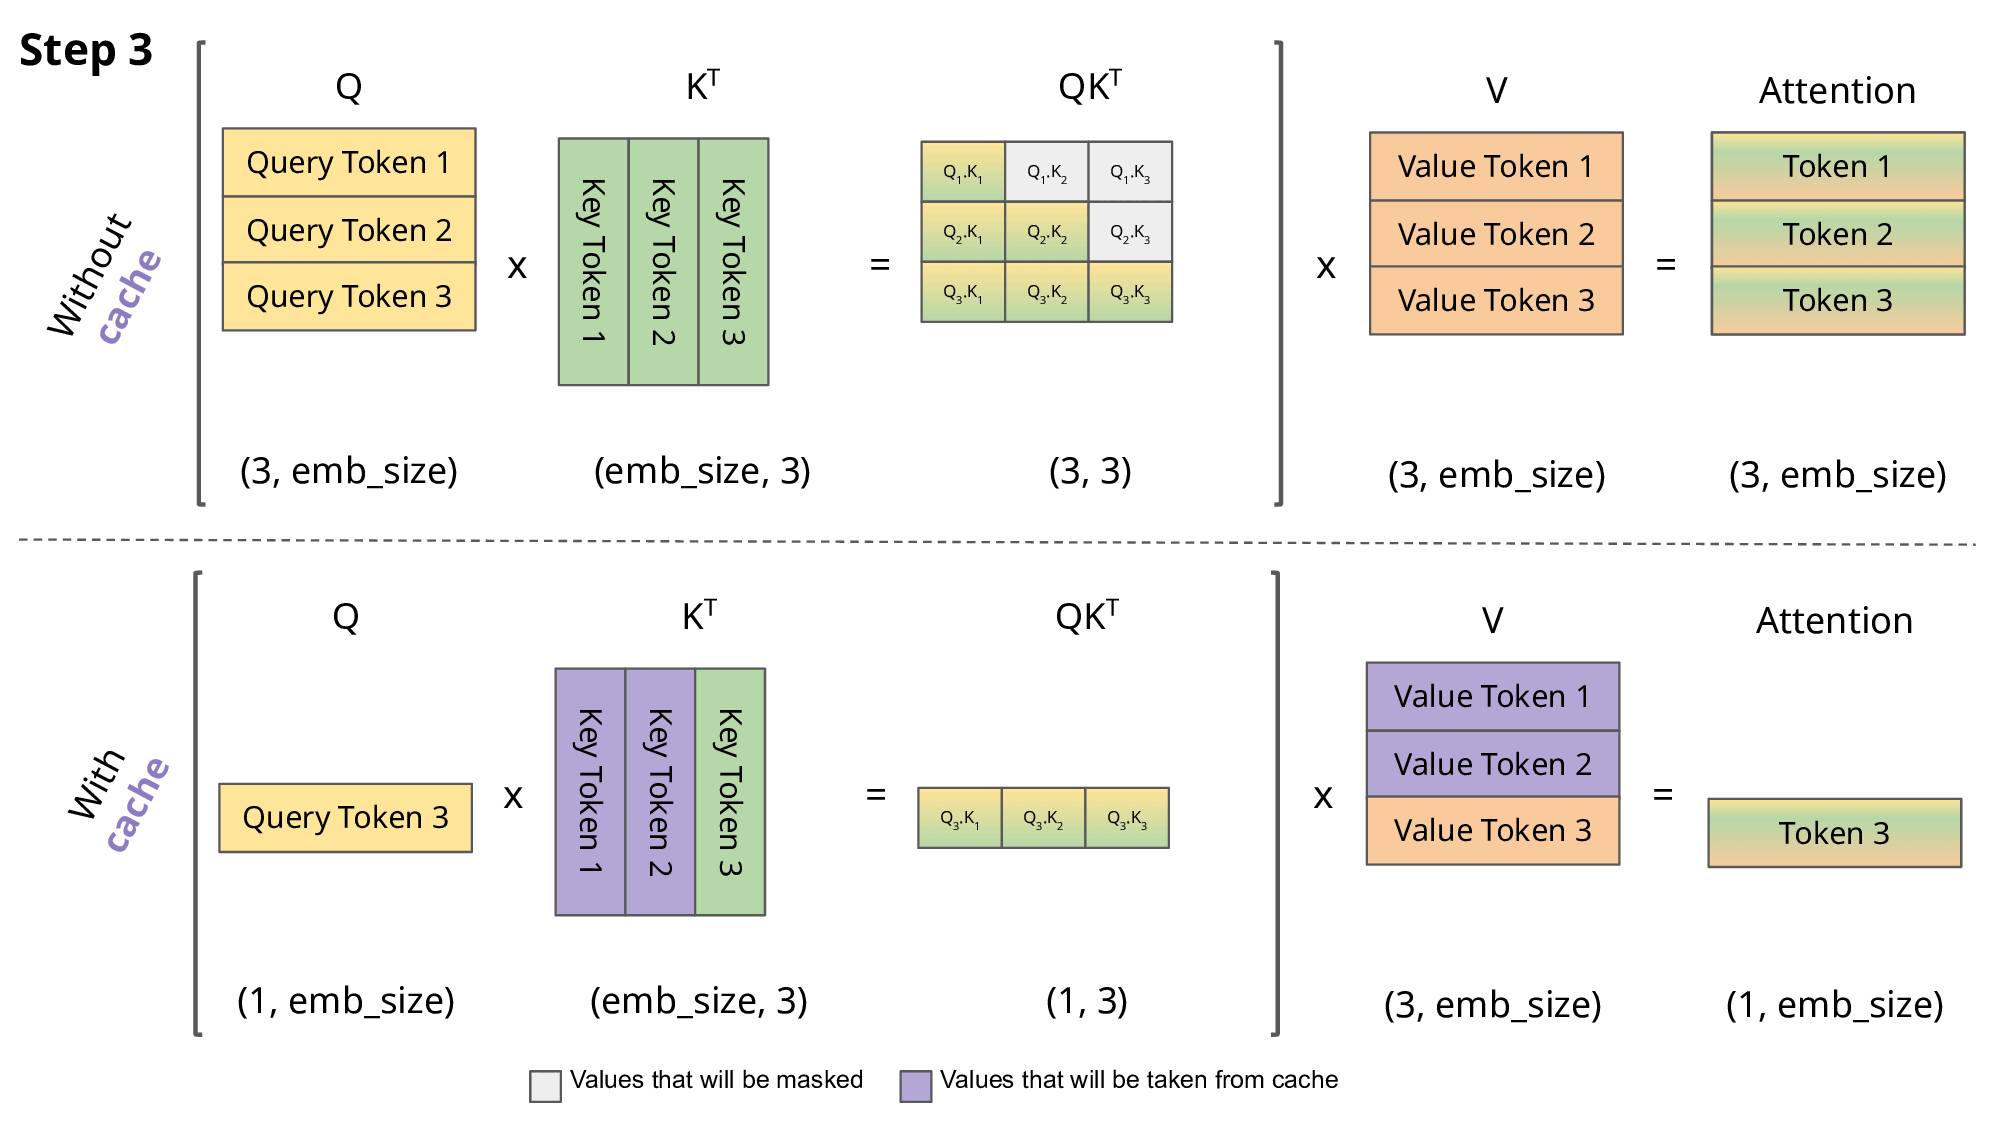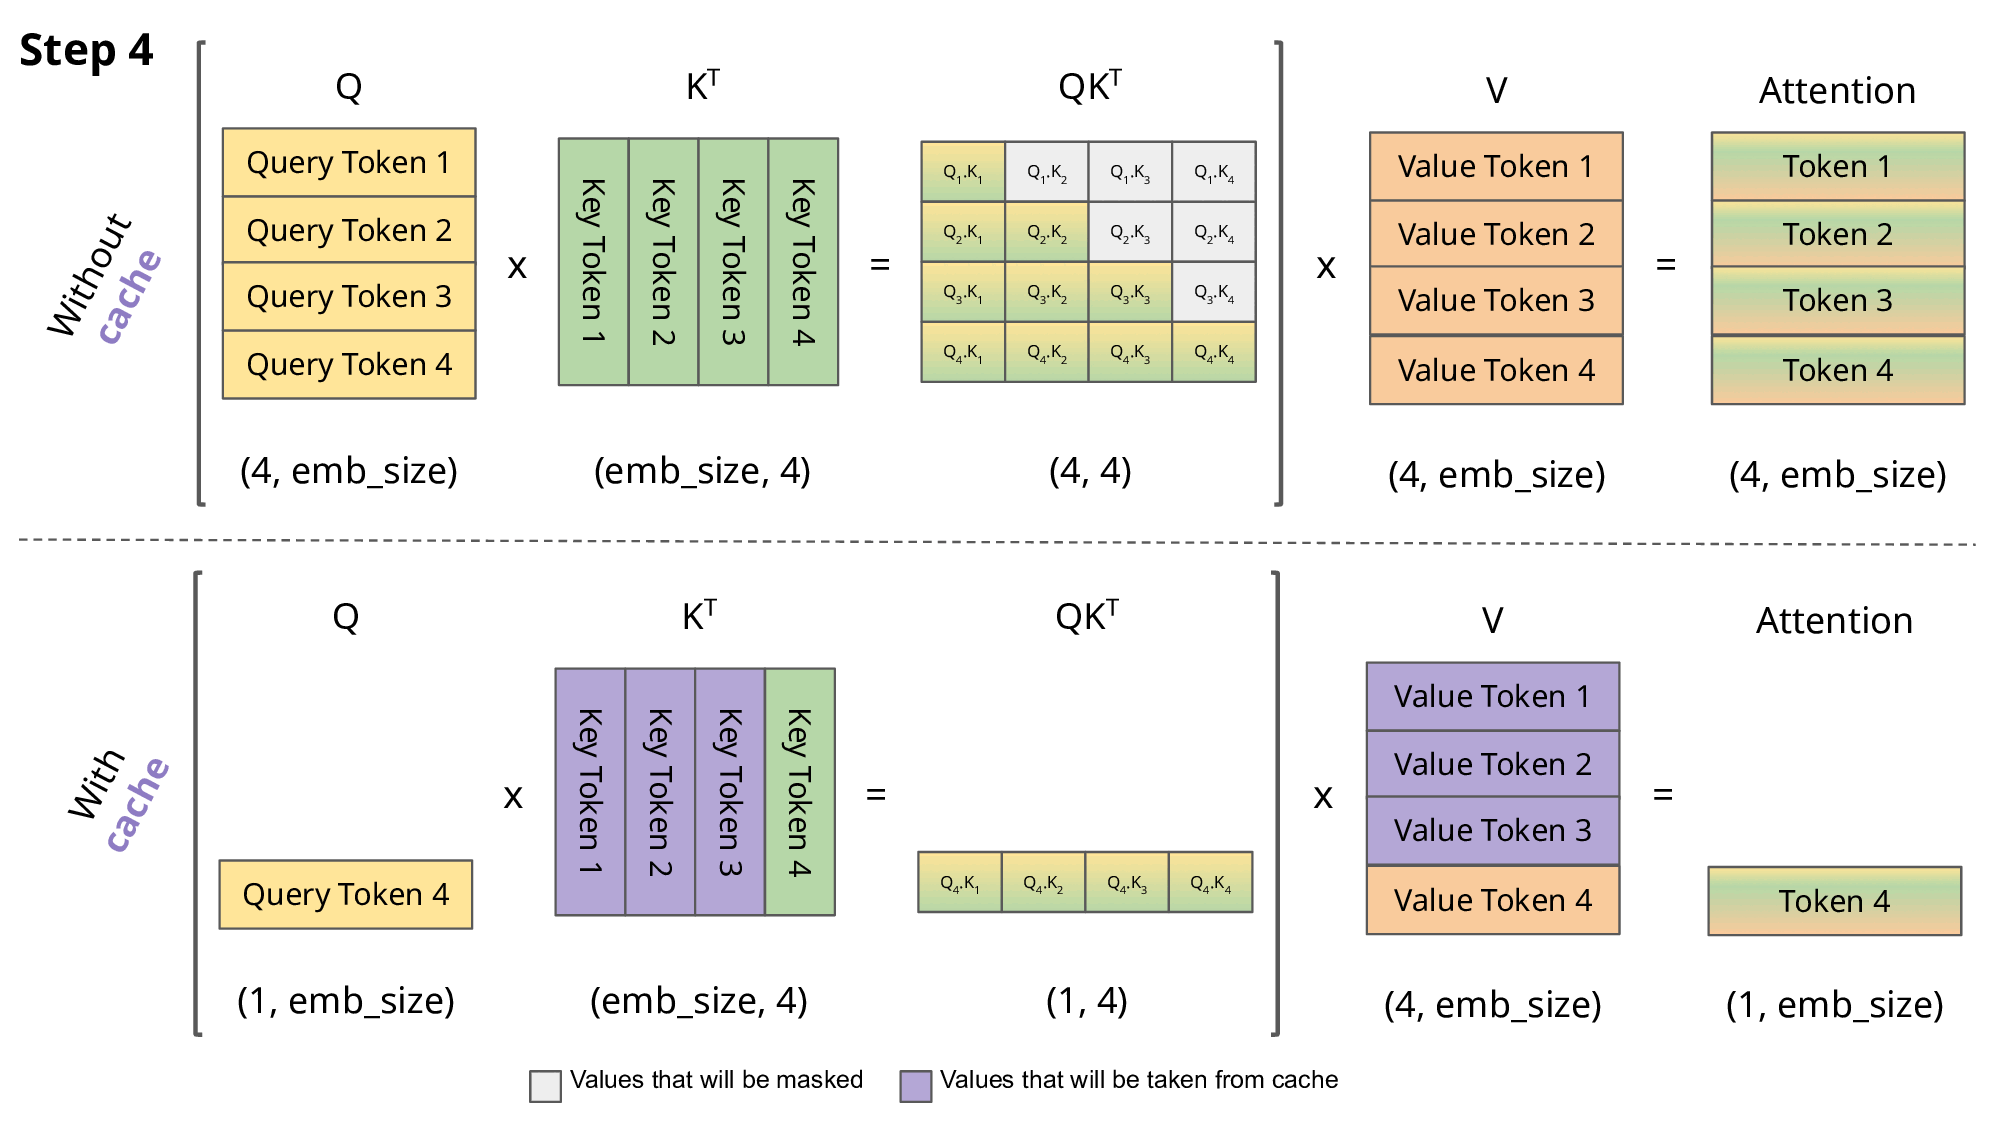
KV Cache 详解:新手也能理解的 LLM 推理加速技巧-CSDN博客

KV Cache Memory: Sizing LLM Inference
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...
Prompt Caching LLM: KV cache 10 times cheaper

Comparative Characterization of KV Cache Management Strategies for LLM ...
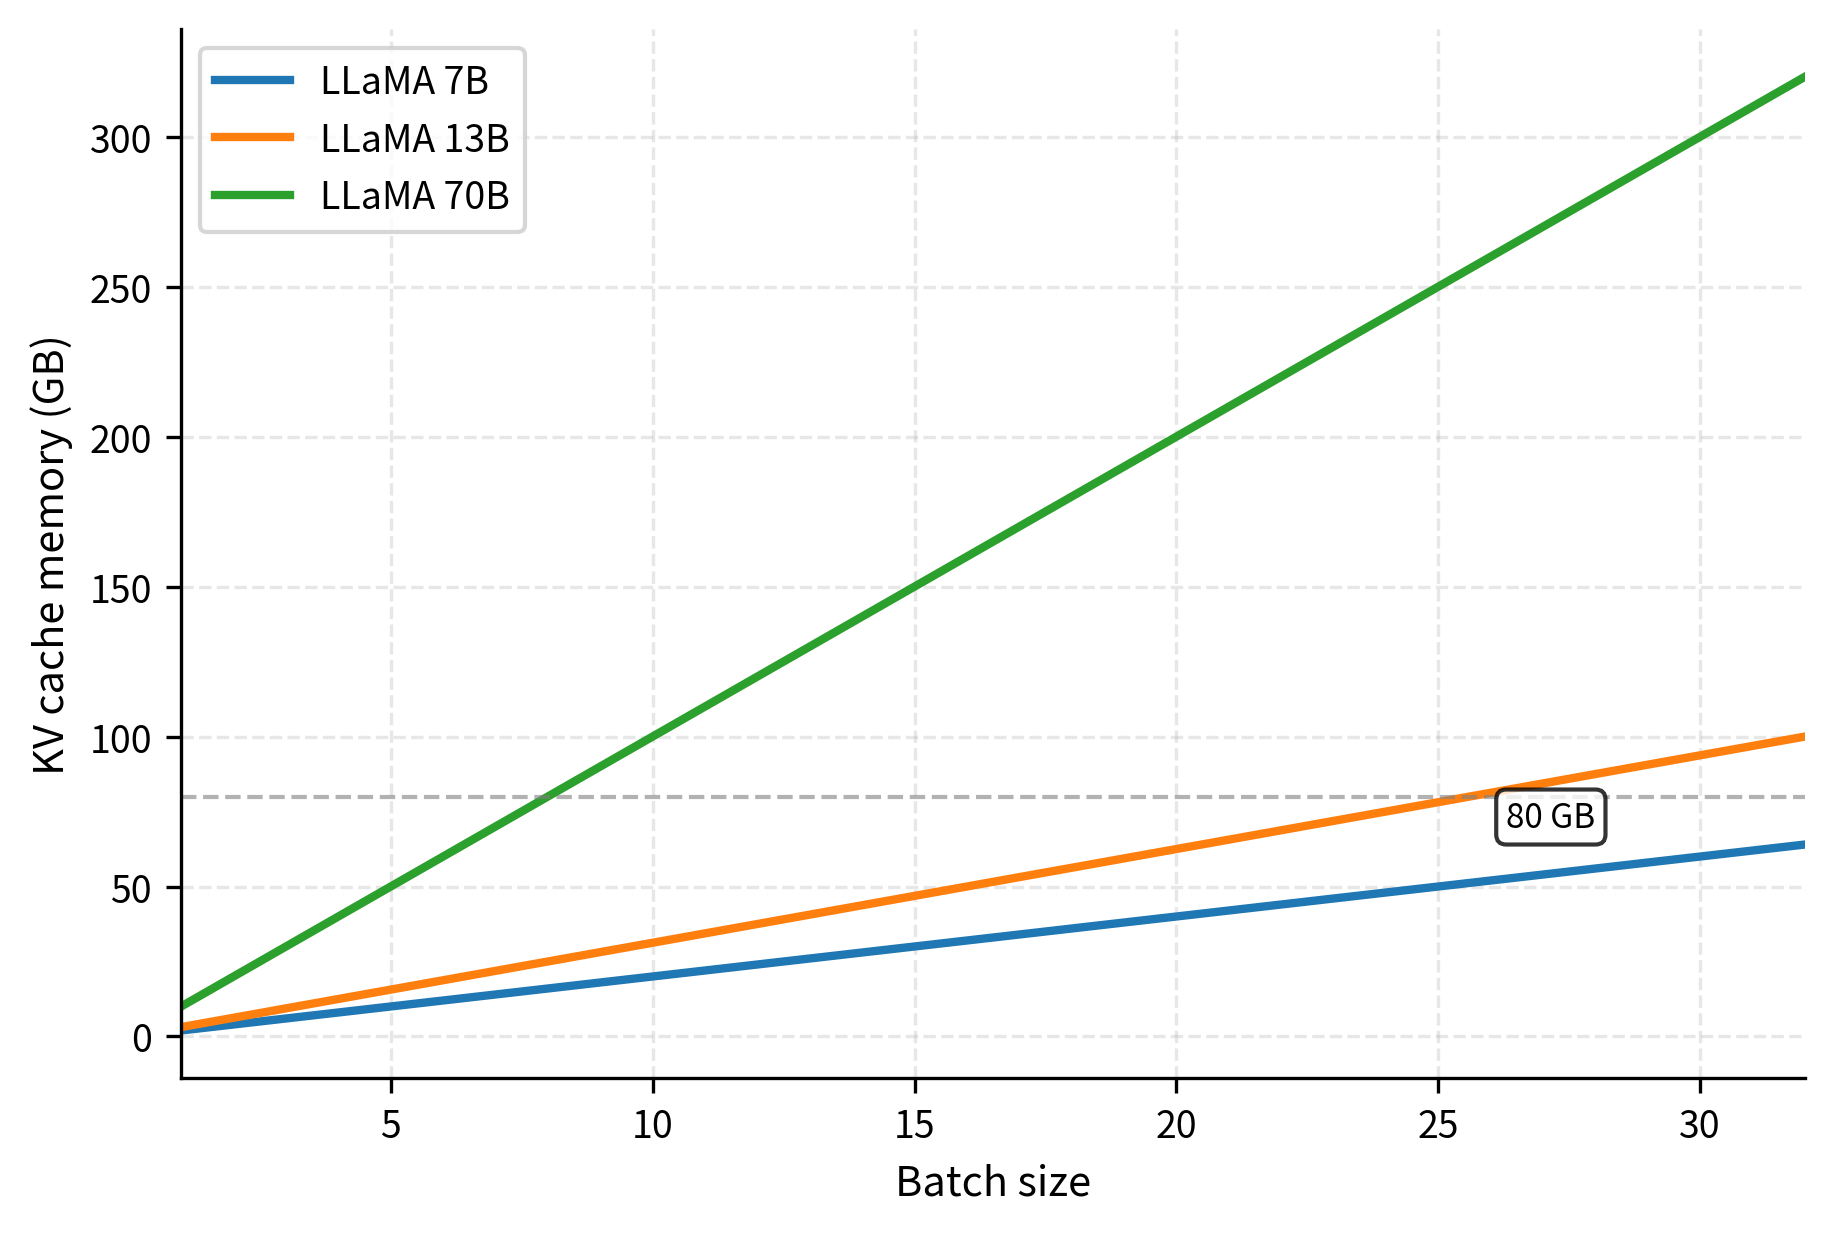
KV Cache Explained: Efficient Attention for LLM Generation ...
KV Cache Explained for LLM Inference
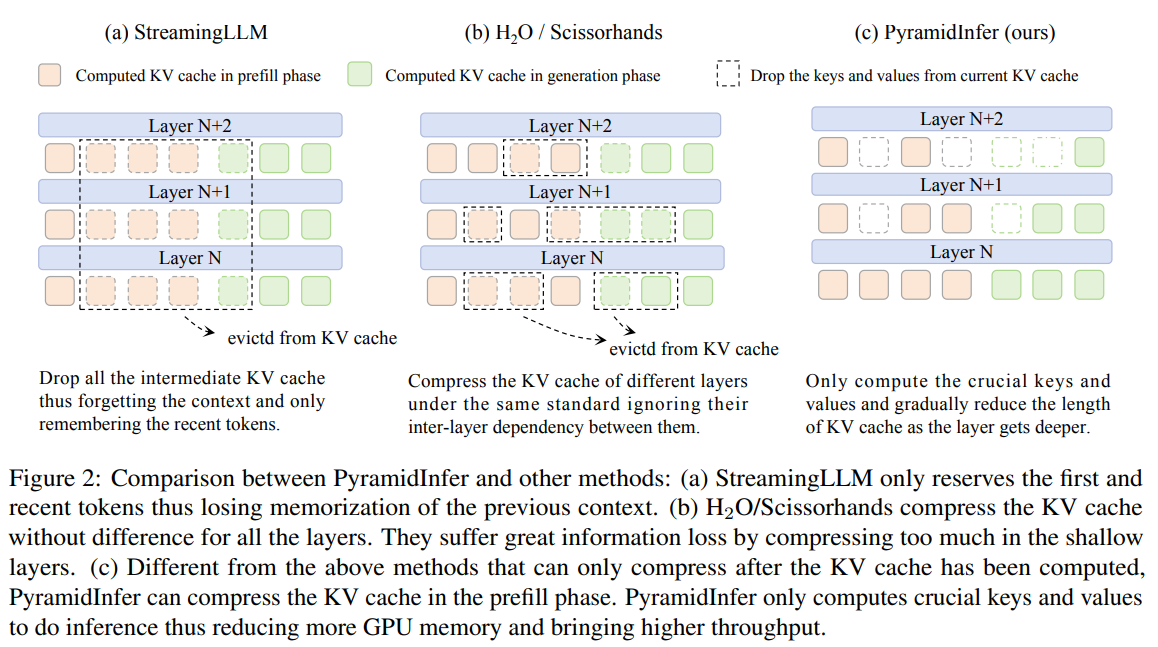
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...

[论文评述] Accelerating LLM Inference Throughput via Asynchronous KV Cache ...

Caching Strategies for LLM Systems (Part 2): KV Cache and the ...
Advertisement Space (336x280)
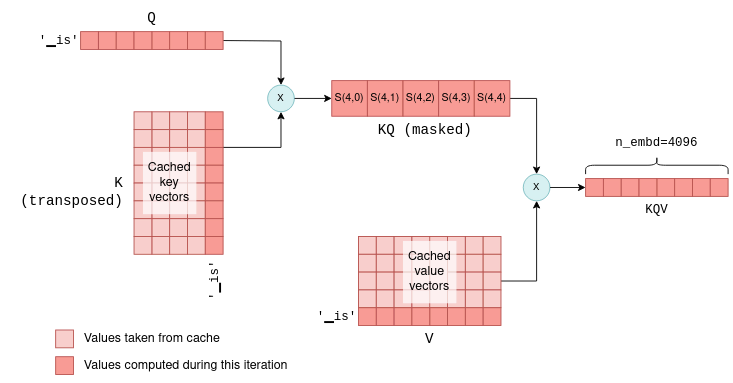
LLM 和 KV cache 详解 | Jasmine
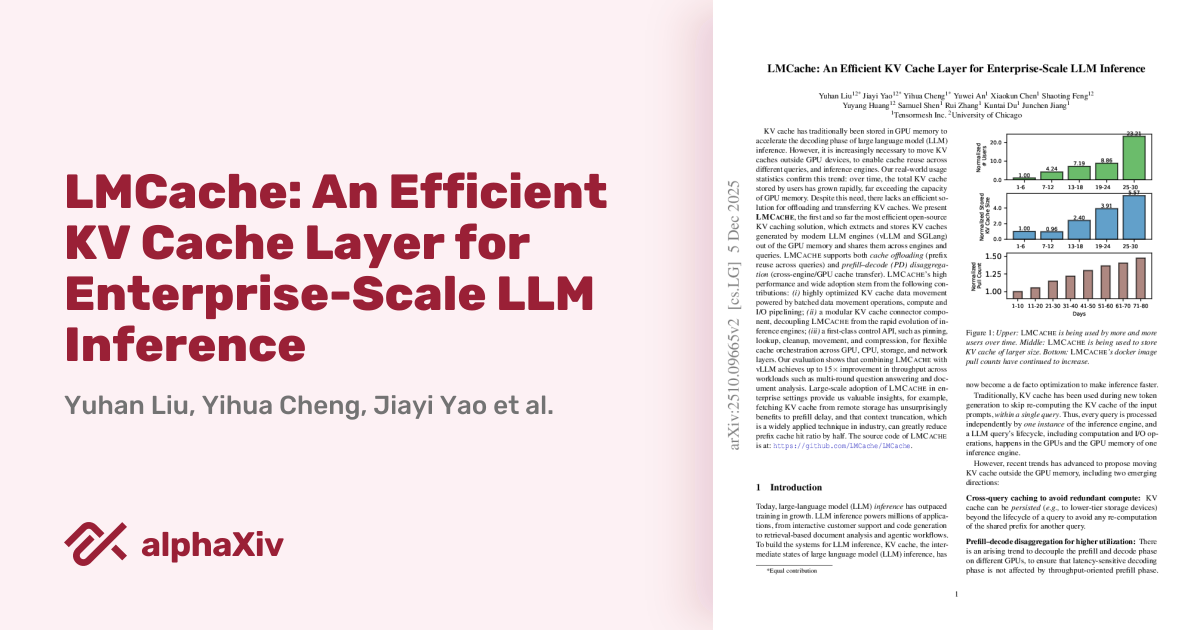
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

KV Cache and Prompt Caching: How to Leverage them to Cut Time and Costs ...
KV Cache Explained — Why LLM Inference Is Fast

Understanding and Coding the KV Cache in LLMs from Scratch
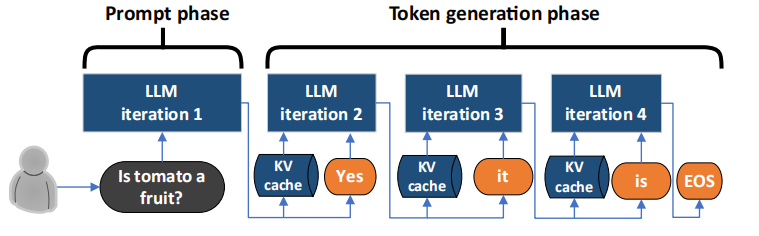
并行 & 框架 & 优化(五)——Context Parallel, LoRA, FSDP, Megatron-LM, KV Cache