
Mxfp4 Quantization On Gpu Cloud Deploy Llms At 4 Bit Precision 2026
MXFP4 Quantization on GPU Cloud: Deploy LLMs at 4-Bit Precision (2026 ...
GGUF Dynamic Quantization on GPU Cloud: Deploy LLMs 50% Cheaper with ...
MXFP6 and MXFP4 Mixed Precision for Accelerating Dense LLMs on AMD ...

Run 70B LLMs on Consumer GPU - VRAM and Quantization Guide (2026)
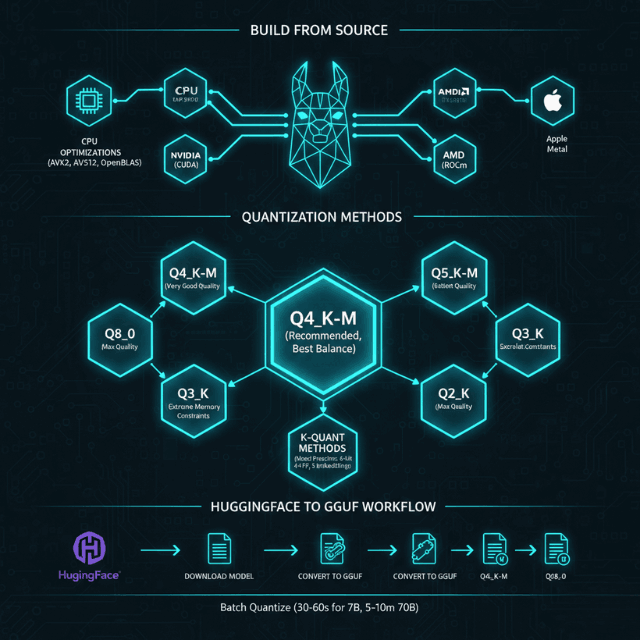
Run 70B LLMs on Consumer GPU - VRAM and Quantization Guide (2026)

Running Qwen3.5 with MXFP4 Quantization on RTX 5090: Performance ...
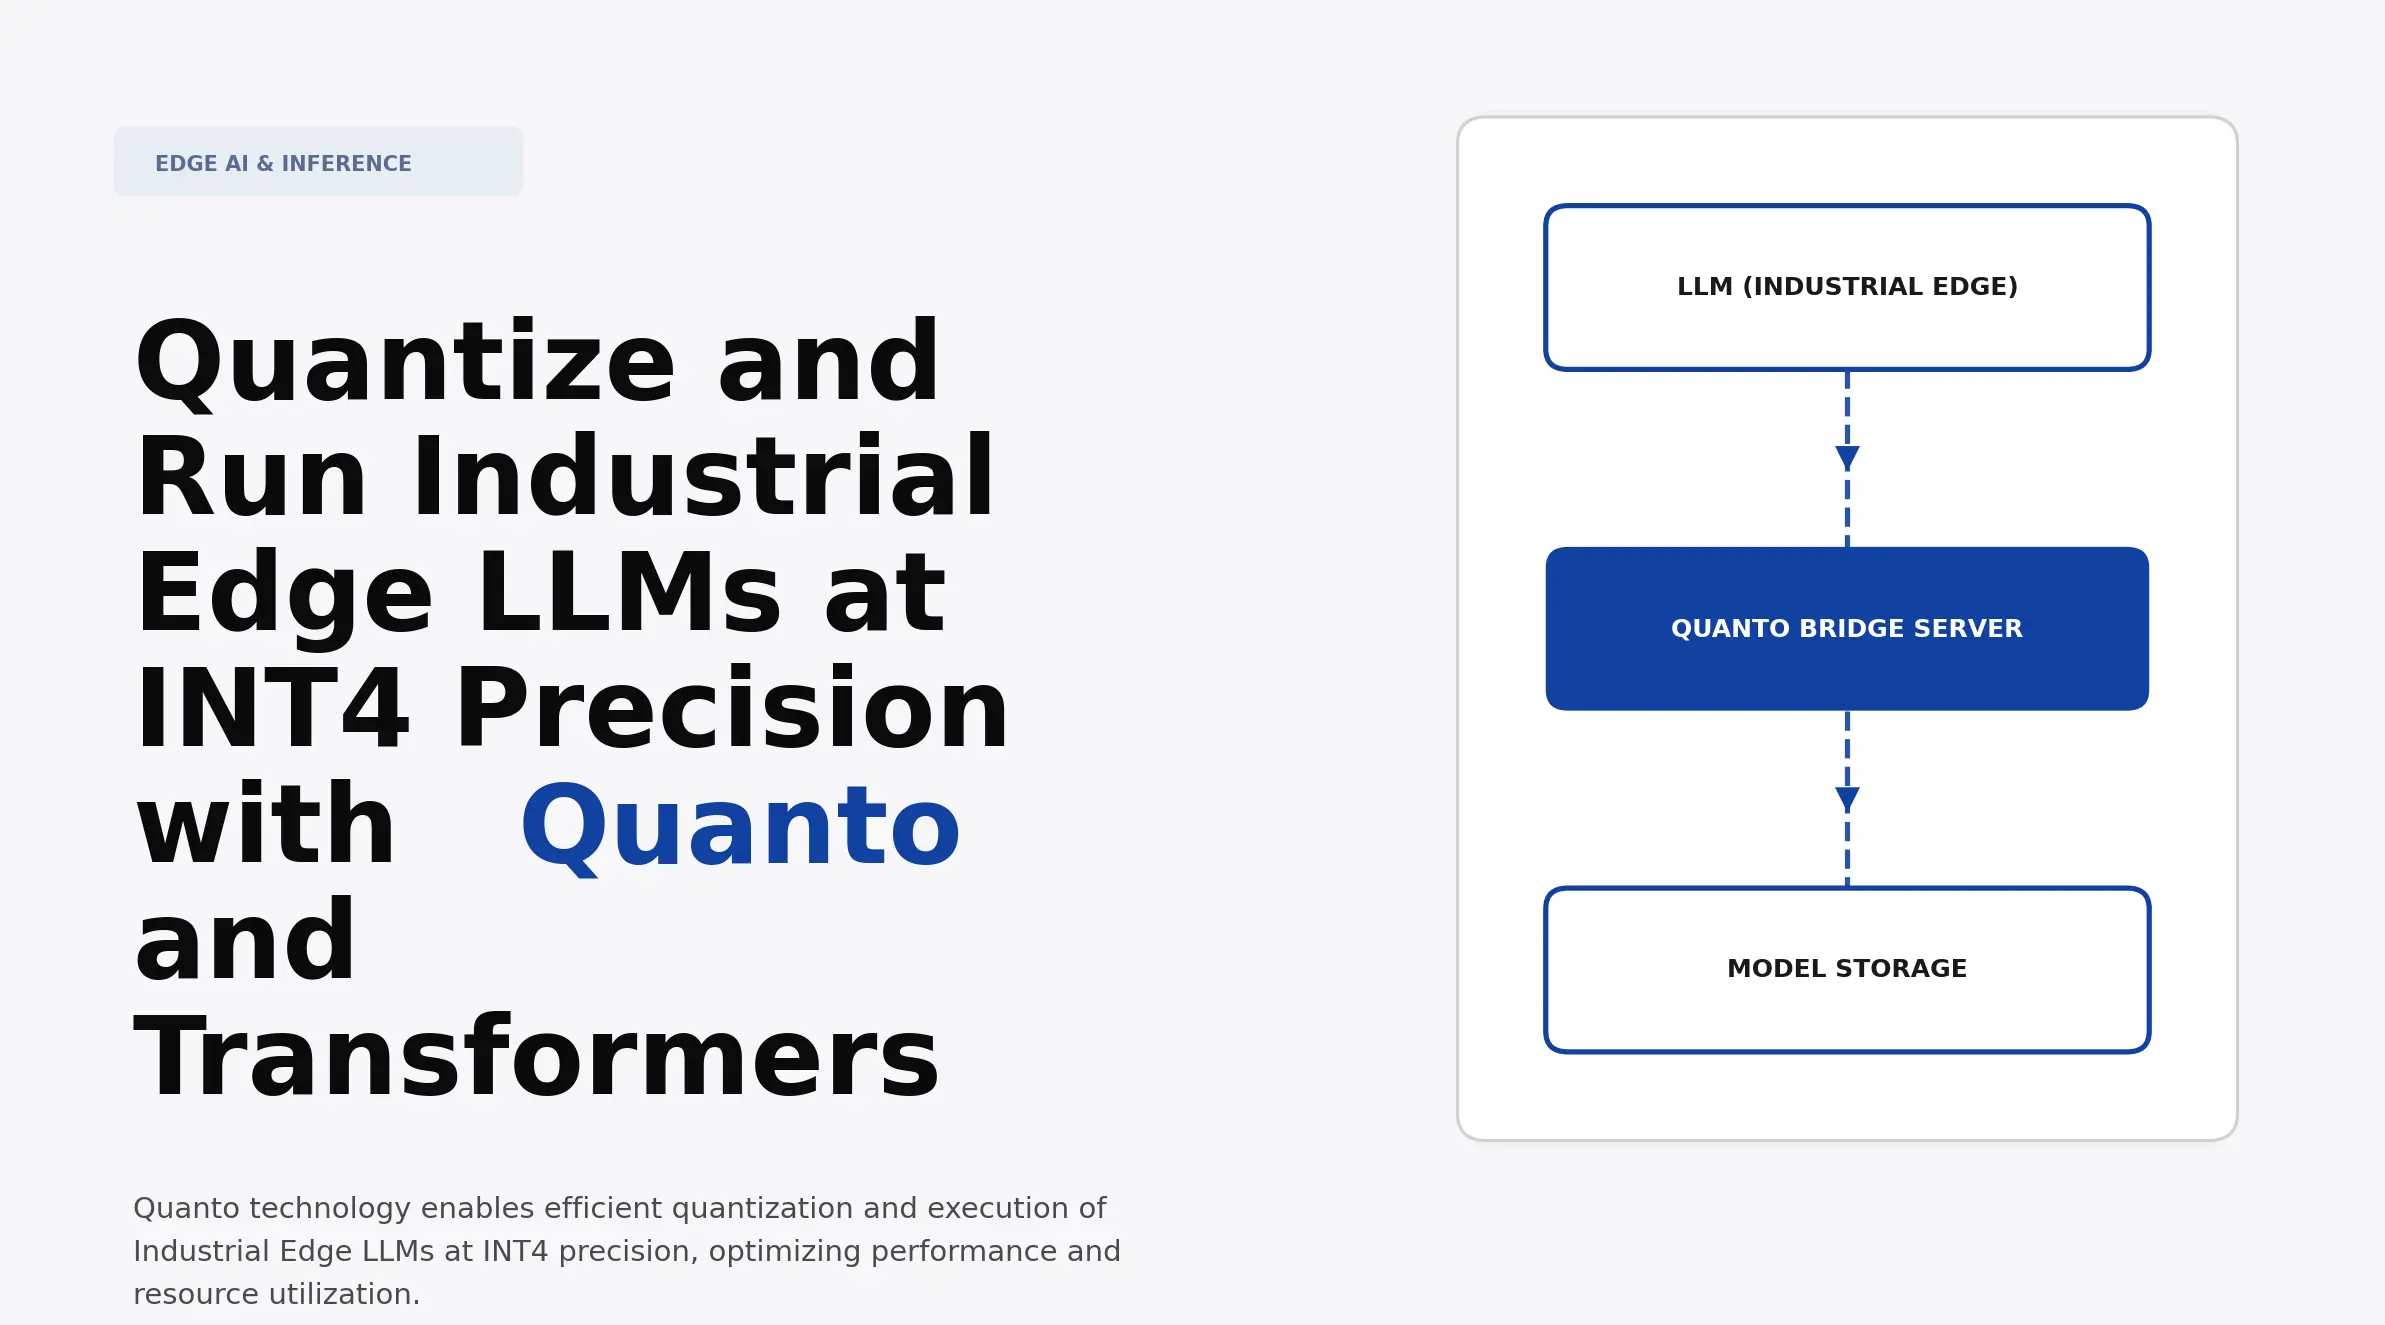
Quantize and Run Industrial Edge LLMs at INT4 Precision with Quanto and ...

Run Big LLMs on Small GPUs: A Hands-On Guide to 4-bit Quantization and ...

How I run 122B-parameter LLMs on a MacBook — outperforming MXFP4 and ...

W4A4 Quantization for Inference on Wan2.2-I2V-A14B ICME 2026 Low-Bit ...
Advertisement Space (300x250)

Training LLMs with MXFP4 | alphaXiv
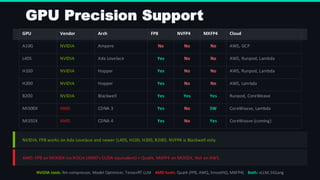
Advanced Quantization Techniques for Large Language Models in 2026 | PDF

openai/gpt-oss-20b · NVIDIA L40S GPU's for MXFP4 quantization

MXFP4 Quantization - LLM Compressor Docs

[论文评述] Block Rotation is All You Need for MXFP4 Quantization

Paper page - Training LLMs with MXFP4

unsloth/gpt-oss-20b-bnb-4bit · How does 4bit bnb quantization work on ...
FP4 and MXFP4 Quantization | sgl-project/sglang | DeepWiki
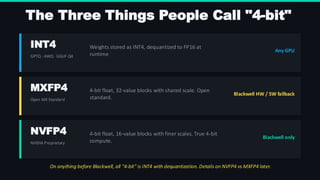
Advanced Quantization Techniques for Large Language Models in 2026 | PDF

TORQ: Two-Level Orthogonal Rotation for MXFP4 Quantization
Advertisement Space (336x280)

Quantization Bits at Amanda Okane blog

LLMs Can Now Retain High Accuracy at 2-Bit Precision: Researchers from ...

BATQuant: Outlier-resilient MXFP4 Quantization via Learnable Block-wise ...
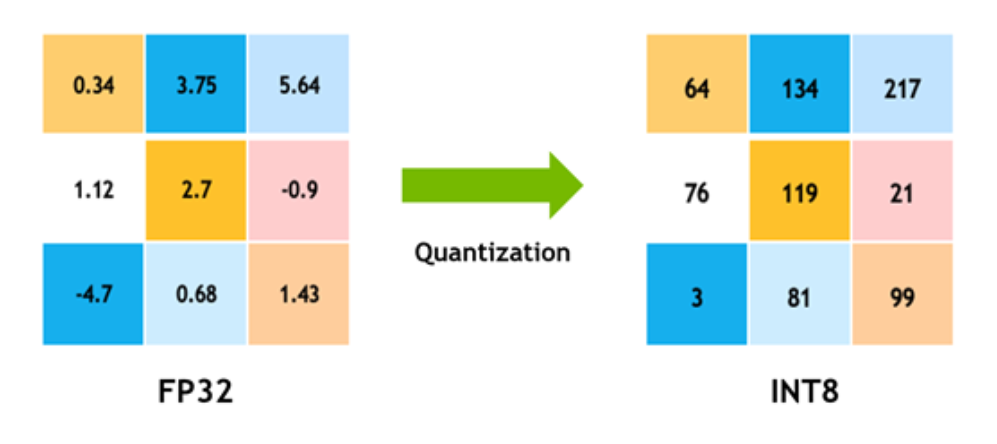
Unlocking LLM Performance: Advanced Quantization Techniques on Dell ...

BATQuant: Outlier-resilient MXFP4 Quantization via Learnable Block-wise ...

DeepLearning.AI | Researchers showed that LLMs can be trained using 4 ...

Decomposing MXFP4 quantization error for LLM reinforcement learning ...
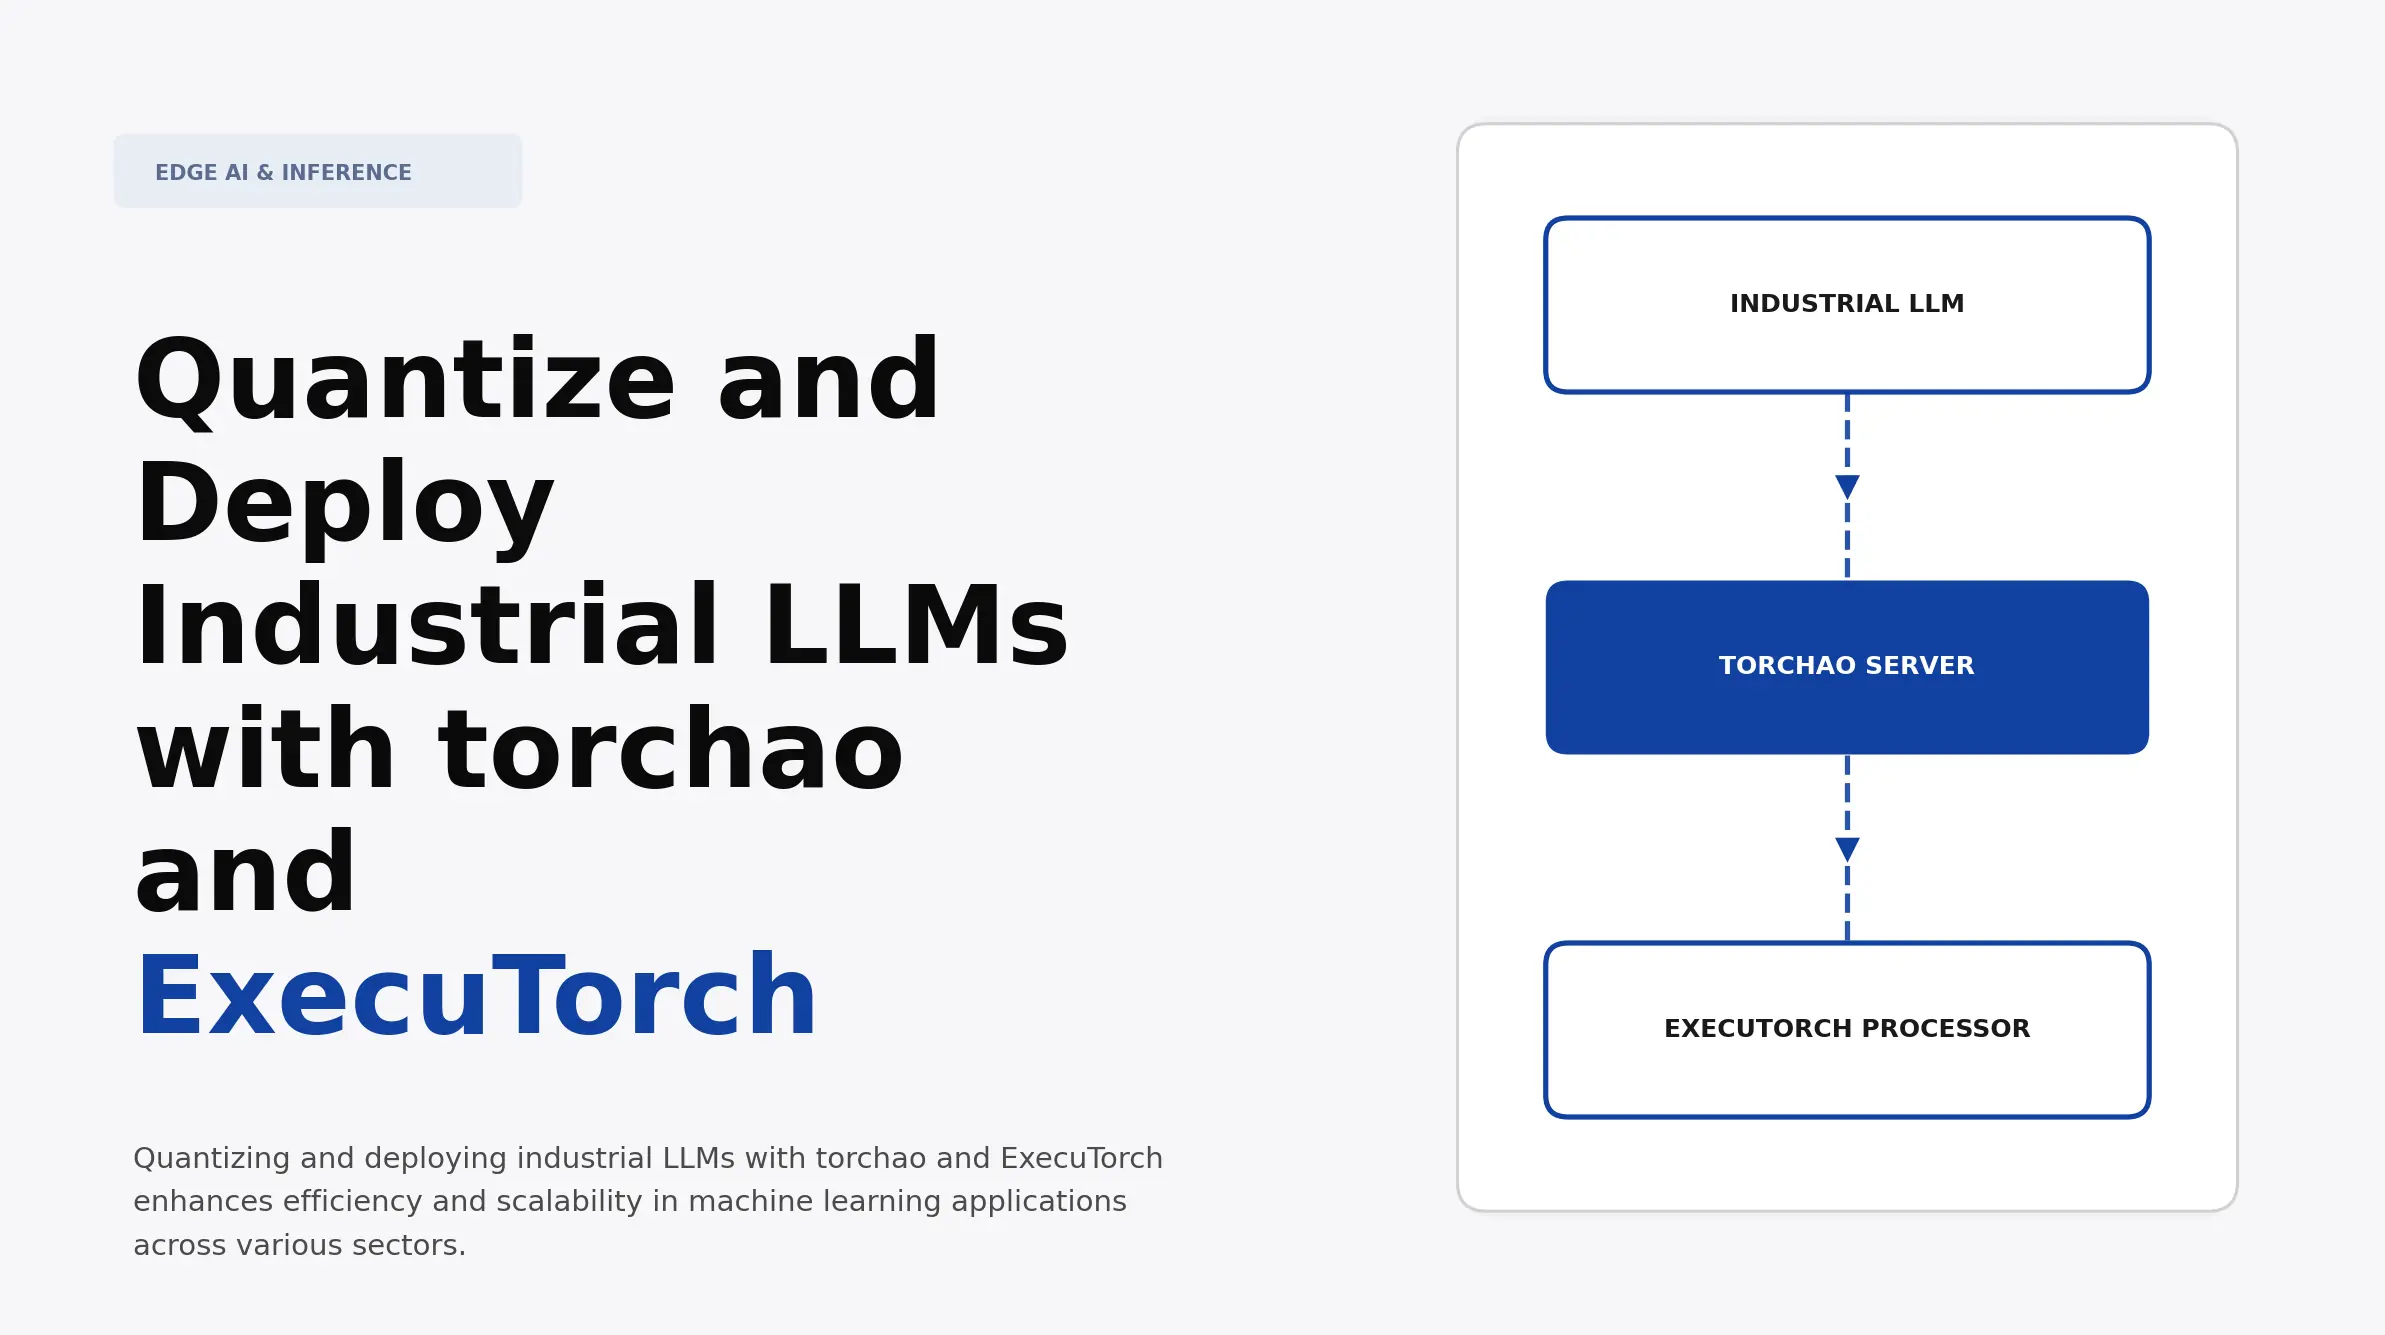
Quantize and Deploy Industrial LLMs with torchao and ExecuTorch ...

The MXFP4 Revolution: Your Ultimate Guide to 4-Bit AI Quantization
[Bug]: Unknown quantization method: mxfp4 · Issue #22276 · vllm-project ...
Advertisement Space (336x280)
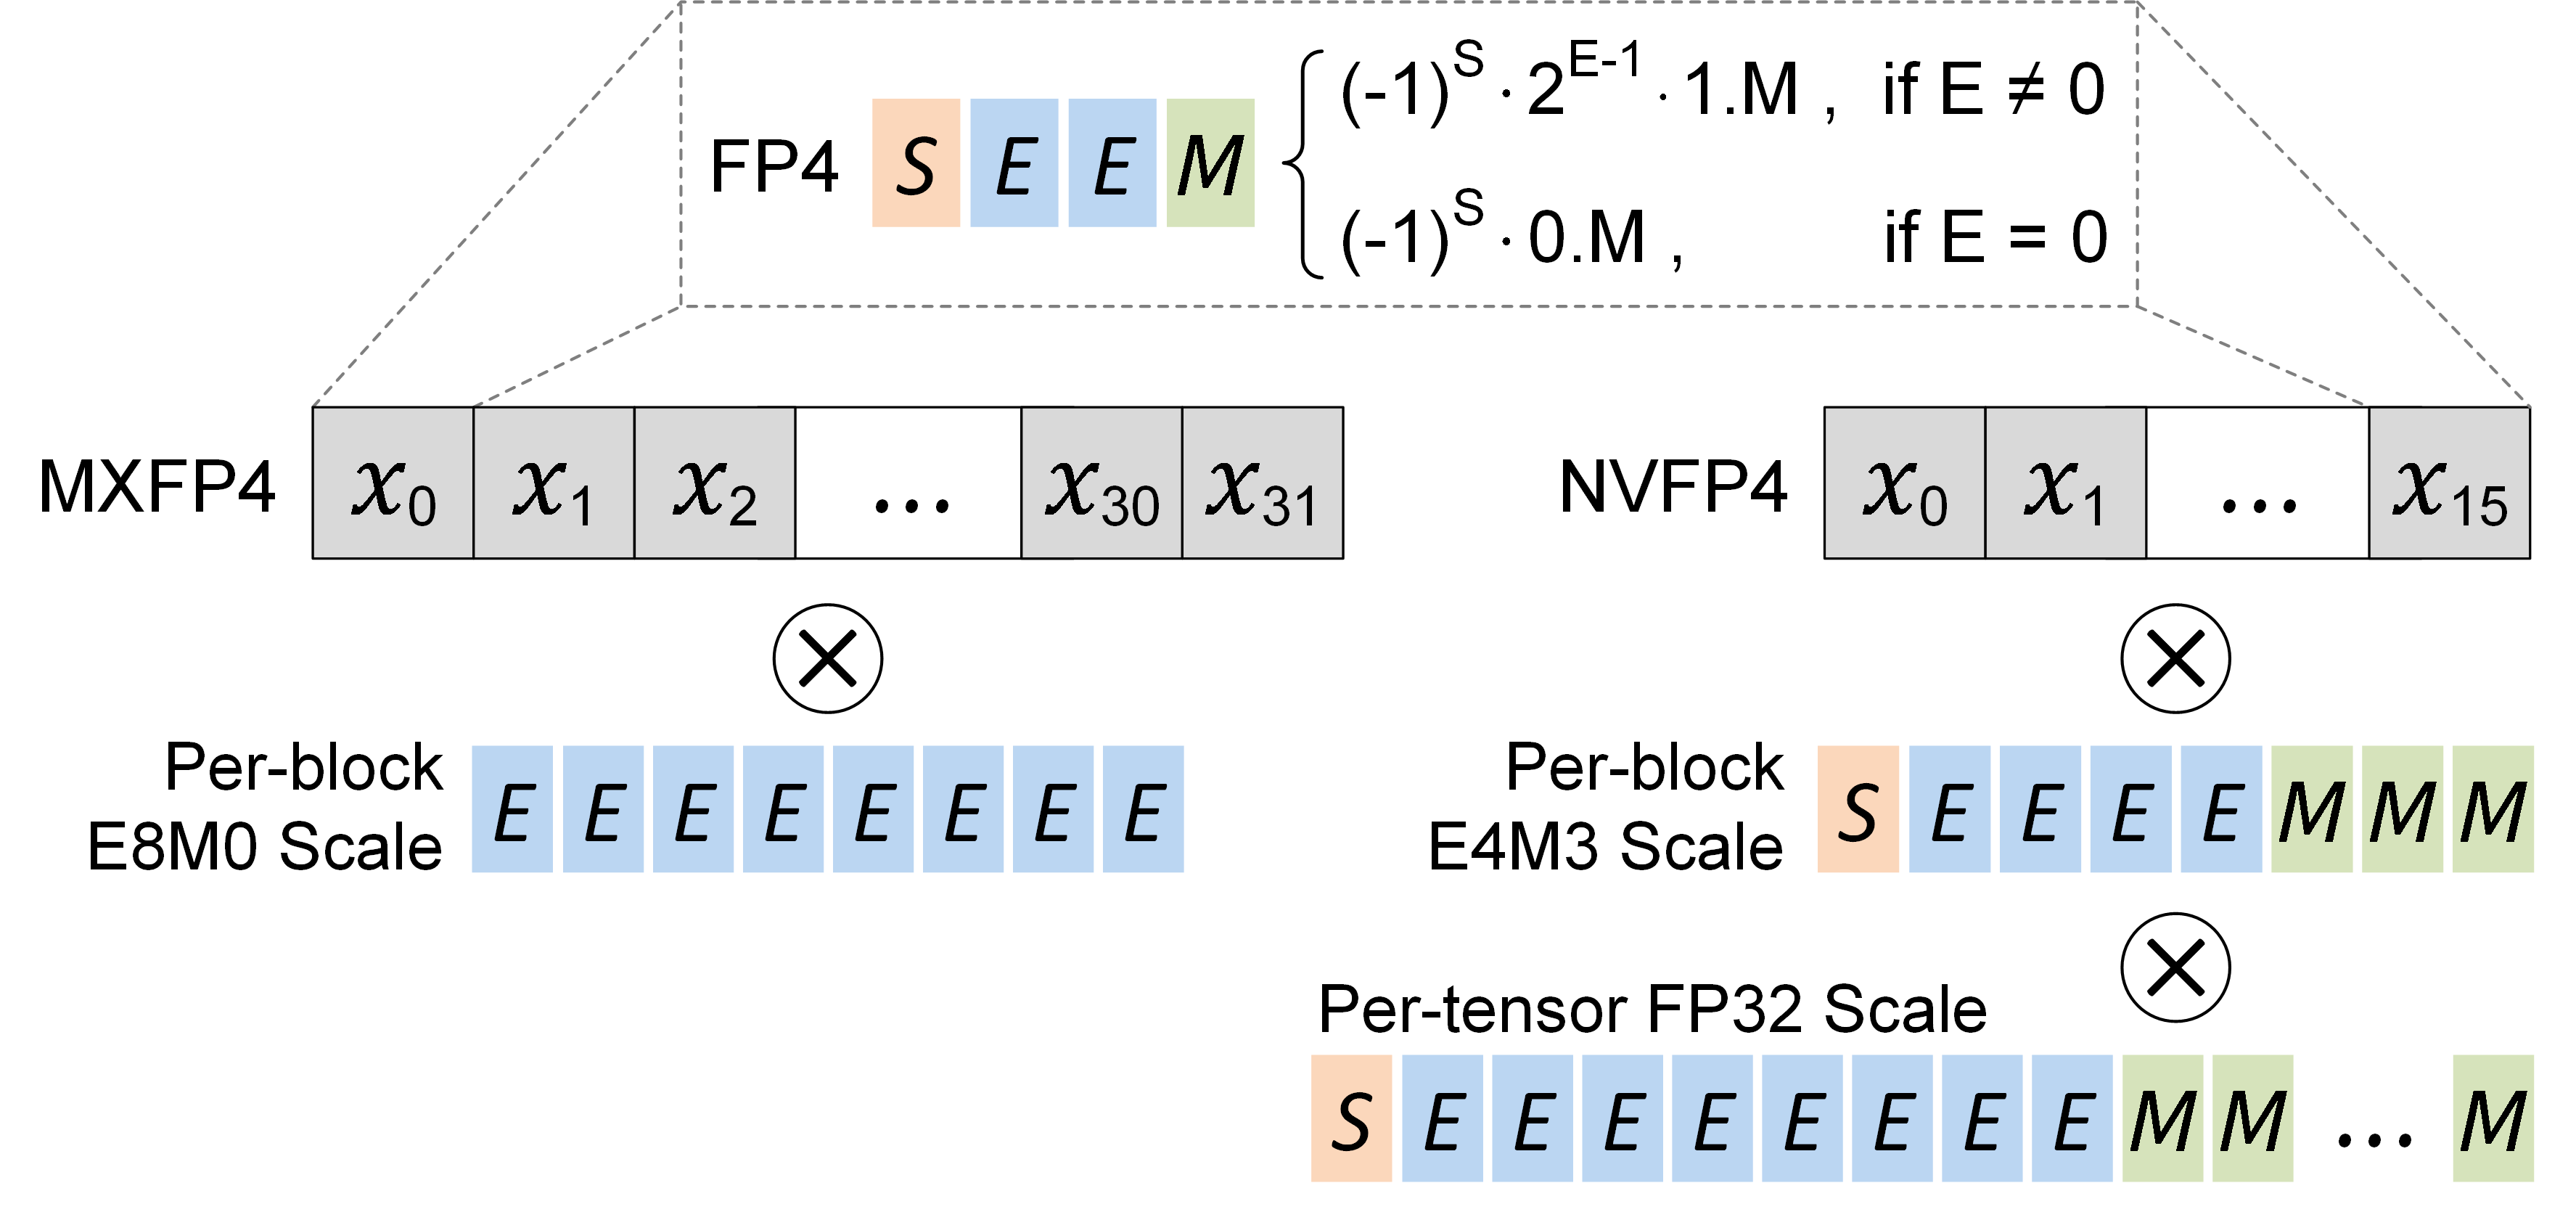
Extending MXFP4 and NVFP4 with Redundant Zero Remapping (RaZeR) for ...

Microscaling FP4 Quantization
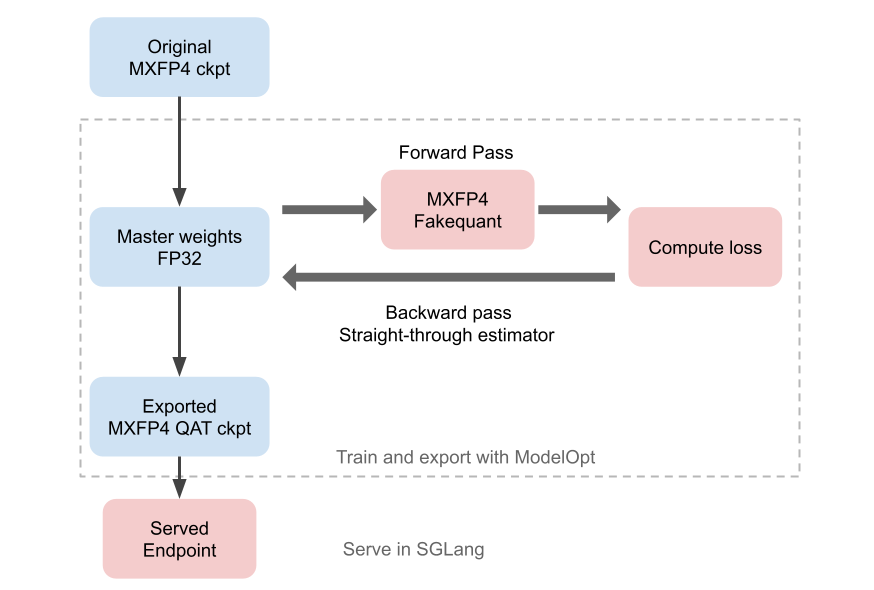
Fine-tune and deploy gpt-oss MXFP4: ModelOpt + SGLang - LMSYS Blog ...

Block Rotation Achieves Accurate W4A4 Quantization
LLM Compressor 0.9.0: Attention quantization, MXFP4 support, and more ...
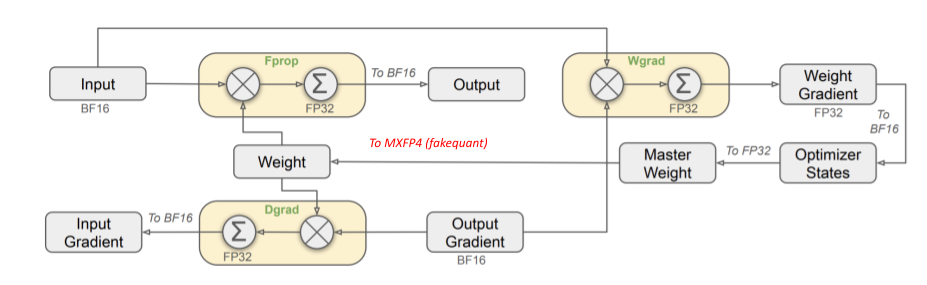
A Dive into LLM Quantization – Huizi Mao