
Gguf Dynamic Quantization On Gpu Cloud Deploy Llms 50 Cheaper With
GGUF Dynamic Quantization on GPU Cloud: Deploy LLMs 50% Cheaper with ...
How to Run Quantized GGUF LLMs Locally on GPU with llama.cpp (No Cloud ...

How to Run Quantized GGUF LLMs Locally on GPU with llama.cpp (No Cloud ...

Run GGUF Quantized 7B LLMs with no GPU on your laptop | Virendra Singh
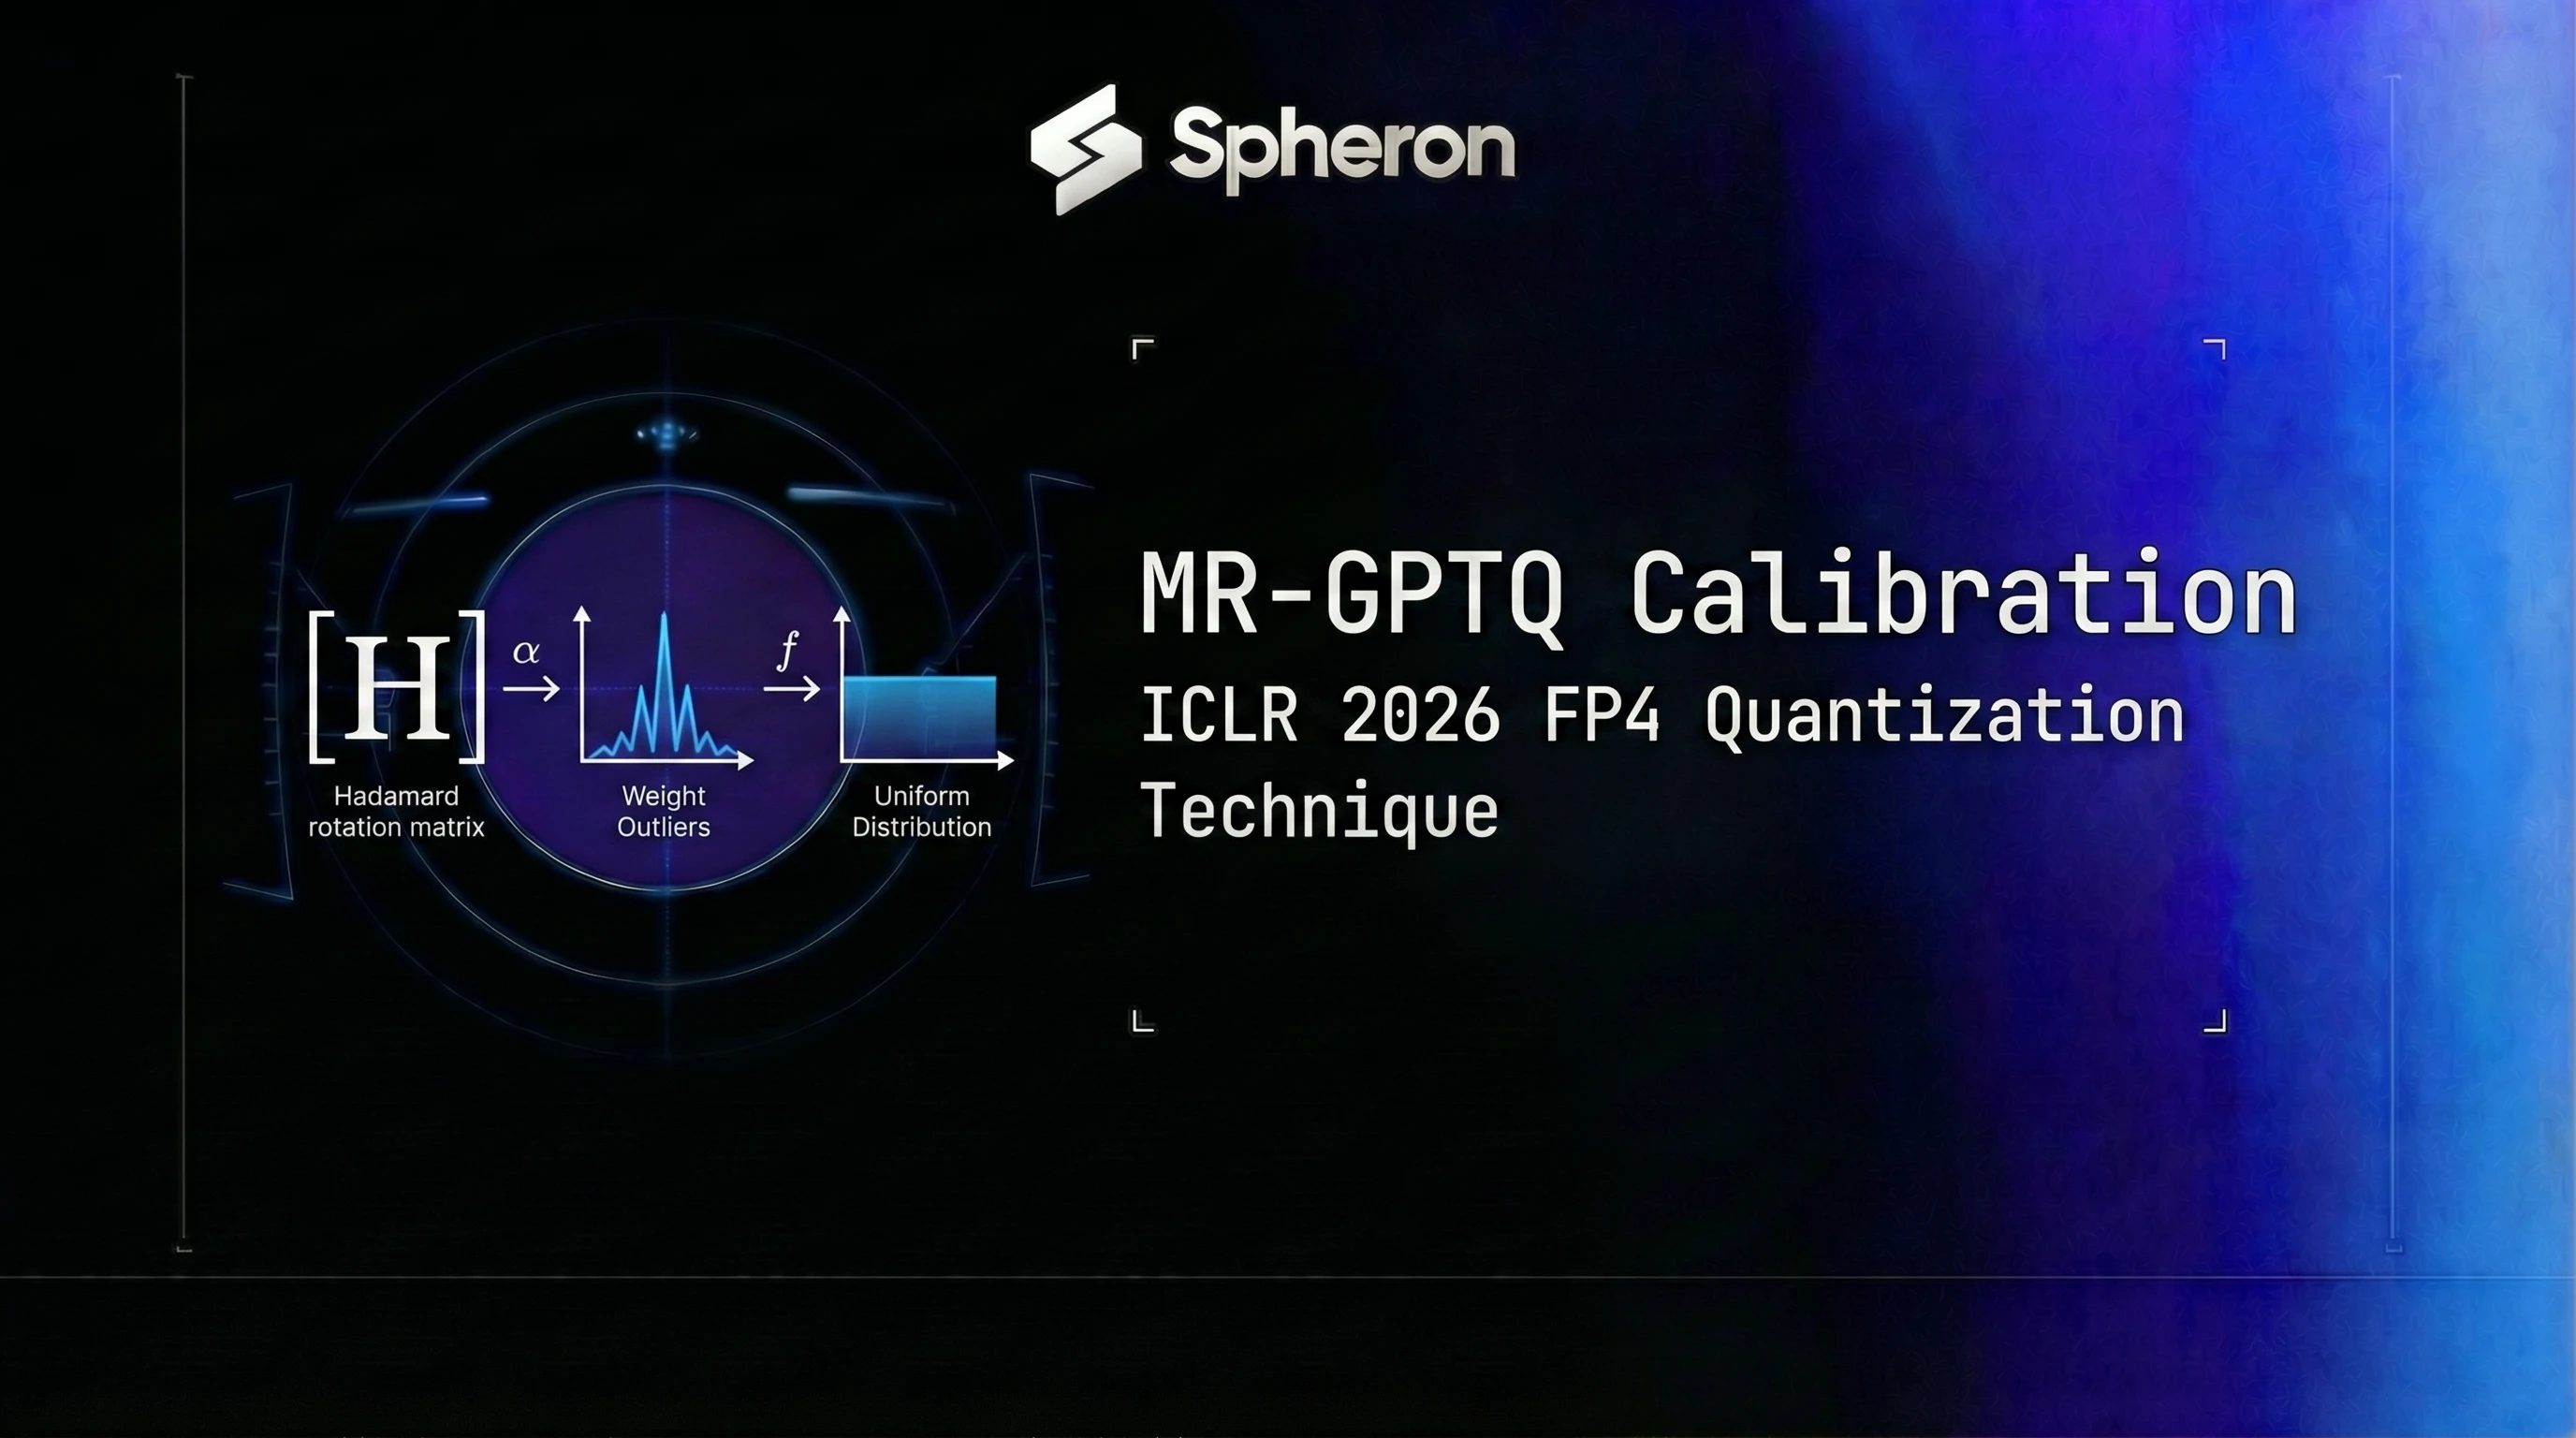
MXFP4 Quantization on GPU Cloud: Deploy LLMs at 4-Bit Precision (2026 ...

GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU

GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU
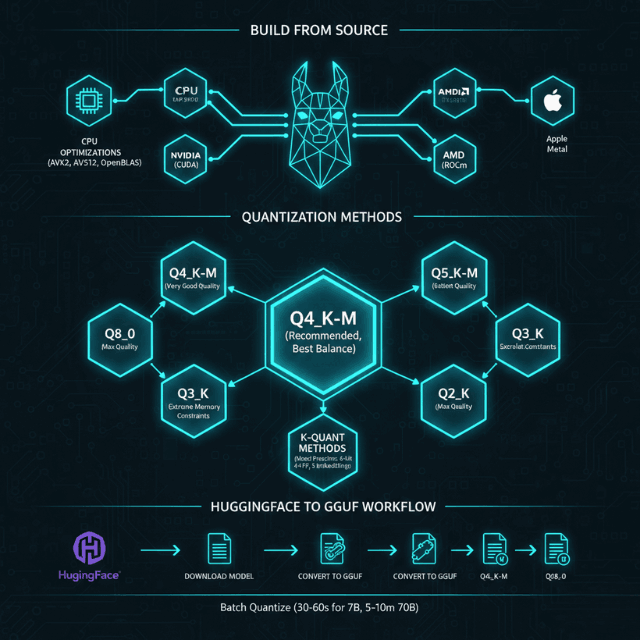
Run 70B LLMs on Consumer GPU - VRAM and Quantization Guide (2026)

LLMs on CPU: The Power of Quantization with GGUF, AWQ, & GPTQ
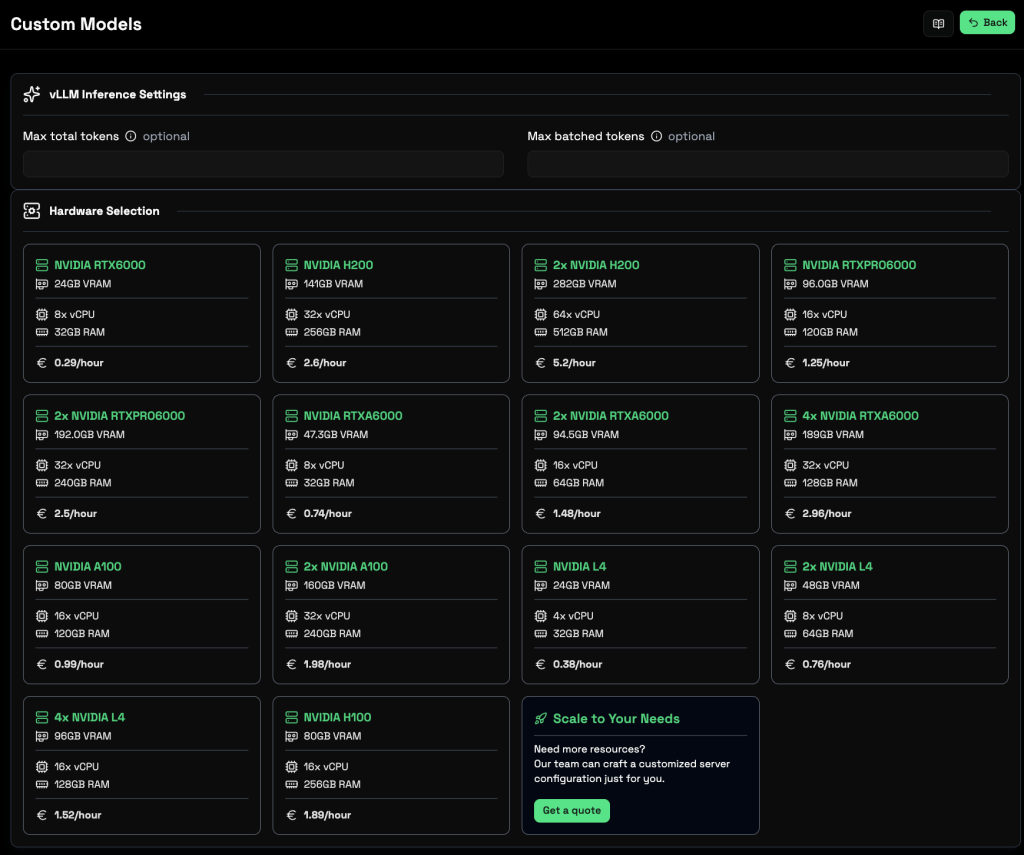
AutoRound Quantization Guide: Local GPU to Production GGUF on Hugging Face
Advertisement Space (300x250)

GGUF quantization of LLMs with llama cpp - YouTube

How to boost LLM quantization with GGUF | MarTechRichard posted on the ...

LLMs on CPU: The Power of Quantization with GGUF, AWQ, & GPTQ

AutoRound Quantization Guide: Local GPU to Production GGUF on Hugging Face

LLMs on CPU: The Power of Quantization with GGUF, AWQ, & GPTQ
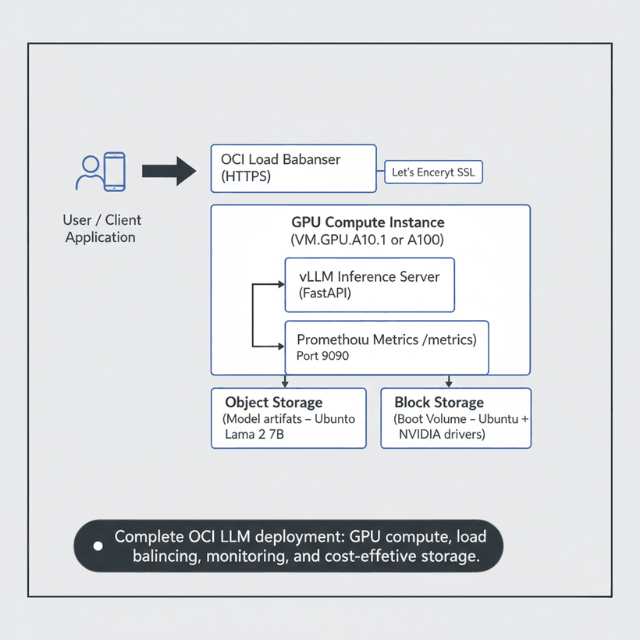
Oracle Cloud Free Tier for LLMs - Always-Free GPU Guide (2026)

How to Deploy GPU-Powered AI Model LLM on Google Cloud Run - Geeky Gadgets

Rent GPU in GPU Cloud to Boost LLMs 30B Met

Free Video: MLOPS LLMs - Converting Microsoft Phi3 to GGUF Format with ...
Deploy LMDeploy on GPU Cloud: TurboMind Inference for InternLM, Qwen3 ...
Advertisement Space (336x280)

Meet GGUF Loader: Run Local LLMs with Zero Hassle - DEV Community
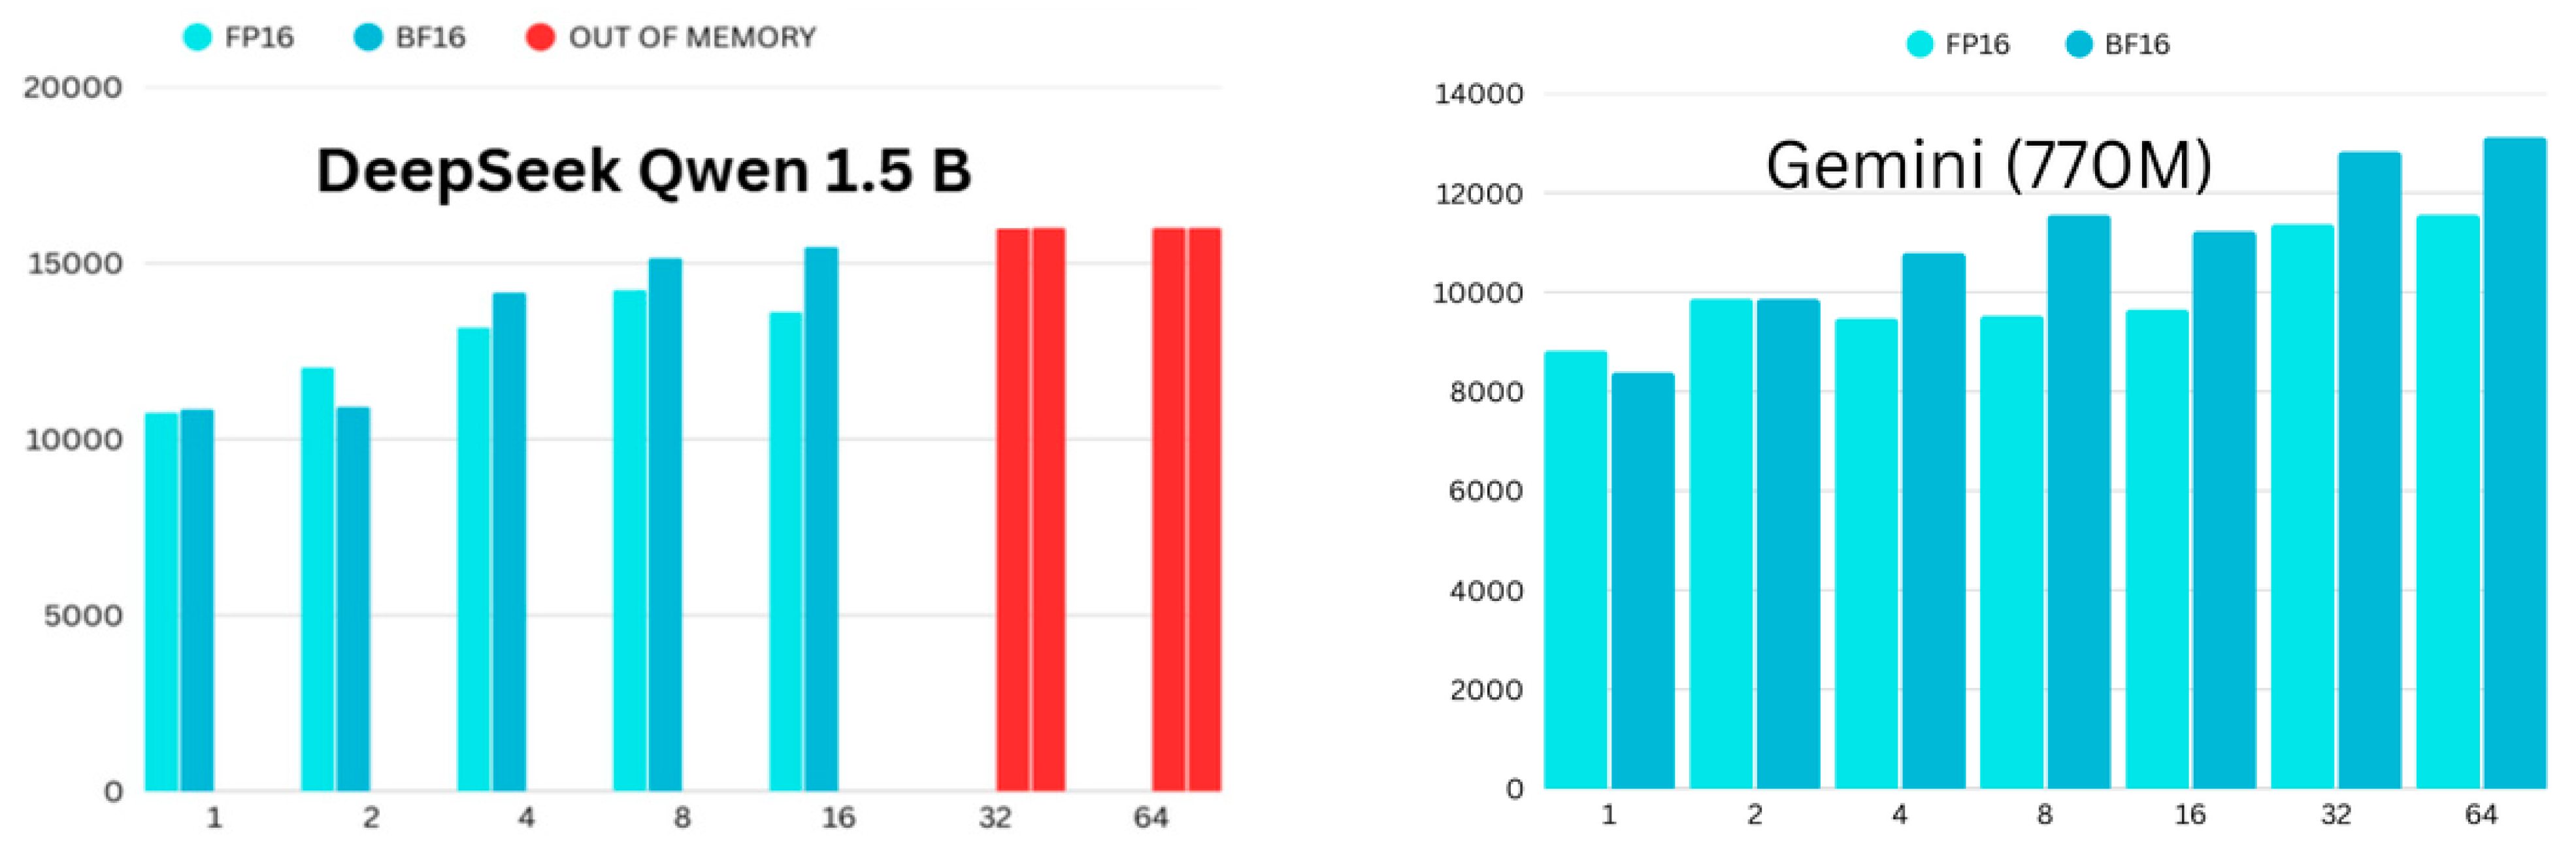
Overview of Training LLMs on One Single GPU
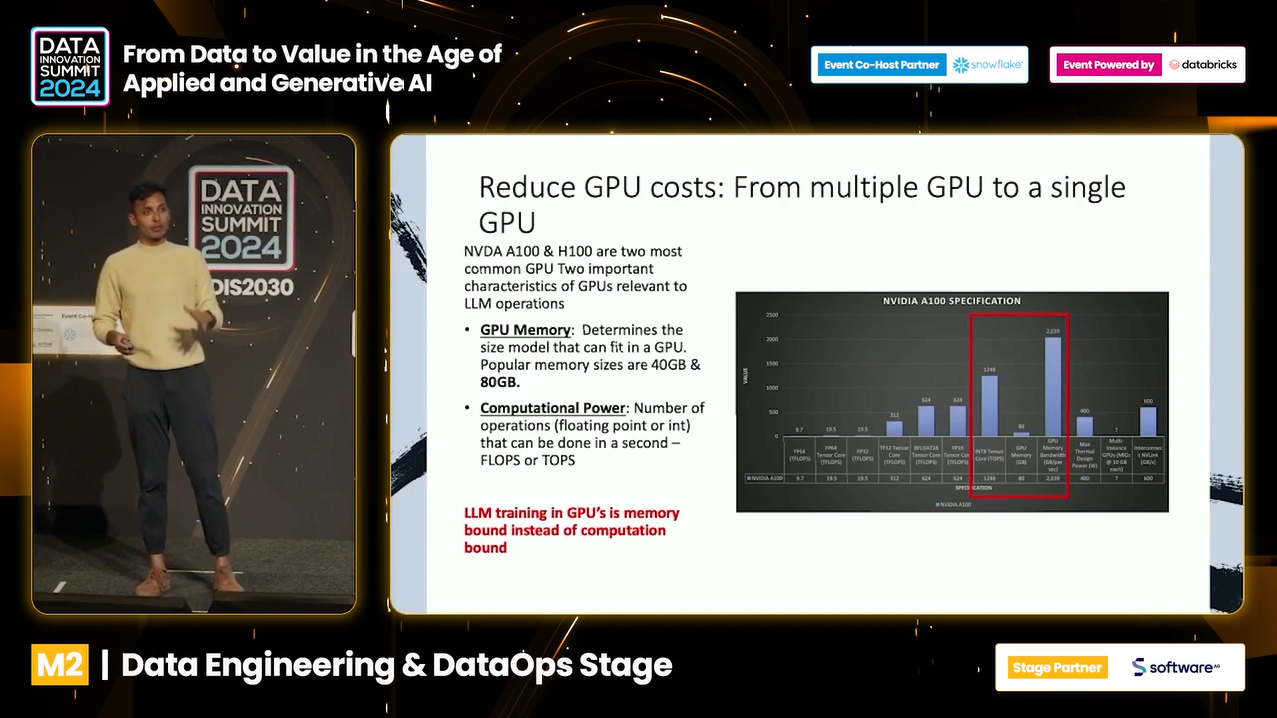
Large Language Models: How to Run LLMs on a Single GPU - Hyperight
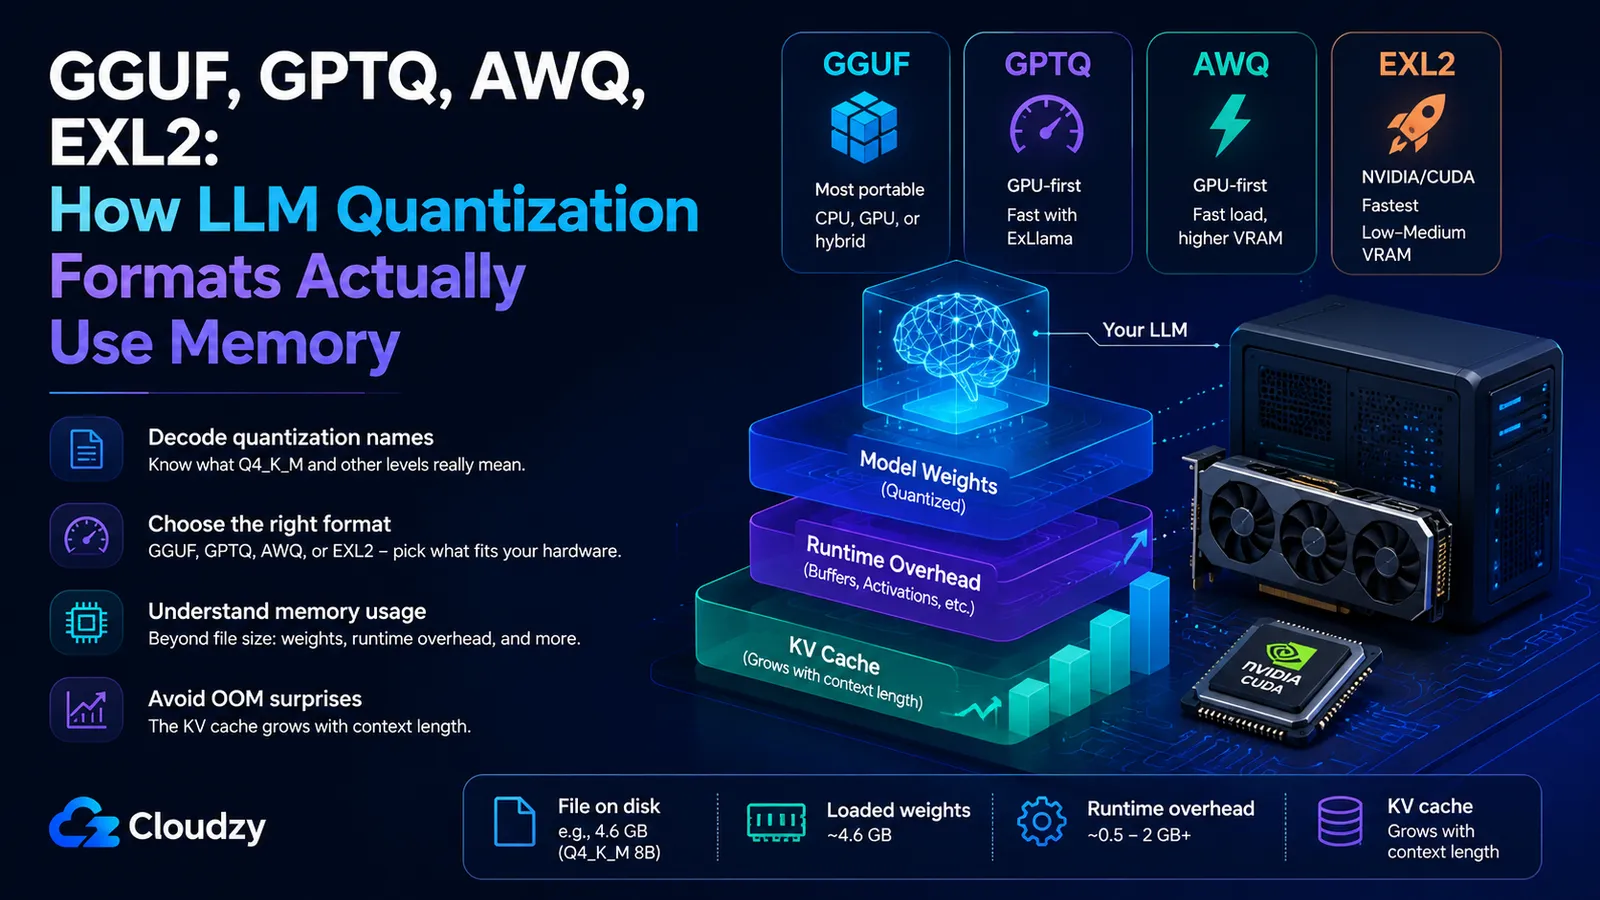
GGUF vs GPTQ vs AWQ vs EXL2: Quantization Formats Explained · Cloudzy Blog

GGUF Quantization: Quality vs Speed on Consumer GPUs · Technical news ...

LLM Quantization Methods: GPTQ, AWQ, GGUF - Cast AI

Doing more with less: LLM quantization (part 2)
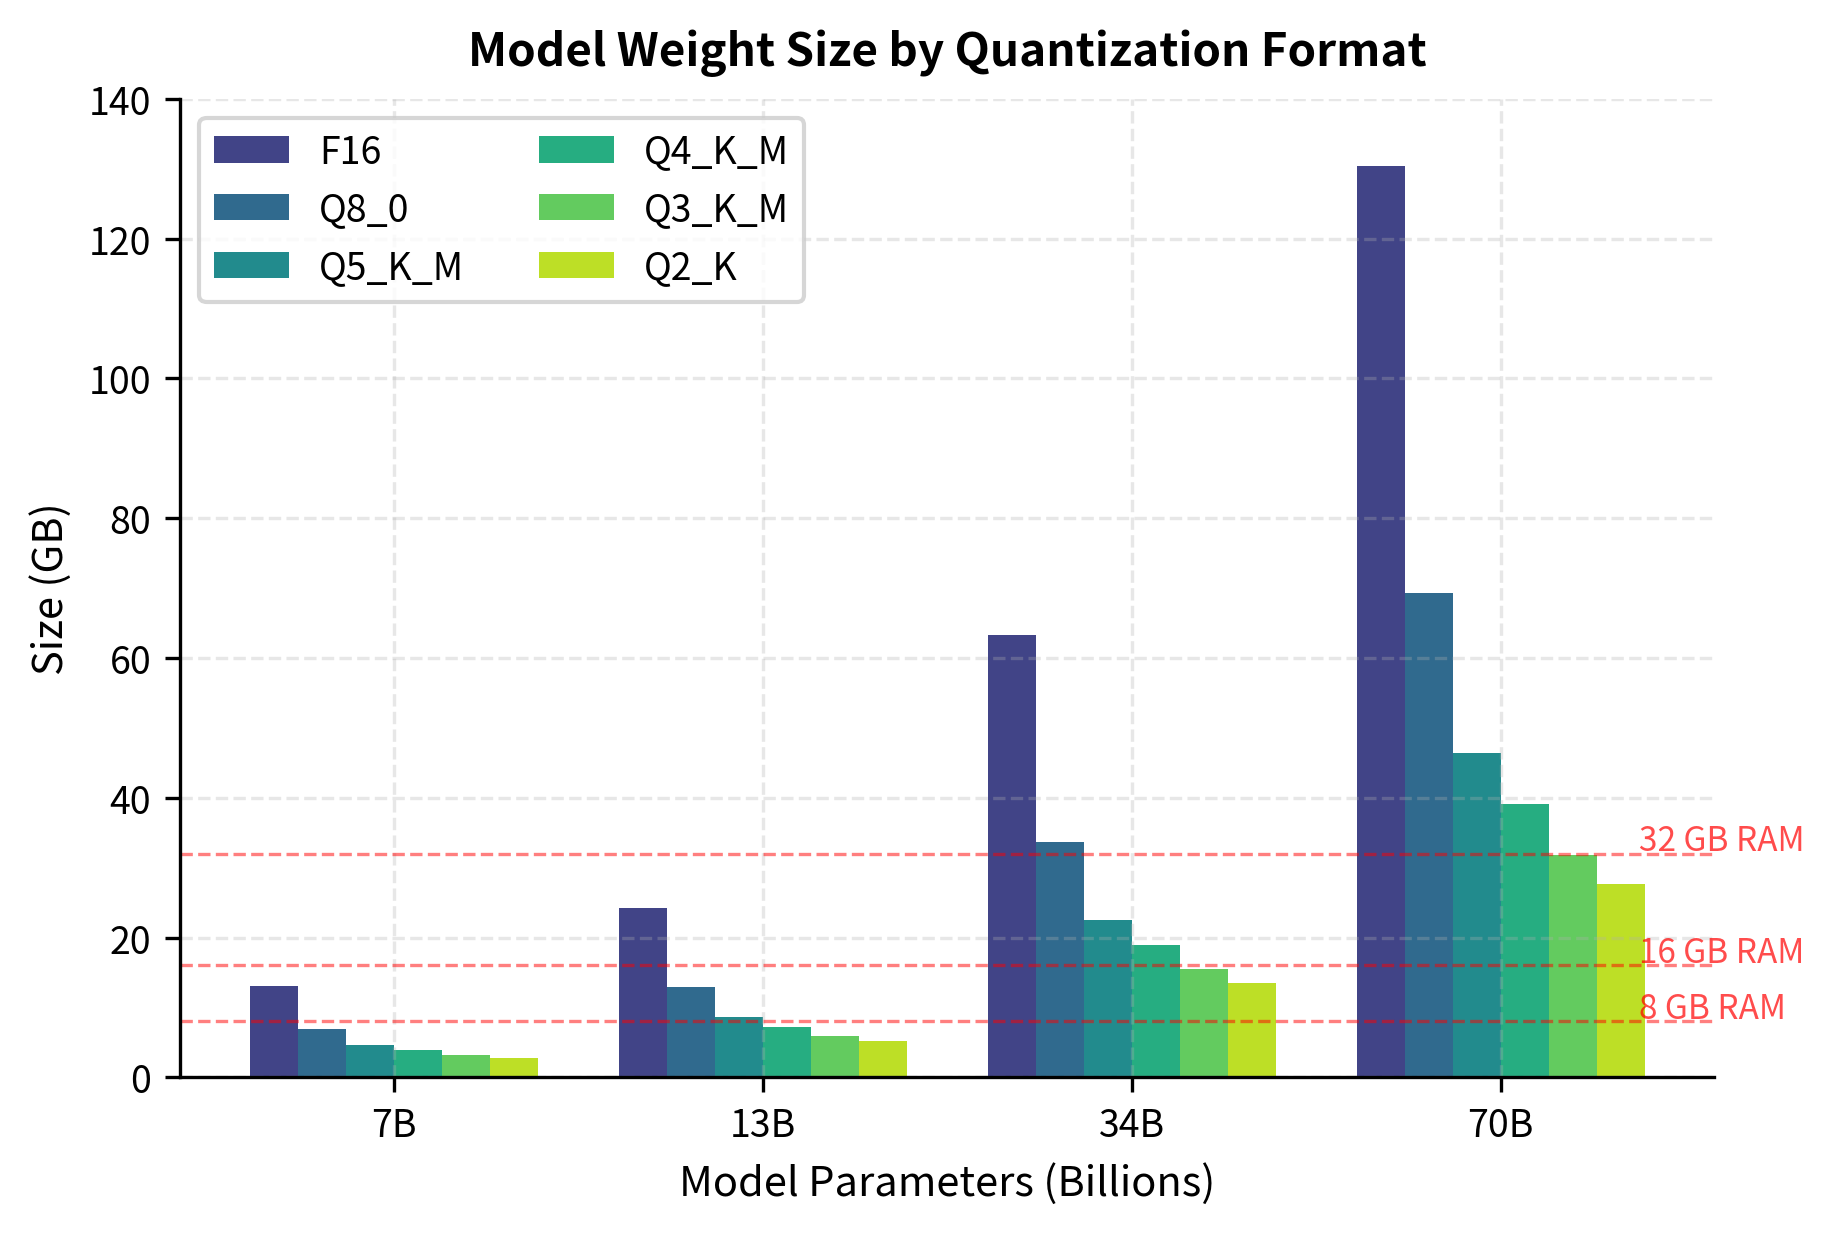
GGUF Format: Efficient Storage & Inference for Quantized LLMs ...

LLM Quantization Methods: GPTQ, AWQ, GGUF - Cast AI
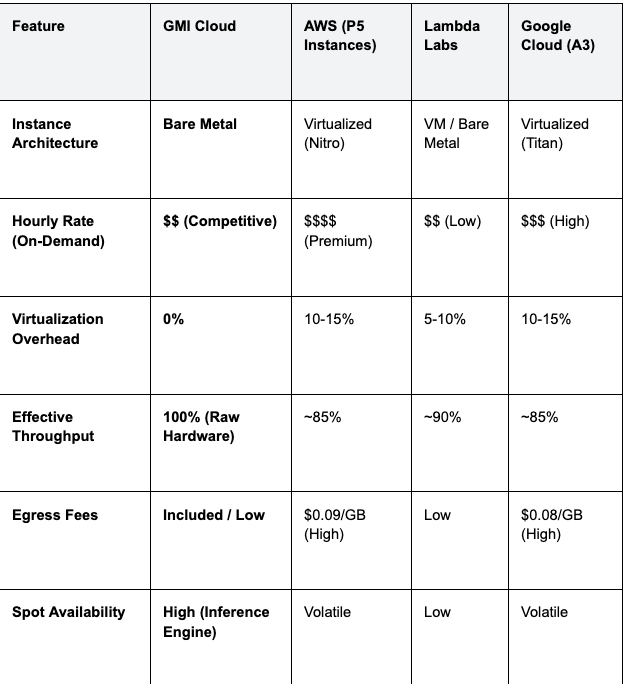
Compare GPU Cloud Pricing for LLM Inference Workloads
Advertisement Space (336x280)

how to quantize an llm with gguf or awq - YouTube
Local LLM vs Cloud GPU Cost: Paperspace, Lambda Labs, AWS Comparison 2026
GGUF LLMs, GGUF Large Language Models Quantization
Q4_K_M vs Q5_K_M vs Q8 — Which GGUF Quantization Should You Use? (2026 ...

LLM Quantization Techniques. GGUF GPTQ AWQ BitNet | by joydeep ...
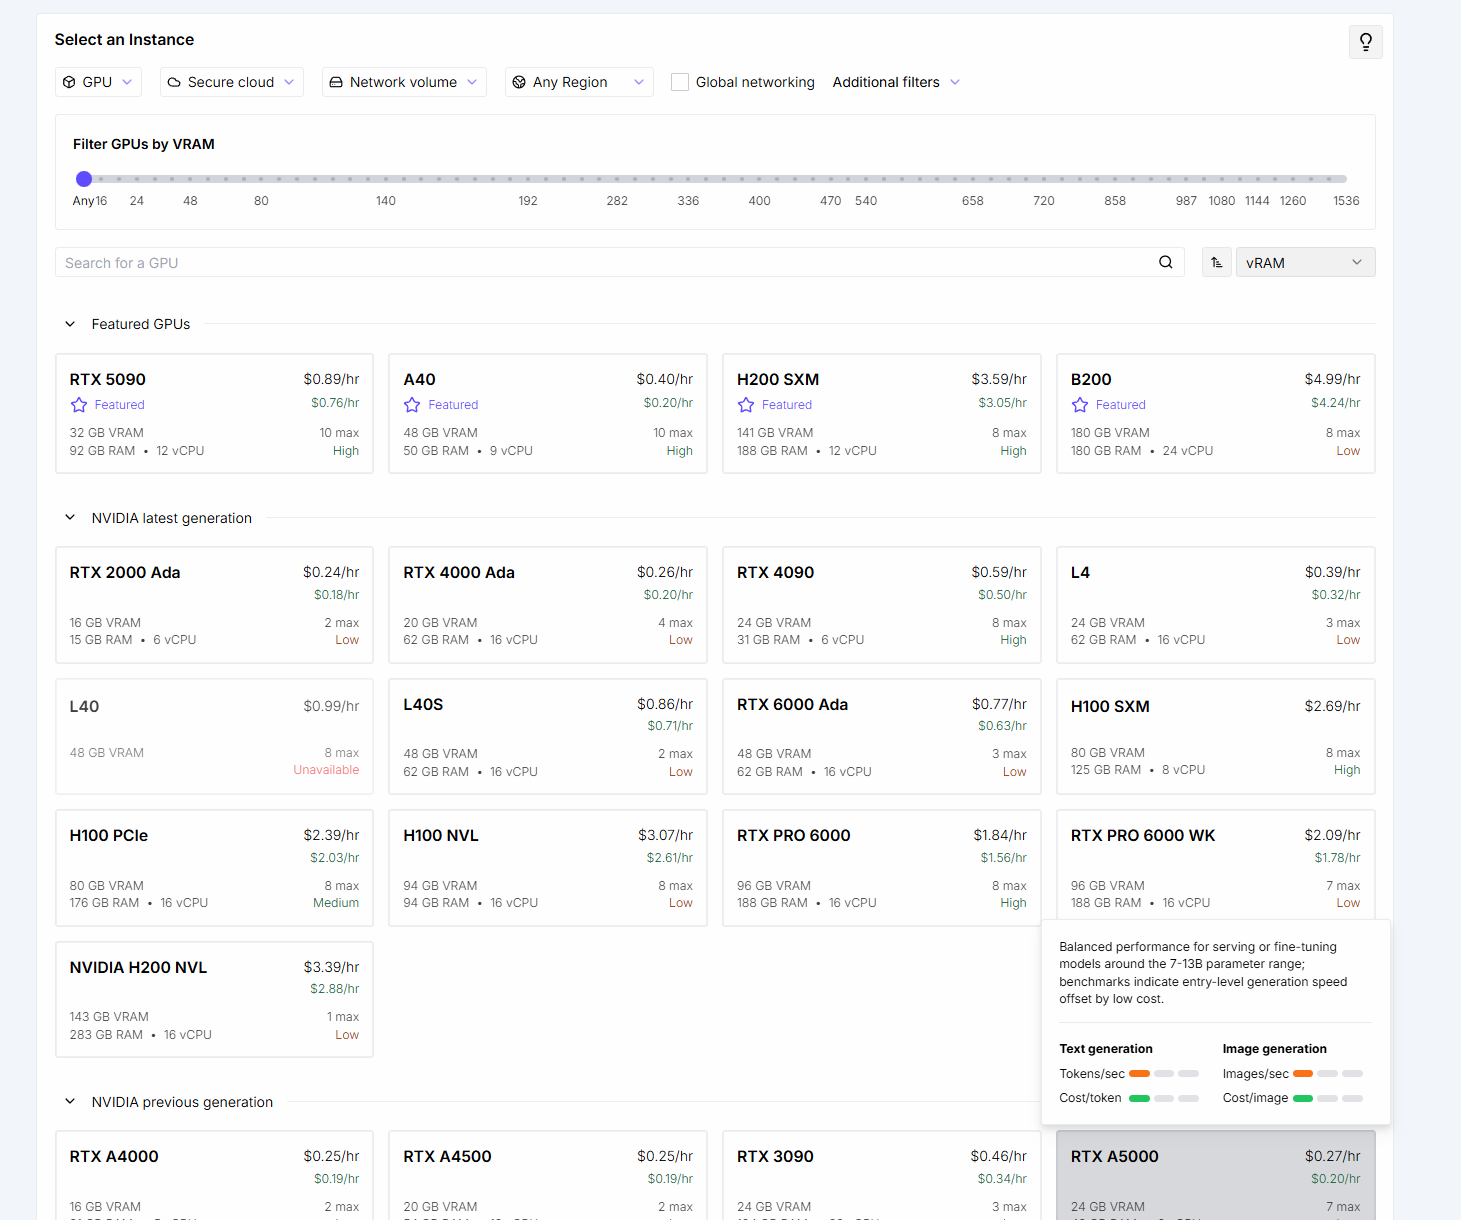
How to Deploy Your LLM in the Cloud - by Benjamin Marie