
Paper Page Scalify Scale Propagation For Efficient Low Precision Llm

Paper page - Scalify: scale propagation for efficient low-precision LLM ...
Scalify: scale propagation for efficient low-precision LLM training ...

Scalify: scale propagation for efficient low-precision LLM training ...

(PDF) Scalify: scale propagation for efficient low-precision LLM training

Paper page - EDGE: Efficient Data Selection for LLM Agents via ...

Paper page — Infinite-LLM: Efficient LLM Service for Long Context with ...

Paper page - Efficient LLM Inference with Kcache

Paper page - User-LLM: Efficient LLM Contextualization with User Embeddings

Paper page - On Data Engineering for Scaling LLM Terminal Capabilities

Paper page - 70% Size, 100% Accuracy: Lossless LLM Compression for ...
Advertisement Space (300x250)

Paper page - Low-rank Optimization Trajectories Modeling for LLM RLVR ...

Paper page - Grass: Compute Efficient Low-Memory LLM Training with ...

Paper page - Sloth: scaling laws for LLM skills to predict multi ...

Paper page - Scaling Environments for LLM Agents in the Era of Learning ...

Paper page - SALE : Low-bit Estimation for Efficient Sparse Attention ...
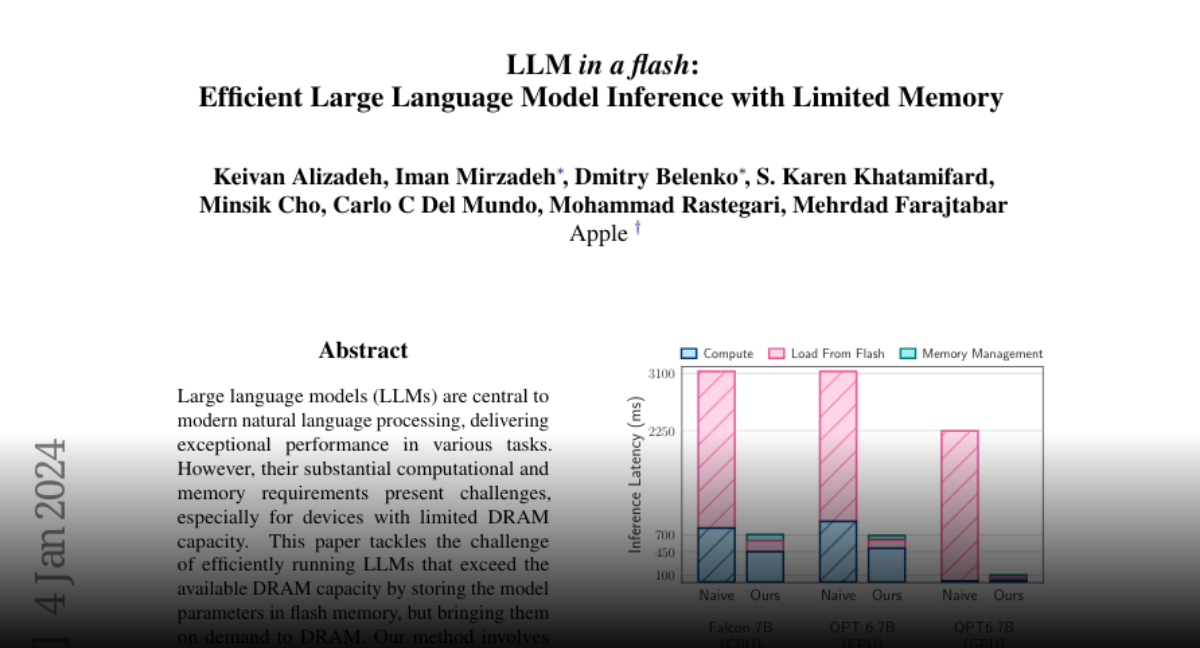
Paper page - LLM in a flash: Efficient Large Language Model Inference ...

Paper page - Performance-Guided LLM Knowledge Distillation for ...

Paper page - Scaling LLM Test-Time Compute Optimally can be More ...

Paper page - MixLLM: LLM Quantization with Global Mixed-precision ...

Paper page - Efficient Pretraining Length Scaling
Advertisement Space (336x280)

Paper page - ParetoQ: Scaling Laws in Extremely Low-bit LLM Quantization

Paper page - The Art of Scaling Reinforcement Learning Compute for LLMs

Efficient Memory Management For LLM Model Serving With Paged Attention ...

RAMP: Reinforcement Adaptive Mixed Precision Quantization for Efficient ...

Paper page - SparQ Attention: Bandwidth-Efficient LLM Inference

Cool new paper preprint Scaling Laws for Precision Two important ...

[논문 리뷰] Optimal Singular Damage: Efficient LLM Inference in Low Storage ...

Paper page - Scaling Laws for Downstream Task Performance of Large ...

From Shotgun to Sniper, A Precision Framework for LLM Efficiency ...

Paper page - LLMs Improving LLMs: Agentic Discovery for Test-Time Scaling
Advertisement Space (336x280)
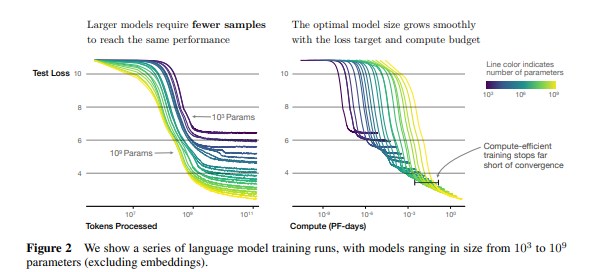
[2024 LLM 스터디] Scaling Laws for Neural Language Models (2020)
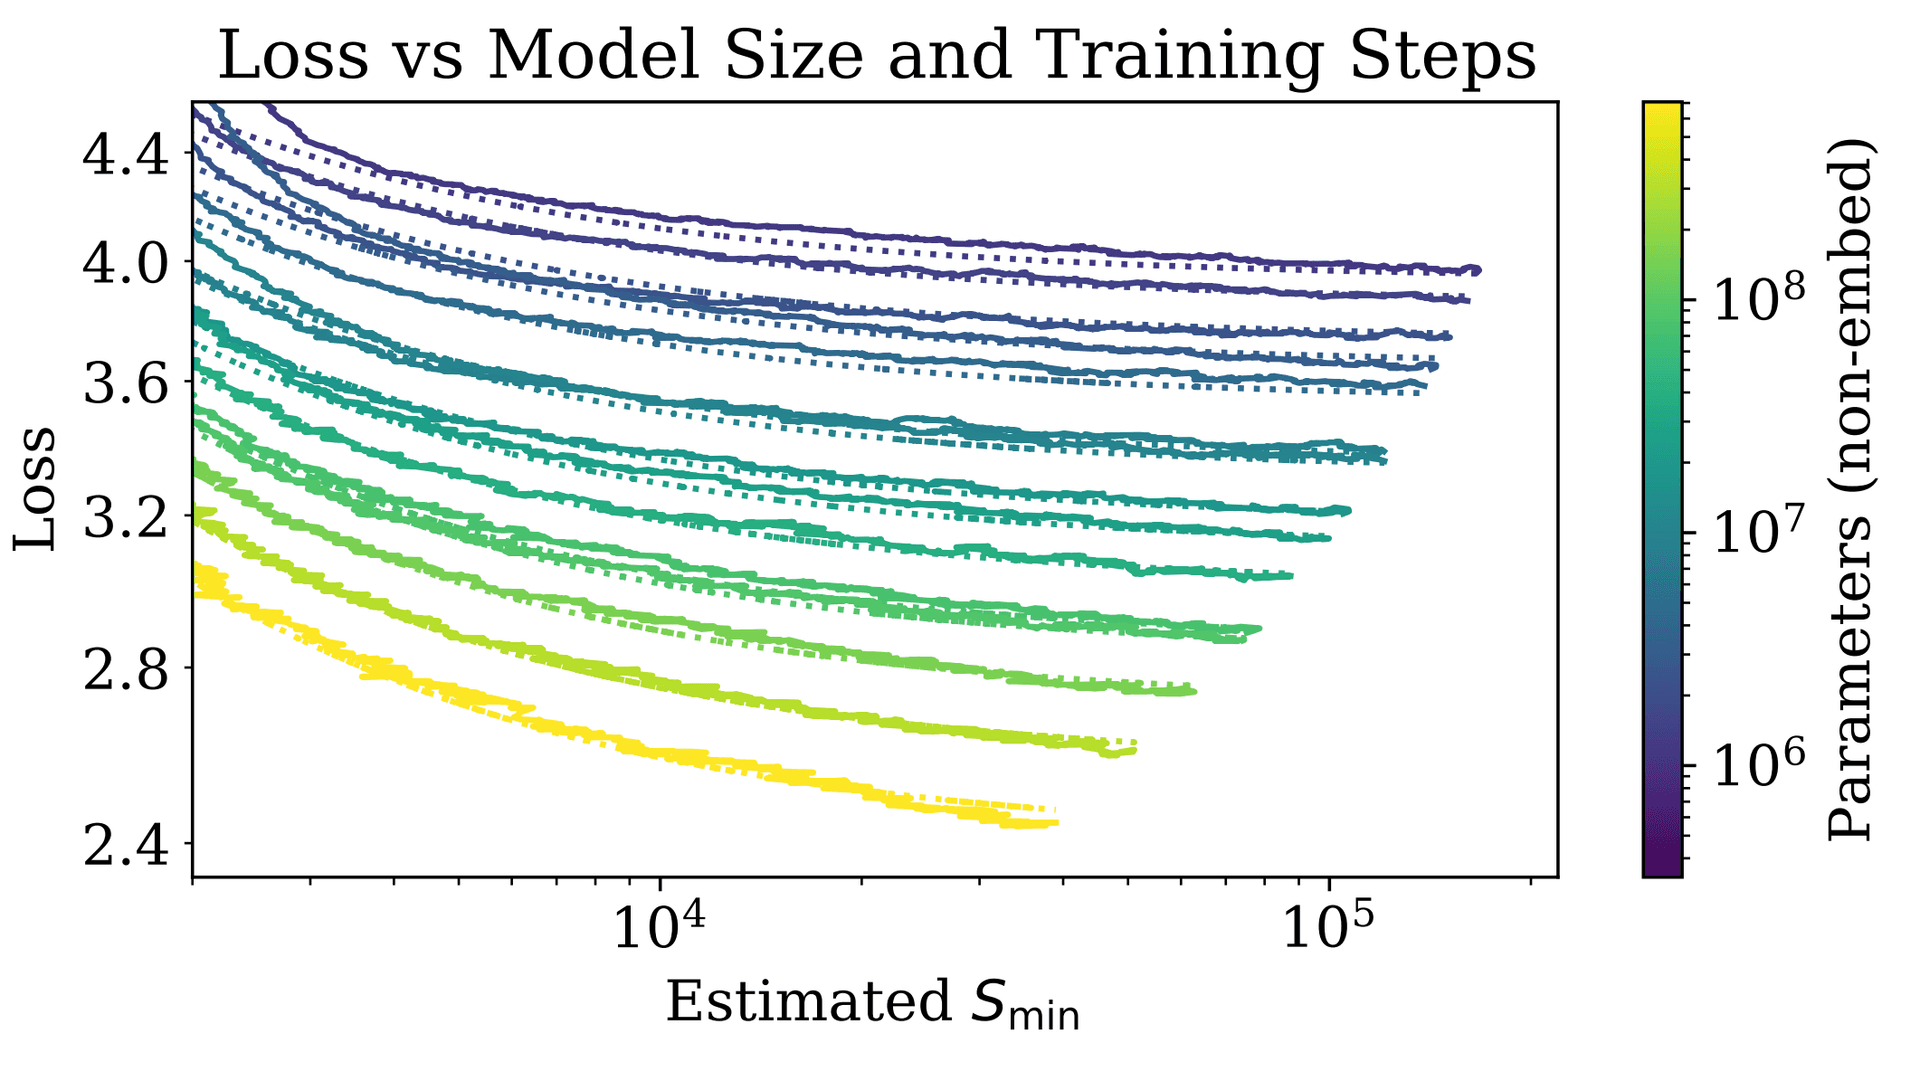
Scaling Laws for LLM Pretraining
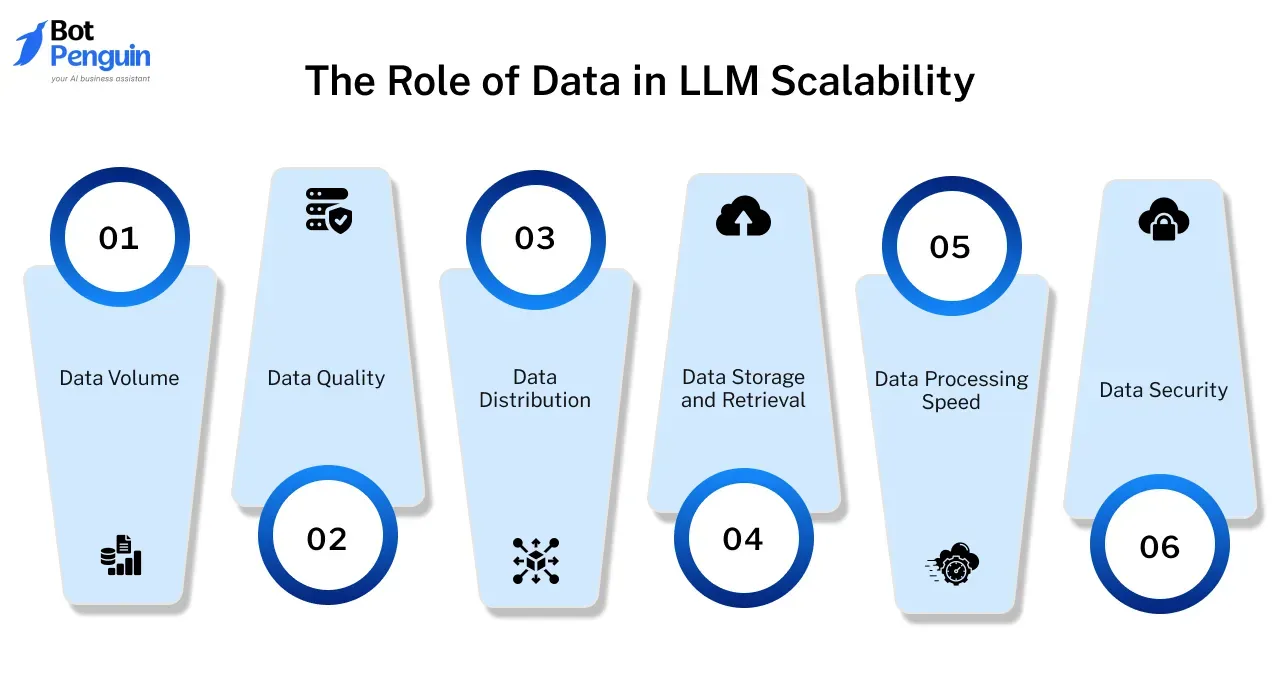
New Scalability Tips for LLM Platforms: Step-by-Step Guide

GitHub - horseee/Awesome-Efficient-LLM: A curated list for Efficient ...
GitHub - horseee/Awesome-Efficient-LLM: A curated list for Efficient ...

I-LLM: Efficient Integer-Only Inference for Fully-Quantized Low-Bit ...