
Pipeline Parallelism Support Issue 752 Vllm Projectvllm Github
Pipeline parallelism support · Issue #752 · vllm-project/vllm · GitHub
Pipeline parallelism + vLLM + Ray · Issue #2697 · verl-project/verl ...
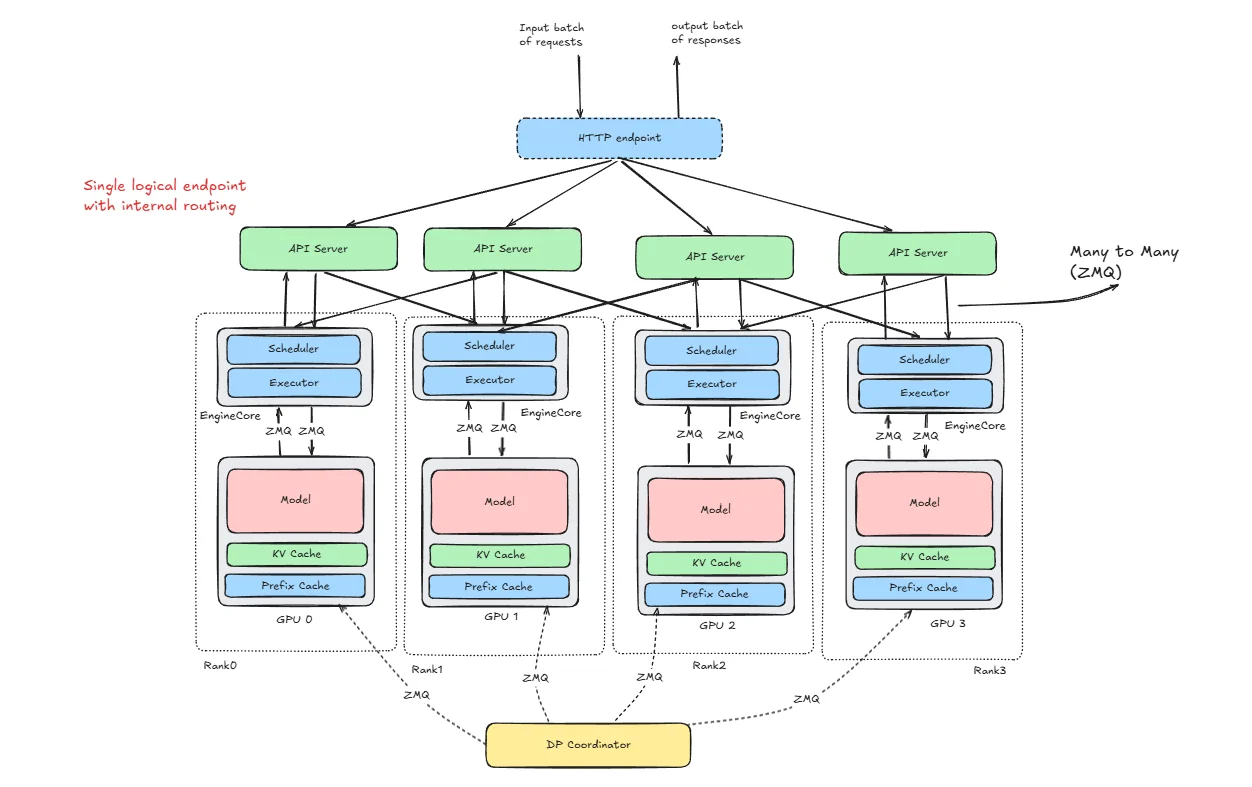
Scaling LLM Inference: Data, Pipeline & Tensor Parallelism in vLLM ...
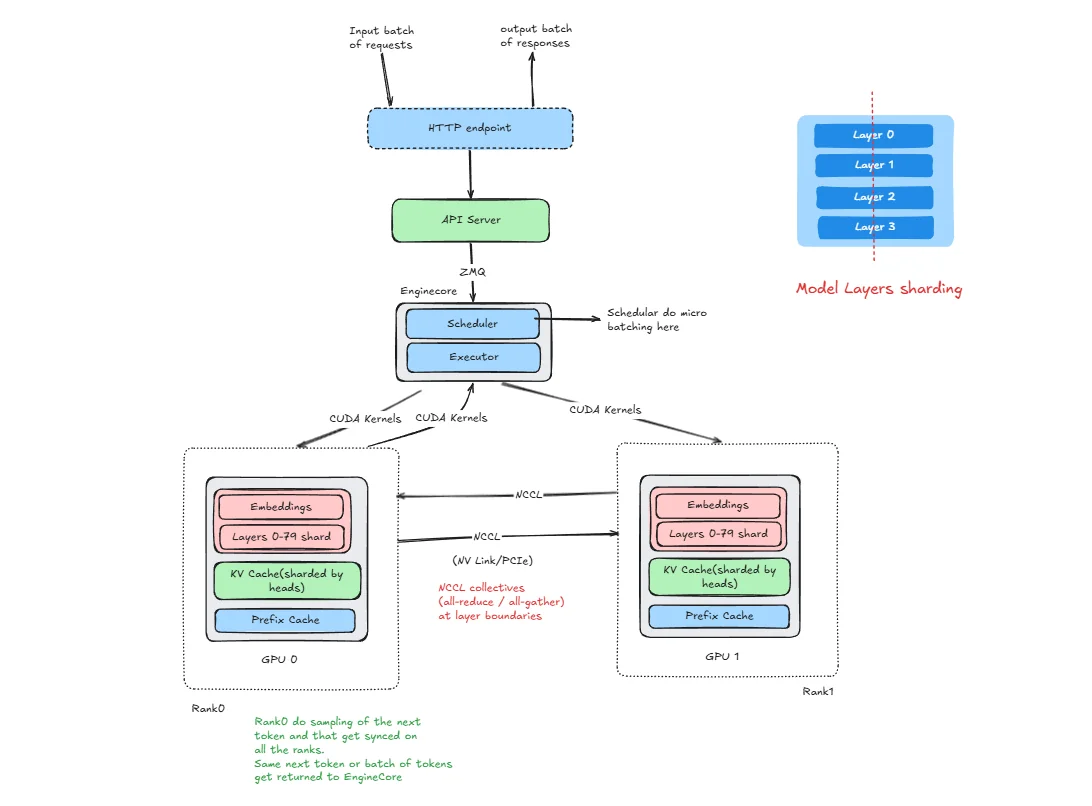
Scaling LLM Inference: Data, Pipeline & Tensor Parallelism in vLLM ...
[Bug]: vLLM Multinode Pipeline Error with pipeline parallelism using ...
[Feature]: Pipeline Parallelism support for the Vision Language Models ...
pipeline parallel support in the future? · Issue #387 · vllm-project ...
model parallelism · vllm-project vllm · Discussion #243 · GitHub
[Feature]: is vllm support sequence-parallel? · Issue #3940 · vllm ...
[Feature]: Context Parallelism · Issue #7519 · vllm-project/vllm · GitHub
Advertisement Space (300x250)
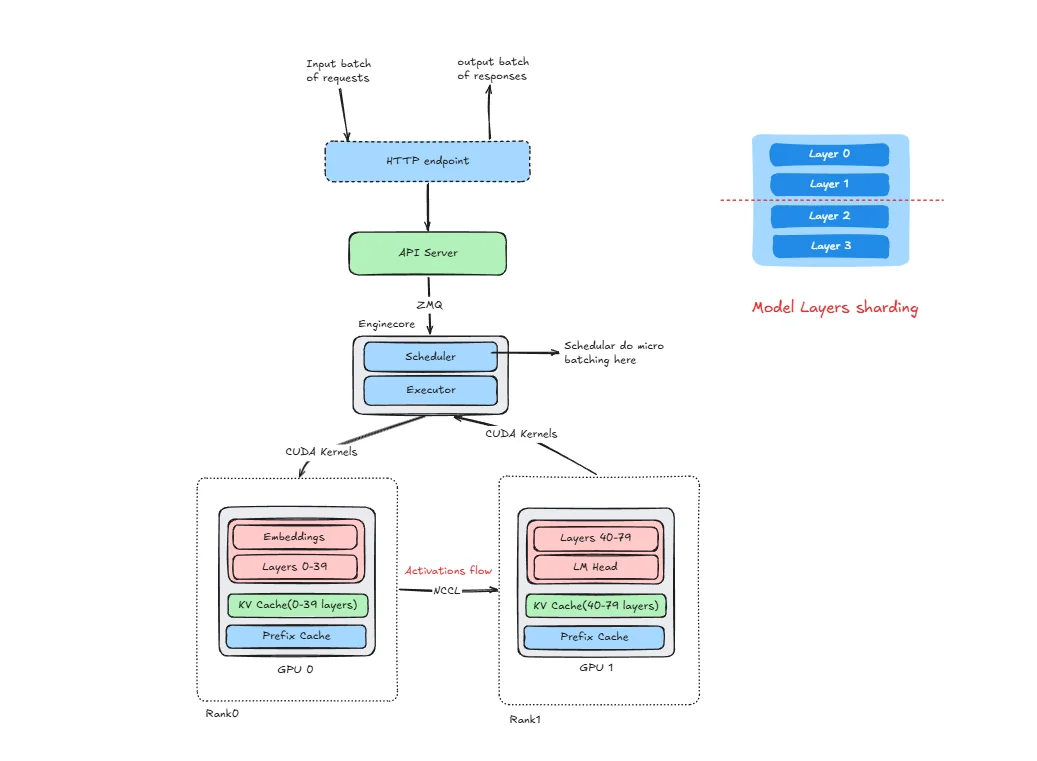
Scaling LLM Inference: Data, Pipeline & Tensor Parallelism in vLLM ...
Support VLM model and GPT4V API · Issue #2058 · vllm-project/vllm · GitHub
[Installation]: vLLM does not support torch 2.5 · Issue #9554 · vllm ...
Pipeline Parallelism slightly faster than single gpu · Issue #1102 ...
Is there a plan to support pipeline inference? · Issue #85 ...
[RFC]: vLLM plugin system · Issue #7131 · vllm-project/vllm · GitHub
pip install vllm not working · Issue #2634 · vllm-project/vllm · GitHub
[Usage]: Does vLLM support multi-task · Issue #13390 · vllm-project ...
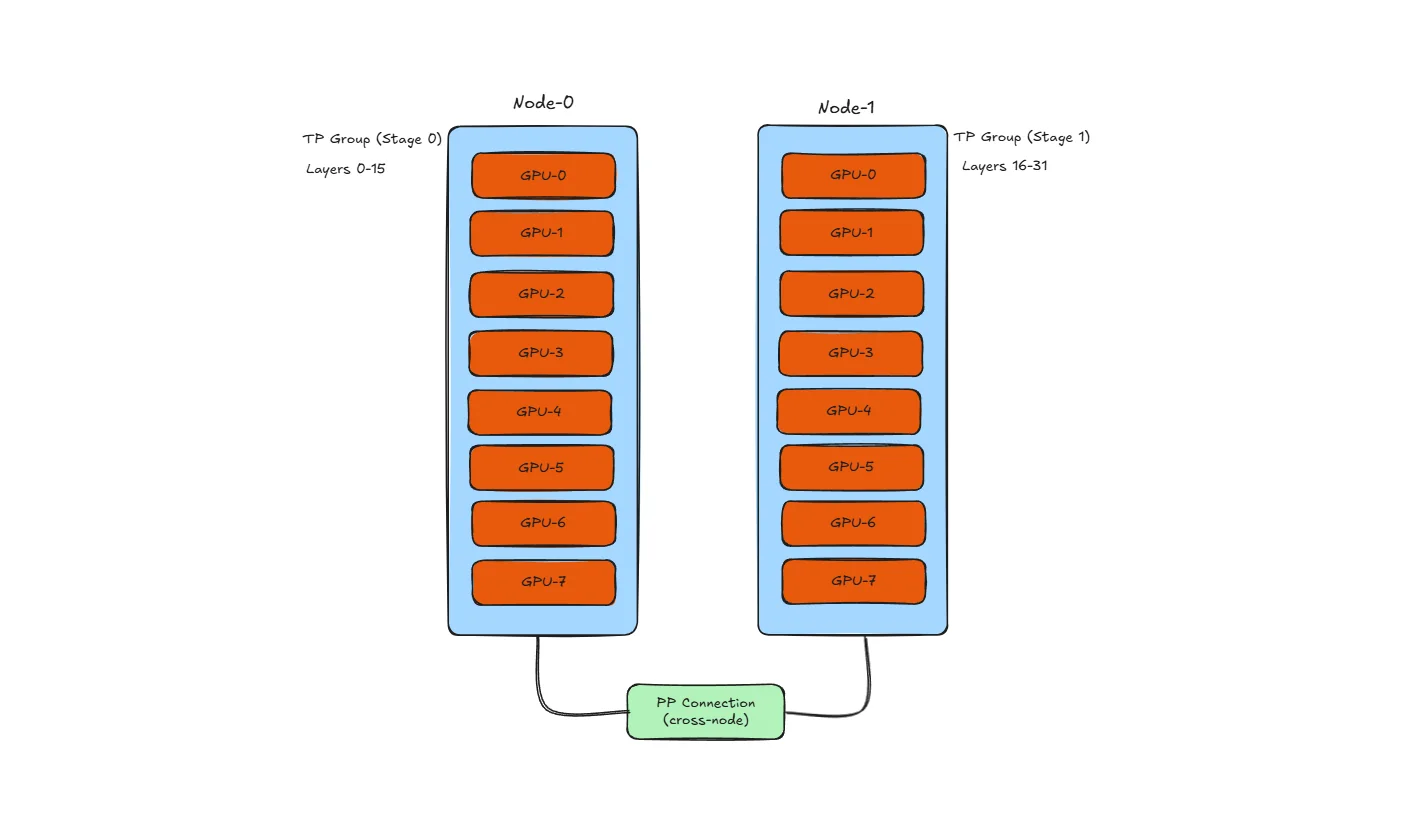
Scaling LLM Inference: Data, Pipeline & Tensor Parallelism in vLLM ...
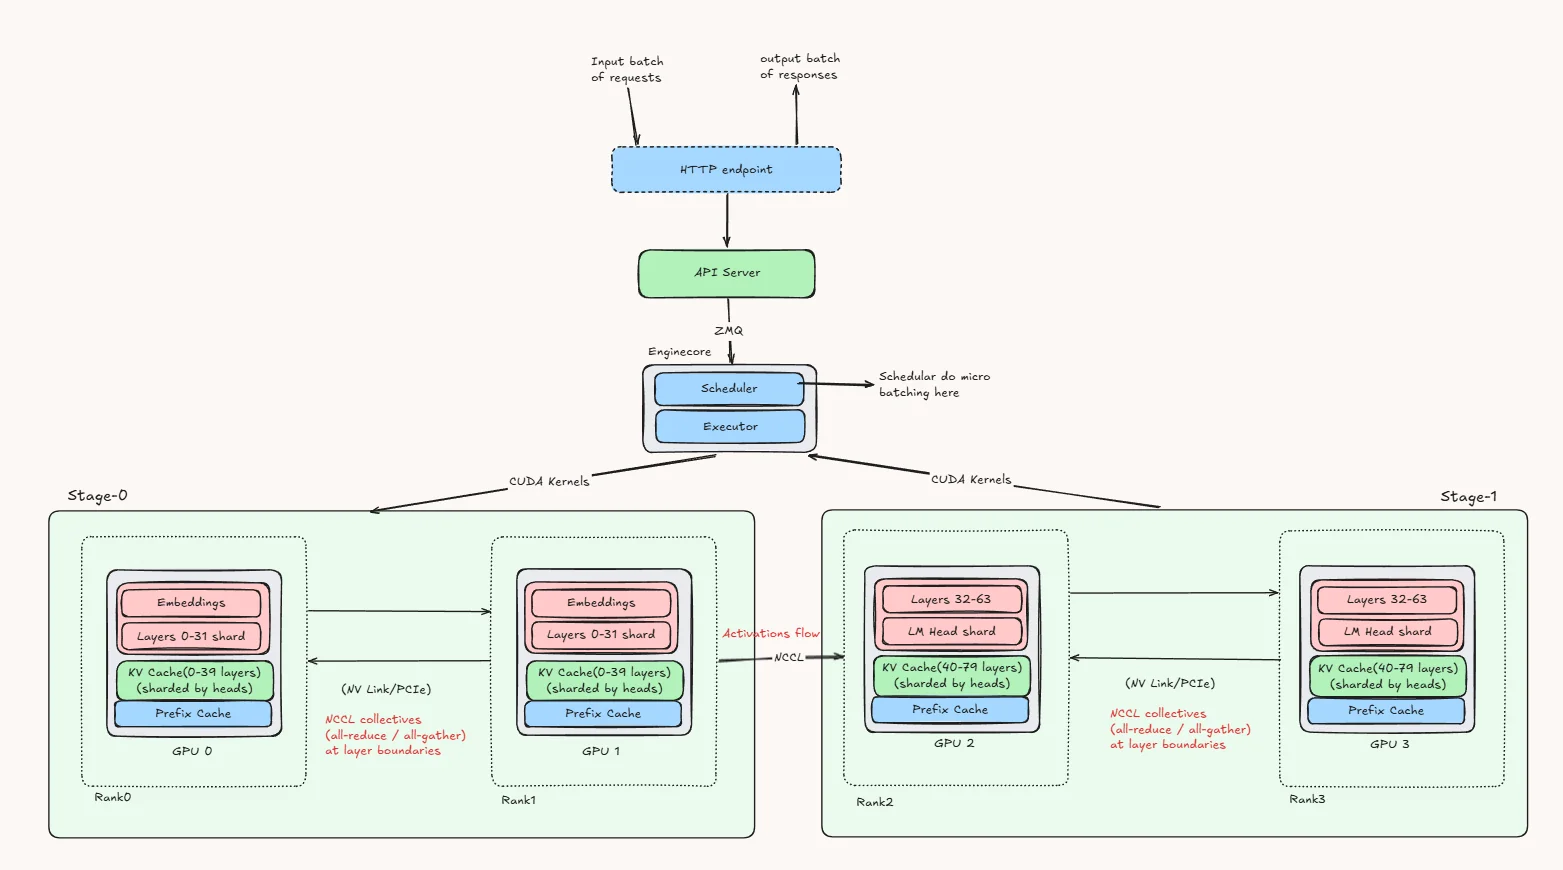
Expert Parallelism and Mixed Parallelism Strategies in vLLM | Jarvis ...
Advertisement Space (336x280)
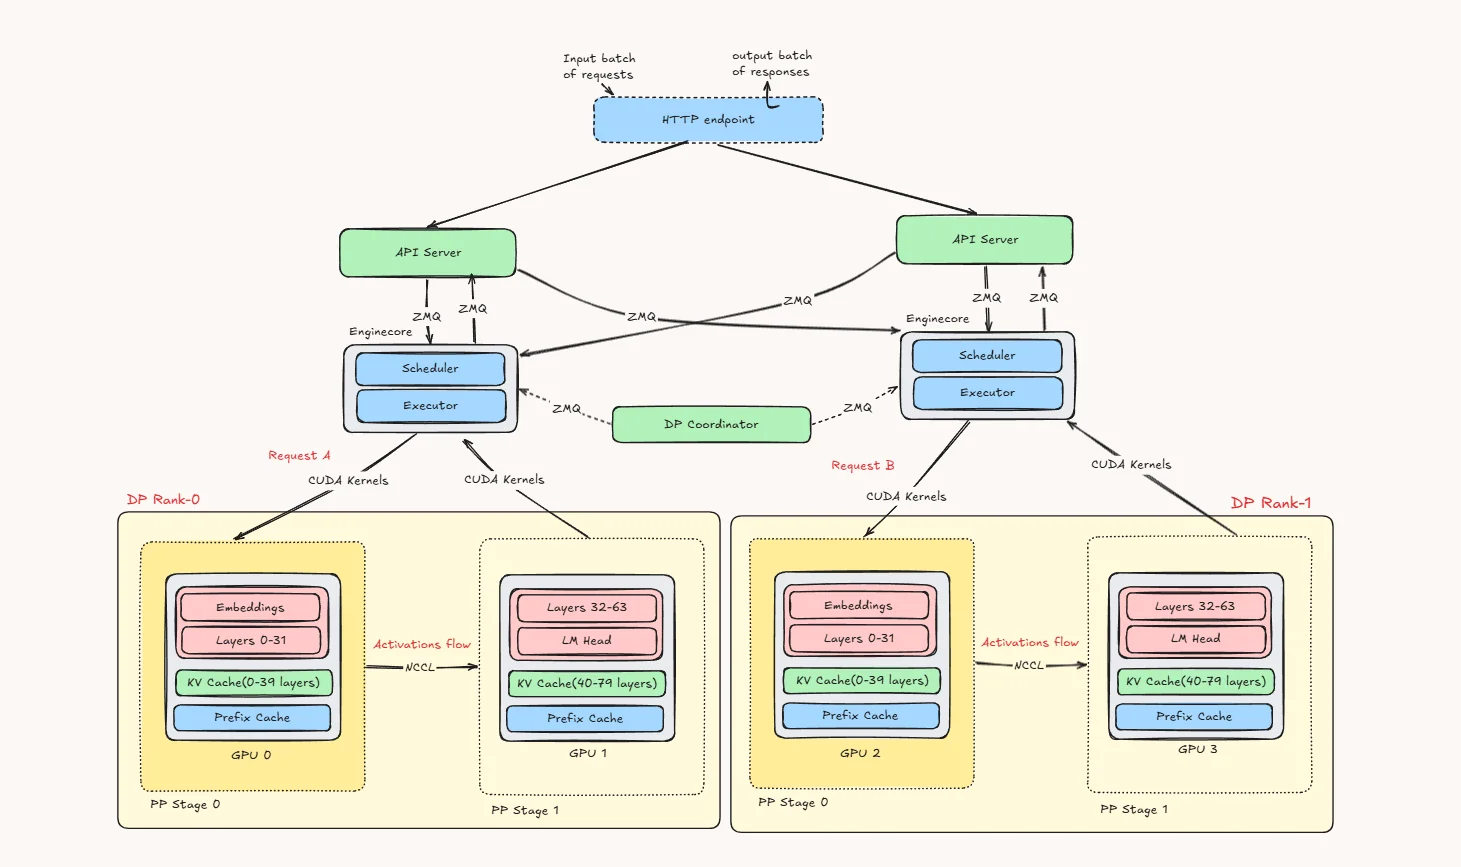
Expert Parallelism and Mixed Parallelism Strategies in vLLM | Jarvis ...
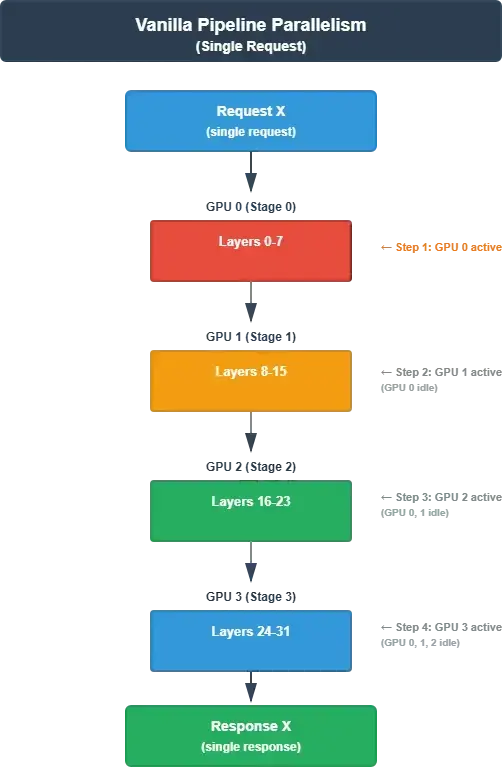
vLLM MoE 调优手册(上篇):TP、DP、PP 与 Expert Parallelism 实战指南 - 知乎
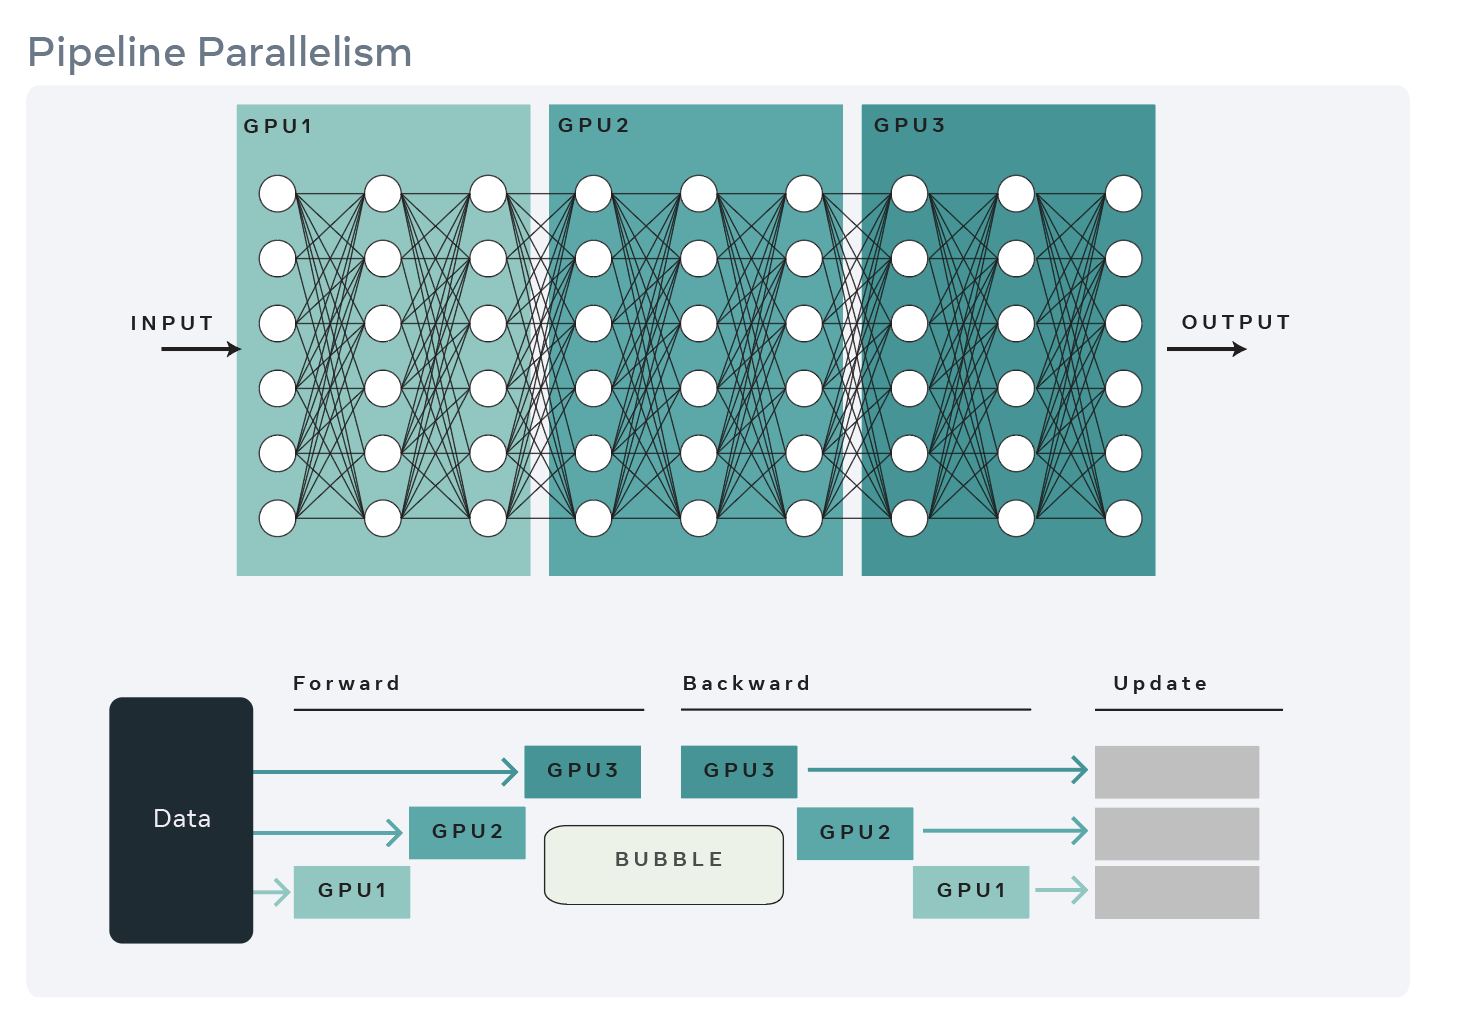
Pipeline Parallelism | FairScale documentation
[RFC]: Pipeline-Parallelism for vLLM V1 · Issue #11945 · vllm-project ...
[Bug]: Pipeline parallelism is only supported through AsyncLLMEngine as ...
[Usage]: how should I do data parallelism using vLLM? · Issue #5143 ...
[Usage]: How to use --pipeline-parallel-size · Issue #6054 · vllm ...
[Performance]: Online serving with Pipeline Parallel · Issue #11192 ...
Tensor and Pipeline Parallelism | baidu/vLLM-Kunlun | DeepWiki
load model in batches · Issue #759 · vllm-project/vllm · GitHub
Advertisement Space (336x280)
Segmentation fault with pipeline parallelism and `gather_all_token ...
[Bug]: vLLM 0.5.1 tensor parallel 2 hang · Issue #6370 · vllm-project ...
[Feature]: Speculative decoding and Pipeline Paralelism · Issue #14044 ...
Expert Parallelism and Mixed Parallelism Strategies in vLLM | Jarvis ...
[Bug]: Extreme low throughput when using pipeline parallelism when ...
[Bug]: requests with response_format cause vllm to hang with pipeline ...