
Run Gguf Quantized 7b Llms With No Gpu On Your Laptop Youtube

Run GGUF Quantized 7B LLMs with no GPU on your laptop - YouTube
How to Run Quantized GGUF LLMs Locally on GPU with llama.cpp (No Cloud ...

GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU

Run LLMs Locally on Your GPU with vLLM (No APIs) | Top Python Libraries

GPT4All: Run Local LLMs on Your Laptop Without GPU

GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU

LLMs with No GPUs - Use Custom GGUF Models with LLMWare - YouTube
GGUF Dynamic Quantization on GPU Cloud: Deploy LLMs 50% Cheaper with ...

How to Use Intel and AMD GPUs to run LLMs on Your PC - YouTube

EASIEST Way to Run Gemma 7b/2b Locally! NO GPU Required! - YouTube
Advertisement Space (300x250)

Run a LLM on your WINDOWS PC | Convert Hugging face model to GGUF ...
Mistral 7B Instruct GGUF Run On CPU Basic - a Hugging Face Space by ...

Meet GGUF Loader: Run Local LLMs with Zero Hassle - DEV Community
Run 70B LLMs on Consumer GPU - VRAM and Quantization Guide (2026)

Large Language Models: How to Run LLMs on a Single GPU - hyperight.com

Run 70B LLMs on Consumer GPU - VRAM and Quantization Guide (2026)

Run LLMs FASTER on Intel Graphics (ARC)- The SYCL way! - YouTube

LM Studio - How I was able to run Open Source LLMs LOCALLY on a LAPTOP ...
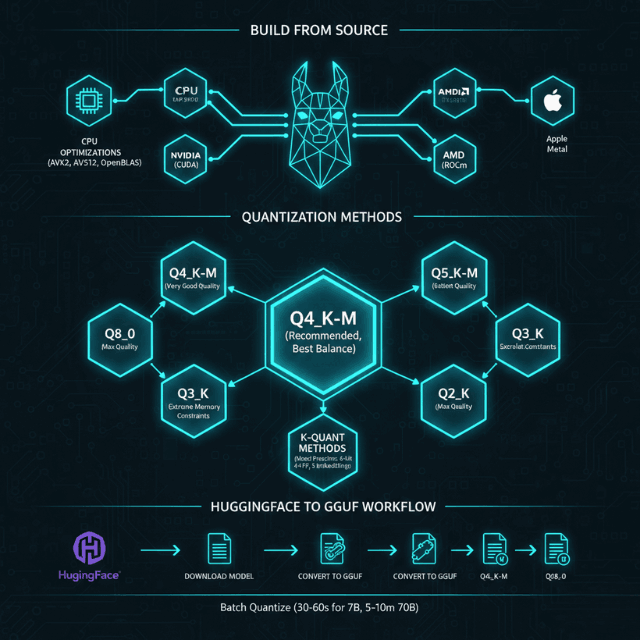
Run 70B LLMs on Consumer GPU - VRAM and Quantization Guide (2026)
How to run LLMs with less GPU and CPU memory? | by Mehul Gupta | Data ...
Advertisement Space (336x280)
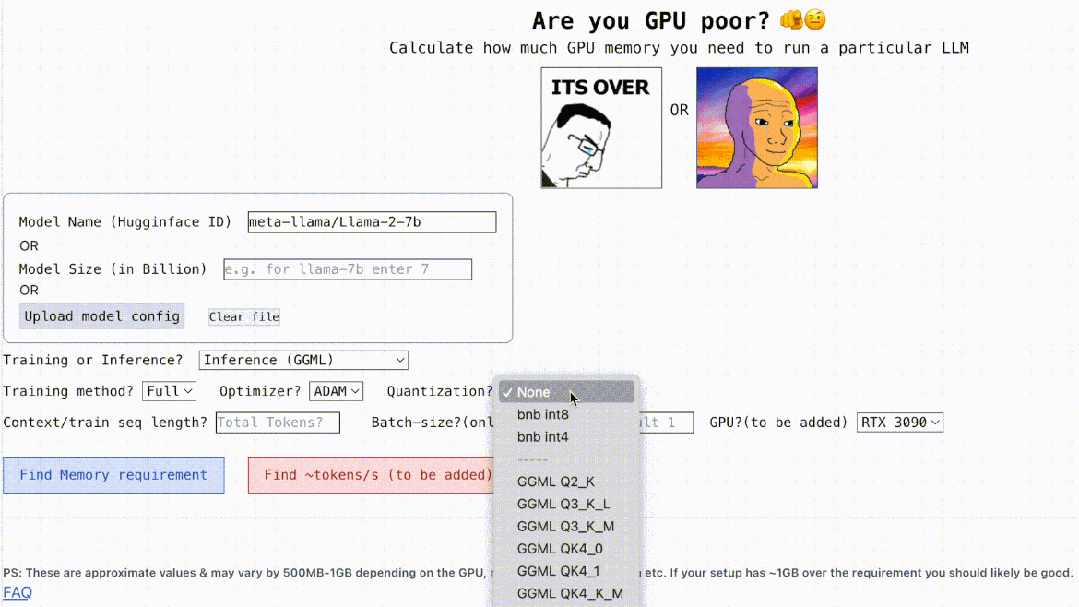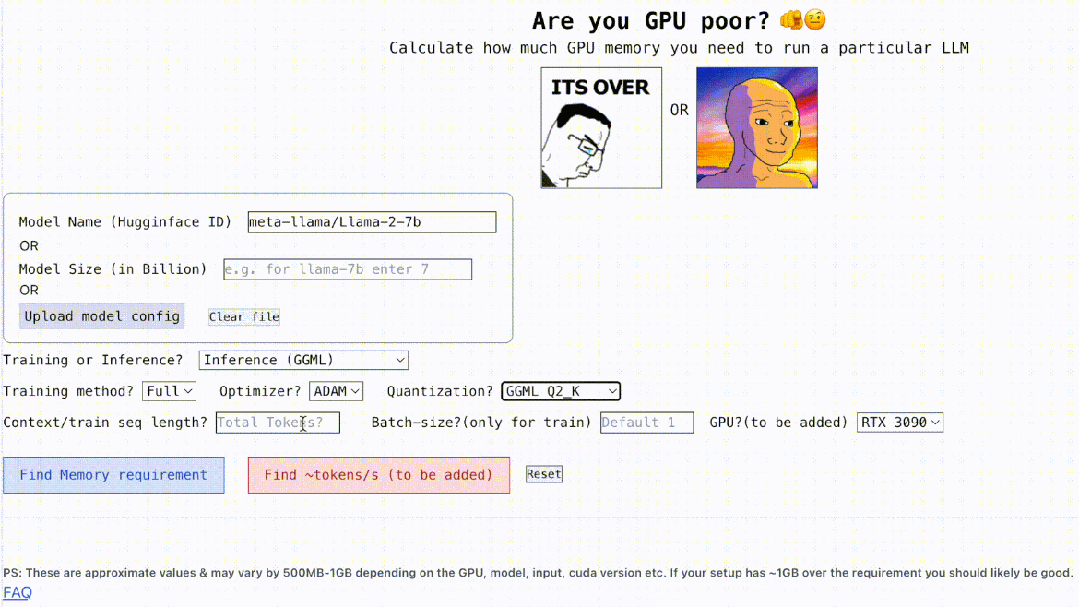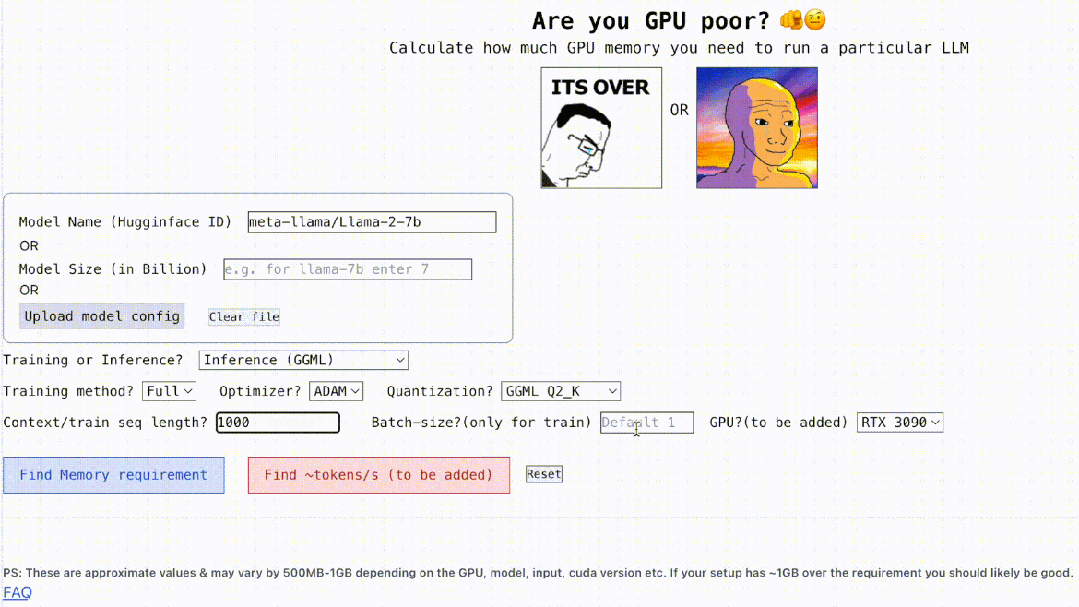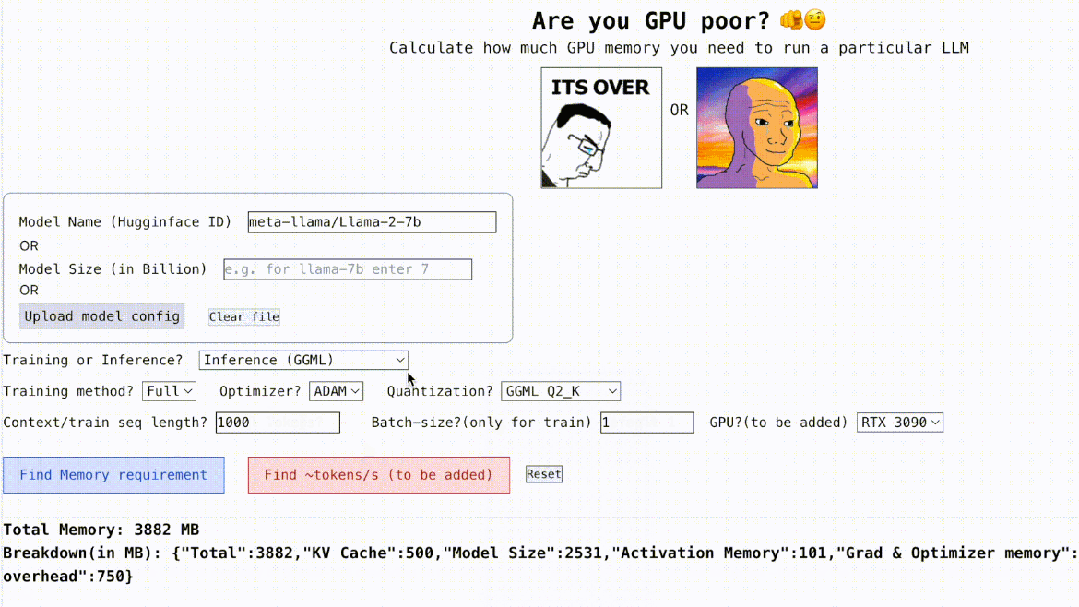
How To Run LLMs On Your RTX PC - Part 1 (Hugging Face) - NUA Dev
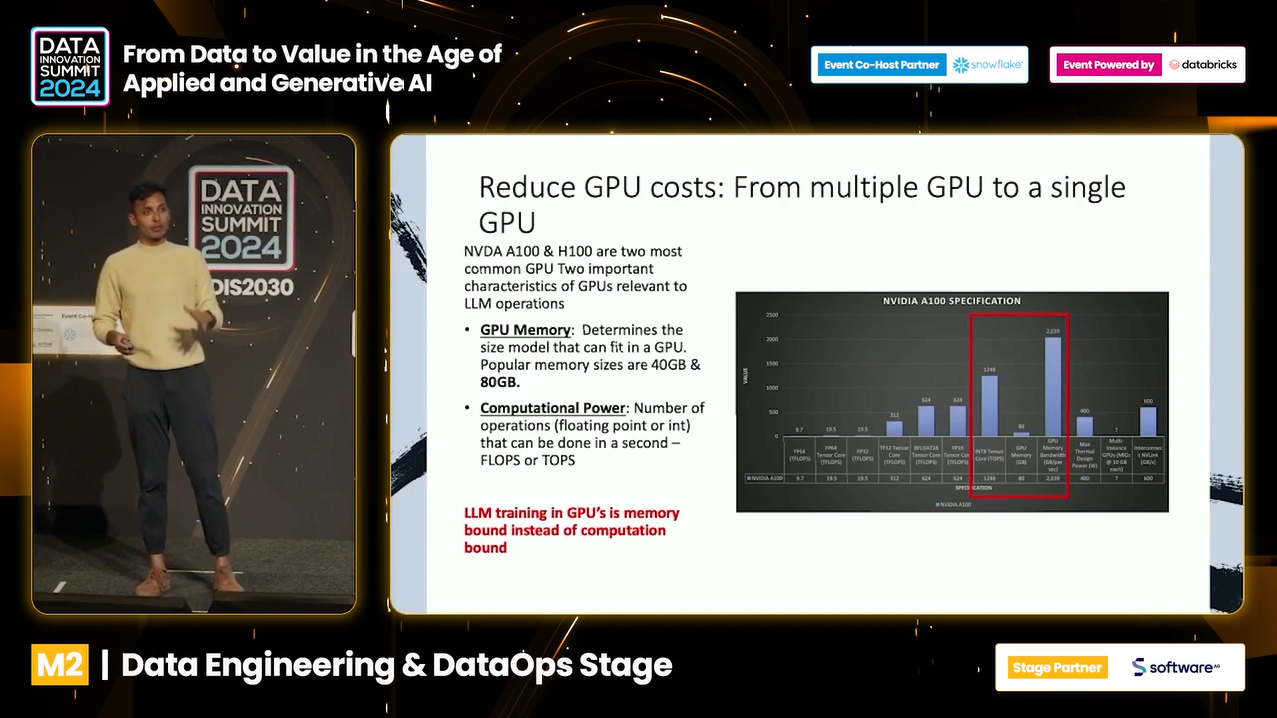
Large Language Models: How to Run LLMs on a Single GPU - Hyperight

How to Run Any GGUF AI Model with Ollama Locally - YouTube

Run Code Llama 13B GGUF Model on CPU: GGUF is the new GGML - YouTube

Quantize any LLM with GGUF and Llama.cpp - YouTube
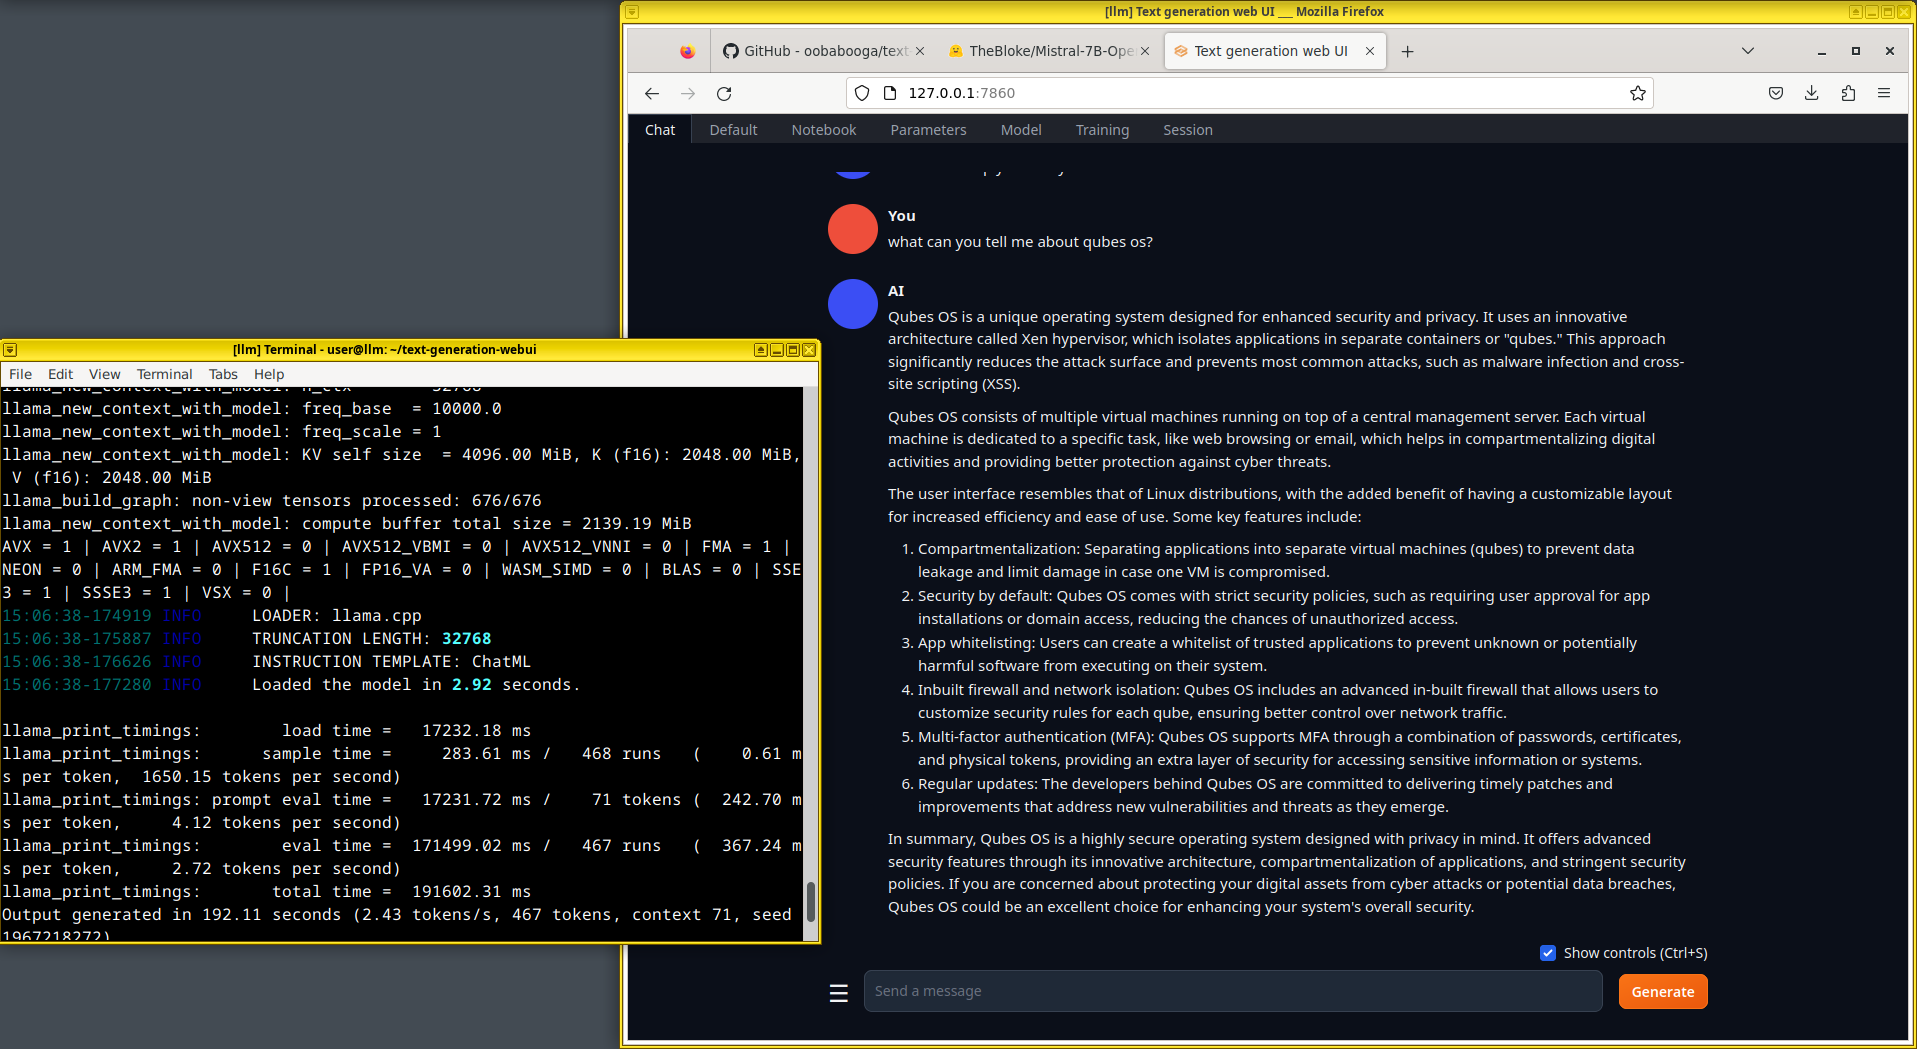
Running local LLMs with or without GPU acceleration - Community Guides ...

Run LLM on Your PC - Harnessing AI Power on Your Own Machine
Can You Run LLMs Locally Without a GPU? I Tested 8 Models on Linux

Local LLMs: How To Run gguf-bassed Models With Gradio - YouTube

Build Your Own CODE-LLAMA 7B GGUF Model powered Gradio App for Coding ...
Advertisement Space (336x280)

Your Health Data, Your GPU: Local 7B LLM Inference with WebLLM & Google ...

Quantizing LLMs - How & Why (8-Bit, 4-Bit, GGUF & More) - YouTube
[Bug]: Issue running the Granite-7b GGUF quantized model on multiple ...

Putting the GPU to Work: Running Local LLMs on a Home Lab - DEV Community

MIT and Yandex’s Researchers Introduce HIGGS to Makes LLMs Run on ...

LLMs on CPU: The Power of Quantization with GGUF, AWQ, & GPTQ