
Usage Vllm Serving With Local Model Issue 12378 Vllm Project
[Usage]: vLLM serving with local model · Issue #12378 · vllm-project ...
Serving multiple models in vLLM with single or multiple engines · Issue ...
vLLM model serving server hangs when GPU KV cache usage reaches 10% ...
Multi-node serving with vLLM - Problems with Ray · Issue #2406 · vllm ...
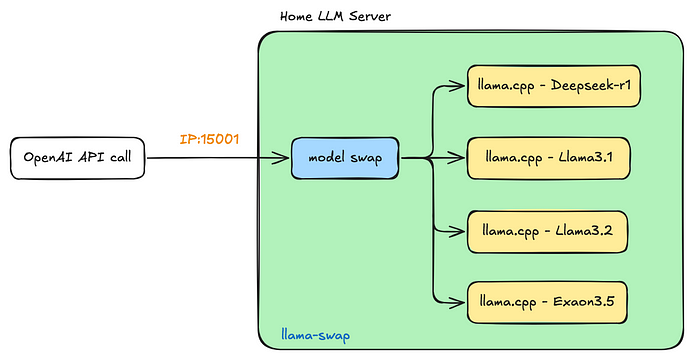
Deploy Large Language Model (LLM) with vLLM on K8s | by FiftyFive ...
Serving Models with vLLM | vllm-project/speculators | DeepWiki
Deploying local LLM hosting for free with vLLM
[Bug]: Load a custom model when VLLM_USE_V1=1 · Issue #12533 · vllm ...
[Usage]: Run local models using vLLM · Issue #5011 · vllm-project/vllm ...
How long does vllm take to load your local model? · Issue #2253 · vllm ...
Advertisement Space (300x250)
Can vllm serving clients by using multiple model instances? · vllm ...
How to deploy vllm model across multiple nodes in kubernetes? · Issue ...
[Usage]: Using VLLM with Langchain for RAG purposes · Issue #5572 ...
[Installation]: Facing Issue while installing vllm in local machine ...
[Usage]: Can't use the local model with LLM class. · Issue #14518 ...
Ray Serve LLM on Anyscale: Wide-EP and Disaggregated Serving with vLLM

Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...

Deploying a Model with vLLM :: vLLM Master Class
[Usage]: Persistent Errors with vllm serve on Neuron Device: Model ...

Deploying a Model with vLLM :: vLLM Master Class
Advertisement Space (336x280)
[Bug]: Error After Model Load in vllm 0.7.0 (No Issue in vllm 0.6.6 ...
[Bug]: Some issues in integrating vllm with verl · Issue #12782 · vllm ...

Deploying a Model with vLLM :: vLLM Master Class
Deploying local LLM hosting for free with vLLM
usage of vllm for extracting embeddings · Issue #1654 · vllm-project ...
unable to run vllm model deployment · Issue #6464 · vllm-project/vllm ...

Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...
[Bug]: VLLM_USE_V1=1 failed with deepseek-v3 · Issue #12956 · vllm ...
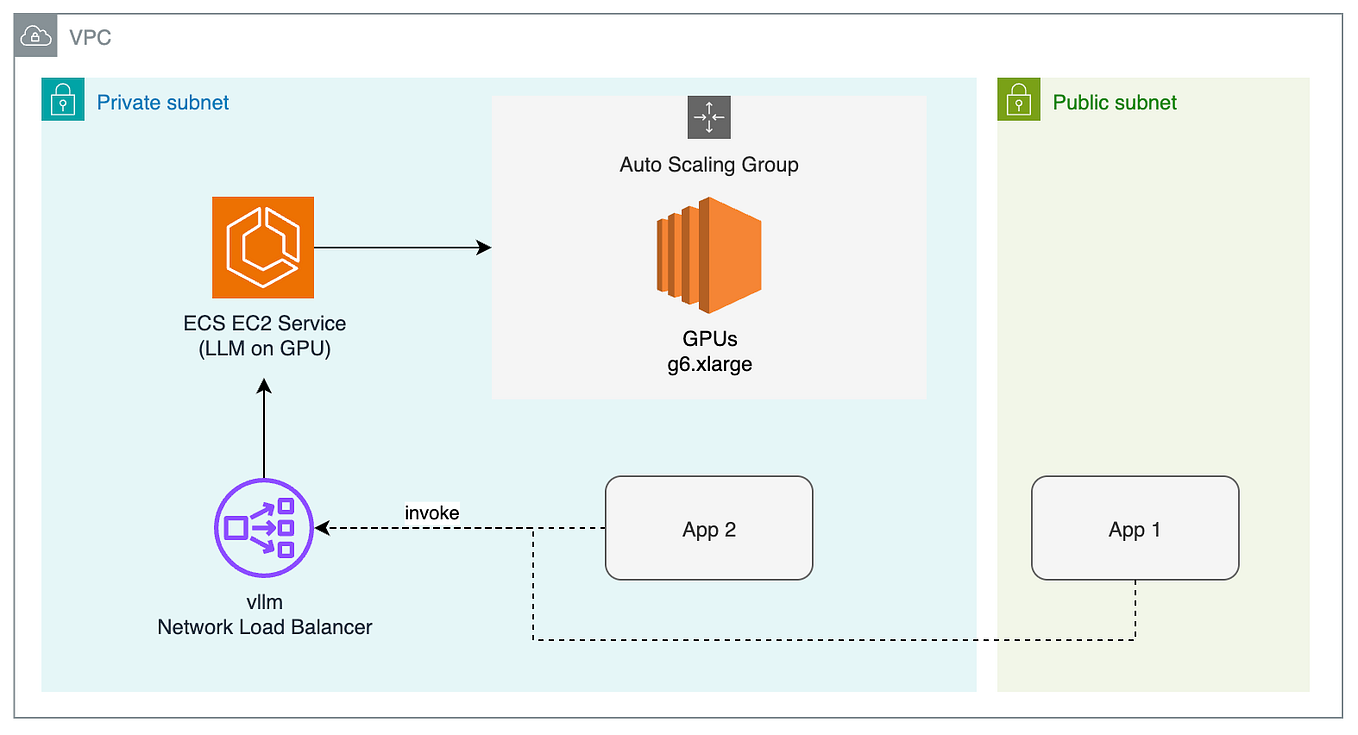
Deploy Large Language Model (LLM) with vLLM on K8s | by FiftyFive ...

GraphRAG local setup via vLLM and Ollama : A detailed integration guide ...
Advertisement Space (336x280)
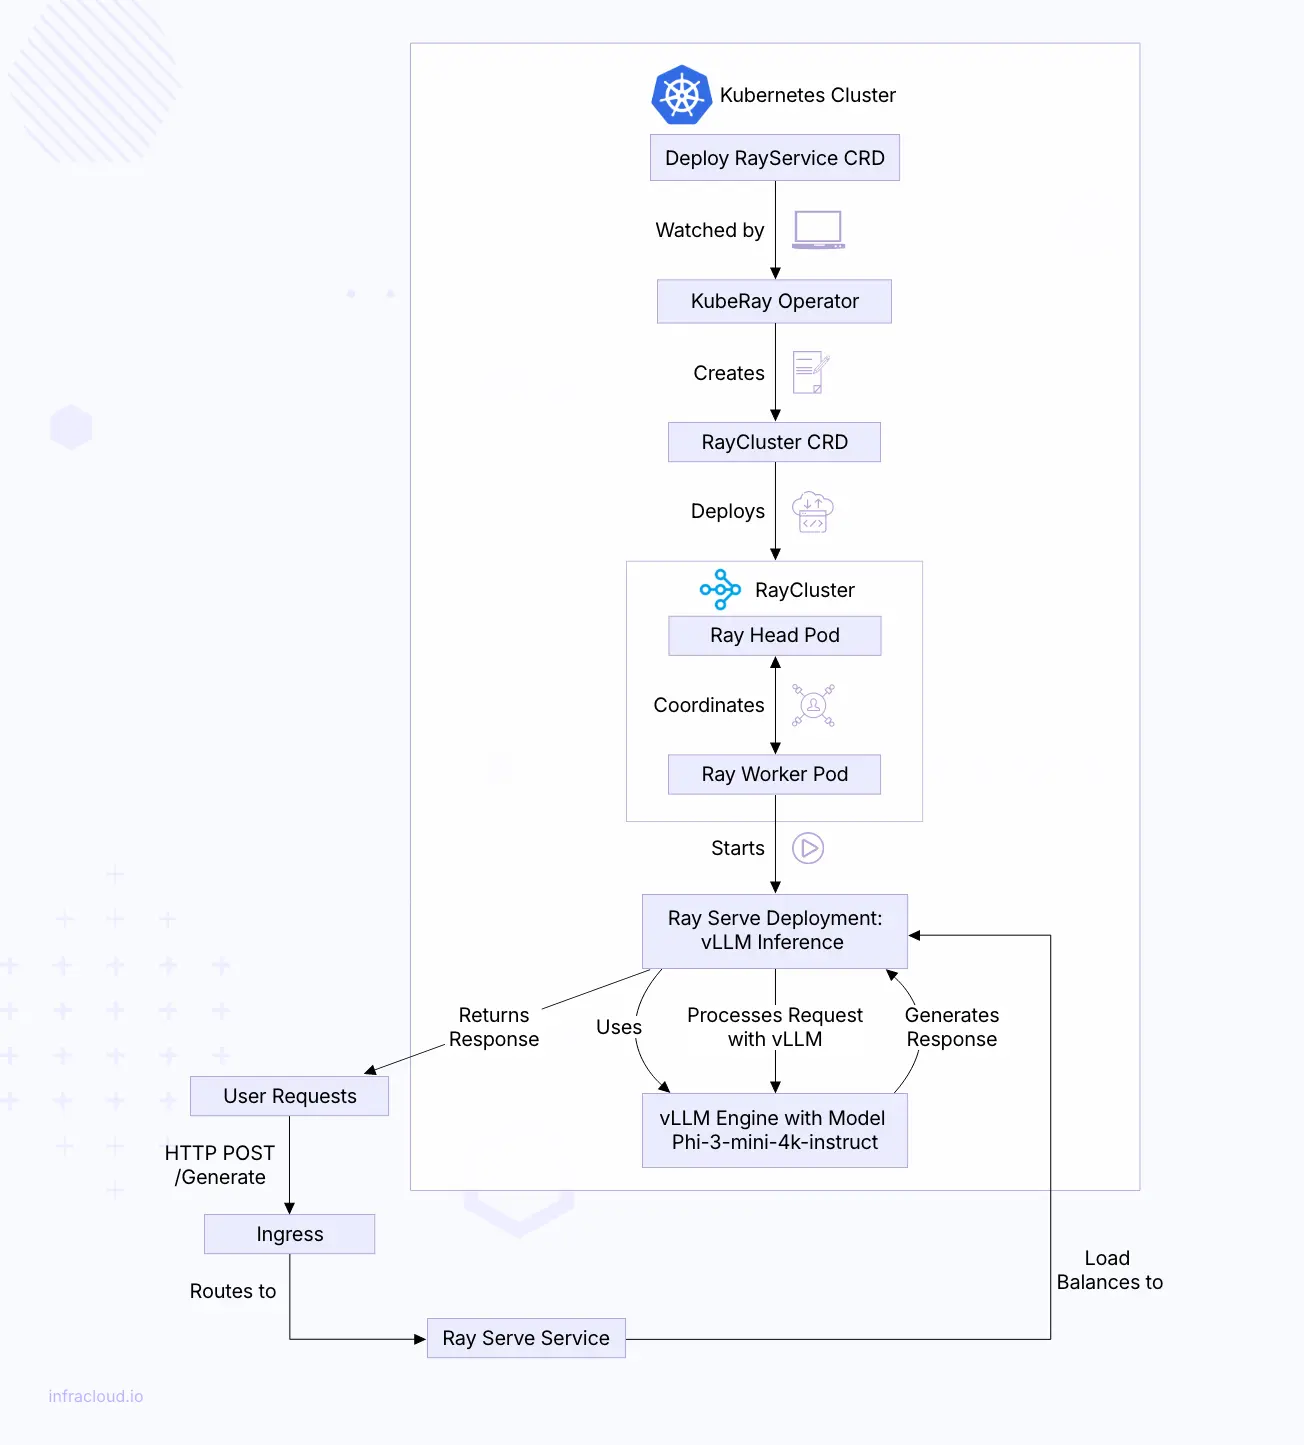
Running Phi 3 with vLLM and Ray Serve

Unlocking Enterprise AI with Gaudi 3: Model Serving and Fine-Tuning at ...

A Brief Introduction to Optimized Batched Inference with vLLM | by ...

How vLLM solves LLM serving issues for AI apps | Aaroh Bhardwaj posted ...
[BUG]: How to use VLLM to serve local models in an environment without ...

A Gentle Introduction to vLLM for Serving - KDnuggets