
Speculative Decoding Kv Cache Clay Technology World

整合 Speculative Decoding 和 KV Cache 之實作筆記 - Clay-Technology World

整合 Speculative Decoding 和 KV Cache 之實作筆記 - Clay-Technology World

Papers - Speculative Decoding - KV Cache - a matlok Collection

Papers - Inference - Speculative Decoding - Draft - KV Cache - a matlok ...
LLM 推理优化全指南:从 KV Cache 到 Speculative Decoding | AI 实战派 · 从技术到赚钱
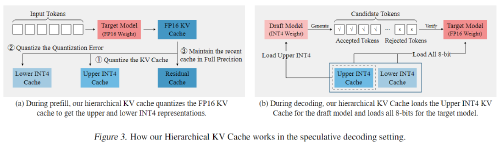
QuantSpec: Self-Speculative Decoding with Hierarchical Quantized KV Cache
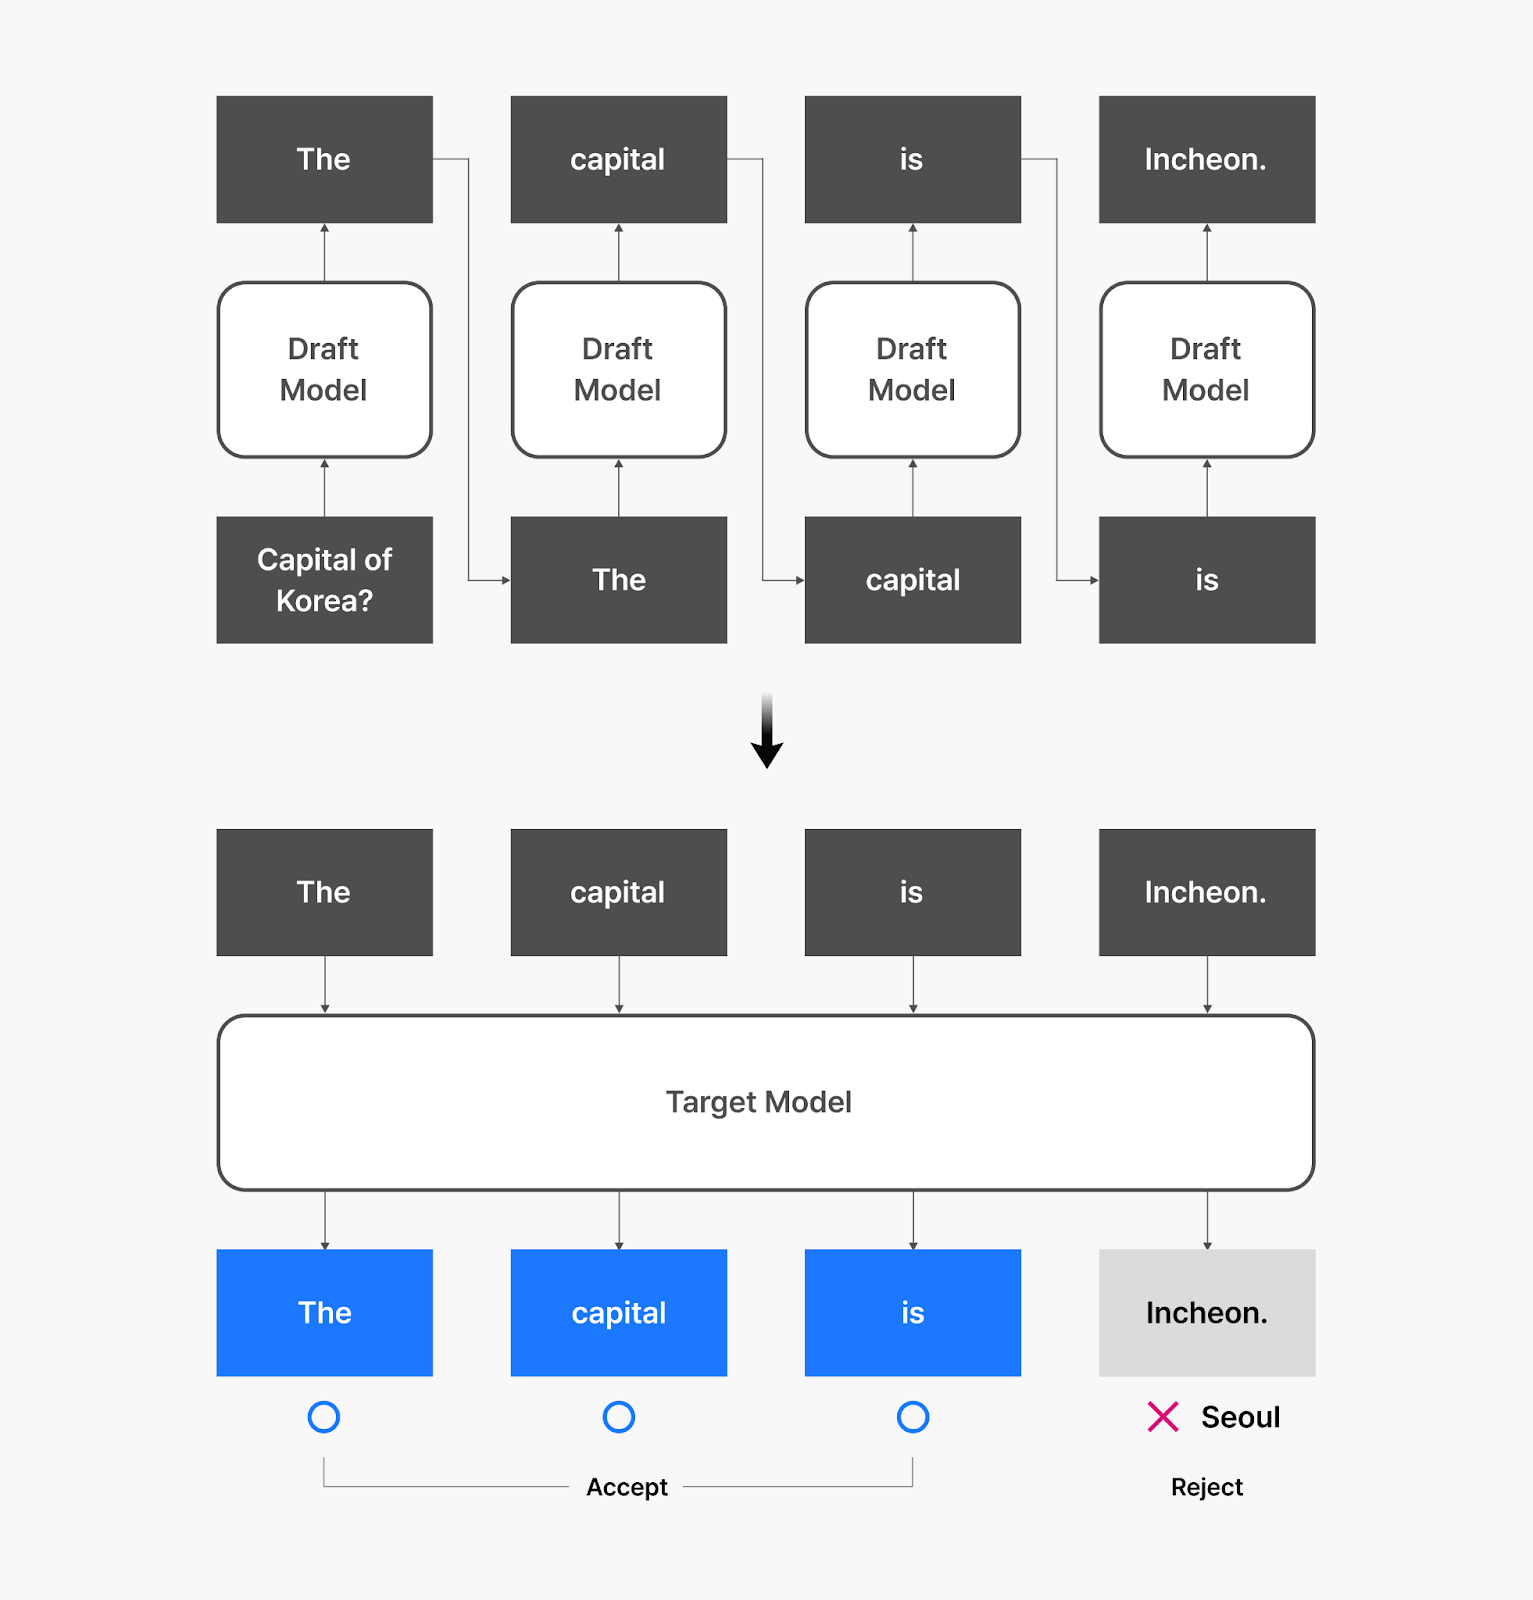
KV Caching and Speculative Decoding
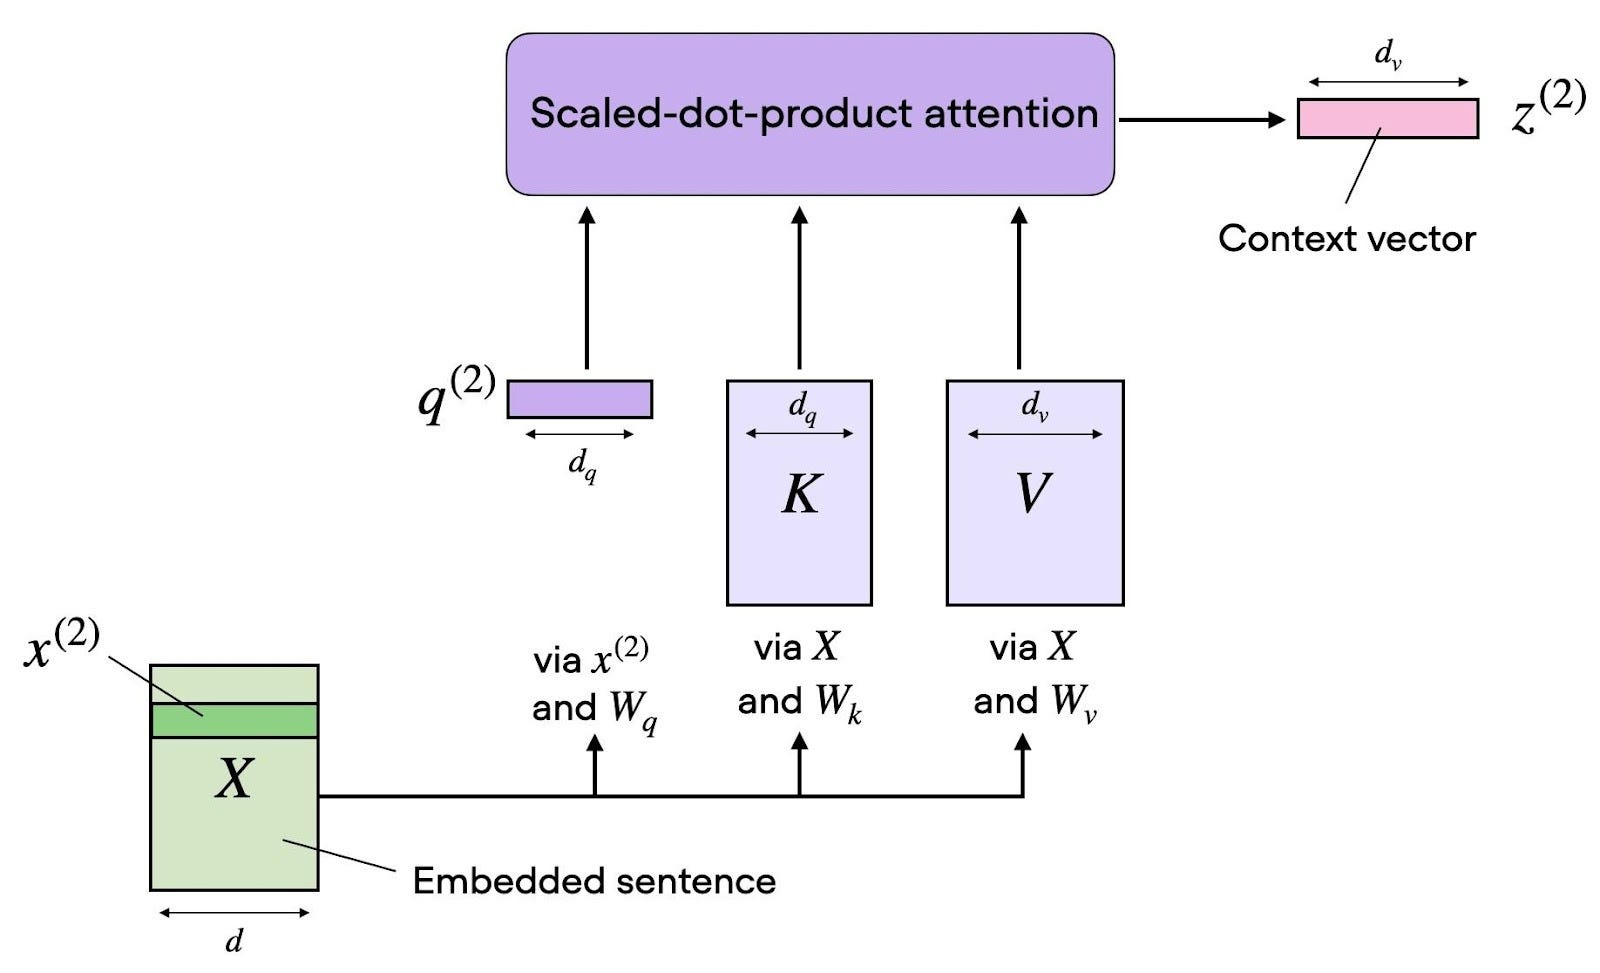
KV Caching and Speculative Decoding
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...
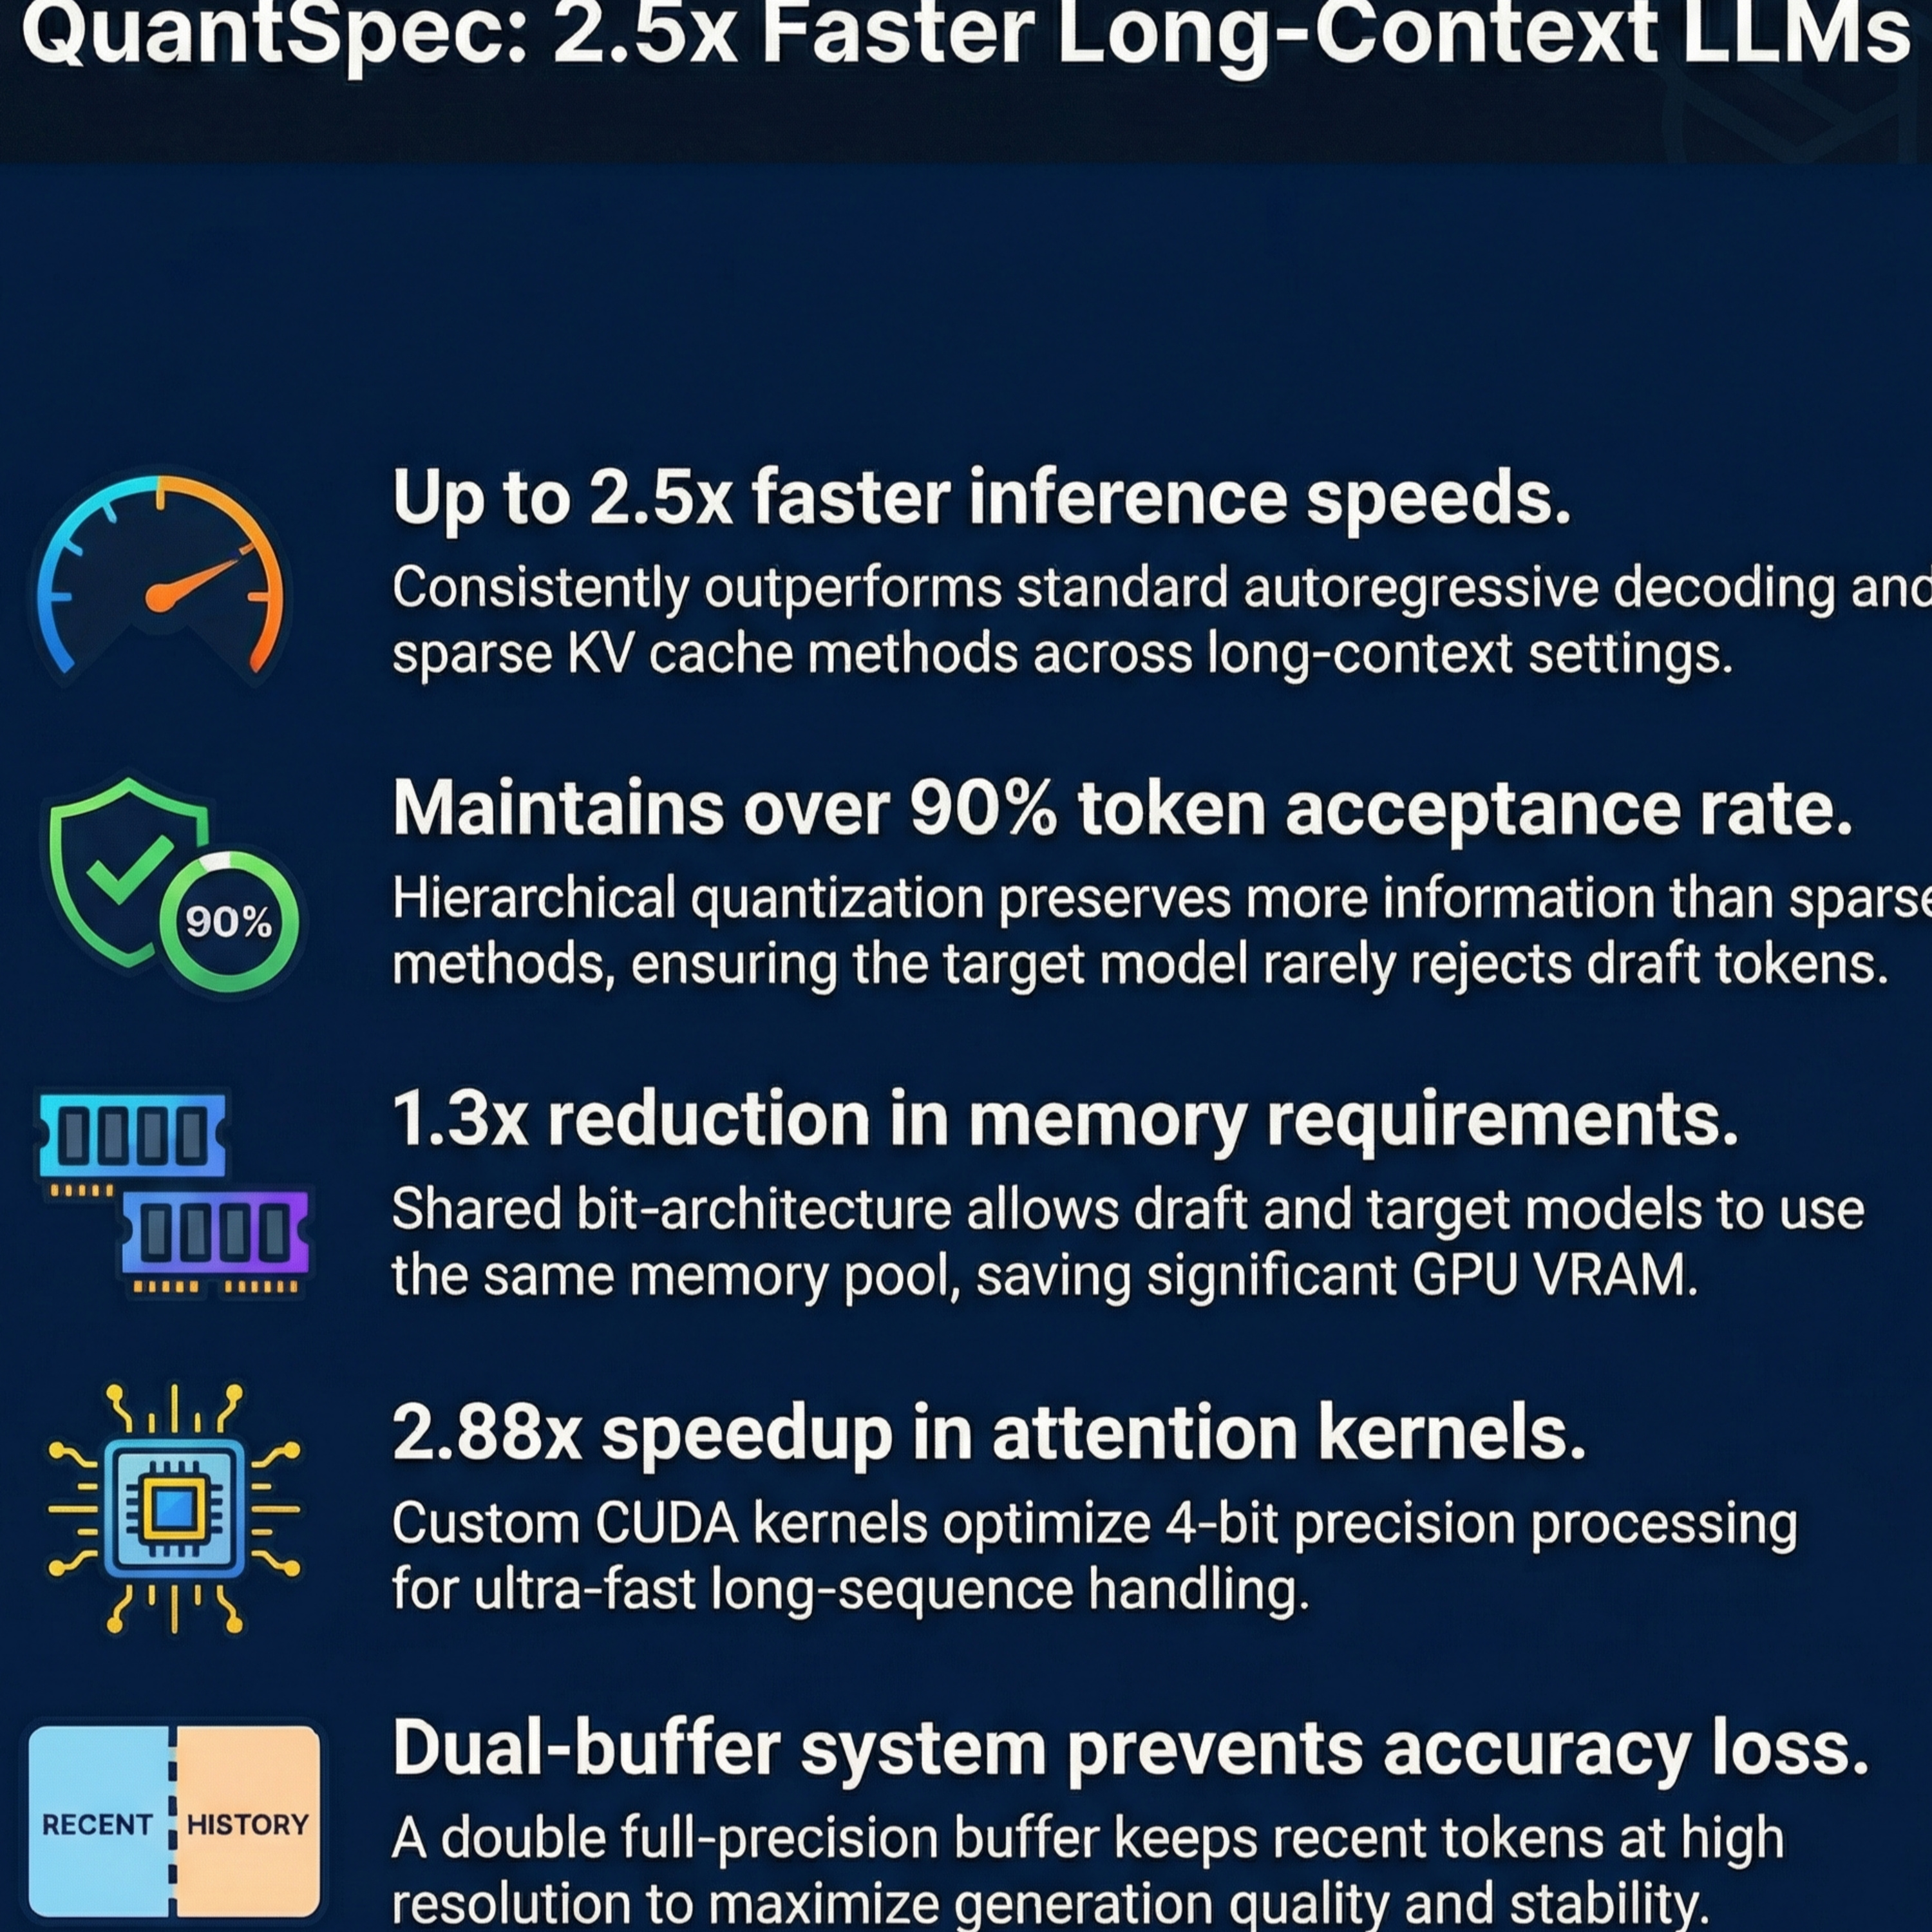
QuantSpec: Hierarchical KV Cache for Self-Speculative Decoding — AI ...
Advertisement Space (300x250)
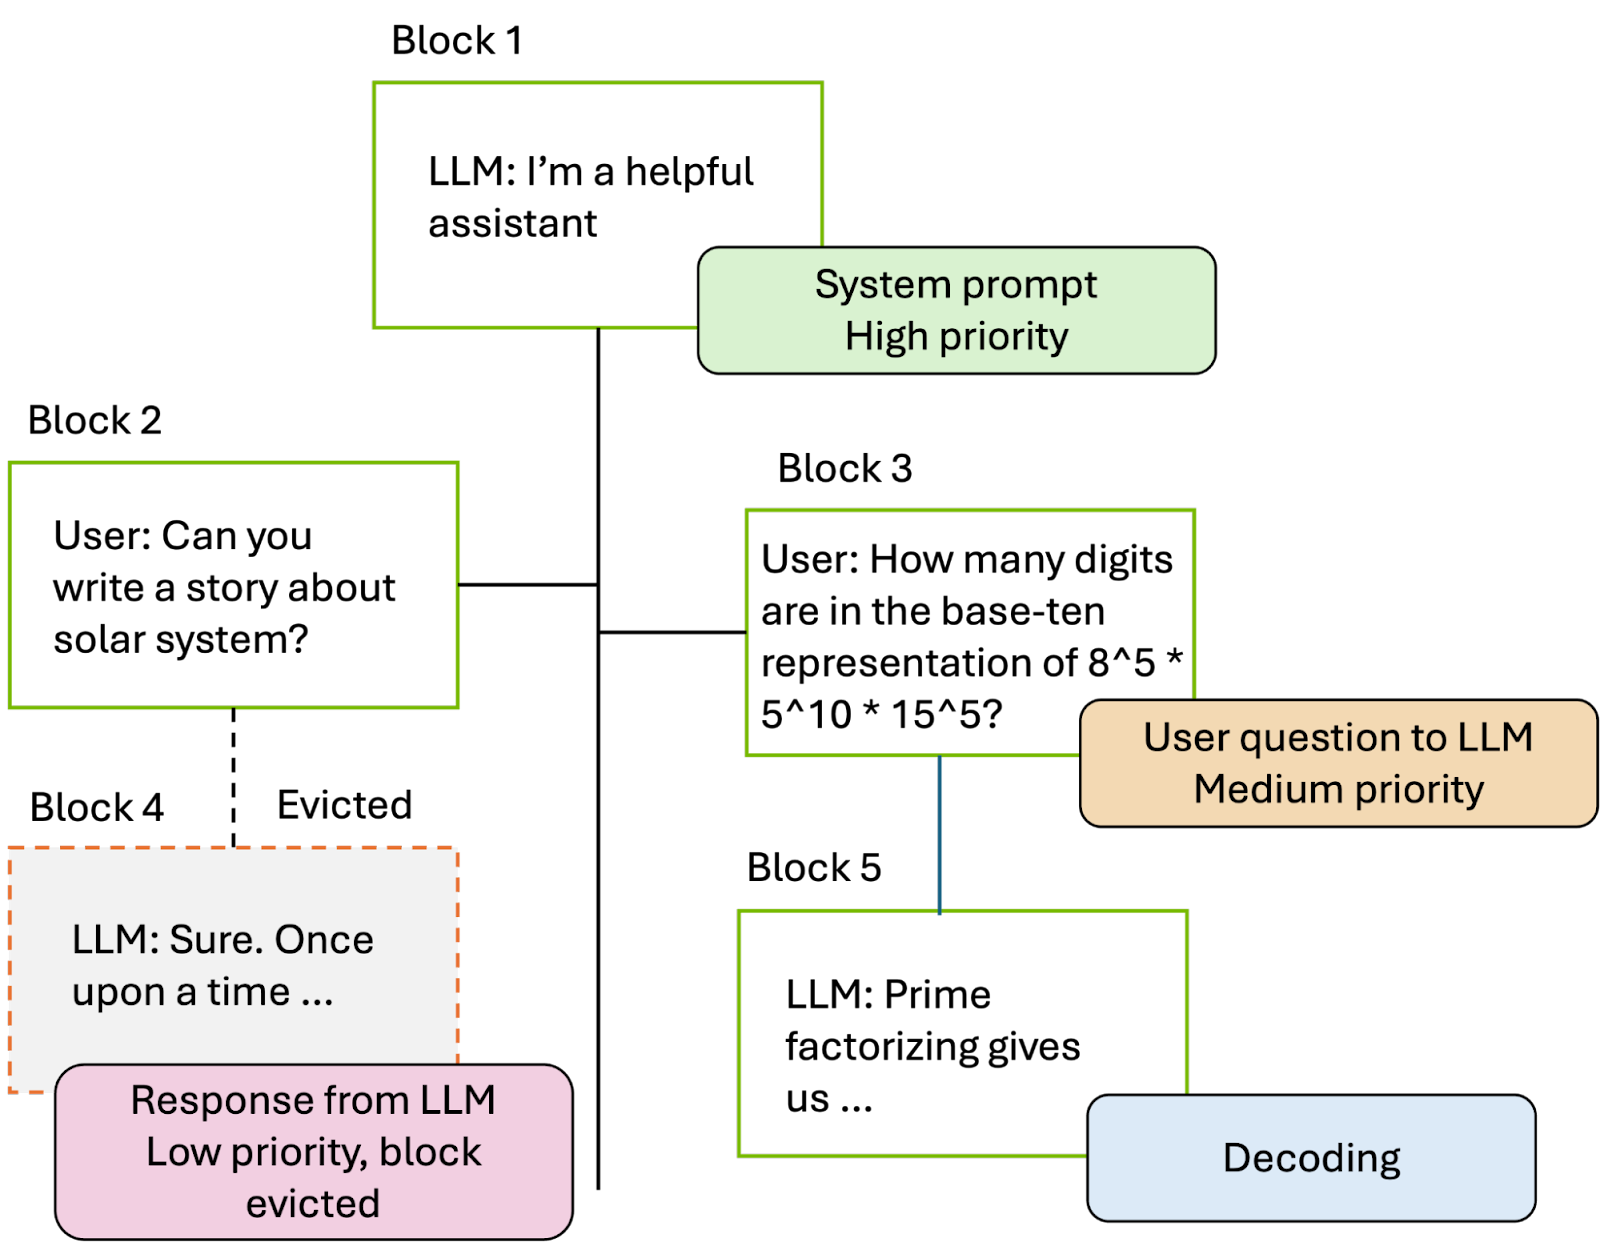
KV Caching and Speculative Decoding
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...
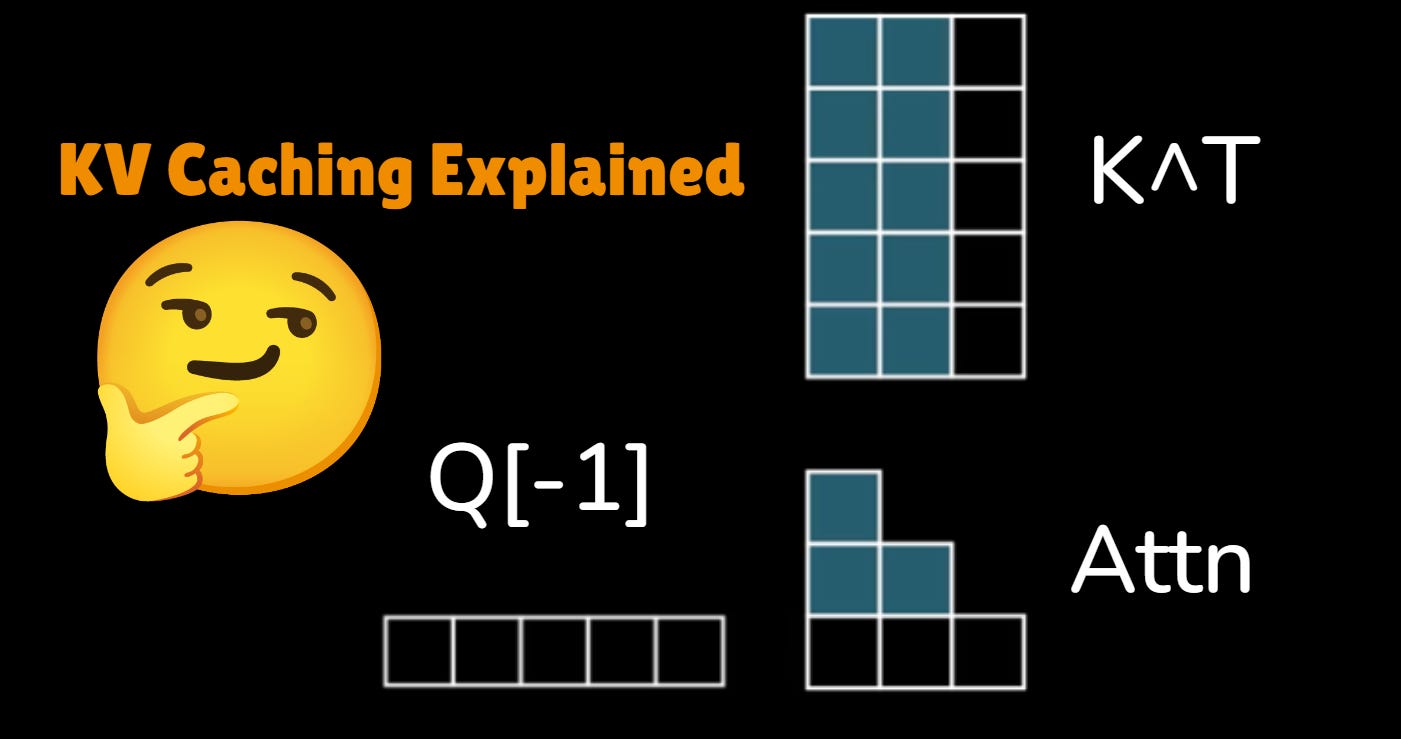
KV Caching and Speculative Decoding

Optimizing LLM Inference: KV Cache Quantization and Speculative ...
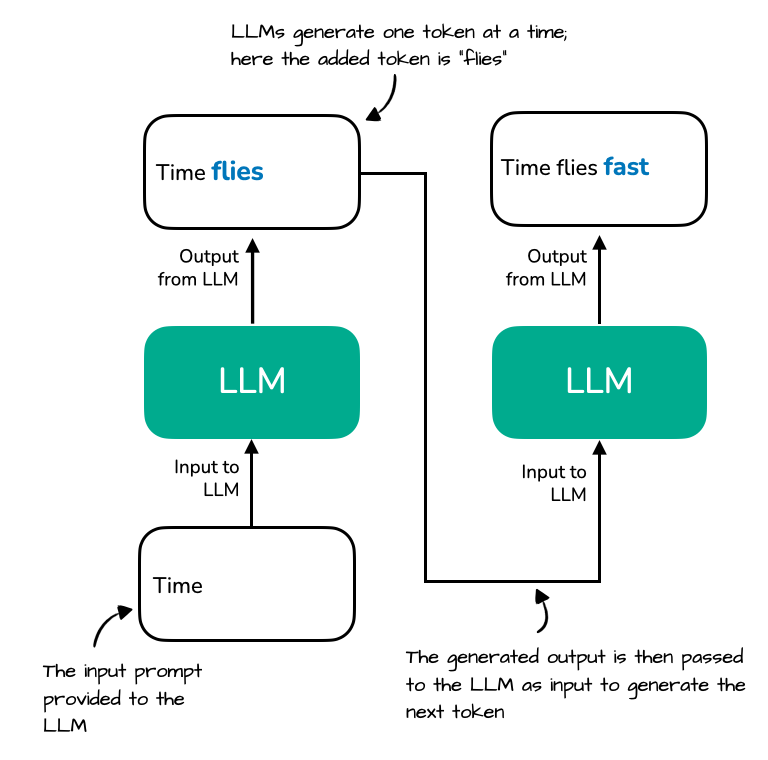
KV Caching and Speculative Decoding
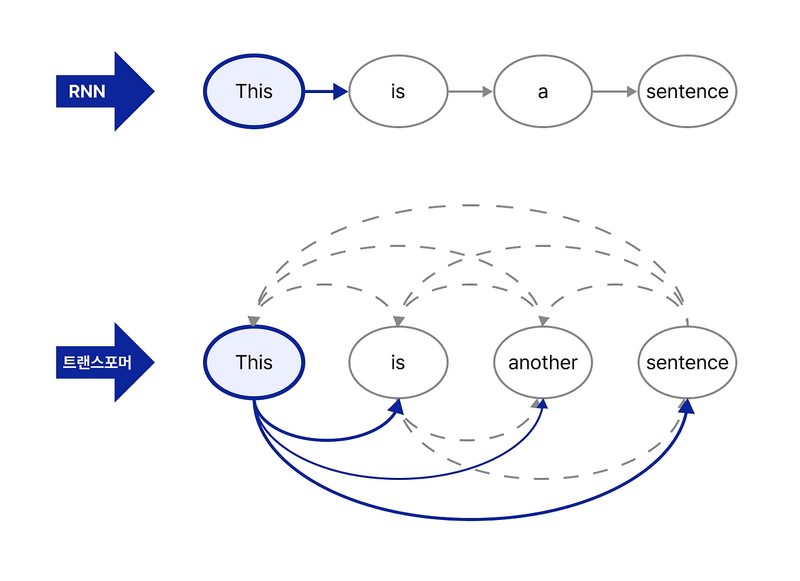
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...
Speculative KV Coding Achieves 4× Lossless Compression of LLM Cache ...
SpecCache: Speculative KV Cache Reuse for Efficient RAG Serving - ACL ...

Inference Optimization Design: KV Cache Compression, Speculative ...
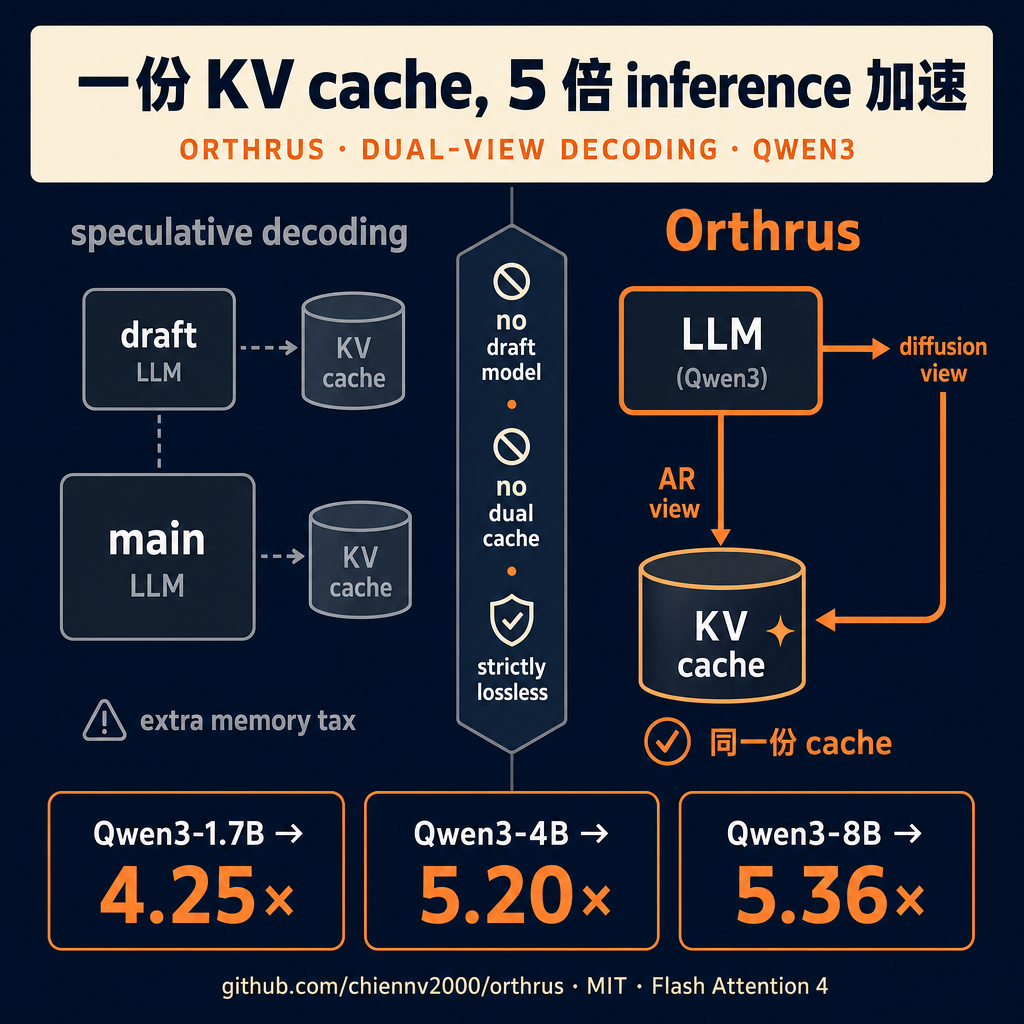
speculative decoding 这条 inference 加速路线,过去一年是默认选择——但有人在用另一种思路把 5 倍速度搞出来 ...
Advertisement Space (336x280)

Revolutionizing AI Efficiency: Breakthroughs in KV Cache Compression ...

🚀 Fast and accurate Speculative Decoding for Long Context? Excited to ...

Revolutionizing AI Efficiency: Breakthroughs in KV Cache Compression ...

When Hidden States Drift: Can KV Caches Rescue Long-Range Speculative ...
Speculative KV Cache: Definition & Optimization | Inference Systems
Speculative Decoding (EAGLE and Variants) | kvcache-ai/sglang | DeepWiki
BlockManager and KV Cache Allocation | limei1221/nano-vllm-speculative ...
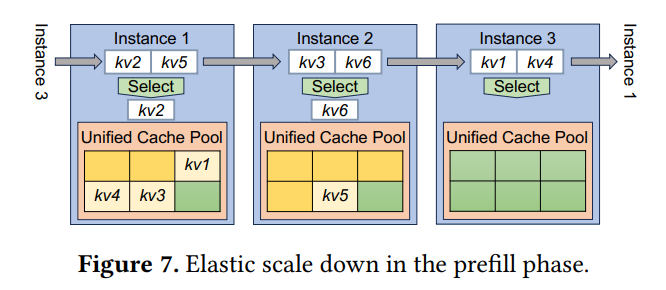
LoongServe 论文解读:prefill/decode 分离、弹性并行、零 KV Cache 迁移开销 - 知乎
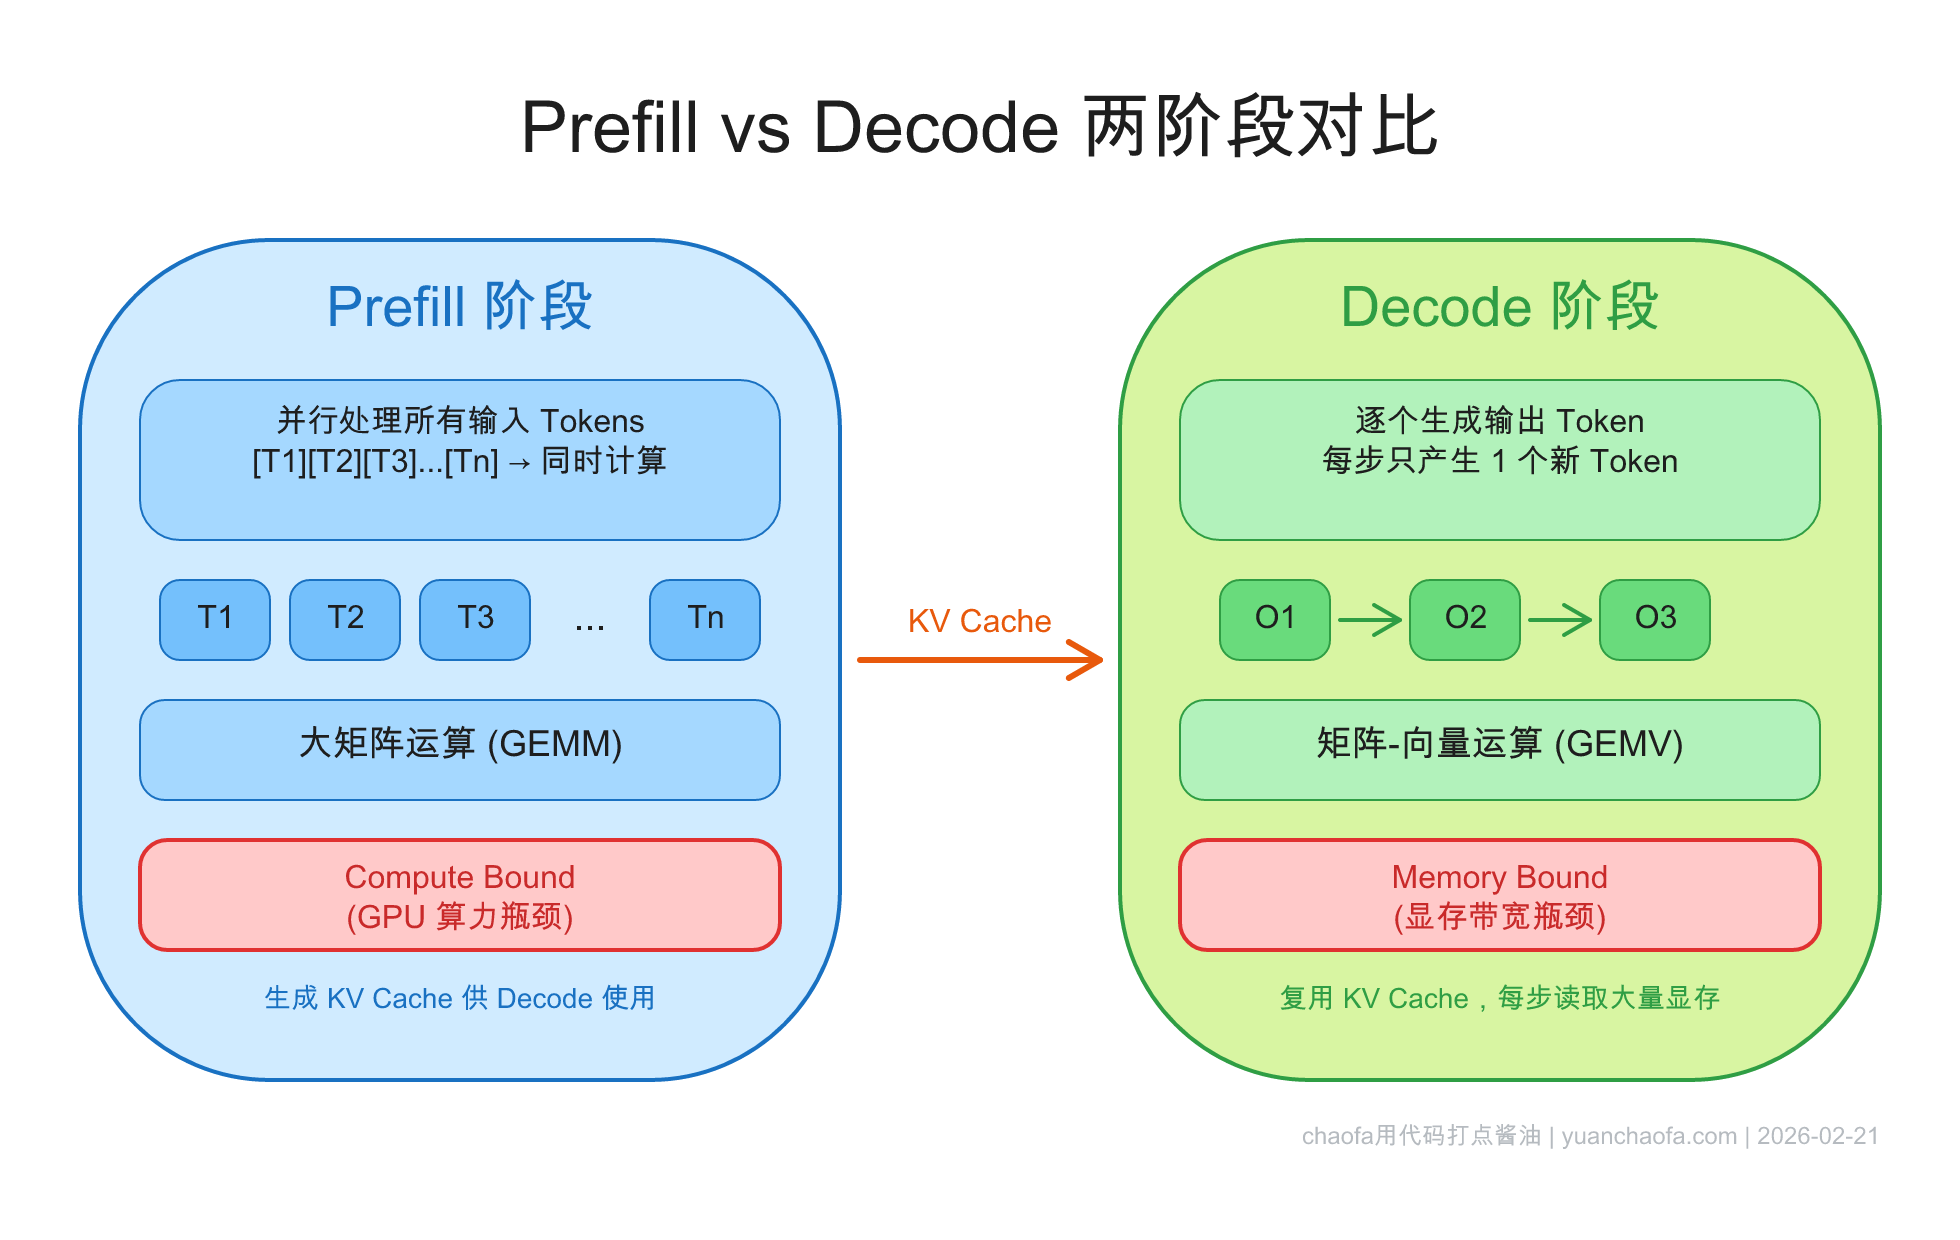
理解 KV Cache 与 Prompt Caching:LLM 推理加速的核心机制 | chaofa用代码打点酱油
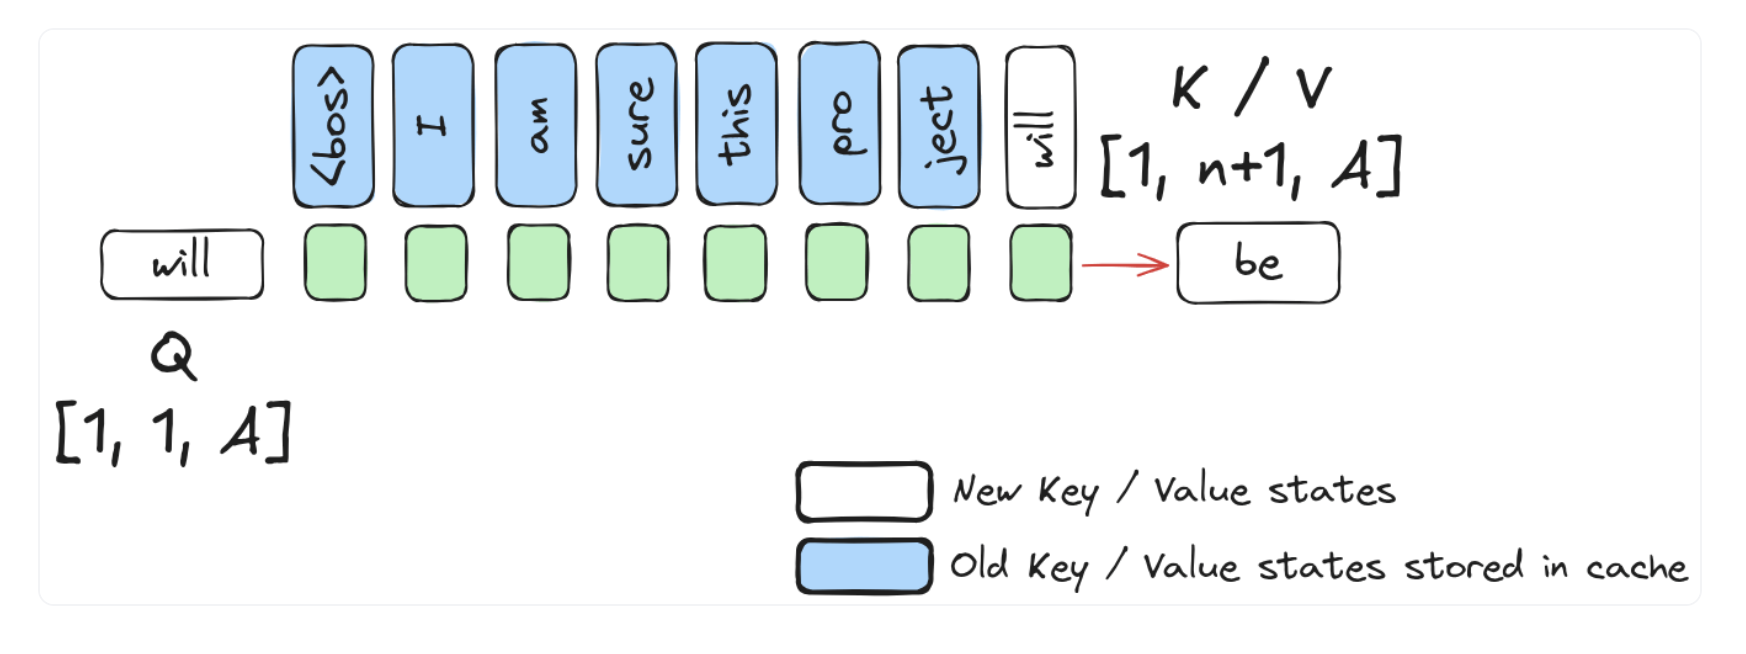
Speculative Decoding Tutorial | Pramodith Dissects
Advertisement Space (336x280)
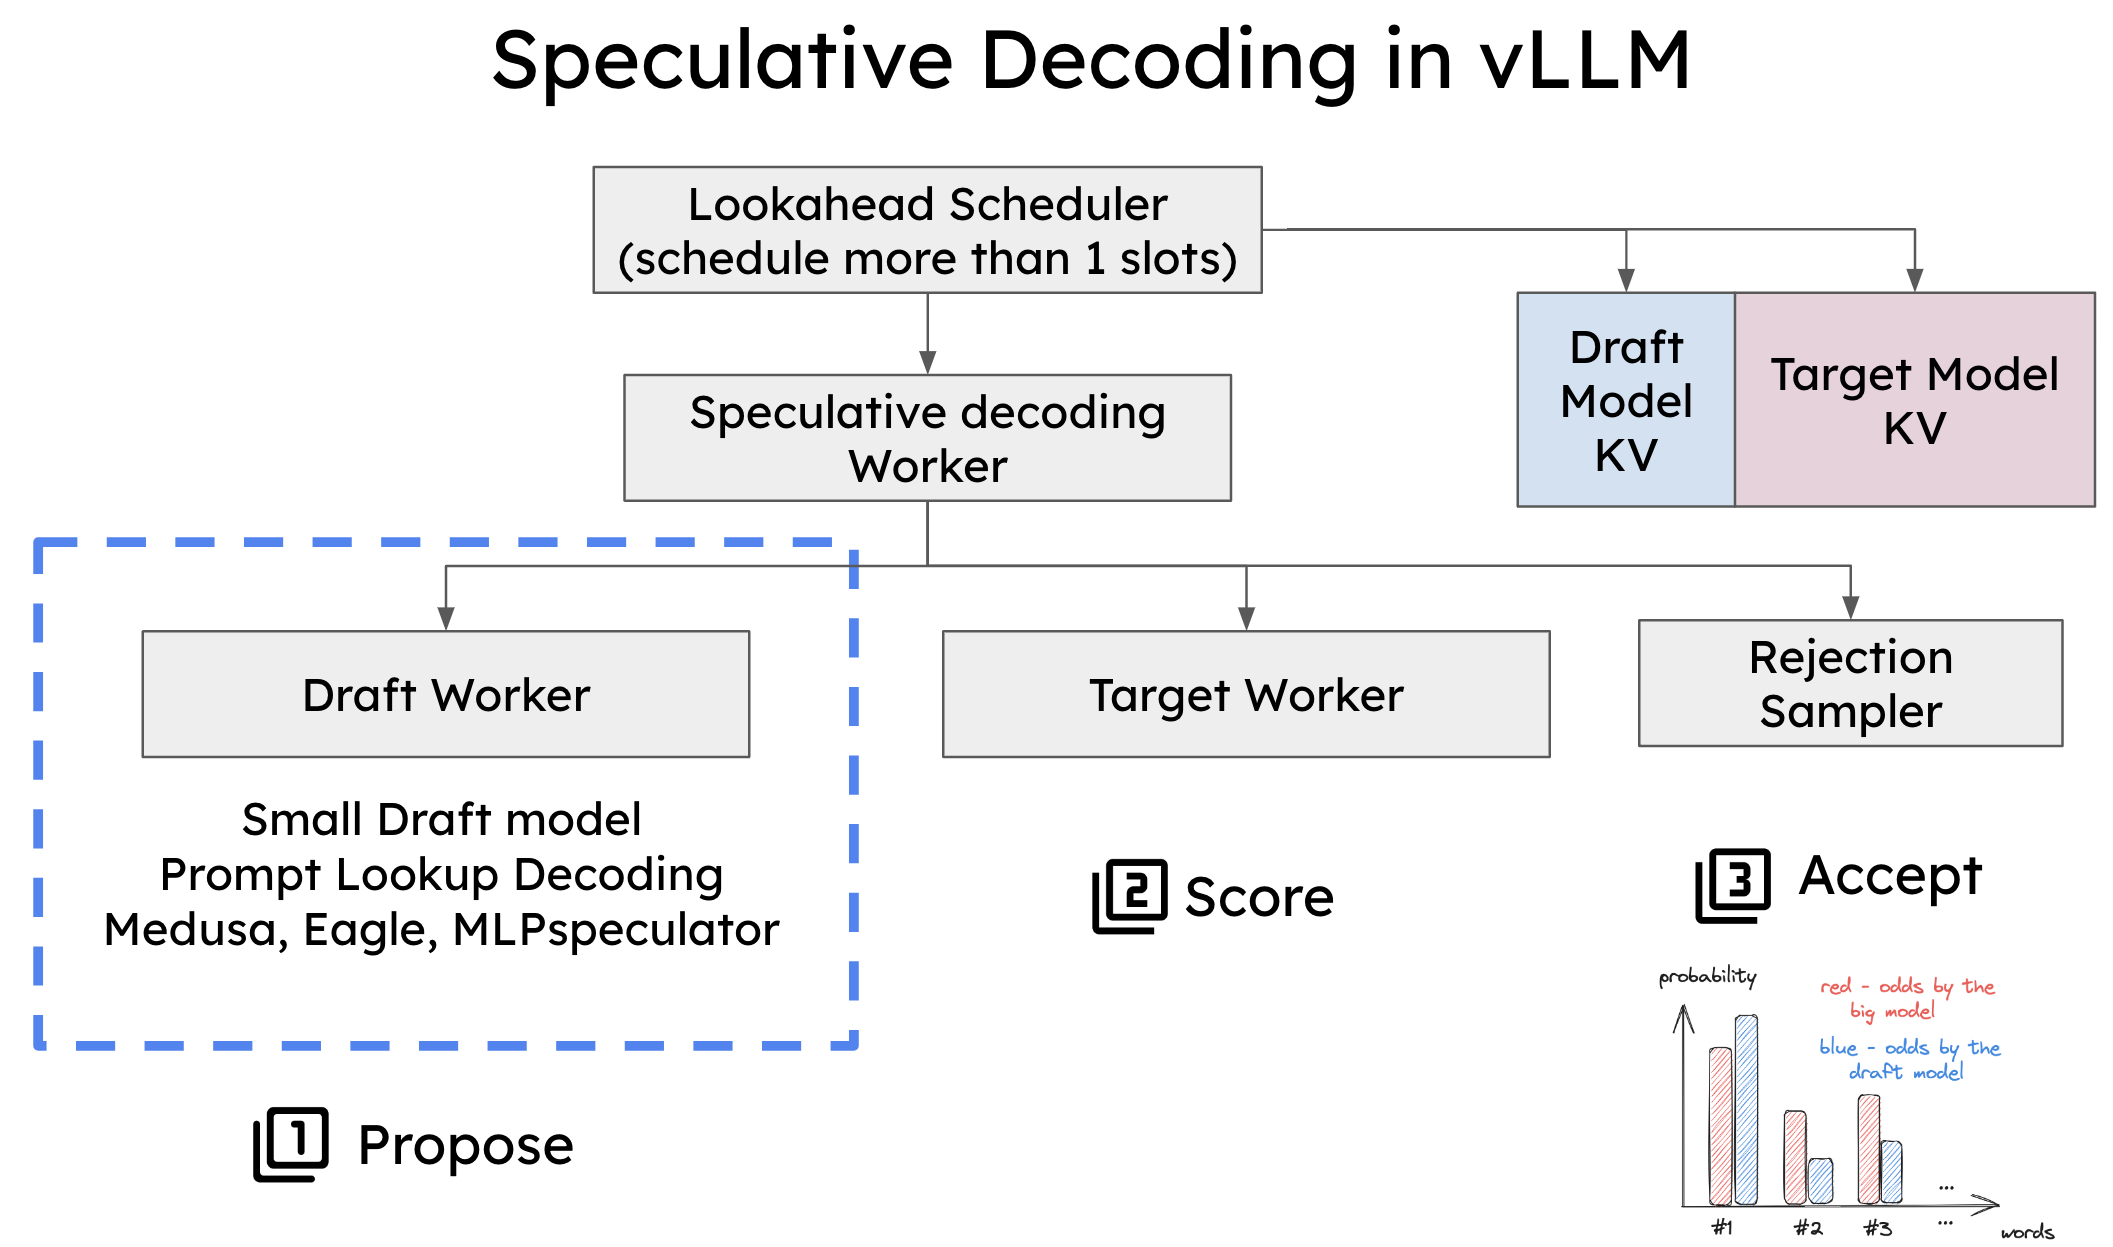
Speculative Decoding in vLLM | OpenLM.ai

Self-Speculative Decoding Implementation: LayerSkip Transformer - Clay ...

Speculative Decoding - Making Language Models Generate Faster Without ...
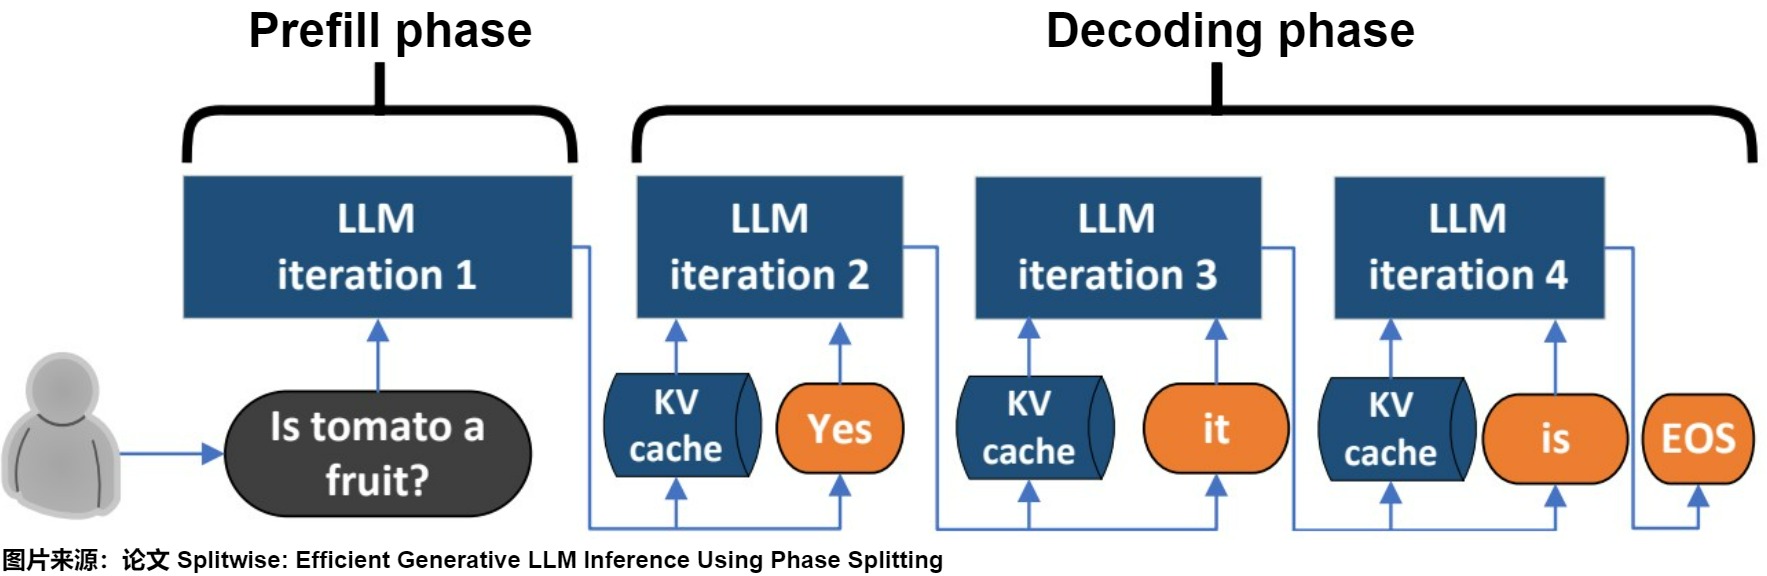
探秘Transformer系列之(20)--- KV Cache - 罗西的思考 - 博客园

LLM Jargons Explained: Part 4 - KV Cache - YouTube
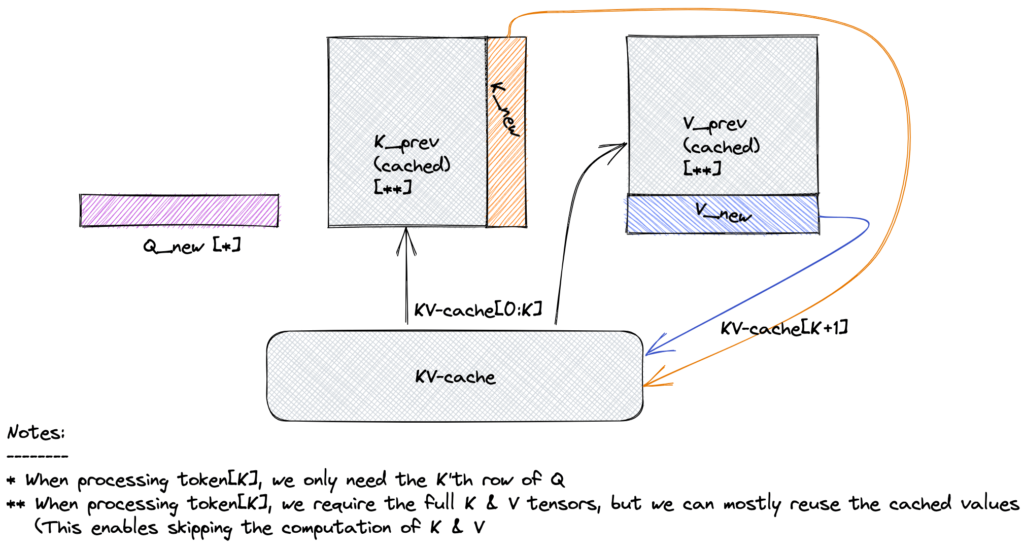
KV Cache in Transformer Models - Data Magic AI Blog