
Llm 25 Speculative Decoding Kv Cache
LLM 推理优化全指南:从 KV Cache 到 Speculative Decoding | AI 实战派 · 从技术到赚钱

整合 Speculative Decoding 和 KV Cache 之實作筆記 - Clay-Technology World
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...

Optimizing LLM Inference: KV Cache Quantization and Speculative ...
Speculative KV Coding Achieves 4× Lossless Compression of LLM Cache ...
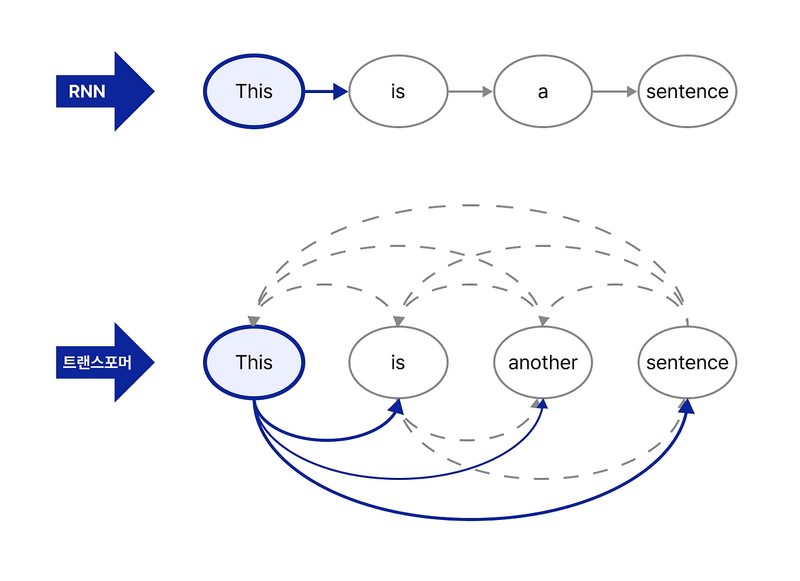
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...

RelayCaching: Accelerating LLM Collaboration via Decoding KV Cache Reuse
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...

RelayCaching: Accelerating LLM Collaboration via Decoding KV Cache Reuse
Boost LLM Inference: Optimize Speculative Decoding, Batching, KV Cache ...
Advertisement Space (300x250)

LLM Inference Bottleneck: KV Cache vs Model Weights | Vinjam ...
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...
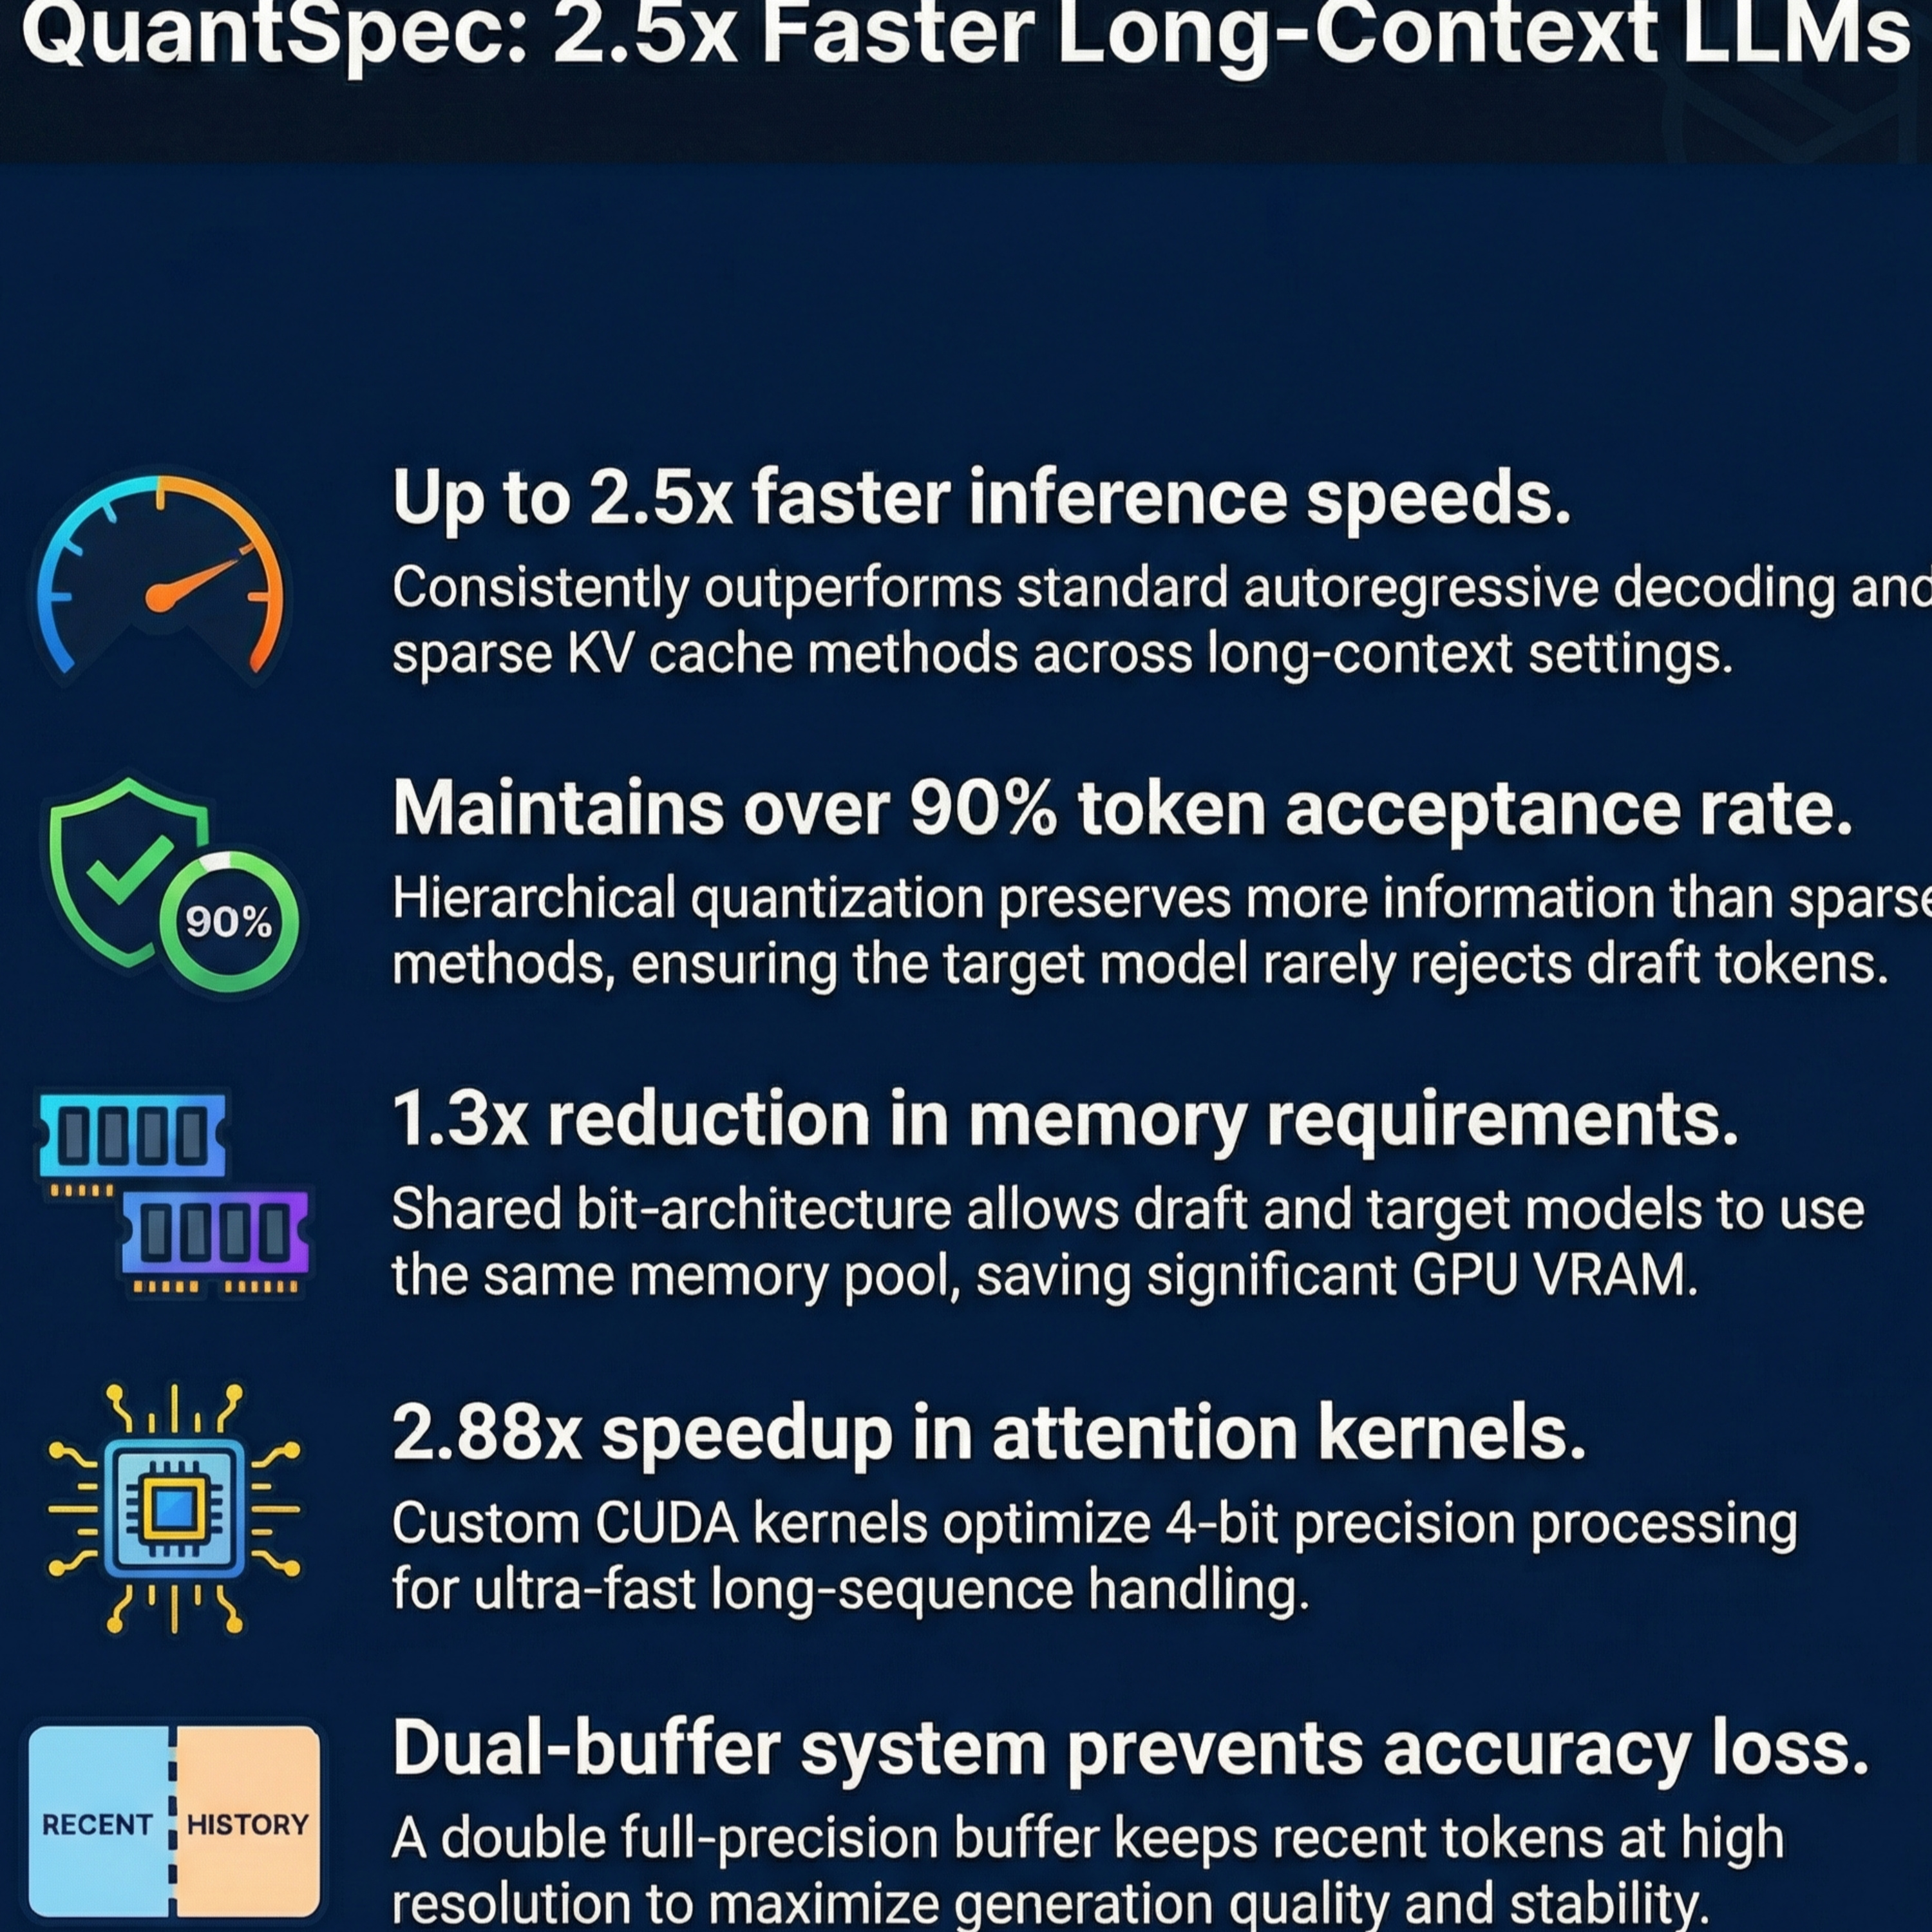
QuantSpec: Hierarchical KV Cache for Self-Speculative Decoding — AI ...
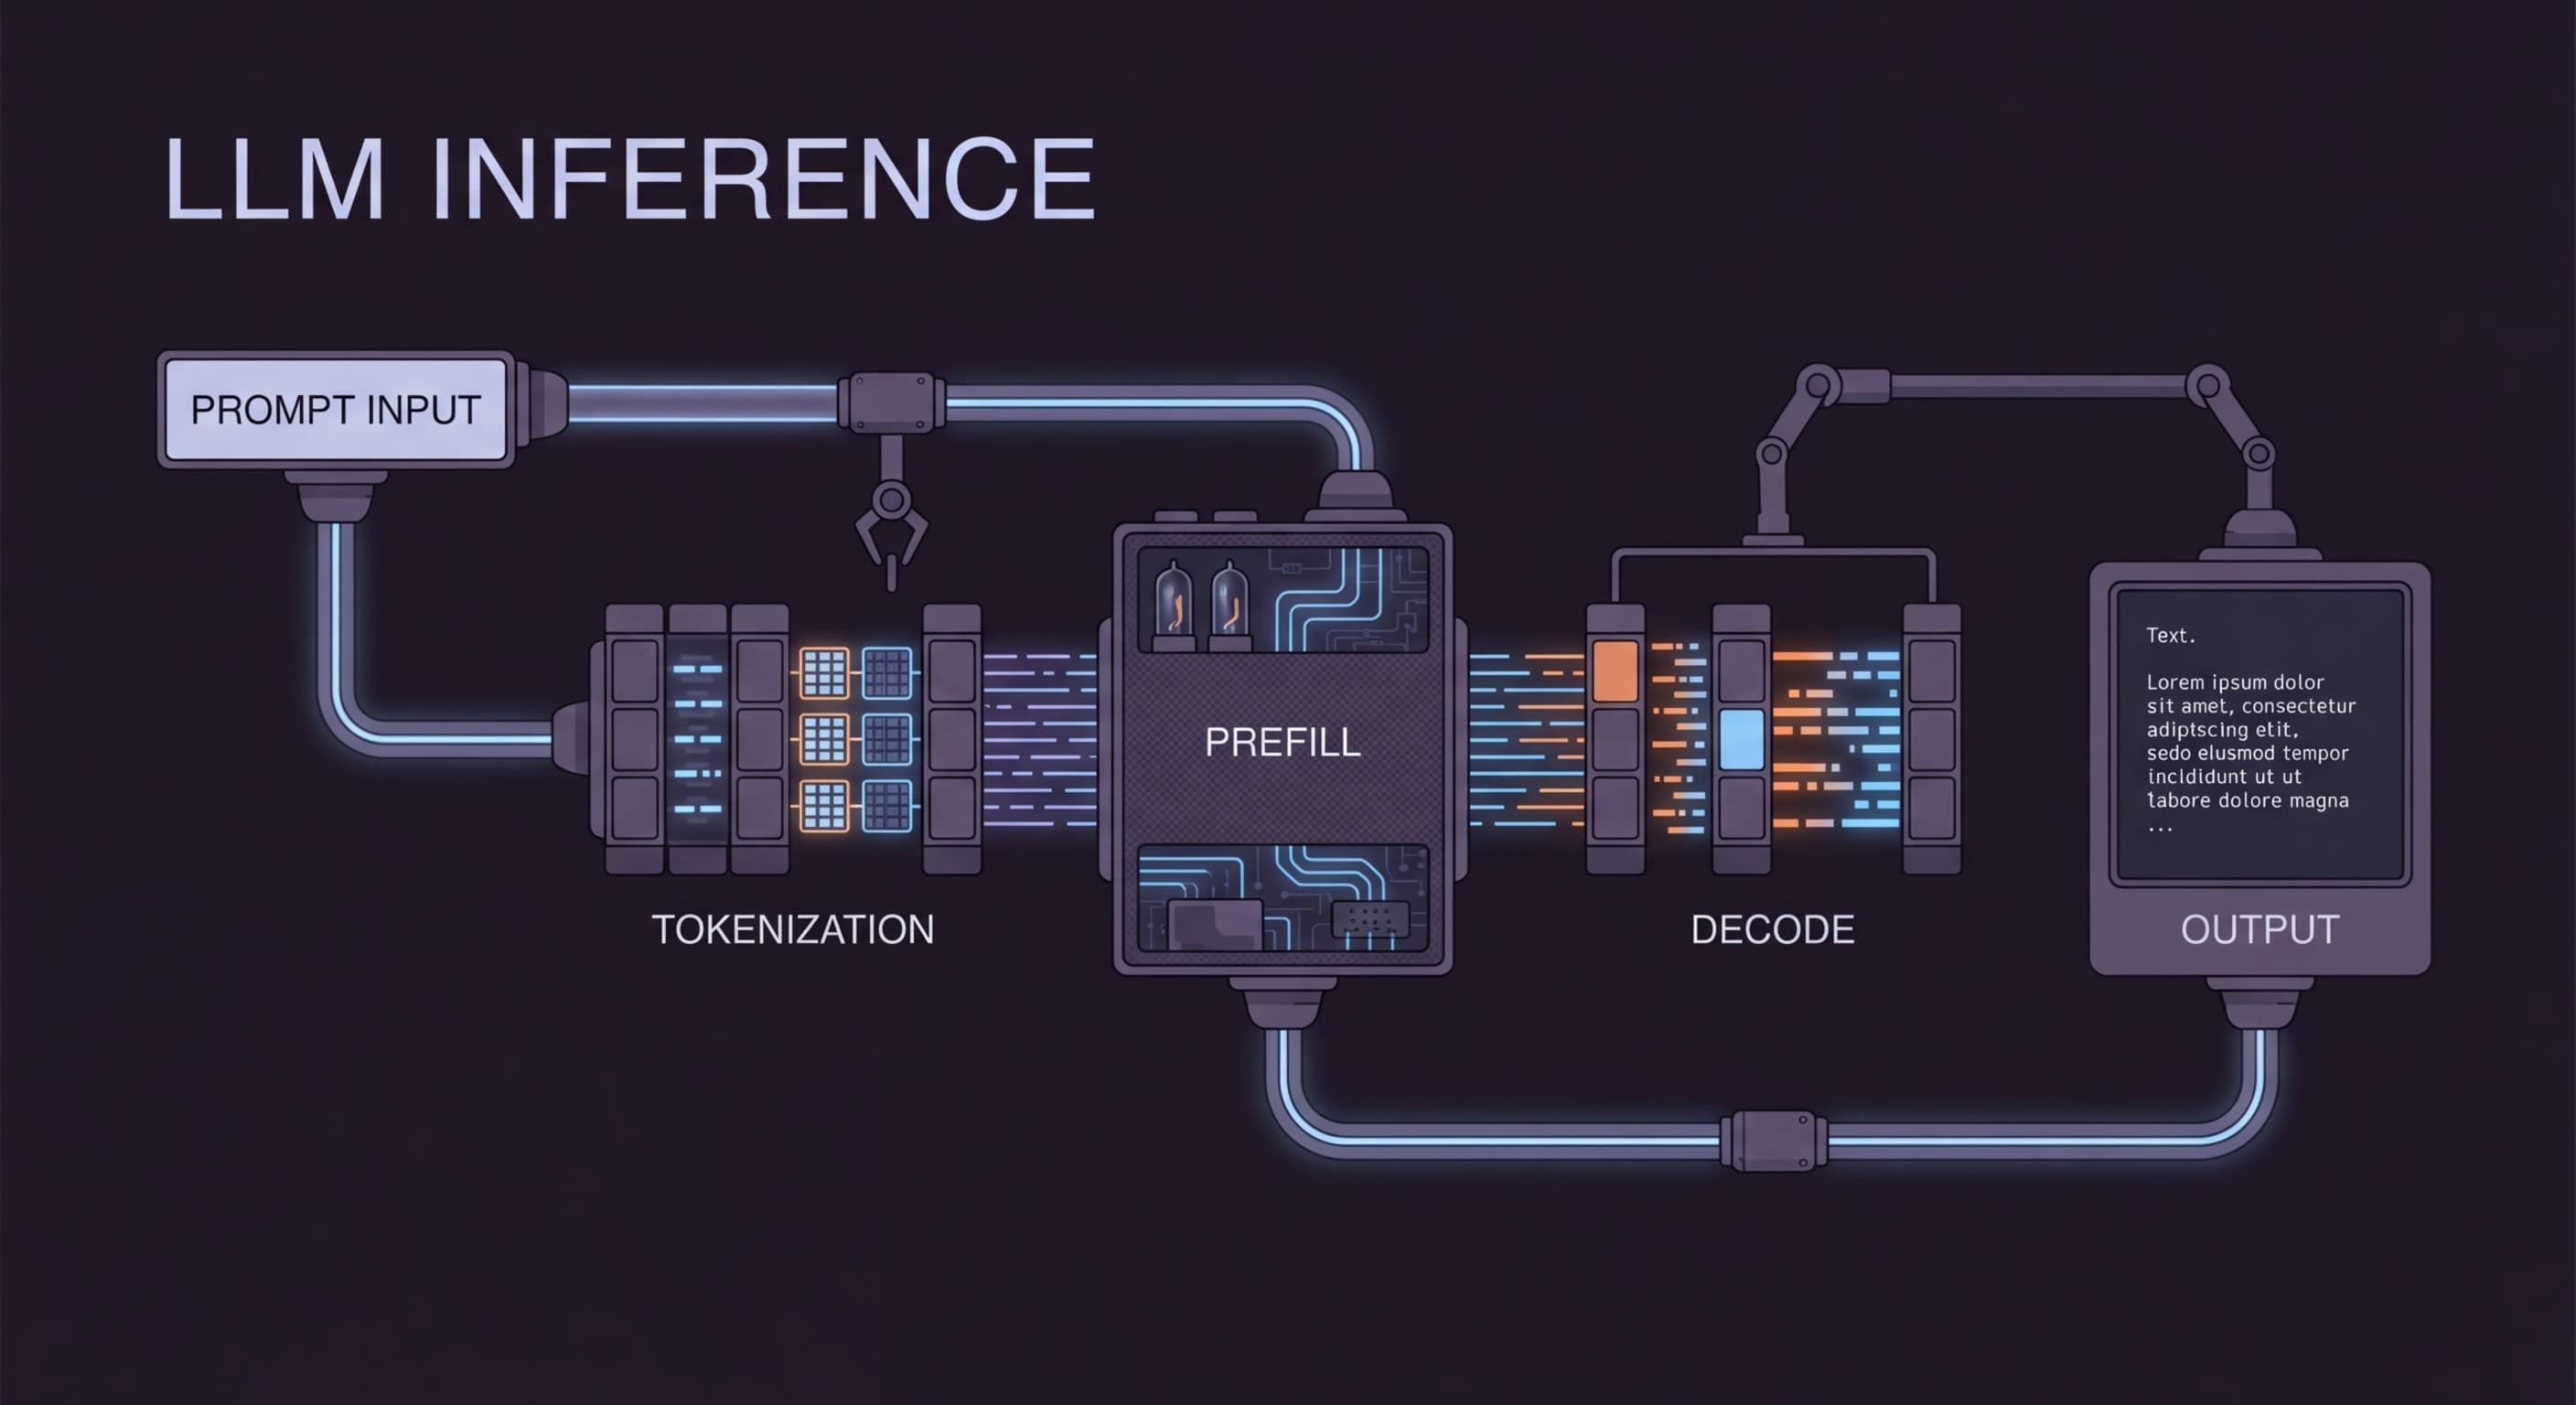
LLM Inference: Prefill, Decode, KV Cache & Cost Guide (2026) | Morph

ClusterKV: Manipulating LLM KV Cache in Semantic Space for Recallable ...
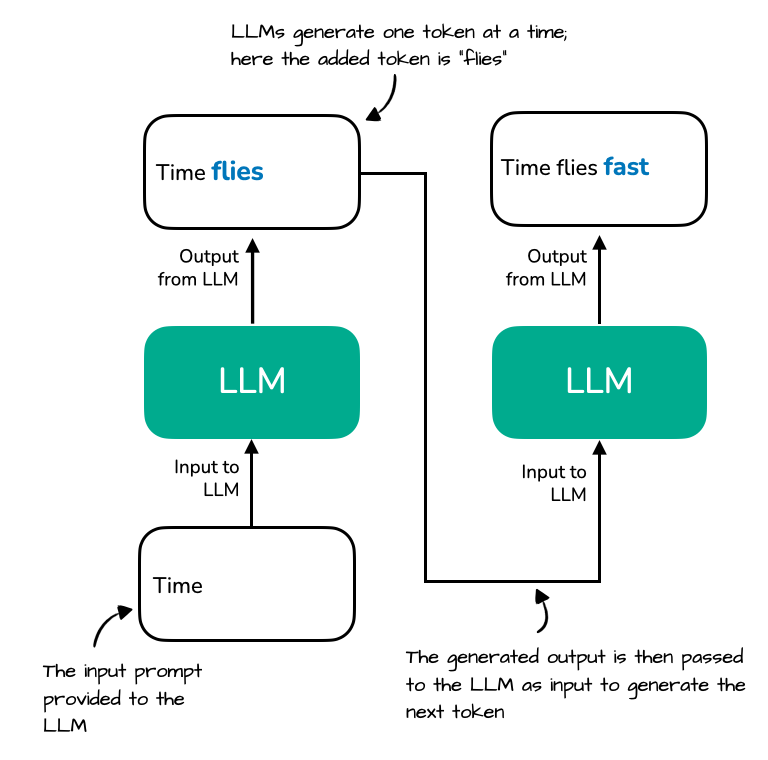
KV Caching and Speculative Decoding

FreeKV: Boosting KV Cache Retrieval for Efficient LLM Inference
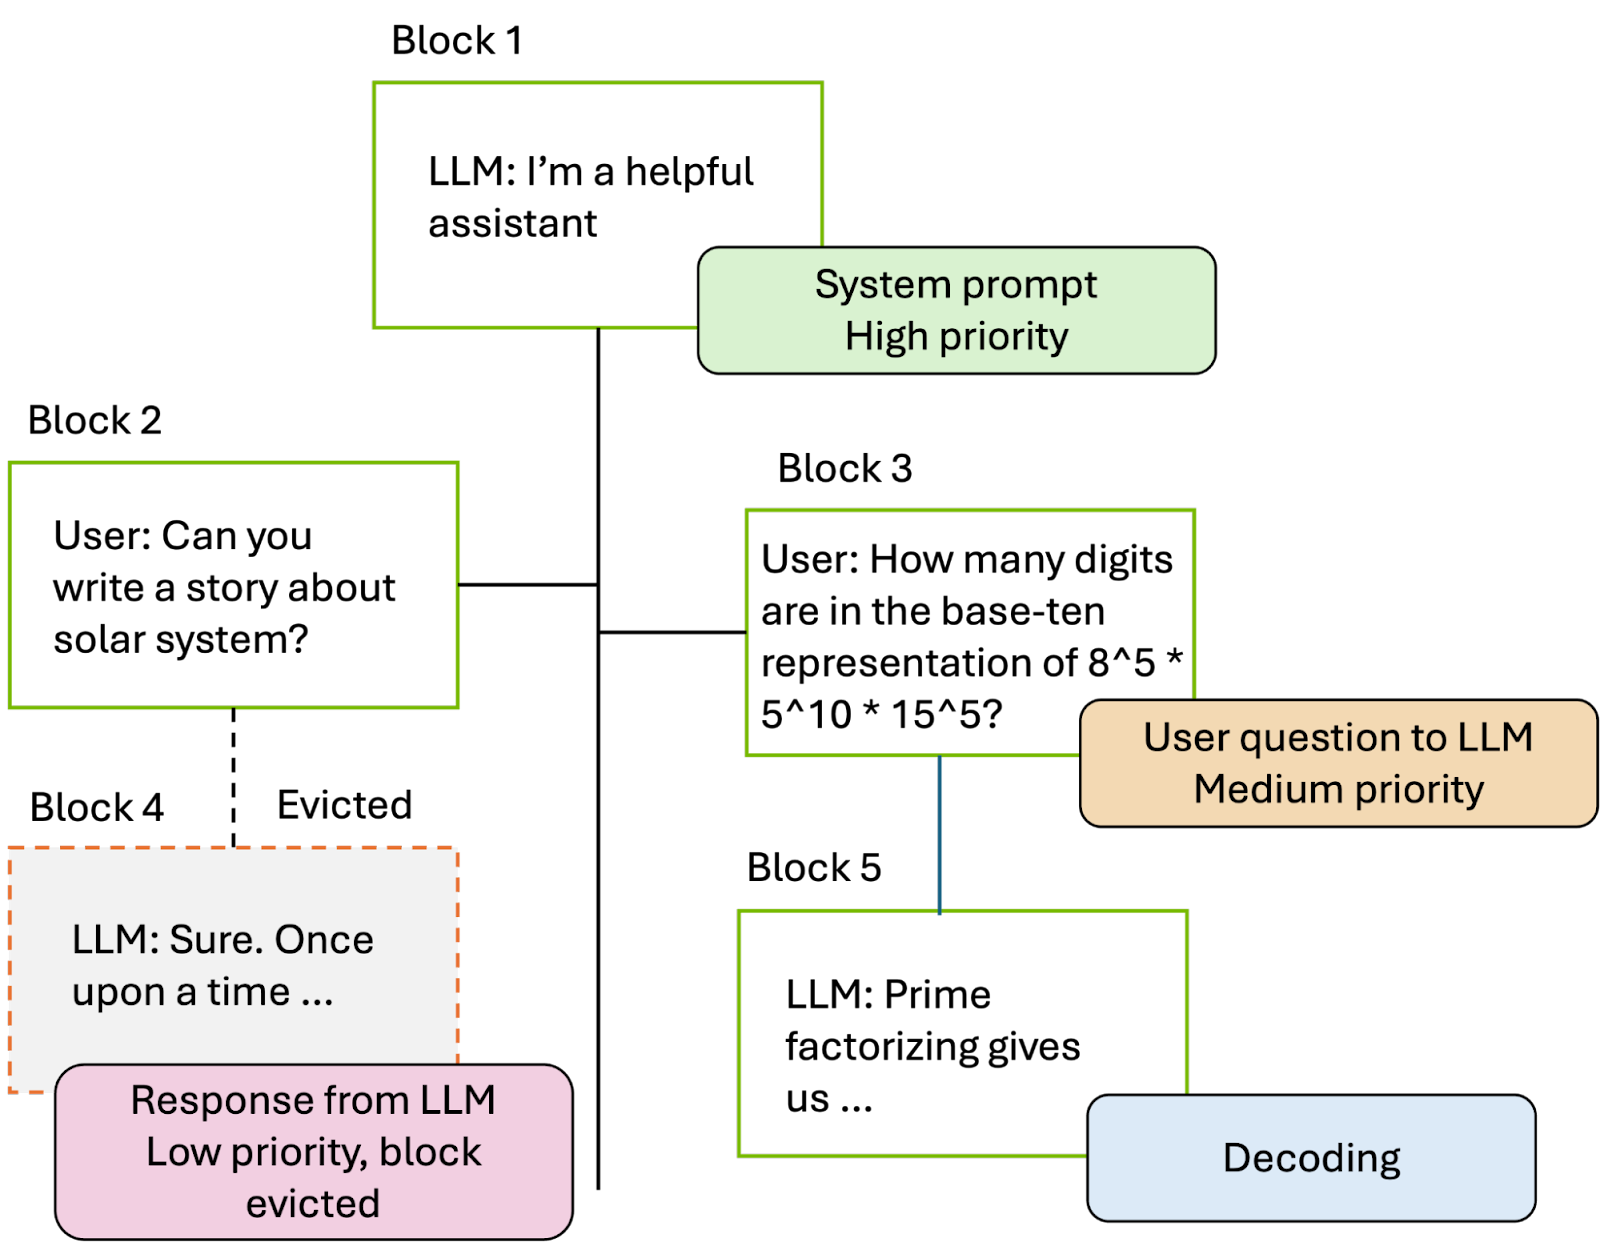
KV Caching and Speculative Decoding

KV Cache Offload Accelerates LLM Inference - NADDOD Blog

LLM inference optimization: Architecture, KV cache and Flash attention ...
Advertisement Space (336x280)
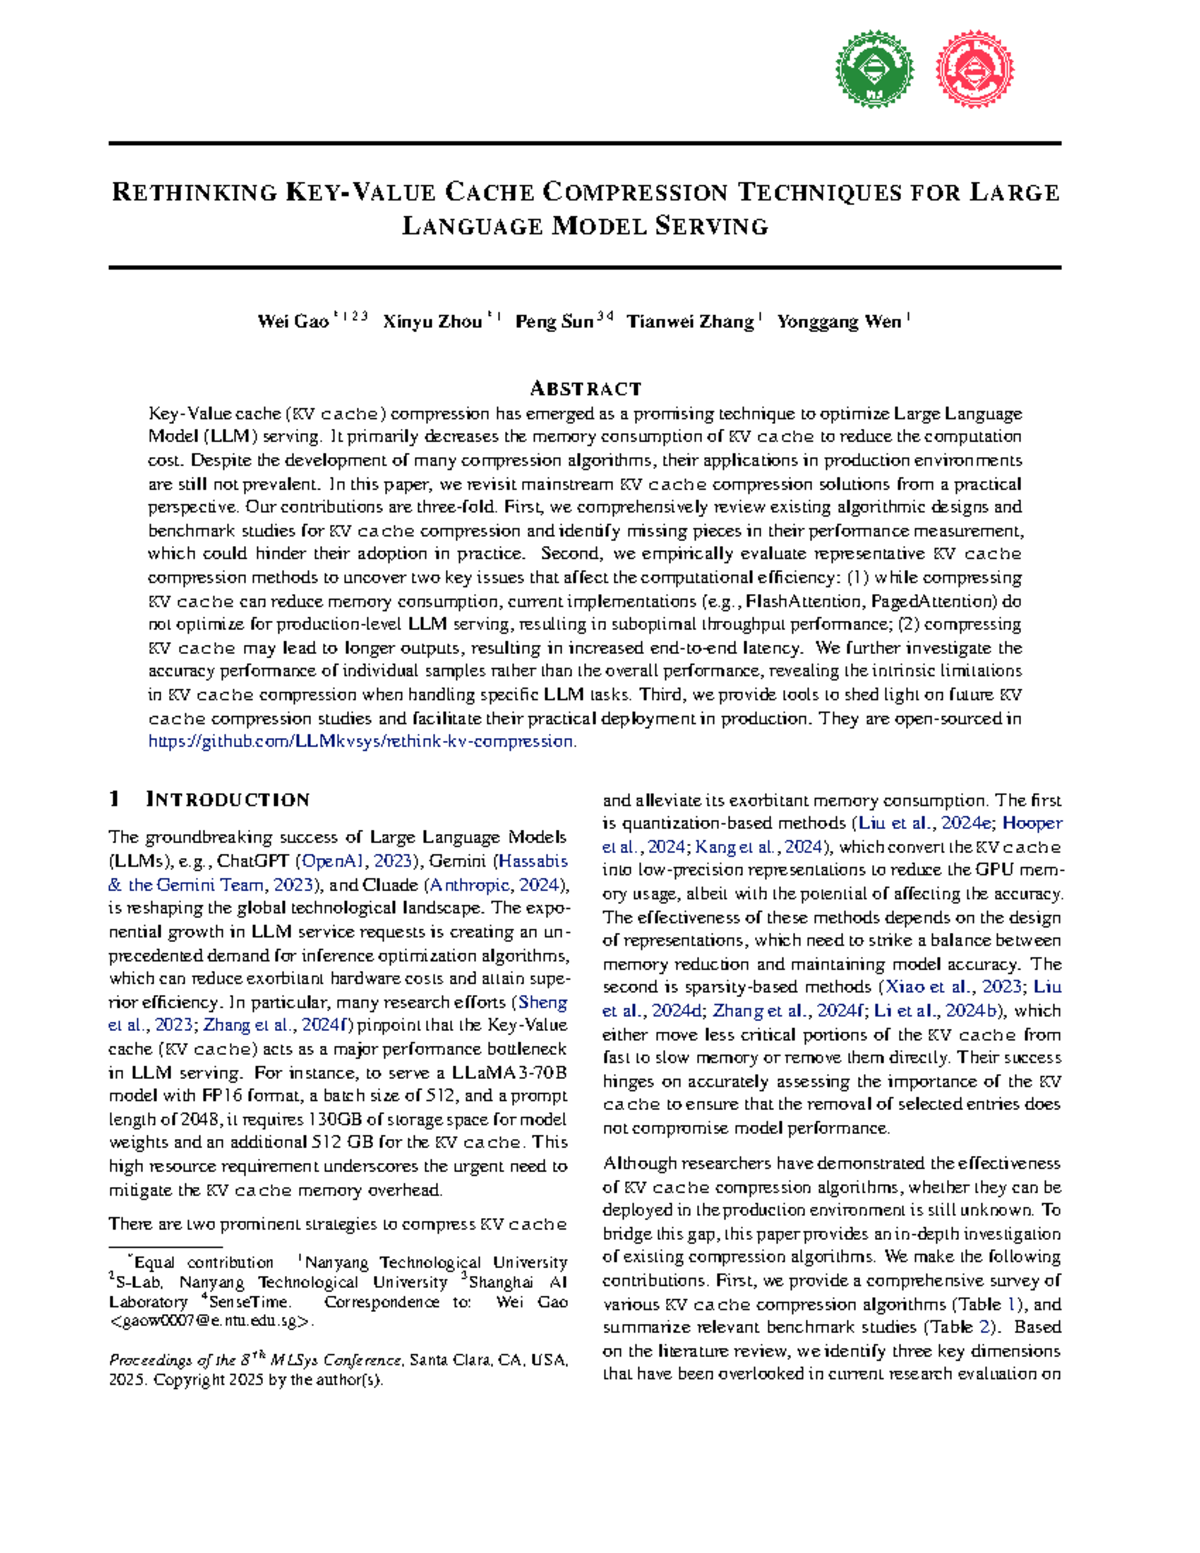
Rethinking KV Cache Compression Techniques for LLM Serving (25-mlsys ...
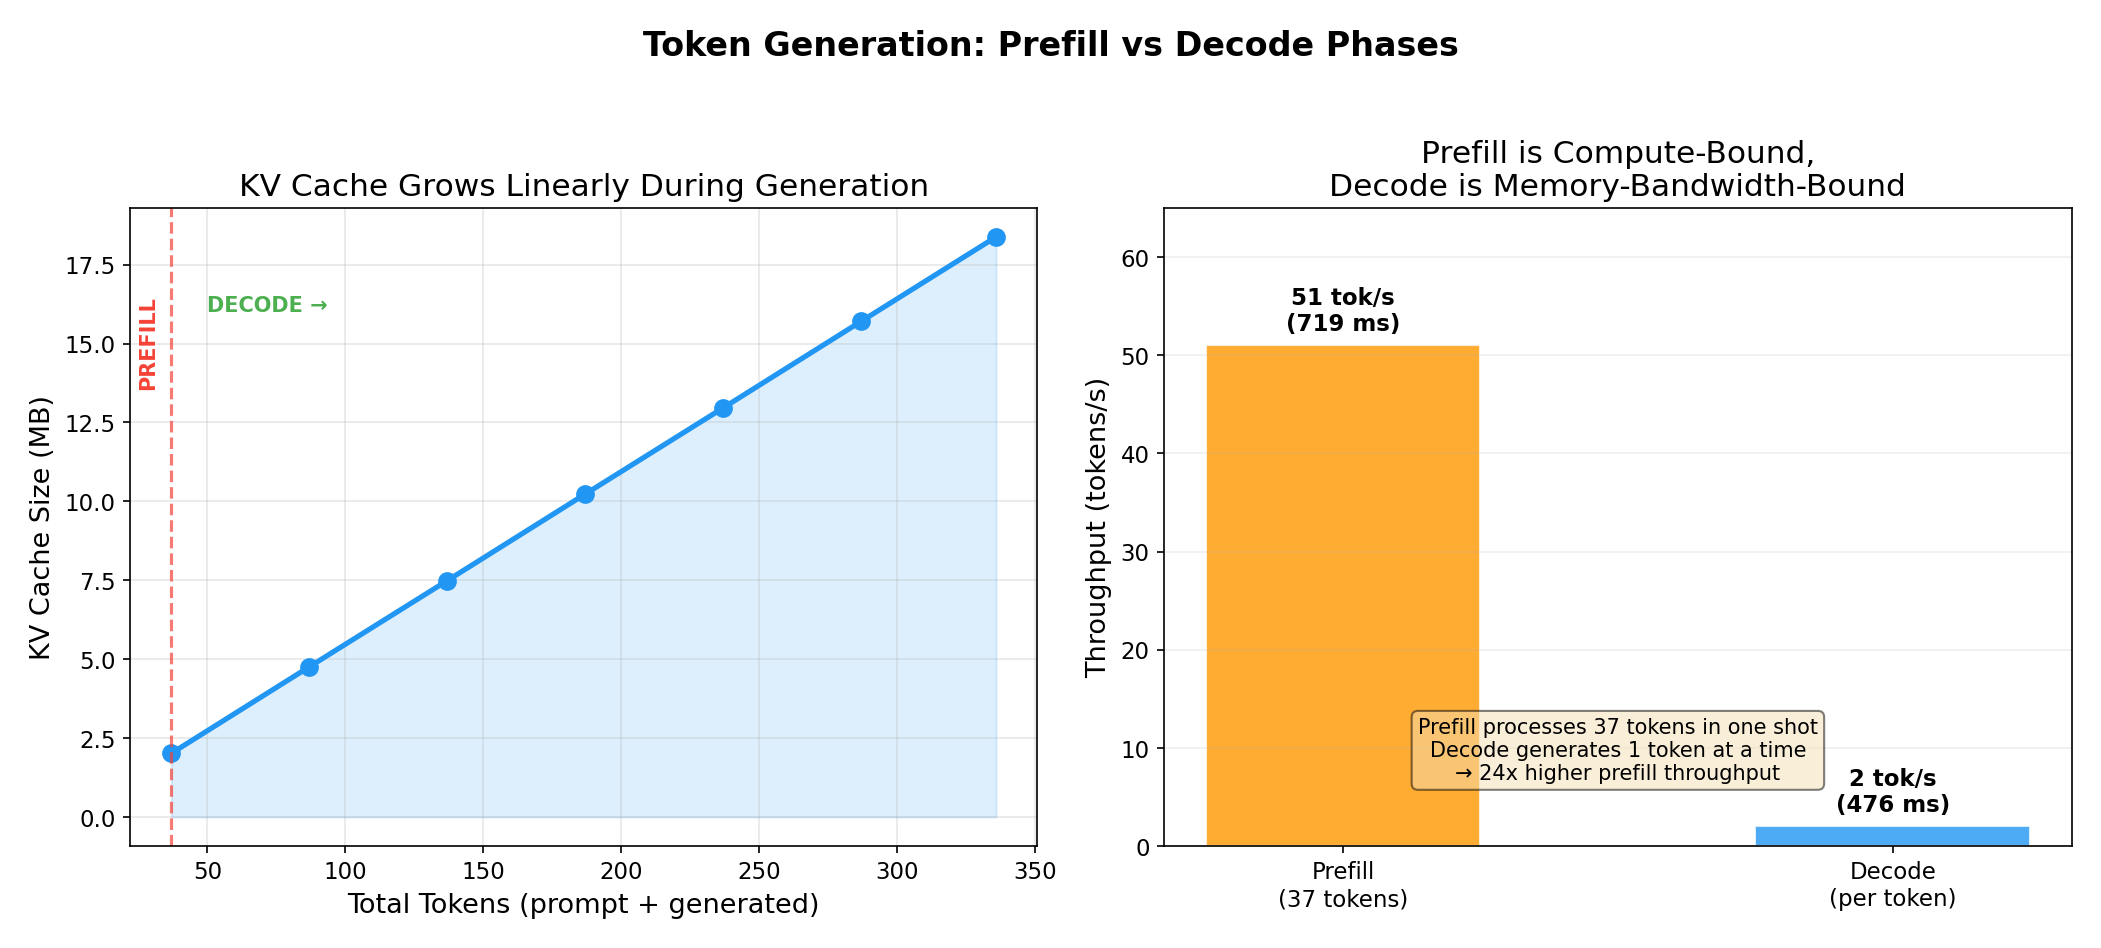
Understanding KV Cache in LLM Inference - Jingchao’s Website
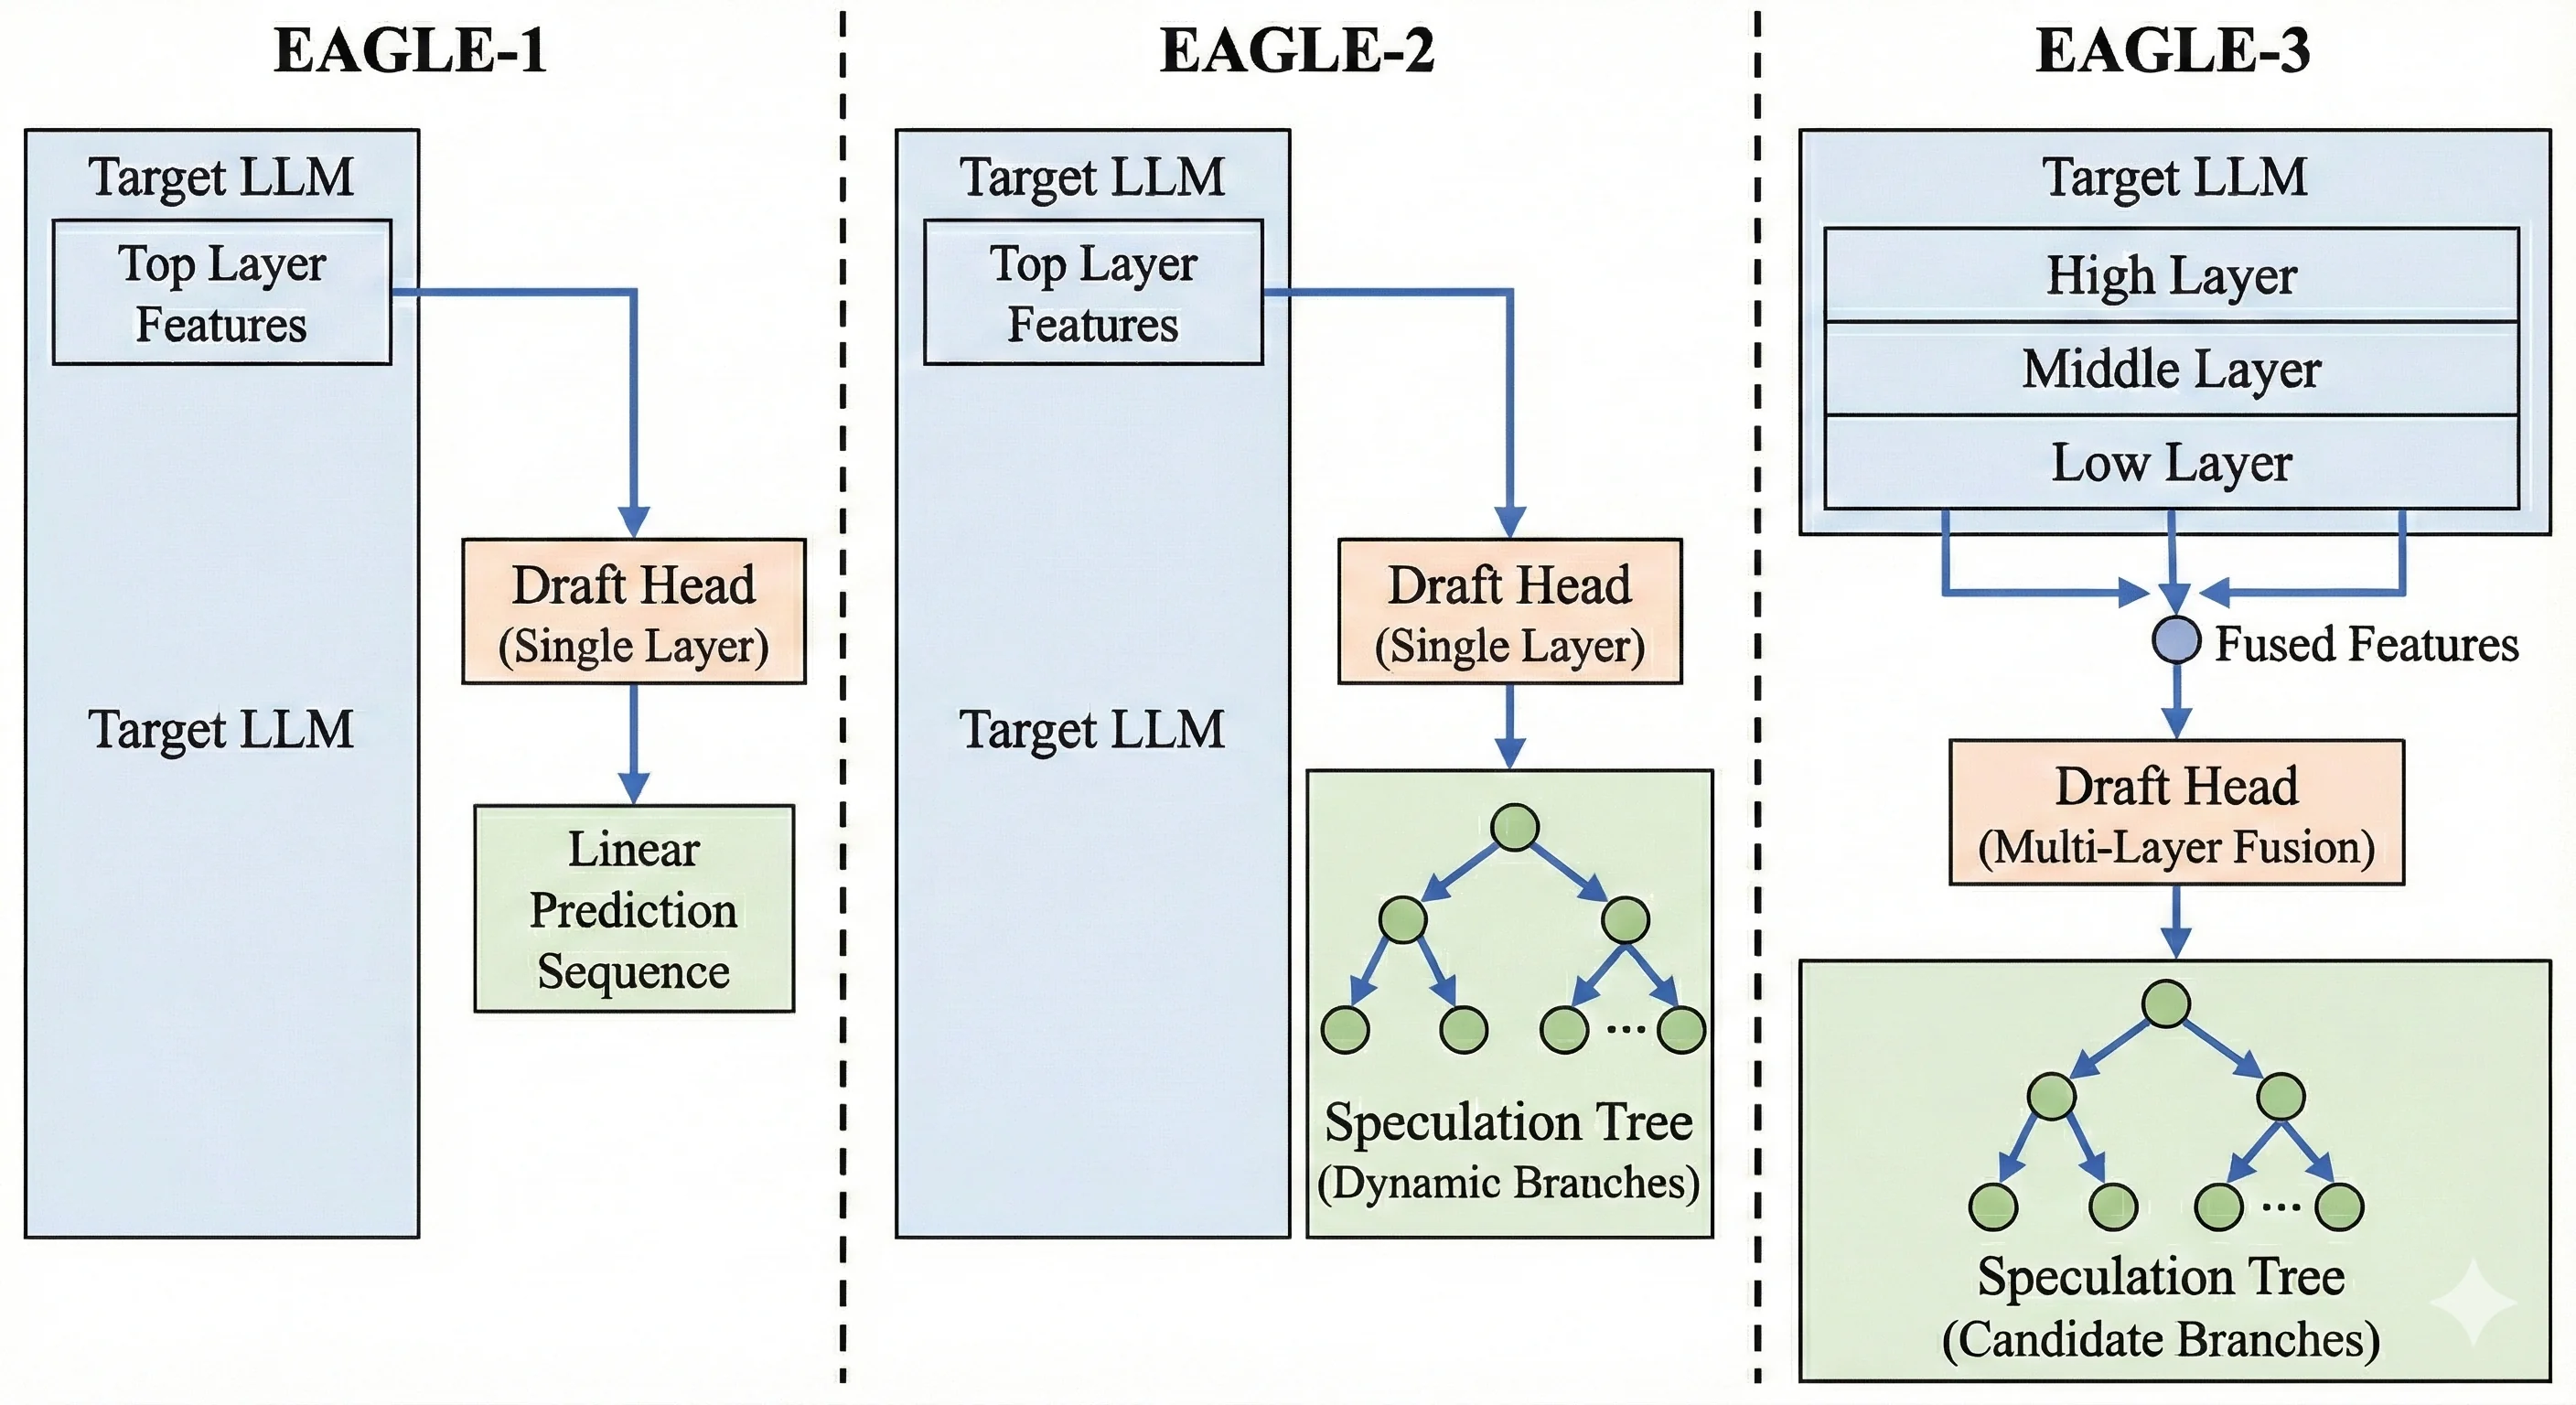
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
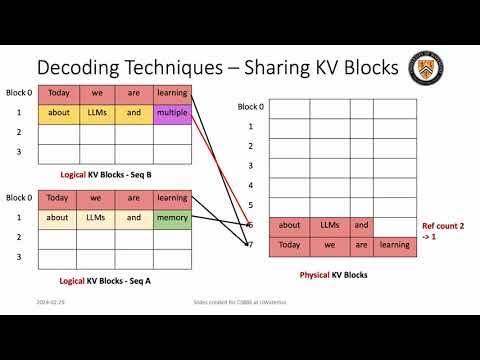
Efficient LLM Inference (vLLM KV Cache, Flash Decoding & Lookahead ...

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...

(PDF) ClusterKV: Manipulating LLM KV Cache in Semantic Space for ...
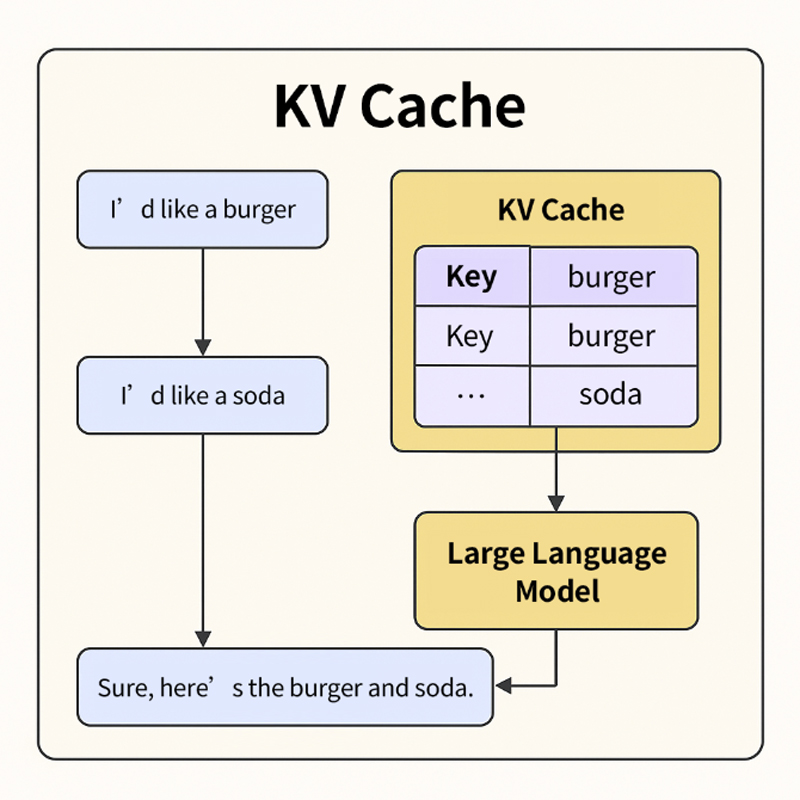
KV Cache Meets NVMe: The Key to Accelerating LLM Inference

(PDF) ClusterKV: Manipulating LLM KV Cache in Semantic Space for ...

FreeKV: Boosting KV Cache Retrieval for Efficient LLM Inference

KVSharer: method for efficient LLM inference via dissimilar KV Cache ...
Advertisement Space (336x280)
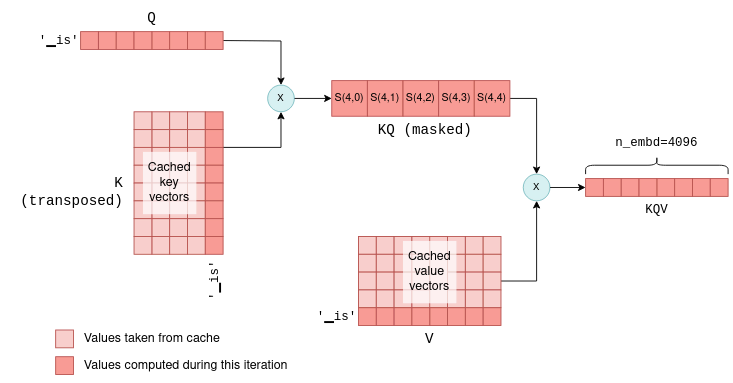
LLM 和 KV cache 详解 | Jasmine

KV Cache Memory: Sizing LLM Inference

[2412.03213] ClusterKV: Manipulating LLM KV Cache in Semantic Space for ...

Comparative Characterization of KV Cache Management Strategies for LLM ...

Accelerating LLM Inference with Speculative Decoding Using OpenVINO ...