
Table 1 From Task Oriented Sequential Grounding In 3d Scenes Semantic

Table 1 from Task-oriented Sequential Grounding in 3D Scenes | Semantic ...
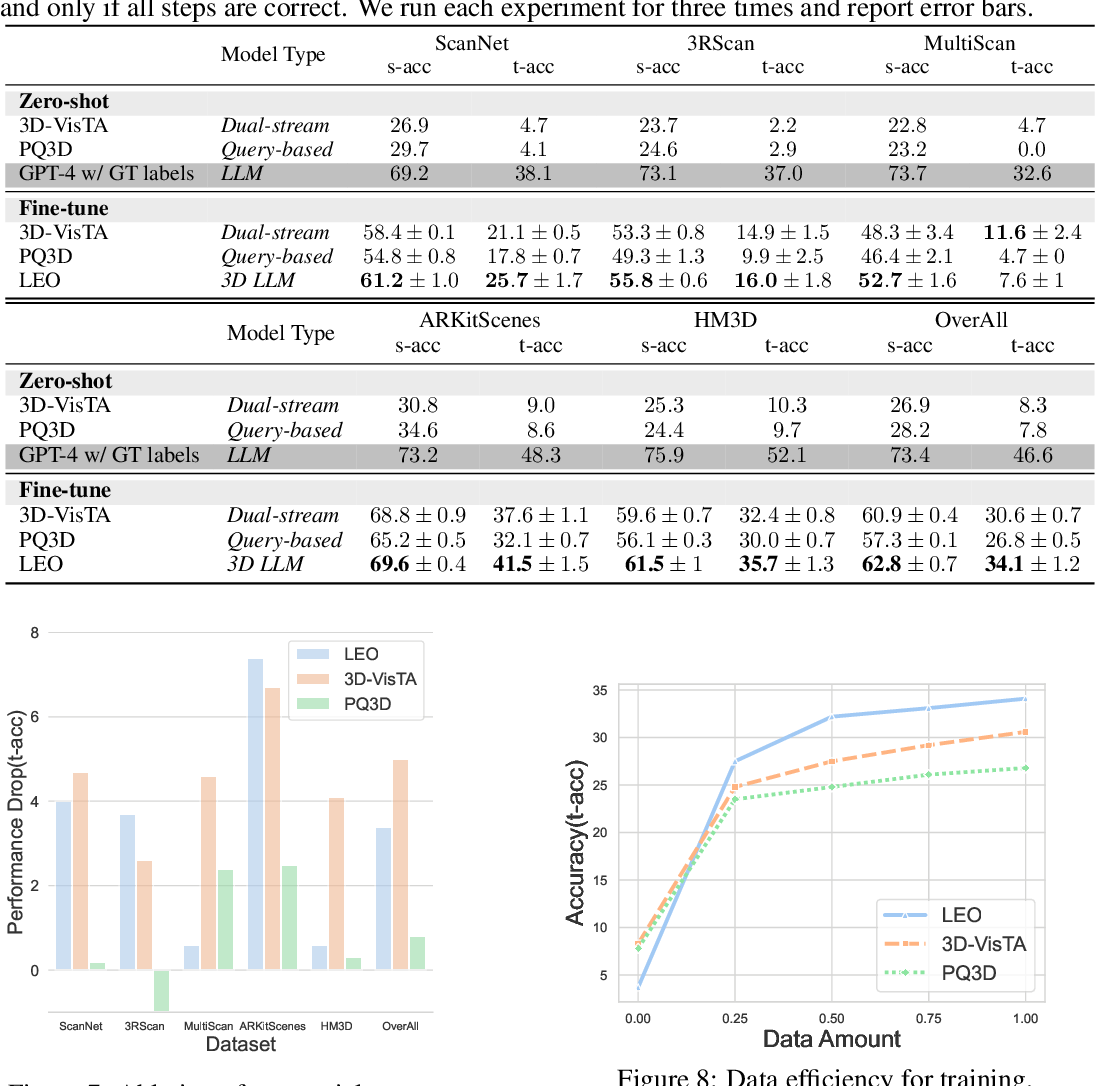
Table 1 from Task-oriented Sequential Grounding in 3D Scenes | Semantic ...
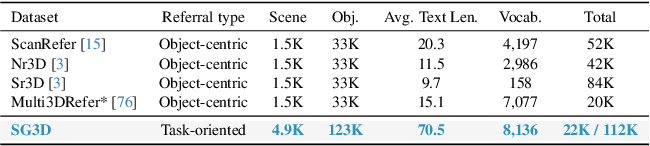
Table 1 from Task-oriented Sequential Grounding and Navigation in 3D ...

Figure 1 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Table 1 from Grounding 3D Object Affordance from 2D Interactions in ...

Figure 2 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Figure 3 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Task-oriented Sequential Grounding in 3D Scenes

Task-oriented Sequential Grounding in 3D Scenes

Table 1 from ScanERU: Interactive 3D Visual Grounding based on Embodied ...
Advertisement Space (300x250)

Task-oriented Sequential Grounding in 3D Scenes

Task-oriented Sequential Grounding and Navigation in 3D Scenes | alphaXiv
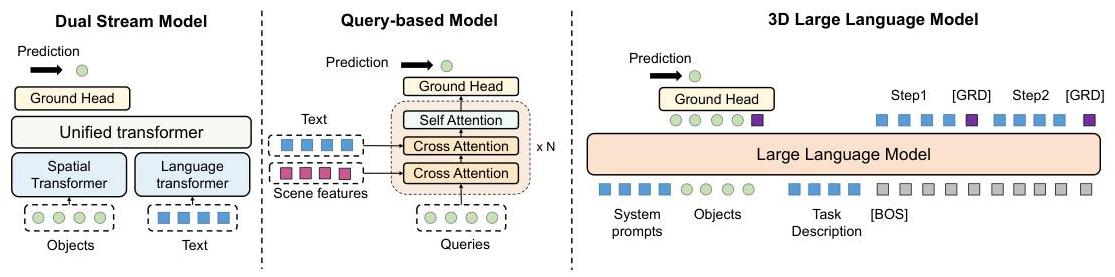
Task-oriented Sequential Grounding in 3D Scenes | alphaXiv
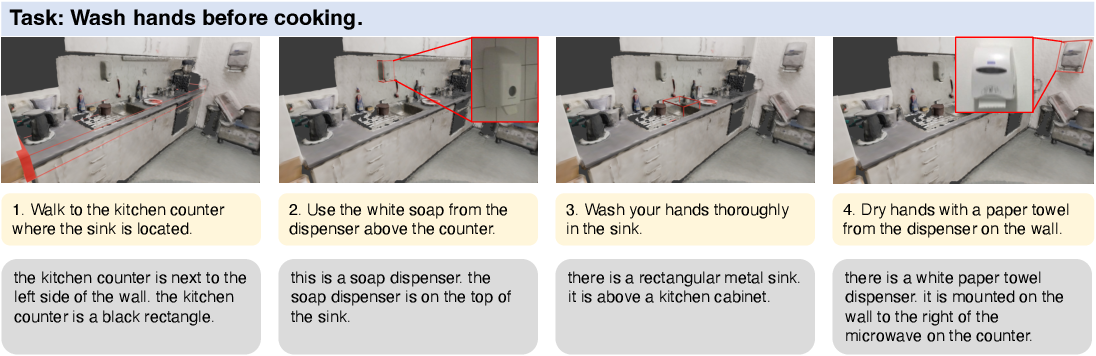
Figure 2 from Task-oriented Sequential Grounding and Navigation in 3D ...

Task-oriented Sequential Grounding in 3D Scenes - YouTube

Paper page - Task-oriented Sequential Grounding in 3D Scenes

Table 1 from SayPlan: Grounding Large Language Models using 3D Scene ...
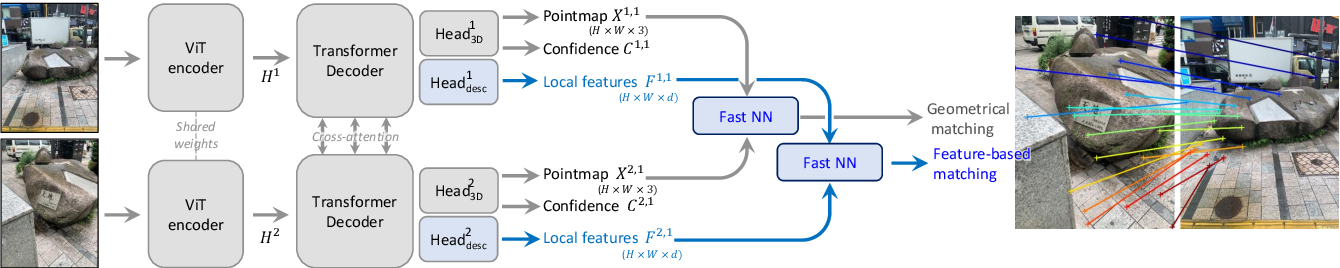
Figure 2 from Grounding Image Matching in 3D with MASt3R | Semantic Scholar
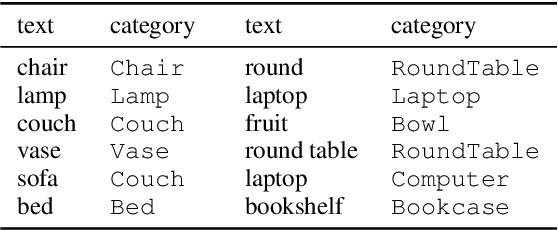
Table 1 from Text to 3D Scene Generation with Rich Lexical Grounding ...
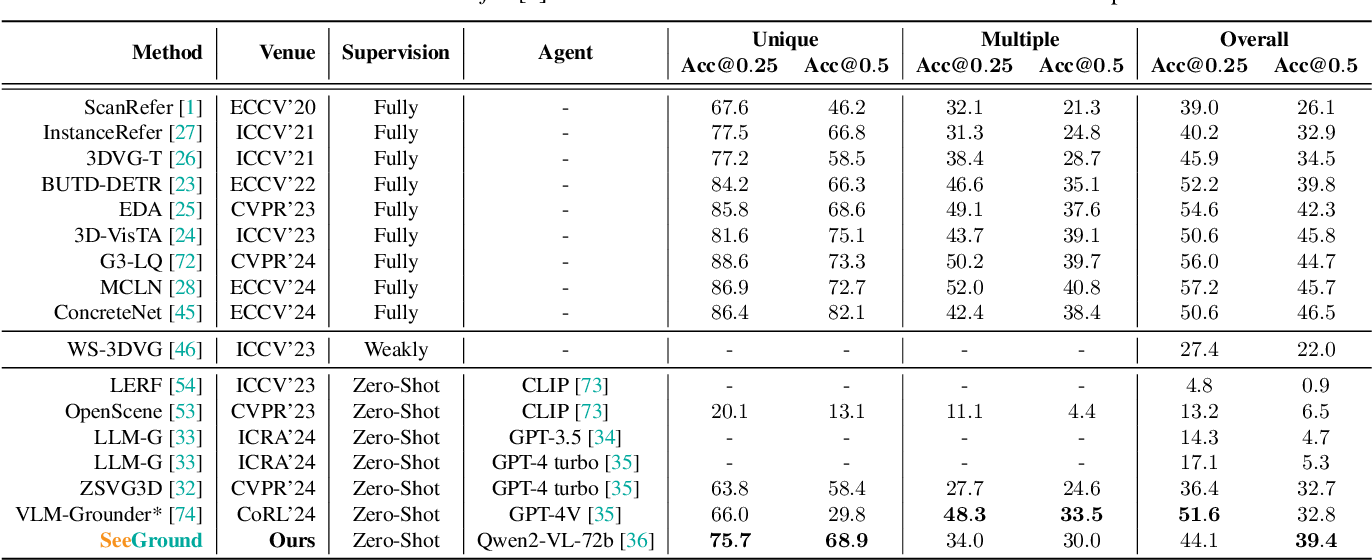
Table 1 from Zero-Shot 3D Visual Grounding from Vision-Language Models ...
Advertisement Space (336x280)

Table 1 from Naturally Supervised 3D Visual Grounding with Language ...

Figure 1 from SeCG: Semantic-Enhanced 3D Visual Grounding via Cross ...

Figure 1 from Grounding 3D Scene Affordance From Egocentric ...

Figure 1 from Toward Explainable and Fine-Grained 3D Grounding through ...

Figure 1 from SeCG: Semantic-Enhanced 3D Visual Grounding via Cross ...

Figure 1 from Grounding 3D Scene Affordance From Egocentric ...

Figure 3 from Grounding 3D Object Affordance from 2D Interactions in ...
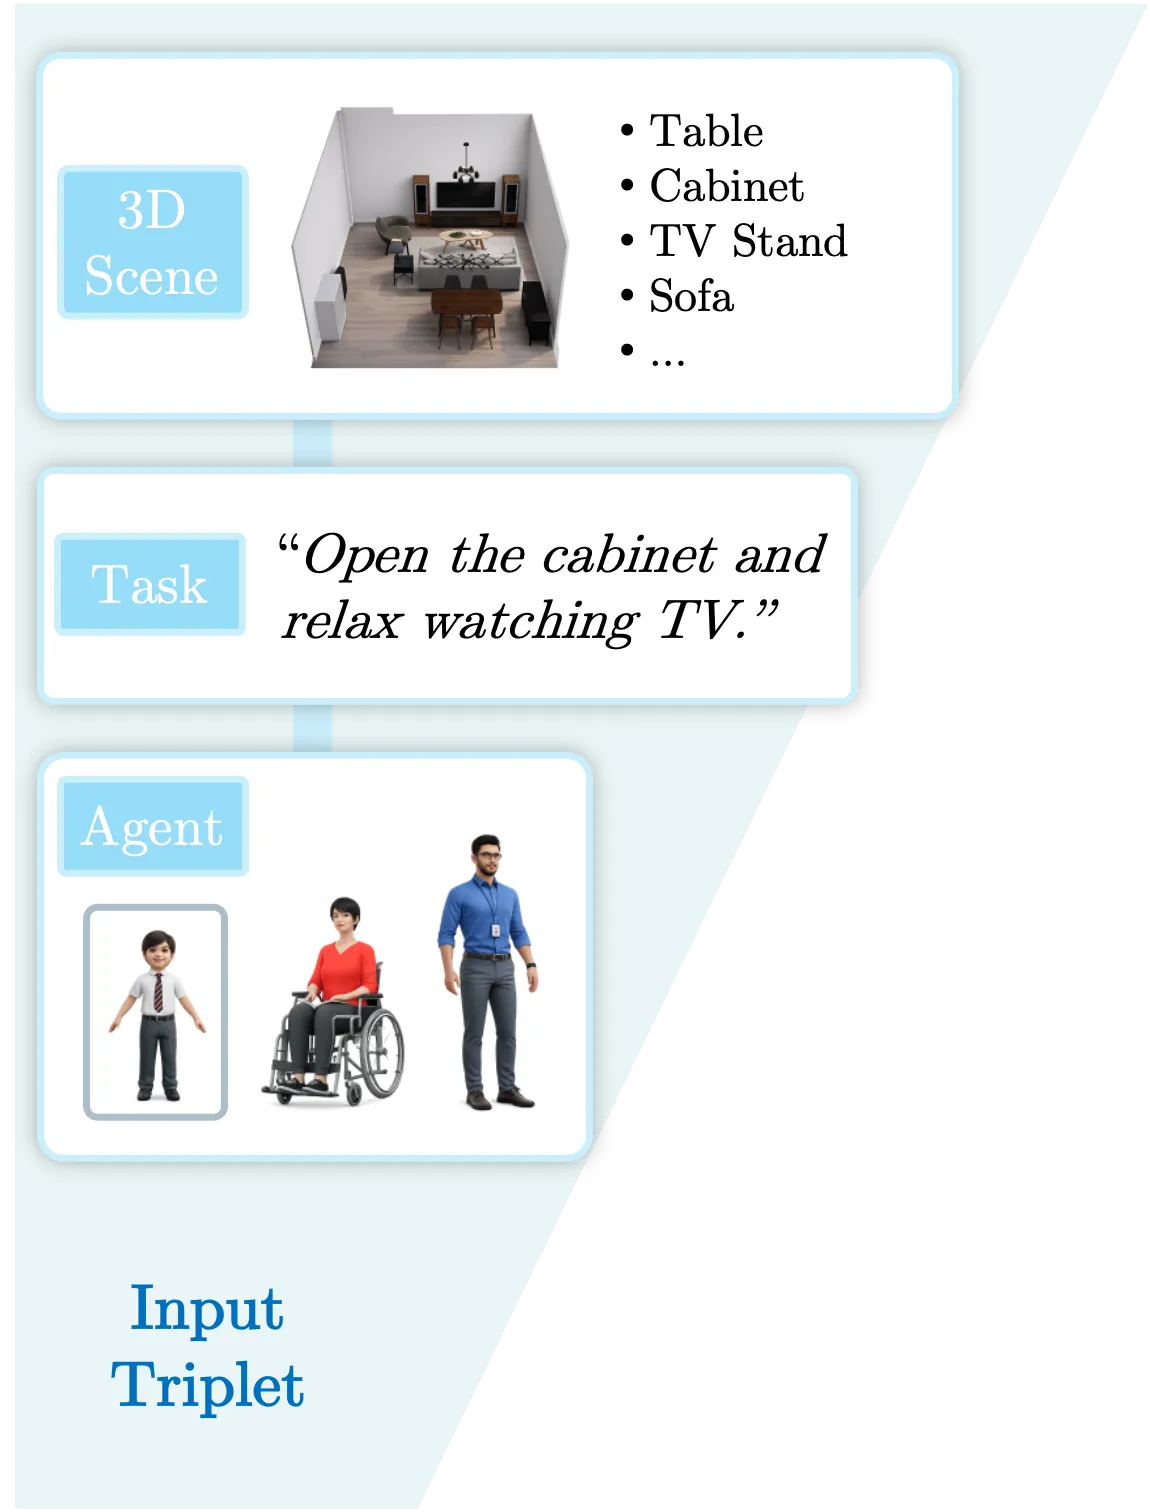
SceneTeract: Agentic Functional Affordances and VLM Grounding in 3D Scenes

Figure 1 from ScanReason: Empowering 3D Visual Grounding with Reasoning ...
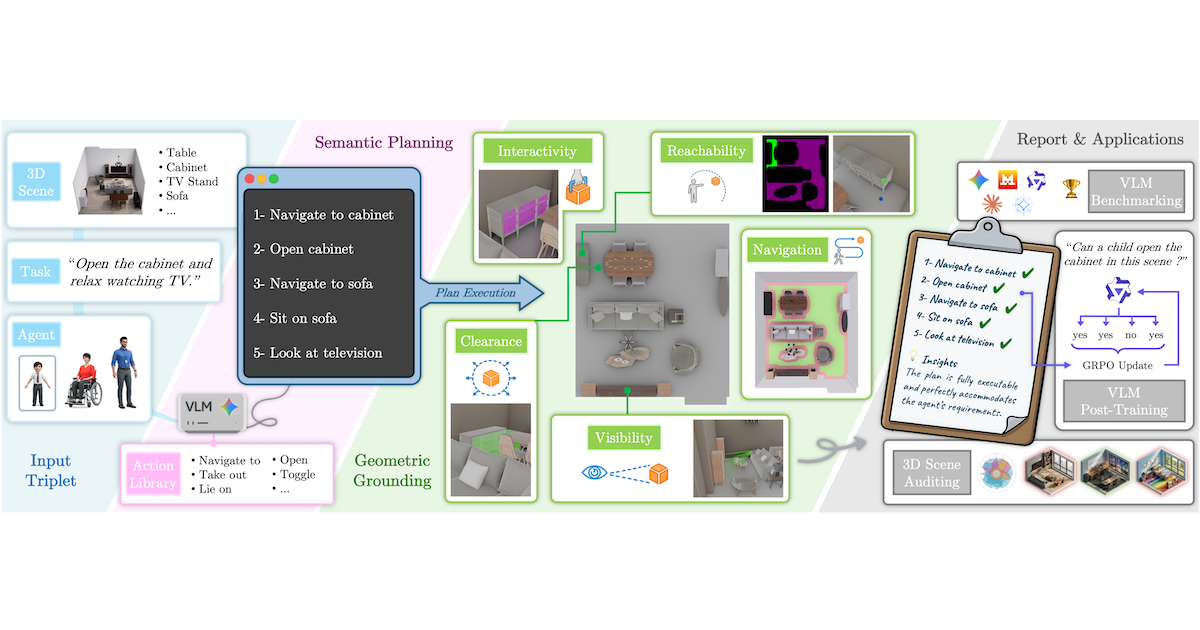
SceneTeract: Agentic Functional Affordances and VLM Grounding in 3D Scenes
Advertisement Space (336x280)

Figure 1 from Visual Grounding with Transformers | Semantic Scholar

Figure 2 from 3D Concept Grounding on Neural Fields | Semantic Scholar

Figure 1 from Task-oriented Grasping in Object Stacking Scenes with CRF ...
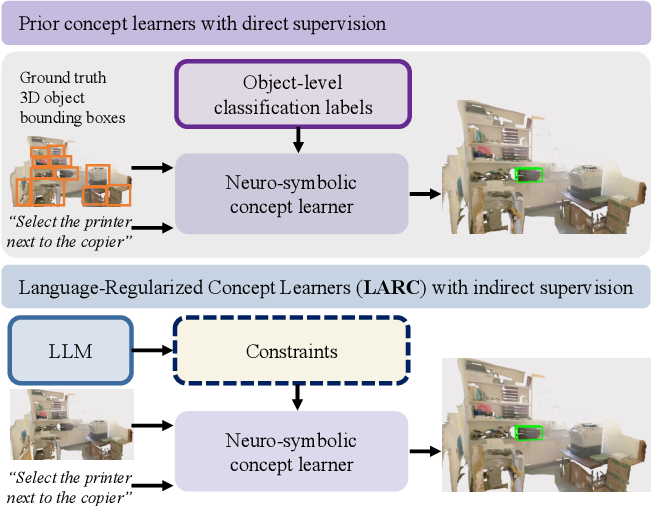
Figure 1 from Naturally Supervised 3D Visual Grounding with Language ...

Table I from Grounding 3D Scene Affordance From Egocentric Interactions ...

Figure 1 from Data-Efficient 3D Visual Grounding via Order-Aware ...