
Table 2 From Low Delay Voice Conversion Based On Maximum Likelihood
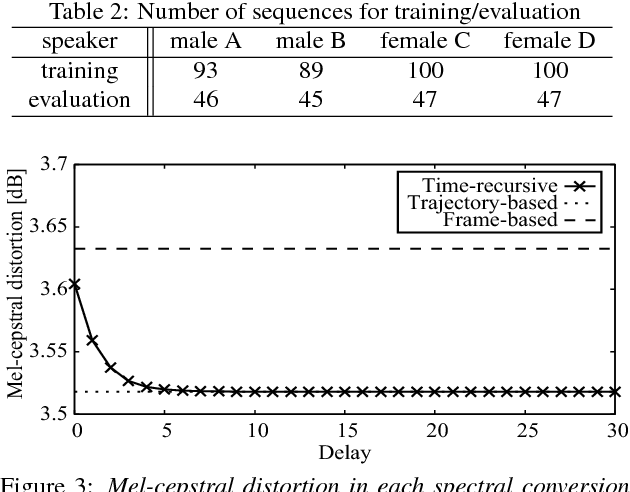
Table 2 from Low-delay voice conversion based on maximum likelihood ...

Figure 2 from Low-delay voice conversion based on maximum likelihood ...

Figure 2 from Maximum likelihood voice conversion based on GMM with ...
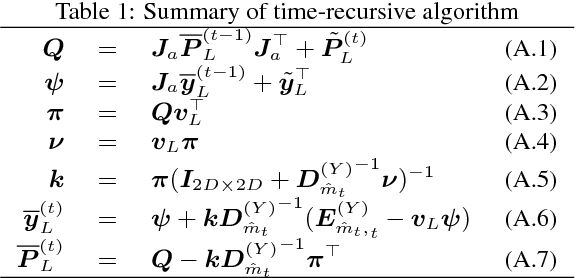
Table 1 from Low-delay voice conversion based on maximum likelihood ...
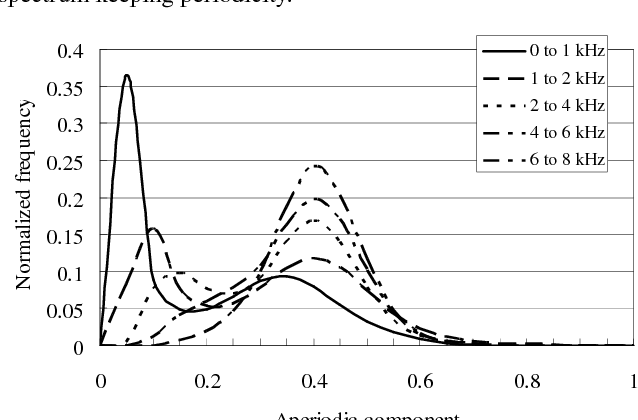
Figure 3 from Maximum likelihood voice conversion based on GMM with ...
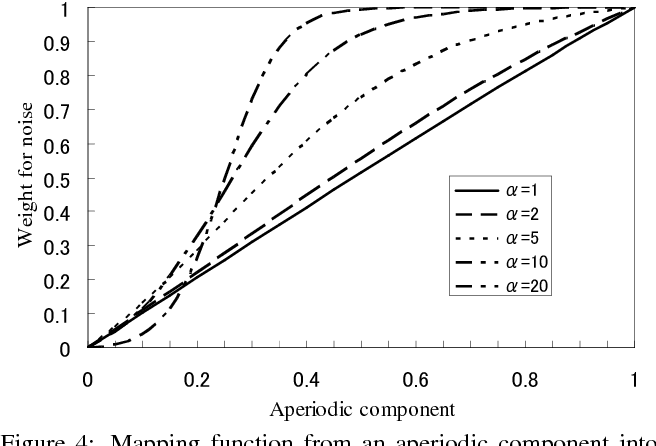
Figure 4 from Maximum likelihood voice conversion based on GMM with ...
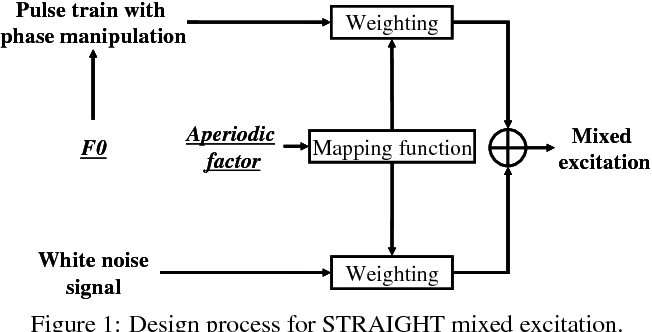
Figure 1 from Maximum likelihood voice conversion based on GMM with ...

(PDF) Low-delay voice conversion based on maximum likelihood estimation ...
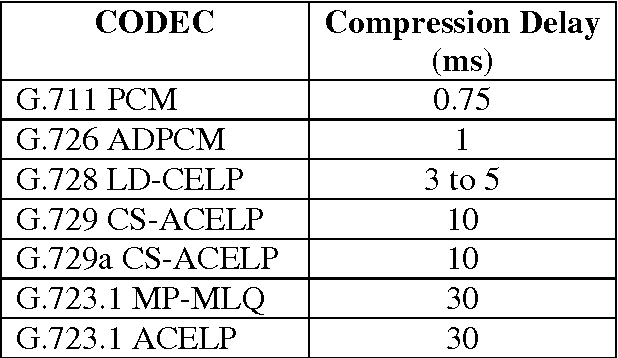
Table 2 from THE EFFECT OF VOICE PACKET SIZE ON END-TO-END DELAY IN 802 ...

(PDF) Maximum likelihood voice conversion based on GMM with STRAIGHT ...
Advertisement Space (300x250)

Figure 2 from Voice Conversion Based on Locally Linear Embedding ...

Figure 2 from High-Quality Nonparallel Voice Conversion Based on Cycle ...

Table 3 from Voice Conversion Based on Locally Linear Embedding ...
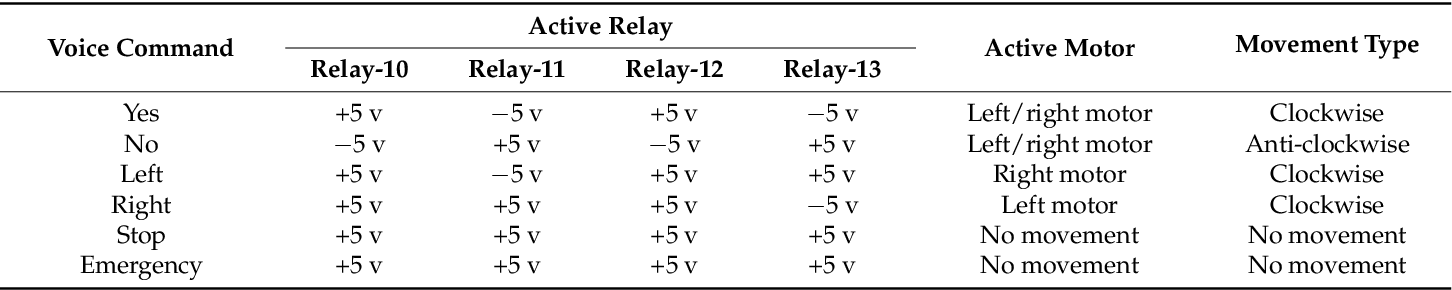
Table 2 from Steering a Robotic Wheelchair Based on Voice Recognition ...

Table 2 from End-to-End Zero-Shot Voice Conversion with Location ...
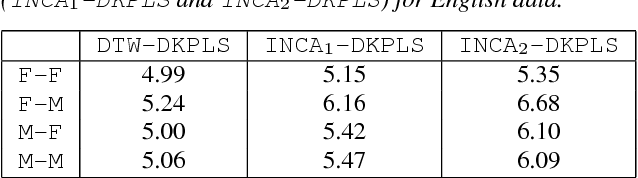
Table 2 from Voice conversion for non-parallel datasets using dynamic ...
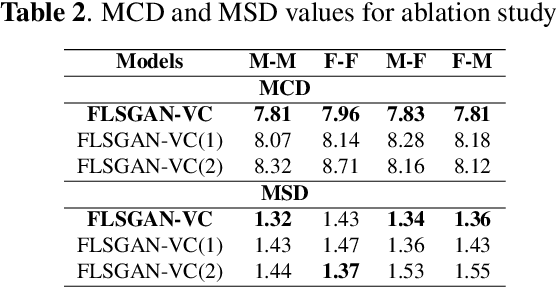
Table 2 from Voice Conversion Using Feature Specific Loss Function ...

Figure 2 from Low-Latency Real-Time Non-Parallel Voice Conversion based ...

Figure 5 from Voice Conversion Based on Locally Linear Embedding ...

Table 2 from Reverberation-Controllable Voice Conversion Using ...
Advertisement Space (336x280)

Figure 10 from Voice Conversion Based on Deep Neural Networks for Time ...

Table 2 from End-to-End Zero-Shot Voice Conversion Using a DDSP Vocoder ...

Figure 1 from Voice Conversion Based on Deep Neural Networks for Time ...

Figure 3 from Voice Conversion Based on Locally Linear Embedding ...

Table 2 from Multi-Target Emotional Voice Conversion With Neural ...
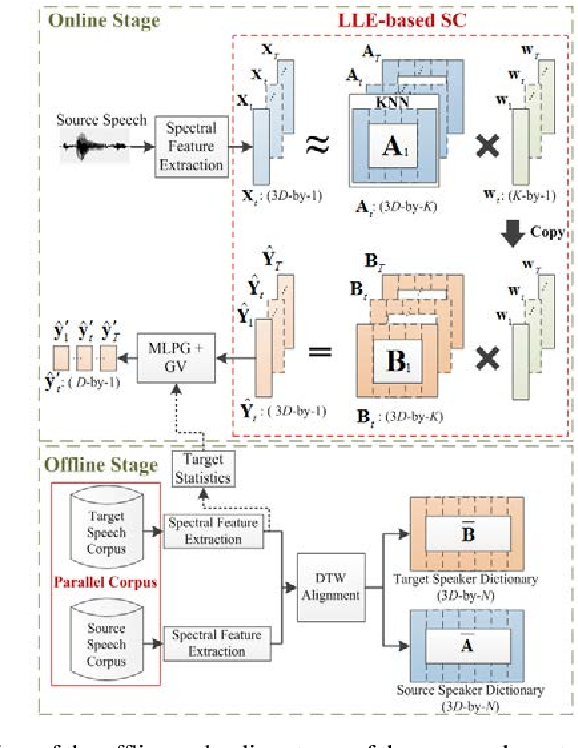
Figure 1 from Voice Conversion Based on Locally Linear Embedding ...
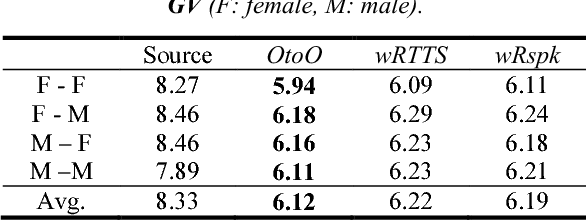
Table 2 from The NU Non-Parallel Voice Conversion System for the Voice ...
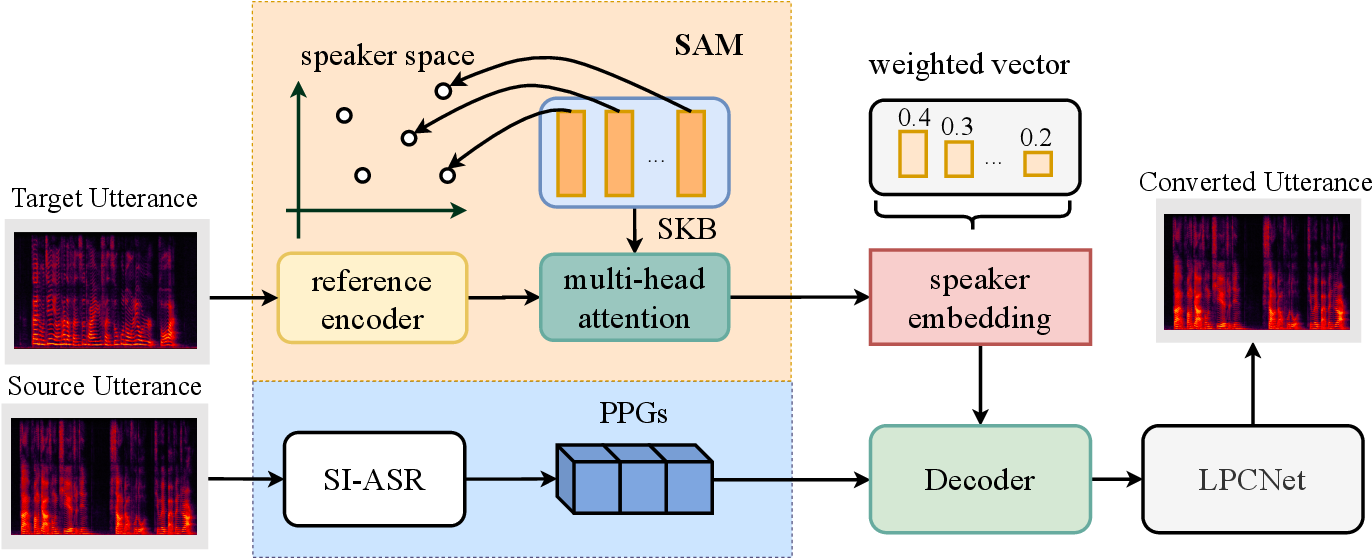
Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

Figure 1 from A system for voice conversion based on adaptive filtering ...

Figure 4 from Voice Conversion Based on Locally Linear Embedding ...
Advertisement Space (336x280)
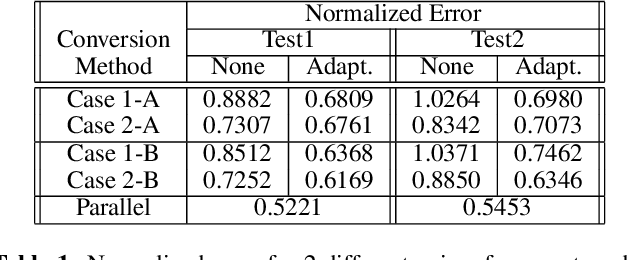
Table 1 from Non-parallel training for voice conversion by maximum ...

Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

Table 1 from Enhancing Multilingual TTS with Voice Conversion Based ...

Table 2 from Voice-to-voice conversion using transformer network ...
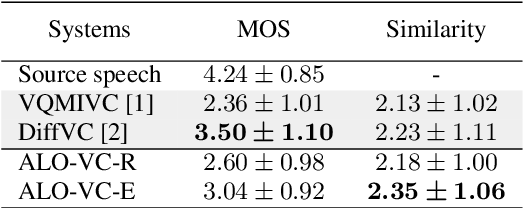
Table 1 from ALO-VC: Any-to-any Low-latency One-shot Voice Conversion ...

Diffusion-Based Voice Conversion with Fast Maximum Likelihood Sampling ...