
Usage Async Engine Batch Request Issue 15314 Vllm Projectvllm
[Usage]: Async engine batch request · Issue #15314 · vllm-project/vllm ...
API causes slowdown in batch request handling · Issue #1707 · vllm ...
[Usage]: How to use vllm serve for batch inference? · Issue #16494 ...
[Usage]: vllm OpenAI API Offline Batch Inference · Issue #8567 · vllm ...

vLLM — Session 2: The Engine Layer — Request Management - DEV Community
API Server batch request issue · Issue #2441 · vllm-project/vllm · GitHub
[Bug][V1]: Qwen2.5_vl not support on V1 engine · Issue #514 · vllm ...
VLLM Integration - Getting 400 Bad Request Error · Issue #74 · browser ...
when I use async vllm rollout in dapo get ERROR · Issue #2863 · verl ...
Request for GLM-5.1 + AMD MI300X vLLM deployment recipe · Issue #333 ...
Advertisement Space (300x250)
[Bug]:Qwen2.5vl vllm serve Engine process failed to start · Issue ...
[Feature]: Batch inference for `llm.chat()` API · Issue #8481 · vllm ...
Unable to specify GPU usage in VLLM code · Issue #3012 · vllm-project ...

Batch Async LLM Requests Save Money | Rohit Jibhakate posted on the ...
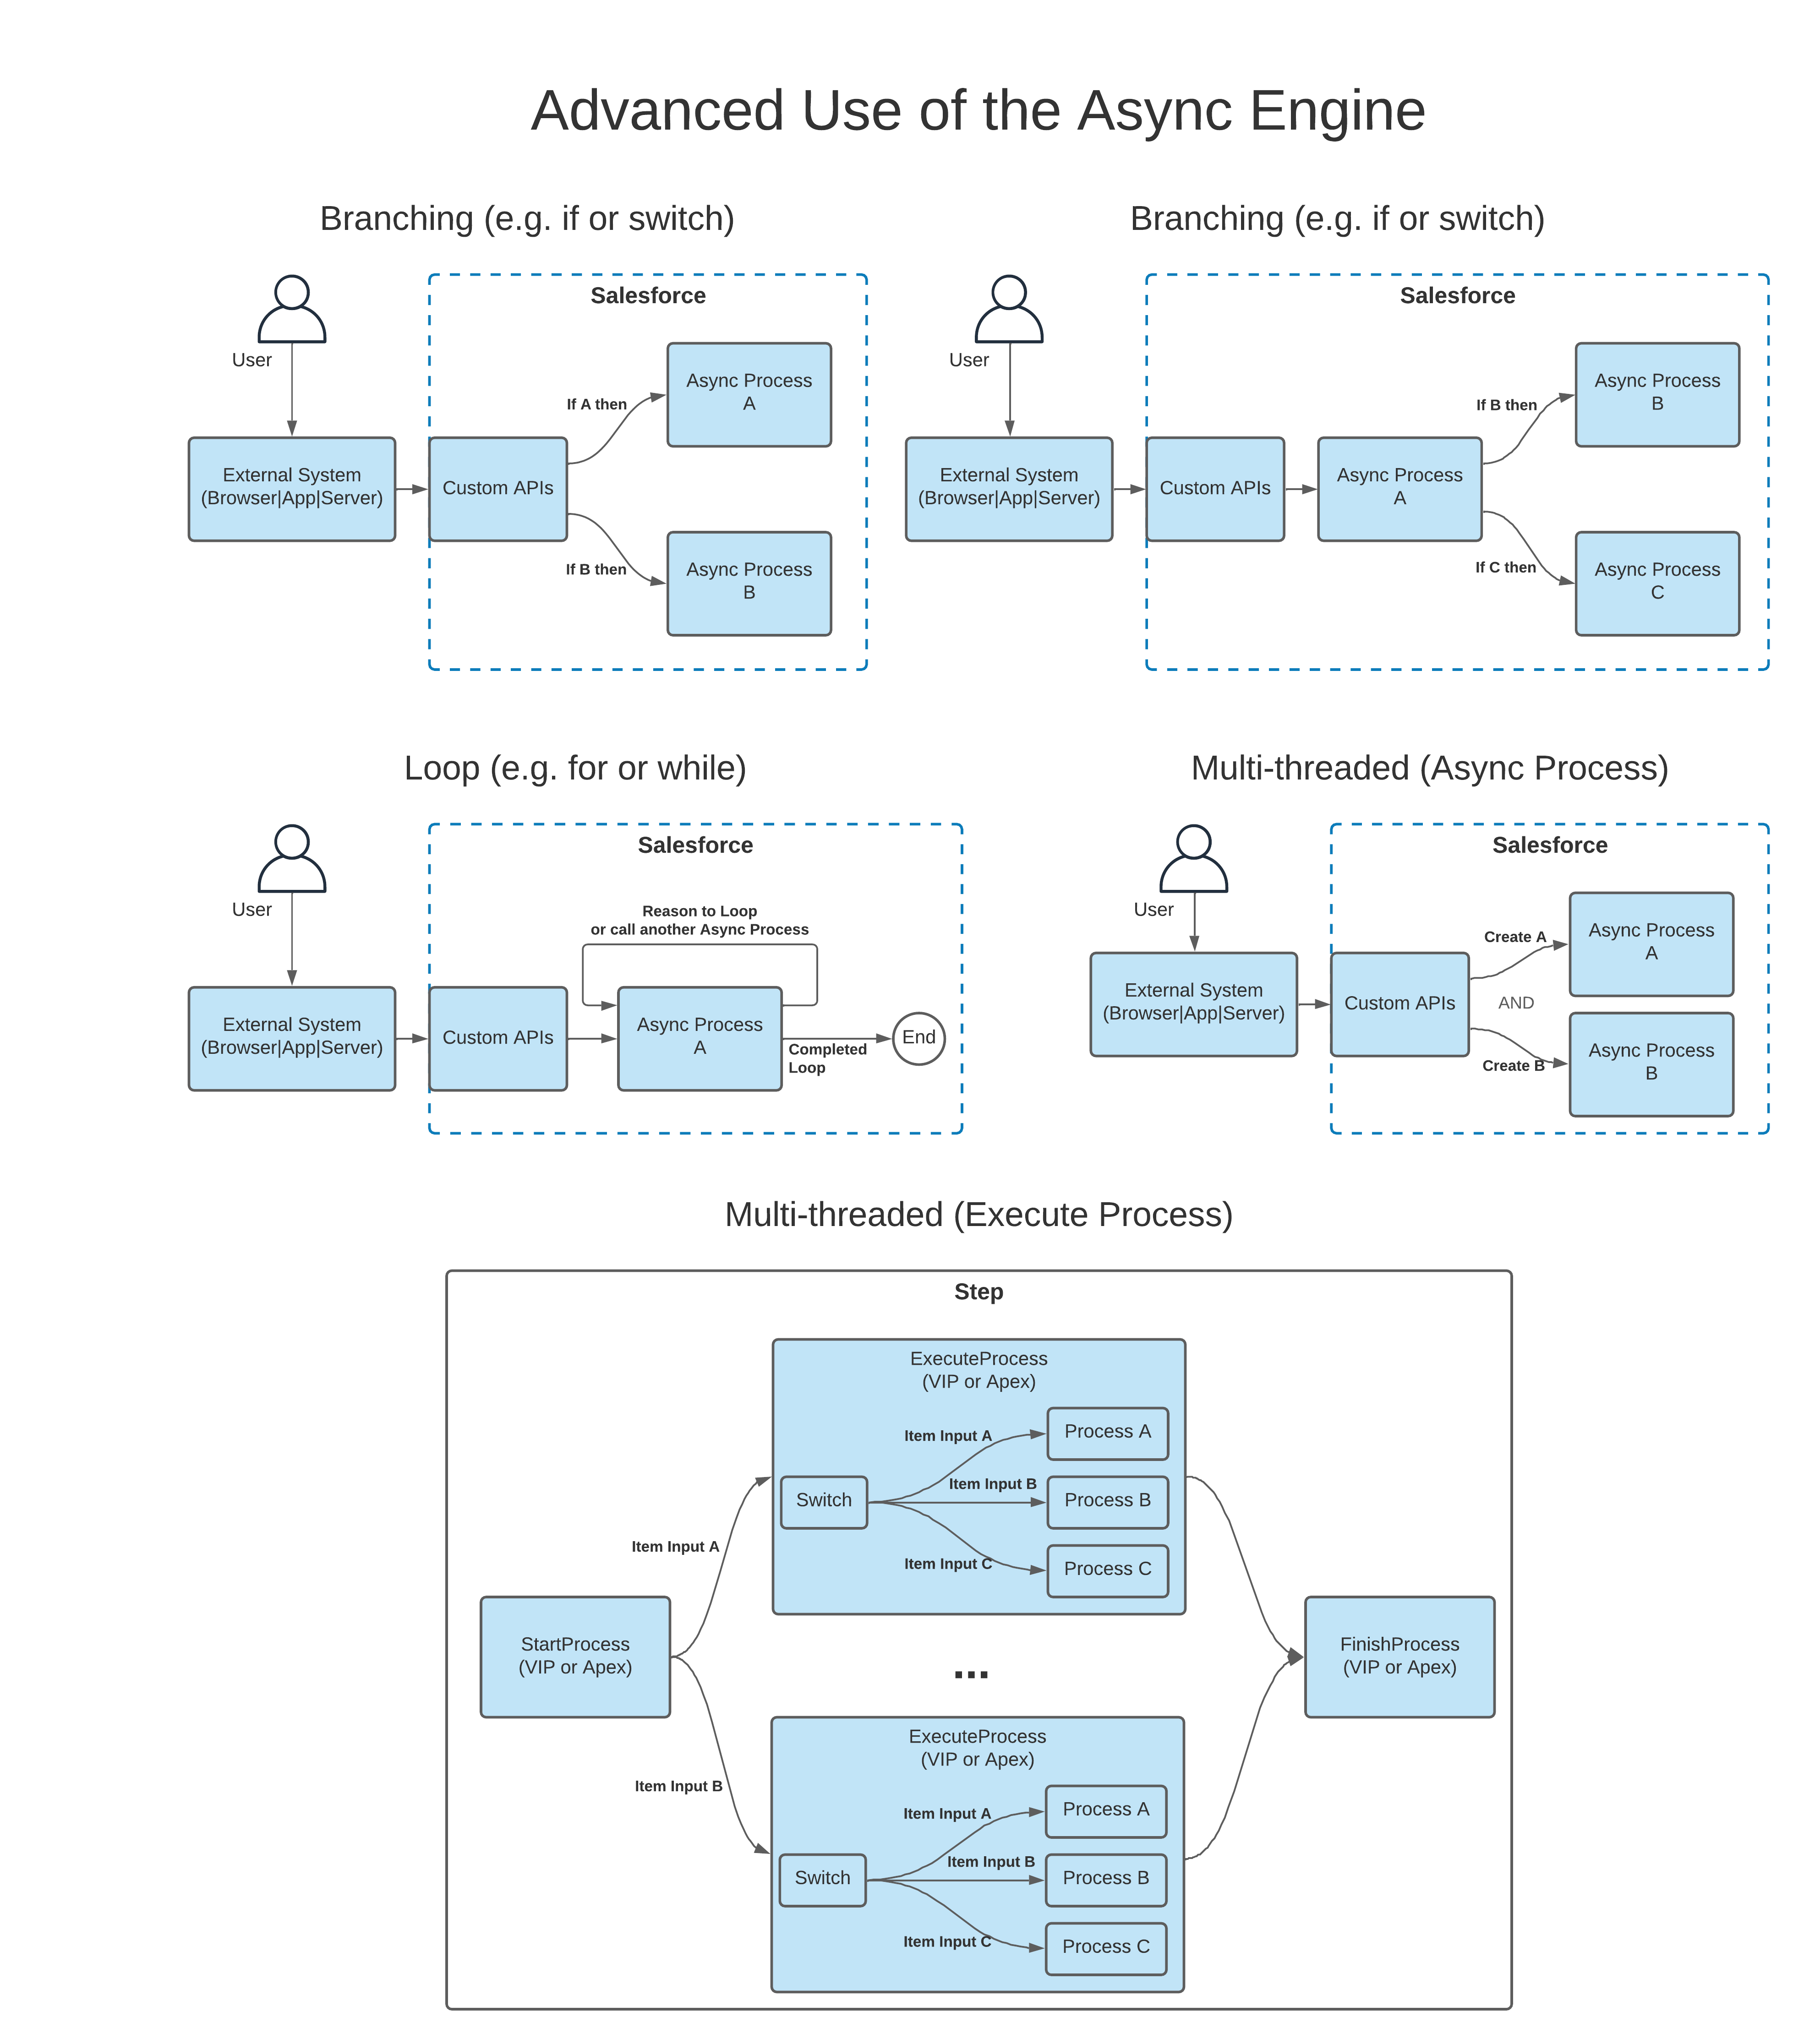
Advanced Use of the Async Engine
(Async) Batch request, OpenAI API server · Issue #1636 · vllm-project ...
[Bug]: async llm engine failed unexpectedly (using mixtral-8x7b with tp ...
vllm.engine.async_llm_engine.AsyncEngineDeadError · Issue #1364 · vllm ...
AsyncEngineDeadError: Task Finished Unexpectedly in VLLM Async LLM ...
[Bug]: V1 Engine crashes when sending requests with same request id ...
Advertisement Space (336x280)
[Bug]: Frequent Errors:async_llm_engine.py:158] Aborted request · Issue ...
Does the API server automatically batch user requests together? · Issue ...
vLLM's V1 Engine Architecture · Issue #8779 · vllm-project/vllm · GitHub
[Usage]: How to determine whether the vllm engine is full with requests ...
[Bug]: Engine stuck with requests are blocked, running/waiting request ...
[Installation]: vLLM build from source errors · Issue #8532 · vllm ...
[Bug]: vllm serve Exception in ASGI application · Issue #10215 · vllm ...
[Usage]: Does vLLM support multi-task · Issue #13390 · vllm-project ...
[Usage]: How to stop VLLM during generation ? · Issue #8332 · vllm ...
[Bug]: V1 engine Index Error When Single Request Near Max Context ...
Advertisement Space (336x280)
Low VRAM batch processing mode · Issue #1297 · vllm-project/vllm · GitHub
Engine Core and Request Lifecycle | npuichigo/vllm | DeepWiki
Question regarding behavior of AsyncLLMEngine on single batch · Issue ...
Async & Batch Rendering API with Webhooks | Rendex
Unable to process request · Issue #2595 · vllm-project/vllm · GitHub
[Bug]: Crashing on unsupported Sampling params · Issue #15312 · vllm ...