
Vllm Guide 2026 High Throughput Llm Serving
vLLM Guide 2026 | High-Throughput LLM Serving
vLLM Production LLM Serving: Developer Guide 2026
vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide
vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide

Scaling LLM Inference on GKE: Serving with vLLM or llm-d | by Don ...

vLLM Throughput Guide - PagedAttention and Batching Tips (2026)

LLM Semantic Router Production Implementation vLLM SR 2026 | Iterathon

vLLM Throughput Guide - PagedAttention and Batching Tips (2026)

vLLM Tutorial 2026: PagedAttention LLM Inference Guide - WeavAI Blog

How vLLM solves LLM serving issues for AI apps | Aaroh Bhardwaj posted ...
Advertisement Space (300x250)
vLLM Throughput Guide - PagedAttention and Batching Tips (2026)
vLLM Optimization — Batching, Quantization, and Throughput Tuning 2026 ...

Install vLLM on Linux for Production LLM Serving (2026 Guide)

VLLM Quickstart Guide of HOS: High-Performance LLM Inference for ...

Install vLLM on Linux for Production LLM Serving (2026 Guide)

vLLM High-Throughput LLM Inference Guide | PDF | Cache (Computing ...
Why vLLM is the King of High-Throughput LLM Serving - By Suyog Kale ...

Install vLLM on Linux for Production LLM Serving (2026 Guide)

Boost LLM Throughput: vLLM vs. Sglang and Other Serving Frameworks

Embedded LLM’s Guide to vLLM Architecture & High-Performance Serving ...
Advertisement Space (336x280)

SharkTime Software - Lokales Serving des LLM mit vLLM
How to Configure vLLM for LLM Serving
vLLM คืออะไร? คู่มือ LLM Inference Server สำหรับ SME 2026 — ADS FIT
Ollama vs vLLM: A Performance-Focused Guide to LLM Serving

Install vLLM on Linux for Production LLM Serving (2026 Guide)
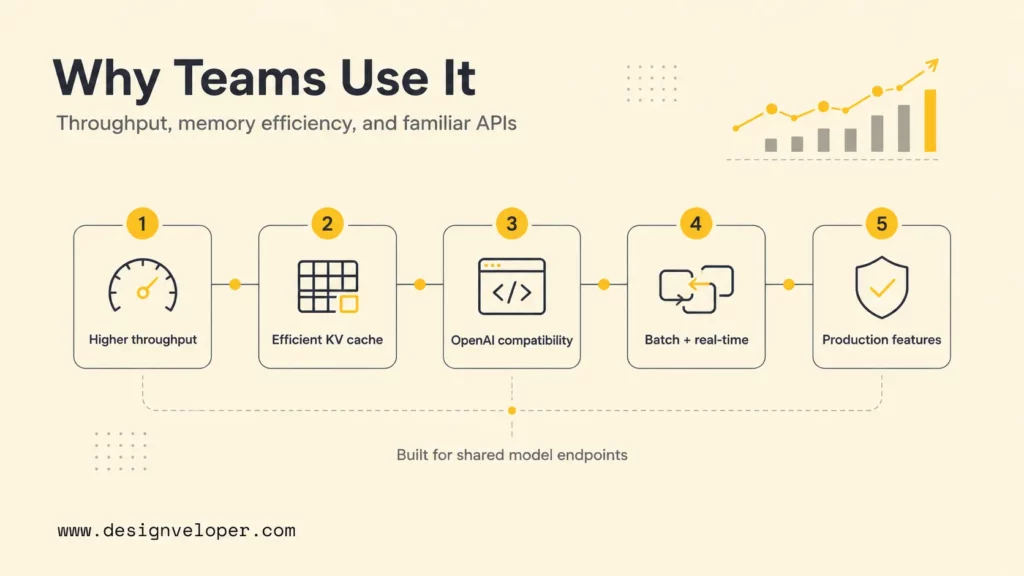
vLLM Tutorial: A Step-By-Step Guide To Deploying And Serving LLMs ...

LLM Scaling: vLLM HOD Interview System Design Guide - Studocu
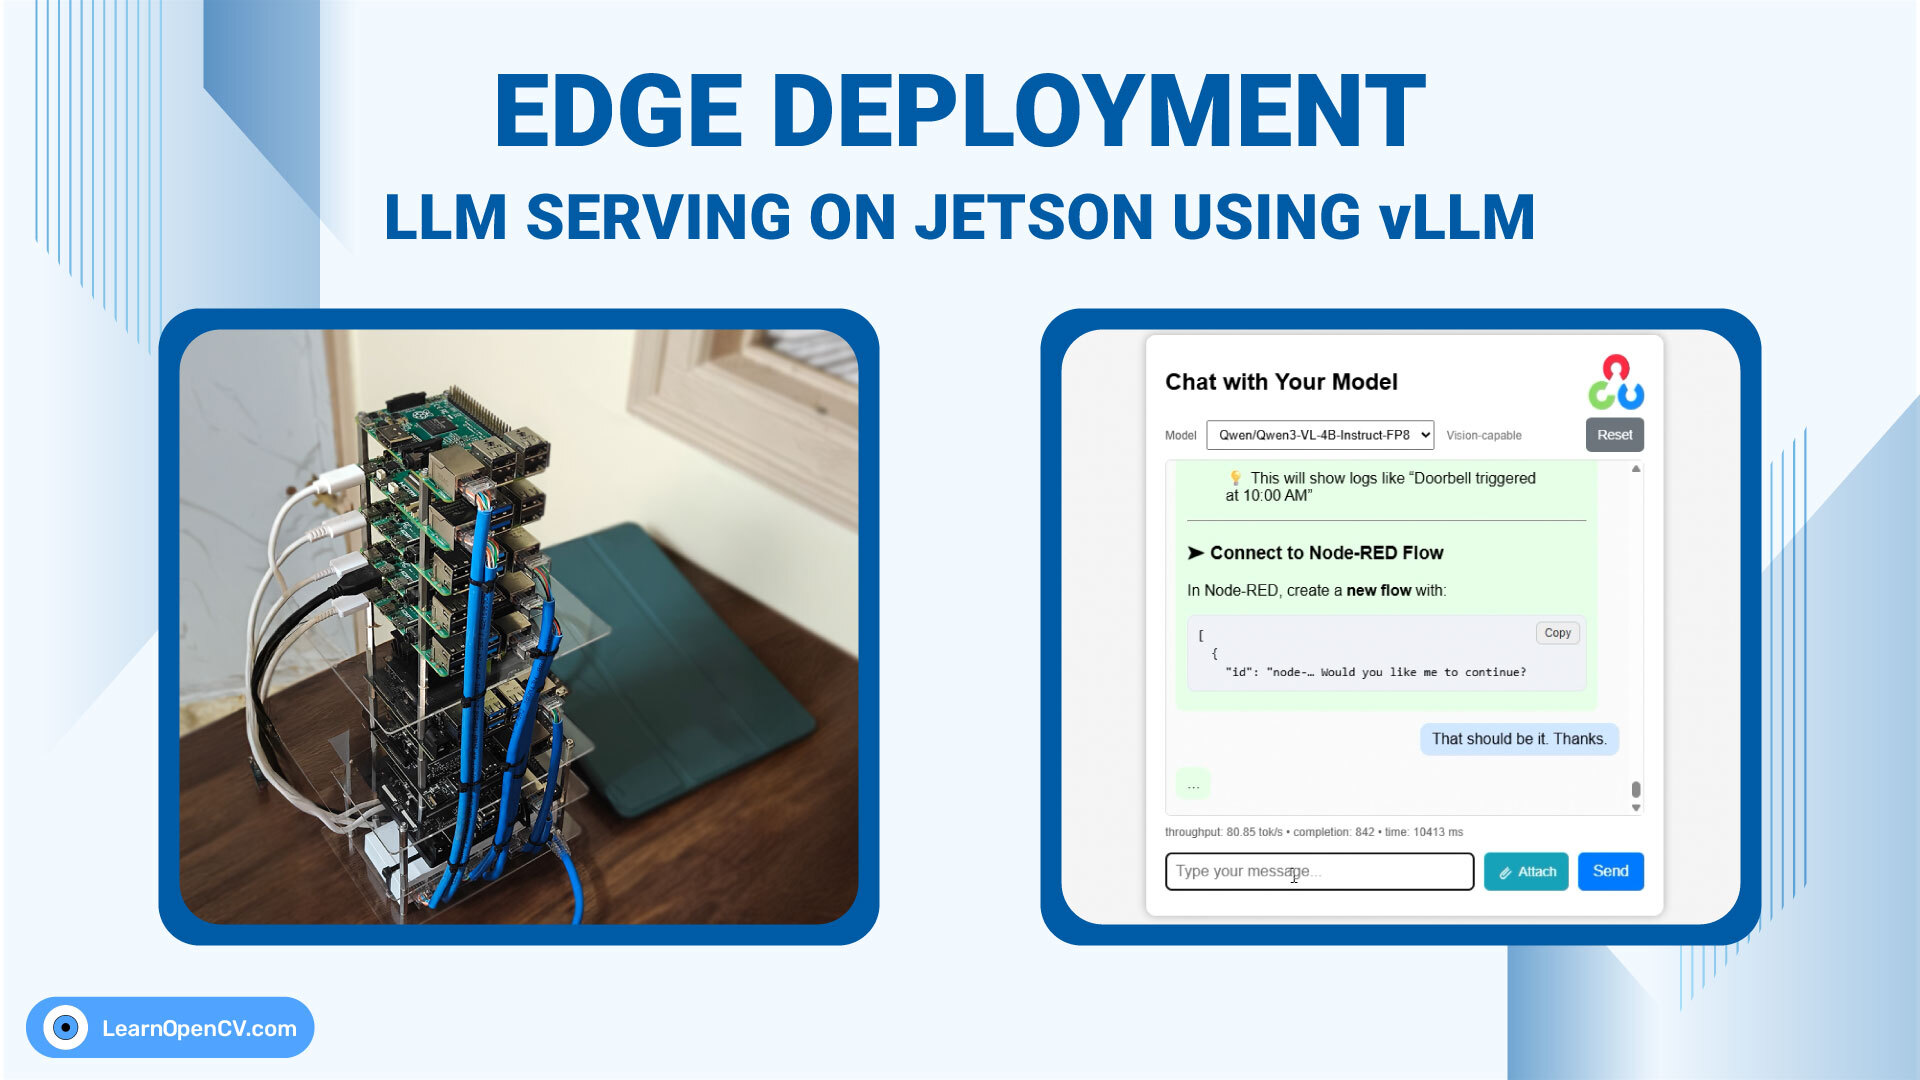
Deployment on Edge: LLM Serving on Jetson using vLLM

Optimize LLM serving with vLLM on Intel® GPUs - Intel Community
vLLM Production Deployment Guide 2026 | Lyceum | Lyceum Technology
Advertisement Space (336x280)

Install vLLM on Linux for Production LLM Serving (2026 Guide)

Optimizing LLM Throughput with vLLM: Understanding the Engine Behind ...

GraphRAG local setup via vLLM and Ollama : A detailed integration guide ...

LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...