
250305248 Optimizing Llm Inference Throughput Via Memory Aware And

Optimizing LLM Inference Throughput via Memory-aware and SLA ...
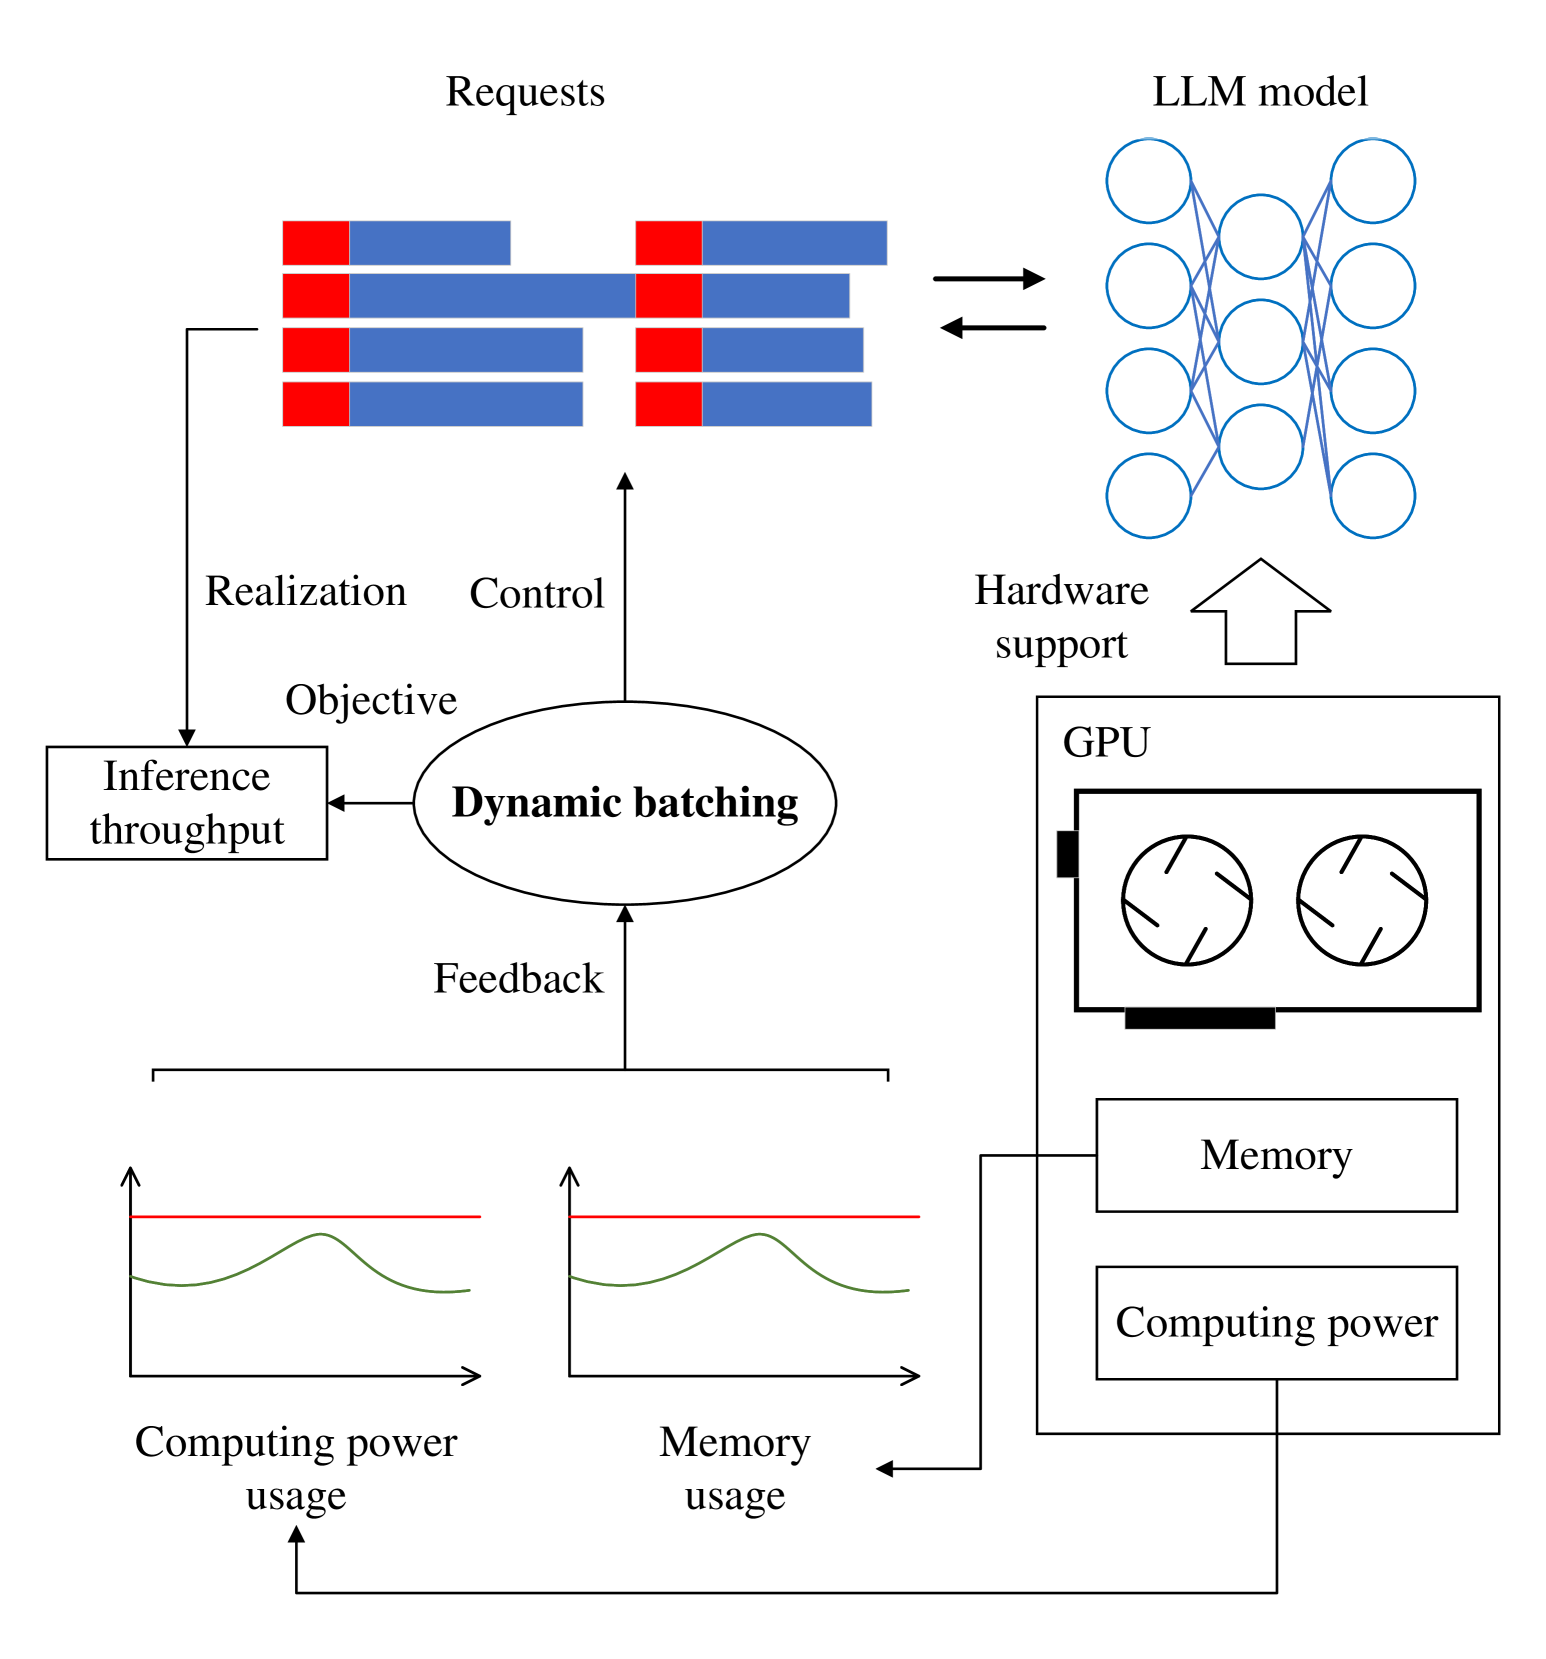
[2503.05248] Optimizing LLM Inference Throughput via Memory-aware and ...

[2503.05248] Optimizing LLM Inference Throughput via Memory-aware and ...

[2503.05248] Optimizing LLM Inference Throughput via Memory-aware and ...

[2503.05248] Optimizing LLM Inference Throughput via Memory-aware and ...
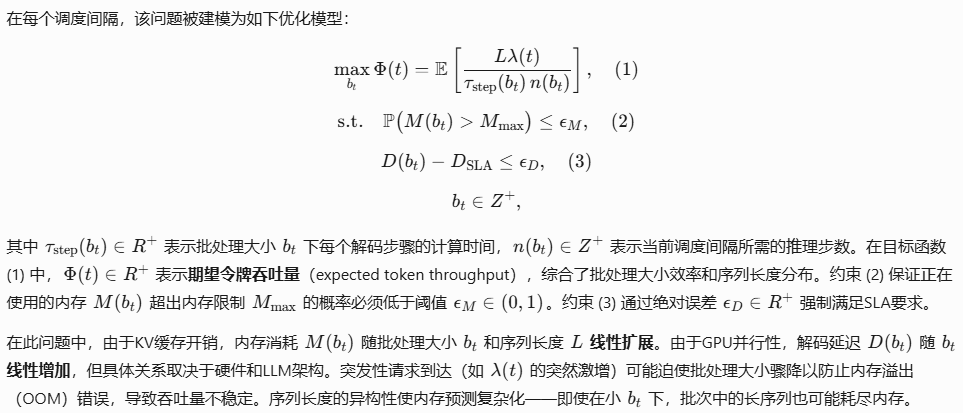
【大模型推理】Optimizing LLM Inference Throughput via Memory-aware and SLA ...
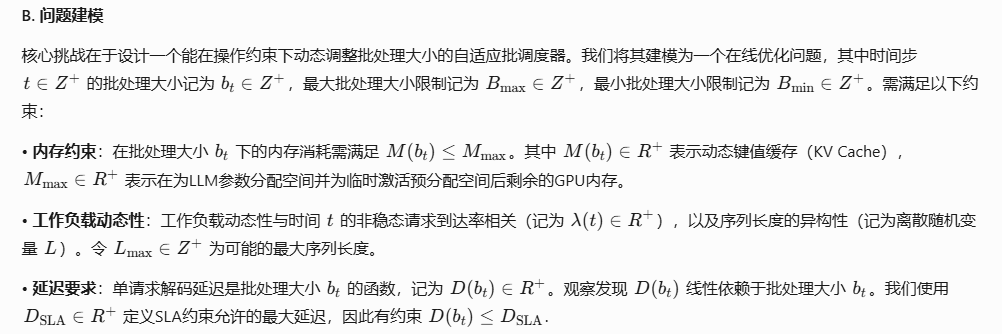
【大模型推理】Optimizing LLM Inference Throughput via Memory-aware and SLA ...
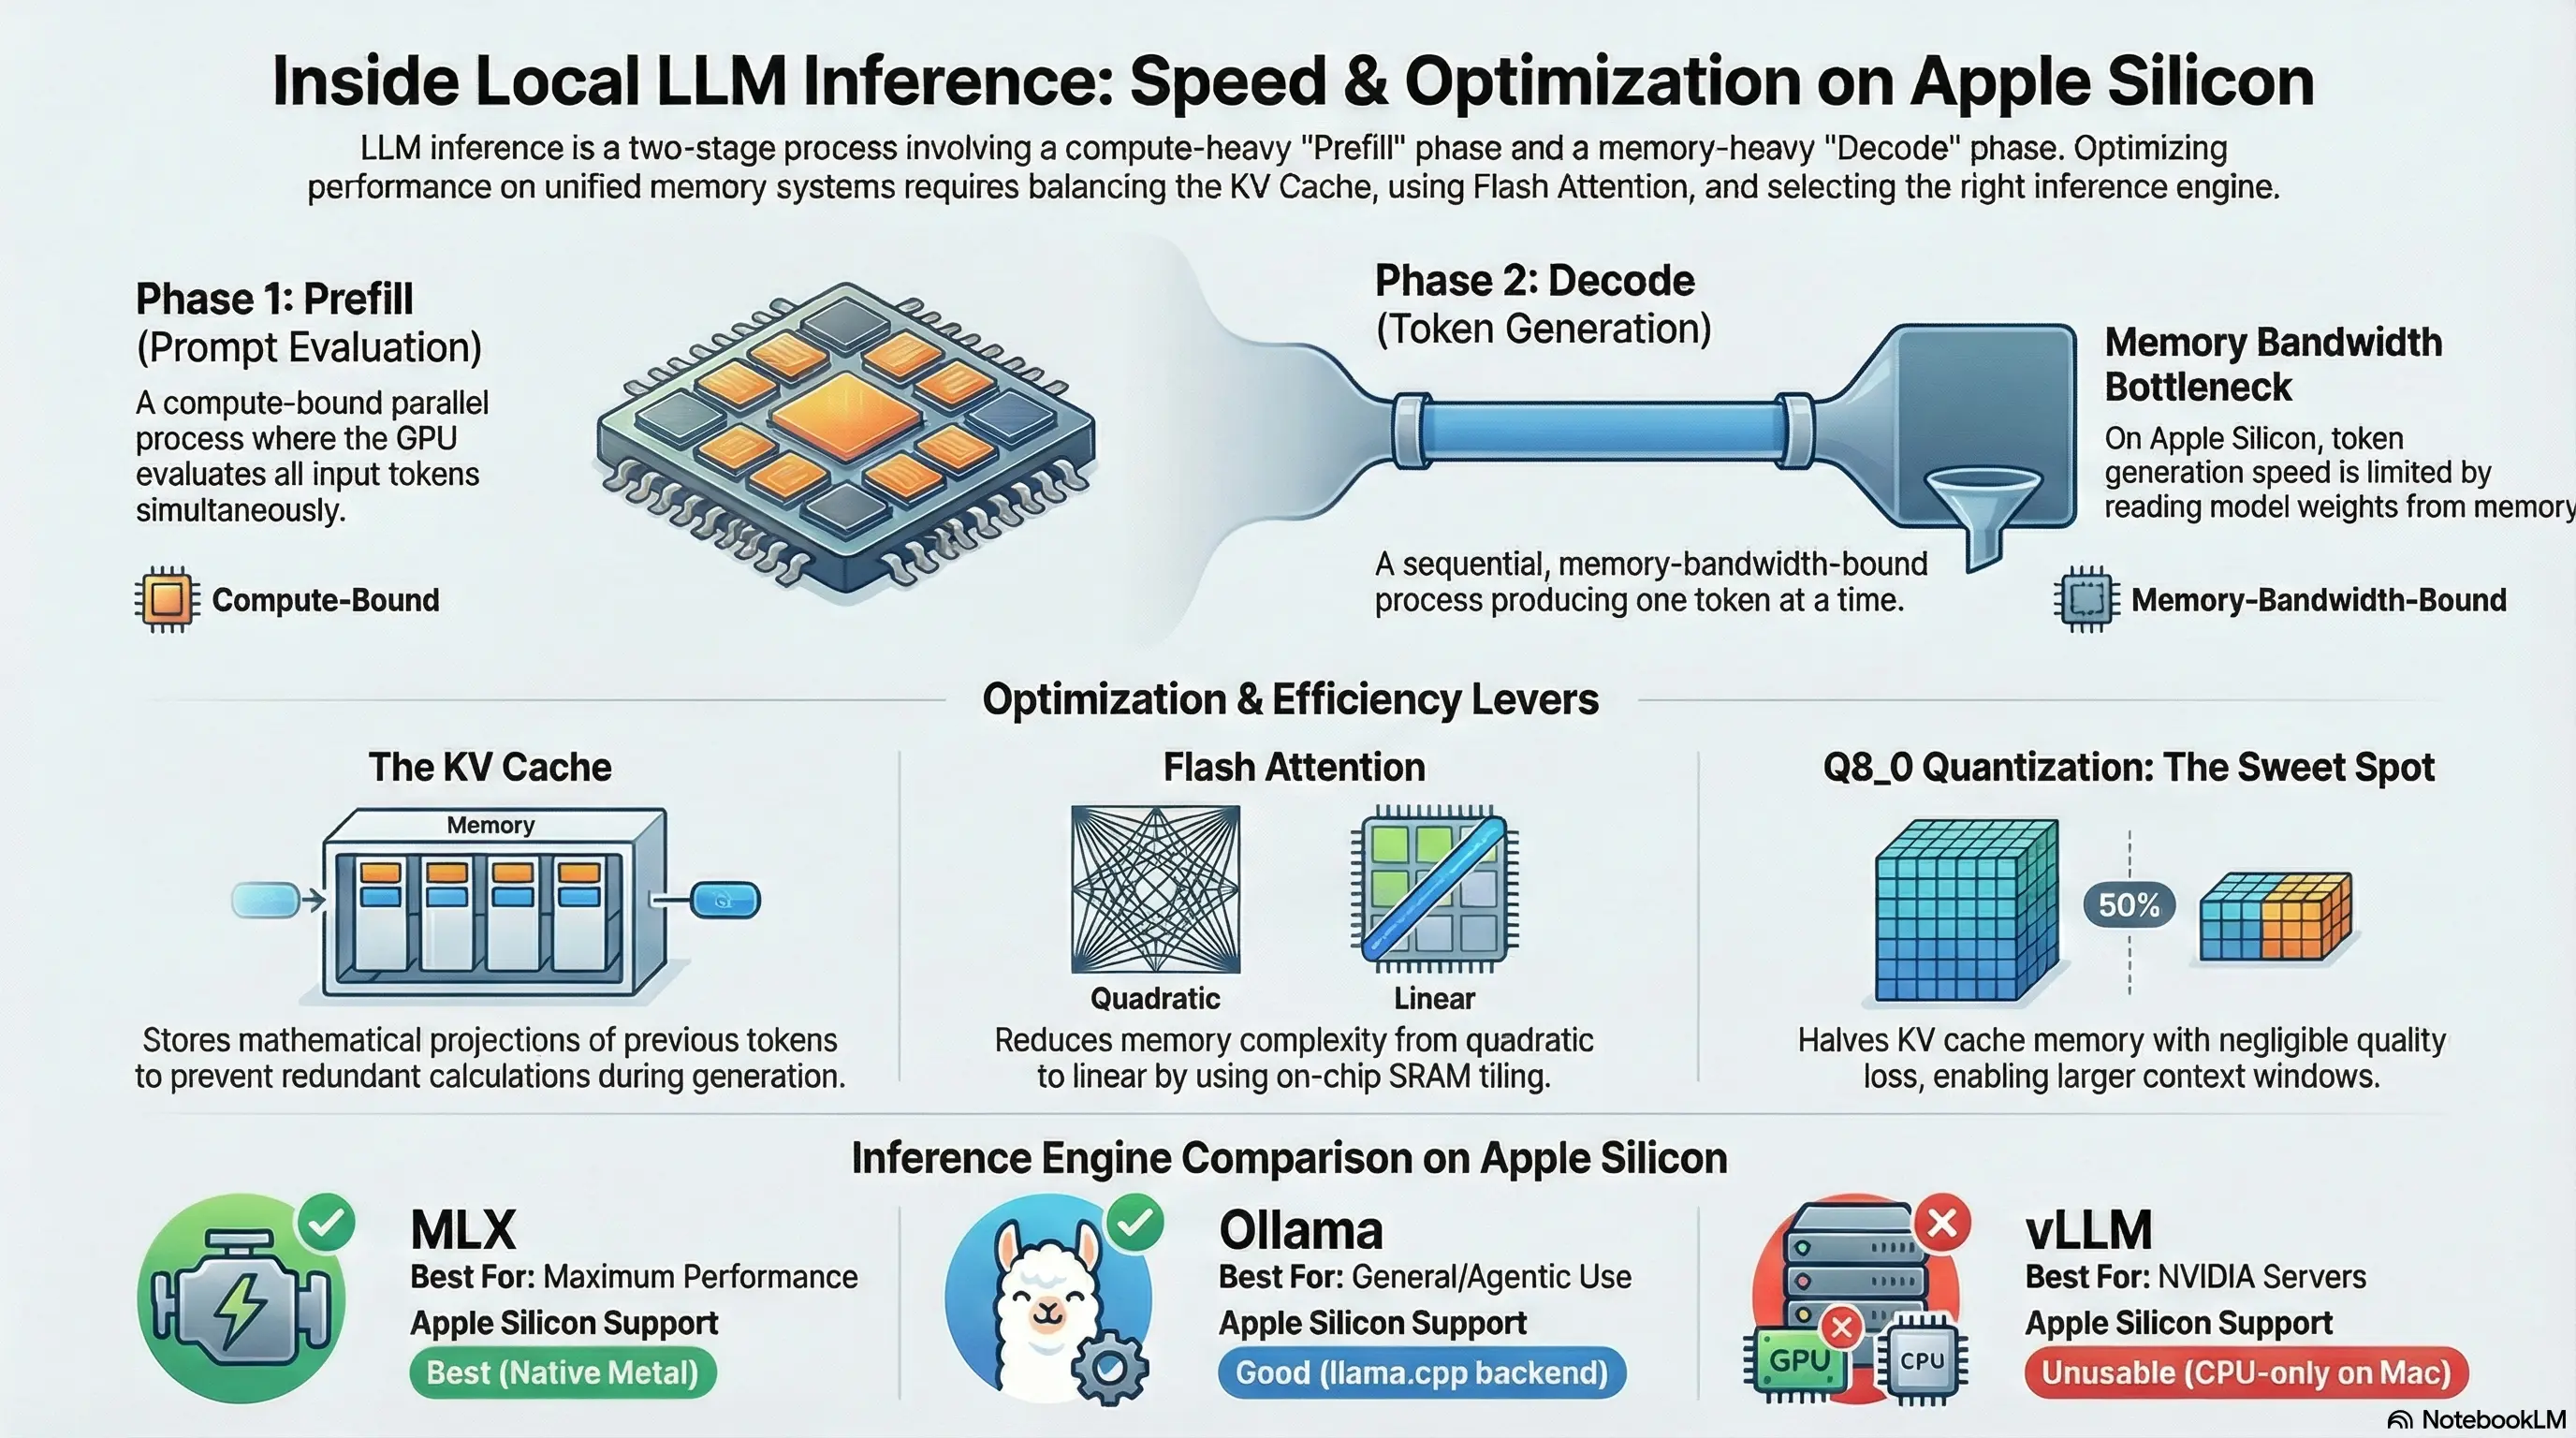
LLM Inference Internals: KV Cache, Flash Attention, and Optimizing for ...

Optimizing Local LLM Inference On Apple M4: Memory Bottlenecks Vs ...
Optimizing LLM inference for higher throughput
Advertisement Space (300x250)

(PDF) Optimizing LLM Latency and Throughput for Interactive Web Interfaces

LLM Inference Performance: Latency and Throughput Metrics - YouTube

[论文评述] Amplifying Effective CXL Memory Bandwidth for LLM Inference via ...

Lessons Learned Scaling LLM Training and Inference with Direct Memory ...

(PDF) Characterizing and Optimizing LLM Inference Workloads on CPU-GPU ...

LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

ZipServ: Fast and Memory-Efficient LLM Inference with Hardware-Aware ...
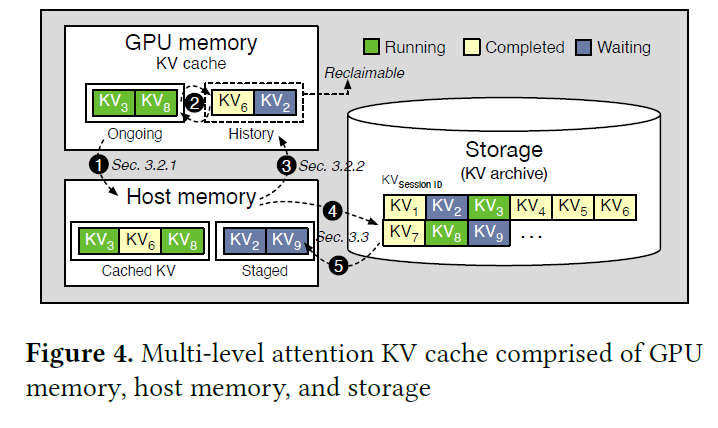
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
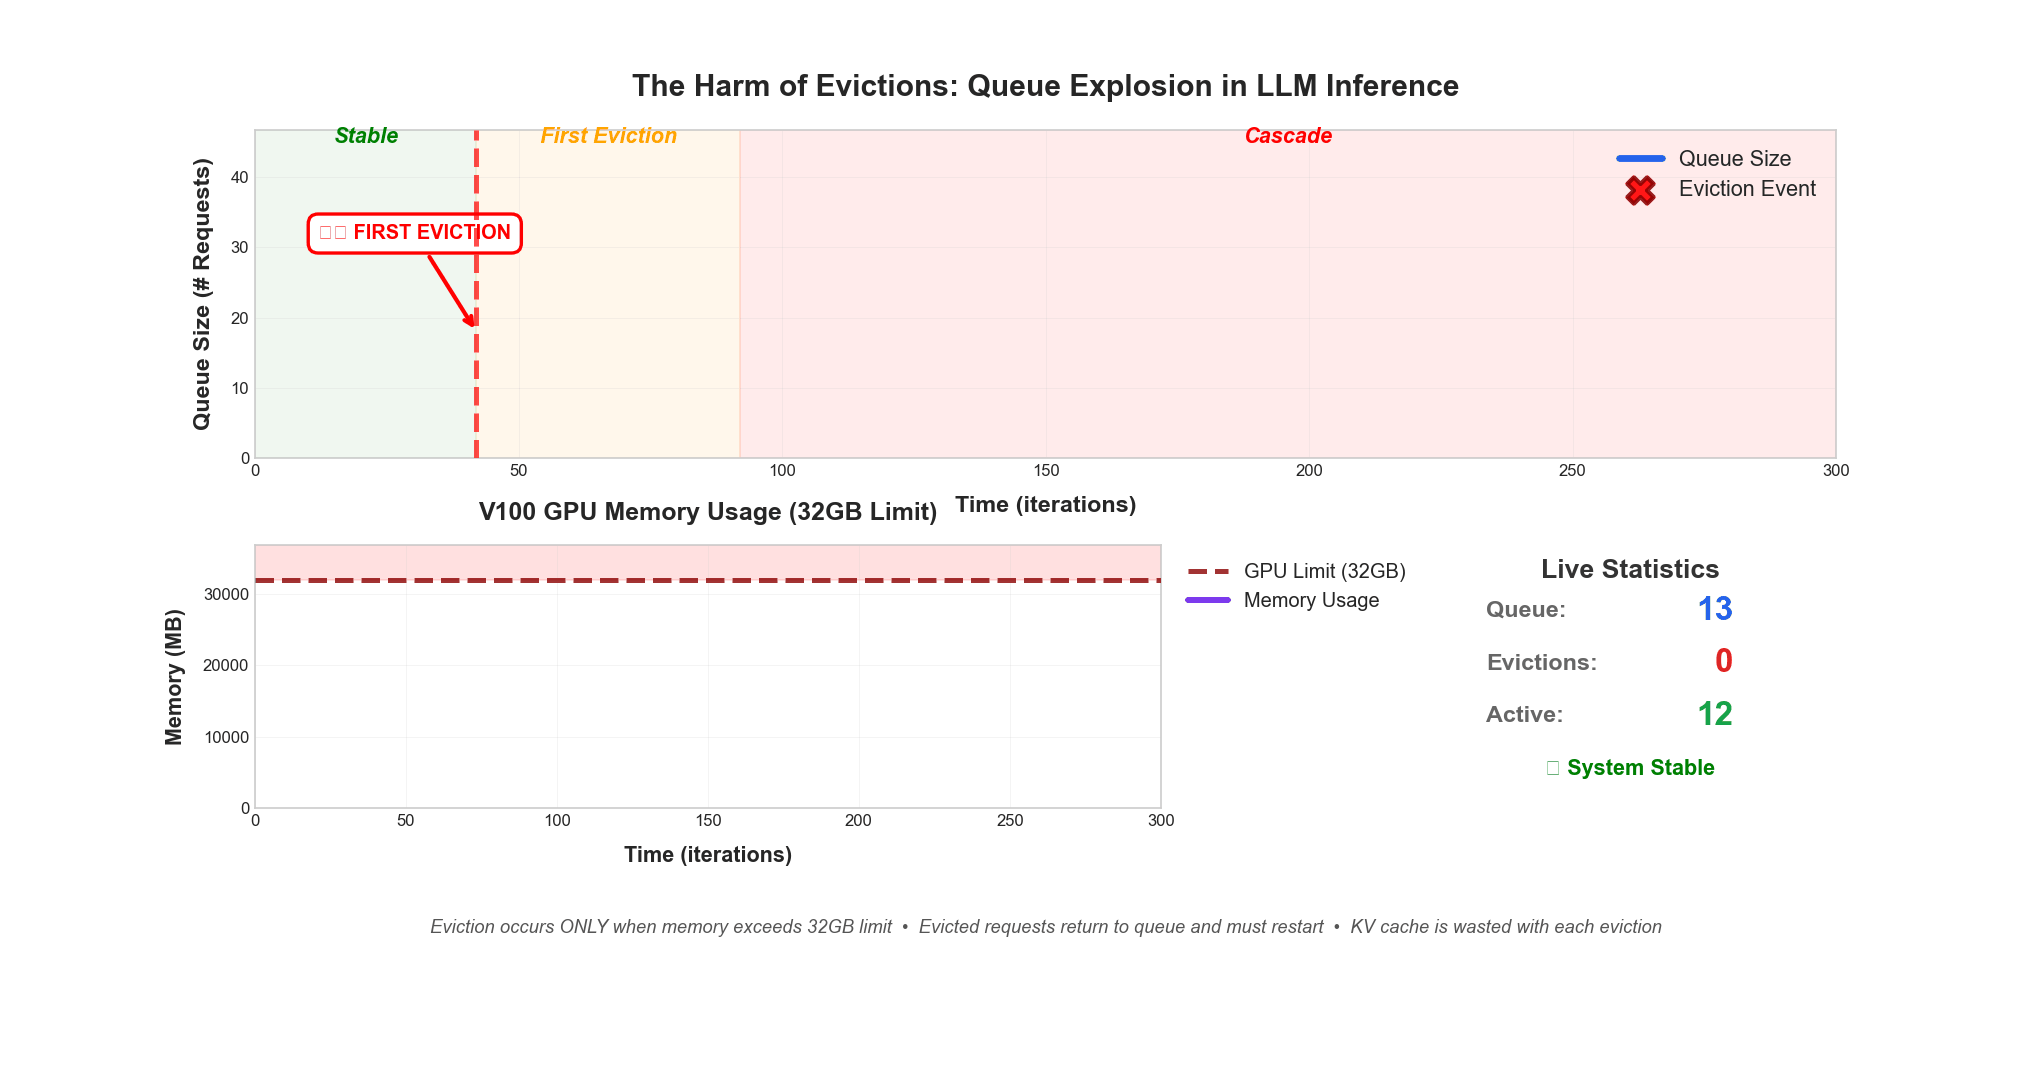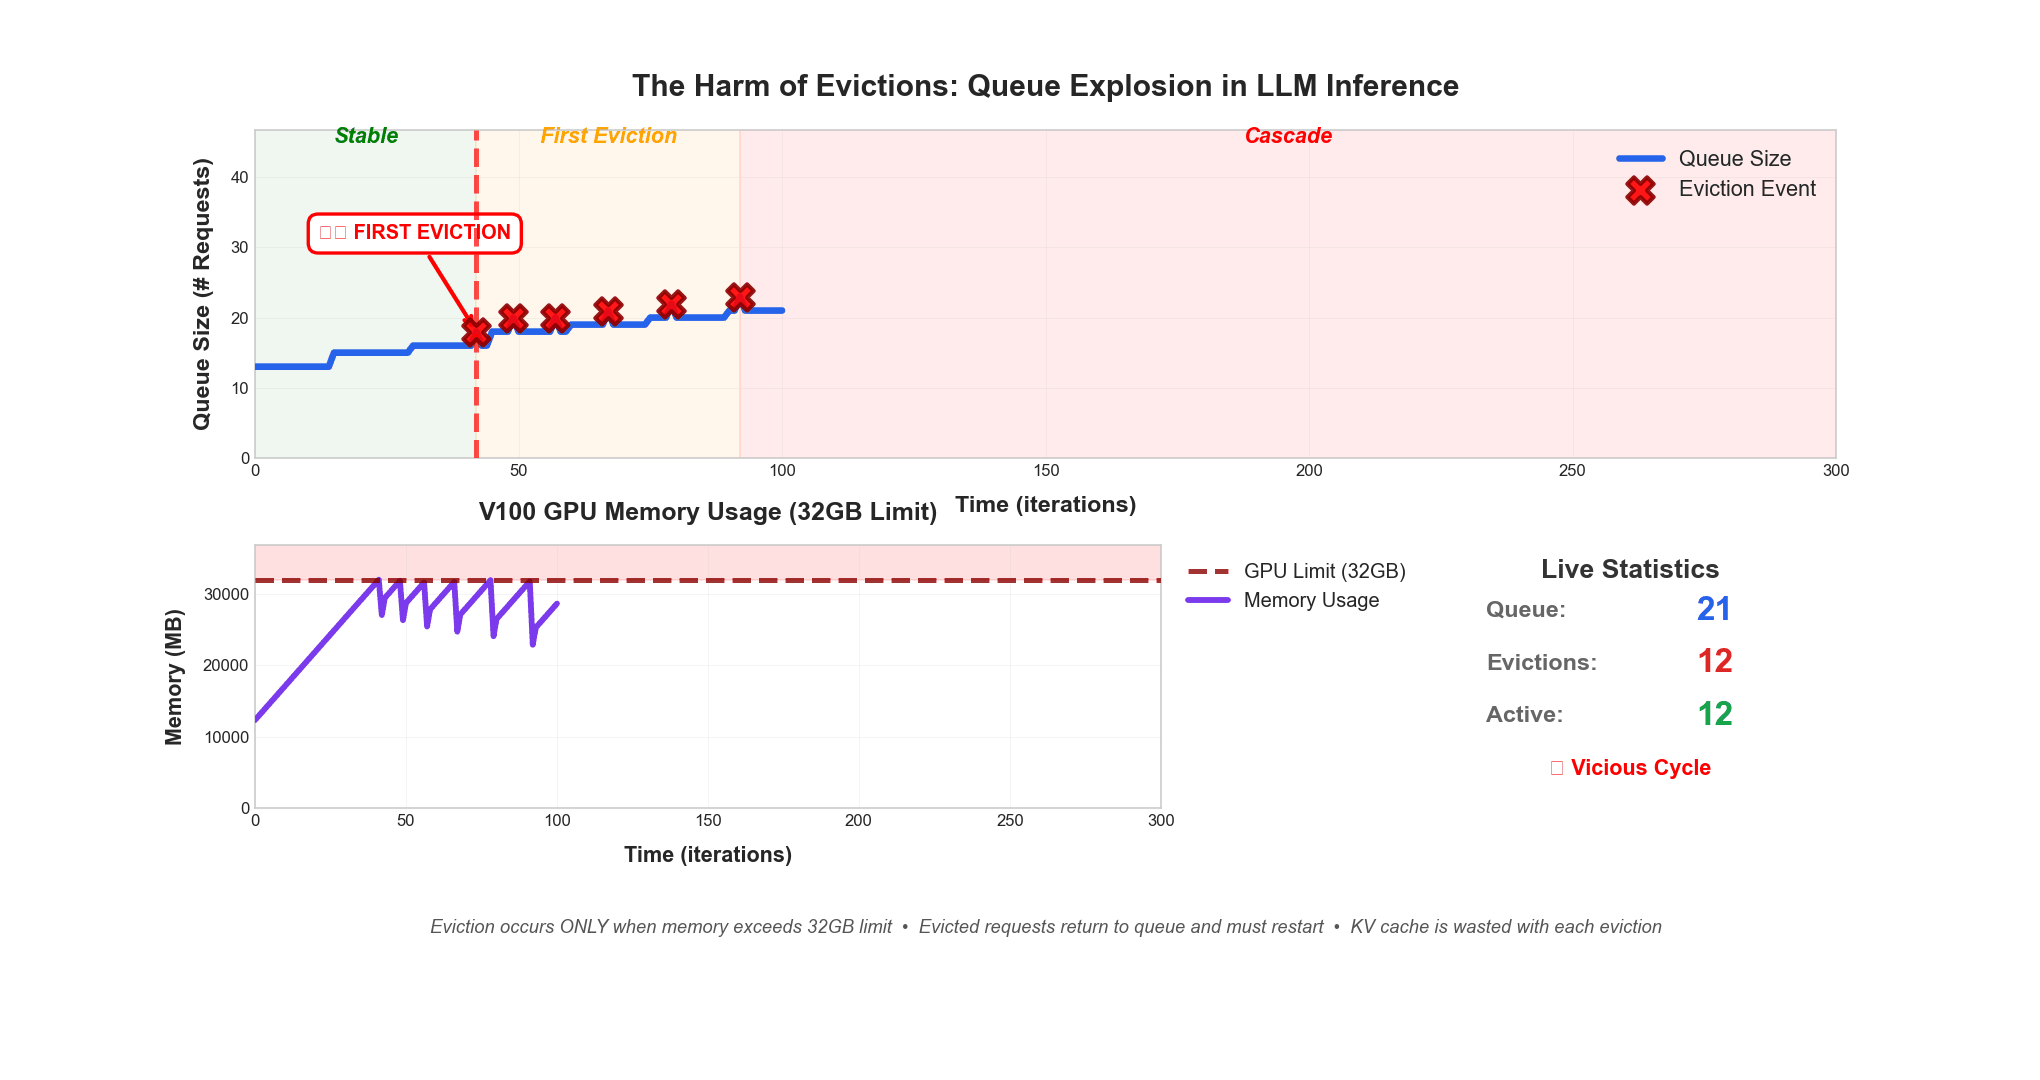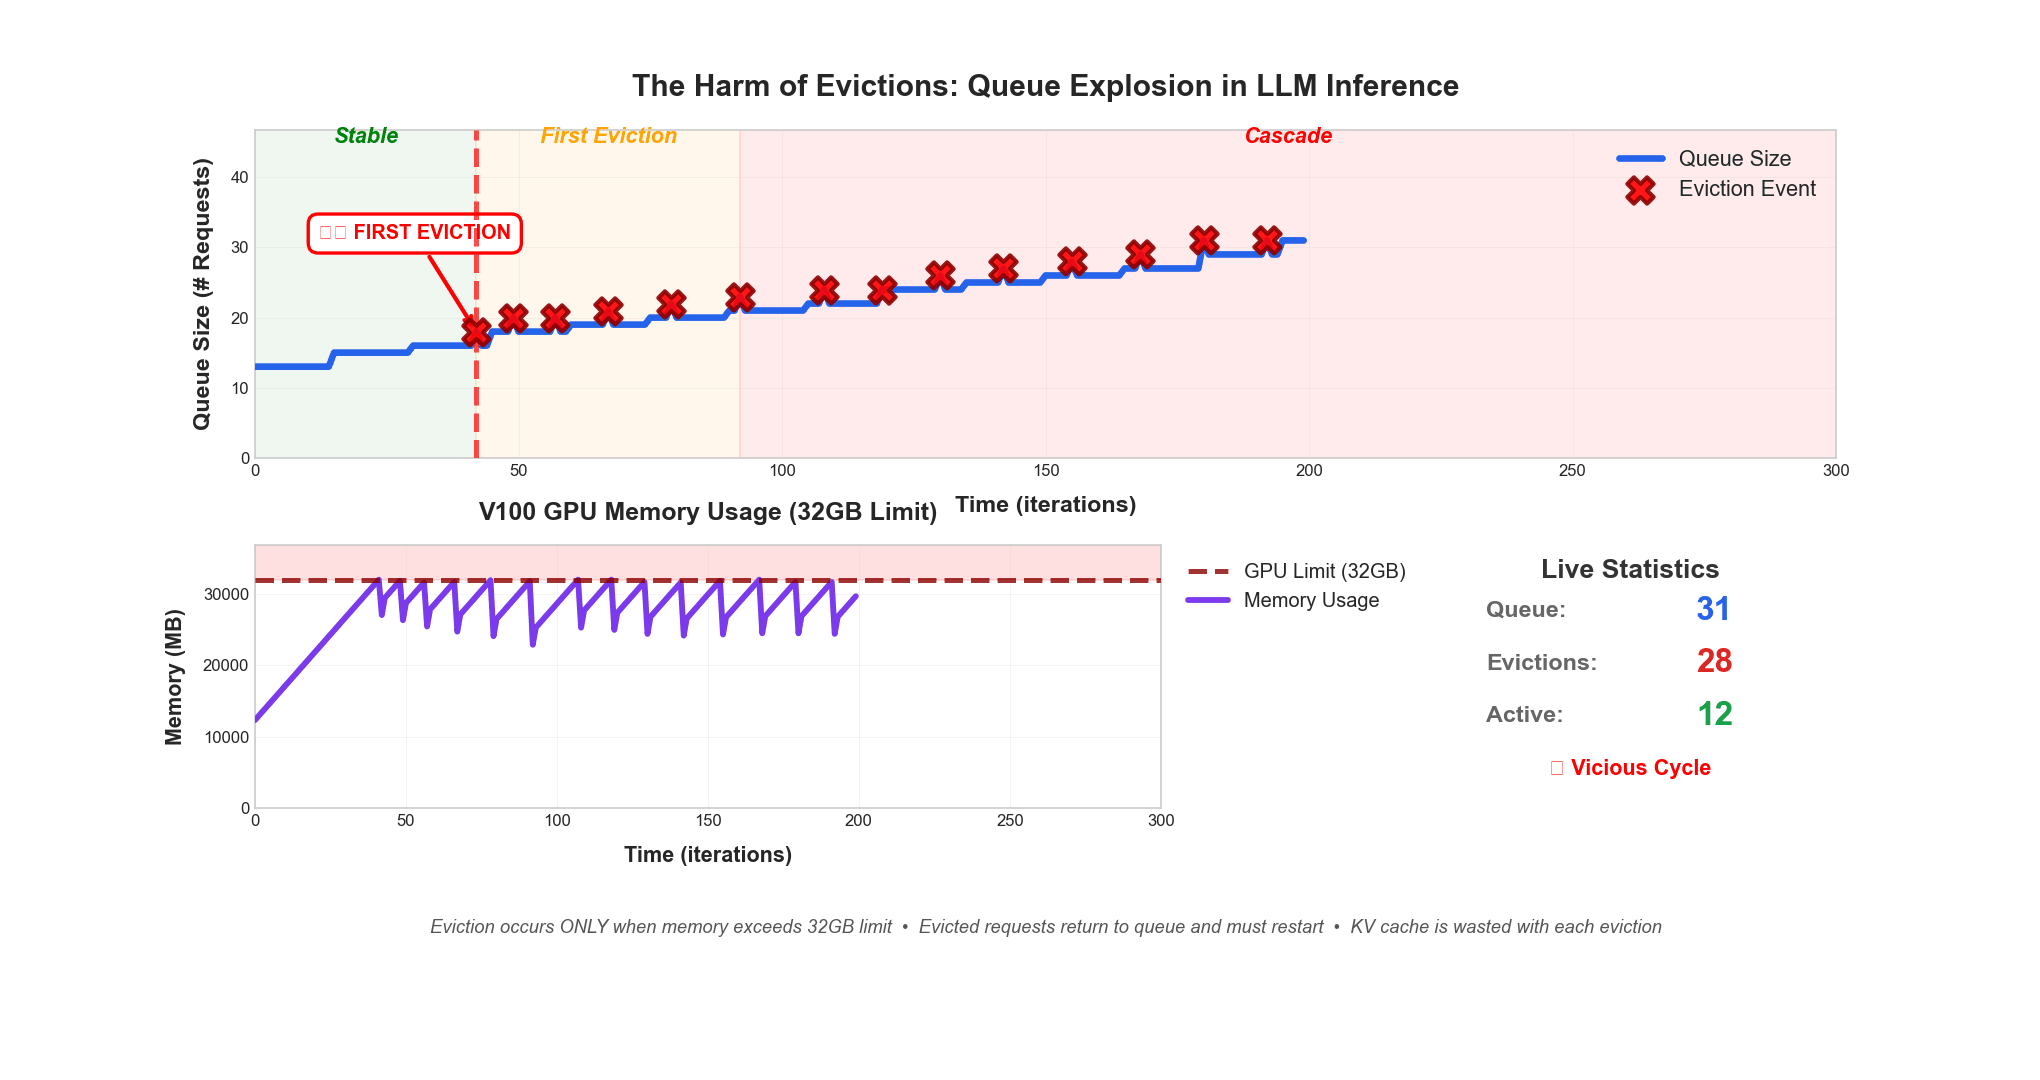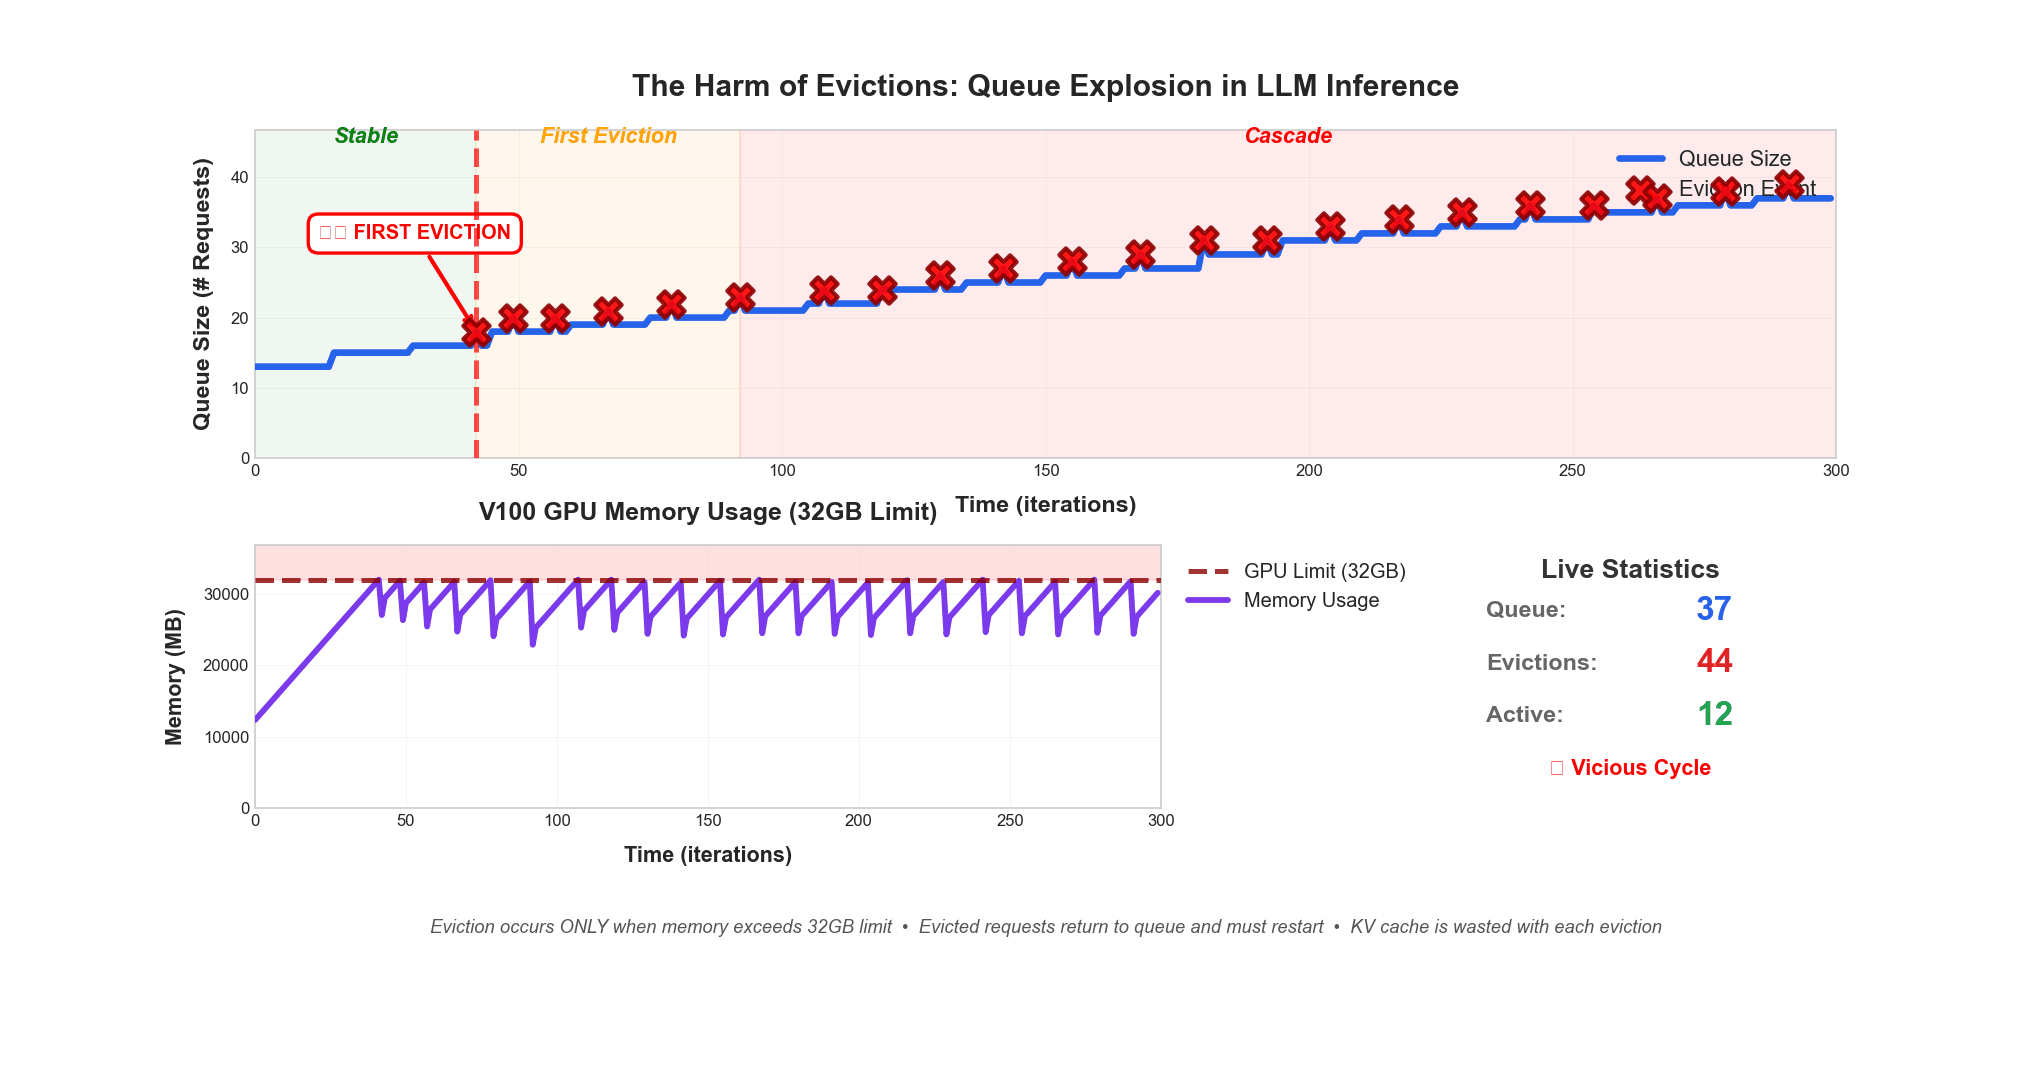
Optimizing LLM Inference: Fluid-Guided Online Scheduling with Memory ...

GPU Memory Bandwidth Limits LLM Inference Performance | Rajan Sethi ...
Advertisement Space (336x280)

Optimizing LLM Throughput with vLLM: Understanding the Engine Behind ...
Estimating LLM Inference Memory Requirements
Memory Bandwidth — The Real Bottleneck in LLM Inference | tutorialQ
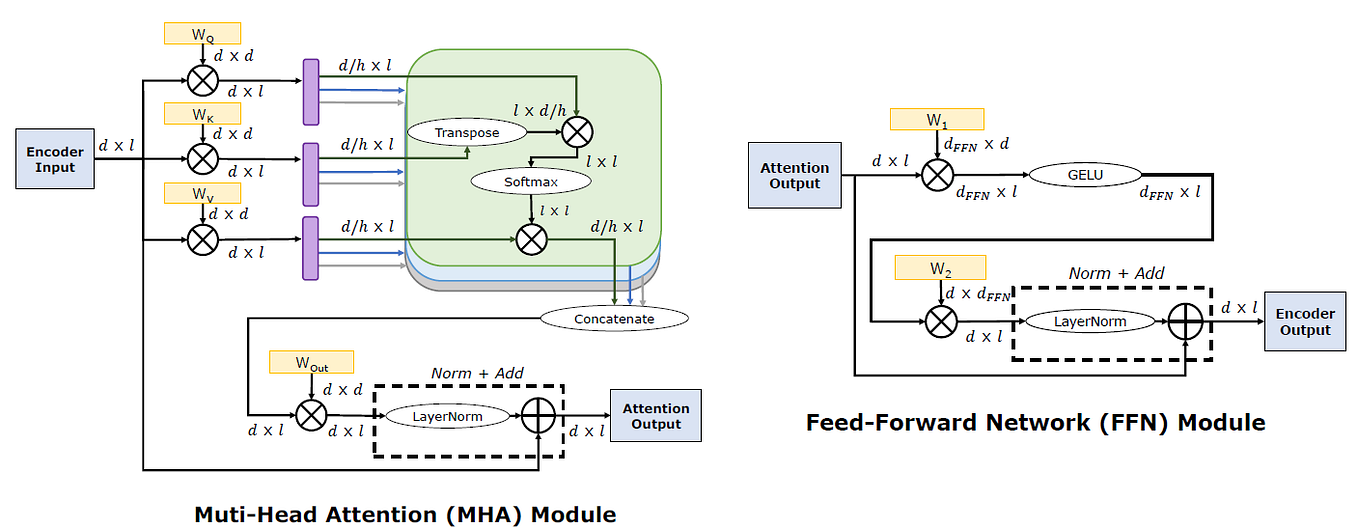
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

Optimizing LLM Inference: Metrics, Memory, Math, and System | Burak ...

Optimizing LLM Inference for Maximum Efficiency

CPU-GPU I/O-Aware LLM Inference Reduces Latency in GPUs by Optimizing ...

LLM in a flash: Efficient LLM Inference with Limited Memory
Accelerate Deep Learning and LLM Inference with Apache Spark in the ...

Efficient LLM Inference using Dynamic Input Pruning and Cache-Aware Masking
Advertisement Space (336x280)

How continuous batching enables 23x throughput in LLM inference ...

Optimizing LLM Inference with Azure AI Supercomputing Clusters

LLM Inference Optimization: Techniques That Actually Reduce Latency and ...
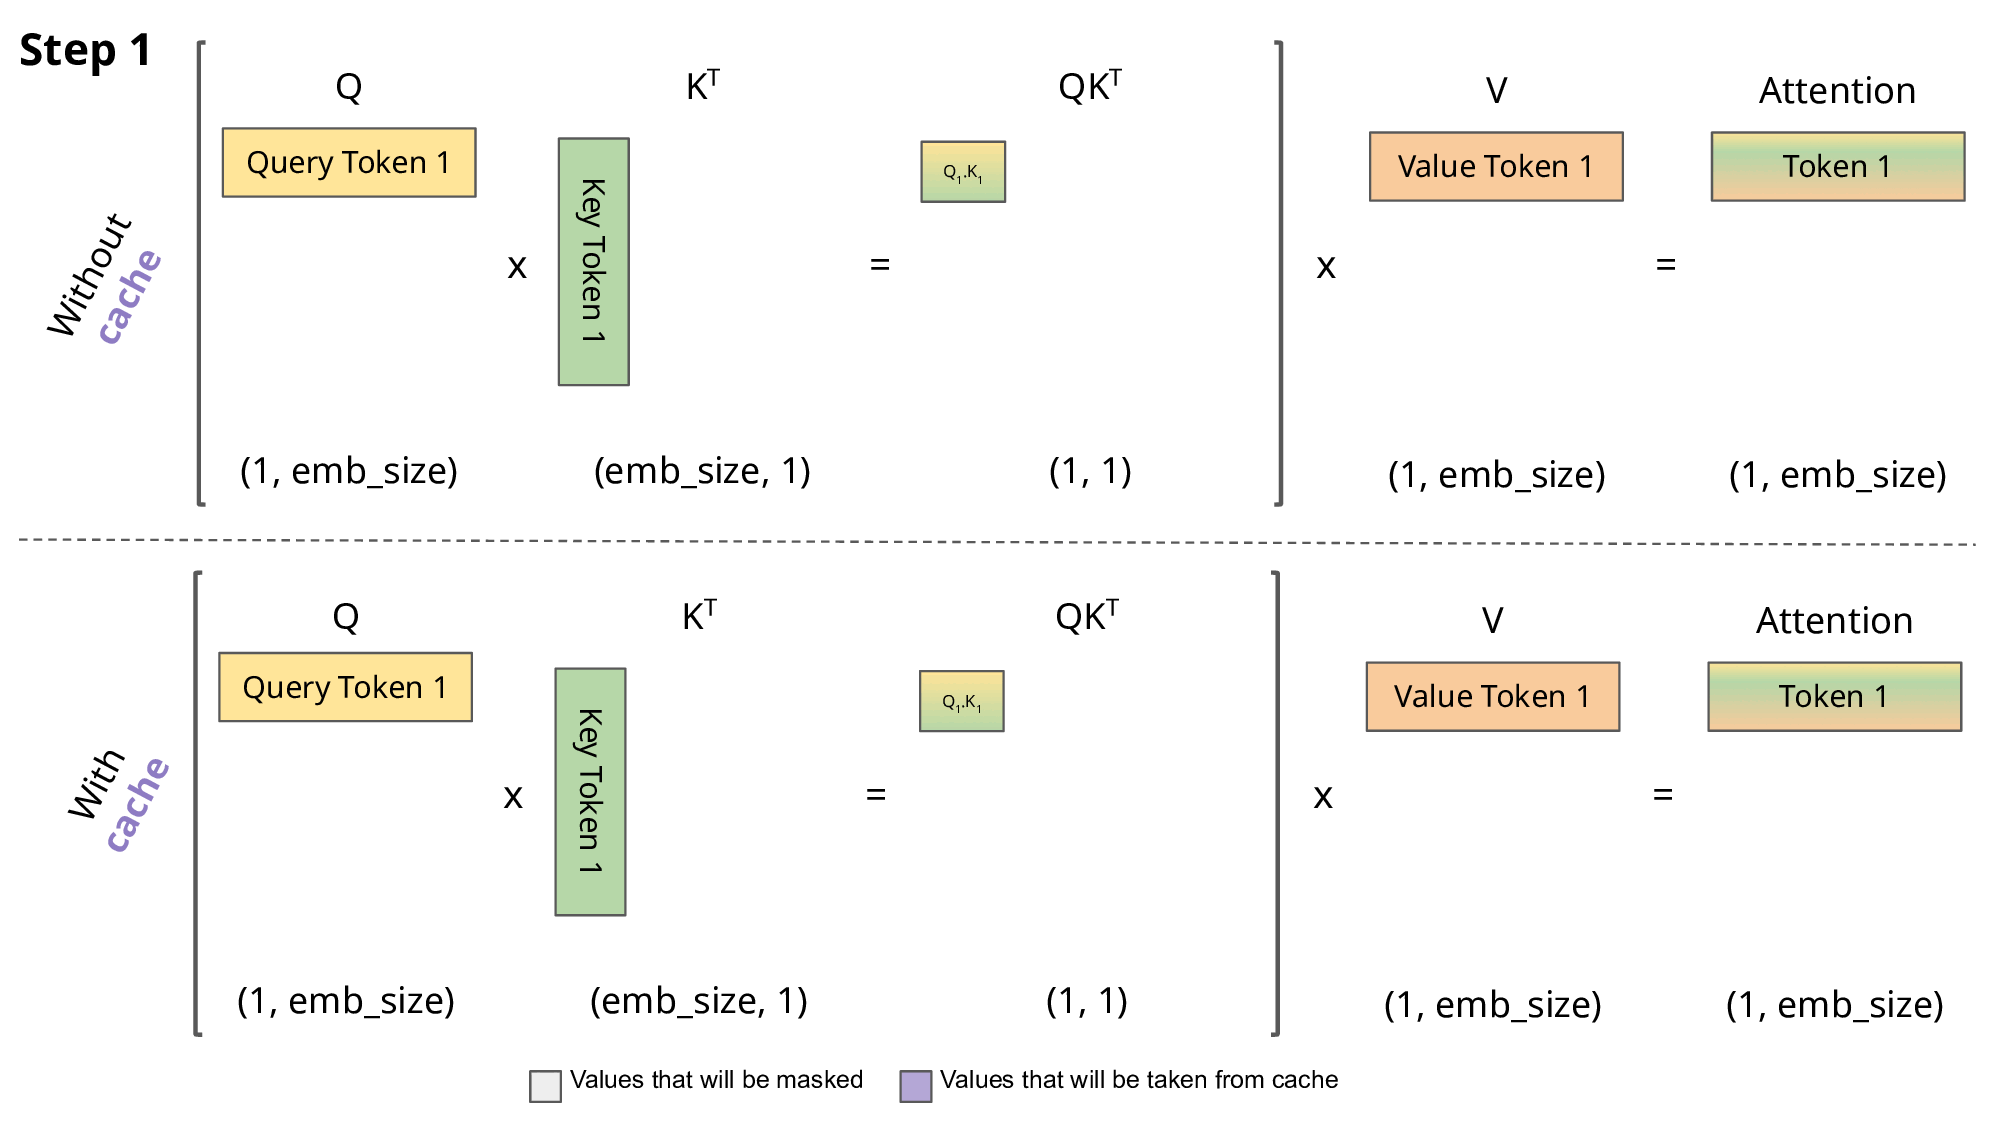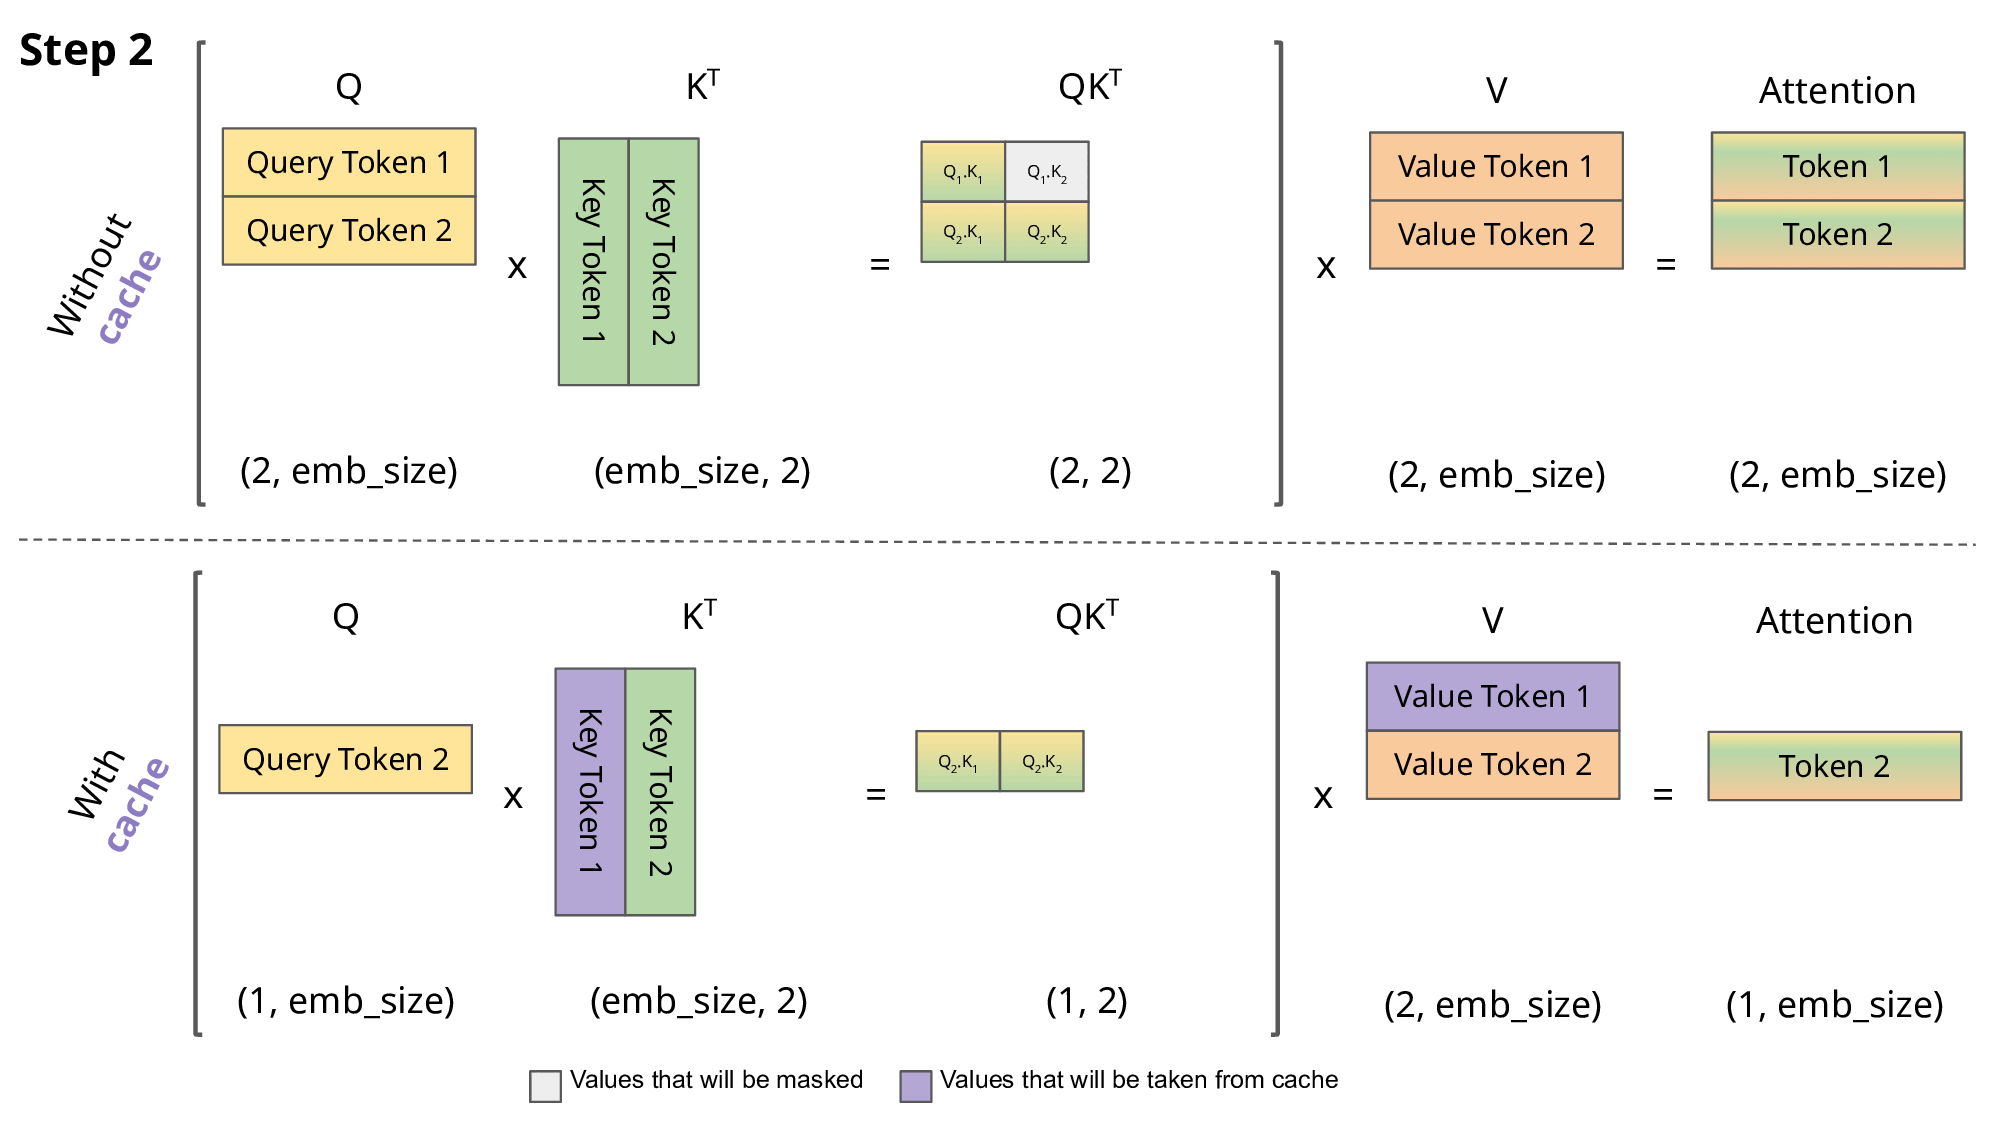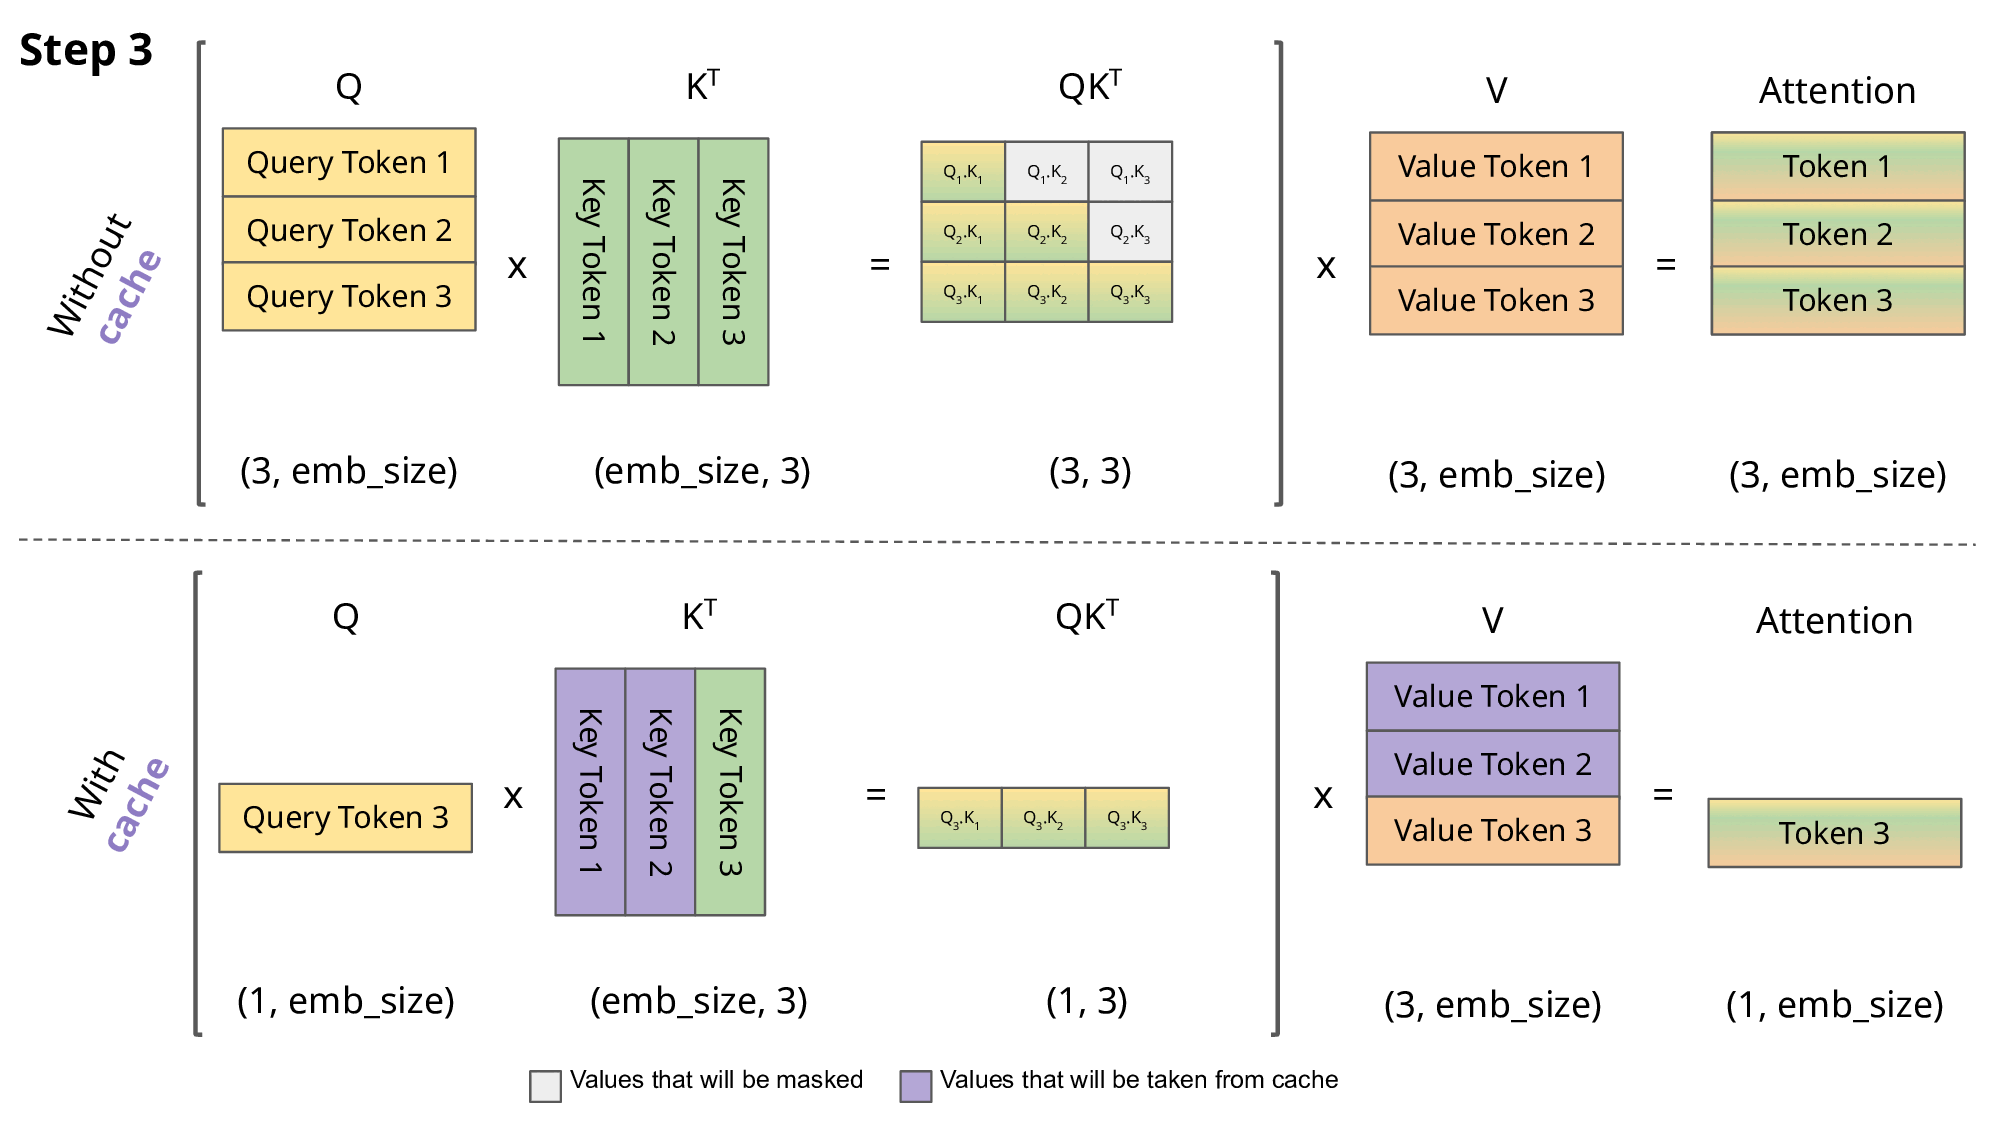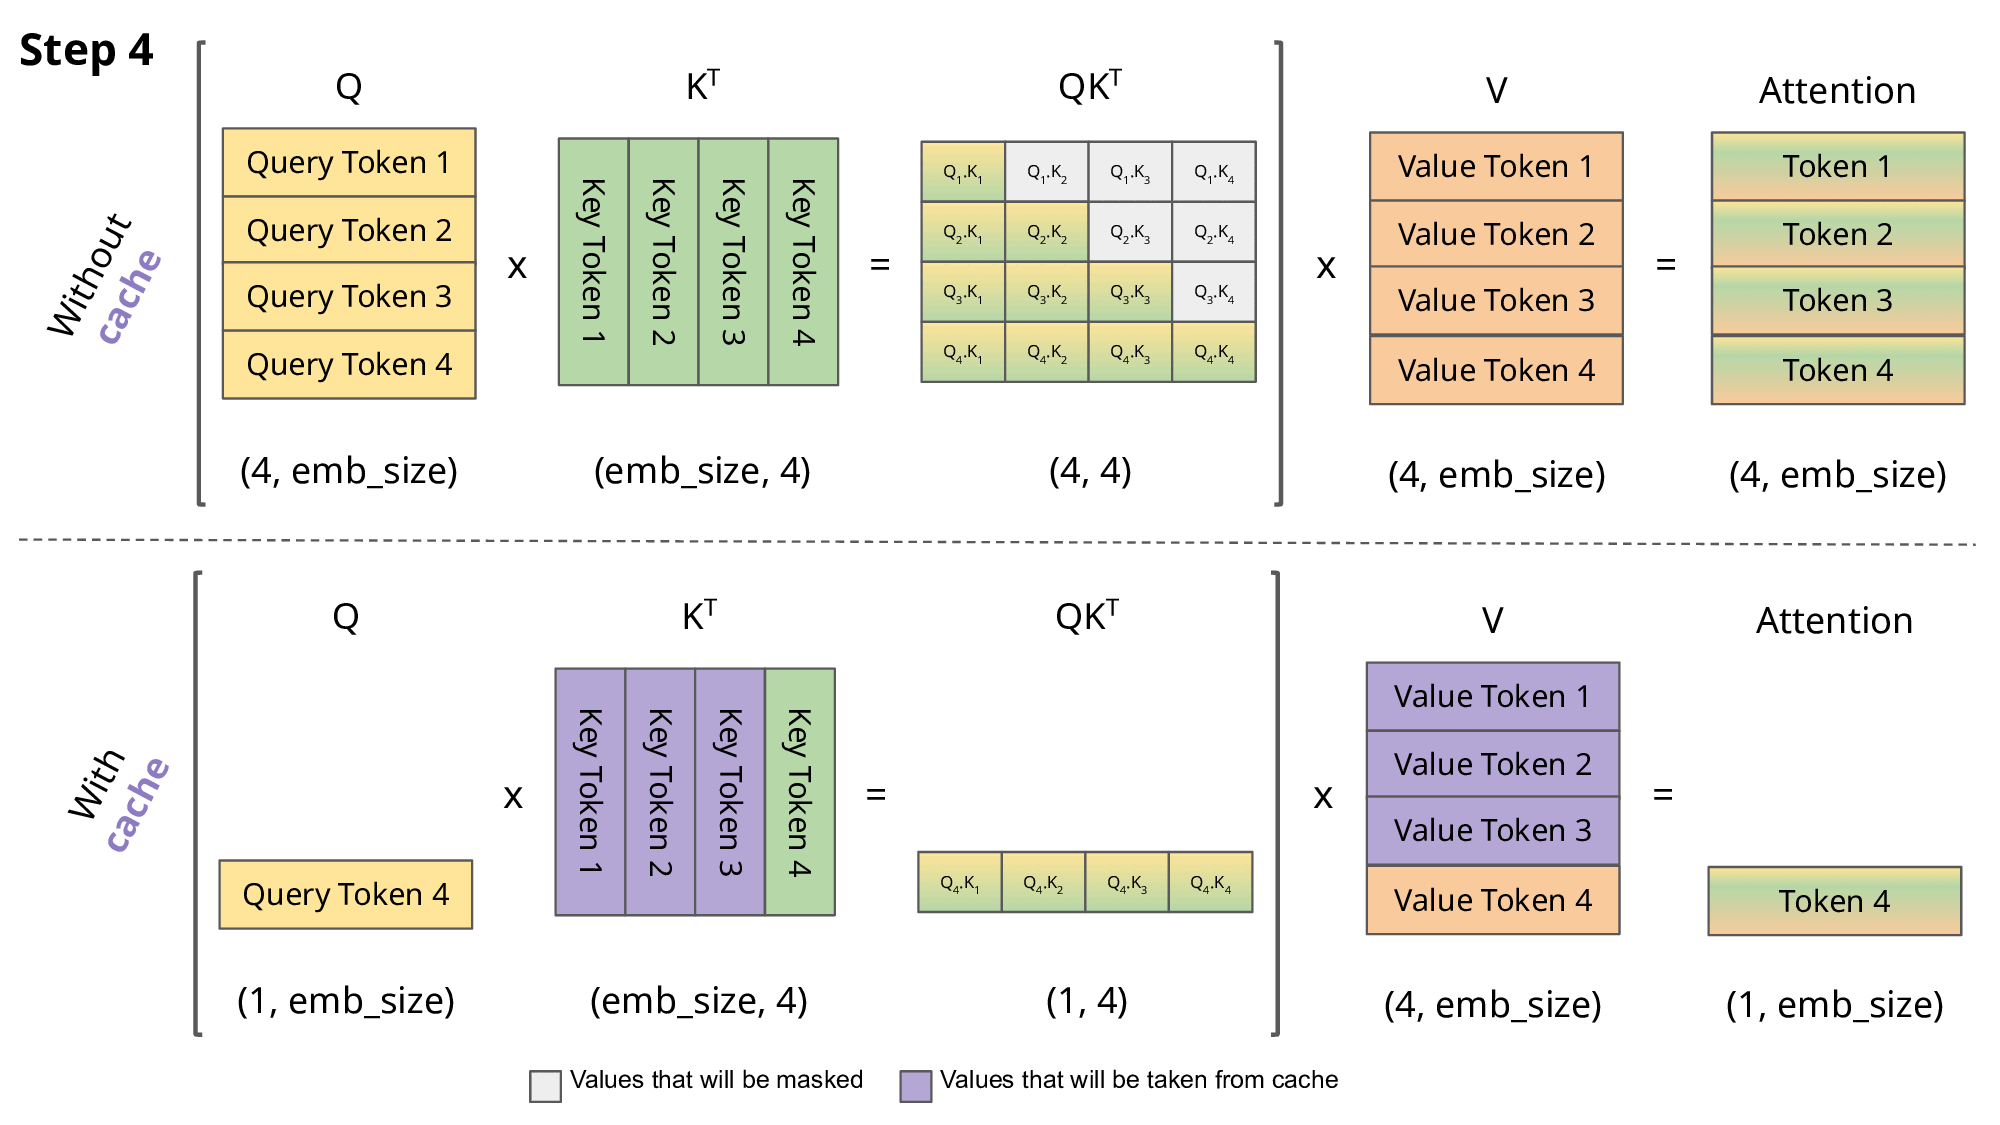
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

How continuous batching enables 23x throughput in LLM inference ...

Paper page - AccLLM: Accelerating Long-Context LLM Inference Via ...