
Run Llm Inference At Maximum Throughput Modal Docs
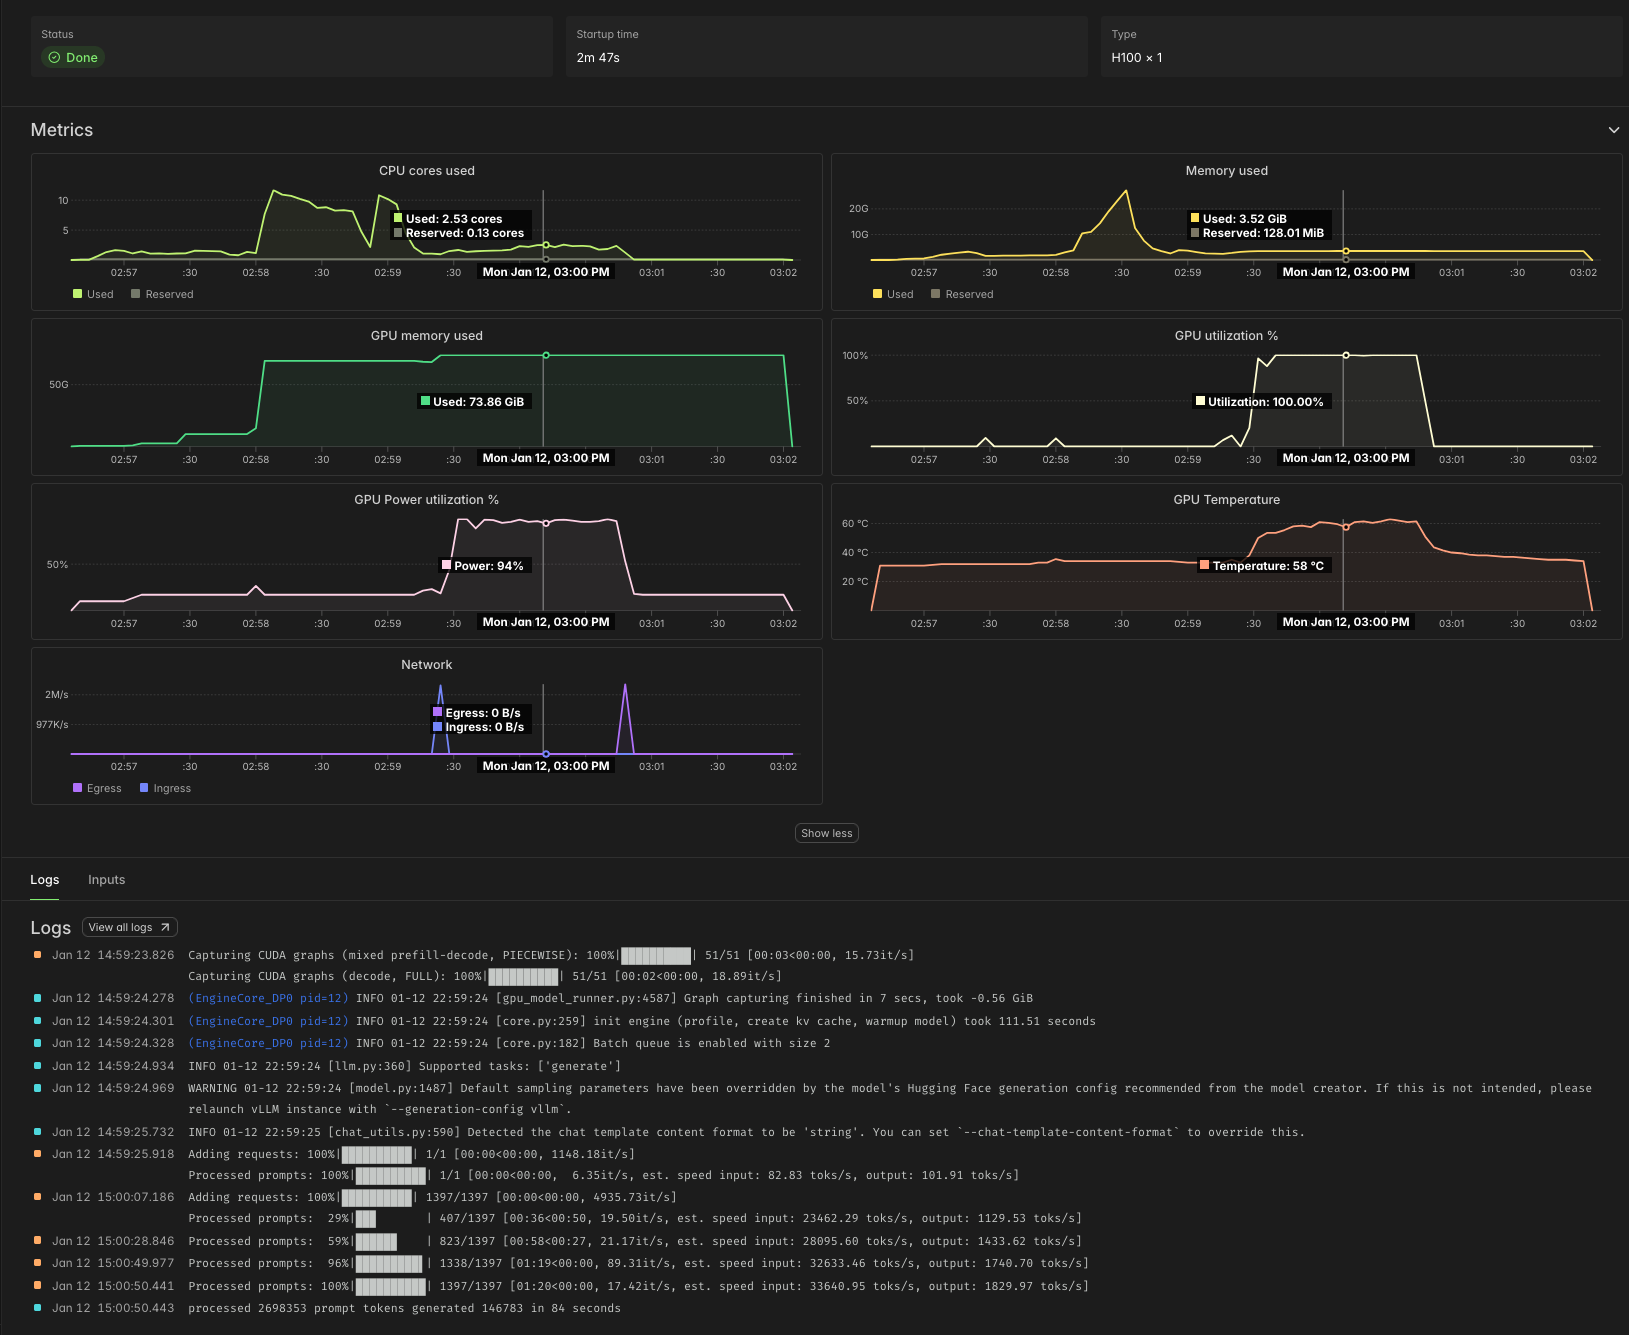
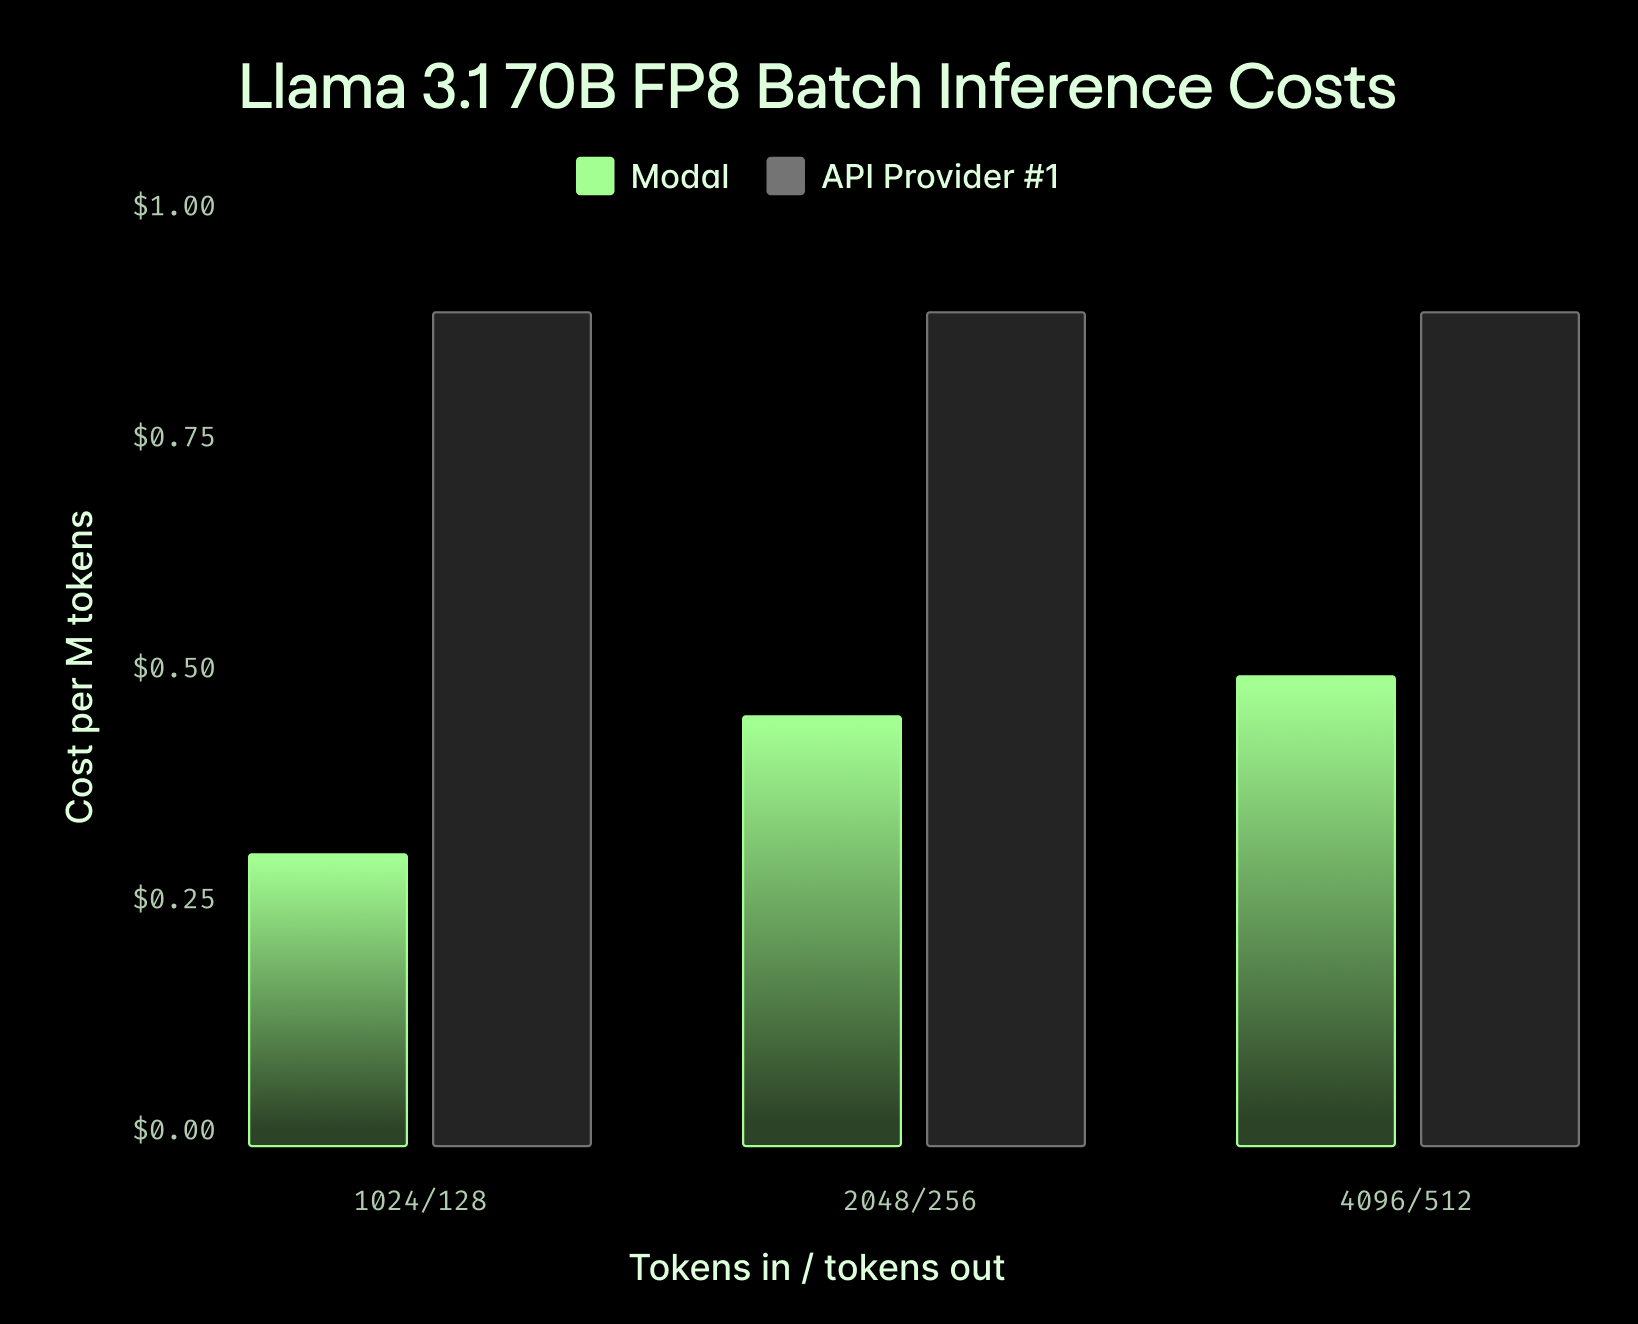
Run LLM inference at maximum throughput | Modal Docs

Run LLM inference at maximum throughput | Modal Docs

Run OpenAI-compatible LLM inference with Qwen and vLLM | Modal Docs

High-performance LLM inference | Modal Docs

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...
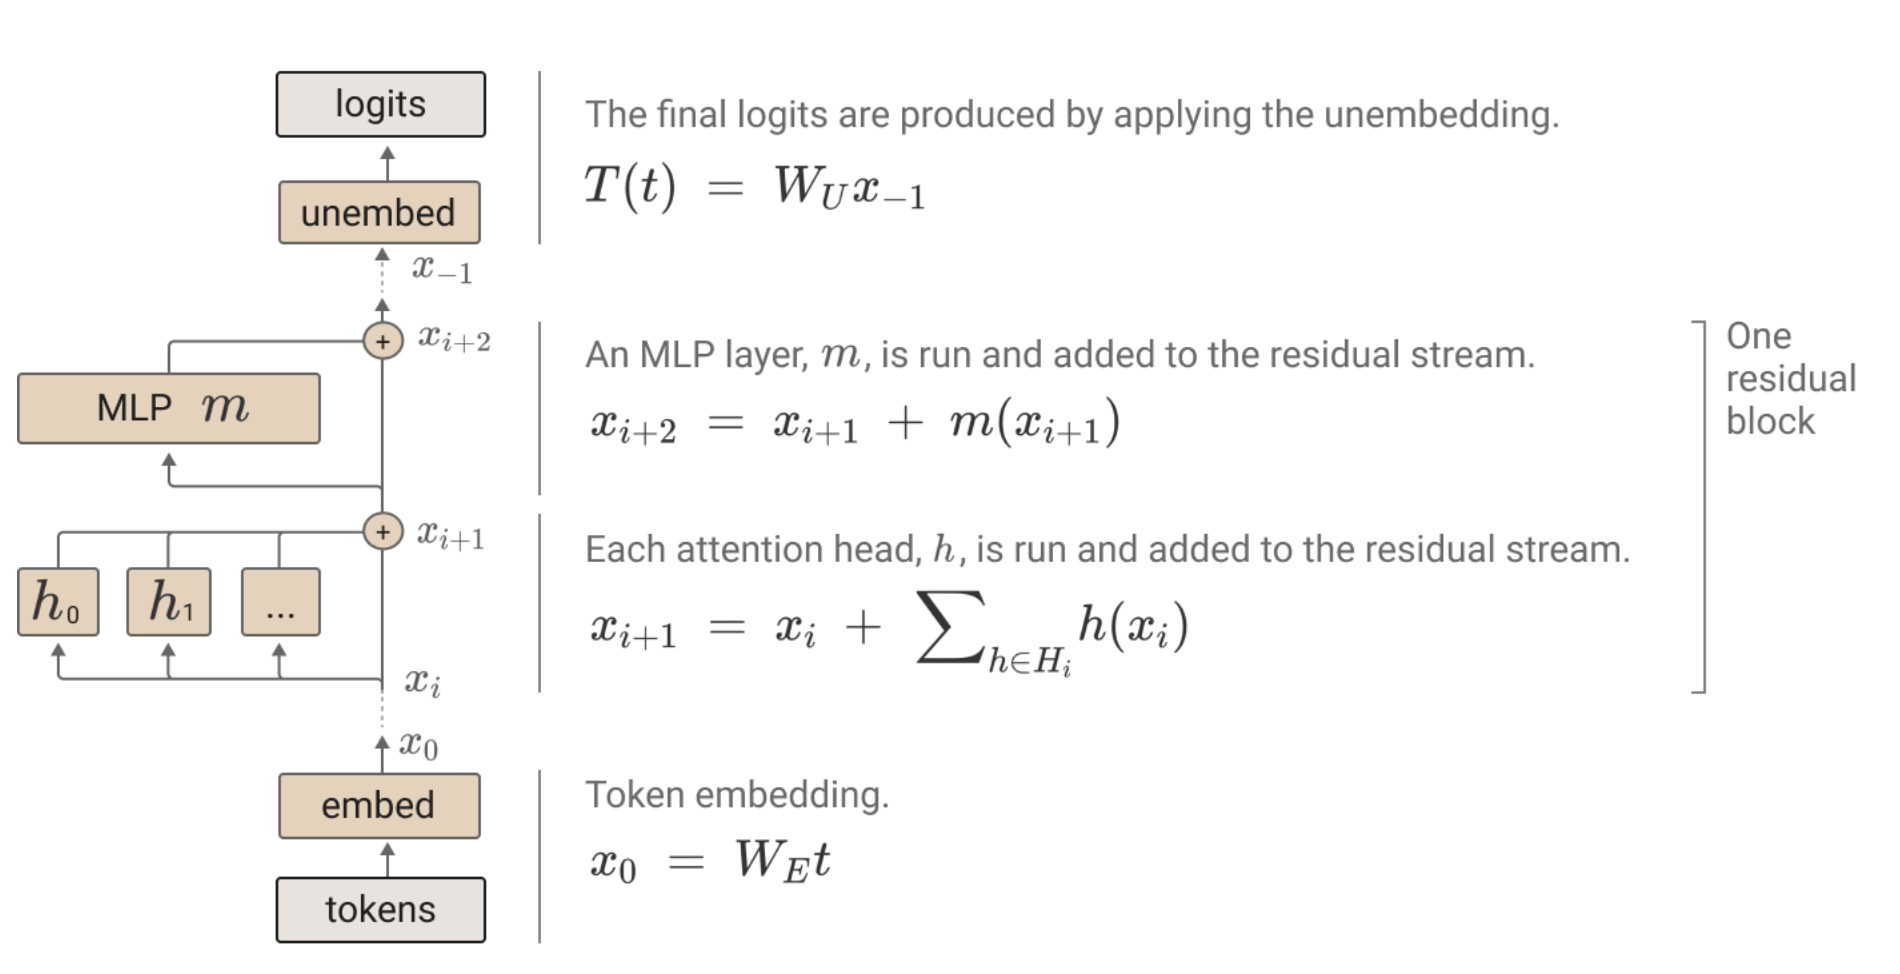
Optimise LLM Inference Throughput from First Principles

How continuous batching enables 23x throughput in LLM inference ...
How to Run LLM Inference with vLLM in Docker
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...
Advertisement Space (300x250)

LLM Inference Performance: Latency and Throughput Metrics - YouTube
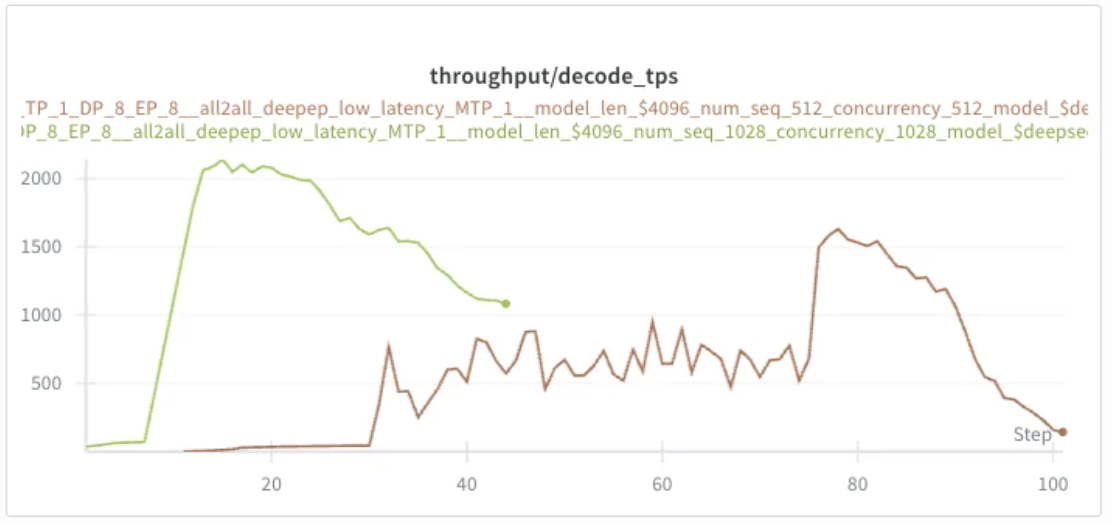
Optimise LLM Inference Throughput from First Principles

Table 1 from Multi-Bin Batching for Increasing LLM Inference Throughput ...

[论文评述] Accelerating LLM Inference Throughput via Asynchronous KV Cache ...
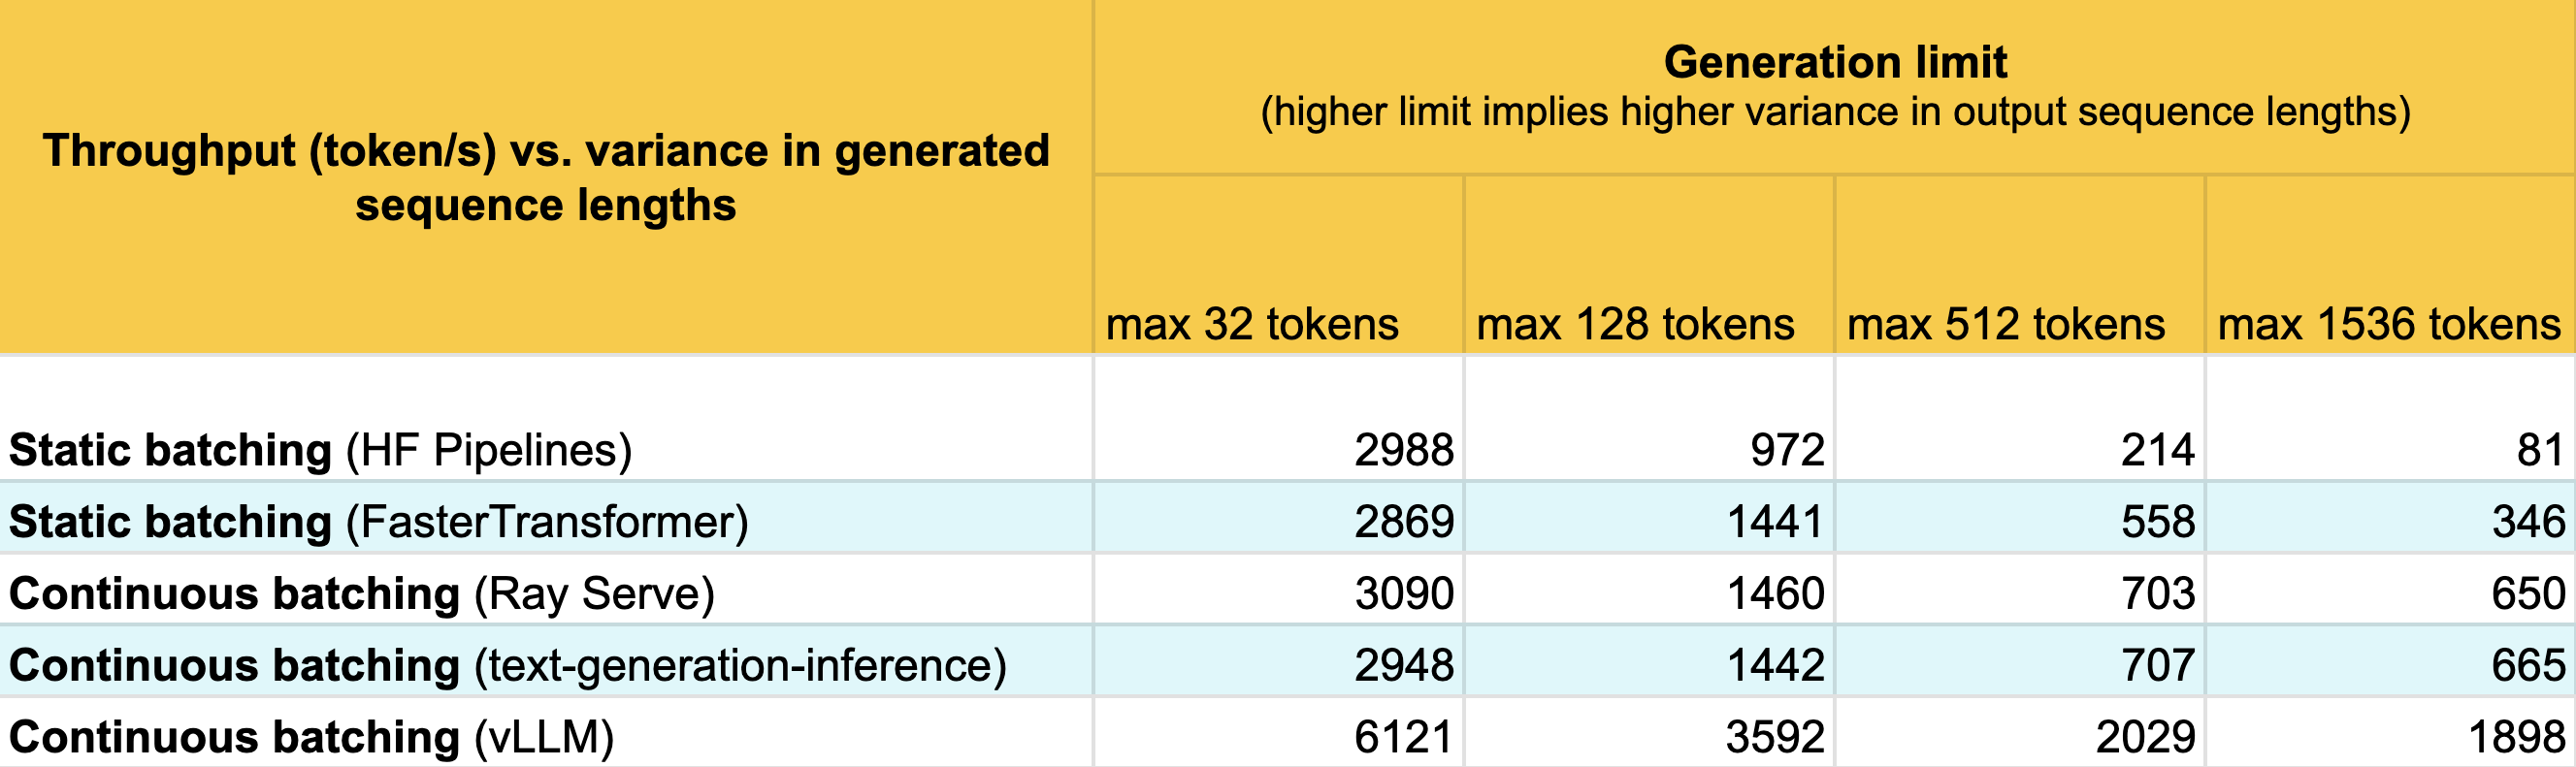
Achieve 23x LLM Inference Throughput & Reduce p50 Latency

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...
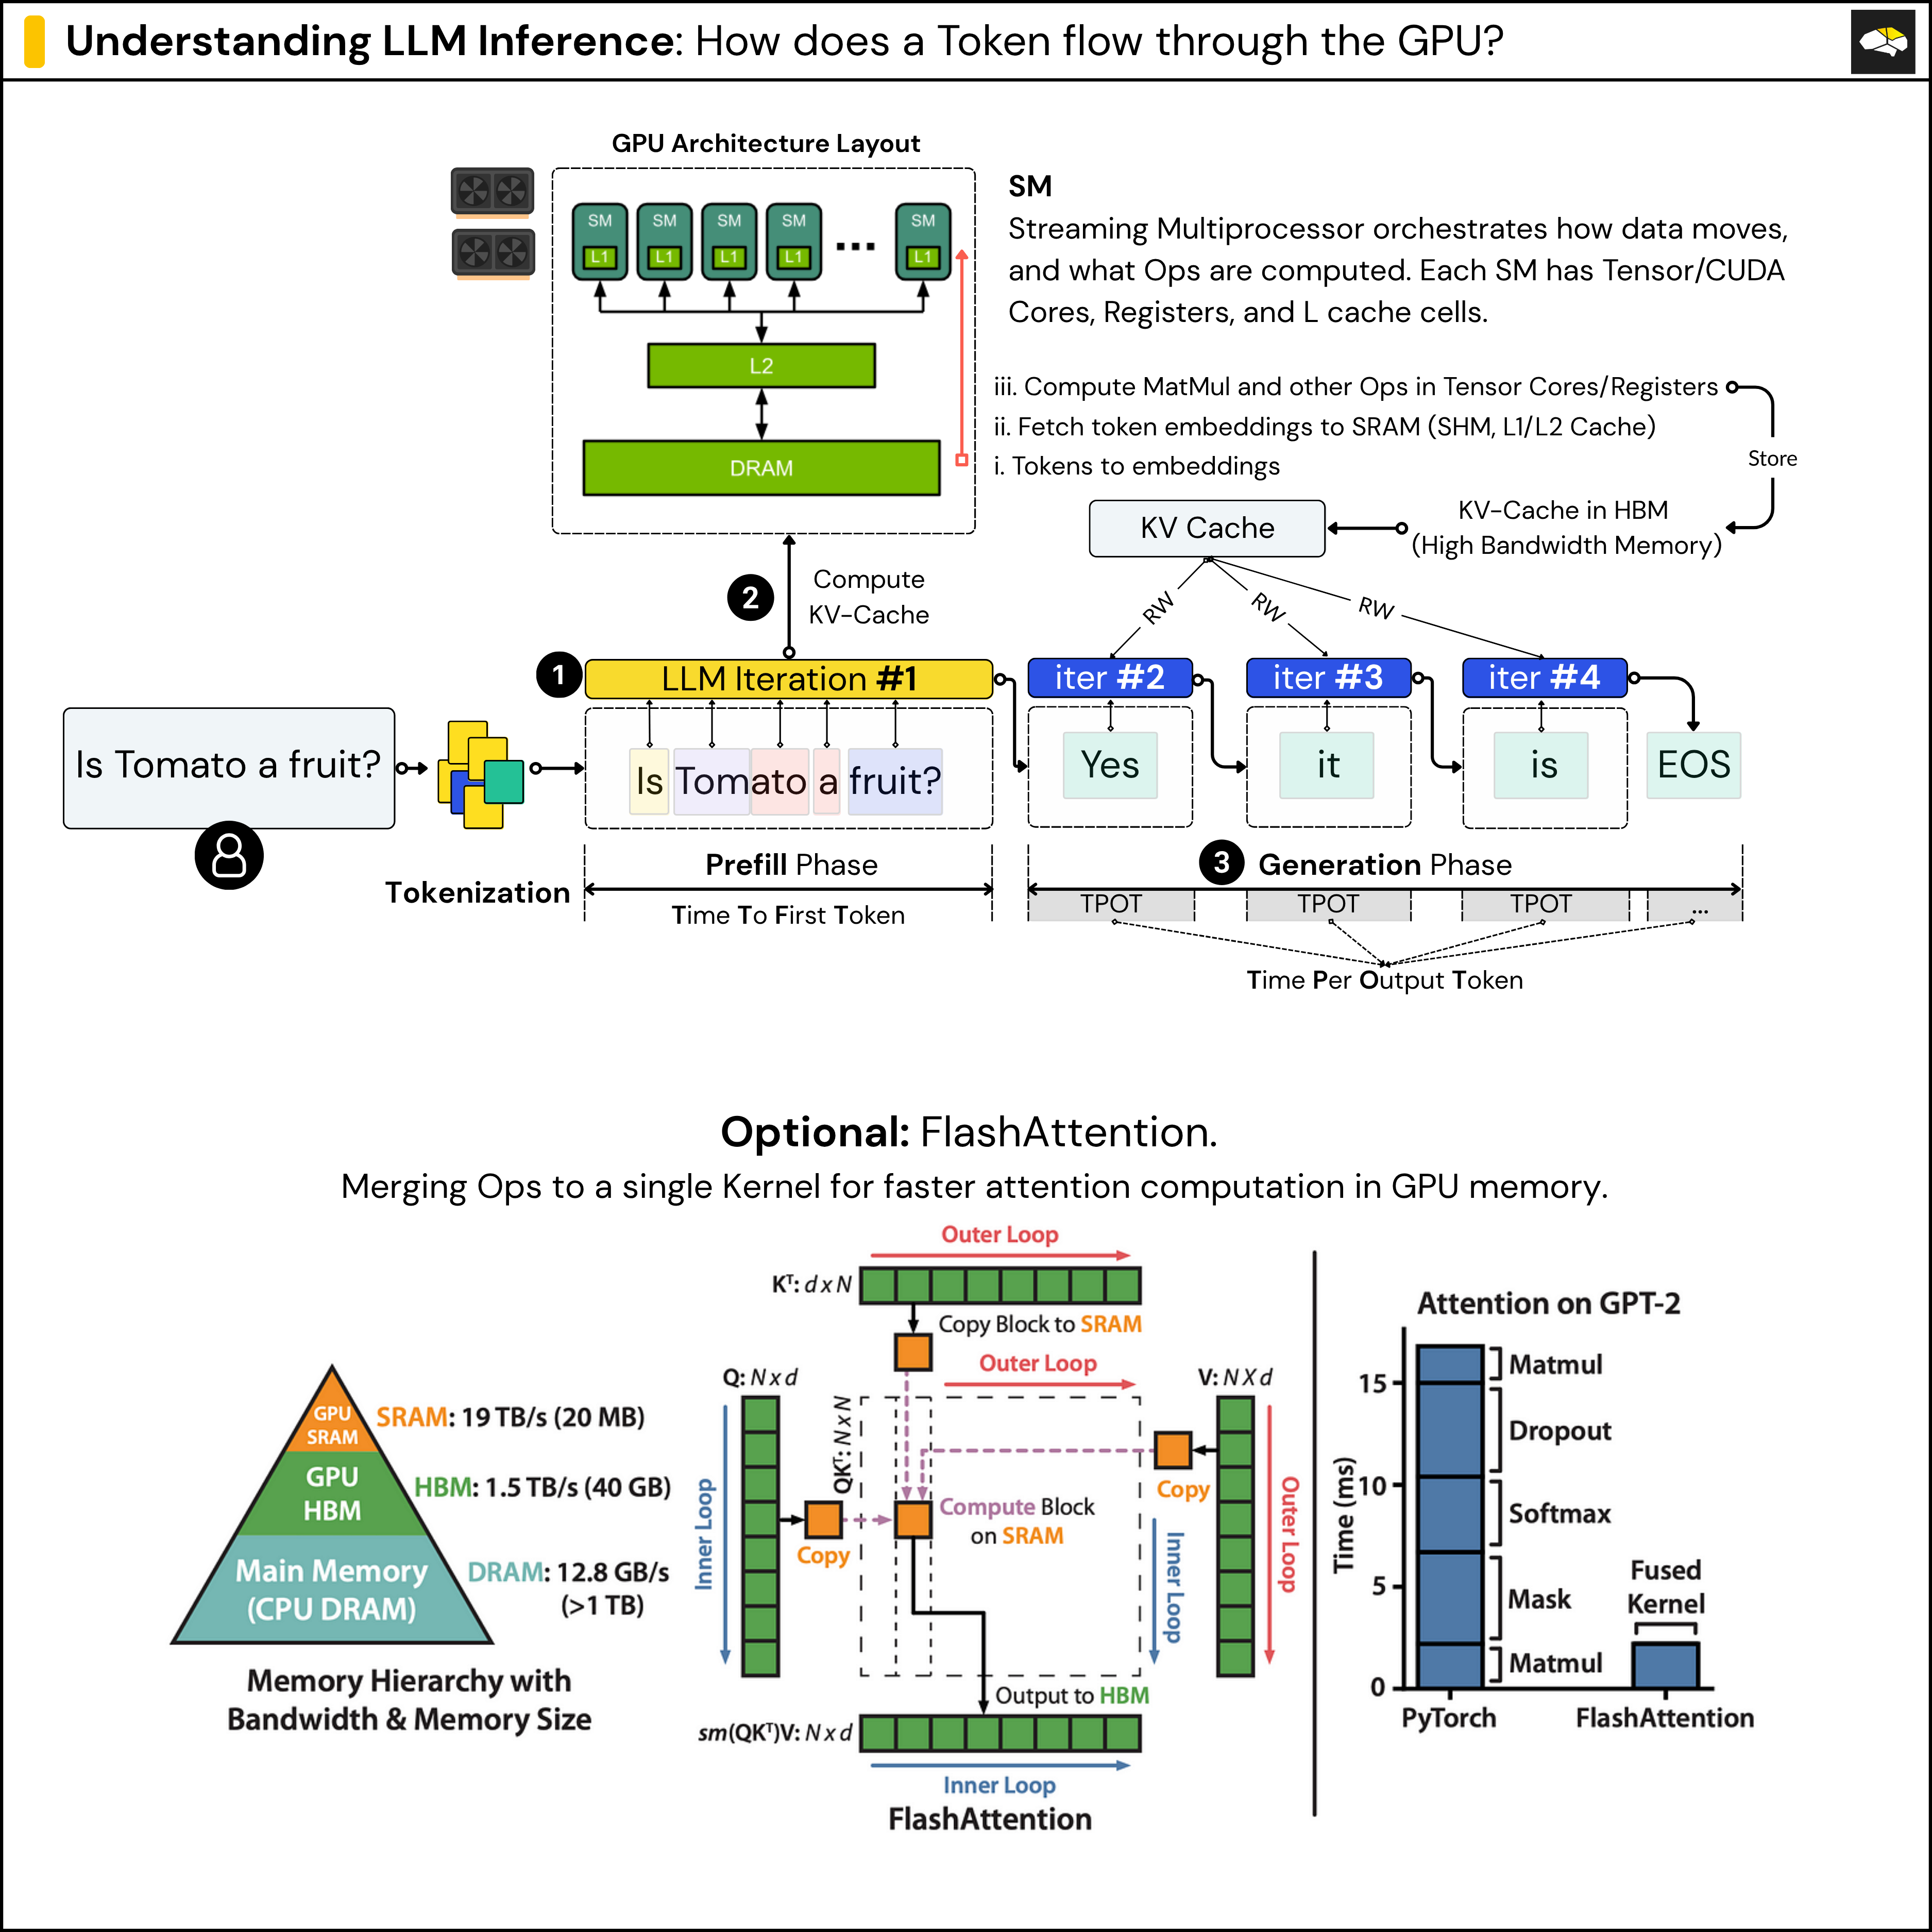
Understanding LLM Inference - by Alex Razvant
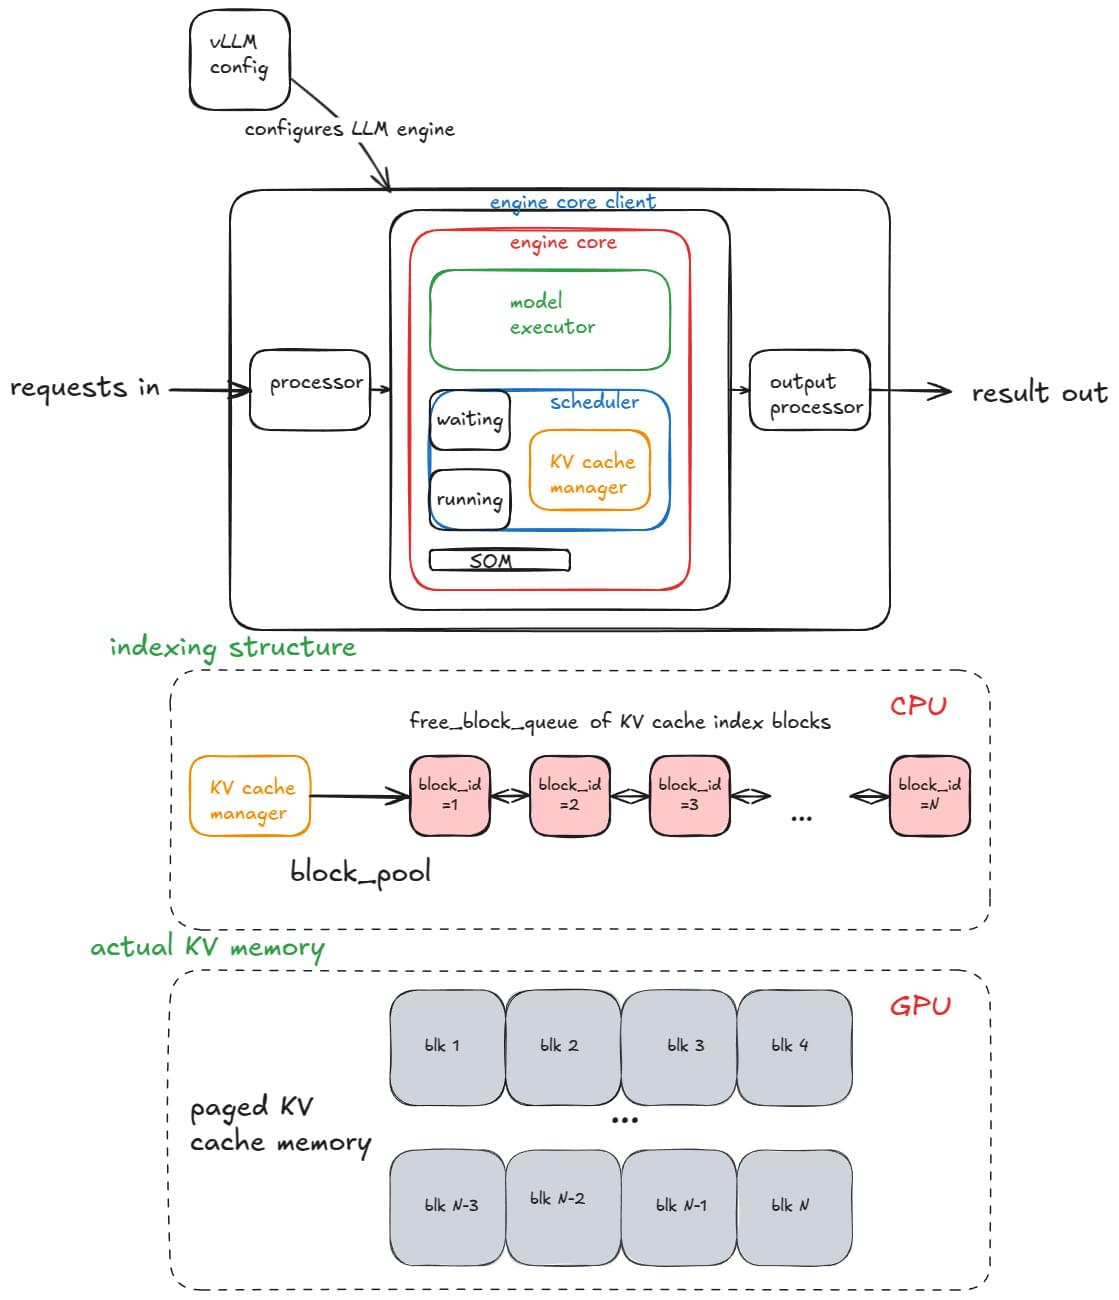
Inside vLLM: Anatomy of a High-Throughput LLM Inference System ...
Advertisement Space (336x280)

Scaling Up Throughput-oriented LLM Inference Applications on ...
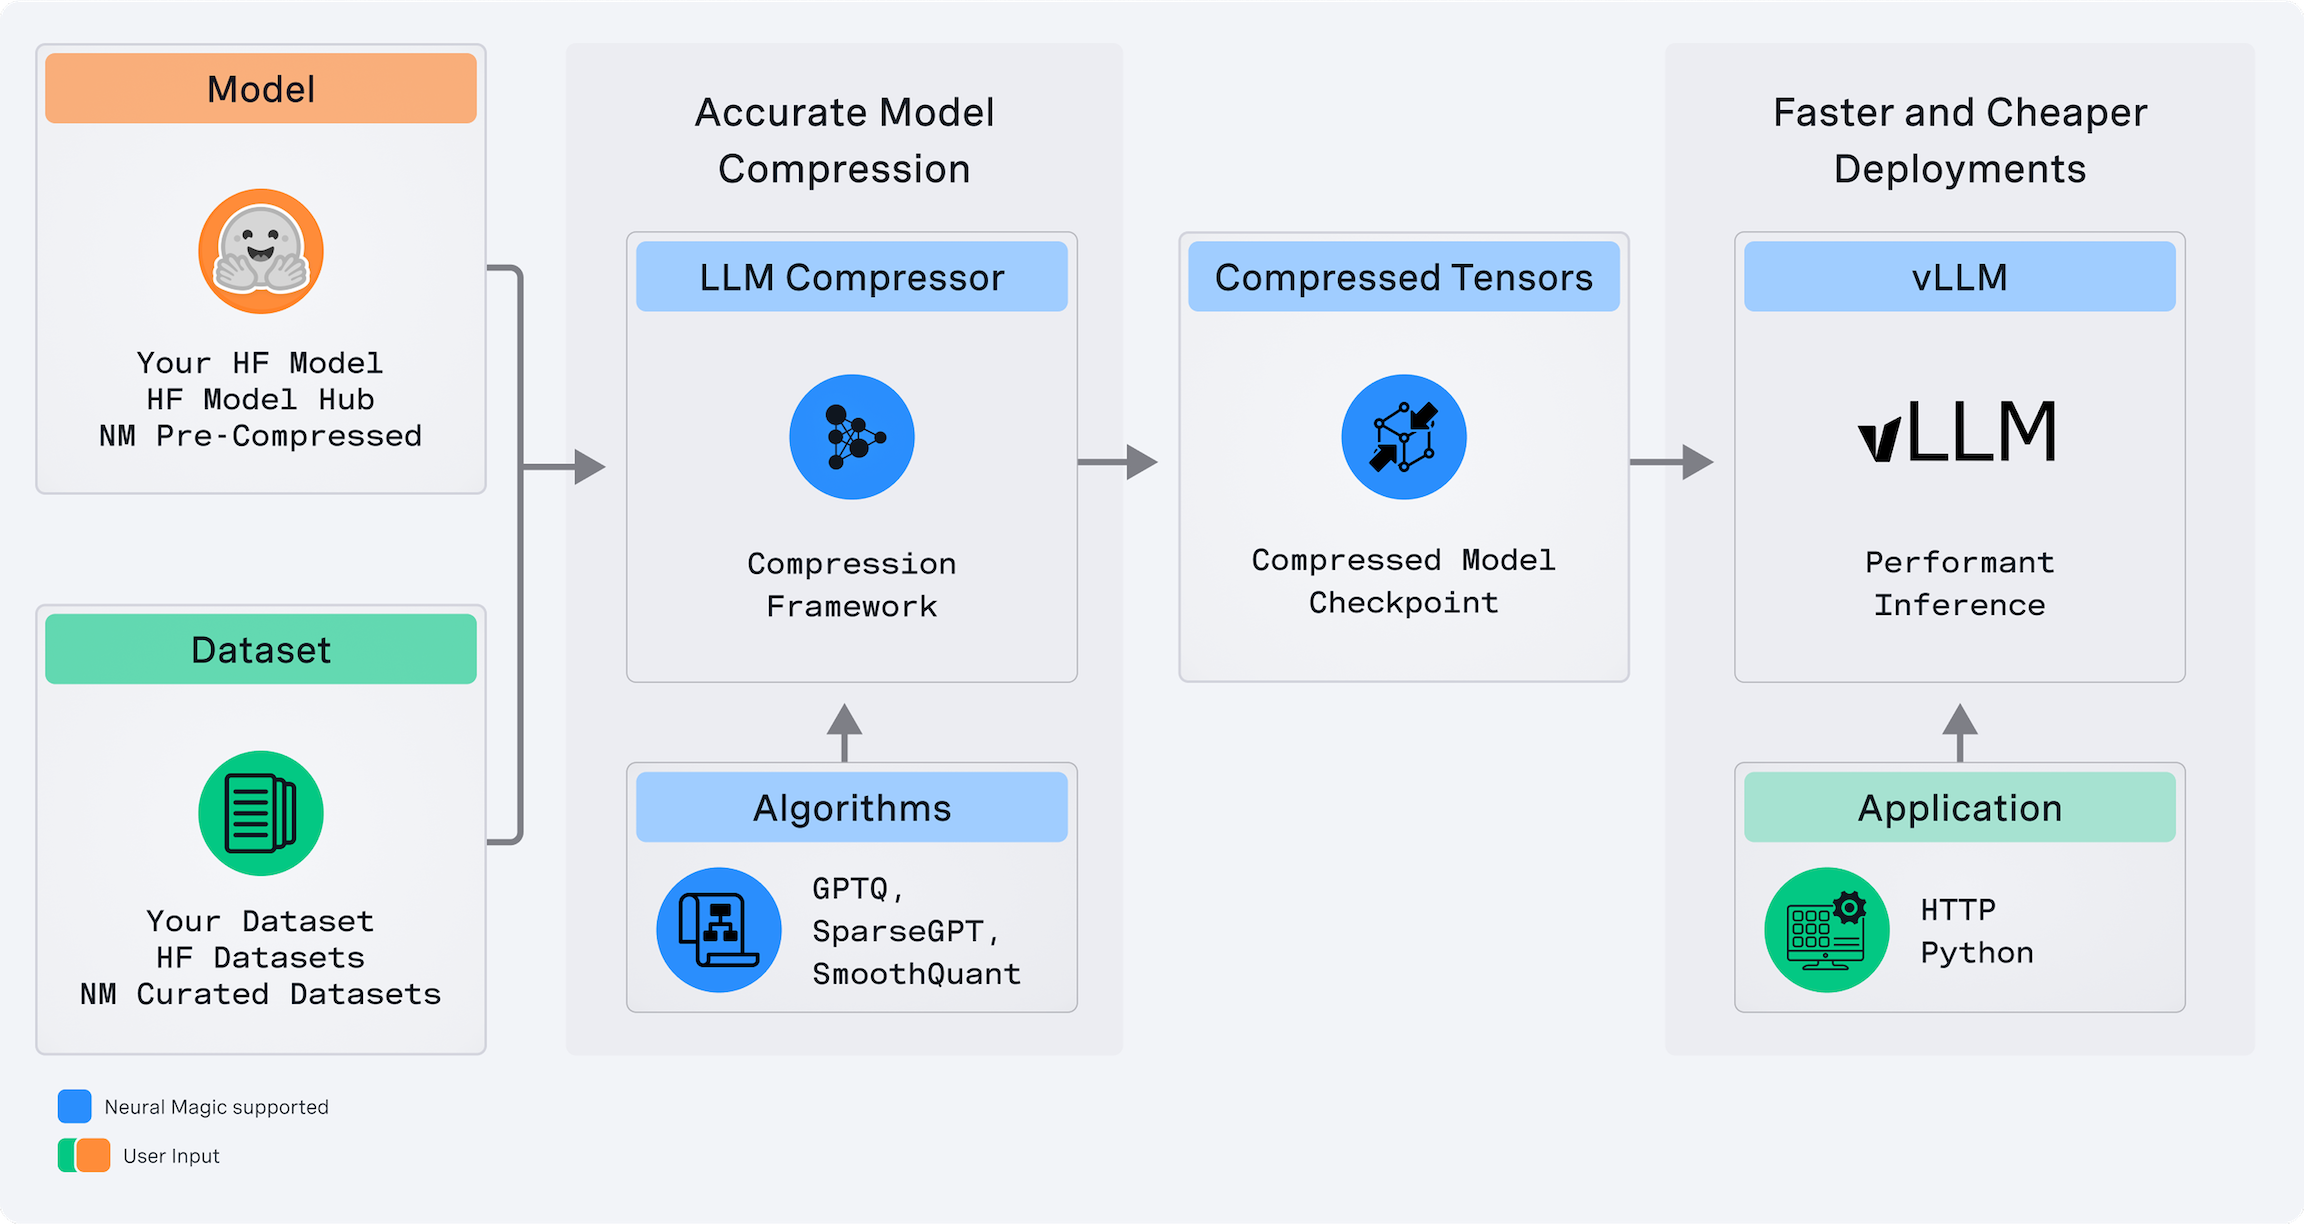
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer

Understanding LLM Batch Inference | Adaline
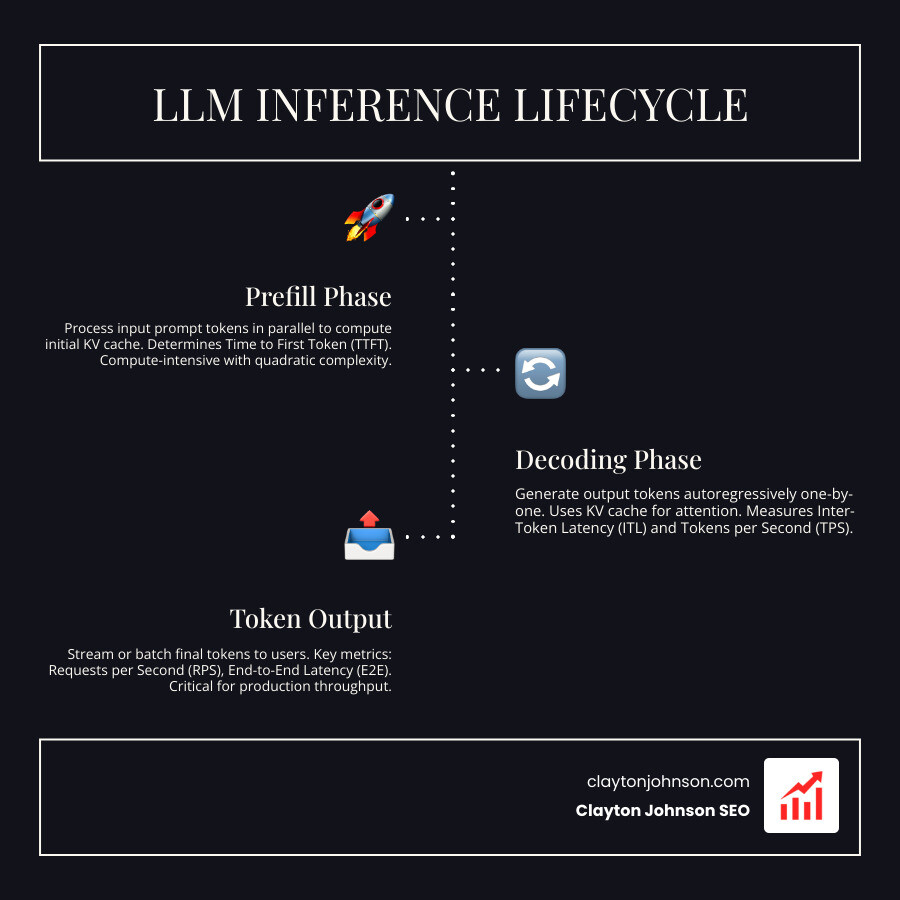
What LLM Throughput Benchmarks Reveal #1 Secrets

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...
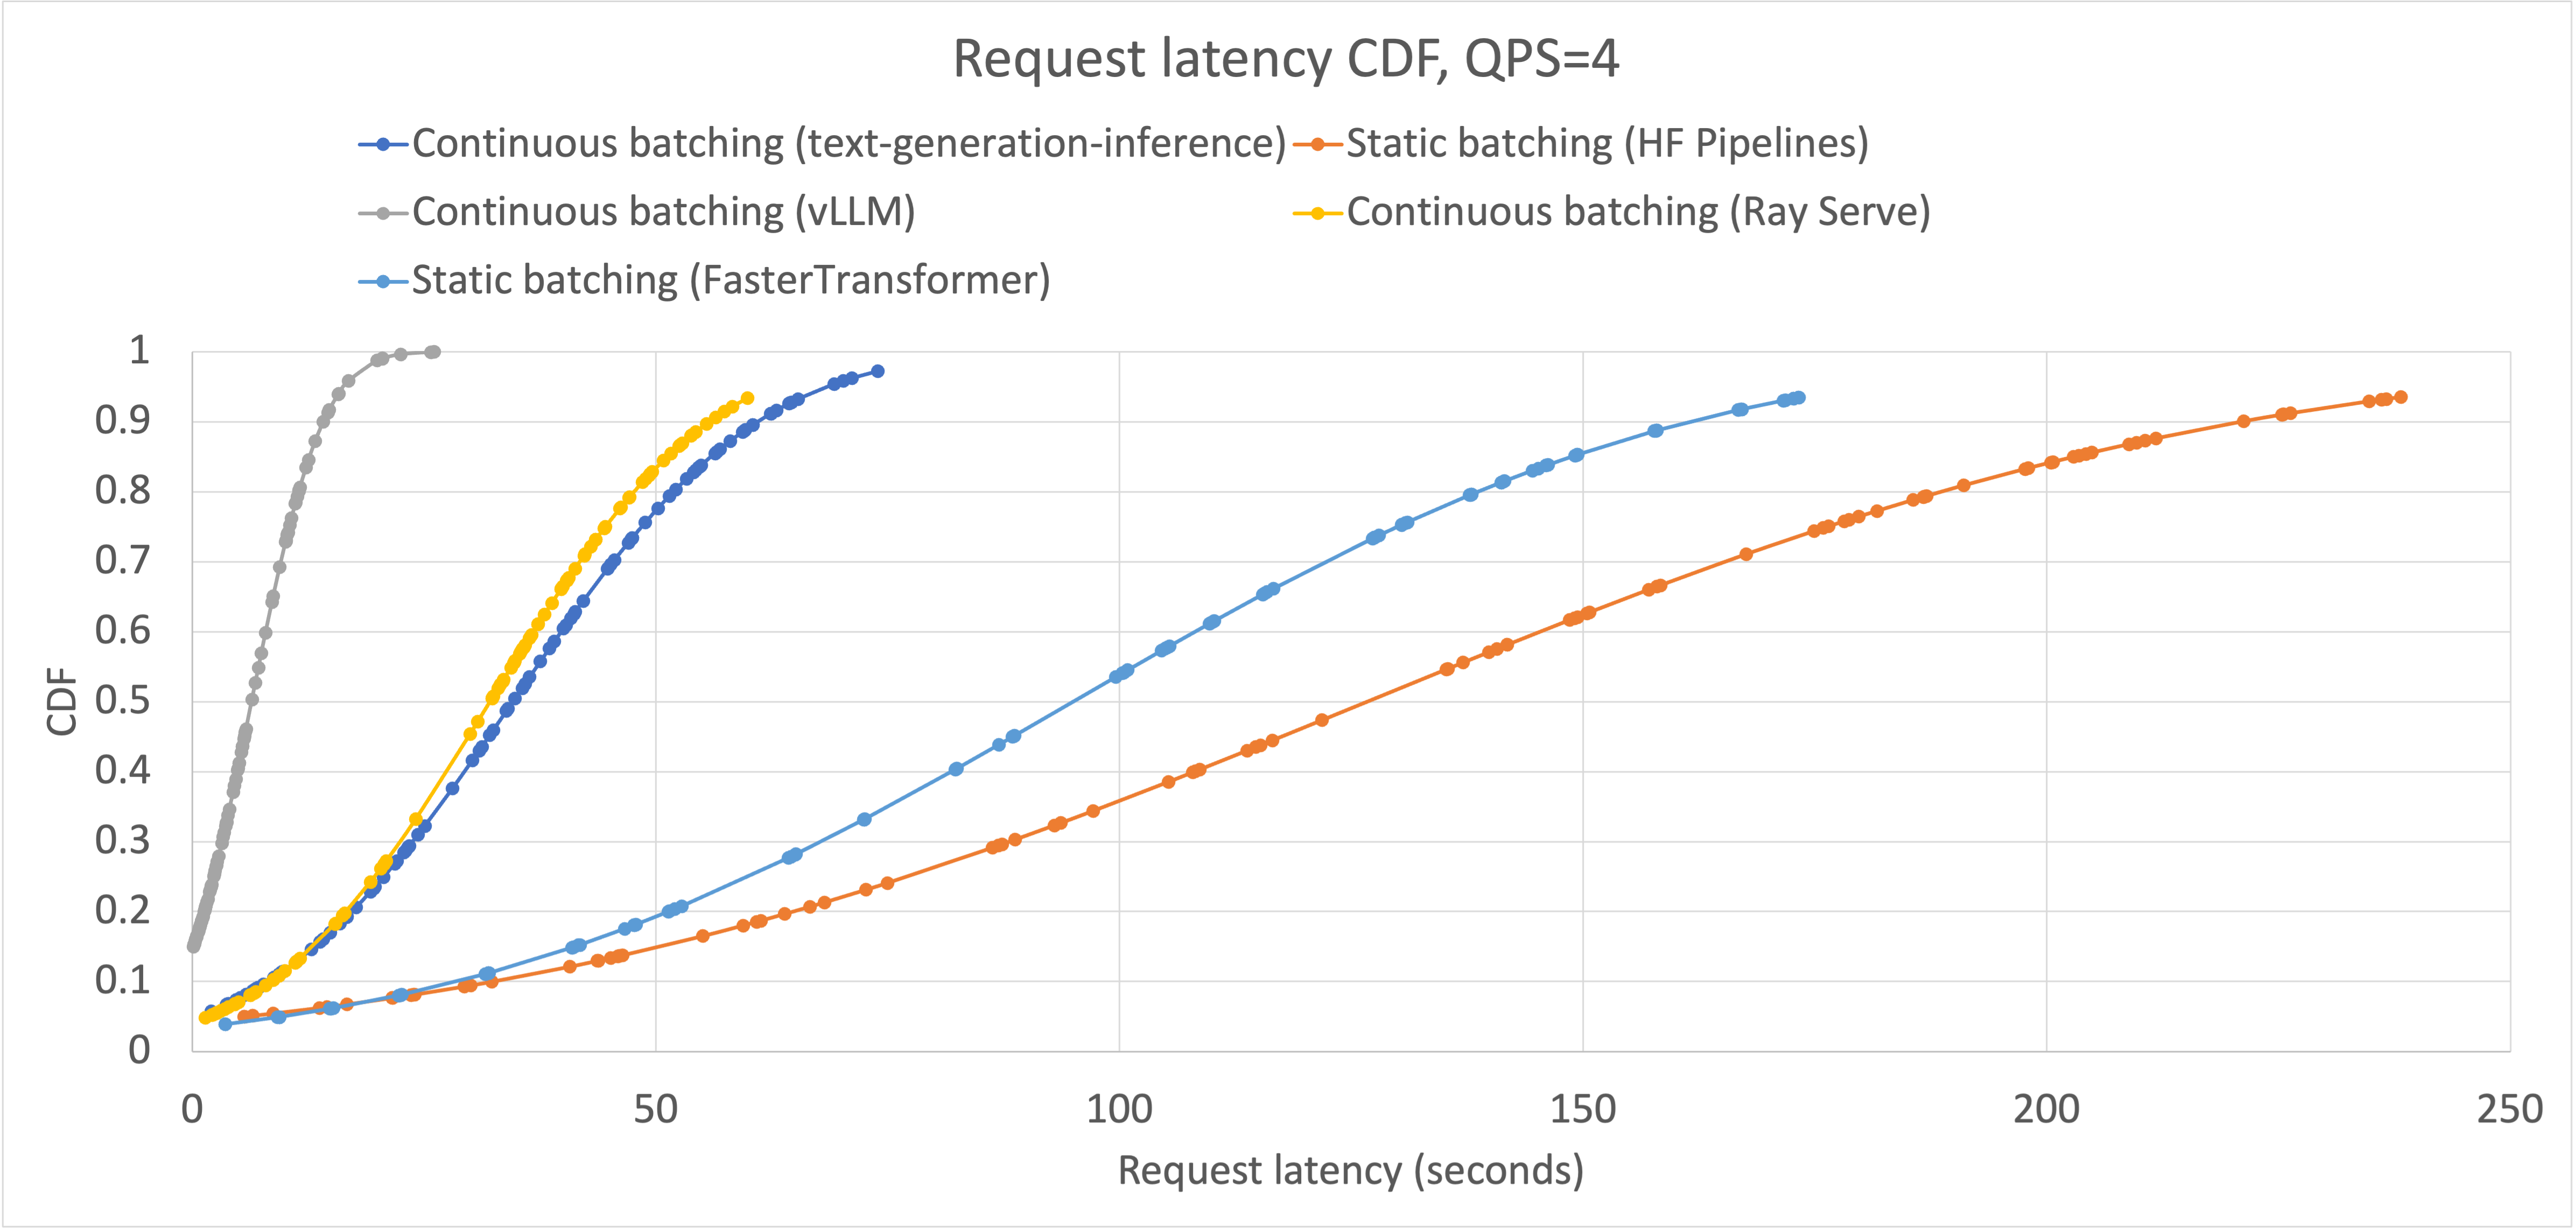
Scaling LLM inference with Ray and vLLM

Throughput-Optimal Scheduling Algorithms for LLM Inference and AI ...
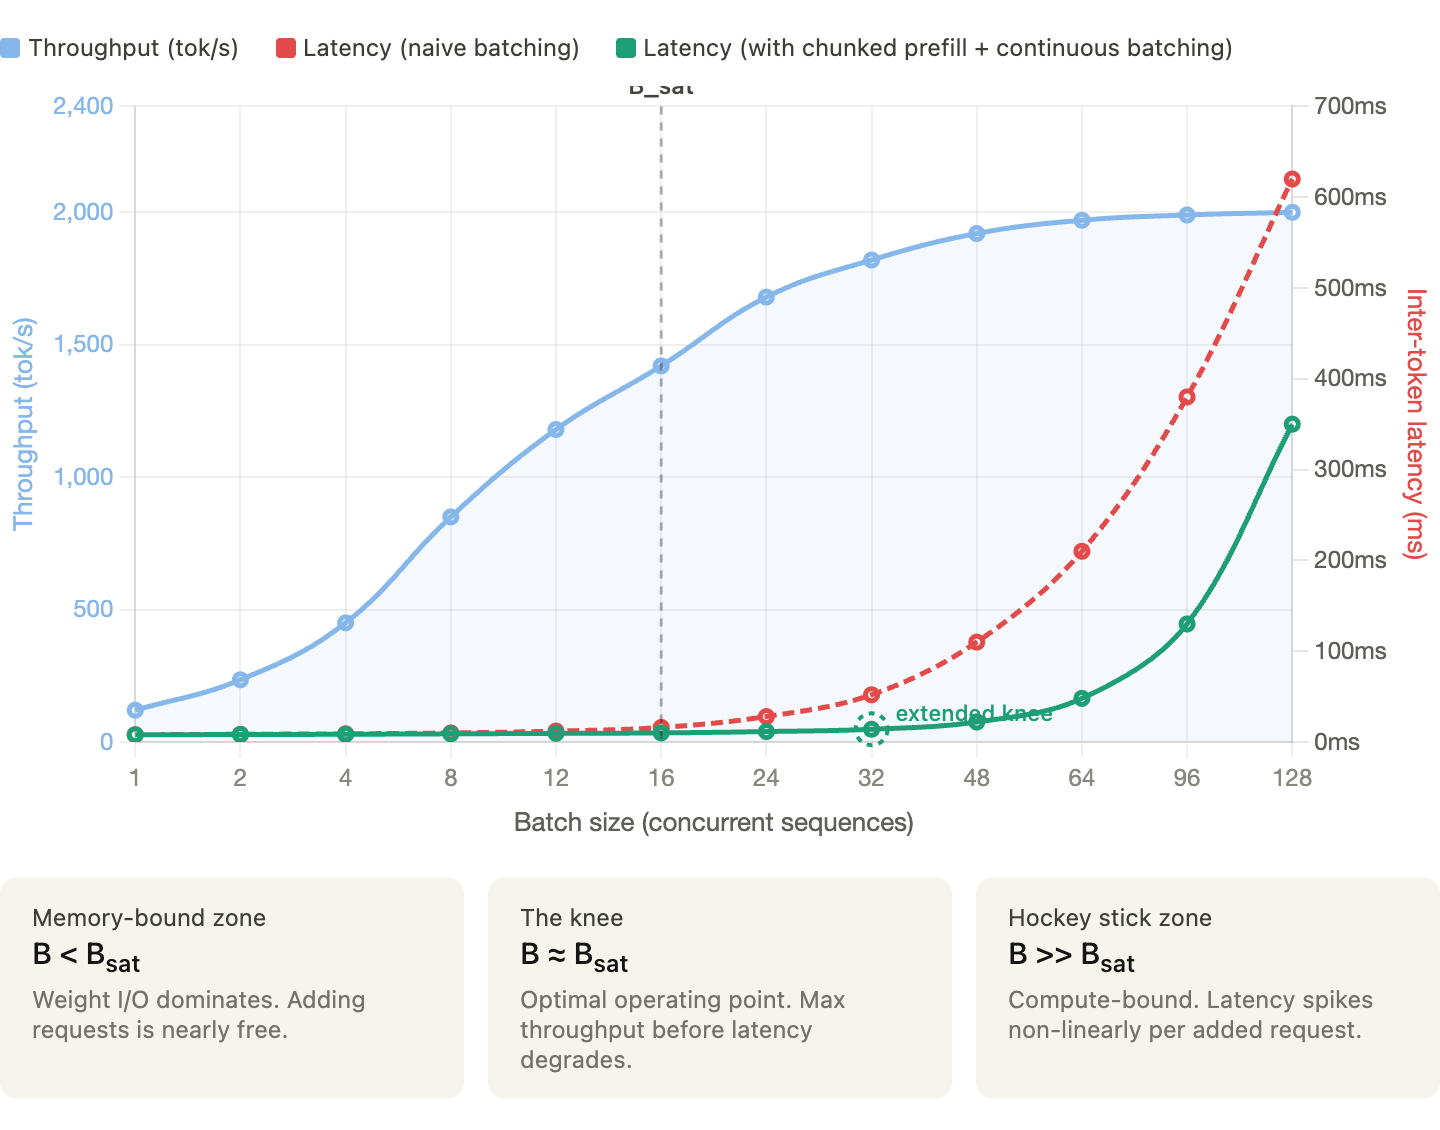
The LLM Inference Trilemma: Throughput, Latency, Cost | DigitalOcean
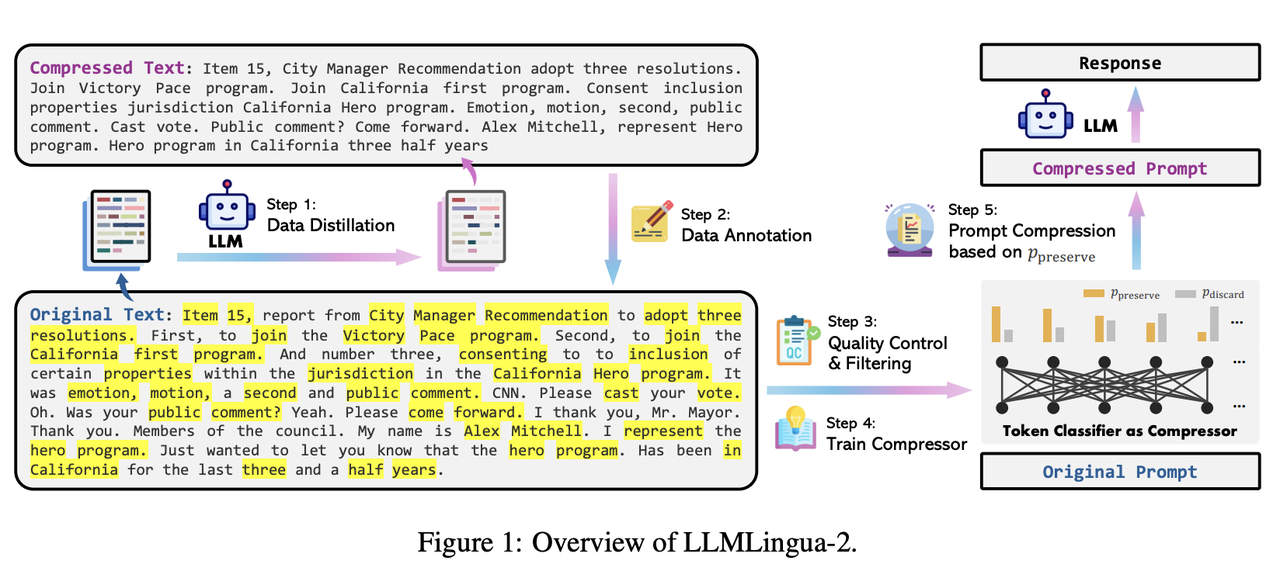
LLM Inference Optimization Overview - From Data to System Architecture ...

Beyond the Prompt: The “Why” of High-Throughput LLM Inference | by Arun ...
Advertisement Space (336x280)

High-Throughput LLM Inference Optimization | PDF | Parallel Computing ...
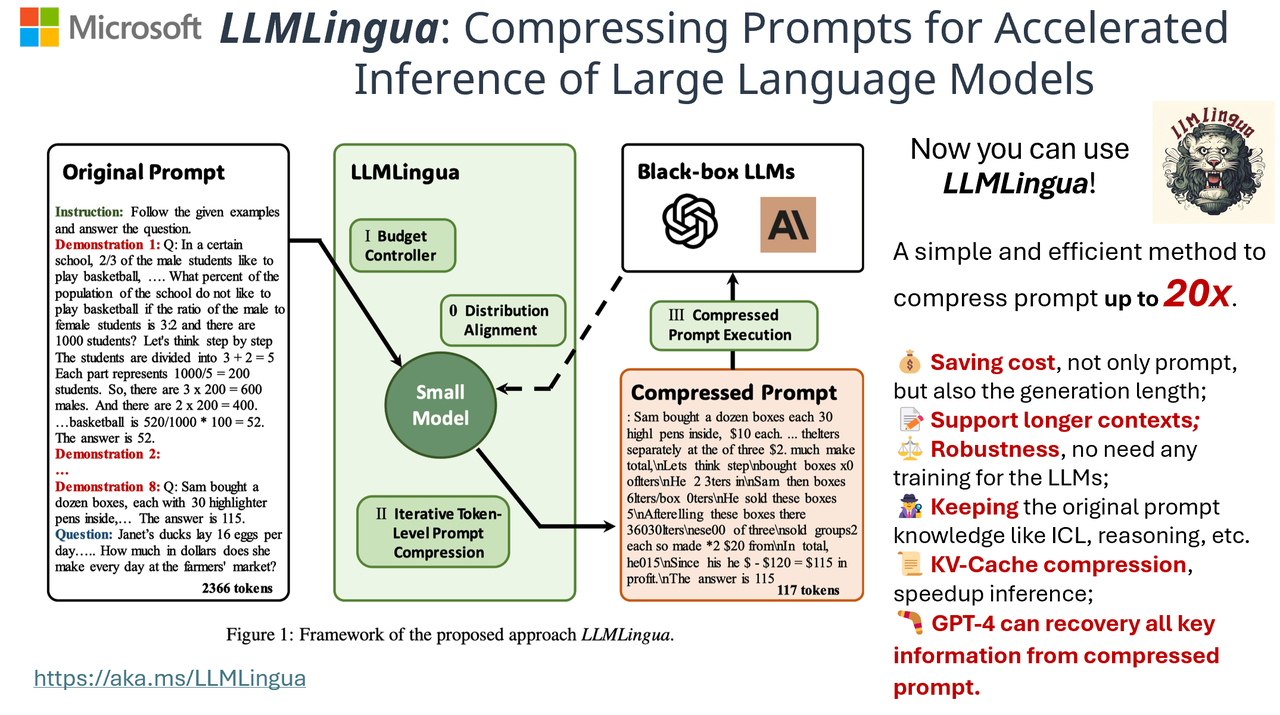
LLM Inference Optimization Overview - From Data to System Architecture ...
Ways to Optimize LLM Inference: Boost Response Time, Amplify Throughput ...
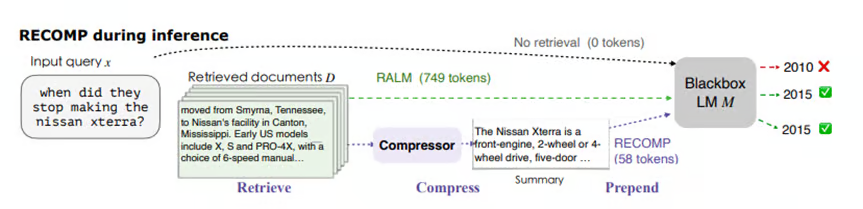
LLM Inference Optimization Overview - From Data to System Architecture ...
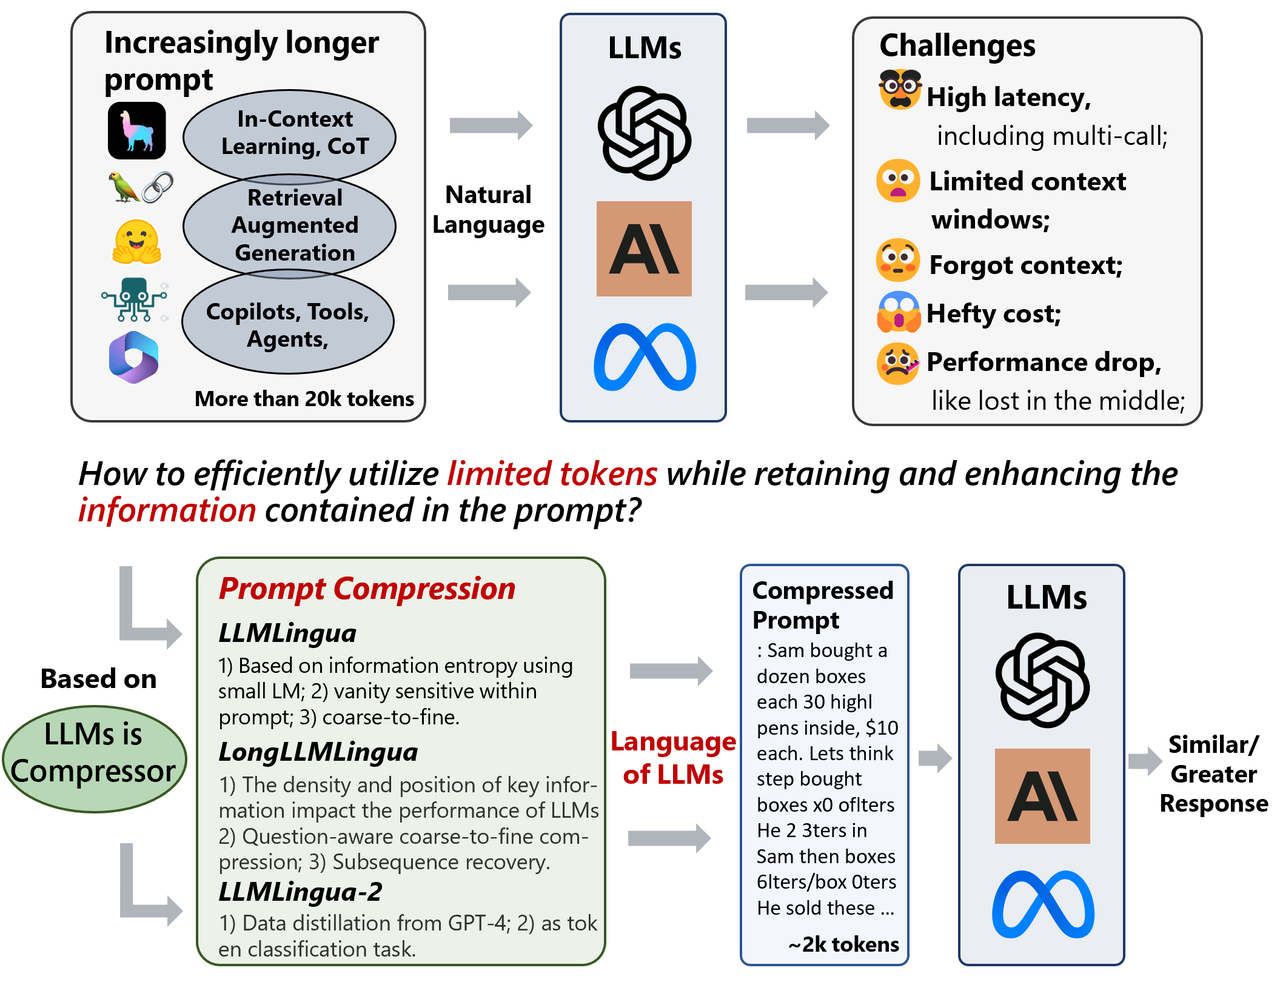
LLM Inference Optimization Overview - From Data to System Architecture ...
Solutions - LLM | Modal