
Figure 1 From Efficient Llm Inference With Kcache Semantic Scholar

Figure 1 from Efficient LLM Inference with Kcache | Semantic Scholar

Figure 1 from Efficient LLM Inference with Kcache | Semantic Scholar
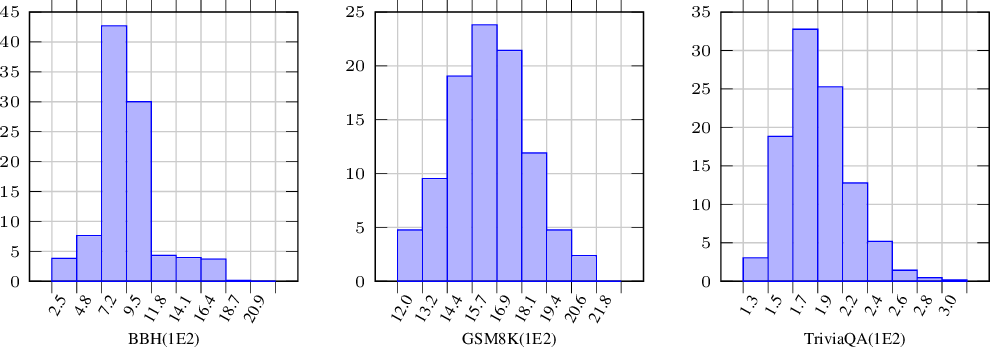
Figure 1 from Efficient LLM Inference with Kcache | Semantic Scholar
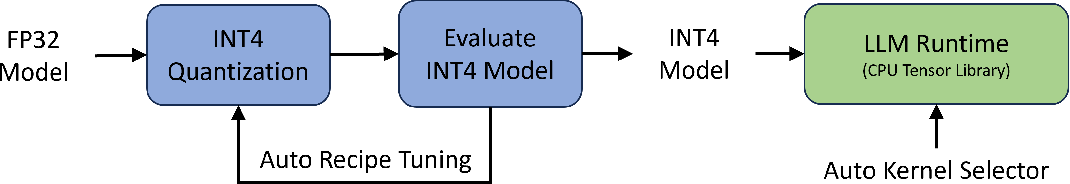
Figure 1 from Efficient LLM Inference on CPUs | Semantic Scholar
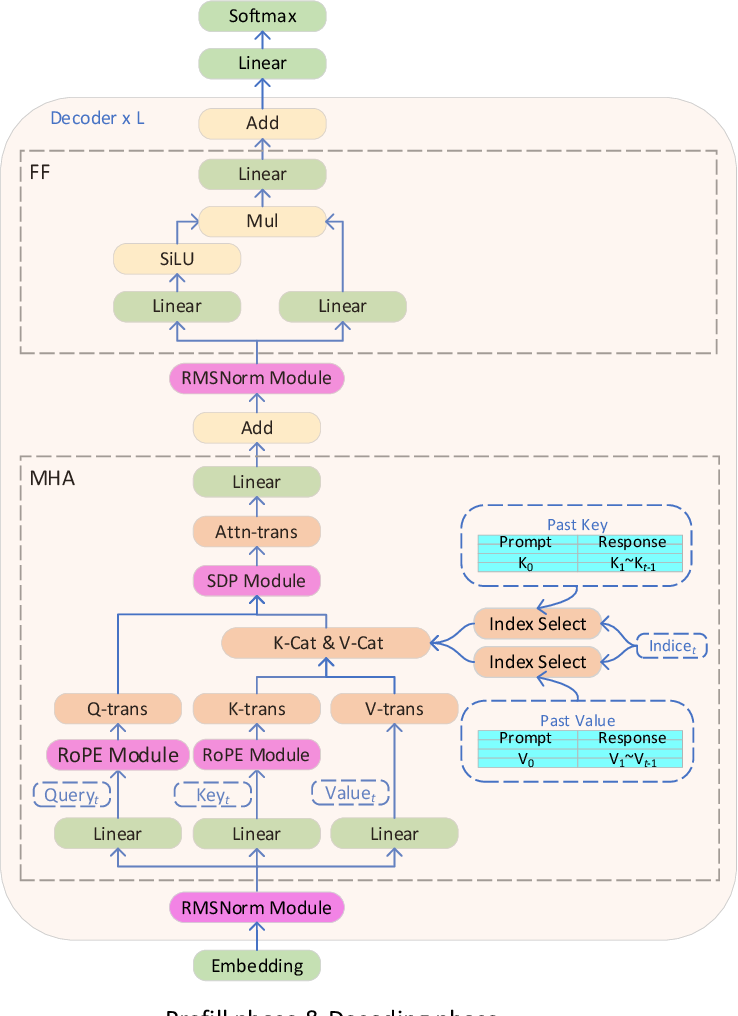
Figure 1 from Efficient LLM inference solution on Intel GPU | Semantic ...
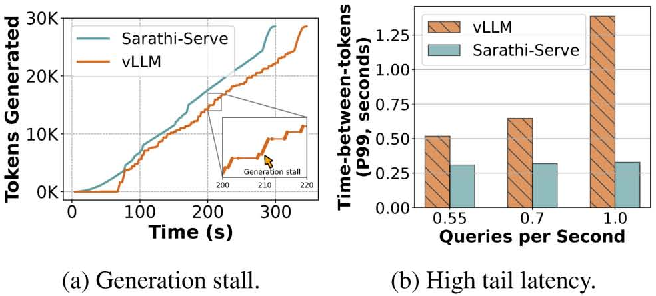
Figure 1 from Efficient LLM Inference via Chunked Prefills | Semantic ...

Figure 1 from A Survey of LLM Inference Systems | Semantic Scholar
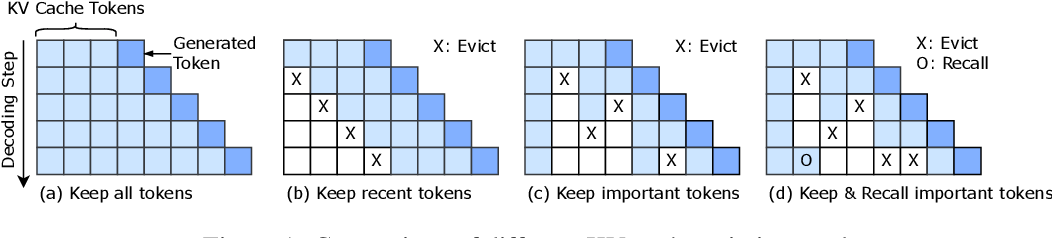
Figure 1 from ArkVale: Efficient Generative LLM Inference with ...

Figure 1 from Oaken: Fast and Efficient LLM Serving with Online-Offline ...
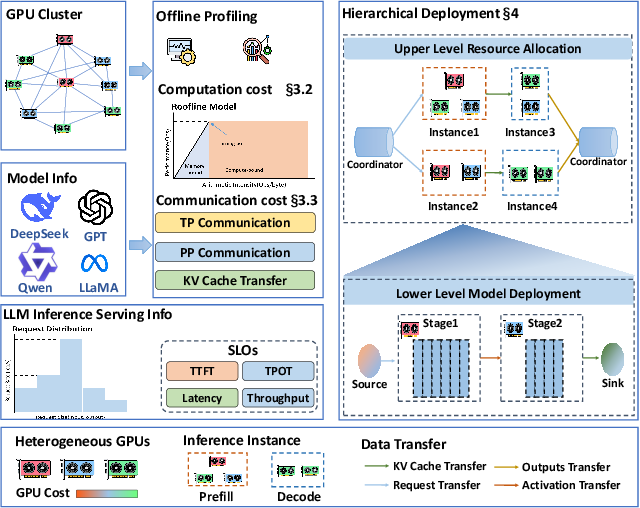
Figure 1 from SwiftServe: Efficient Disaggregated LLM Inference Serving ...
Advertisement Space (300x250)

Figure 1 from Efficient LLM Inference using Dynamic Input Pruning and ...

Figure 1 from User-LLM: Efficient LLM Contextualization with User ...

Figure 3 from Efficient LLM inference solution on Intel GPU | Semantic ...

Figure 1 from Medusa: Simple LLM Inference Acceleration Framework with ...
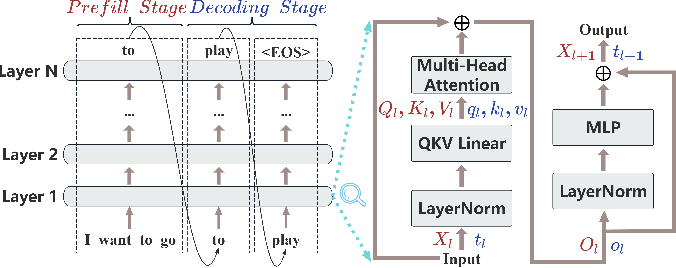
Figure 1 from Efficient LLM Edge Collaboration Deployment with LoRA ...

Figure 1 from A Survey of Useful LLM Evaluation | Semantic Scholar
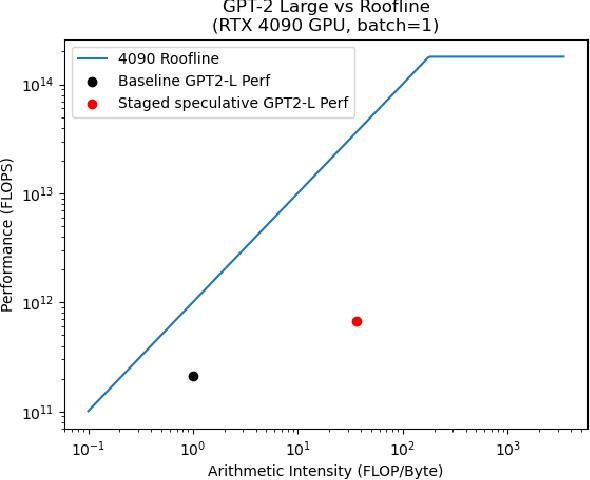
Figure 1 from Accelerating LLM Inference with Staged Speculative ...

Figure 1 from Accelerating LLM Inference via Dynamic KV Cache Placement ...
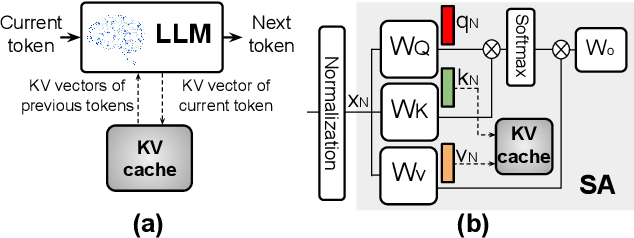
Figure 1 from Kelle: Co-design KV Caching and eDRAM for Efficient LLM ...
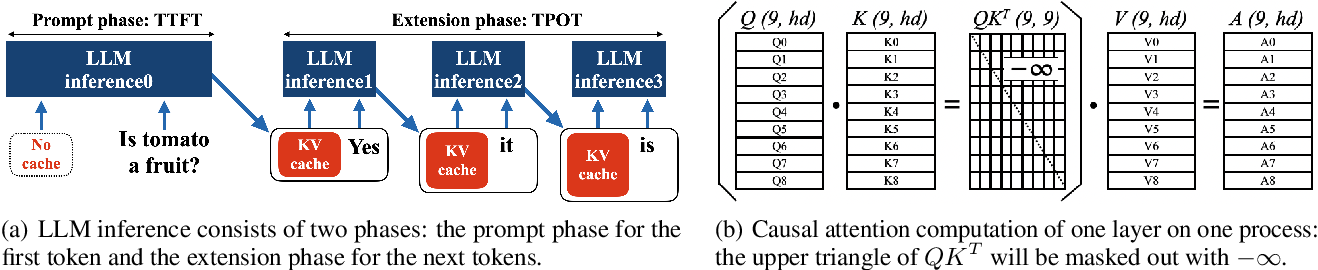
Figure 1 from KV-Runahead: Scalable Causal LLM Inference by Parallel ...
Advertisement Space (336x280)

Figure 1 from Progressive Mixed-Precision Decoding for Efficient LLM ...

Efficient LLM Inference with Kcache - 智源社区论文

Figure 1 from SparQ Attention: Bandwidth-Efficient LLM Inference ...
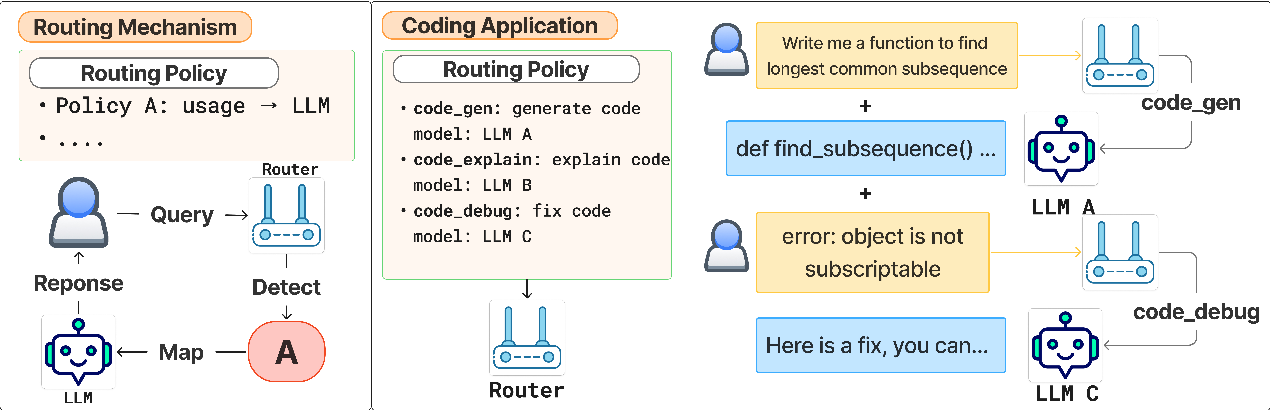
Figure 1 from Dynamic Model Routing and Cascading for Efficient LLM ...

Figure 1 from An Agile Framework for Efficient LLM Accelerator ...

Paper page - Efficient LLM Inference with Kcache
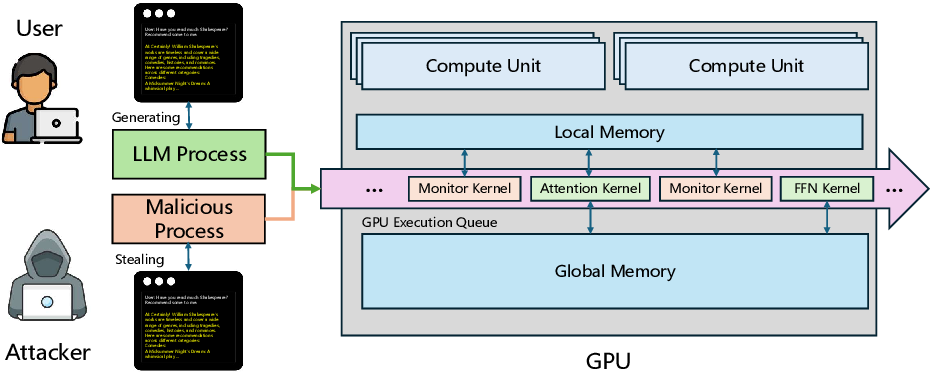
Figure 1 from A First Look At Efficient And Secure On-Device LLM ...

Figure 1 from A Systematic Characterization of LLM Inference on GPUs ...
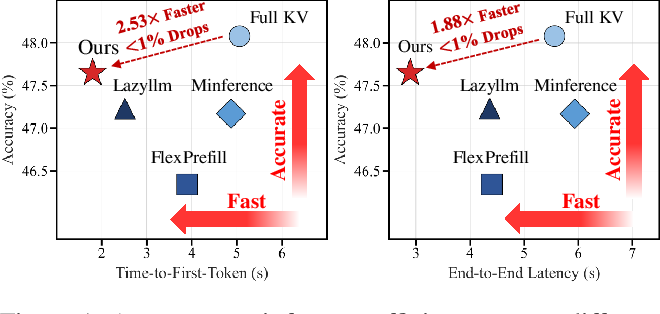
Figure 1 from SlimInfer: Accelerating Long-Context LLM Inference via ...

Figure 1 from DynamoLLM: Designing LLM Inference Clusters for ...
Advertisement Space (336x280)

Figure 1 from A Little Help Goes a Long Way: Efficient LLM Training by ...
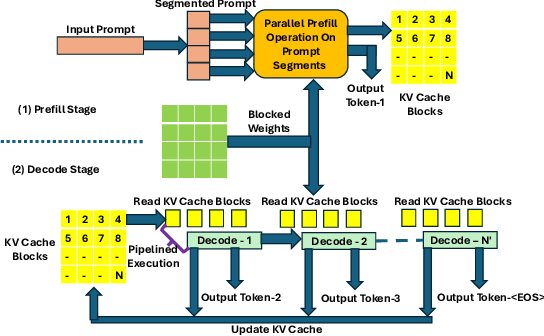
Figure 1 from Towards Real-Time LLM Inference on Heterogeneous Edge ...
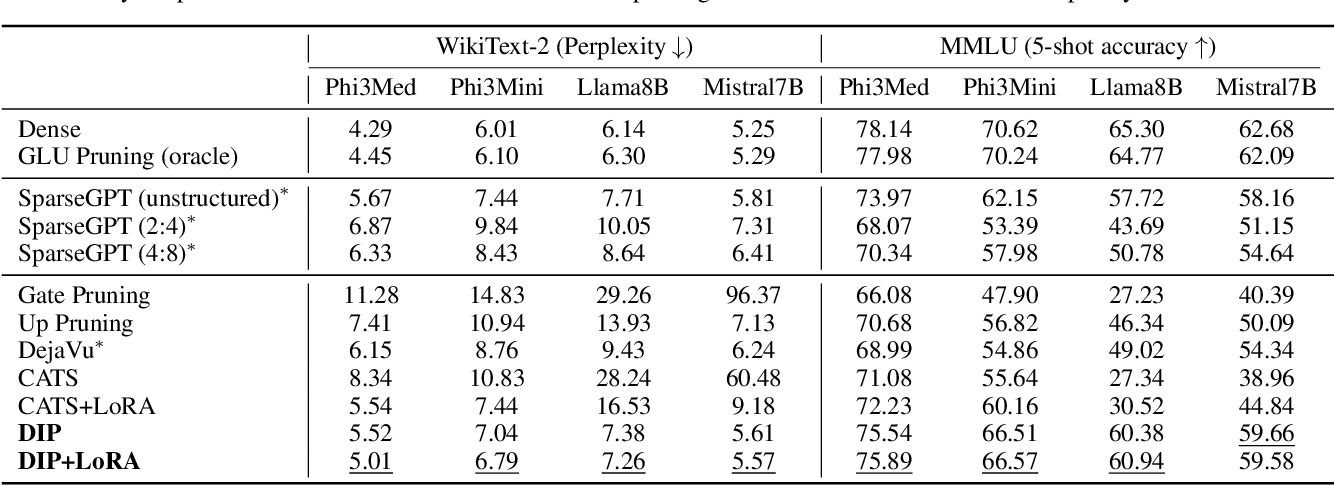
Table 1 from Efficient LLM Inference using Dynamic Input Pruning and ...

Figure 1 from Designing Efficient LLM Accelerators for Edge Devices ...

Figure 1 from Inference with Reference: Lossless Acceleration of Large ...
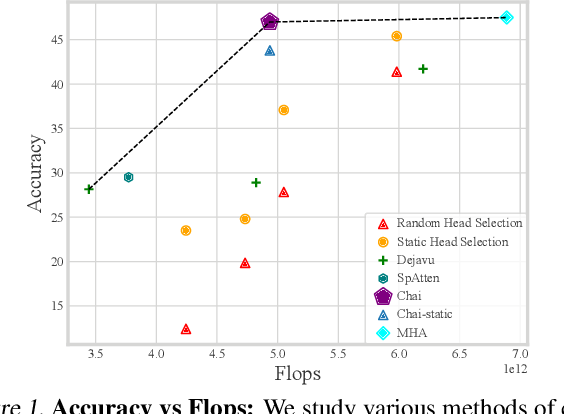
Figure 1 from CHAI: Clustered Head Attention for Efficient LLM ...