
Figure 1 From Efficient Speaker Embedding Extraction Using A Twofold

Figure 1 from Efficient Speaker Embedding Extraction Using a Twofold ...

Figure 1 from Speaker Embedding Extraction with Phonetic Information ...
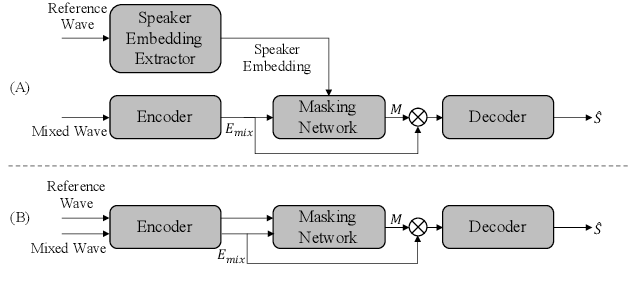
Figure 1 from SEF-Net: Speaker Embedding Free Target Speaker Extraction ...

Figure 1 from A Word-axis Speaker Embedding Trained with Multi-Speaker ...

Figure 1 from Speaker Embedding Extraction with Phonetic Information ...

Figure 1 from Speaker Embedding Extraction with Phonetic Information ...

Figure 1 from Improving Embedding Extraction for Speaker Verification ...

Figure 1 from Efficient speaker identification using distributional ...

Figure 1 from Investigation on Deep Speaker Embedding Extraction ...
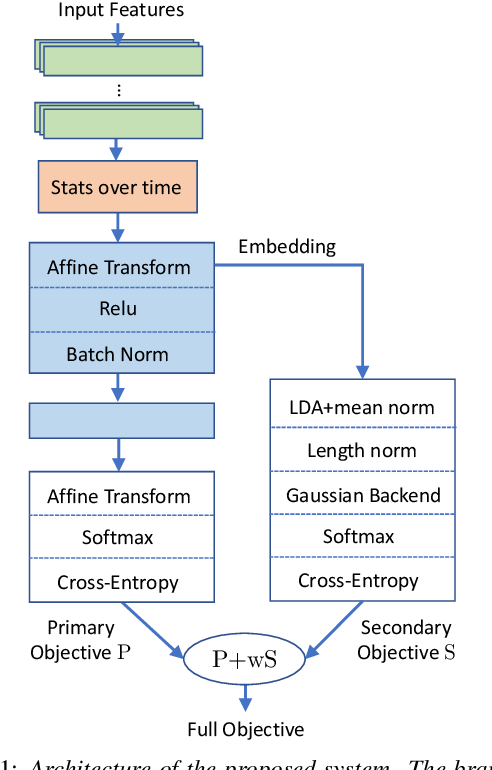
Figure 1 from Optimizing a Speaker Embedding Extractor Through Backend ...
Advertisement Space (300x250)

Figure 1 from High-Resolution Embedding Extractor for Speaker ...

Figure 1 from Low-complexity Multi-Channel Speaker Extraction with Pure ...
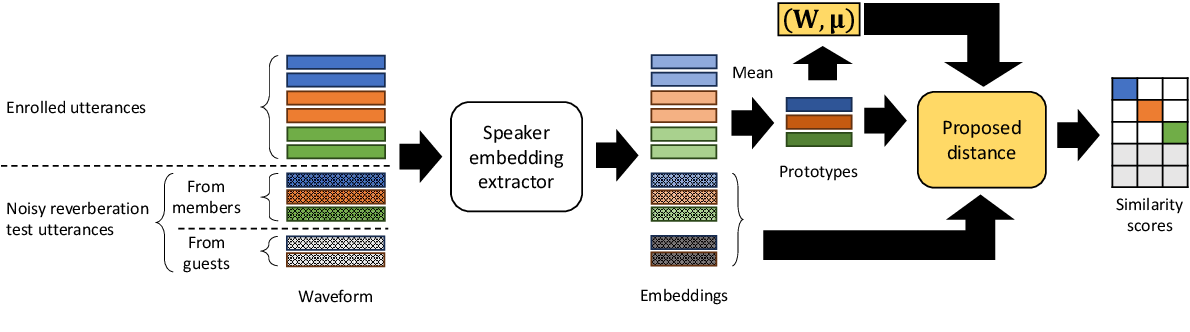
Figure 1 from Speaker Verification Using Distance Based on Principal ...
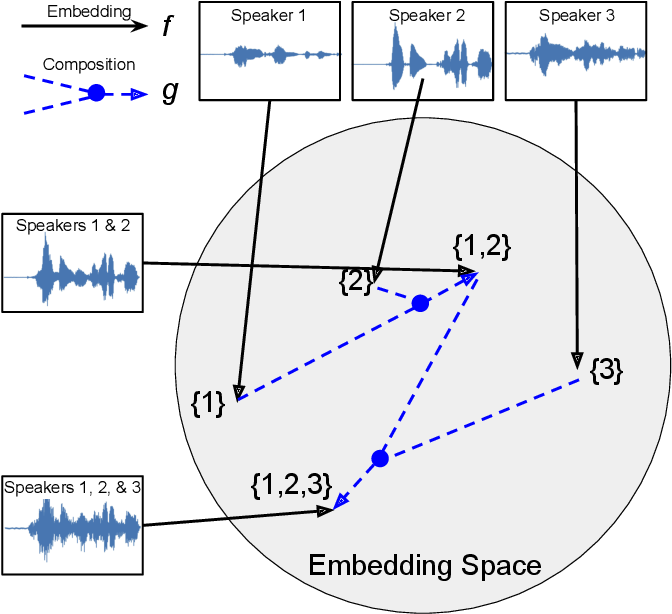
Figure 1 from Compositional Embedding Models for Speaker Identification ...

Figure 1 from Vision-Guided Speaker Embedding Based Speech Separation ...
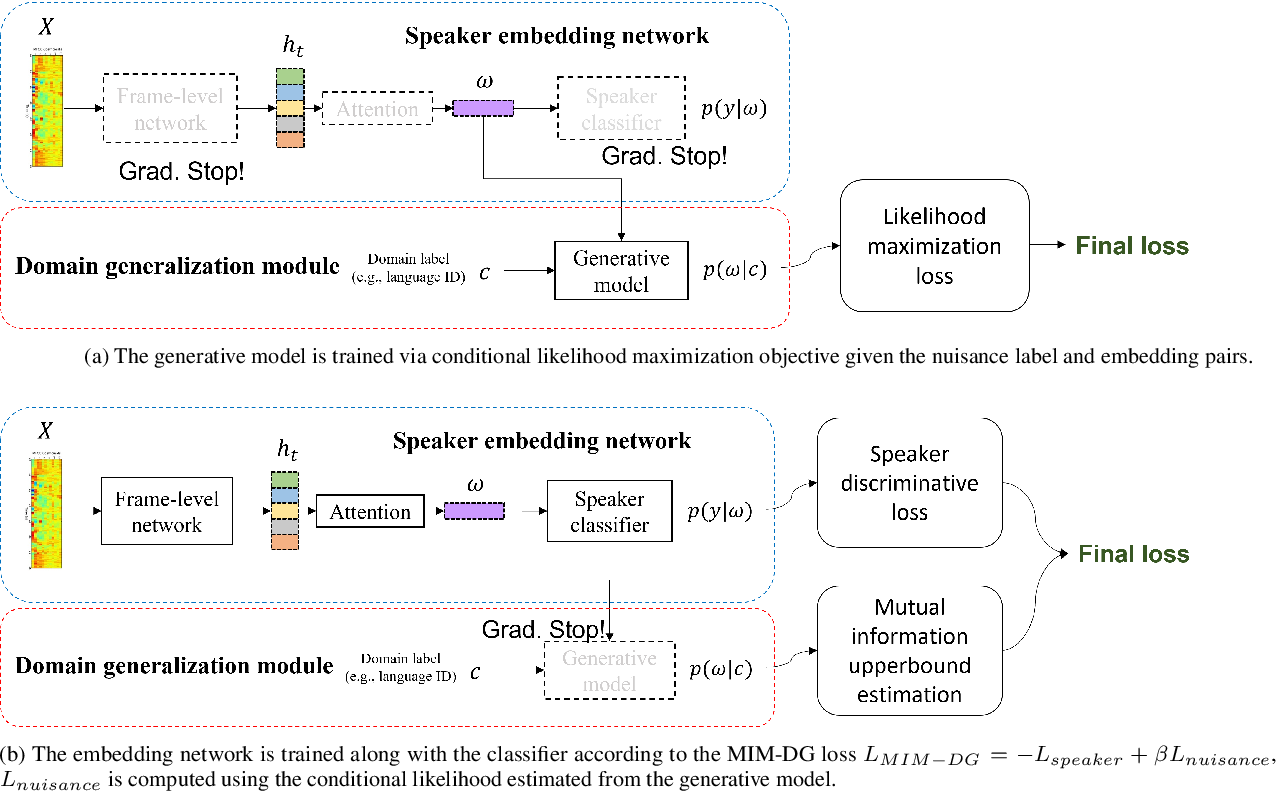
Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...

Figure 1 from High-Resolution Embedding Extractor for Speaker ...

Figure 1 from Joint Training of Speaker Embedding Extractor, Speech and ...
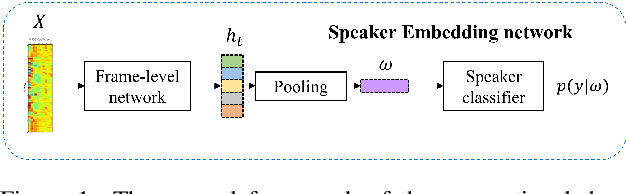
Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...
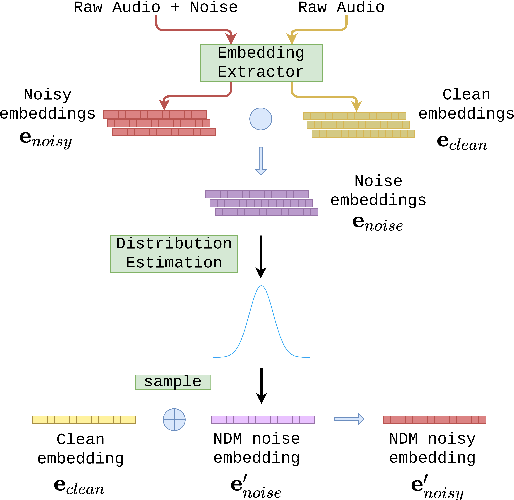
Figure 1 from Speaker Embedding Augmentation with Noise Distribution ...
Advertisement Space (336x280)

Figure 1 from Target Speaker Extraction with Curriculum Learning ...

Figure 1 from Multi-Stage Speaker Extraction with Utterance and Frame ...

Figure 1 from Target Speaker Extraction with Attention Enhancement and ...

Figure 1 from Speech Rhythm-Based Speaker Embeddings Extraction from ...

Figure 1 from Speaker Embedding-aware Neural Diarization: an Efficient ...

Figure 1 from An Efficient Approach for MFCC Feature Extraction for ...

Figure 1 from High-Resolution Embedding Extractor for Speaker ...
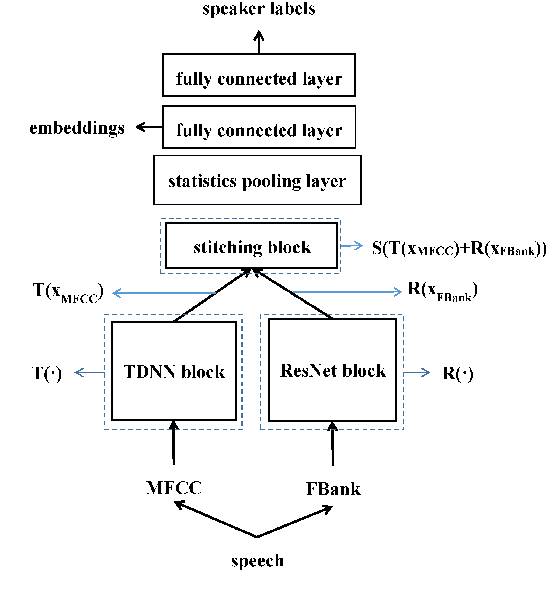
Figure 3 from Speaker Embedding Extraction with Multi-feature ...

Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...

Figure 1 from End-to-End Multi-Speaker Speech Recognition using Speaker ...
Advertisement Space (336x280)
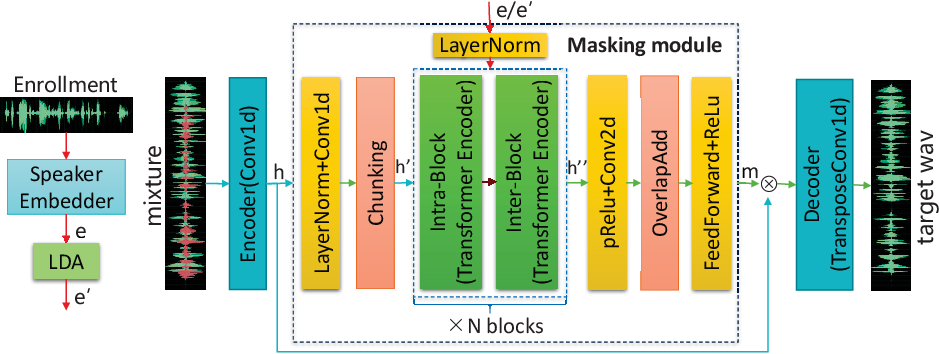
Figure 1 from Improving Target Speaker Extraction with Sparse LDA ...

Figure 1 from Single Channel Target Speaker Extraction Based on Deep ...
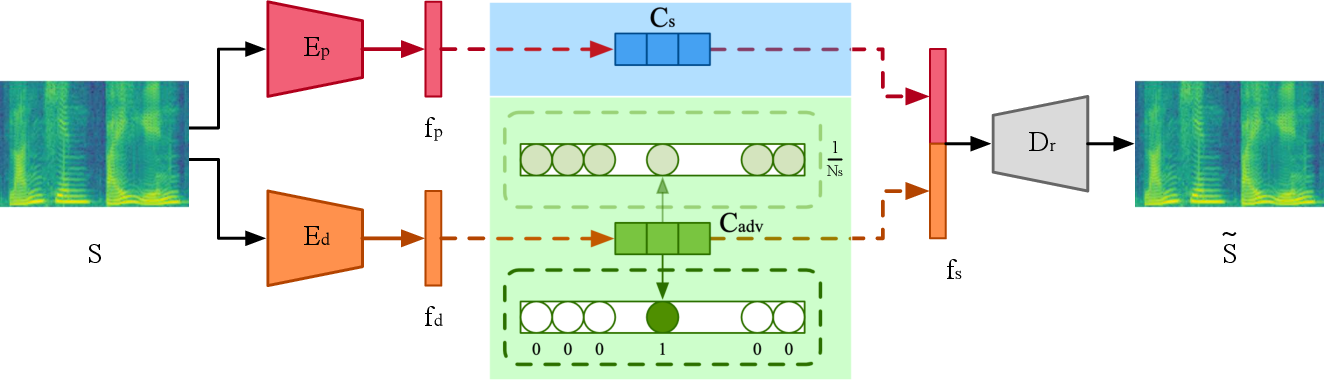
Figure 1 from Powerful Speaker Embedding Training Framework by ...

Table 1 from MC-SpEx: Towards Effective Speaker Extraction with Multi ...

Figure 1 from Speaker-Aware Target Speaker Enhancement by Jointly ...

Figure 1 from Speaker Embeddings With Weakly Supervised Voice Activity ...