
Figure 2 From Efficient Llm Inference Solution On Intel Gpu Semantic

Figure 2 from Efficient LLM inference solution on Intel GPU | Semantic ...

Figure 3 from Efficient LLM inference solution on Intel GPU | Semantic ...

Figure 6 from Efficient LLM inference solution on Intel GPU | Semantic ...

Table 1 from Efficient LLM inference solution on Intel GPU | Semantic ...

Table 1 from Efficient LLM inference solution on Intel GPU | Semantic ...
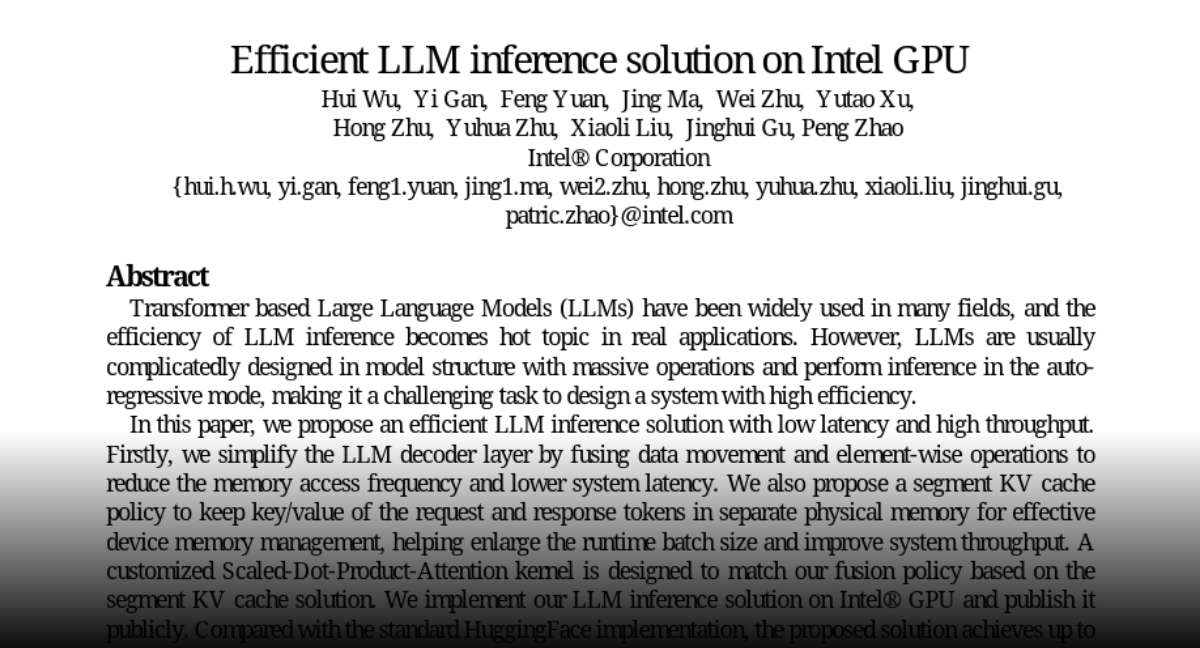
Paper page - Efficient LLM inference solution on Intel GPU

Intel presents Efficient LLM inference solution on Intel GPU paper page ...
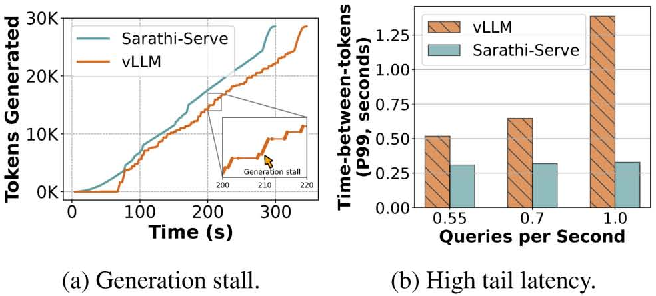
Figure 1 from Efficient LLM Inference via Chunked Prefills | Semantic ...
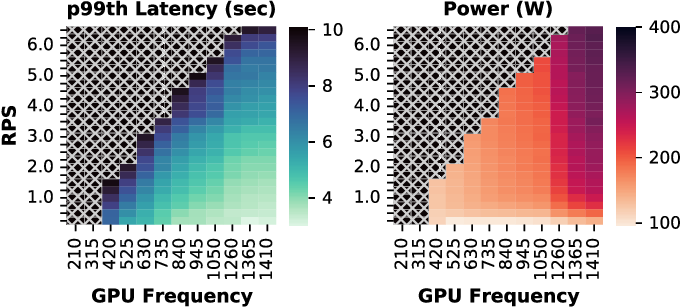
Figure 1 from SLO-Aware GPU DVFS for Energy-Efficient LLM Inference ...

Figure 1 from A Systematic Characterization of LLM Inference on GPUs ...
Advertisement Space (300x250)

Demo | LLM Inference on Intel® Data Center GPU Flex Series | Intel ...

[논문 리뷰] Cronus: Efficient LLM inference on Heterogeneous GPU Clusters ...
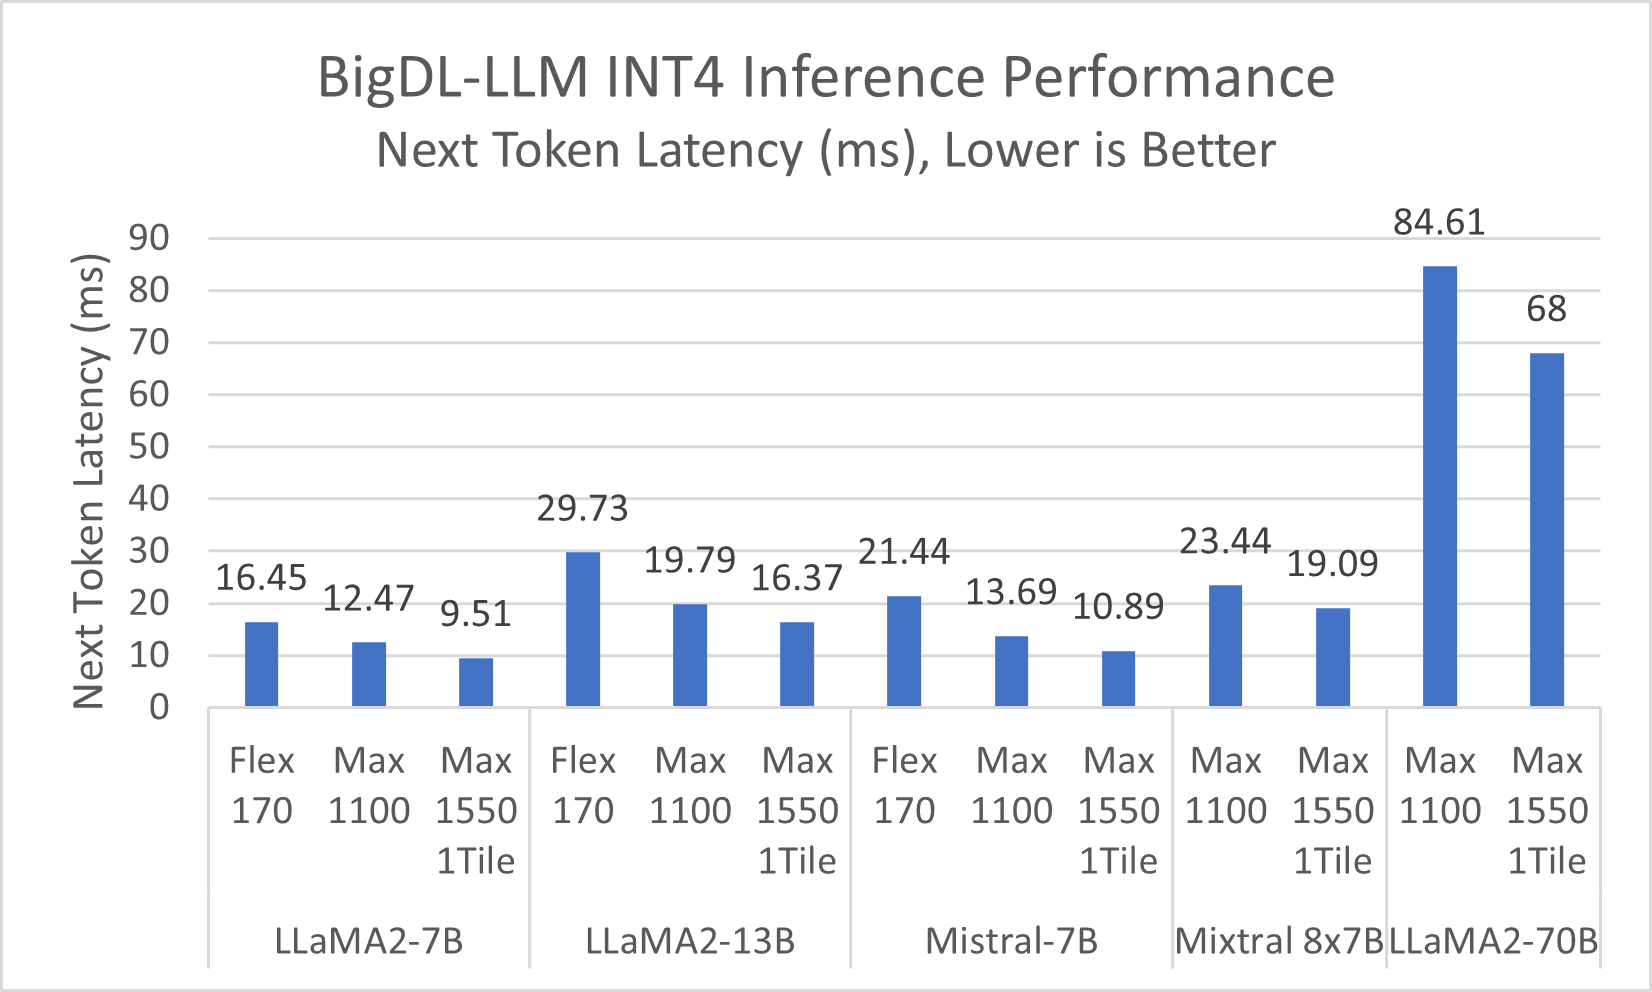
Accelerating LLM Inference on Intel Data Center GPUs using BigDL LLM

SLO-aware GPU Frequency Scaling for Energy Efficient LLM Inference ...

SLO-aware GPU Frequency Scaling for Energy Efficient LLM Inference ...
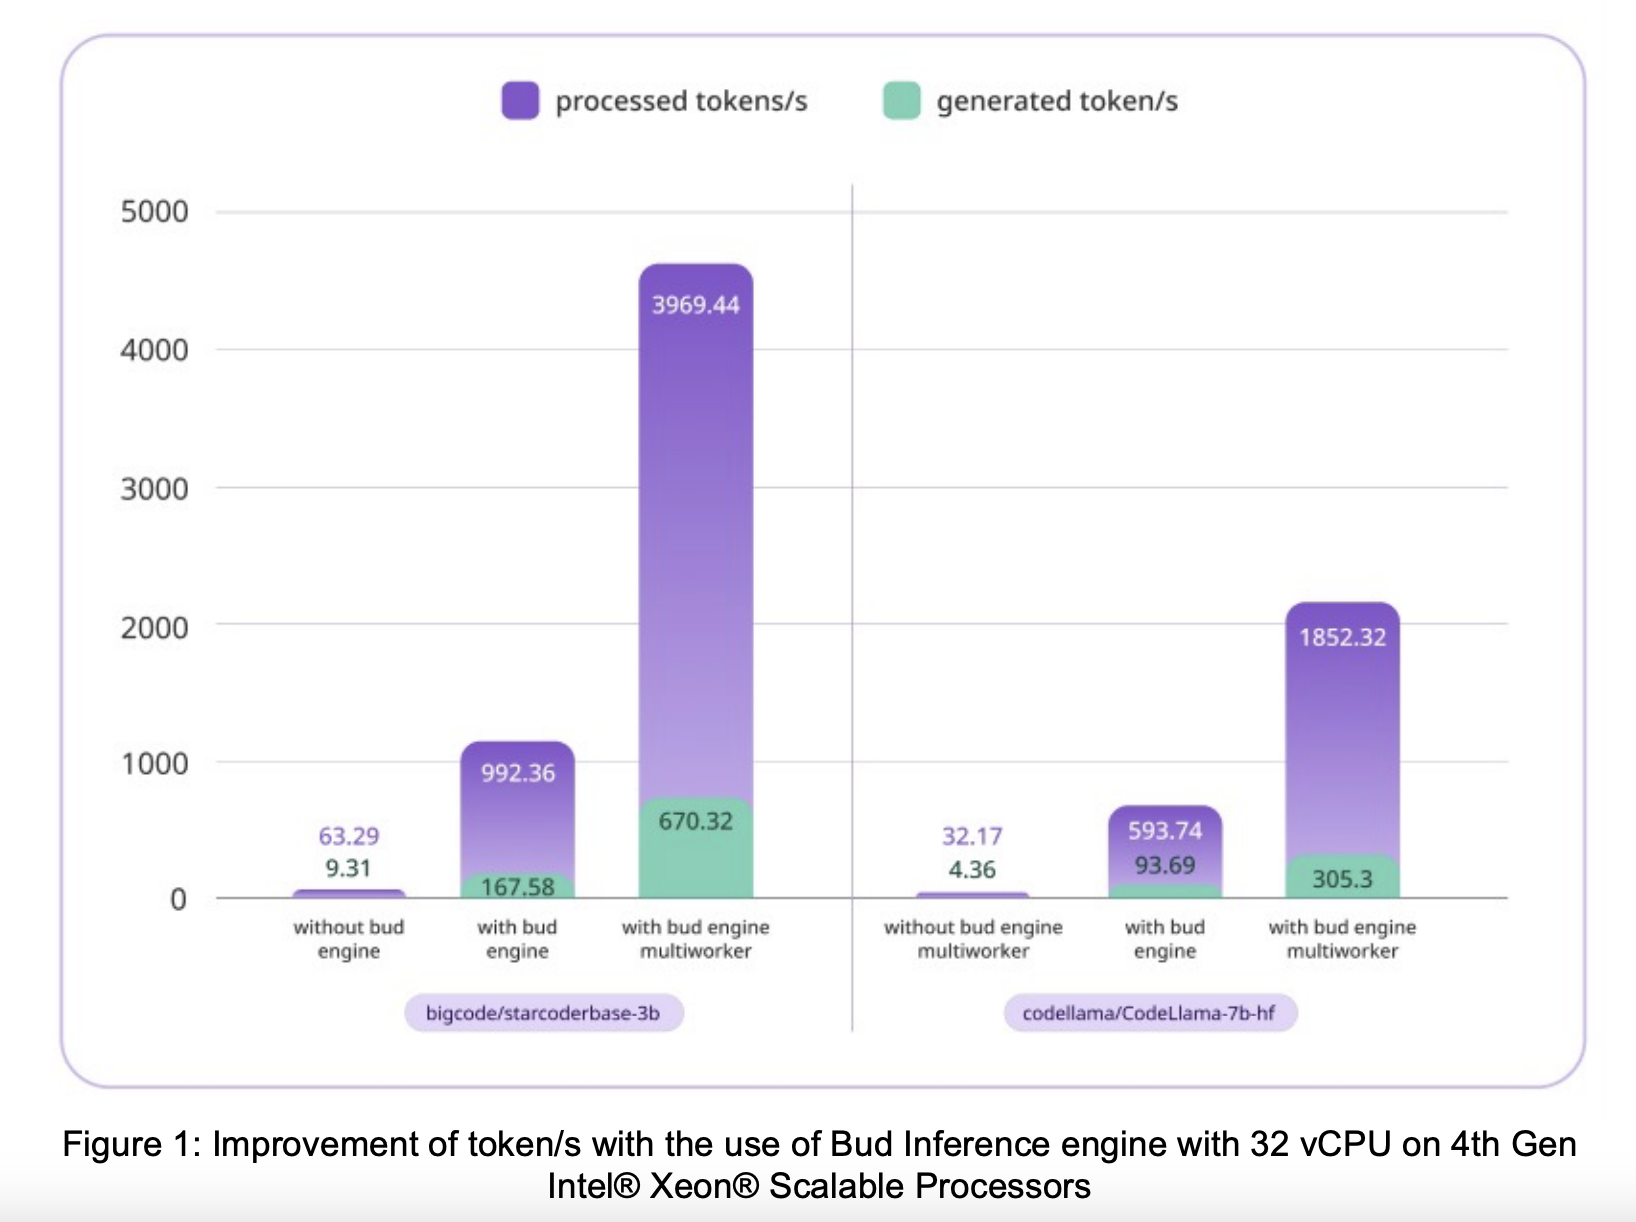
Enhancing LLM inference performance on Intel CPUs - BudEcosystem
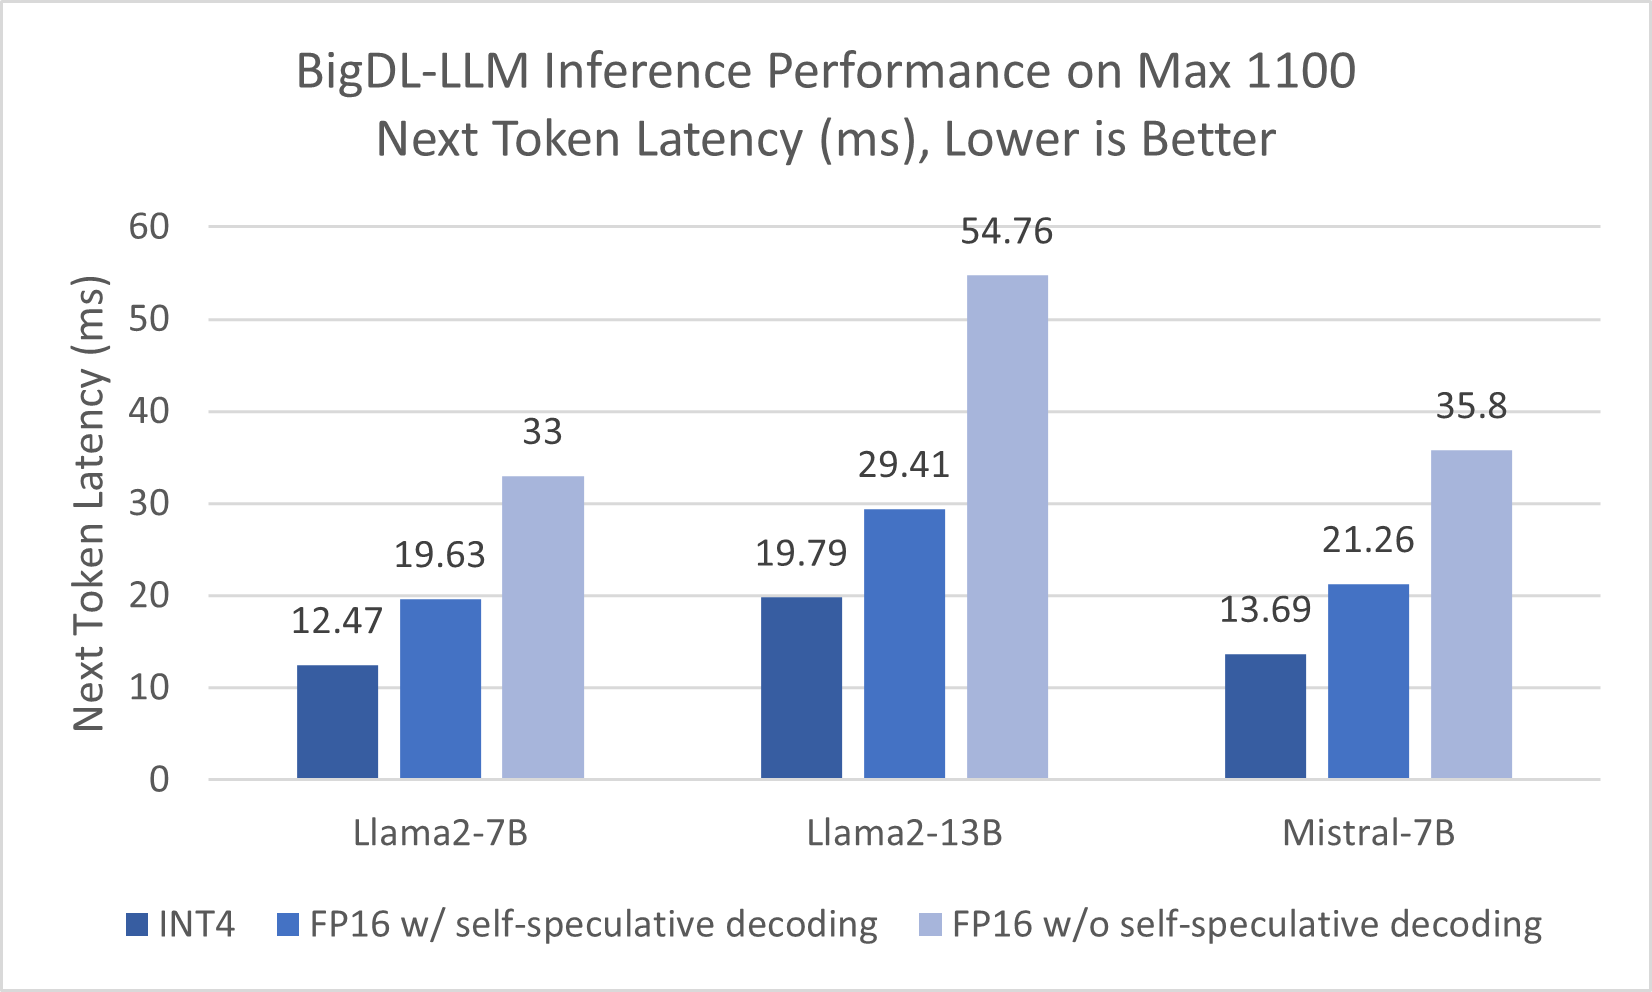
Accelerating LLM Inference on Intel Data Center GPUs using BigDL LLM

Figure 1 from An Efficient Inference Frame for SMLM (Single-Molecule ...
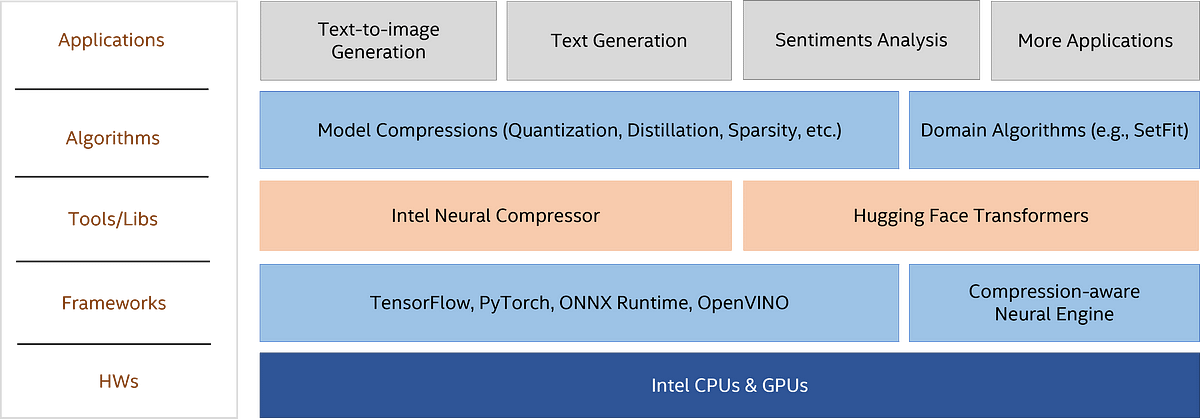
Highly-efficient LLM Inference on Intel Platforms | by Intel(R) Neural ...
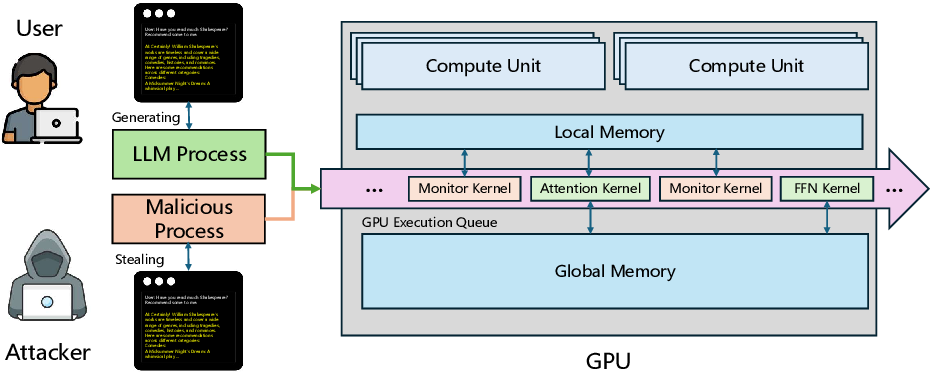
Figure 1 from A First Look At Efficient And Secure On-Device LLM ...
Advertisement Space (336x280)

Figure 1 from SparQ Attention: Bandwidth-Efficient LLM Inference ...

Outshift | LLM inference optimization: An efficient GPU traffic routing ...

[PDF] A Systematic Characterization of LLM Inference on GPUs | Semantic ...
LLM Training and Inference with Intel Gaudi 2 AI Accelerators ...

Figure 1 from Medusa: Simple LLM Inference Acceleration Framework with ...
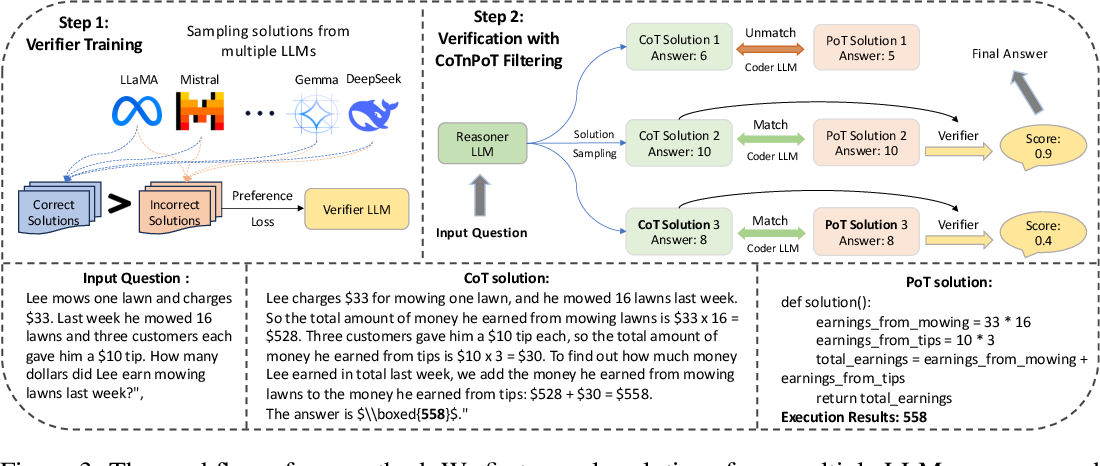
Figure 3 from Improving LLM Reasoning through Scaling Inference ...

Accelerate LLM Inference on Your Local PC

[논문 리뷰] SLO-aware GPU Frequency Scaling for Energy Efficient LLM ...
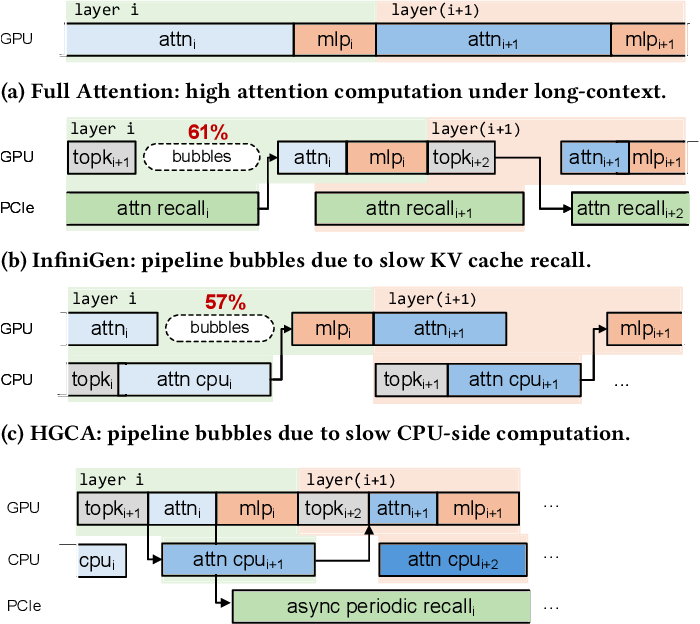
Figure 1 from ScoutAttention: Efficient KV Cache Offloading via Layer ...

Figure 3 from FastDecode: High-Throughput GPU-Efficient LLM Serving ...
Advertisement Space (336x280)

LLM Inference - Consumer GPU performance | Puget Systems

(PDF) Characterizing and Optimizing LLM Inference Workloads on CPU-GPU ...

Parallel CPU-GPU Execution for LLM Inference on Constrained GPUs | AI ...
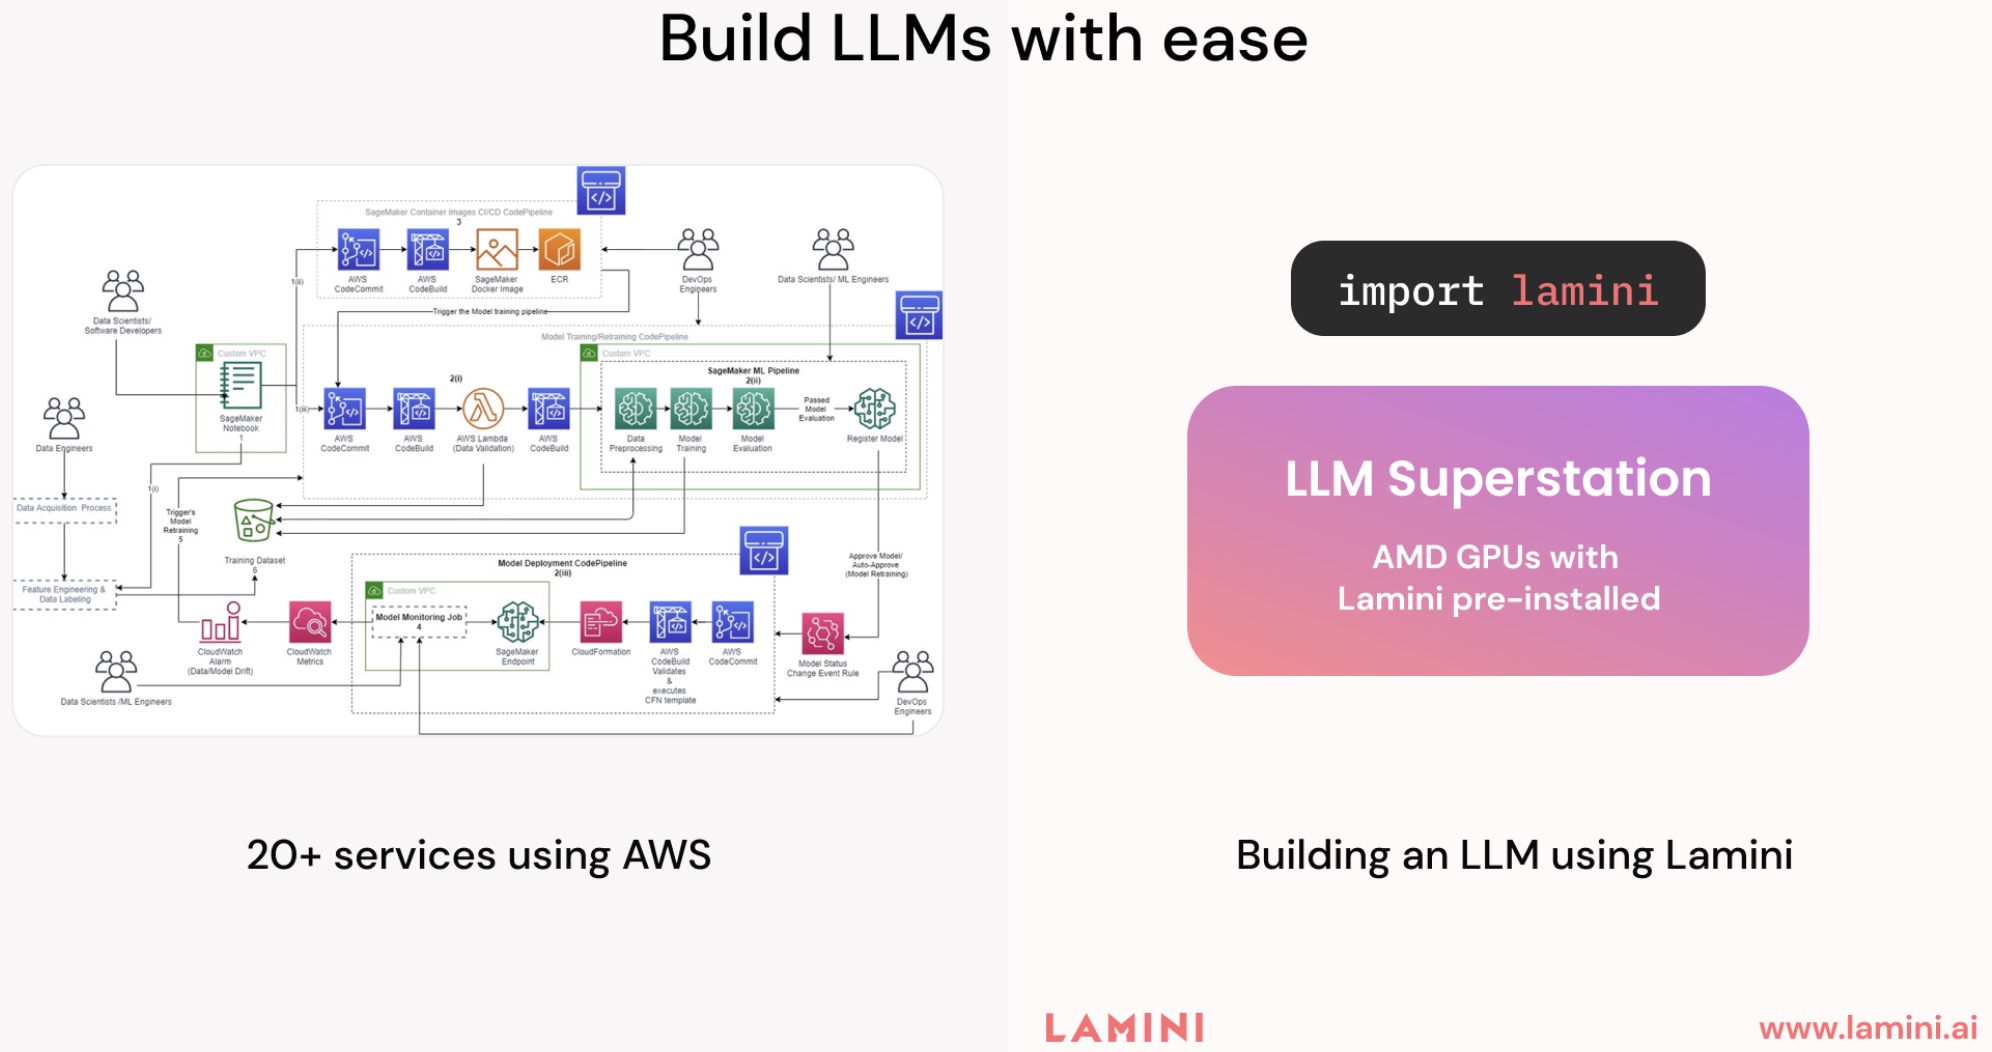
LLM Inference Hardware: Emerging from Nvidia's Shadow

Optimizing LLM Inference on Intel® Gaudi® Accelerators with llm-d ...

[PDF] A Survey of LLM Inference Systems | Semantic Scholar