
Table 1 From Efficient Llm Inference Solution On Intel Gpu Semantic

Table 1 from Efficient LLM inference solution on Intel GPU | Semantic ...

Table 1 from Efficient LLM inference solution on Intel GPU | Semantic ...

Figure 3 from Efficient LLM inference solution on Intel GPU | Semantic ...

Figure 2 from Efficient LLM inference solution on Intel GPU | Semantic ...

Figure 6 from Efficient LLM inference solution on Intel GPU | Semantic ...
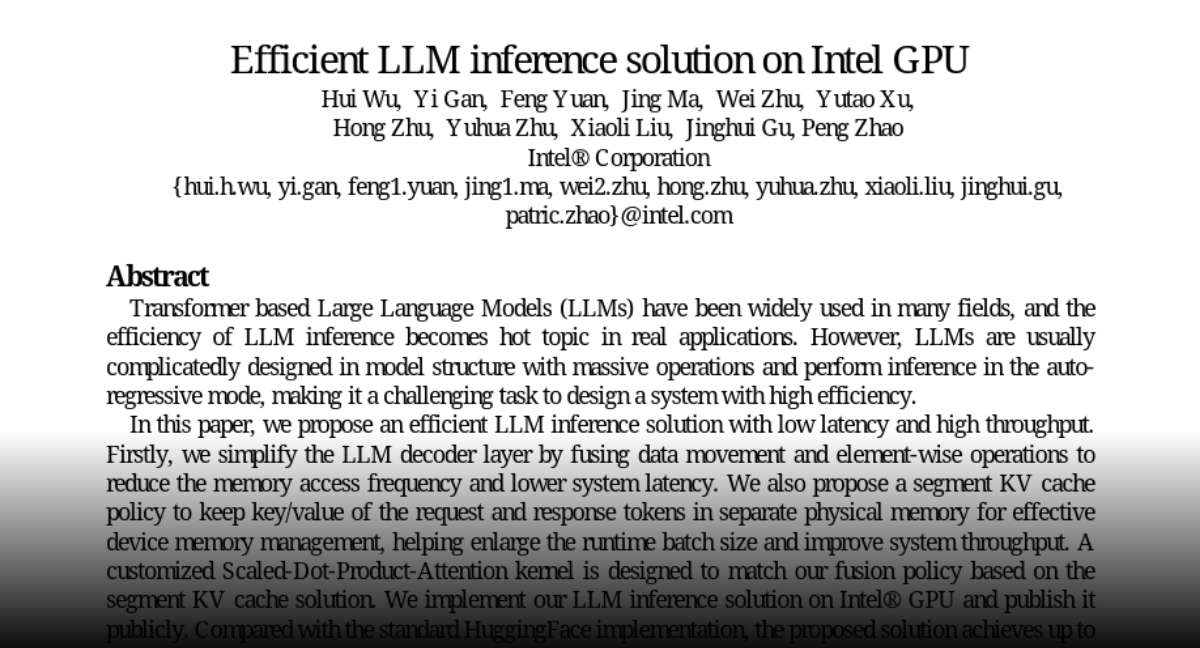
Paper page - Efficient LLM inference solution on Intel GPU

Intel presents Efficient LLM inference solution on Intel GPU paper page ...

Efficient LLM-An efficient solution for LLM inference on Intel GPUs.
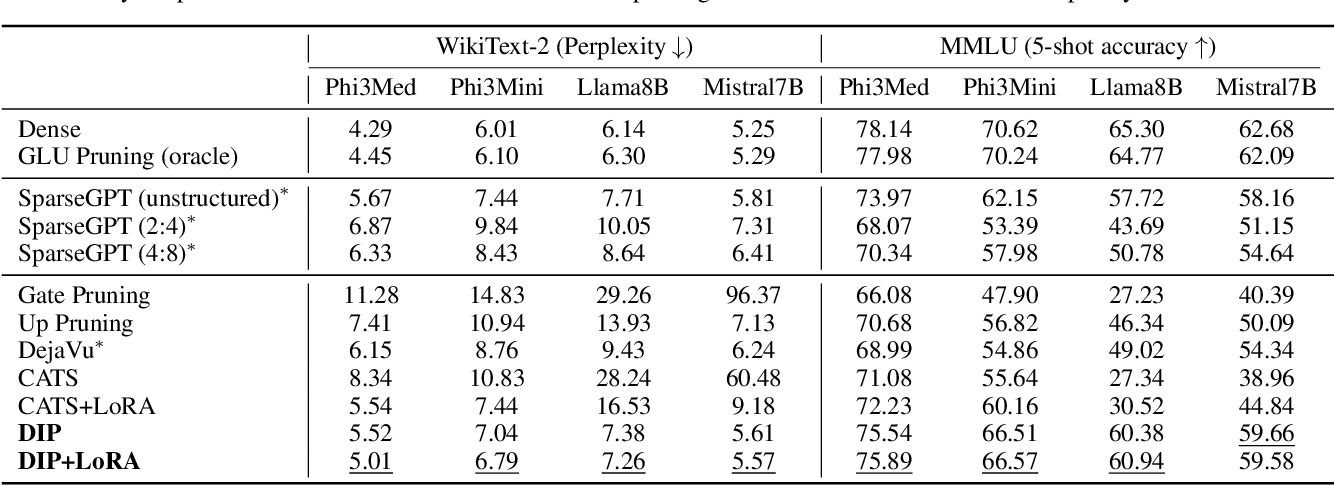
Table 1 from Efficient LLM Inference using Dynamic Input Pruning and ...
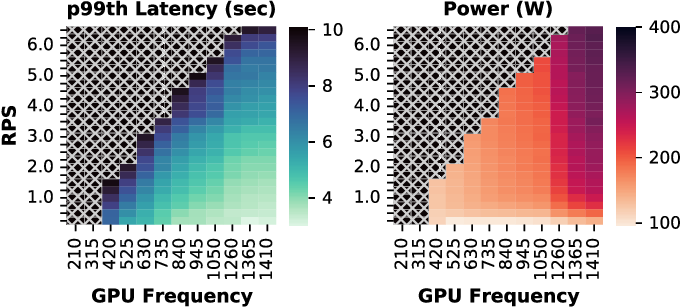
Figure 1 from SLO-Aware GPU DVFS for Energy-Efficient LLM Inference ...
Advertisement Space (300x250)
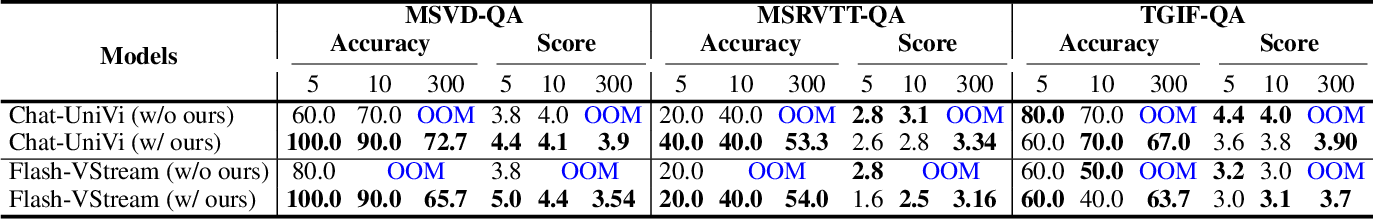
Table 1 from Inf-MLLM: Efficient Streaming Inference of Multimodal ...

Table 1 from Improving LLM Reasoning through Scaling Inference ...

Figure 1 from A Systematic Characterization of LLM Inference on GPUs ...
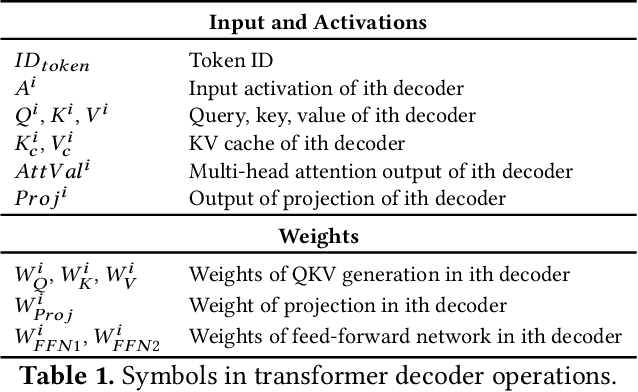
Table 1 from Throughput-Oriented LLM Inference via KV-Activation Hybrid ...

Demo | LLM Inference on Intel® Data Center GPU Flex Series | Intel ...
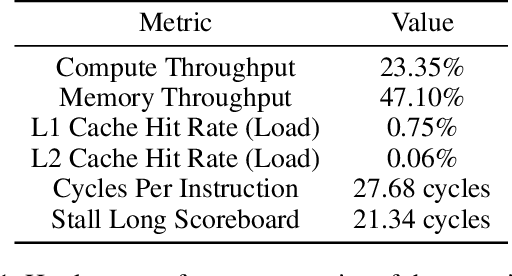
Table 1 from Accelerating LLM Inference Throughput via Asynchronous KV ...
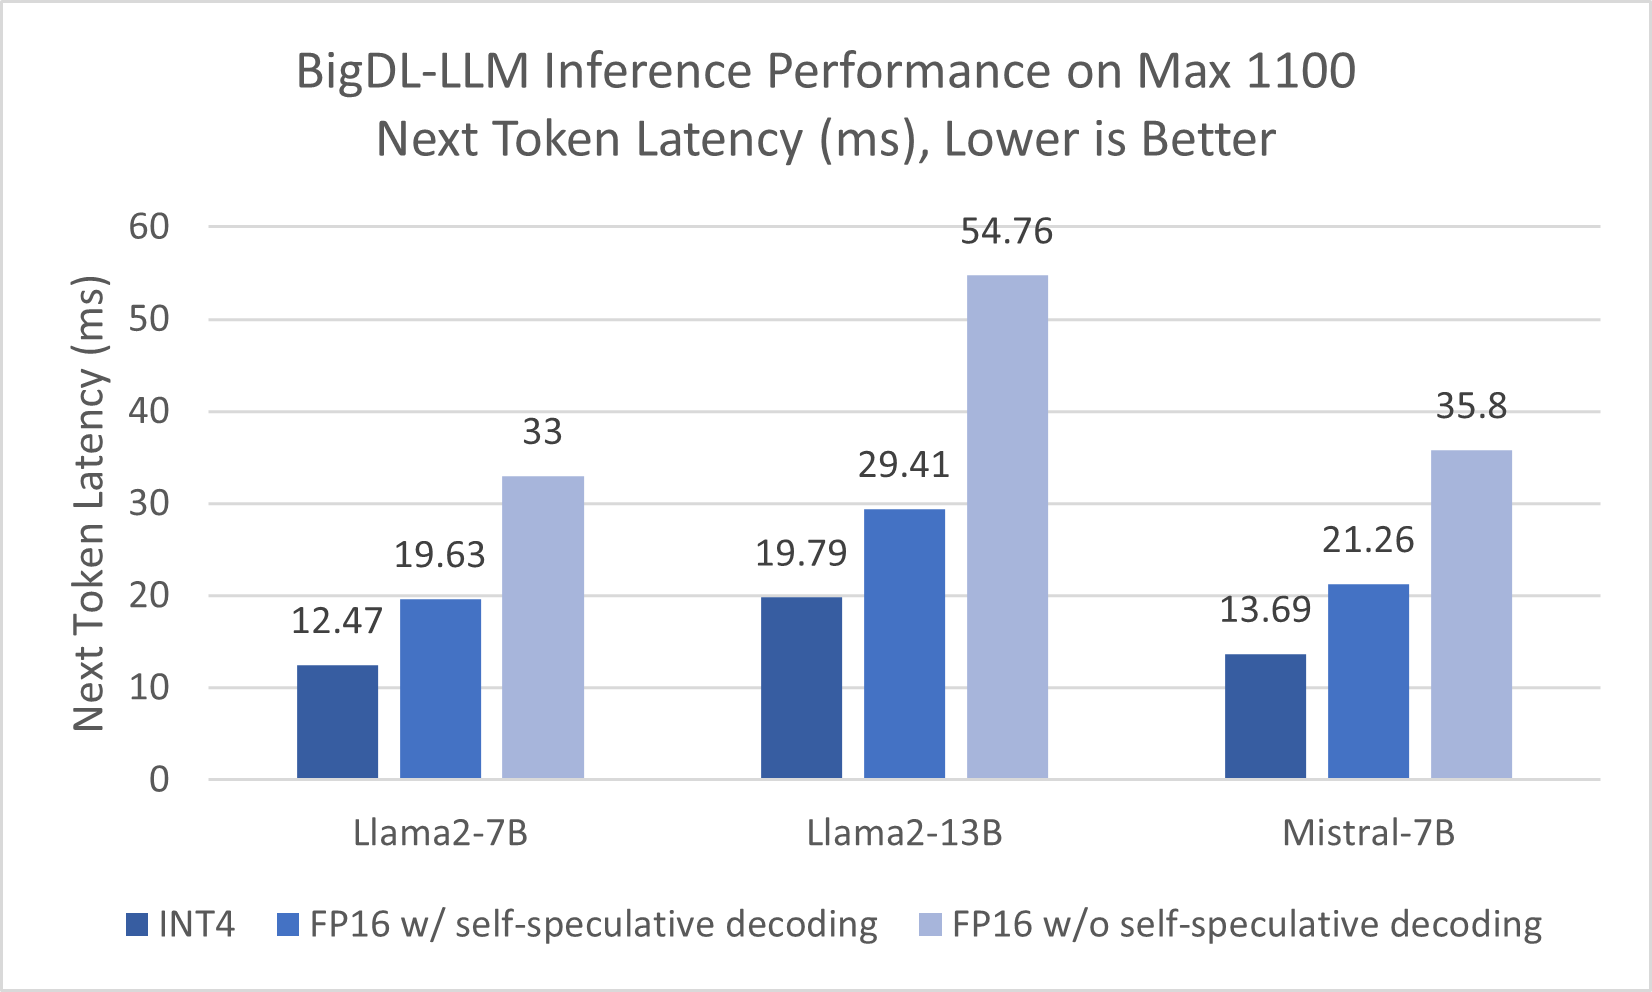
Accelerating LLM Inference on Intel Data Center GPUs using BigDL LLM
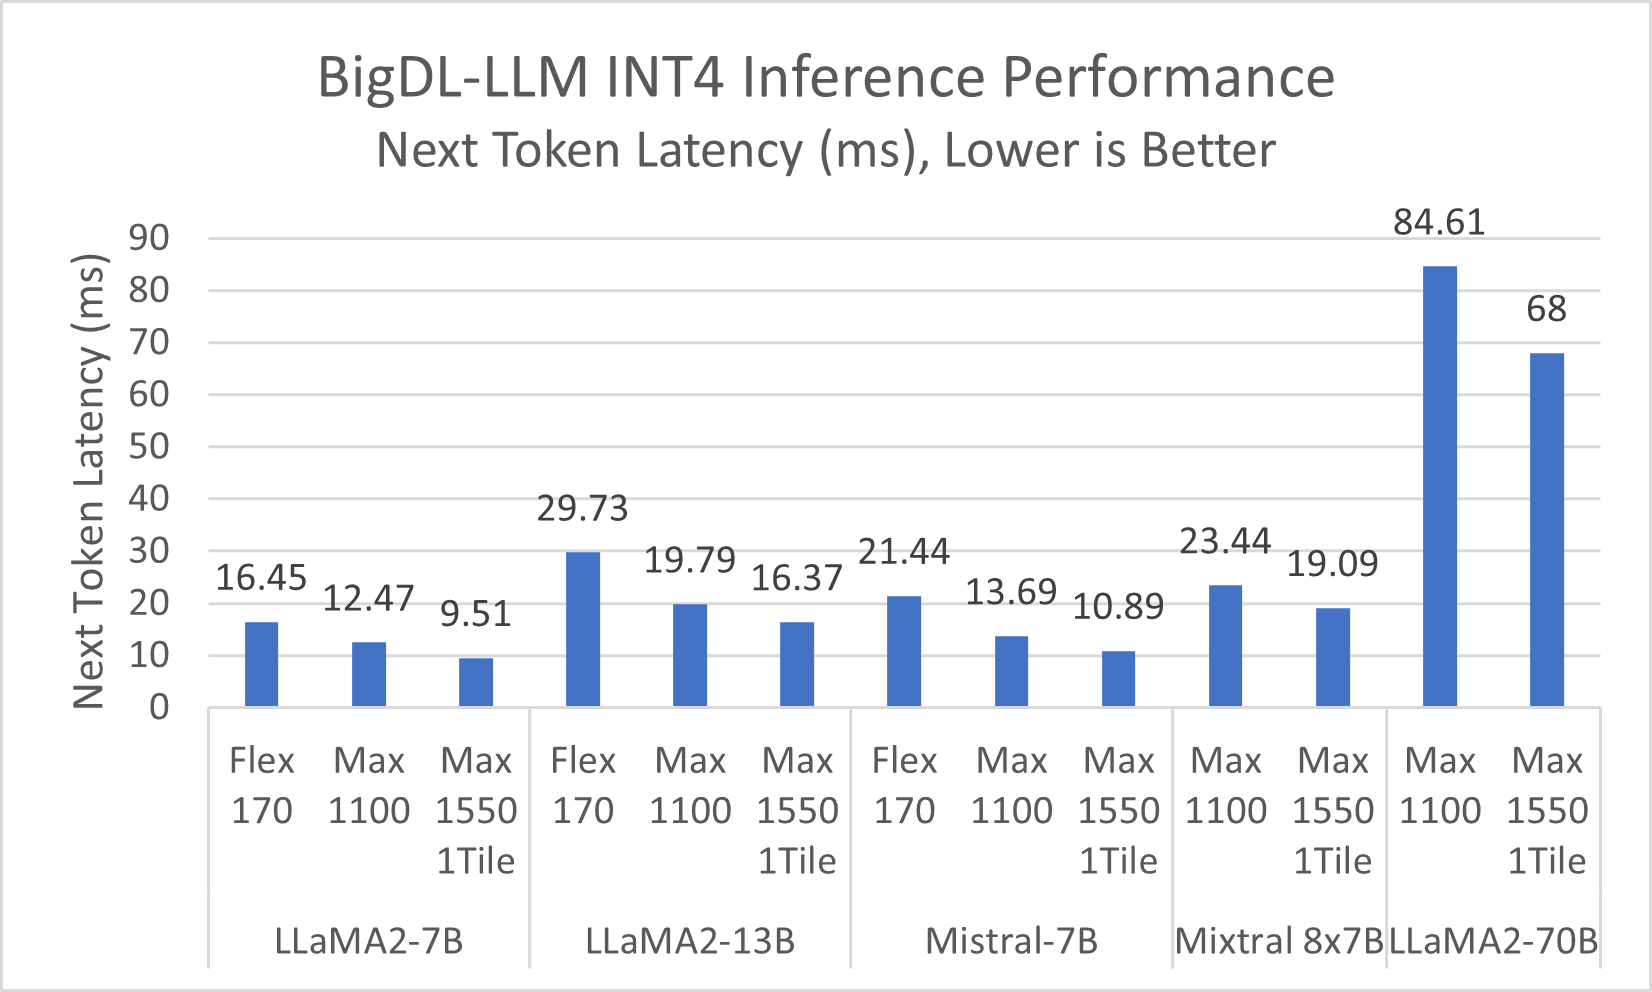
Accelerating LLM Inference on Intel Data Center GPUs using BigDL LLM

Table 1 from Energy Efficient or Exhaustive? Benchmarking Power ...
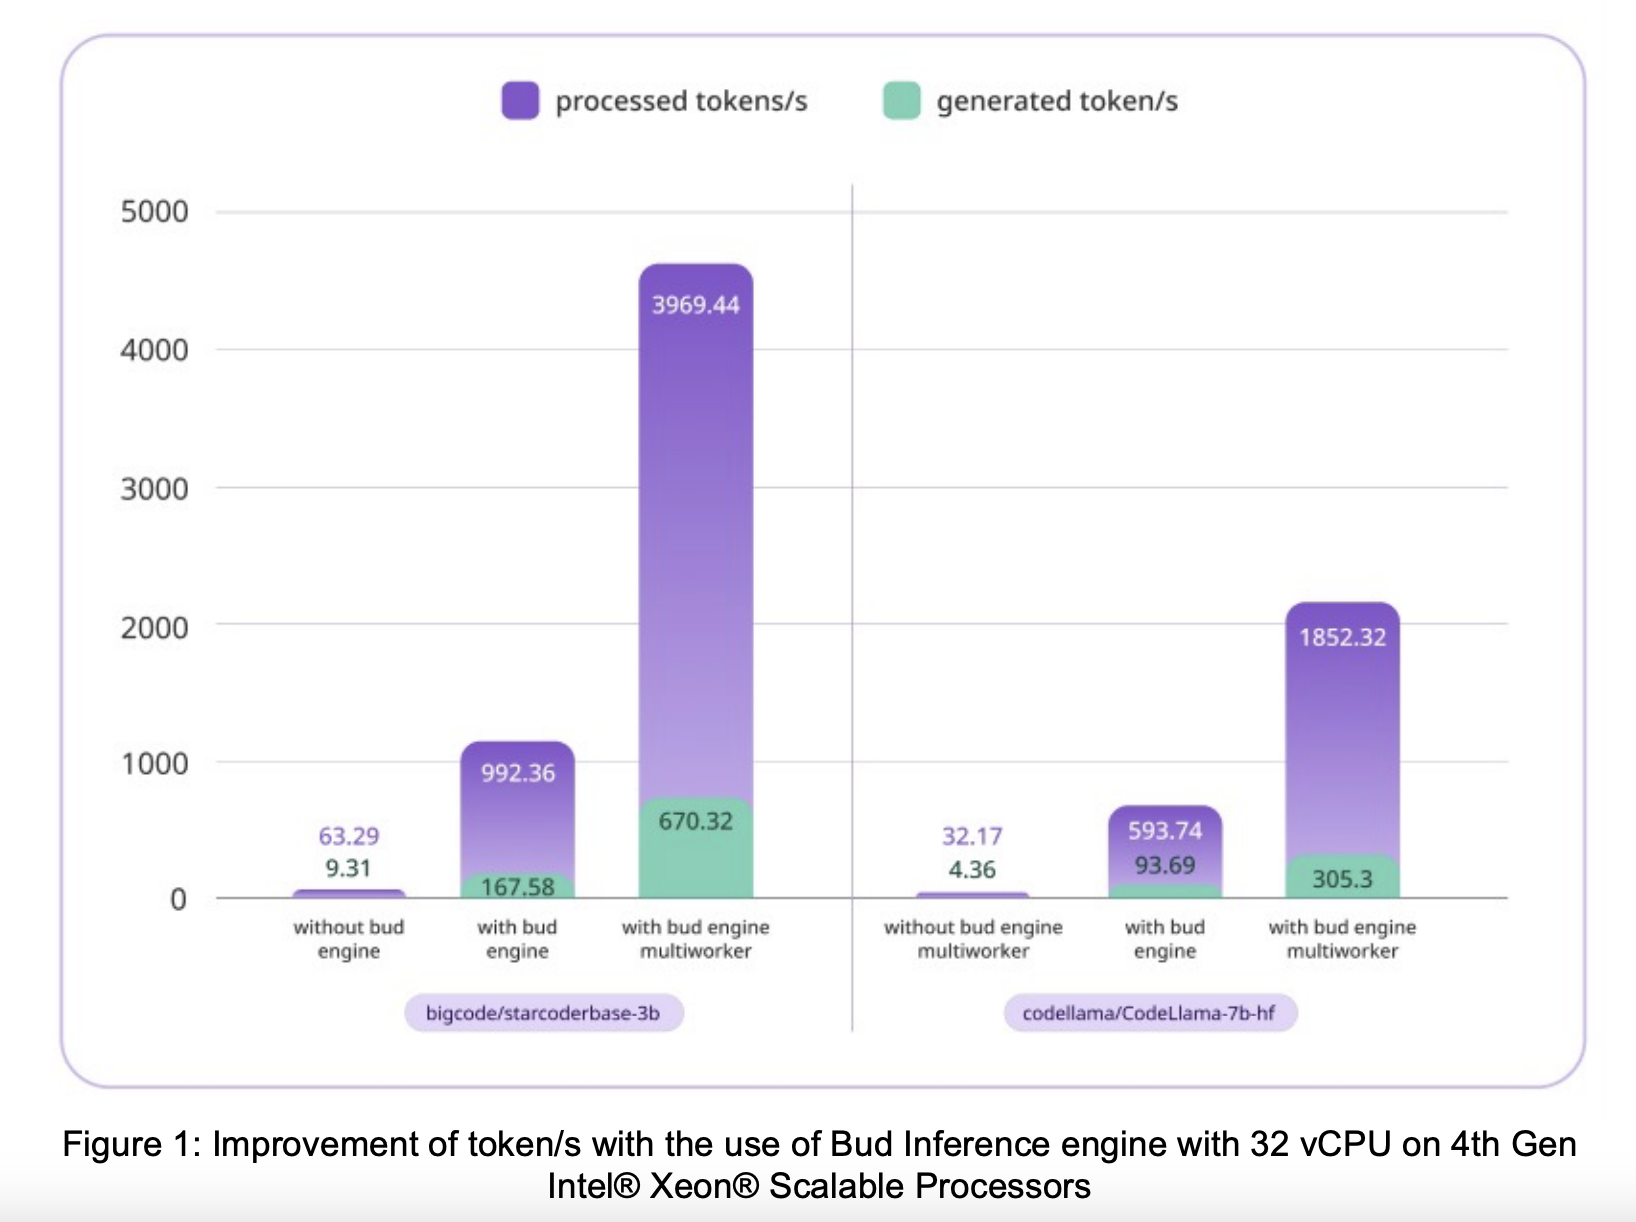
Enhancing LLM inference performance on Intel CPUs - BudEcosystem
Advertisement Space (336x280)

SLO-aware GPU Frequency Scaling for Energy Efficient LLM Inference ...
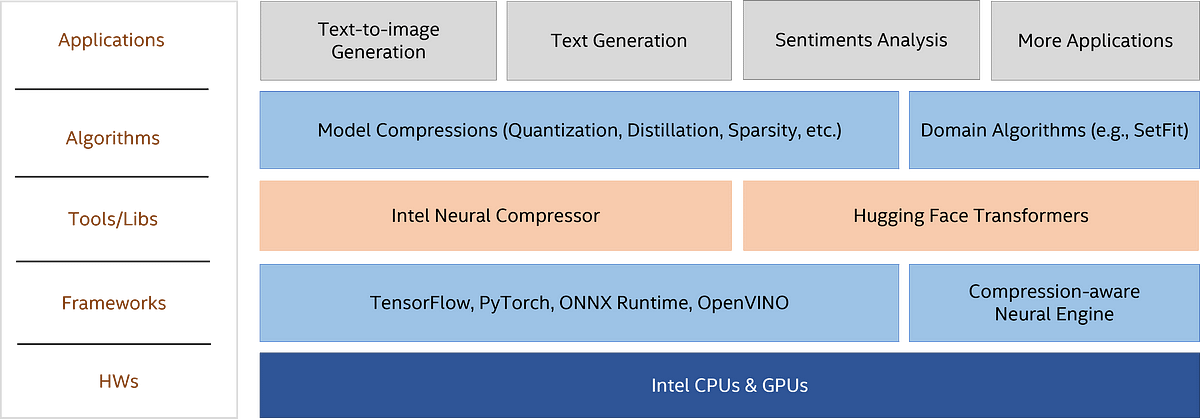
Highly-efficient LLM Inference on Intel Platforms | by Intel(R) Neural ...

Figure 1 from An Efficient Inference Frame for SMLM (Single-Molecule ...

[PDF] A Systematic Characterization of LLM Inference on GPUs | Semantic ...

Outshift | LLM inference optimization: An efficient GPU traffic routing ...

Figure 1 from Medusa: Simple LLM Inference Acceleration Framework with ...

SLO-aware GPU Frequency Scaling for Energy Efficient LLM Inference ...
How Public AI delivers sovereign LLM inference on AWS and Intel | AWS ...
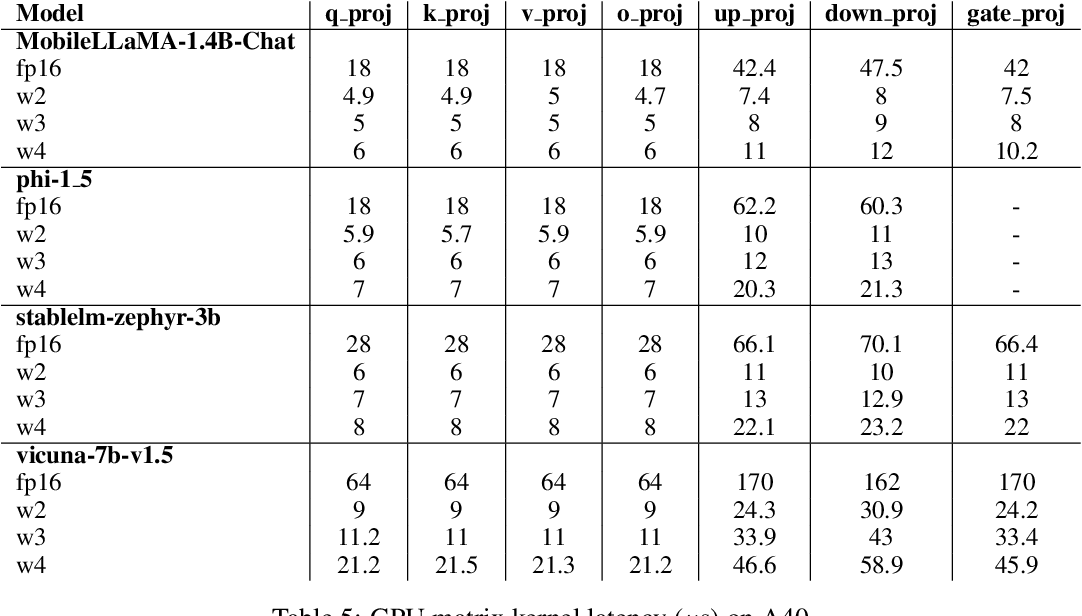
Table 5 from Progressive Mixed-Precision Decoding for Efficient LLM ...

Free Video: LLM Efficient Inference in CPUs and Intel GPUs - Intel ...
Advertisement Space (336x280)
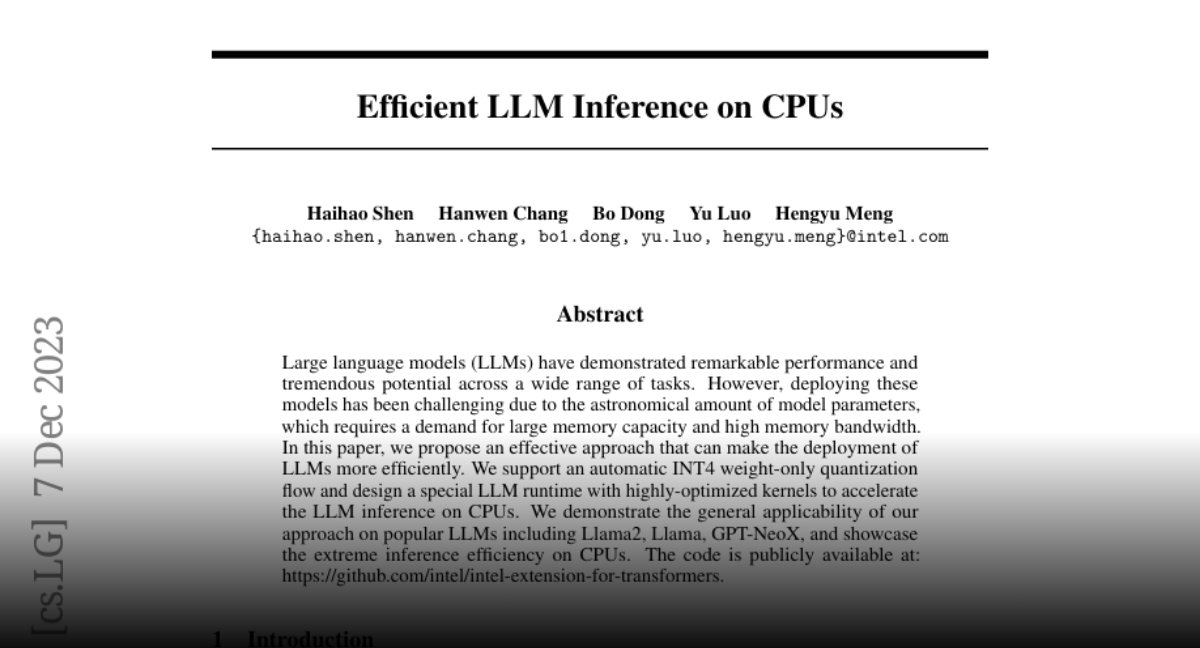
Paper page - Efficient LLM Inference on CPUs

LLM Inference - Consumer GPU performance | Puget Systems

[논문 리뷰] SLO-aware GPU Frequency Scaling for Energy Efficient LLM ...

Efficient KV Cache Spillover Management on Memory-Constrained GPU for ...

[PDF] A Survey of LLM Inference Systems | Semantic Scholar
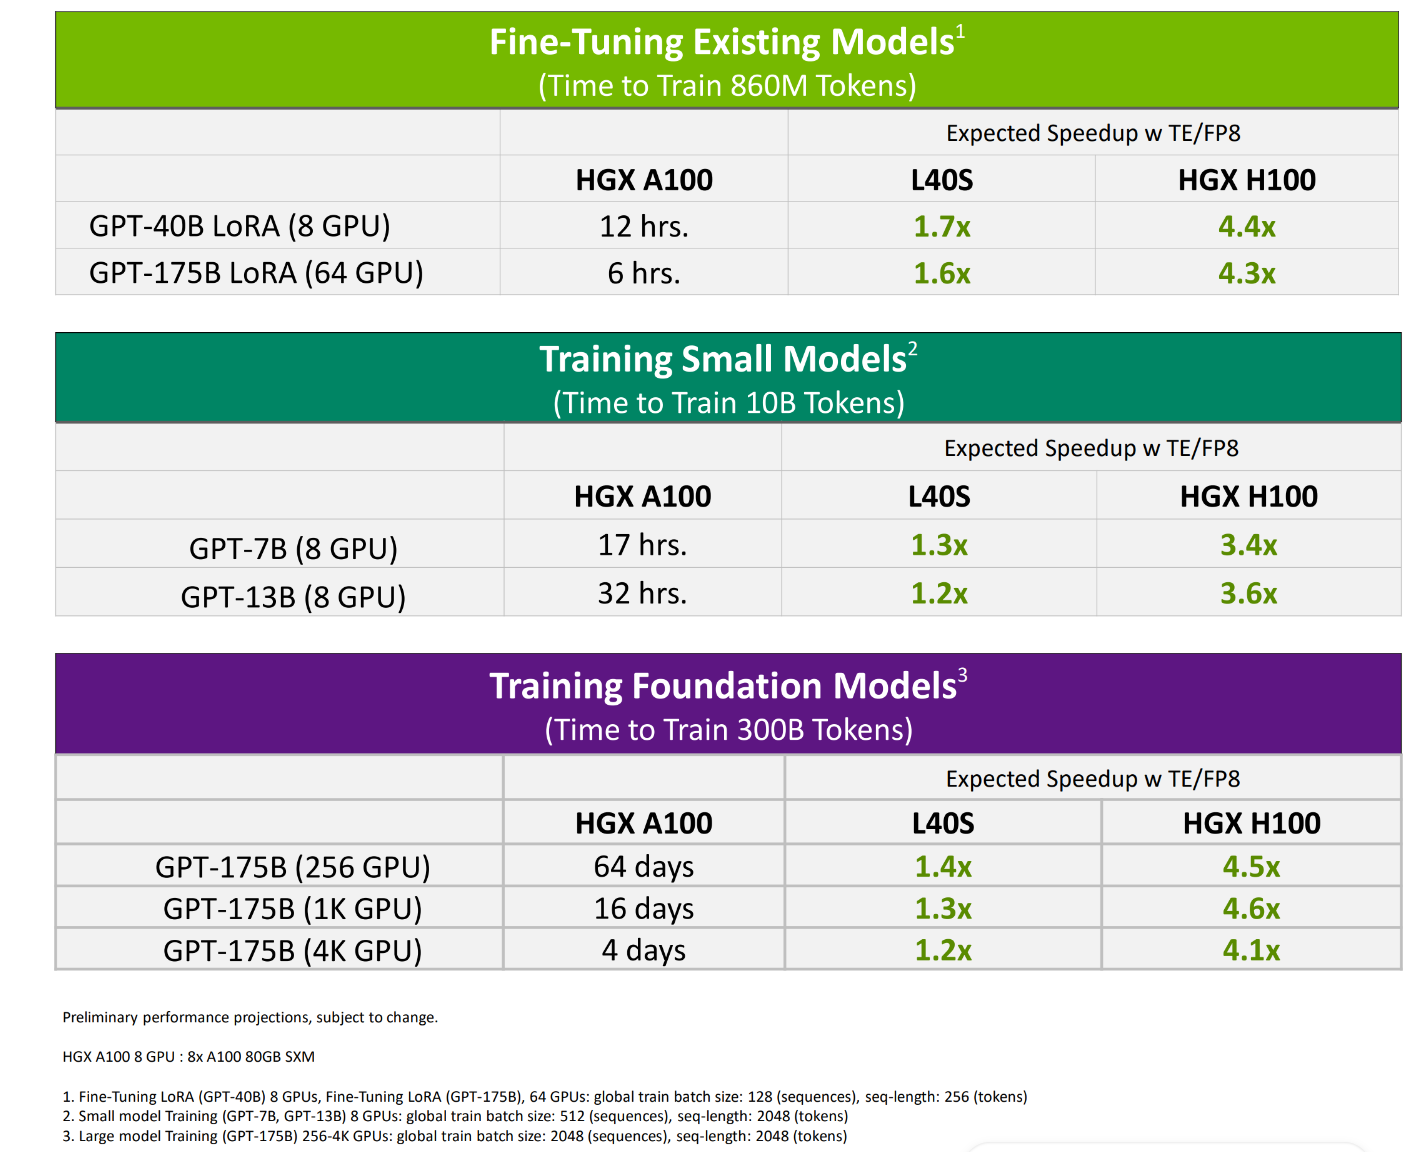
Choosing the Right GPU for LLM Inference and Training