
Scaling To Millions Of Tokens With Efficient Long Context Llm Training

Scaling to Millions of Tokens with Efficient Long-Context LLM Training ...

Scaling to Millions of Tokens with Efficient Long-Context LLM Training ...

Scaling to Millions of Tokens with Efficient Long-Context LLM Training ...

Scaling to Millions of Tokens with Efficient Long-Context LLM Training ...
Scaling to Millions of Tokens with Efficient Long-Context LLM Training ...

Scaling to Millions of Tokens with Efficient Long-Context LLM Training ...

Scaling to Millions of Tokens with Efficient Long-Context LLM Training ...

ByteScale: Efficient Scaling of LLM Training with a 2048K Context ...

Paper page - ByteScale: Efficient Scaling of LLM Training with a 2048K ...

Scaling with Collapse: Efficient and Predictable Training of LLM ...
Advertisement Space (300x250)

[논문 리뷰] From 128K to 4M: Efficient Training of Ultra-Long Context Large ...
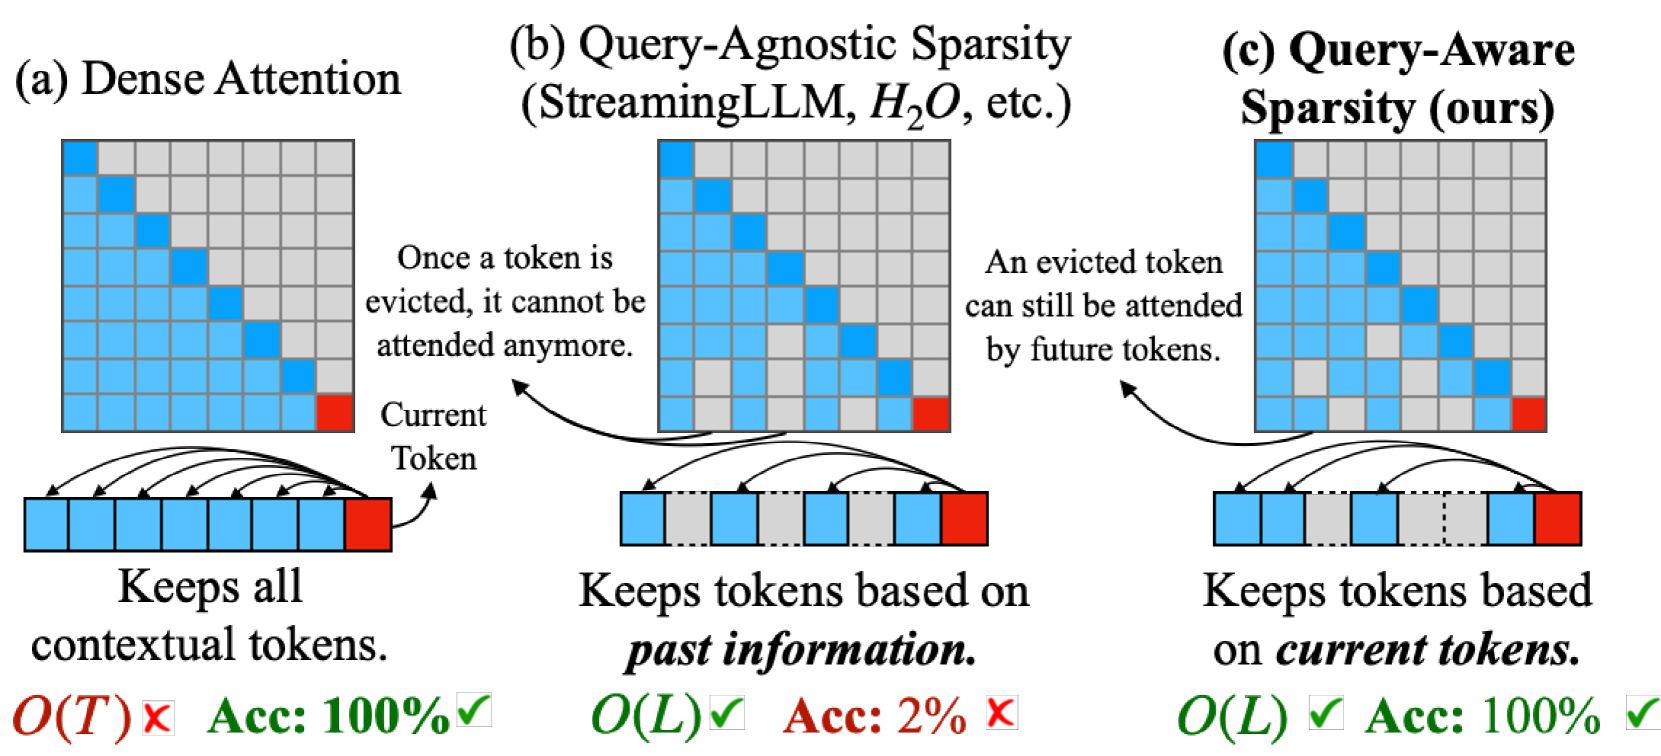
Near-Lossless Acceleration of Long Context LLM Inference with Adaptive ...

Infinite-LLM: Efficient LLM Service for Long Context with DistAttention ...

Extending LLM context with 99% less training tokens - Cerebras

[논문 리뷰] Scaling with Collapse: Efficient and Predictable Training of ...
LLM Scaling Laws: A Synthesis of Hyperparameter Optimization and Long ...

Stream: Scaling up Mechanistic Interpretability to Long Context in LLMs ...

Figure 1 from A Little Help Goes a Long Way: Efficient LLM Training by ...
Long-VITA: Scaling Large Multi-modal Models to 1 Million Tokens with ...

LazyLLM: Dynamic Token Pruning for Efficient Long Context LLM Inference ...
Advertisement Space (336x280)
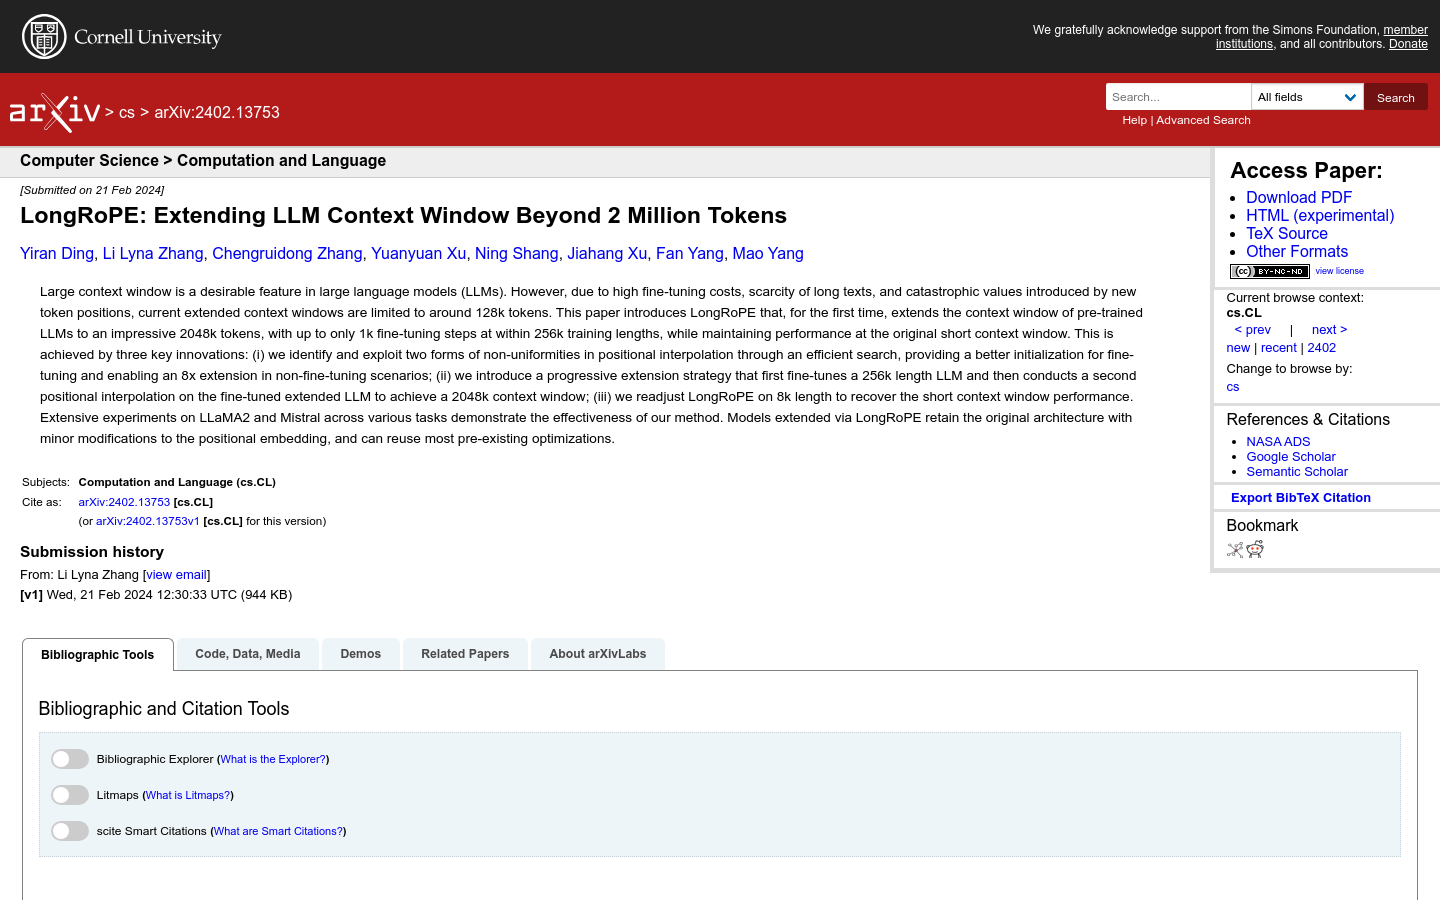
LongRoPE-Technology that extends the LLM context window to 2 million tokens

(PDF) LoongTrain: Efficient Training of Long-Sequence LLMs with Head ...
Billions of Tokens Later: Scaling LLM Fuzzing in Practice

[논문 리뷰] LazyLLM: Dynamic Token Pruning for Efficient Long Context LLM ...

Scaling Transformer to 1M tokens and beyond with RMT (Paper Explained ...

解读 Effective Long Context Scaling of Foundation Models - 知乎
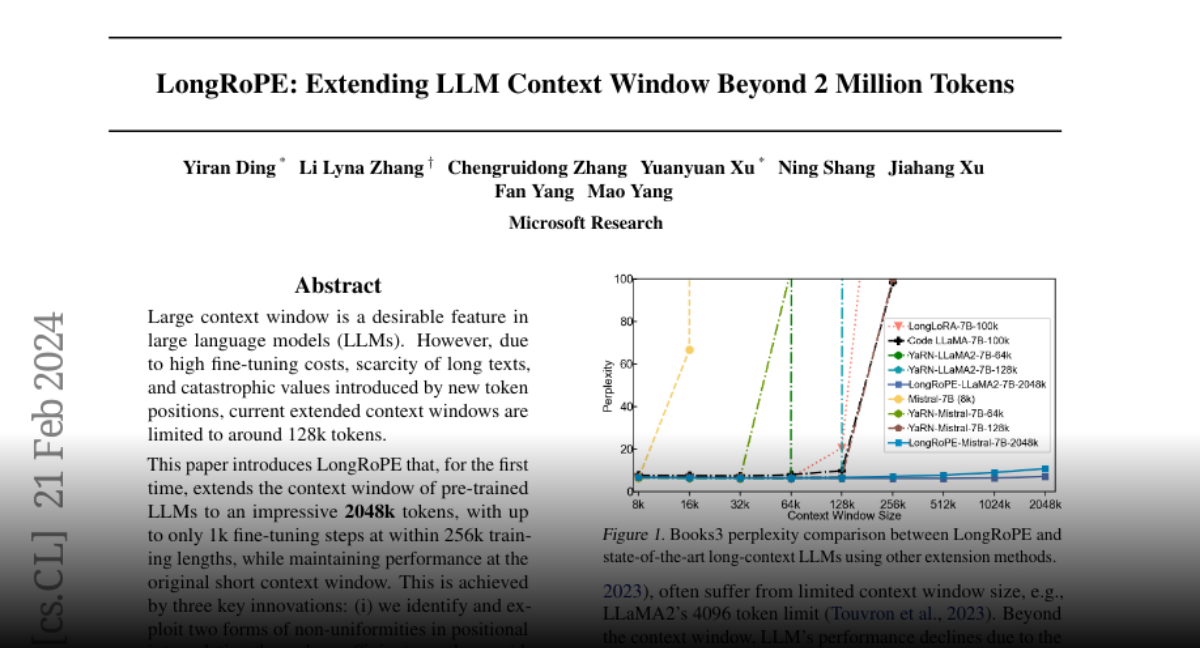
Paper page - LongRoPE: Extending LLM Context Window Beyond 2 Million Tokens
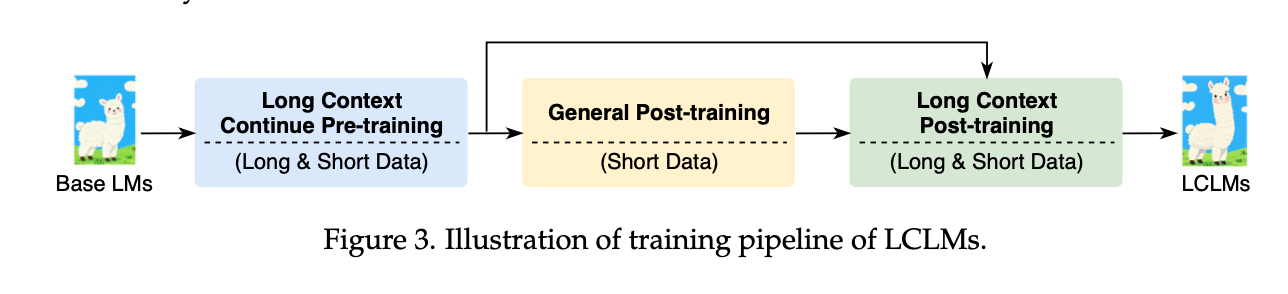
Long Context LLM (1): Pre-training부터 Post-training까지 data 전략 | ML감자
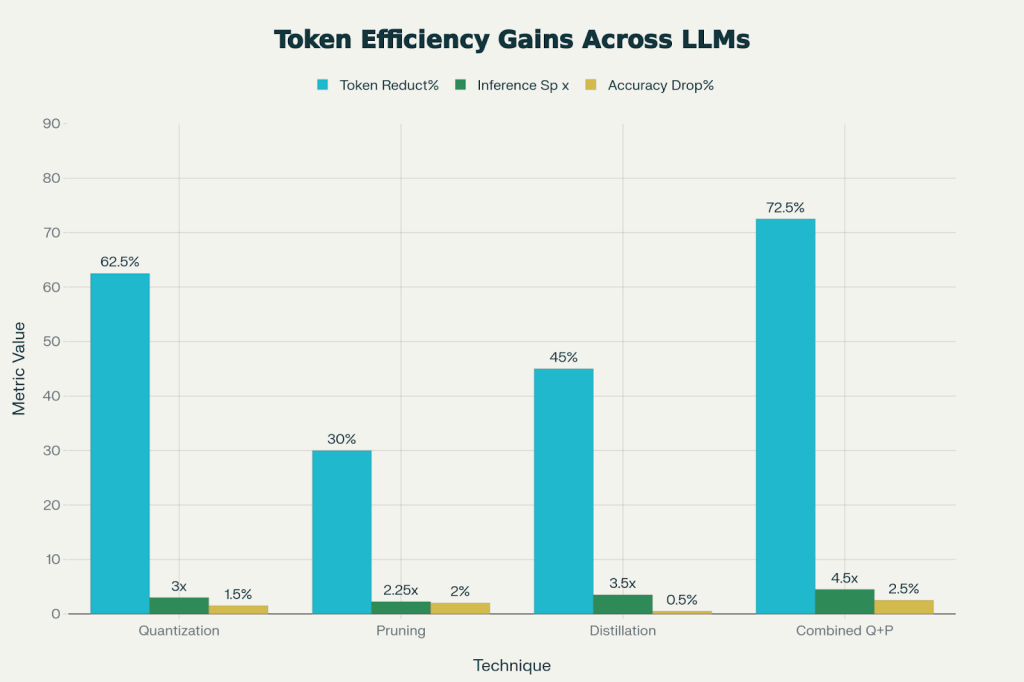
Fine-Tuning LLM Tokens for Efficient Edge and GigaCampus Integration

Context length in LLMs: how to make the most out of it
Advertisement Space (336x280)

Paper page - LazyLLM: Dynamic Token Pruning for Efficient Long Context ...

Paper page - LazyLLM: Dynamic Token Pruning for Efficient Long Context ...

How LLMs Learn: From Tokens to Training

Not All Tokens Matter: Towards Efficient LLM Reasoning via Token ...
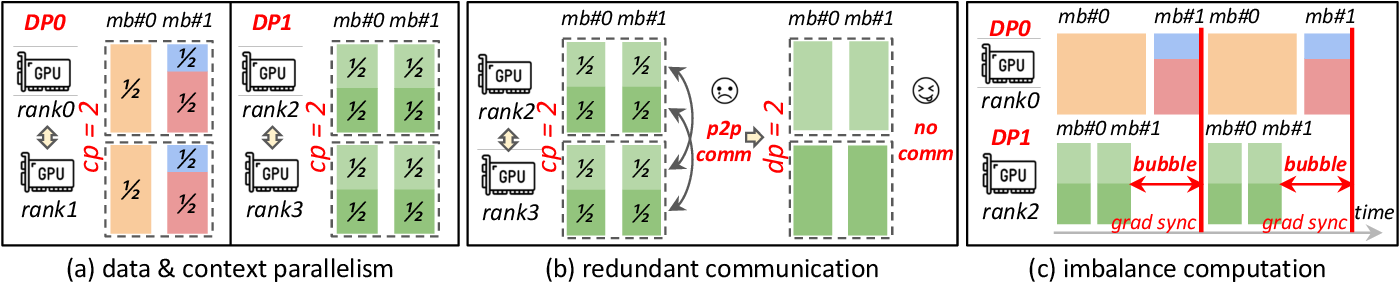
Figure 3 from ByteScale: Communication-Efficient Scaling of LLM ...

How LLMs Learn: From Tokens to Training