
Efficient Llm An Efficient Solution For Llm Inference On Intel Gpus

Efficient LLM-An efficient solution for LLM inference on Intel GPUs.
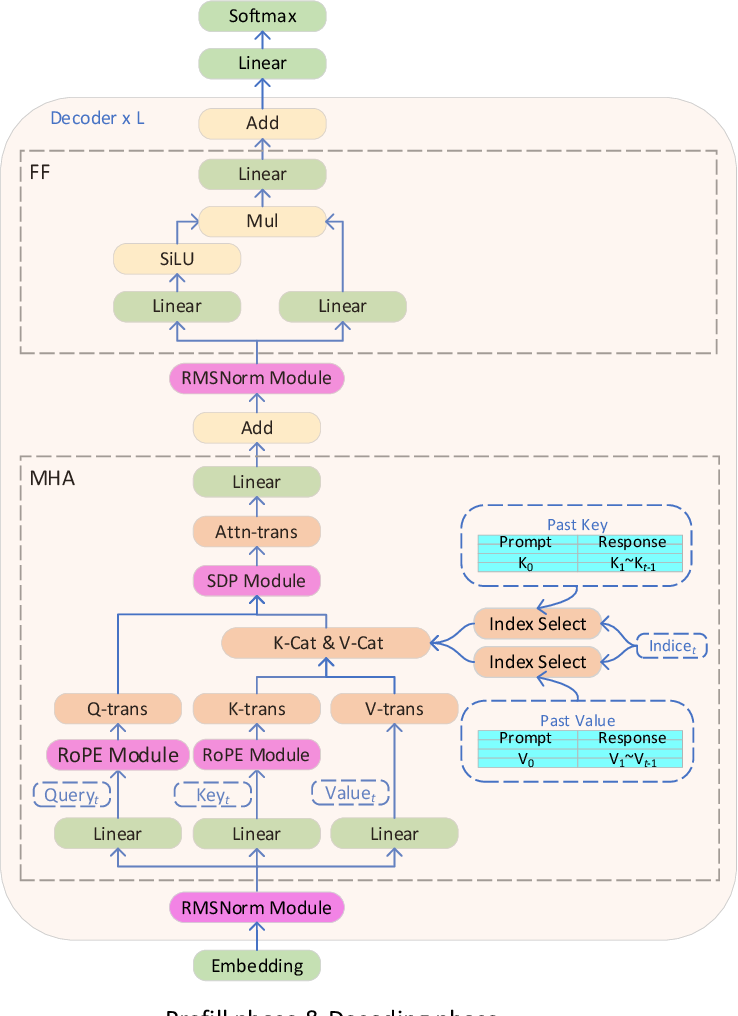
Figure 1 from Efficient LLM inference solution on Intel GPU | Semantic ...

Figure 2 from Efficient LLM inference solution on Intel GPU | Semantic ...

Figure 3 from Efficient LLM inference solution on Intel GPU | Semantic ...

Table 1 from Efficient LLM inference solution on Intel GPU | Semantic ...

Intel presents Efficient LLM inference solution on Intel GPU paper page ...
Paper page - Efficient LLM inference solution on Intel GPU

Free Video: LLM Efficient Inference in CPUs and Intel GPUs - Intel ...
vLLM x AMD: Highly Efficient LLM Inference on AMD Instinct™ MI300X GPUs
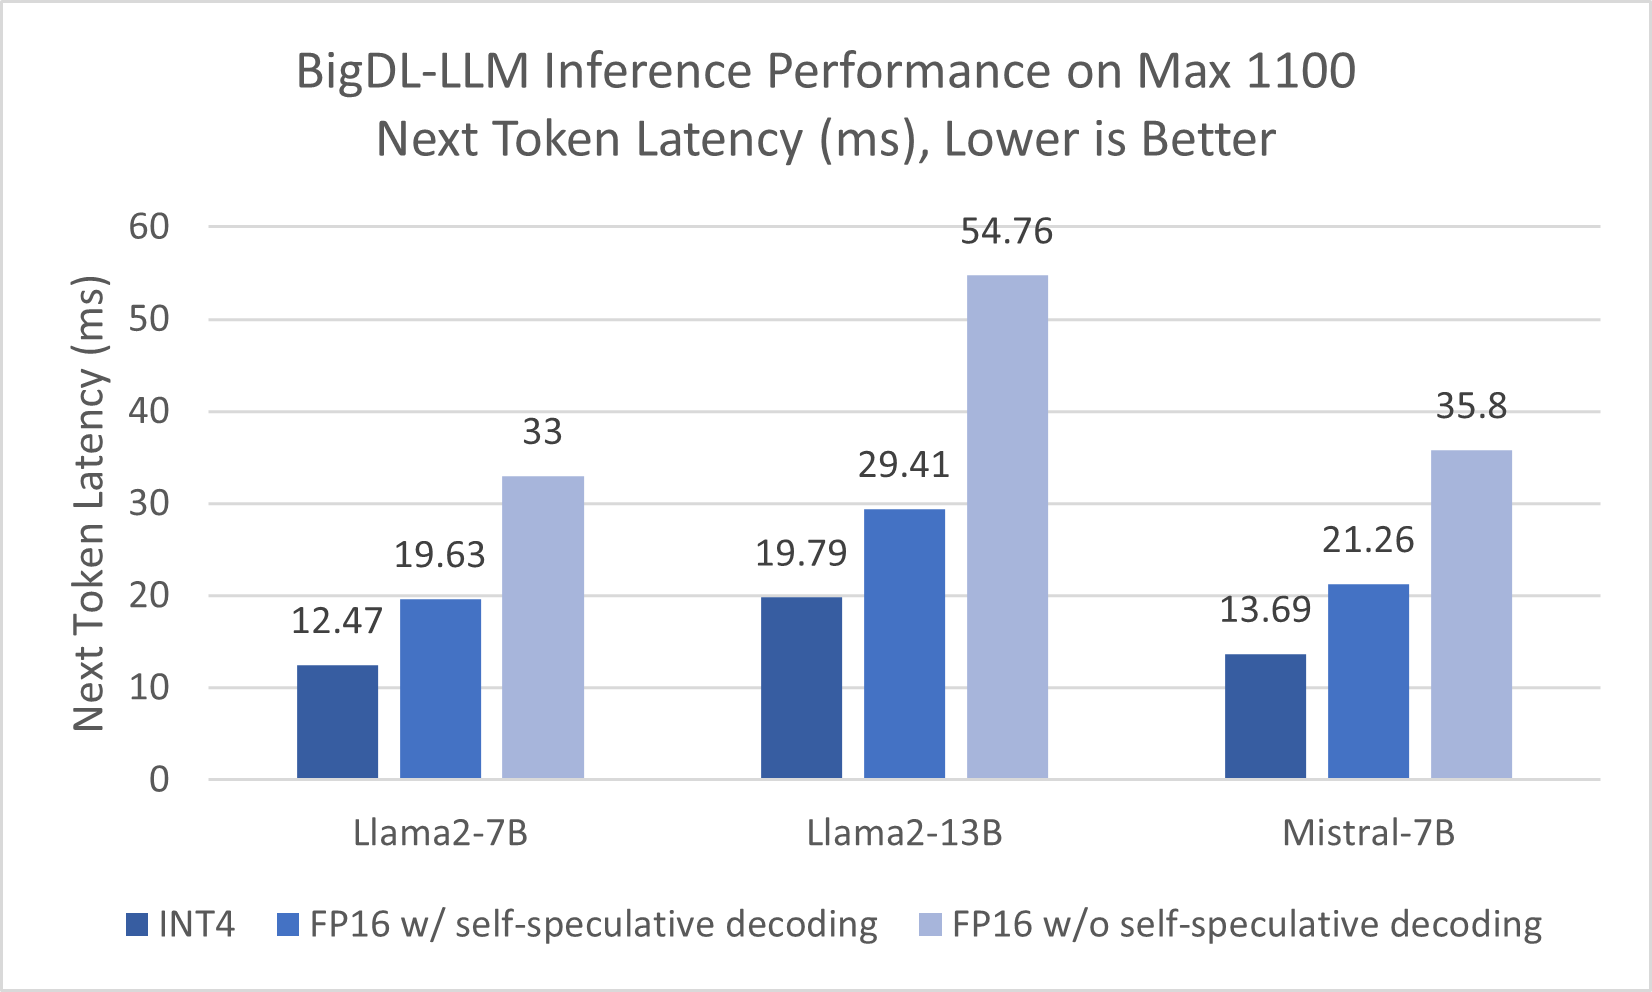
Accelerating LLM Inference on Intel Data Center GPUs using BigDL LLM
Advertisement Space (300x250)
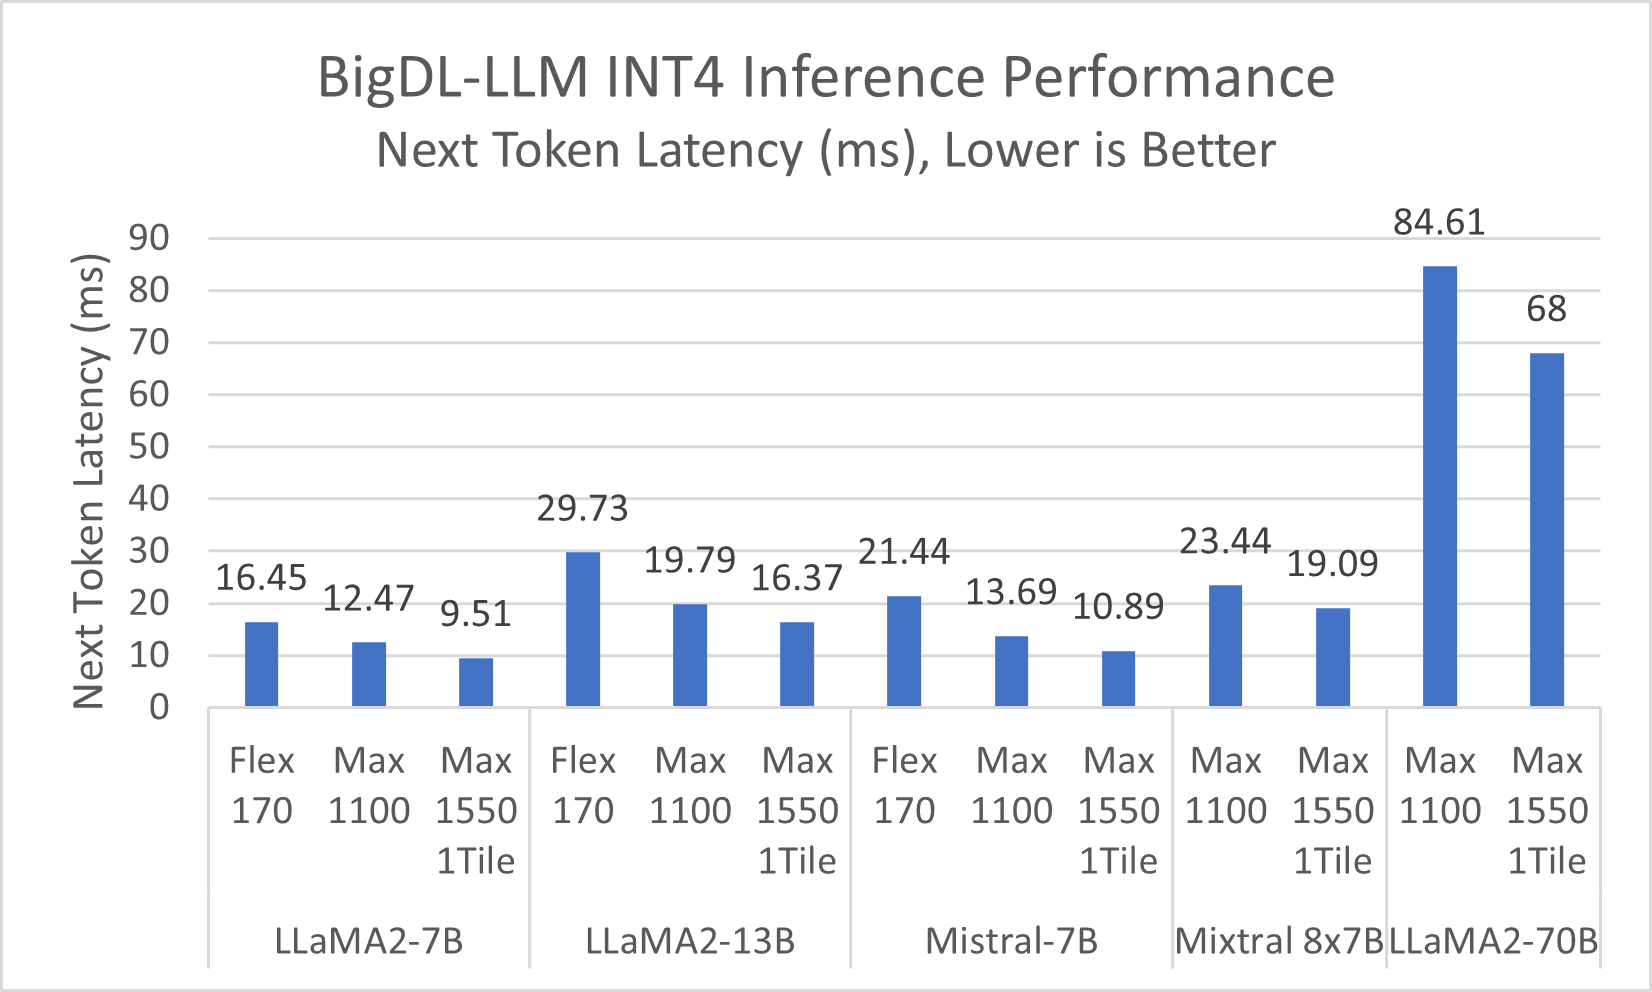
Accelerating LLM Inference on Intel Data Center GPUs using BigDL LLM

Intel AutoRound Enables Faster & More Efficient Quantized LLM Models On ...

Parallel CPU-GPU Execution for LLM Inference on Constrained GPUs | AI ...
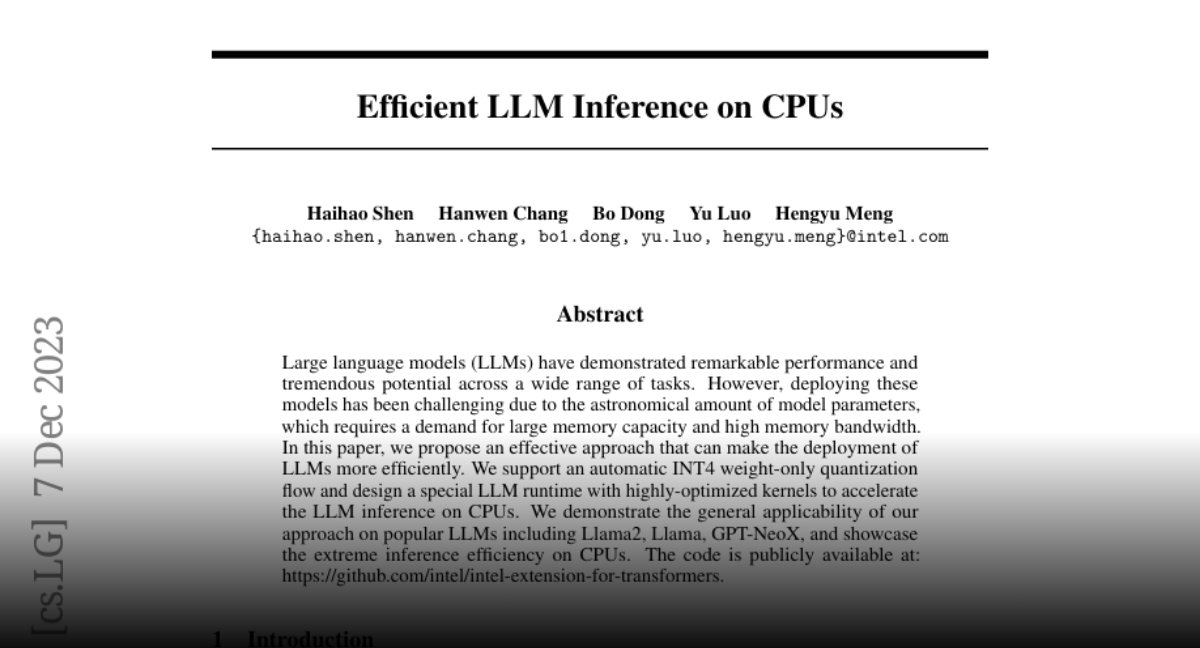
Paper page - Efficient LLM Inference on CPUs

SLO-aware GPU Frequency Scaling for Energy Efficient LLM Inference ...

[논문 리뷰] SLO-aware GPU Frequency Scaling for Energy Efficient LLM ...
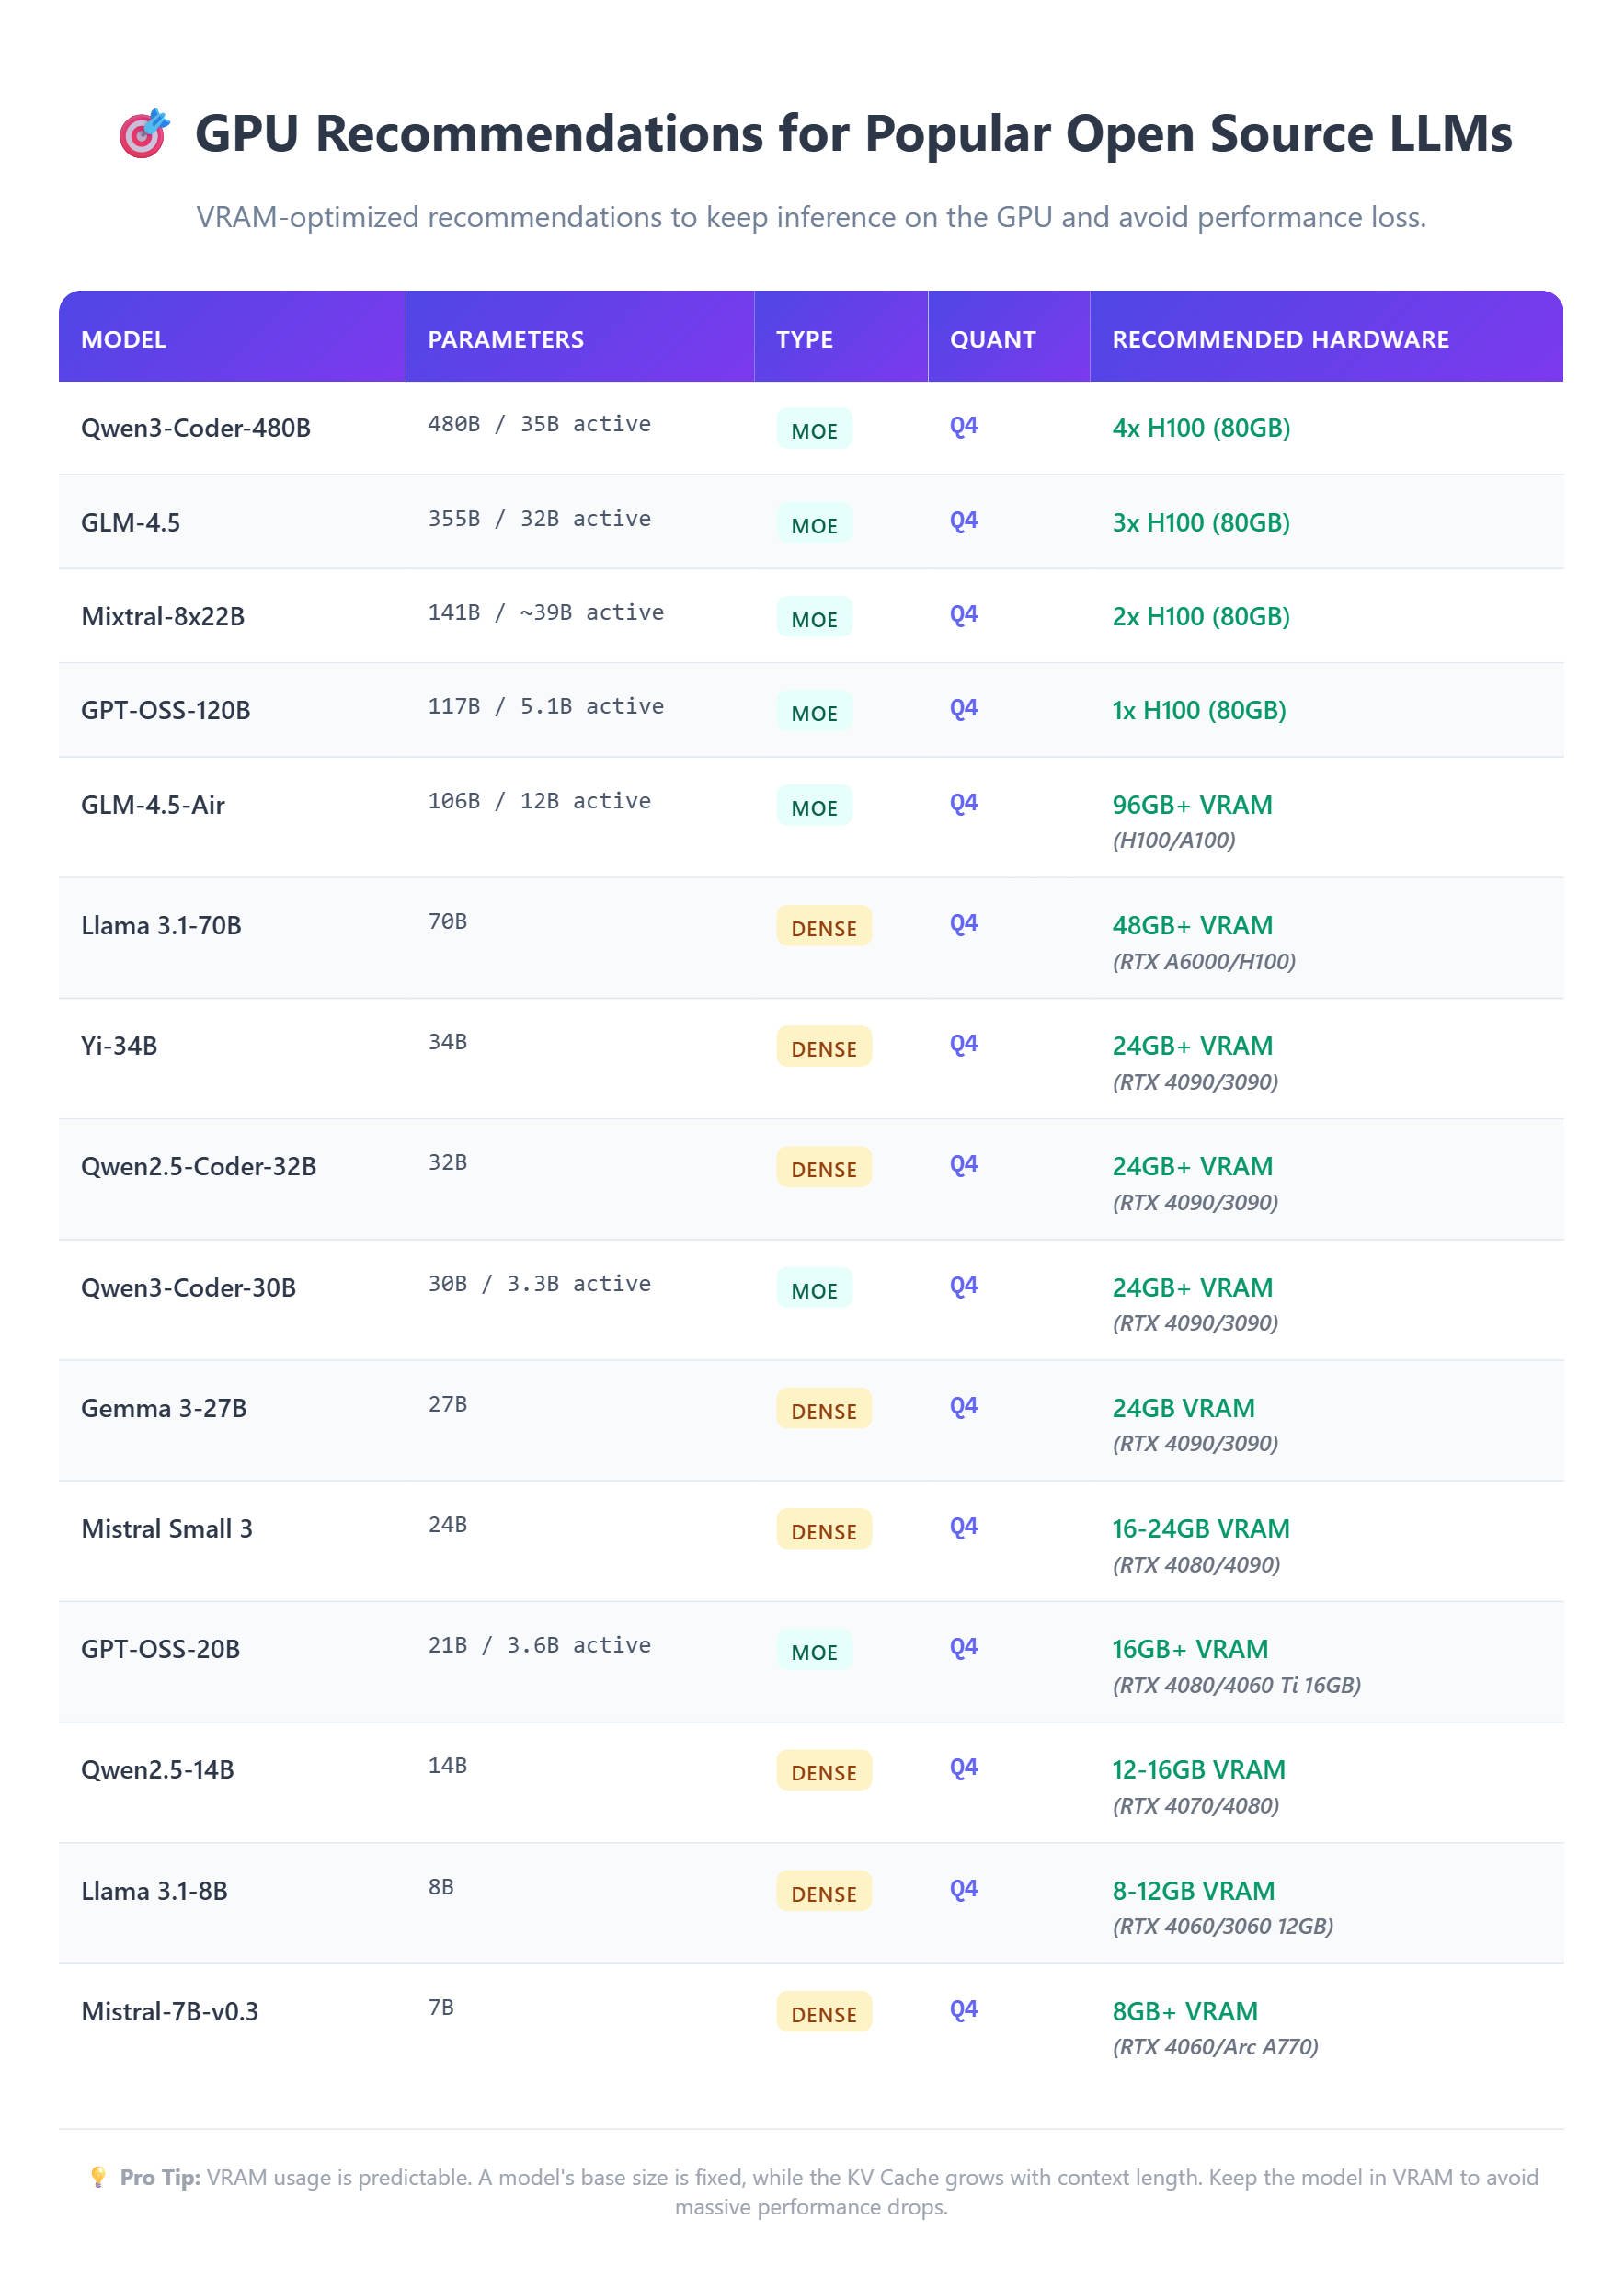
The Best GPUs for Local LLM Inference in 2025 | LocalLLM.in
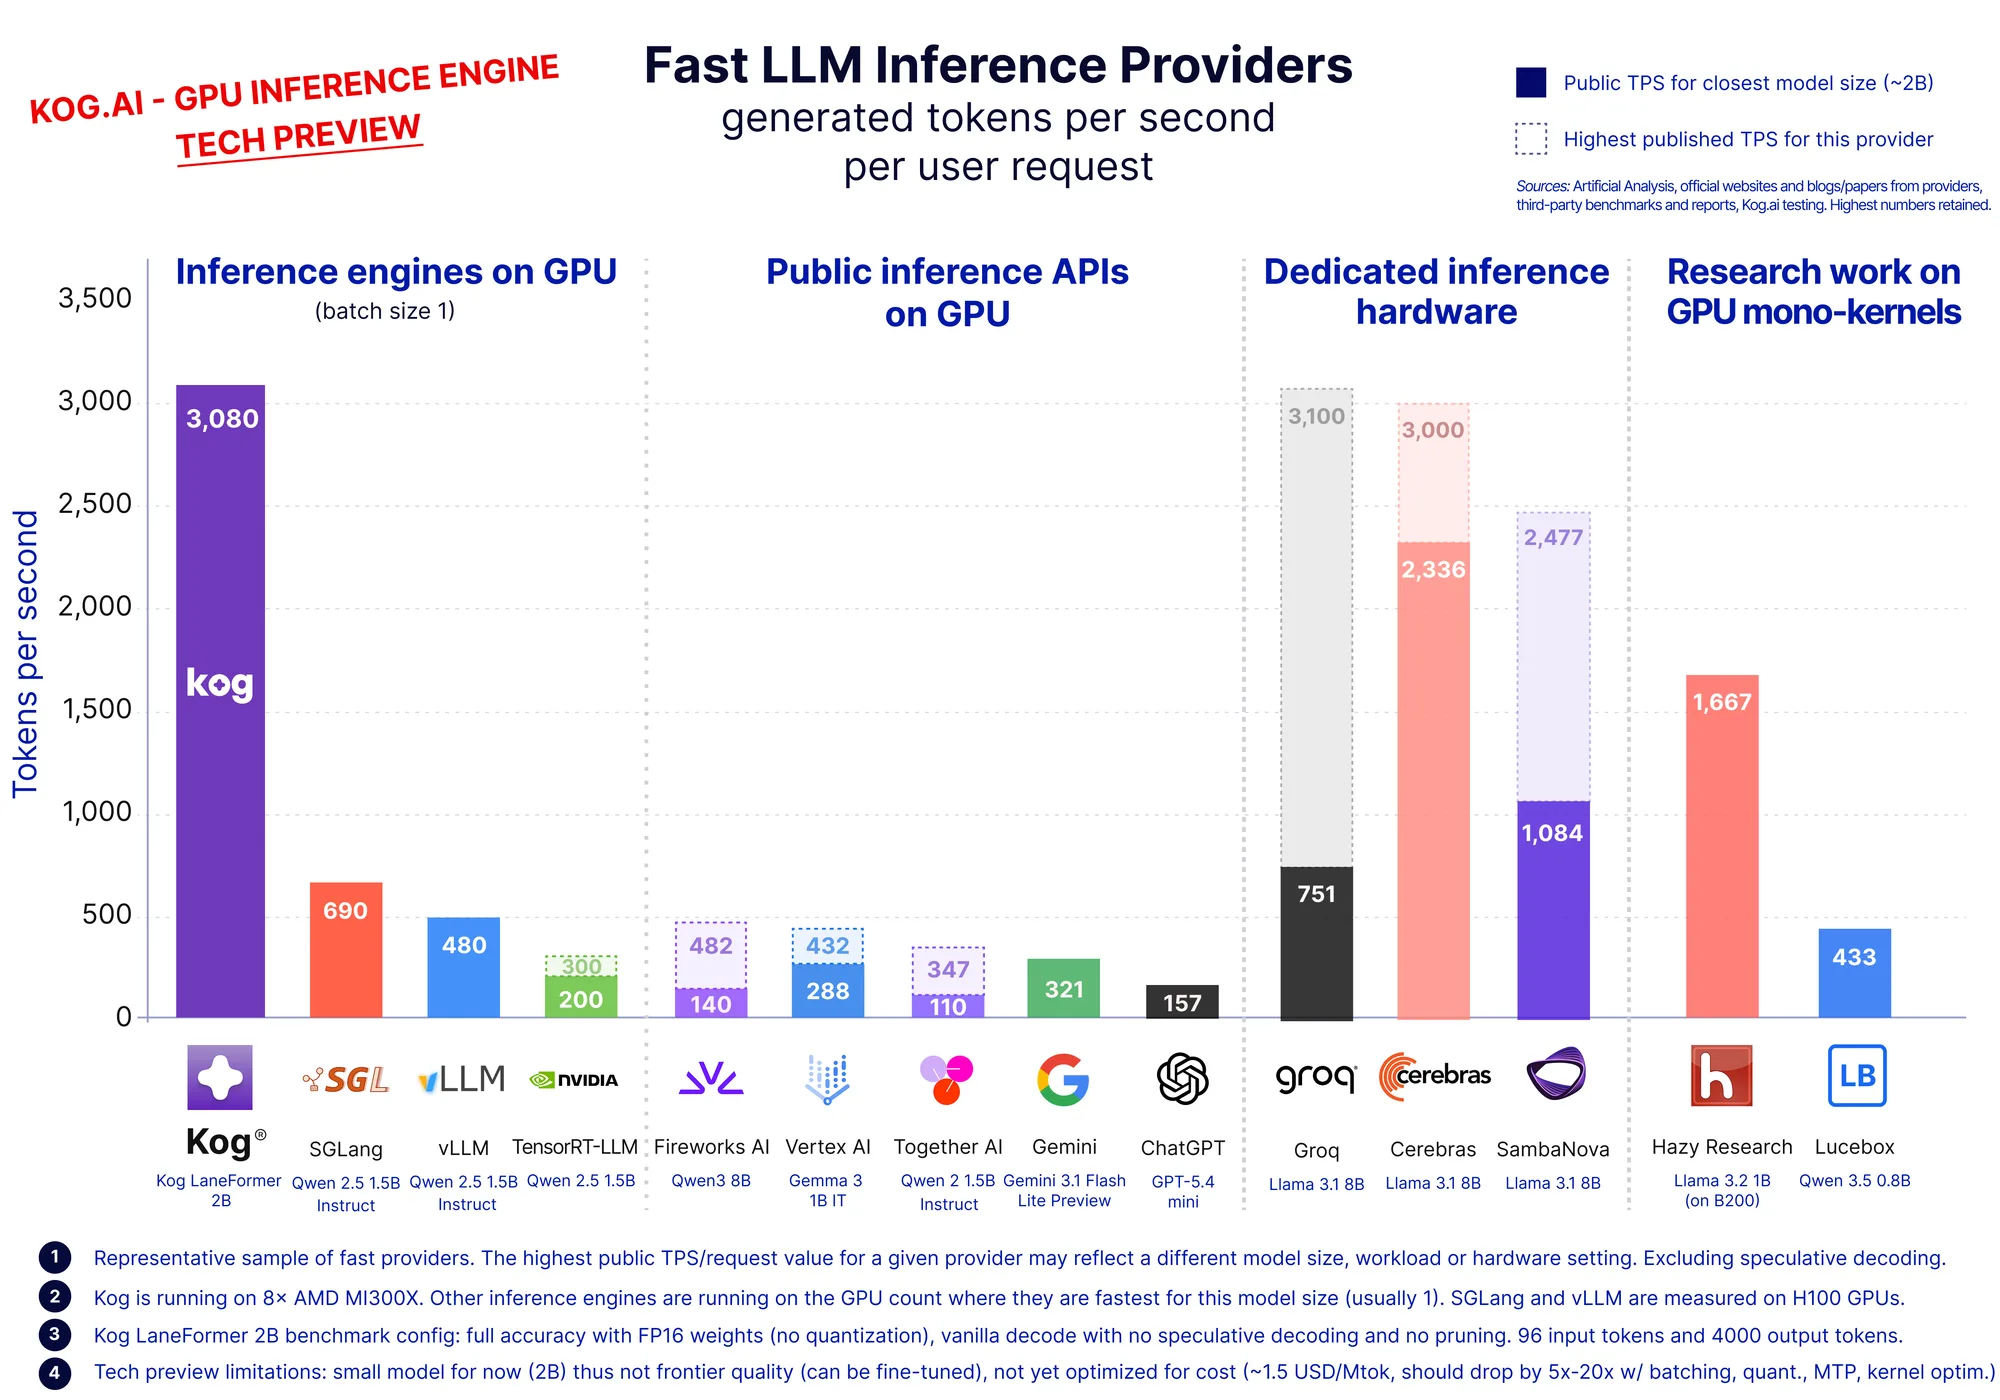
LLM Inference Speed: 3,000 Tokens/s On Standard GPUs
Harmonizing Multi-GPUs: Efficient Scaling of LLM Inference | by TitanML ...

Harmonizing Multi-GPUs: Efficient Scaling of LLM Inference | by TitanML ...
Advertisement Space (336x280)
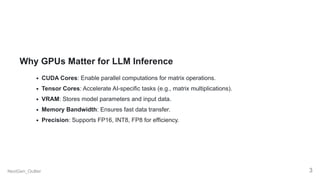
The Best NVIDIA GPUs for LLM Inference in 2025.pdf

LLM Inference Algorithms Based on GPUs and NPUs by Won Wook Song on Prezi

Intel Breakthrough: 1-2 Bit LLM Inference for AI PCs & Edge - Up to 7x ...
Top GPUs Optimized for LLM Inference Workloads

Figure 1 from A Systematic Characterization of LLM Inference on GPUs ...
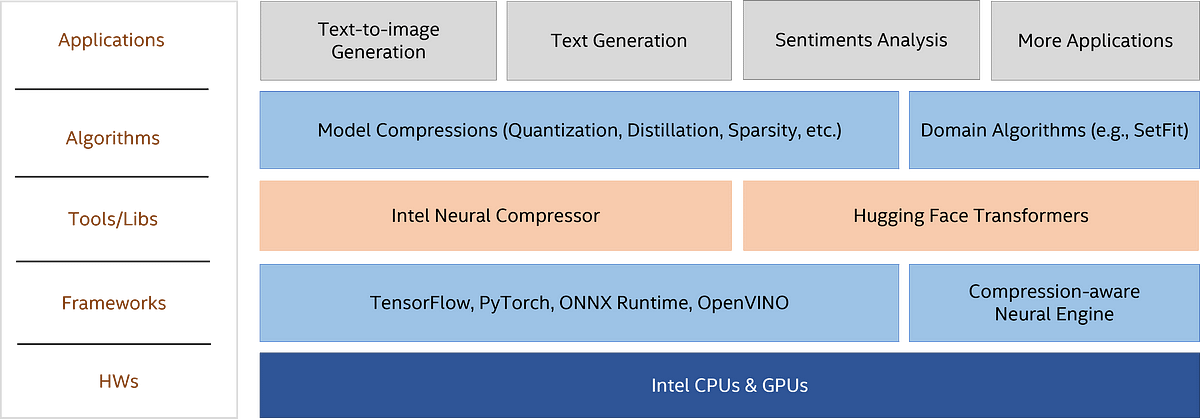
Highly-efficient LLM Inference on Intel Platforms | by Intel(R) Neural ...

Optimize LLM serving with vLLM on Intel® GPUs - Intel Community

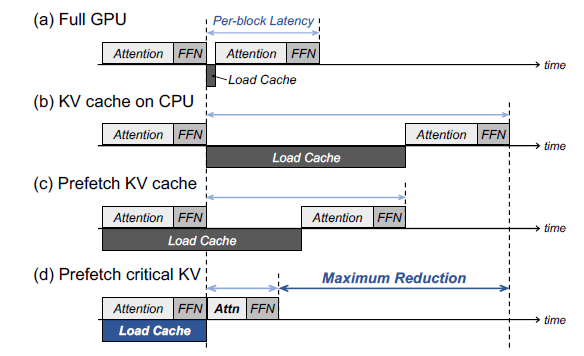
CLO: Efficient LLM Inference System with CPU-Light KVCache Offloading ...
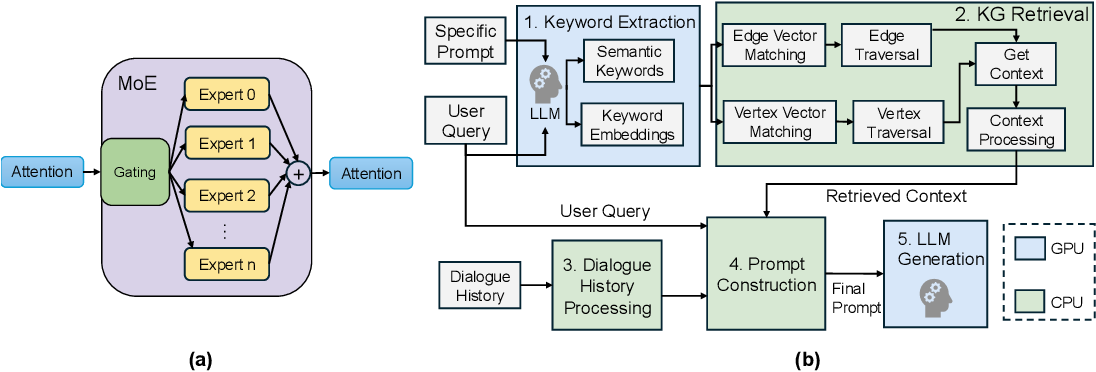
Figure 2 from A Systematic Characterization of LLM Inference on GPUs ...

Demo | LLM Inference on Intel® Data Center GPU Flex Series | Intel ...
Advertisement Space (336x280)
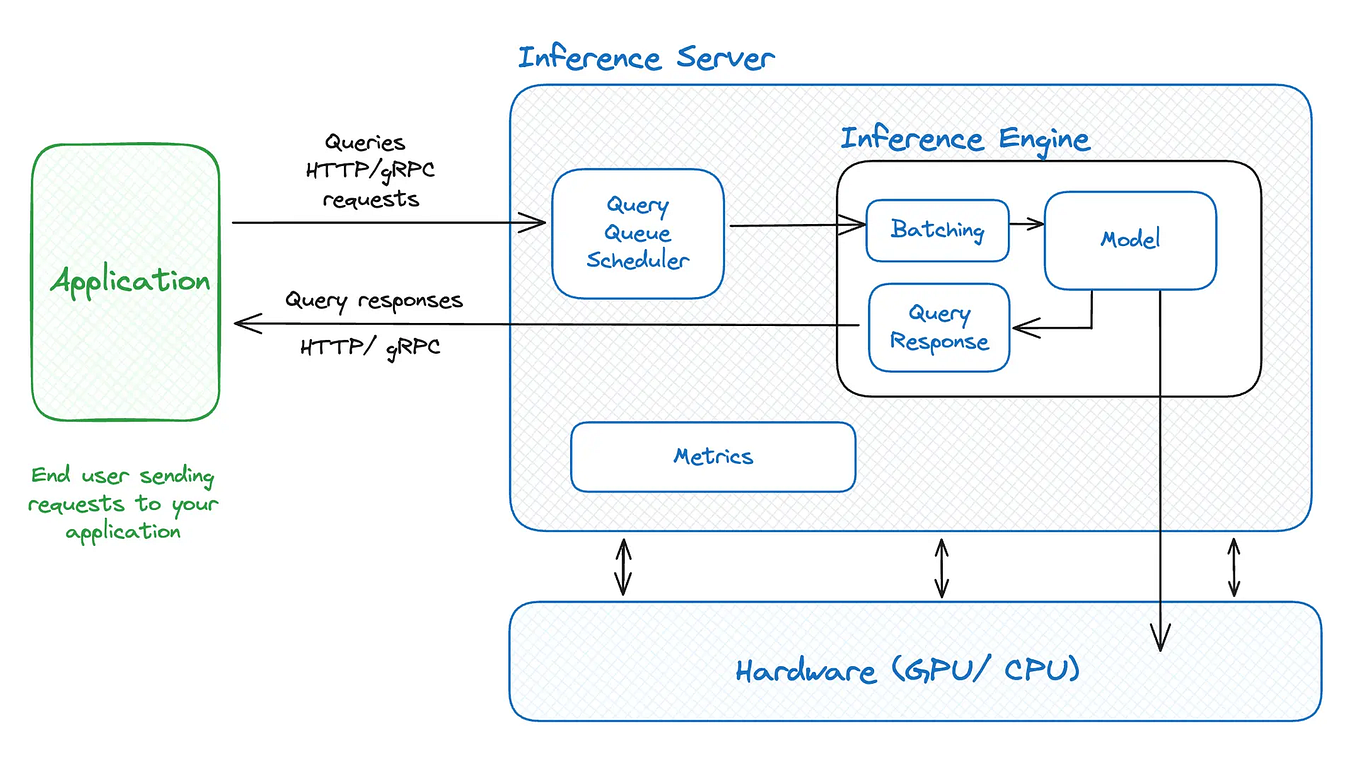
Harmonizing Multi-GPUs: Efficient Scaling of LLM Inference | by TitanML ...
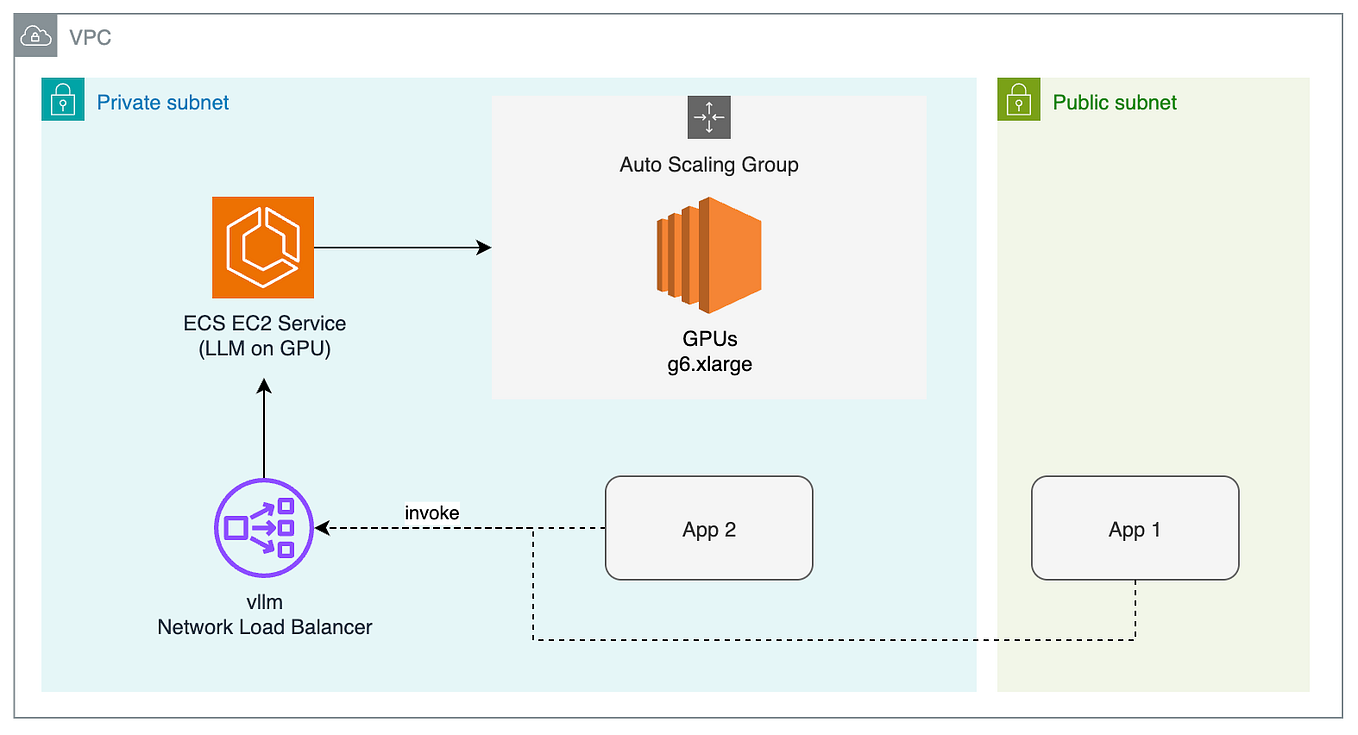
LLM Inference on multiple GPUs with 🤗 Accelerate | by Geronimo | Medium

Will ASICs Dethrone GPUs for LLM Inference
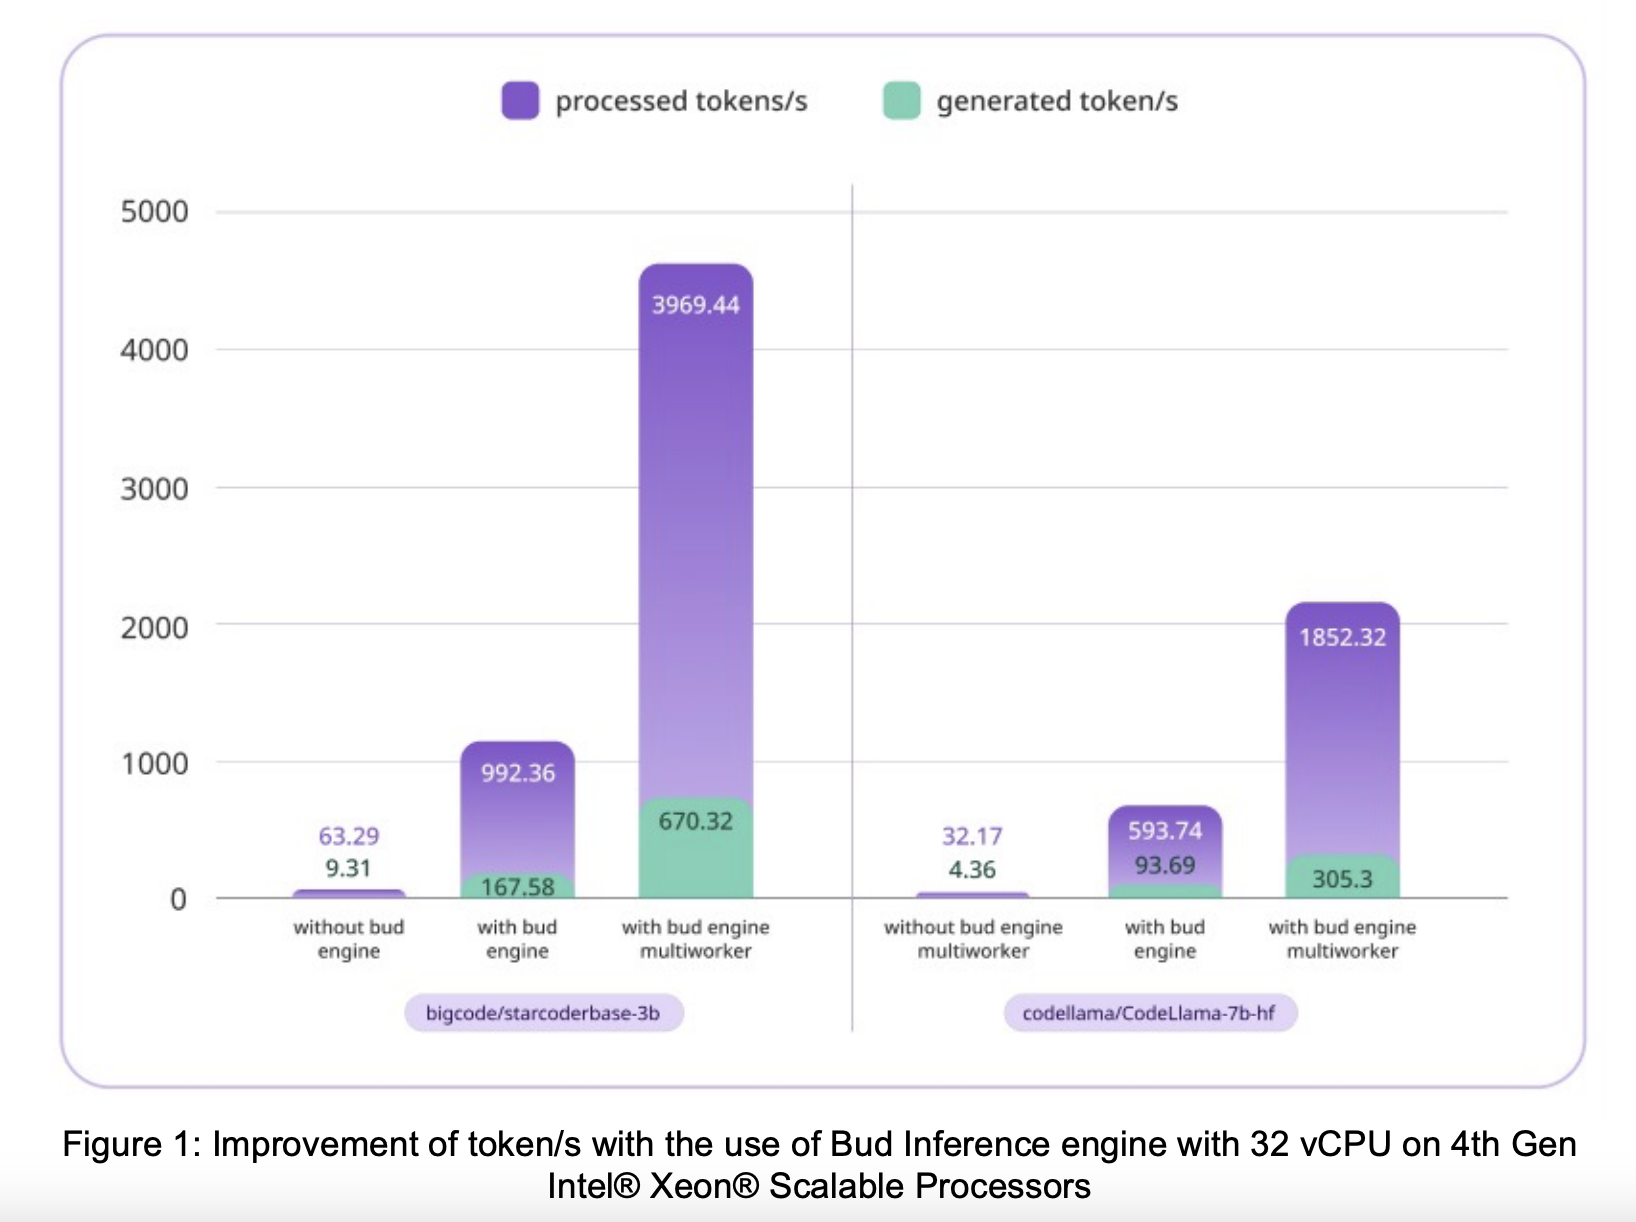
Enhancing LLM inference performance on Intel CPUs - BudEcosystem

Optimize price-performance of LLM inference on NVIDIA GPUs using the ...

Harmonizing Multi-GPUs: Efficient Scaling of LLM Inference | by TitanML ...